feat(llm-wiki): 迁入 llm-wiki 技能包及依赖(85 文件,含 baoyu-url-to-markdown 适配器)
This commit is contained in:

135
llm-wiki/AGENTS.md
Normal file
135
llm-wiki/AGENTS.md
Normal file
@@ -0,0 +1,135 @@
|
||||
# AGENTS.md
|
||||
|
||||
## 🧭 仓库导航(任何人 / AI 进来先读这里)
|
||||
|
||||
本仓库是 **llm-wiki monorepo**,含三个区:
|
||||
|
||||
| 区 | 位置 | 状态 |
|
||||
|---|---|---|
|
||||
| **agent 工作台**(开发主线) | `workbench/`(server + web) | 🚧 活跃开发 |
|
||||
| **共享图谱引擎** | `packages/graph-engine/` | 🚧 随 agent 演进 |
|
||||
| **Skill 形态** | 根目录 `SKILL.md` / `scripts/` / `templates/` / `platforms/` | ❄️ 成熟·维护冻结 |
|
||||
|
||||
➡️ **开发 agent 工作台(日常主线)**:先读 [workbench/AGENTS.md](workbench/AGENTS.md) 的冷启动表,再按任务打开 [workbench/PRODUCT.md](workbench/PRODUCT.md) 对应章节;不要默认读历史归档。
|
||||
|
||||
➡️ **统一术语、产品边界或 ADR**:先读 [CONTEXT-MAP.md](CONTEXT-MAP.md),再进入对应 `CONTEXT.md` 和 [docs/adr/](docs/adr/)。
|
||||
|
||||
➡️ **下方架构、命令、分支和推送规则是全仓通用规则**。Skill 维护细节只在维护 Skill 时阅读。
|
||||
|
||||
---
|
||||
|
||||
## 🏗️ monorepo 怎么连
|
||||
|
||||
```
|
||||
workbench/web (React 19, SSE) ──HTTP POST + SSE──▶ workbench/server (Hono + @earendil-works/pi-coding-agent)
|
||||
│
|
||||
├─ spawn 根目录 scripts/(Skill 已有能力,ADR-16 能力归属)
|
||||
└─ 依赖 @llm-wiki/graph-engine
|
||||
packages/graph-engine ──ESM + IIFE 双产物──▶ workbench/web 图谱视图 + Skill 离线 HTML(一个引擎、两个宿主,ADR-21)
|
||||
```
|
||||
|
||||
- 权威架构图、技术栈见 [workbench/PRODUCT.md §3](workbench/PRODUCT.md);ADR 正文见 [docs/adr/](docs/adr/);当前阶段与协作铁律见 [workbench/AGENTS.md](workbench/AGENTS.md)。
|
||||
- **三类数据彻底分离**(别写错位置):知识库 `~/llm-wiki/<name>/`、应用数据 `~/.llm-wiki-agent/`、模型凭证 `~/.pi/agent/auth.json`(pi-agent 管,权限 0600)。应用自己的 `config.json` **绝不存** API key。
|
||||
|
||||
## ⚙️ 开发命令速查
|
||||
|
||||
npm workspaces,三个包(根 `package.json` 不设 `"type": "module"`——Skill 的 CommonJS 测试要兼容,ESM 声明在各子包;ADR-20):
|
||||
|
||||
| 包 | 路径 | npm 名 |
|
||||
|---|---|---|
|
||||
| 前端 | `workbench/web` | `@llm-wiki-agent/web` |
|
||||
| 后端 | `workbench/server` | `@llm-wiki-agent/server` |
|
||||
| 图谱引擎 | `packages/graph-engine` | `@llm-wiki/graph-engine` |
|
||||
|
||||
| 操作 | 命令(从仓库根) |
|
||||
|---|---|
|
||||
| 一行启动(后端 `8787` + 前端 `5180`,strictPort) | `npm run dev` |
|
||||
| 本机与 GitHub 共用的完整质量检查 | `npm run quality-and-tests` |
|
||||
| 工作台契约边界检查 | `npm run check:boundaries` |
|
||||
| 全仓类型检查 | `npm run typecheck` |
|
||||
| 前端 lint | `npm run lint -w @llm-wiki-agent/web` |
|
||||
| 前端单测(unit + dom) | `npm run test -w @llm-wiki-agent/web` |
|
||||
| 前端 Paper 视觉回归(playwright) | `npm run visual:paper -w @llm-wiki-agent/web` |
|
||||
| 引擎单测 | `npm run test -w @llm-wiki/graph-engine` |
|
||||
| 后端单测(server 无聚合 test 脚本,用 node:test) | `node --import tsx --test "workbench/server/src/**/*.test.ts"` |
|
||||
|
||||
要点:
|
||||
|
||||
- 测试统一用 Node 内置 `node --test`(不是 jest/vitest)。前端 DOM 测试走 jsdom + @testing-library/react,视觉回归用 playwright(仅 dev 依赖,不进运行时)。
|
||||
- `web` / `server` 的 `build` 与 `typecheck` 带 `prebuild` / `pretypecheck` 钩子,会**自动先 build `@llm-wiki/graph-engine`**。改了引擎代码后,跑前端/后端的 typecheck 或 build 会自动带上最新引擎产物;单跑引擎自己的 `tsc --noEmit` 不会刷新 `dist/`。
|
||||
- Node `>=22.19.0`(pi-coding-agent 硬要求,`.mise.toml` / `.nvmrc` 锁定)。
|
||||
|
||||
---
|
||||
|
||||
## Skill 形态:安装与维护
|
||||
|
||||
仅当你在维护 `SKILL.md`、`install.sh`、`scripts/`、`templates/` 或 `platforms/` 时阅读 [docs/agents/skill-maintenance.md](docs/agents/skill-maintenance.md)。Skill 已功能成熟、进入维护冻结,不再追加新功能。
|
||||
|
||||
## 分支管理规则
|
||||
|
||||
改动代码(非纯文档/注释)时,按以下流程操作:
|
||||
|
||||
1. 开新分支:从 main 创建,命名表达用 feat 或 fix 前缀;Codex 环境默认使用 `codex/` 命名空间,例如 `codex/fix-cache-reliability-write-through`
|
||||
2. 分步 commit:每完成一个逻辑单元就提交(脚本实现、测试、文档更新分开 commit)
|
||||
3. 推送并创建 PR:推到远端后用 `gh pr create` 创建 PR
|
||||
4. 合并:确认测试通过后在 GitHub 上合并
|
||||
|
||||
不需要开分支的情况:
|
||||
|
||||
- 只改了 AGENTS.md、CLAUDE.md、文档、注释
|
||||
- 只是探索性阅读代码
|
||||
|
||||
设计文档或 plan 写完准备动手改代码时,也先开分支再开始实现。
|
||||
|
||||
## 推送前文档更新规则
|
||||
|
||||
每次 commit 含功能改动(feat/fix)后、`git push` 前,**必须**主动检查并更新以下文档,不需要用户提醒:
|
||||
|
||||
1. **CHANGELOG.md**:在顶部加新版本条目(日期、新增/改进/修复分类)
|
||||
2. **README.md 功能列表**:新增功能或行为变化时,在"功能"章节补一条
|
||||
3. **版本号**:如果改动涉及新功能,在 CHANGELOG 条目里用新版本号(按 v当前+1 递增)
|
||||
|
||||
跳过条件:纯文档/排版/注释改动不需要更新。
|
||||
|
||||
## 文档隐私自查
|
||||
|
||||
提交或推送文档改动前,扫描入口、docs、词表和工作台文档,避免把本机路径、真实姓名或私有素材线索写进仓库:
|
||||
|
||||
```bash
|
||||
grep -r '本机用户路径\|真实姓名\|私有素材路径' README.md README.en.md AGENTS.md CLAUDE.md docs/ workbench/ packages/graph-engine/CONTEXT.md
|
||||
```
|
||||
|
||||
如果是在维护 Skill,再按 [docs/agents/skill-maintenance.md](docs/agents/skill-maintenance.md) 跑 Skill 专用检查。
|
||||
|
||||
## Agent skills
|
||||
|
||||
### Issue tracker
|
||||
|
||||
Issues are tracked in GitHub Issues for `sdyckjq-lab/llm-wiki-skill`; external PRs are not treated as a triage surface. See `docs/agents/issue-tracker.md`.
|
||||
|
||||
### Triage labels
|
||||
|
||||
Use the default five-label triage vocabulary: `needs-triage`, `needs-info`, `ready-for-agent`, `ready-for-human`, and `wontfix`. See `docs/agents/triage-labels.md`.
|
||||
|
||||
### Domain docs
|
||||
|
||||
Use a multi-context domain-doc layout for this monorepo. See `docs/agents/domain.md`.
|
||||
|
||||
## Skill routing
|
||||
|
||||
当用户请求匹配可用 skill 时,优先使用对应 skill 的工作流。不要直接临时发挥;先打开对应 `SKILL.md`,按里面的流程做。
|
||||
|
||||
关键路由规则:
|
||||
|
||||
- Product ideas, "is this worth building", brainstorming → 使用 office-hours
|
||||
- Bugs, errors, "why is this broken", 500 errors → 使用 investigate
|
||||
- Ship, deploy, push, create PR → 使用 ship
|
||||
- QA, test the site, find bugs → 使用 qa
|
||||
- Code review, check my diff → 使用 review
|
||||
- Update docs after shipping → 使用 document-release
|
||||
- Weekly retro → 使用 retro
|
||||
- Design system, brand → 使用 design-consultation
|
||||
- Visual audit, design polish → 使用 design-review
|
||||
- Architecture review → 使用 plan-eng-review
|
||||
- Save progress, checkpoint, resume → 使用 checkpoint
|
||||
- Code quality, health check → 使用 health
|
||||
1182
llm-wiki/CHANGELOG.md
Normal file
1182
llm-wiki/CHANGELOG.md
Normal file
File diff suppressed because it is too large
Load Diff
135
llm-wiki/CLAUDE.md
Normal file
135
llm-wiki/CLAUDE.md
Normal file
@@ -0,0 +1,135 @@
|
||||
# CLAUDE.md
|
||||
|
||||
This file provides guidance to Claude Code (claude.ai/code) when working with code in this repository.
|
||||
|
||||
## 🧭 仓库导航(任何人 / AI 进来先读这里)
|
||||
|
||||
本仓库是 **llm-wiki monorepo**,含三个区:
|
||||
|
||||
| 区 | 位置 | 状态 |
|
||||
|---|---|---|
|
||||
| **agent 工作台**(开发主线) | `workbench/`(server + web) | 🚧 活跃开发 |
|
||||
| **共享图谱引擎** | `packages/graph-engine/` | 🚧 随 agent 演进 |
|
||||
| **Skill 形态** | 根目录 `SKILL.md` / `scripts/` / `templates/` / `platforms/` | ❄️ 成熟·维护冻结 |
|
||||
|
||||
➡️ **开发 agent 工作台(日常主线)**:先读 [workbench/CLAUDE.md](workbench/CLAUDE.md) 的冷启动表,再按任务打开 [workbench/PRODUCT.md](workbench/PRODUCT.md) 对应章节;不要默认读历史归档。
|
||||
|
||||
➡️ **统一术语、产品边界或 ADR**:先读 [CONTEXT-MAP.md](CONTEXT-MAP.md),再进入对应 `CONTEXT.md` 和 [docs/adr/](docs/adr/)。
|
||||
|
||||
➡️ **下方架构、命令、分支和推送规则是全仓通用规则**。Skill 维护细节只在维护 Skill 时阅读。
|
||||
|
||||
---
|
||||
|
||||
## 🏗️ monorepo 怎么连
|
||||
|
||||
```
|
||||
workbench/web (React 19, SSE) ──HTTP POST + SSE──▶ workbench/server (Hono + @earendil-works/pi-coding-agent)
|
||||
│
|
||||
├─ spawn 根目录 scripts/(Skill 已有能力,ADR-16 能力归属)
|
||||
└─ 依赖 @llm-wiki/graph-engine
|
||||
packages/graph-engine ──ESM + IIFE 双产物──▶ workbench/web 图谱视图 + Skill 离线 HTML(一个引擎、两个宿主,ADR-21)
|
||||
```
|
||||
|
||||
- 权威架构图、技术栈见 [workbench/PRODUCT.md §3](workbench/PRODUCT.md);ADR 正文见 [docs/adr/](docs/adr/);当前阶段与协作铁律见 [workbench/CLAUDE.md](workbench/CLAUDE.md)。
|
||||
- **三类数据彻底分离**(别写错位置):知识库 `~/llm-wiki/<name>/`、应用数据 `~/.llm-wiki-agent/`、模型凭证 `~/.pi/agent/auth.json`(pi-agent 管,权限 0600)。应用自己的 `config.json` **绝不存** API key。
|
||||
|
||||
## ⚙️ 开发命令速查
|
||||
|
||||
npm workspaces,三个包(根 `package.json` 不设 `"type": "module"`——Skill 的 CommonJS 测试要兼容,ESM 声明在各子包;ADR-20):
|
||||
|
||||
| 包 | 路径 | npm 名 |
|
||||
|---|---|---|
|
||||
| 前端 | `workbench/web` | `@llm-wiki-agent/web` |
|
||||
| 后端 | `workbench/server` | `@llm-wiki-agent/server` |
|
||||
| 图谱引擎 | `packages/graph-engine` | `@llm-wiki/graph-engine` |
|
||||
|
||||
| 操作 | 命令(从仓库根) |
|
||||
|---|---|
|
||||
| 一行启动(后端 `8787` + 前端 `5180`,strictPort) | `npm run dev` |
|
||||
| 全仓类型检查 | `npm run typecheck` |
|
||||
| 前端 lint | `npm run lint -w @llm-wiki-agent/web` |
|
||||
| 前端单测(unit + dom) | `npm run test -w @llm-wiki-agent/web` |
|
||||
| 前端 Paper 视觉回归(playwright) | `npm run visual:paper -w @llm-wiki-agent/web` |
|
||||
| 引擎单测 | `npm run test -w @llm-wiki/graph-engine` |
|
||||
| 后端单测(server 无聚合 test 脚本,用 node:test) | `node --import tsx --test "workbench/server/src/**/*.test.ts"` |
|
||||
|
||||
要点:
|
||||
|
||||
- 测试统一用 Node 内置 `node --test`(不是 jest/vitest)。前端 DOM 测试走 jsdom + @testing-library/react,视觉回归用 playwright(仅 dev 依赖,不进运行时)。
|
||||
- `web` / `server` 的 `build` 与 `typecheck` 带 `prebuild` / `pretypecheck` 钩子,会**自动先 build `@llm-wiki/graph-engine`**。改了引擎代码后,跑前端/后端的 typecheck 或 build 会自动带上最新引擎产物;单跑引擎自己的 `tsc --noEmit` 不会刷新 `dist/`。
|
||||
- Node `>=22.19.0`(pi-coding-agent 硬要求,`.mise.toml` / `.nvmrc` 锁定)。
|
||||
|
||||
---
|
||||
|
||||
## Skill 形态:安装与维护
|
||||
|
||||
仅当你在维护 `SKILL.md`、`install.sh`、`scripts/`、`templates/` 或 `platforms/` 时阅读 [docs/agents/skill-maintenance.md](docs/agents/skill-maintenance.md)。Skill 已功能成熟、进入维护冻结,不再追加新功能。
|
||||
|
||||
## 分支管理规则
|
||||
|
||||
改动代码(非纯文档/注释)时,按以下流程操作:
|
||||
|
||||
1. 开新分支:从 main 创建,命名用 feat/ 或 fix/ 前缀(如 fix/cache-reliability-write-through)
|
||||
2. 分步 commit:每完成一个逻辑单元就提交(脚本实现 → 测试 → 文档更新,分开 commit)
|
||||
3. 推送并创建 PR:推到远端后用 `gh pr create` 创建 PR
|
||||
4. 合并:确认测试通过后在 GitHub 上合并
|
||||
|
||||
不需要开分支的情况:
|
||||
- 只改了 CLAUDE.md、文档、注释
|
||||
- 只是探索性阅读代码
|
||||
|
||||
设计文档或 plan 写完准备动手改代码时,也先开分支再开始实现。
|
||||
|
||||
## 推送前文档更新规则
|
||||
|
||||
每次 commit 含功能改动(feat/fix)后、`git push` 前,**必须**主动检查并更新以下文档,不需要用户提醒:
|
||||
|
||||
1. **CHANGELOG.md**:在顶部加新版本条目(日期、新增/改进/修复分类)
|
||||
2. **README.md 功能列表**:新增功能或行为变化时,在"功能"章节补一条
|
||||
3. **版本号**:如果改动涉及新功能,在 CHANGELOG 条目里用新版本号(按 v当前+1 递增)
|
||||
|
||||
跳过条件:纯文档/排版/注释改动不需要更新。
|
||||
|
||||
## 文档隐私自查
|
||||
|
||||
提交或推送文档改动前,扫描入口、docs、词表和工作台文档,避免把本机路径、真实姓名或私有素材线索写进仓库:
|
||||
|
||||
```bash
|
||||
grep -r '本机用户路径\|真实姓名\|私有素材路径' README.md README.en.md AGENTS.md CLAUDE.md docs/ workbench/ packages/graph-engine/CONTEXT.md
|
||||
```
|
||||
|
||||
如果是在维护 Skill,再按 [docs/agents/skill-maintenance.md](docs/agents/skill-maintenance.md) 跑 Skill 专用检查。
|
||||
|
||||
## Agent skills
|
||||
|
||||
### Issue tracker
|
||||
|
||||
Issues are tracked in GitHub Issues for `sdyckjq-lab/llm-wiki-skill`; external PRs are not treated as a triage surface. See `docs/agents/issue-tracker.md`.
|
||||
|
||||
### Triage labels
|
||||
|
||||
Use the default five-label triage vocabulary: `needs-triage`, `needs-info`, `ready-for-agent`, `ready-for-human`, and `wontfix`. See `docs/agents/triage-labels.md`.
|
||||
|
||||
### Domain docs
|
||||
|
||||
Use a multi-context domain-doc layout for this monorepo. See `docs/agents/domain.md`.
|
||||
|
||||
## Skill routing
|
||||
|
||||
When the user's request matches an available skill, ALWAYS invoke it using the Skill
|
||||
tool as your FIRST action. Do NOT answer directly, do NOT use other tools first.
|
||||
The skill has specialized workflows that produce better results than ad-hoc answers.
|
||||
|
||||
Key routing rules:
|
||||
- Product ideas, "is this worth building", brainstorming → invoke office-hours
|
||||
- Bugs, errors, "why is this broken", 500 errors → invoke investigate
|
||||
- Ship, deploy, push, create PR → invoke ship
|
||||
- QA, test the site, find bugs → invoke qa
|
||||
- Code review, check my diff → invoke review
|
||||
- Update docs after shipping → invoke document-release
|
||||
- Weekly retro → invoke retro
|
||||
- Design system, brand → invoke design-consultation
|
||||
- Visual audit, design polish → invoke design-review
|
||||
- Architecture review → invoke plan-eng-review
|
||||
- Save progress, checkpoint, resume → invoke checkpoint
|
||||
- Code quality, health check → invoke health
|
||||
44
llm-wiki/HERMES.md
Normal file
44
llm-wiki/HERMES.md
Normal file
@@ -0,0 +1,44 @@
|
||||
# HERMES.md
|
||||
|
||||
这是 llm-wiki 在 Hermes 下的入口文件。
|
||||
|
||||
先看这三个文件:
|
||||
|
||||
- [README.md](README.md):多平台总说明
|
||||
- [platforms/hermes/README.md](platforms/hermes/README.md):Hermes 专属入口提示
|
||||
- [SKILL.md](SKILL.md):核心能力和工作流
|
||||
|
||||
## Hermes 安装动作
|
||||
|
||||
如果当前任务是安装这个 skill,执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform hermes
|
||||
```
|
||||
|
||||
默认安装到 `~/.hermes/skills/llm-wiki`。
|
||||
|
||||
默认只准备知识库核心主线。如果这次要自动提取网页 / X / 微信公众号 / YouTube / 知乎,再执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform hermes --with-optional-adapters
|
||||
```
|
||||
|
||||
## 重要提醒
|
||||
|
||||
- 不要把这个仓库当成 Hermes 专属仓库;Claude Code、Codex、OpenClaw 也共用同一套核心内容
|
||||
- Hermes 会优先读取仓库根的 `HERMES.md`;这里负责安装入口,知识库能力本身仍以 [SKILL.md](SKILL.md) 为准
|
||||
- 安装完成后,再按 [SKILL.md](SKILL.md) 的工作流继续做事
|
||||
|
||||
## 使用顺序
|
||||
|
||||
安装完成后,按 [SKILL.md](SKILL.md) 中的工作流继续执行:
|
||||
|
||||
1. `init`
|
||||
2. `ingest`
|
||||
3. `batch-ingest`
|
||||
4. `query`
|
||||
5. `digest`
|
||||
6. `lint`
|
||||
7. `status`
|
||||
8. `graph`
|
||||
336
llm-wiki/README.md
Normal file
336
llm-wiki/README.md
Normal file
@@ -0,0 +1,336 @@
|
||||
[English](README.en.md) | 中文
|
||||
|
||||
<div align="center">
|
||||
|
||||
# llm-wiki
|
||||
|
||||
基于 [Andrej Karpathy](https://karpathy.ai/) 的 [llm-wiki 方法论](https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f)
|
||||
|
||||
**更适合国内宝宝体质的 K 神知识库**
|
||||
|
||||
把碎片化的信息变成持续积累、互相链接的知识库
|
||||
|
||||
[](https://github.com/sdyckjq-lab/llm-wiki-skill/releases)
|
||||
[](LICENSE)
|
||||
[]
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 效果预览
|
||||
|
||||
<div align="center">
|
||||
<img src="assets/graph-demo.gif?v=20260428" width="100%" alt="知识图谱演示">
|
||||
</div>
|
||||
|
||||
东方编辑部 × 数字山水风交互式知识图谱 — 双击 HTML 文件即可在浏览器中探索。搜索、社区图例、聚焦筛选、节点视觉分层、社区轻量地图、统一社区抽屉、悬停预览、轻量摘要、明确进入阅读、Shift 多选、画布缩放拖拽和小地图定位,全部离线运行,不依赖服务器。
|
||||
|
||||
---
|
||||
|
||||
## 两种入口
|
||||
|
||||
本仓库是 llm-wiki 的 monorepo,包含两种使用形态,读写同一份知识库格式:
|
||||
|
||||
- **Skill 形态**(成熟稳定):把仓库链接丢给 Claude Code / Codex / OpenClaw / Hermes 一键安装,在你的 AI CLI 里维护知识库。
|
||||
- **agent 工作台**(`workbench/`,开发中):本地运行的知识库工作台,以对话为中心、内置交互式数字山水知识图谱。当前面向开发者(`npm run dev`),成熟后提供桌面应用。
|
||||
|
||||
交互式图谱引擎(`packages/graph-engine/`)由两种形态共享:Skill 的离线 HTML 和工作台的图谱视图,是同一个引擎的两个出口。
|
||||
|
||||
**隐私边界**:知识库文件和离线图谱产物保存在本机;当你让 agent 回答、消化或生成内容时,prompt、选中的引用、检索片段、工具输出和生成产物可能会发送给你配置的模型提供商。API key 不写入 llm-wiki 自己的配置;第三方 Skill 只有显式安装并启用后才作为受信任本地代码运行。
|
||||
|
||||
---
|
||||
|
||||
## 30 秒上手
|
||||
|
||||
把仓库链接扔给你正在用的 agent,让它自己完成安装。
|
||||
|
||||
```bash
|
||||
# Claude Code
|
||||
bash install.sh --platform claude
|
||||
|
||||
# Codex
|
||||
bash install.sh --platform codex
|
||||
|
||||
# OpenClaw
|
||||
bash install.sh --platform openclaw
|
||||
|
||||
# Hermes
|
||||
bash install.sh --platform hermes
|
||||
```
|
||||
|
||||
然后说:
|
||||
|
||||
> "帮我初始化一个知识库"
|
||||
> "帮我消化这篇:<链接>"
|
||||
|
||||
核心区别:知识被**编译一次,持续维护**,而不是每次查询都从原始文档重新推导。
|
||||
|
||||
---
|
||||
|
||||
## 核心亮点
|
||||
|
||||
### Skill 稳定主线
|
||||
|
||||
| | 功能 | 说明 |
|
||||
|---|---|---|
|
||||
| 🗺️ | **数字山水知识图谱** | 自包含 HTML,双击即可浏览;三栏国风布局、山水底图、可拖拽缩放画布、小地图定位和左右阅读区全部离线运行 |
|
||||
| ✨ | **图谱阅读体验打磨** | 节点按地名、索引签条、朱砂批注分层;默认画面更轻,悬停可预览,点击先看摘要,再通过明确动作进入阅读 |
|
||||
| 🎓 | **本地阅读动线** | 社区图例、聚焦筛选、图谱搜索、右侧摘要/阅读抽屉和选区抽屉保持联动;社区阅读内搜索和类型筛选只作用于当前社区 |
|
||||
| 📦 | **零配置初始化** | 一句话创建完整知识库,自动生成目录结构、模板和研究方向页 |
|
||||
| 🔗 | **结构化 Wiki** | 自动生成实体页、主题页、素材摘要,用 `[[双向链接]]` 互相关联 |
|
||||
| 🏷️ | **置信度标注** | EXTRACTED / INFERRED / AMBIGUOUS / UNVERIFIED,一眼看出哪些需要核实 |
|
||||
| 🔄 | **智能缓存** | SHA256 去重 + 写入即更新 + 自愈安全网,弱模型也不会漏缓存 |
|
||||
| 🧠 | **对话结晶** | 把有价值的对话内容直接沉淀为知识库页面 |
|
||||
| 📡 | **自动上下文注入** | SessionStart hook 让 agent 每次会话自动感知知识库 |
|
||||
| 📊 | **多格式分析** | 深度报告、对比表、时间线三种综合分析格式 |
|
||||
|
||||
### 工作台开发预览
|
||||
|
||||
| | 功能 | 说明 |
|
||||
|---|---|---|
|
||||
| 🧮 | **共享绘制策略** | 密度、节点显示、标签与关系预算、稳定骨架和社区层级由一份规则产出;旧工具箱与早期 wash 模板已退休,Sigma 主路线与 DOM/SVG 故障回退使用同一份准备结果,每次更新只计算一次 |
|
||||
| 🧯 | **图谱故障恢复** | 共享结果失败时,工作台和离线图谱都会清掉旧内容并显示明确提示;只有 Sigma 自身故障才进入 DOM/SVG 回退,不会留下可操作的半成品 |
|
||||
| ⚠️ | **图谱身份与告警** | 同名页面按知识库内相对路径分别保留;歧义、断链、待创建和路径冲突会集中提示,图谱仍可阅读,详情只读并按页加载;无效详情也不会把本机绝对路径带入离线文件;只有迁移提示的刷新不会卡在待播放状态 |
|
||||
| 📝 | **图谱安全改名与恢复** | 可从可处理的告警或页面阅读区选择同目录安全改名;提交前查看完整影响并确认全部歧义,外部编辑、意外中断或图谱更新失败后都有明确恢复和重试入口,排队中的图谱更新完成后会自动显示最终结果 |
|
||||
| 🗺️ | **图谱位置与视野连续** | 初始布局、Pin 和实时拖动共同维护同一张地图;远端节点仍在完整内容范围内,社区取景、缩放、平移、重置、窗口变化和小地图保持一致 |
|
||||
| 🧭 | **社区近景地图** | 进入社区后像从全局图靠近刚才那片区域;节点位置、层级和标签更稳定,社区内可多选节点并带入对话,返回全图时高亮会跟随视野稳定后再淡出 |
|
||||
| 🧩 | **全局意图反馈** | 全局图谱悬停节点可轻量看一阶关系,单击节点固定关系强调并打开摘要;选中社区只预览少量内部结构和跨社区通道,不直接变成完整社区阅读 |
|
||||
| 🖱️ | **图谱全区域缩放** | 在桌面上,鼠标停在节点、社区色块、关系或空白处时,滚轮和触摸板都只缩放图谱,不会误缩放浏览器;地图内控件和图谱外页面保持各自应有的行为 |
|
||||
| 🪶 | **图谱增强显示** | 工作台图谱默认已分清主次;需要时可打开语义强调和聚焦点亮,让关键关系更容易看清 |
|
||||
| 🎨 | **工作台 Paper 视觉** | 工作台沿用暖纸配色,按钮、消息、侧栏和图谱控件保持统一,长标题不会撑开页面 |
|
||||
| 💬 | **工作台对话自动跟随** | 发送和流式回复时自动停在最新内容,用户上翻时暂停,并用向下箭头一键回到底部 |
|
||||
| 🧰 | **工作台动态工具状态** | agent 执行工具时显示当前动作;完成后折叠成摘要,避免主对话被工具流水账刷屏 |
|
||||
| 🛡️ | **工作台安全流式状态** | prompt、工具状态、产物和终态使用统一流式契约;检索内容只进入发起它的运行和对话,切换、取消或重复发送不会串用旧内容;模型失败不会显示为完成,图谱断线后会重新取得当前错误或当前图谱,异常流会安全结束并恢复操作 |
|
||||
| / | **工作台检索日志隐私** | 默认检索日志只保留排障所需的会话、知识库、触发状态、结果信息和稳定失败状态,不保存用户提问或可恢复的派生内容 |
|
||||
| 🔒 | **工作台本地访问保护** | 本地配置、对话、页面、图谱事件、文件和状态操作都只对同时通过来源与启动凭证检查的工作台开放 |
|
||||
| 🧷 | **工作台请求边界** | 前台只会发送已登记的请求方式与入口组合;产出物清单和下载统一拒绝不合规编号,文件下载和事件流保持各自独立处理 |
|
||||
| / | **工作台命令清单** | 对话里的 `/` 菜单和设置里的能力统计使用同一套受保护读取;列表不会显示本机能力路径 |
|
||||
| 🔑 | **工作台认证设置** | 保存 API key 和测试连接使用同一套保护与提示;失败不会暴露本机信息、密钥或底层错误 |
|
||||
| 📚 | **工作台知识库创建** | 侧栏可以分别在默认目录新建知识库或添加已有目录;初始化已有目录和批量消化保持独立,取消、重复名称、同名请求正在处理和异常不会暴露本机路径或内部信息 |
|
||||
| ✅ | **工作台可靠启动** | 后台只监听本机,失败启动不会替换现有凭证,重启会换新并恢复上次知识库;退出时会有序结束持续连接和图谱重建进程,必要时再启用兜底清理 |
|
||||
| 🧪 | **工作台真实浏览器检查** | 自动启动真实前台和后台,检查知识库、对话、页面、图谱、消息、产出物、设置与模型的主要流程,以及隔离、取消、断线和失败恢复;线上准备、正式检查、清理和诊断各有明确时限,冷启动不会静默挤掉正式检查;Paper 视觉检查会从页面搜索进入右侧阅读区并确认正文已经显示,也会实际读取产出物、设置和模型,旧结果形状会被明确拒绝;平板打开阅读区时输入区仍保持可用,文字和发送按钮不会重叠 |
|
||||
| 🔎 | **工作台统一质量检查** | 本机与 GitHub 使用同一入口,顺序检查公开内容隐私、前后台、共享规则、图谱、边界、类型、规范和构建,并在隔离环境验证启动与入口反例;图谱交互结束按实际视图提交时点确认,不会因短暂繁忙被提前判定完成 |
|
||||
|
||||
---
|
||||
|
||||
## 素材来源
|
||||
|
||||
| 分类 | 来源 | 处理方式 |
|
||||
|---|---|---|
|
||||
| 核心 | PDF、Markdown、文本、HTML、纯文本粘贴 | 直接消化,不依赖外挂 |
|
||||
| 可选 | 网页文章、X/Twitter、微信公众号、YouTube、知乎 | 自动提取;失败时按回退提示改走手动 |
|
||||
| 手动 | 小红书 | 当前只支持手动粘贴 |
|
||||
|
||||
可选提取器需要在安装时显式开启:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform claude --with-optional-adapters
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 平台入口
|
||||
|
||||
每个平台有专属入口说明:
|
||||
|
||||
- [Claude Code](platforms/claude/CLAUDE.md)
|
||||
- [Codex](platforms/codex/AGENTS.md)
|
||||
- [OpenClaw](platforms/openclaw/README.md)
|
||||
- [Hermes](platforms/hermes/README.md)
|
||||
|
||||
---
|
||||
|
||||
<details>
|
||||
<summary><strong>完整功能列表</strong></summary>
|
||||
|
||||
- **研究方向引导** — `purpose.md` 让 agent 在整理和查询时有明确方向
|
||||
- **两步式整理** — 先分析后生成,长内容走两步链式思考,短内容简化处理
|
||||
- **ingest 格式验证** — 脚本自动校验分析结果,模型再笨也不会写出残缺数据
|
||||
- **智能素材路由** — 根据 URL 域名自动选择最佳提取方式
|
||||
- **核心优先安装** — 默认只准备知识库主线,网页/X/公众号/YouTube/知乎按需显式开启
|
||||
- **伴随升级命令** — Claude Code 安装后自带 `/llm-wiki-upgrade`
|
||||
- **素材删除** — 级联删除时自动清理关联页面、断链和缓存
|
||||
- **图谱坏数据安全兼容** — 未知、残缺或畸形图谱会先整理成可安全使用的结果,节点、关系、社区和起点再由同一份稳定模型交给绘制;重复编号稳定保留第一项并明确提示,自动编号避开已有值,常规搜索仍对应正确页面
|
||||
- **图谱路径身份与告警** — 同名页面按知识库内相对路径分别进入图谱;歧义链接不猜目标,重复编号、断链、待创建、不规范路径和可移植冲突集中显示;告警详情只读、按页读取,首次刷新和 Pin 继续对应正确页面
|
||||
- **图谱安全改名与恢复** — 从可处理的告警或页面阅读区发起可选的同目录改名;完整预览会列出自动更新、只读引用、固定位置和全部歧义,确认后才写入;外部编辑、崩溃和图谱待更新状态可恢复或单独重试,排队中的更新完成后会自动显示最终结果
|
||||
- **图谱搜索与筛选更稳** — 工作台、离线图谱和两种显示路线使用同一份结果;常规搜索保留原有 500 字符范围,Atlas 全文搜索继续覆盖完整正文,类型筛选、社区聚焦和临时显示的节点与关系保持一致;中文、组合字符和 emoji 长标题在旧浏览器环境下也能安全省略并保留完整标题
|
||||
- **图谱共享绘制策略** — 密度、节点显示、标签与关系预算、稳定骨架、社区层级和标签方向由同一份规则产出;模型、布局、可见结果和绘制规则在一次更新中各计算一次,旧工具箱与早期 wash 模板已退休,Sigma 主路线与 DOM/SVG 故障回退使用同一份准备结果,工作台和离线图谱保持一致
|
||||
- **图谱故障恢复** — 工作台首次打开或更新失败时会清空旧图、选择、筛选、Pin 和失败实例;离线创建失败会显示恢复提示并撤掉半成品,存储不可用时仍可阅读,社区选区可继续进入近景阅读;只有共享结果成功后的 Sigma 专属故障才进入 DOM/SVG 回退
|
||||
- **Sigma 图谱主路线** — 全局视角和社区阅读都以 Sigma/Graphology 承接;DOM/SVG 只保留为回退、对照和异常兜底,不再作为社区阅读主路径扩展
|
||||
- **Sigma 迁移前性能基线** — 生产 1k 与隔离 1k/5k/10k 图谱都连续测量三次悬停预览并保存中位数;后续迁移使用固定公式自动比较,其他渲染试验不承担 Sigma 专属门禁
|
||||
- **图谱全区域缩放** — 在桌面上,鼠标停在节点、社区色块、关系或空白处时,滚轮和触摸板都只缩放图谱,不会误缩放浏览器;地图内控件和图谱外页面保持各自应有的行为
|
||||
- **统一社区抽屉** — 普通社区和"未分组"使用同一套概览、固定动作、可展开核心节点和对话入口;"进入社区"放在顶部,未分组默认推荐探索潜在关系
|
||||
- **图谱增强显示** — 工作台图谱默认已分清主次;增强显示面板支持语义强调和聚焦点亮,社区图谱保留原有关系显示和图例
|
||||
- **全局图谱意图反馈** — 在全局视图悬停节点会轻量点亮一阶真实关系,移开恢复且不打开抽屉、不移动镜头;单击节点固定关系强调并打开摘要;选中社区只露出少量内部结构和跨社区桥接上下文,不进入完整社区阅读
|
||||
- **图谱位置与视野连续** — 初始布局不再污染节点内容,实时拖动位置优先于 Pin 和初始位置;类型筛选、临时显示与远端其他社区节点共同决定完整内容范围,社区取景继续按窗口比例扩展,缩放、平移、重置、窗口变化和小地图结果保持一致
|
||||
- **社区近景地图** — 进入社区是一段连续过渡:摘要抽屉退场、画布平滑扩展,镜头从全局社区高亮近景继续推进到社区阅读近景,过渡后落在 Sigma 社区阅读主路径且不重开摘要(减少动态效果下抽屉直接关闭、不做大幅推进);进入社区后沿用 Sigma 主图,只显示当前社区内部节点和关系;节点位置、身份色、边层级和标签预算保持连续,搜索、类型筛选和 Shift 多选只影响当前社区,返回全图时社区高亮会跟随视野稳定后再淡出;社区阅读点“回全图”是一段更短的连续退出过渡,镜头拉回全局构图、保留来源社区高亮,不重开摘要抽屉、不清钉扎位置和全局筛选偏好
|
||||
- **社区阅读关系视觉分层** — 进入社区默认第一眼就能区分结构关系和背景关系:结构跨度选择器只从真实关系里按社区规模分档挑出少量骨架关系,优先串起核心节点和小团块,而不是堆在权重最强的关系上;Sigma 社区阅读主路径让结构关系比背景关系更清楚,关系颜色仍只表达关系类型。沿用明亮、直向的视觉语言,不引入弯曲关系呈现或粗重主干视觉
|
||||
- **社区节点阅读让位** — 社区内单击节点打开右侧阅读抽屉时,画布变窄和镜头让位保持连续;宽屏下节点留在剩余画布的舒适位置,窄屏覆盖或全屏阅读时不强行移动镜头
|
||||
- **选区抽屉查看全部 / 收起** — Shift 多选攒下的选区抽屉默认只显示前 3 个选中页面,超过 3 个可"查看全部",展开后可"收起";继续 Shift 多选保持展开 / 收起状态,抽屉静默实时更新(不重开、不抢焦点、不清补充说明),多选全程不移动镜头
|
||||
- **图谱视野稳定** — 点击社区摘要或重复点击同一位置时,图谱保持原视角,不会被右侧抽屉挤动
|
||||
- **工作台 Paper 视觉** — Paper v2 暖纸配色覆盖工作台默认主题、新对话按钮、消息气泡、侧栏和图谱控件,长标题和长消息保持在页面内部
|
||||
- **查询结果持久化** — 有价值的综合回答可保存回知识库,越用越完整
|
||||
- **批量消化** — 给一个文件夹路径,批量处理所有文件
|
||||
- **工作台事件流更稳** — 批量消化进度和活地图更新都有明确顺序与结束规则;单文件失败可继续,整体失败或取消会明确收口,图谱断线后会确认进入新的连接并重新取得当前错误或当前图谱,异常事件会安全停止或重连
|
||||
- **工作台对话自动跟随** — 发送消息和接收长回复时默认跟随最新内容,用户上翻阅读历史时暂停,并提供图标按钮回到底部
|
||||
- **工作台工具摘要** — `workbench/` 对话区采用 `omp` 风格动态工具状态,停止时显示取消状态,历史工具调用默认折叠为分组摘要
|
||||
- **工作台本地访问保护** — 本地内容和状态操作都要同时通过来源与启动凭证检查,陌生网页不能读取内容或改变工作台状态
|
||||
- **工作台请求边界** — 前台只会发送已登记的请求方式与入口组合;产出物清单和下载统一拒绝不合规编号,文件下载和事件流继续使用各自独立的处理通道
|
||||
- **工作台命令清单** — 对话里的 `/` 菜单和设置里的能力统计使用同一套受保护读取,列表不会显示本机能力路径
|
||||
- **工作台认证设置** — 保存 API key 和测试连接使用同一套保护与提示;失败不会暴露本机信息、密钥或底层错误
|
||||
- **工作台可靠启动** — 正式启动和自动检查走同一套恢复与关闭流程;失败启动不改现有凭证,退出会有序结束持续连接和图谱重建进程并在必要时兜底清理,macOS 与 Linux 检查都会主动阻止真实用户资料读取、临时目录外写入和外网访问
|
||||
- **工作台真实浏览器检查** — 使用一次性用户环境、真实前后台、真实端口、HTTP 和事件流验证七类主要流程,并覆盖隔离、取消、断线、繁忙和失败恢复;线上准备、正式检查、清理和诊断各有明确时限,冷启动不会静默挤掉正式检查;外部模型和系统文件夹选择器由测试边界替代,普通启动和正式构建不包含这些替身
|
||||
- **工作台统一质量检查** — 本机与 GitHub 运行同一套完整检查;前台不会复用过期结果,失败会清理进程并只短期保留经过清理的虚构测试材料
|
||||
- **知识库健康检查** — 脚本检测孤立页面、断链、index 一致性;AI 层面检查矛盾和交叉引用
|
||||
- **ingest 隐私自查** — 首次消化素材时提醒检查手机号、API key 等敏感信息
|
||||
- **图谱关系词汇表** — 可选的手动标注词汇,让图谱表达更精确
|
||||
- **Obsidian 兼容** — 所有内容都是本地 markdown,直接用 Obsidian 打开
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>安装详情</strong></summary>
|
||||
|
||||
### 默认安装位置
|
||||
|
||||
| 平台 | 路径 |
|
||||
|---|---|
|
||||
| Claude Code | `~/.claude/skills/llm-wiki` |
|
||||
| Codex | `~/.codex/skills/llm-wiki` |
|
||||
| OpenClaw | `~/.openclaw/skills/llm-wiki` |
|
||||
| Hermes | `~/.hermes/skills/llm-wiki` |
|
||||
|
||||
### 更新
|
||||
|
||||
已安装?进入仓库目录执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --upgrade
|
||||
```
|
||||
|
||||
自动完成:`git pull` → 检测已安装平台 → 重新复制核心文件 → 已有 hook 不受影响。
|
||||
|
||||
Claude Code 默认安装的,可以直接用 `/llm-wiki-upgrade`。
|
||||
|
||||
自定义目录:
|
||||
|
||||
```bash
|
||||
bash install.sh --upgrade --platform openclaw --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
|
||||
```bash
|
||||
bash install.sh --upgrade --platform hermes --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
|
||||
### 前置条件
|
||||
|
||||
- 核心:agent 能执行 shell 命令、读写本地文件即可;图谱构建和来源信号覆盖检查需要 `jq` + `node`
|
||||
- 可选:微信公众号提取需要 `uv`;网页提取需要 `bun` 或 `npm`;需要登录态的内容可开启 Chrome 调试端口 9222
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>目录结构</strong></summary>
|
||||
|
||||
```
|
||||
你的知识库/
|
||||
├── raw/ # 原始素材(不可变)
|
||||
│ ├── articles/ # 网页文章
|
||||
│ ├── tweets/ # X/Twitter
|
||||
│ ├── wechat/ # 微信公众号
|
||||
│ ├── xiaohongshu/ # 小红书
|
||||
│ ├── zhihu/ # 知乎
|
||||
│ ├── pdfs/ # PDF
|
||||
│ ├── notes/ # 笔记
|
||||
│ └── assets/ # 图片等附件
|
||||
├── wiki/ # AI 生成的知识库
|
||||
│ ├── entities/ # 实体页(人物、概念、工具)
|
||||
│ ├── topics/ # 主题页
|
||||
│ ├── sources/ # 素材摘要
|
||||
│ ├── comparisons/ # 对比分析
|
||||
│ ├── synthesis/ # 综合分析
|
||||
│ │ └── sessions/ # 对话结晶页面
|
||||
│ └── queries/ # 保存的查询结果
|
||||
├── purpose.md # 研究方向与目标
|
||||
├── index.md # 索引
|
||||
├── log.md # 操作日志
|
||||
├── .wiki-schema.md # 配置
|
||||
└── .wiki-cache.json # 素材去重缓存
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>常见问题</strong></summary>
|
||||
|
||||
**这个仓库还是只给 Claude 用吗?**
|
||||
不是。Claude 只是其中一个入口。同一个链接能被 Claude Code、Codex、OpenClaw、Hermes 安装和使用。
|
||||
|
||||
**为什么 Hermes 要看 `HERMES.md`?**
|
||||
Hermes 会优先加载仓库根的 `HERMES.md` 作为项目上下文。这个文件只负责 Hermes 的入口与安装说明,核心能力和工作流仍以 `SKILL.md` 为准。
|
||||
|
||||
**Claude Code 里可以直接用命令更新吗?**
|
||||
可以。默认安装后自带 `/llm-wiki-upgrade`,更新核心主线。需要网页/X/公众号/YouTube/知乎提取能力时,再加 `--with-optional-adapters`。
|
||||
|
||||
**X/Twitter 提取失败?**
|
||||
确保已安装可选提取器(`--with-optional-adapters`)。需要登录态的内容请开启 Chrome 调试端口 9222,或者直接粘贴内容给 agent。
|
||||
|
||||
**公众号提取失败?**
|
||||
需要 `uv`。安装后重新运行 `bash install.sh --platform <你的平台> --with-optional-adapters`。
|
||||
|
||||
</details>
|
||||
|
||||
## Windows 用户
|
||||
|
||||
Windows PowerShell 5.1(Win10 / Win11 系统自带)默认 console 编码为 GB2312、`$OutputEncoding` 为 ASCII,Python 子进程 `sys.stdout.encoding` 默认为 `gbk`。直接在 PS 5.1 下运行 `bash install.sh` 会导致中文输出和 hook JSON 出现乱码([#16](https://github.com/sdyckjq-lab/llm-wiki-skill/issues/16))。
|
||||
|
||||
**方案 A — 使用 `install.ps1`(推荐)**
|
||||
|
||||
在仓库根目录下:
|
||||
|
||||
```powershell
|
||||
powershell -ExecutionPolicy Bypass -File install.ps1 --platform claude
|
||||
powershell -ExecutionPolicy Bypass -File install.ps1 --platform codex --dry-run
|
||||
```
|
||||
|
||||
`install.ps1` 会自动把 console / `$OutputEncoding` / `PYTHONIOENCODING` 全部设为 UTF-8,再转发到 `bash install.sh`。
|
||||
|
||||
**方案 B — 手动设置 PowerShell 编码**
|
||||
|
||||
```powershell
|
||||
chcp 65001
|
||||
[Console]::OutputEncoding = [System.Text.Encoding]::UTF8
|
||||
$OutputEncoding = [System.Text.Encoding]::UTF8
|
||||
$env:PYTHONIOENCODING = 'utf-8'
|
||||
bash install.sh --platform claude
|
||||
```
|
||||
|
||||
**方案 C — 升级到 PowerShell 7+**
|
||||
|
||||
PowerShell 7 默认 UTF-8。安装:`winget install Microsoft.PowerShell`,然后 `pwsh` 下直接 `bash install.sh --platform claude`。
|
||||
|
||||
### Python 命令
|
||||
|
||||
Windows 上 Python 通常安装为 `python.exe` 而非 `python3.exe`(Microsoft Store 的 `python3` 是安装提示 stub,调用会失败)。本项目 `scripts/shared-config.sh` 已加入自动检测:**先尝试 `python3`,失败回退到 `python`**。所以只要 Python 3.8+ 在 PATH 中(任一命名即可),脚本能正常工作。
|
||||
|
||||
---
|
||||
|
||||
## 致谢
|
||||
|
||||
本项目复用和集成了以下开源项目:
|
||||
|
||||
- **[Andrej Karpathy](https://karpathy.ai/)** — [llm-wiki gist](https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f),核心方法论来源
|
||||
- **[baoyu-url-to-markdown](https://github.com/JimLiu/baoyu-skills#baoyu-url-to-markdown)** by [JimLiu](https://github.com/JimLiu) — 网页、X/Twitter 内容提取
|
||||
- **youtube-transcript** — YouTube 字幕提取
|
||||
- **[wechat-article-to-markdown](https://github.com/jackwener/wechat-article-to-markdown)** — 微信公众号文章提取
|
||||
|
||||
## License
|
||||
|
||||
MIT
|
||||
|
||||
---
|
||||
|
||||
## Star History
|
||||
|
||||
[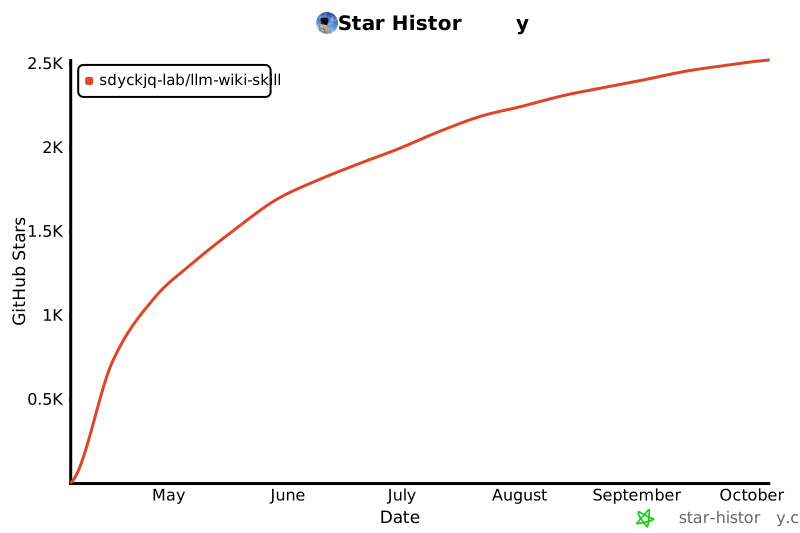](https://www.star-history.com/?repos=sdyckjq-lab%2Fllm-wiki-skill&type=date)
|
||||
1136
llm-wiki/SKILL.md
Normal file
1136
llm-wiki/SKILL.md
Normal file
File diff suppressed because it is too large
Load Diff
13
llm-wiki/deps/LICENSE-d3.txt
Normal file
13
llm-wiki/deps/LICENSE-d3.txt
Normal file
@@ -0,0 +1,13 @@
|
||||
Copyright 2010-2023 Mike Bostock
|
||||
|
||||
Permission to use, copy, modify, and/or distribute this software for any purpose
|
||||
with or without fee is hereby granted, provided that the above copyright notice
|
||||
and this permission notice appear in all copies.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS" AND THE AUTHOR DISCLAIMS ALL WARRANTIES WITH
|
||||
REGARD TO THIS SOFTWARE INCLUDING ALL IMPLIED WARRANTIES OF MERCHANTABILITY AND
|
||||
FITNESS. IN NO EVENT SHALL THE AUTHOR BE LIABLE FOR ANY SPECIAL, DIRECT,
|
||||
INDIRECT, OR CONSEQUENTIAL DAMAGES OR ANY DAMAGES WHATSOEVER RESULTING FROM LOSS
|
||||
OF USE, DATA OR PROFITS, WHETHER IN AN ACTION OF CONTRACT, NEGLIGENCE OR OTHER
|
||||
TORTIOUS ACTION, ARISING OUT OF OR IN CONNECTION WITH THE USE OR PERFORMANCE OF
|
||||
THIS SOFTWARE.
|
||||
44
llm-wiki/deps/LICENSE-marked.txt
Normal file
44
llm-wiki/deps/LICENSE-marked.txt
Normal file
@@ -0,0 +1,44 @@
|
||||
# License information
|
||||
|
||||
## Contribution License Agreement
|
||||
|
||||
If you contribute code to this project, you are implicitly allowing your code
|
||||
to be distributed under the MIT license. You are also implicitly verifying that
|
||||
all code is your original work. `</legalese>`
|
||||
|
||||
## Marked
|
||||
|
||||
Copyright (c) 2018+, MarkedJS (https://github.com/markedjs/)
|
||||
Copyright (c) 2011-2018, Christopher Jeffrey (https://github.com/chjj/)
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in
|
||||
all copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN
|
||||
THE SOFTWARE.
|
||||
|
||||
## Markdown
|
||||
|
||||
Copyright © 2004, John Gruber
|
||||
http://daringfireball.net/
|
||||
All rights reserved.
|
||||
|
||||
Redistribution and use in source and binary forms, with or without modification, are permitted provided that the following conditions are met:
|
||||
|
||||
* Redistributions of source code must retain the above copyright notice, this list of conditions and the following disclaimer.
|
||||
* Redistributions in binary form must reproduce the above copyright notice, this list of conditions and the following disclaimer in the documentation and/or other materials provided with the distribution.
|
||||
* Neither the name “Markdown” nor the names of its contributors may be used to endorse or promote products derived from this software without specific prior written permission.
|
||||
|
||||
This software is provided by the copyright holders and contributors “as is” and any express or implied warranties, including, but not limited to, the implied warranties of merchantability and fitness for a particular purpose are disclaimed. In no event shall the copyright owner or contributors be liable for any direct, indirect, incidental, special, exemplary, or consequential damages (including, but not limited to, procurement of substitute goods or services; loss of use, data, or profits; or business interruption) however caused and on any theory of liability, whether in contract, strict liability, or tort (including negligence or otherwise) arising in any way out of the use of this software, even if advised of the possibility of such damage.
|
||||
568
llm-wiki/deps/LICENSE-purify.txt
Normal file
568
llm-wiki/deps/LICENSE-purify.txt
Normal file
@@ -0,0 +1,568 @@
|
||||
DOMPurify
|
||||
Copyright 2024 Dr.-Ing. Mario Heiderich, Cure53
|
||||
|
||||
DOMPurify is free software; you can redistribute it and/or modify it under the
|
||||
terms of either:
|
||||
|
||||
a) the Apache License Version 2.0, or
|
||||
b) the Mozilla Public License Version 2.0
|
||||
|
||||
-----------------------------------------------------------------------------
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
-----------------------------------------------------------------------------
|
||||
Mozilla Public License, version 2.0
|
||||
|
||||
1. Definitions
|
||||
|
||||
1.1. “Contributor”
|
||||
|
||||
means each individual or legal entity that creates, contributes to the
|
||||
creation of, or owns Covered Software.
|
||||
|
||||
1.2. “Contributor Version”
|
||||
|
||||
means the combination of the Contributions of others (if any) used by a
|
||||
Contributor and that particular Contributor’s Contribution.
|
||||
|
||||
1.3. “Contribution”
|
||||
|
||||
means Covered Software of a particular Contributor.
|
||||
|
||||
1.4. “Covered Software”
|
||||
|
||||
means Source Code Form to which the initial Contributor has attached the
|
||||
notice in Exhibit A, the Executable Form of such Source Code Form, and
|
||||
Modifications of such Source Code Form, in each case including portions
|
||||
thereof.
|
||||
|
||||
1.5. “Incompatible With Secondary Licenses”
|
||||
means
|
||||
|
||||
a. that the initial Contributor has attached the notice described in
|
||||
Exhibit B to the Covered Software; or
|
||||
|
||||
b. that the Covered Software was made available under the terms of version
|
||||
1.1 or earlier of the License, but not also under the terms of a
|
||||
Secondary License.
|
||||
|
||||
1.6. “Executable Form”
|
||||
|
||||
means any form of the work other than Source Code Form.
|
||||
|
||||
1.7. “Larger Work”
|
||||
|
||||
means a work that combines Covered Software with other material, in a separate
|
||||
file or files, that is not Covered Software.
|
||||
|
||||
1.8. “License”
|
||||
|
||||
means this document.
|
||||
|
||||
1.9. “Licensable”
|
||||
|
||||
means having the right to grant, to the maximum extent possible, whether at the
|
||||
time of the initial grant or subsequently, any and all of the rights conveyed by
|
||||
this License.
|
||||
|
||||
1.10. “Modifications”
|
||||
|
||||
means any of the following:
|
||||
|
||||
a. any file in Source Code Form that results from an addition to, deletion
|
||||
from, or modification of the contents of Covered Software; or
|
||||
|
||||
b. any new file in Source Code Form that contains any Covered Software.
|
||||
|
||||
1.11. “Patent Claims” of a Contributor
|
||||
|
||||
means any patent claim(s), including without limitation, method, process,
|
||||
and apparatus claims, in any patent Licensable by such Contributor that
|
||||
would be infringed, but for the grant of the License, by the making,
|
||||
using, selling, offering for sale, having made, import, or transfer of
|
||||
either its Contributions or its Contributor Version.
|
||||
|
||||
1.12. “Secondary License”
|
||||
|
||||
means either the GNU General Public License, Version 2.0, the GNU Lesser
|
||||
General Public License, Version 2.1, the GNU Affero General Public
|
||||
License, Version 3.0, or any later versions of those licenses.
|
||||
|
||||
1.13. “Source Code Form”
|
||||
|
||||
means the form of the work preferred for making modifications.
|
||||
|
||||
1.14. “You” (or “Your”)
|
||||
|
||||
means an individual or a legal entity exercising rights under this
|
||||
License. For legal entities, “You” includes any entity that controls, is
|
||||
controlled by, or is under common control with You. For purposes of this
|
||||
definition, “control” means (a) the power, direct or indirect, to cause
|
||||
the direction or management of such entity, whether by contract or
|
||||
otherwise, or (b) ownership of more than fifty percent (50%) of the
|
||||
outstanding shares or beneficial ownership of such entity.
|
||||
|
||||
|
||||
2. License Grants and Conditions
|
||||
|
||||
2.1. Grants
|
||||
|
||||
Each Contributor hereby grants You a world-wide, royalty-free,
|
||||
non-exclusive license:
|
||||
|
||||
a. under intellectual property rights (other than patent or trademark)
|
||||
Licensable by such Contributor to use, reproduce, make available,
|
||||
modify, display, perform, distribute, and otherwise exploit its
|
||||
Contributions, either on an unmodified basis, with Modifications, or as
|
||||
part of a Larger Work; and
|
||||
|
||||
b. under Patent Claims of such Contributor to make, use, sell, offer for
|
||||
sale, have made, import, and otherwise transfer either its Contributions
|
||||
or its Contributor Version.
|
||||
|
||||
2.2. Effective Date
|
||||
|
||||
The licenses granted in Section 2.1 with respect to any Contribution become
|
||||
effective for each Contribution on the date the Contributor first distributes
|
||||
such Contribution.
|
||||
|
||||
2.3. Limitations on Grant Scope
|
||||
|
||||
The licenses granted in this Section 2 are the only rights granted under this
|
||||
License. No additional rights or licenses will be implied from the distribution
|
||||
or licensing of Covered Software under this License. Notwithstanding Section
|
||||
2.1(b) above, no patent license is granted by a Contributor:
|
||||
|
||||
a. for any code that a Contributor has removed from Covered Software; or
|
||||
|
||||
b. for infringements caused by: (i) Your and any other third party’s
|
||||
modifications of Covered Software, or (ii) the combination of its
|
||||
Contributions with other software (except as part of its Contributor
|
||||
Version); or
|
||||
|
||||
c. under Patent Claims infringed by Covered Software in the absence of its
|
||||
Contributions.
|
||||
|
||||
This License does not grant any rights in the trademarks, service marks, or
|
||||
logos of any Contributor (except as may be necessary to comply with the
|
||||
notice requirements in Section 3.4).
|
||||
|
||||
2.4. Subsequent Licenses
|
||||
|
||||
No Contributor makes additional grants as a result of Your choice to
|
||||
distribute the Covered Software under a subsequent version of this License
|
||||
(see Section 10.2) or under the terms of a Secondary License (if permitted
|
||||
under the terms of Section 3.3).
|
||||
|
||||
2.5. Representation
|
||||
|
||||
Each Contributor represents that the Contributor believes its Contributions
|
||||
are its original creation(s) or it has sufficient rights to grant the
|
||||
rights to its Contributions conveyed by this License.
|
||||
|
||||
2.6. Fair Use
|
||||
|
||||
This License is not intended to limit any rights You have under applicable
|
||||
copyright doctrines of fair use, fair dealing, or other equivalents.
|
||||
|
||||
2.7. Conditions
|
||||
|
||||
Sections 3.1, 3.2, 3.3, and 3.4 are conditions of the licenses granted in
|
||||
Section 2.1.
|
||||
|
||||
|
||||
3. Responsibilities
|
||||
|
||||
3.1. Distribution of Source Form
|
||||
|
||||
All distribution of Covered Software in Source Code Form, including any
|
||||
Modifications that You create or to which You contribute, must be under the
|
||||
terms of this License. You must inform recipients that the Source Code Form
|
||||
of the Covered Software is governed by the terms of this License, and how
|
||||
they can obtain a copy of this License. You may not attempt to alter or
|
||||
restrict the recipients’ rights in the Source Code Form.
|
||||
|
||||
3.2. Distribution of Executable Form
|
||||
|
||||
If You distribute Covered Software in Executable Form then:
|
||||
|
||||
a. such Covered Software must also be made available in Source Code Form,
|
||||
as described in Section 3.1, and You must inform recipients of the
|
||||
Executable Form how they can obtain a copy of such Source Code Form by
|
||||
reasonable means in a timely manner, at a charge no more than the cost
|
||||
of distribution to the recipient; and
|
||||
|
||||
b. You may distribute such Executable Form under the terms of this License,
|
||||
or sublicense it under different terms, provided that the license for
|
||||
the Executable Form does not attempt to limit or alter the recipients’
|
||||
rights in the Source Code Form under this License.
|
||||
|
||||
3.3. Distribution of a Larger Work
|
||||
|
||||
You may create and distribute a Larger Work under terms of Your choice,
|
||||
provided that You also comply with the requirements of this License for the
|
||||
Covered Software. If the Larger Work is a combination of Covered Software
|
||||
with a work governed by one or more Secondary Licenses, and the Covered
|
||||
Software is not Incompatible With Secondary Licenses, this License permits
|
||||
You to additionally distribute such Covered Software under the terms of
|
||||
such Secondary License(s), so that the recipient of the Larger Work may, at
|
||||
their option, further distribute the Covered Software under the terms of
|
||||
either this License or such Secondary License(s).
|
||||
|
||||
3.4. Notices
|
||||
|
||||
You may not remove or alter the substance of any license notices (including
|
||||
copyright notices, patent notices, disclaimers of warranty, or limitations
|
||||
of liability) contained within the Source Code Form of the Covered
|
||||
Software, except that You may alter any license notices to the extent
|
||||
required to remedy known factual inaccuracies.
|
||||
|
||||
3.5. Application of Additional Terms
|
||||
|
||||
You may choose to offer, and to charge a fee for, warranty, support,
|
||||
indemnity or liability obligations to one or more recipients of Covered
|
||||
Software. However, You may do so only on Your own behalf, and not on behalf
|
||||
of any Contributor. You must make it absolutely clear that any such
|
||||
warranty, support, indemnity, or liability obligation is offered by You
|
||||
alone, and You hereby agree to indemnify every Contributor for any
|
||||
liability incurred by such Contributor as a result of warranty, support,
|
||||
indemnity or liability terms You offer. You may include additional
|
||||
disclaimers of warranty and limitations of liability specific to any
|
||||
jurisdiction.
|
||||
|
||||
4. Inability to Comply Due to Statute or Regulation
|
||||
|
||||
If it is impossible for You to comply with any of the terms of this License
|
||||
with respect to some or all of the Covered Software due to statute, judicial
|
||||
order, or regulation then You must: (a) comply with the terms of this License
|
||||
to the maximum extent possible; and (b) describe the limitations and the code
|
||||
they affect. Such description must be placed in a text file included with all
|
||||
distributions of the Covered Software under this License. Except to the
|
||||
extent prohibited by statute or regulation, such description must be
|
||||
sufficiently detailed for a recipient of ordinary skill to be able to
|
||||
understand it.
|
||||
|
||||
5. Termination
|
||||
|
||||
5.1. The rights granted under this License will terminate automatically if You
|
||||
fail to comply with any of its terms. However, if You become compliant,
|
||||
then the rights granted under this License from a particular Contributor
|
||||
are reinstated (a) provisionally, unless and until such Contributor
|
||||
explicitly and finally terminates Your grants, and (b) on an ongoing basis,
|
||||
if such Contributor fails to notify You of the non-compliance by some
|
||||
reasonable means prior to 60 days after You have come back into compliance.
|
||||
Moreover, Your grants from a particular Contributor are reinstated on an
|
||||
ongoing basis if such Contributor notifies You of the non-compliance by
|
||||
some reasonable means, this is the first time You have received notice of
|
||||
non-compliance with this License from such Contributor, and You become
|
||||
compliant prior to 30 days after Your receipt of the notice.
|
||||
|
||||
5.2. If You initiate litigation against any entity by asserting a patent
|
||||
infringement claim (excluding declaratory judgment actions, counter-claims,
|
||||
and cross-claims) alleging that a Contributor Version directly or
|
||||
indirectly infringes any patent, then the rights granted to You by any and
|
||||
all Contributors for the Covered Software under Section 2.1 of this License
|
||||
shall terminate.
|
||||
|
||||
5.3. In the event of termination under Sections 5.1 or 5.2 above, all end user
|
||||
license agreements (excluding distributors and resellers) which have been
|
||||
validly granted by You or Your distributors under this License prior to
|
||||
termination shall survive termination.
|
||||
|
||||
6. Disclaimer of Warranty
|
||||
|
||||
Covered Software is provided under this License on an “as is” basis, without
|
||||
warranty of any kind, either expressed, implied, or statutory, including,
|
||||
without limitation, warranties that the Covered Software is free of defects,
|
||||
merchantable, fit for a particular purpose or non-infringing. The entire
|
||||
risk as to the quality and performance of the Covered Software is with You.
|
||||
Should any Covered Software prove defective in any respect, You (not any
|
||||
Contributor) assume the cost of any necessary servicing, repair, or
|
||||
correction. This disclaimer of warranty constitutes an essential part of this
|
||||
License. No use of any Covered Software is authorized under this License
|
||||
except under this disclaimer.
|
||||
|
||||
7. Limitation of Liability
|
||||
|
||||
Under no circumstances and under no legal theory, whether tort (including
|
||||
negligence), contract, or otherwise, shall any Contributor, or anyone who
|
||||
distributes Covered Software as permitted above, be liable to You for any
|
||||
direct, indirect, special, incidental, or consequential damages of any
|
||||
character including, without limitation, damages for lost profits, loss of
|
||||
goodwill, work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses, even if such party shall have been
|
||||
informed of the possibility of such damages. This limitation of liability
|
||||
shall not apply to liability for death or personal injury resulting from such
|
||||
party’s negligence to the extent applicable law prohibits such limitation.
|
||||
Some jurisdictions do not allow the exclusion or limitation of incidental or
|
||||
consequential damages, so this exclusion and limitation may not apply to You.
|
||||
|
||||
8. Litigation
|
||||
|
||||
Any litigation relating to this License may be brought only in the courts of
|
||||
a jurisdiction where the defendant maintains its principal place of business
|
||||
and such litigation shall be governed by laws of that jurisdiction, without
|
||||
reference to its conflict-of-law provisions. Nothing in this Section shall
|
||||
prevent a party’s ability to bring cross-claims or counter-claims.
|
||||
|
||||
9. Miscellaneous
|
||||
|
||||
This License represents the complete agreement concerning the subject matter
|
||||
hereof. If any provision of this License is held to be unenforceable, such
|
||||
provision shall be reformed only to the extent necessary to make it
|
||||
enforceable. Any law or regulation which provides that the language of a
|
||||
contract shall be construed against the drafter shall not be used to construe
|
||||
this License against a Contributor.
|
||||
|
||||
|
||||
10. Versions of the License
|
||||
|
||||
10.1. New Versions
|
||||
|
||||
Mozilla Foundation is the license steward. Except as provided in Section
|
||||
10.3, no one other than the license steward has the right to modify or
|
||||
publish new versions of this License. Each version will be given a
|
||||
distinguishing version number.
|
||||
|
||||
10.2. Effect of New Versions
|
||||
|
||||
You may distribute the Covered Software under the terms of the version of
|
||||
the License under which You originally received the Covered Software, or
|
||||
under the terms of any subsequent version published by the license
|
||||
steward.
|
||||
|
||||
10.3. Modified Versions
|
||||
|
||||
If you create software not governed by this License, and you want to
|
||||
create a new license for such software, you may create and use a modified
|
||||
version of this License if you rename the license and remove any
|
||||
references to the name of the license steward (except to note that such
|
||||
modified license differs from this License).
|
||||
|
||||
10.4. Distributing Source Code Form that is Incompatible With Secondary Licenses
|
||||
If You choose to distribute Source Code Form that is Incompatible With
|
||||
Secondary Licenses under the terms of this version of the License, the
|
||||
notice described in Exhibit B of this License must be attached.
|
||||
|
||||
Exhibit A - Source Code Form License Notice
|
||||
|
||||
This Source Code Form is subject to the
|
||||
terms of the Mozilla Public License, v.
|
||||
2.0. If a copy of the MPL was not
|
||||
distributed with this file, You can
|
||||
obtain one at
|
||||
http://mozilla.org/MPL/2.0/.
|
||||
|
||||
If it is not possible or desirable to put the notice in a particular file, then
|
||||
You may include the notice in a location (such as a LICENSE file in a relevant
|
||||
directory) where a recipient would be likely to look for such a notice.
|
||||
|
||||
You may add additional accurate notices of copyright ownership.
|
||||
|
||||
Exhibit B - “Incompatible With Secondary Licenses” Notice
|
||||
|
||||
This Source Code Form is “Incompatible
|
||||
With Secondary Licenses”, as defined by
|
||||
the Mozilla Public License, v. 2.0.
|
||||
|
||||
21
llm-wiki/deps/LICENSE-roughjs.txt
Normal file
21
llm-wiki/deps/LICENSE-roughjs.txt
Normal file
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2019 Preet Shihn
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
39
llm-wiki/deps/LICENSE-unicode.txt
Normal file
39
llm-wiki/deps/LICENSE-unicode.txt
Normal file
@@ -0,0 +1,39 @@
|
||||
UNICODE LICENSE V3
|
||||
|
||||
COPYRIGHT AND PERMISSION NOTICE
|
||||
|
||||
Copyright © 1991-2026 Unicode, Inc.
|
||||
|
||||
NOTICE TO USER: Carefully read the following legal agreement. BY
|
||||
DOWNLOADING, INSTALLING, COPYING OR OTHERWISE USING DATA FILES, AND/OR
|
||||
SOFTWARE, YOU UNEQUIVOCALLY ACCEPT, AND AGREE TO BE BOUND BY, ALL OF THE
|
||||
TERMS AND CONDITIONS OF THIS AGREEMENT. IF YOU DO NOT AGREE, DO NOT
|
||||
DOWNLOAD, INSTALL, COPY, DISTRIBUTE OR USE THE DATA FILES OR SOFTWARE.
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a
|
||||
copy of data files and any associated documentation (the "Data Files") or
|
||||
software and any associated documentation (the "Software") to deal in the
|
||||
Data Files or Software without restriction, including without limitation
|
||||
the rights to use, copy, modify, merge, publish, distribute, and/or sell
|
||||
copies of the Data Files or Software, and to permit persons to whom the
|
||||
Data Files or Software are furnished to do so, provided that either (a)
|
||||
this copyright and permission notice appear with all copies of the Data
|
||||
Files or Software, or (b) this copyright and permission notice appear in
|
||||
associated Documentation.
|
||||
|
||||
THE DATA FILES AND SOFTWARE ARE PROVIDED "AS IS", WITHOUT WARRANTY OF ANY
|
||||
KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT OF
|
||||
THIRD PARTY RIGHTS.
|
||||
|
||||
IN NO EVENT SHALL THE COPYRIGHT HOLDER OR HOLDERS INCLUDED IN THIS NOTICE
|
||||
BE LIABLE FOR ANY CLAIM, OR ANY SPECIAL INDIRECT OR CONSEQUENTIAL DAMAGES,
|
||||
OR ANY DAMAGES WHATSOEVER RESULTING FROM LOSS OF USE, DATA OR PROFITS,
|
||||
WHETHER IN AN ACTION OF CONTRACT, NEGLIGENCE OR OTHER TORTIOUS ACTION,
|
||||
ARISING OUT OF OR IN CONNECTION WITH THE USE OR PERFORMANCE OF THE DATA
|
||||
FILES OR SOFTWARE.
|
||||
|
||||
Except as contained in this notice, the name of a copyright holder shall
|
||||
not be used in advertising or otherwise to promote the sale, use or other
|
||||
dealings in these Data Files or Software without prior written
|
||||
authorization of the copyright holder.
|
||||
261
llm-wiki/deps/baoyu-url-to-markdown/SKILL.md
Normal file
261
llm-wiki/deps/baoyu-url-to-markdown/SKILL.md
Normal file
@@ -0,0 +1,261 @@
|
||||
---
|
||||
name: baoyu-url-to-markdown
|
||||
description: Fetch any URL and convert to markdown using Chrome CDP. Saves the rendered HTML snapshot alongside the markdown, uses an upgraded Defuddle pipeline with better web-component handling and YouTube transcript extraction, and automatically falls back to the pre-Defuddle HTML-to-Markdown pipeline when needed. If local browser capture fails entirely, it can fall back to the hosted defuddle.md API. Supports two modes - auto-capture on page load, or wait for user signal (for pages requiring login). Use when user wants to save a webpage as markdown.
|
||||
version: 1.58.1
|
||||
metadata:
|
||||
openclaw:
|
||||
homepage: https://github.com/JimLiu/baoyu-skills#baoyu-url-to-markdown
|
||||
requires:
|
||||
anyBins:
|
||||
- bun
|
||||
- npx
|
||||
---
|
||||
|
||||
# URL to Markdown
|
||||
|
||||
Fetches any URL via Chrome CDP, saves the rendered HTML snapshot, and converts it to clean markdown.
|
||||
|
||||
## Script Directory
|
||||
|
||||
**Important**: All scripts are located in the `scripts/` subdirectory of this skill.
|
||||
|
||||
**Agent Execution Instructions**:
|
||||
1. Determine this SKILL.md file's directory path as `{baseDir}`
|
||||
2. Script path = `{baseDir}/scripts/<script-name>.ts`
|
||||
3. Resolve `${BUN_X}` runtime: if `bun` installed → `bun`; if `npx` available → `npx -y bun`; else suggest installing bun
|
||||
4. Replace all `{baseDir}` and `${BUN_X}` in this document with actual values
|
||||
|
||||
**Script Reference**:
|
||||
| Script | Purpose |
|
||||
|--------|---------|
|
||||
| `scripts/main.ts` | CLI entry point for URL fetching |
|
||||
| `scripts/html-to-markdown.ts` | Markdown conversion entry point and converter selection |
|
||||
| `scripts/defuddle-converter.ts` | Defuddle-based conversion |
|
||||
| `scripts/legacy-converter.ts` | Pre-Defuddle legacy extraction and markdown conversion |
|
||||
| `scripts/markdown-conversion-shared.ts` | Shared metadata parsing and markdown document helpers |
|
||||
|
||||
## Preferences (EXTEND.md)
|
||||
|
||||
Check EXTEND.md existence (priority order):
|
||||
|
||||
```bash
|
||||
# macOS, Linux, WSL, Git Bash
|
||||
test -f .baoyu-skills/baoyu-url-to-markdown/EXTEND.md && echo "project"
|
||||
test -f "${XDG_CONFIG_HOME:-$HOME/.config}/baoyu-skills/baoyu-url-to-markdown/EXTEND.md" && echo "xdg"
|
||||
test -f "$HOME/.baoyu-skills/baoyu-url-to-markdown/EXTEND.md" && echo "user"
|
||||
```
|
||||
|
||||
```powershell
|
||||
# PowerShell (Windows)
|
||||
if (Test-Path .baoyu-skills/baoyu-url-to-markdown/EXTEND.md) { "project" }
|
||||
$xdg = if ($env:XDG_CONFIG_HOME) { $env:XDG_CONFIG_HOME } else { "$HOME/.config" }
|
||||
if (Test-Path "$xdg/baoyu-skills/baoyu-url-to-markdown/EXTEND.md") { "xdg" }
|
||||
if (Test-Path "$HOME/.baoyu-skills/baoyu-url-to-markdown/EXTEND.md") { "user" }
|
||||
```
|
||||
|
||||
┌────────────────────────────────────────────────────────┬───────────────────┐
|
||||
│ Path │ Location │
|
||||
├────────────────────────────────────────────────────────┼───────────────────┤
|
||||
│ .baoyu-skills/baoyu-url-to-markdown/EXTEND.md │ Project directory │
|
||||
├────────────────────────────────────────────────────────┼───────────────────┤
|
||||
│ $HOME/.baoyu-skills/baoyu-url-to-markdown/EXTEND.md │ User home │
|
||||
└────────────────────────────────────────────────────────┴───────────────────┘
|
||||
|
||||
┌───────────┬───────────────────────────────────────────────────────────────────────────┐
|
||||
│ Result │ Action │
|
||||
├───────────┼───────────────────────────────────────────────────────────────────────────┤
|
||||
│ Found │ Read, parse, apply settings │
|
||||
├───────────┼───────────────────────────────────────────────────────────────────────────┤
|
||||
│ Not found │ **MUST** run first-time setup (see below) — do NOT silently create defaults │
|
||||
└───────────┴───────────────────────────────────────────────────────────────────────────┘
|
||||
|
||||
**EXTEND.md Supports**: Download media by default | Default output directory | Default capture mode | Timeout settings
|
||||
|
||||
### First-Time Setup (BLOCKING)
|
||||
|
||||
**CRITICAL**: When EXTEND.md is not found, you **MUST use `AskUserQuestion`** to ask the user for their preferences before creating EXTEND.md. **NEVER** create EXTEND.md with defaults without asking. This is a **BLOCKING** operation — do NOT proceed with any conversion until setup is complete.
|
||||
|
||||
Use `AskUserQuestion` with ALL questions in ONE call:
|
||||
|
||||
**Question 1** — header: "Media", question: "How to handle images and videos in pages?"
|
||||
- "Ask each time (Recommended)" — After saving markdown, ask whether to download media
|
||||
- "Always download" — Always download media to local imgs/ and videos/ directories
|
||||
- "Never download" — Keep original remote URLs in markdown
|
||||
|
||||
**Question 2** — header: "Output", question: "Default output directory?"
|
||||
- "url-to-markdown (Recommended)" — Save to ./url-to-markdown/{domain}/{slug}.md
|
||||
- (User may choose "Other" to type a custom path)
|
||||
|
||||
**Question 3** — header: "Save", question: "Where to save preferences?"
|
||||
- "User (Recommended)" — ~/.baoyu-skills/ (all projects)
|
||||
- "Project" — .baoyu-skills/ (this project only)
|
||||
|
||||
After user answers, create EXTEND.md at the chosen location, confirm "Preferences saved to [path]", then continue.
|
||||
|
||||
Full reference: [references/config/first-time-setup.md](references/config/first-time-setup.md)
|
||||
|
||||
### Supported Keys
|
||||
|
||||
| Key | Default | Values | Description |
|
||||
|-----|---------|--------|-------------|
|
||||
| `download_media` | `ask` | `ask` / `1` / `0` | `ask` = prompt each time, `1` = always download, `0` = never |
|
||||
| `default_output_dir` | empty | path or empty | Default output directory (empty = `./url-to-markdown/`) |
|
||||
|
||||
**EXTEND.md → CLI mapping**:
|
||||
| EXTEND.md key | CLI argument | Notes |
|
||||
|---------------|-------------|-------|
|
||||
| `download_media: 1` | `--download-media` | |
|
||||
| `default_output_dir: ./posts/` | `--output-dir ./posts/` | Directory path. Do NOT pass to `-o` (which expects a file path) |
|
||||
|
||||
**Value priority**:
|
||||
1. CLI arguments (`--download-media`, `-o`, `--output-dir`)
|
||||
2. EXTEND.md
|
||||
3. Skill defaults
|
||||
|
||||
## Features
|
||||
|
||||
- Chrome CDP for full JavaScript rendering
|
||||
- Two capture modes: auto or wait-for-user
|
||||
- Save rendered HTML as a sibling `-captured.html` file
|
||||
- Clean markdown output with metadata
|
||||
- Upgraded Defuddle-first markdown conversion with automatic fallback to the pre-Defuddle extractor from git history
|
||||
- Materializes shadow DOM content before conversion so web-component pages survive serialization better
|
||||
- YouTube pages can include transcript/caption text in the markdown when YouTube exposes a caption track
|
||||
- If local browser capture fails completely, can fall back to `defuddle.md/<url>` and still save markdown
|
||||
- Handles login-required pages via wait mode
|
||||
- Download images and videos to local directories
|
||||
|
||||
## Usage
|
||||
|
||||
```bash
|
||||
# Auto mode (default) - capture when page loads
|
||||
${BUN_X} {baseDir}/scripts/main.ts <url>
|
||||
|
||||
# Wait mode - wait for user signal before capture
|
||||
${BUN_X} {baseDir}/scripts/main.ts <url> --wait
|
||||
|
||||
# Save to specific file
|
||||
${BUN_X} {baseDir}/scripts/main.ts <url> -o output.md
|
||||
|
||||
# Save to a custom output directory (auto-generates filename)
|
||||
${BUN_X} {baseDir}/scripts/main.ts <url> --output-dir ./posts/
|
||||
|
||||
# Download images and videos to local directories
|
||||
${BUN_X} {baseDir}/scripts/main.ts <url> --download-media
|
||||
```
|
||||
|
||||
## Options
|
||||
|
||||
| Option | Description |
|
||||
|--------|-------------|
|
||||
| `<url>` | URL to fetch |
|
||||
| `-o <path>` | Output file path — must be a **file** path, not directory (default: auto-generated) |
|
||||
| `--output-dir <dir>` | Base output directory — auto-generates `{dir}/{domain}/{slug}.md` (default: `./url-to-markdown/`) |
|
||||
| `--wait` | Wait for user signal before capturing |
|
||||
| `--timeout <ms>` | Page load timeout (default: 30000) |
|
||||
| `--download-media` | Download image/video assets to local `imgs/` and `videos/`, and rewrite markdown links to local relative paths |
|
||||
|
||||
## Capture Modes
|
||||
|
||||
| Mode | Behavior | Use When |
|
||||
|------|----------|----------|
|
||||
| Auto (default) | Capture on network idle | Public pages, static content |
|
||||
| Wait (`--wait`) | User signals when ready | Login-required, lazy loading, paywalls |
|
||||
|
||||
**Wait mode workflow**:
|
||||
1. Run with `--wait` → script outputs "Press Enter when ready"
|
||||
2. Ask user to confirm page is ready
|
||||
3. Send newline to stdin to trigger capture
|
||||
|
||||
## Output Format
|
||||
|
||||
Each run saves two files side by side:
|
||||
|
||||
- Markdown: YAML front matter with `url`, `title`, `description`, `author`, `published`, optional `coverImage`, and `captured_at`, followed by converted markdown content
|
||||
- HTML snapshot: `*-captured.html`, containing the rendered page HTML captured from Chrome
|
||||
|
||||
When Defuddle or page metadata provides a language hint, the markdown front matter also includes `language`.
|
||||
|
||||
The HTML snapshot is saved before any markdown media localization, so it stays a faithful capture of the page DOM used for conversion.
|
||||
If the hosted `defuddle.md` API fallback is used, markdown is still saved, but there is no local `-captured.html` snapshot for that run.
|
||||
|
||||
## Output Directory
|
||||
|
||||
Default: `url-to-markdown/<domain>/<slug>.md`
|
||||
With `--output-dir ./posts/`: `./posts/<domain>/<slug>.md`
|
||||
|
||||
HTML snapshot path uses the same basename:
|
||||
|
||||
- `url-to-markdown/<domain>/<slug>-captured.html`
|
||||
- `./posts/<domain>/<slug>-captured.html`
|
||||
|
||||
- `<slug>`: From page title or URL path (kebab-case, 2-6 words)
|
||||
- Conflict resolution: Append timestamp `<slug>-YYYYMMDD-HHMMSS.md`
|
||||
|
||||
When `--download-media` is enabled:
|
||||
- Images are saved to `imgs/` next to the markdown file
|
||||
- Videos are saved to `videos/` next to the markdown file
|
||||
- Markdown media links are rewritten to local relative paths
|
||||
|
||||
## Conversion Fallback
|
||||
|
||||
Conversion order:
|
||||
|
||||
1. Try Defuddle first
|
||||
2. For rich pages such as YouTube, prefer Defuddle's extractor-specific output (including transcripts when available) instead of replacing it with the legacy pipeline
|
||||
3. If Defuddle throws, cannot load, returns obviously incomplete markdown, or captures lower-quality content than the legacy pipeline, automatically fall back to the pre-Defuddle extractor
|
||||
4. If the entire local browser capture flow fails before markdown can be produced, try the hosted `https://defuddle.md/<url>` API and save its markdown output directly
|
||||
5. The legacy fallback path uses the older Readability/selector/Next.js-data based HTML-to-Markdown implementation recovered from git history
|
||||
|
||||
CLI output will show:
|
||||
|
||||
- `Converter: defuddle` when Defuddle succeeds
|
||||
- `Converter: legacy:...` plus `Fallback used: ...` when fallback was needed
|
||||
- `Converter: defuddle-api` when local browser capture failed and the hosted API was used instead
|
||||
|
||||
## Media Download Workflow
|
||||
|
||||
Based on `download_media` setting in EXTEND.md:
|
||||
|
||||
| Setting | Behavior |
|
||||
|---------|----------|
|
||||
| `1` (always) | Run script with `--download-media` flag |
|
||||
| `0` (never) | Run script without `--download-media` flag |
|
||||
| `ask` (default) | Follow the ask-each-time flow below |
|
||||
|
||||
### Ask-Each-Time Flow
|
||||
|
||||
1. Run script **without** `--download-media` → markdown saved
|
||||
2. Check saved markdown for remote media URLs (`https://` in image/video links)
|
||||
3. **If no remote media found** → done, no prompt needed
|
||||
4. **If remote media found** → use `AskUserQuestion`:
|
||||
- header: "Media", question: "Download N images/videos to local files?"
|
||||
- "Yes" — Download to local directories
|
||||
- "No" — Keep remote URLs
|
||||
5. If user confirms → run script **again** with `--download-media` (overwrites markdown with localized links)
|
||||
|
||||
## Environment Variables
|
||||
|
||||
| Variable | Description |
|
||||
|----------|-------------|
|
||||
| `URL_CHROME_PATH` | Custom Chrome executable path |
|
||||
| `URL_DATA_DIR` | Custom data directory |
|
||||
| `URL_CHROME_PROFILE_DIR` | Custom Chrome profile directory |
|
||||
|
||||
**Troubleshooting**: Chrome not found → set `URL_CHROME_PATH`. Timeout → increase `--timeout`. Complex pages → try `--wait` mode. If markdown quality is poor, inspect the saved `-captured.html` and check whether the run logged a legacy fallback.
|
||||
|
||||
### YouTube Notes
|
||||
|
||||
- The upgraded Defuddle path uses async extractors, so YouTube pages can include transcript text directly in the markdown body.
|
||||
- Transcript availability depends on YouTube exposing a caption track. Videos with captions disabled, restricted playback, or blocked regional access may still produce description-only output.
|
||||
- If the page needs time to finish loading descriptions, chapters, or player metadata, prefer `--wait` and capture after the watch page is fully hydrated.
|
||||
|
||||
### Hosted API Fallback
|
||||
|
||||
- The hosted fallback endpoint is `https://defuddle.md/<url>`. In shell form: `curl https://defuddle.md/stephango.com`
|
||||
- Use it only when the local Chrome/CDP capture path fails outright. The local path still has higher fidelity because it can save the captured HTML and handle authenticated pages.
|
||||
- The hosted API already returns Markdown with YAML frontmatter, so save that response as-is and then apply the normal media-localization step if requested.
|
||||
|
||||
## Extension Support
|
||||
|
||||
Custom configurations via EXTEND.md. See **Preferences** section for paths and supported options.
|
||||
@@ -0,0 +1,106 @@
|
||||
---
|
||||
name: first-time-setup
|
||||
description: First-time setup flow for baoyu-url-to-markdown preferences
|
||||
---
|
||||
|
||||
# First-Time Setup
|
||||
|
||||
## Overview
|
||||
|
||||
When no EXTEND.md is found, guide user through preference setup.
|
||||
|
||||
**BLOCKING OPERATION**: This setup MUST complete before ANY other workflow steps. Do NOT:
|
||||
- Start converting URLs
|
||||
- Ask about URLs or output paths
|
||||
- Proceed to any conversion
|
||||
|
||||
ONLY ask the questions in this setup flow, save EXTEND.md, then continue.
|
||||
|
||||
## Setup Flow
|
||||
|
||||
```
|
||||
No EXTEND.md found
|
||||
|
|
||||
v
|
||||
+---------------------+
|
||||
| AskUserQuestion |
|
||||
| (all questions) |
|
||||
+---------------------+
|
||||
|
|
||||
v
|
||||
+---------------------+
|
||||
| Create EXTEND.md |
|
||||
+---------------------+
|
||||
|
|
||||
v
|
||||
Continue conversion
|
||||
```
|
||||
|
||||
## Questions
|
||||
|
||||
**Language**: Use user's input language or saved language preference.
|
||||
|
||||
Use AskUserQuestion with ALL questions in ONE call:
|
||||
|
||||
### Question 1: Download Media
|
||||
|
||||
```yaml
|
||||
header: "Media"
|
||||
question: "How to handle images and videos in pages?"
|
||||
options:
|
||||
- label: "Ask each time (Recommended)"
|
||||
description: "After saving markdown, ask whether to download media"
|
||||
- label: "Always download"
|
||||
description: "Always download media to local imgs/ and videos/ directories"
|
||||
- label: "Never download"
|
||||
description: "Keep original remote URLs in markdown"
|
||||
```
|
||||
|
||||
### Question 2: Default Output Directory
|
||||
|
||||
```yaml
|
||||
header: "Output"
|
||||
question: "Default output directory?"
|
||||
options:
|
||||
- label: "url-to-markdown (Recommended)"
|
||||
description: "Save to ./url-to-markdown/{domain}/{slug}.md"
|
||||
```
|
||||
|
||||
Note: User will likely choose "Other" to type a custom path.
|
||||
|
||||
### Question 3: Save Location
|
||||
|
||||
```yaml
|
||||
header: "Save"
|
||||
question: "Where to save preferences?"
|
||||
options:
|
||||
- label: "User (Recommended)"
|
||||
description: "~/.baoyu-skills/ (all projects)"
|
||||
- label: "Project"
|
||||
description: ".baoyu-skills/ (this project only)"
|
||||
```
|
||||
|
||||
## Save Locations
|
||||
|
||||
| Choice | Path | Scope |
|
||||
|--------|------|-------|
|
||||
| User | `~/.baoyu-skills/baoyu-url-to-markdown/EXTEND.md` | All projects |
|
||||
| Project | `.baoyu-skills/baoyu-url-to-markdown/EXTEND.md` | Current project |
|
||||
|
||||
## After Setup
|
||||
|
||||
1. Create directory if needed
|
||||
2. Write EXTEND.md
|
||||
3. Confirm: "Preferences saved to [path]"
|
||||
4. Continue with conversion using saved preferences
|
||||
|
||||
## EXTEND.md Template
|
||||
|
||||
```md
|
||||
download_media: [ask/1/0]
|
||||
default_output_dir: [path or empty]
|
||||
```
|
||||
|
||||
## Modifying Preferences Later
|
||||
|
||||
Users can edit EXTEND.md directly or delete it to trigger setup again.
|
||||
179
llm-wiki/deps/baoyu-url-to-markdown/scripts/cdp.ts
Normal file
179
llm-wiki/deps/baoyu-url-to-markdown/scripts/cdp.ts
Normal file
@@ -0,0 +1,179 @@
|
||||
import {
|
||||
CdpConnection,
|
||||
findChromeExecutable as findChromeExecutableBase,
|
||||
findExistingChromeDebugPort,
|
||||
getFreePort,
|
||||
killChrome,
|
||||
launchChrome as launchChromeBase,
|
||||
sleep,
|
||||
waitForChromeDebugPort,
|
||||
type PlatformCandidates,
|
||||
} from 'baoyu-chrome-cdp';
|
||||
|
||||
import { resolveUrlToMarkdownChromeProfileDir } from './paths.js';
|
||||
import { NETWORK_IDLE_TIMEOUT_MS } from './constants.js';
|
||||
|
||||
const CHROME_CANDIDATES_FULL: PlatformCandidates = {
|
||||
darwin: [
|
||||
'/Applications/Google Chrome.app/Contents/MacOS/Google Chrome',
|
||||
'/Applications/Google Chrome Canary.app/Contents/MacOS/Google Chrome Canary',
|
||||
'/Applications/Google Chrome Beta.app/Contents/MacOS/Google Chrome Beta',
|
||||
'/Applications/Chromium.app/Contents/MacOS/Chromium',
|
||||
'/Applications/Microsoft Edge.app/Contents/MacOS/Microsoft Edge',
|
||||
],
|
||||
win32: [
|
||||
'C:\\Program Files\\Google\\Chrome\\Application\\chrome.exe',
|
||||
'C:\\Program Files (x86)\\Google\\Chrome\\Application\\chrome.exe',
|
||||
'C:\\Program Files\\Microsoft\\Edge\\Application\\msedge.exe',
|
||||
'C:\\Program Files (x86)\\Microsoft\\Edge\\Application\\msedge.exe',
|
||||
],
|
||||
default: [
|
||||
'/usr/bin/google-chrome',
|
||||
'/usr/bin/google-chrome-stable',
|
||||
'/usr/bin/chromium',
|
||||
'/usr/bin/chromium-browser',
|
||||
'/snap/bin/chromium',
|
||||
'/usr/bin/microsoft-edge',
|
||||
],
|
||||
};
|
||||
|
||||
export { CdpConnection, getFreePort, killChrome, sleep, waitForChromeDebugPort };
|
||||
|
||||
export async function findExistingChromePort(): Promise<number | null> {
|
||||
return await findExistingChromeDebugPort({
|
||||
profileDir: resolveUrlToMarkdownChromeProfileDir(),
|
||||
});
|
||||
}
|
||||
|
||||
export function findChromeExecutable(): string | null {
|
||||
return findChromeExecutableBase({
|
||||
candidates: CHROME_CANDIDATES_FULL,
|
||||
envNames: ['URL_CHROME_PATH'],
|
||||
}) ?? null;
|
||||
}
|
||||
|
||||
export async function launchChrome(url: string, port: number, headless = false) {
|
||||
const chromePath = findChromeExecutable();
|
||||
if (!chromePath) throw new Error('Chrome executable not found. Install Chrome or set URL_CHROME_PATH env.');
|
||||
|
||||
return await launchChromeBase({
|
||||
chromePath,
|
||||
profileDir: resolveUrlToMarkdownChromeProfileDir(),
|
||||
port,
|
||||
url,
|
||||
headless,
|
||||
extraArgs: ['--disable-popup-blocking'],
|
||||
});
|
||||
}
|
||||
|
||||
export async function waitForNetworkIdle(
|
||||
cdp: CdpConnection,
|
||||
sessionId: string,
|
||||
timeoutMs: number = NETWORK_IDLE_TIMEOUT_MS,
|
||||
): Promise<void> {
|
||||
return new Promise((resolve) => {
|
||||
let timer: ReturnType<typeof setTimeout> | null = null;
|
||||
let pending = 0;
|
||||
const cleanup = () => {
|
||||
if (timer) clearTimeout(timer);
|
||||
cdp.off('Network.requestWillBeSent', onRequest);
|
||||
cdp.off('Network.loadingFinished', onFinish);
|
||||
cdp.off('Network.loadingFailed', onFinish);
|
||||
};
|
||||
const done = () => { cleanup(); resolve(); };
|
||||
const resetTimer = () => {
|
||||
if (timer) clearTimeout(timer);
|
||||
timer = setTimeout(done, timeoutMs);
|
||||
};
|
||||
const onRequest = () => { pending++; resetTimer(); };
|
||||
const onFinish = () => { pending = Math.max(0, pending - 1); if (pending <= 2) resetTimer(); };
|
||||
cdp.on('Network.requestWillBeSent', onRequest);
|
||||
cdp.on('Network.loadingFinished', onFinish);
|
||||
cdp.on('Network.loadingFailed', onFinish);
|
||||
resetTimer();
|
||||
});
|
||||
}
|
||||
|
||||
export async function waitForPageLoad(
|
||||
cdp: CdpConnection,
|
||||
sessionId: string,
|
||||
timeoutMs: number = 30_000,
|
||||
): Promise<void> {
|
||||
void sessionId;
|
||||
return new Promise((resolve) => {
|
||||
const timer = setTimeout(() => {
|
||||
cdp.off('Page.loadEventFired', handler);
|
||||
resolve();
|
||||
}, timeoutMs);
|
||||
const handler = () => {
|
||||
clearTimeout(timer);
|
||||
cdp.off('Page.loadEventFired', handler);
|
||||
resolve();
|
||||
};
|
||||
cdp.on('Page.loadEventFired', handler);
|
||||
});
|
||||
}
|
||||
|
||||
export async function createTargetAndAttach(
|
||||
cdp: CdpConnection,
|
||||
url: string,
|
||||
): Promise<{ targetId: string; sessionId: string }> {
|
||||
const { targetId } = await cdp.send<{ targetId: string }>('Target.createTarget', { url });
|
||||
const { sessionId } = await cdp.send<{ sessionId: string }>('Target.attachToTarget', { targetId, flatten: true });
|
||||
await cdp.send('Network.enable', {}, { sessionId });
|
||||
await cdp.send('Page.enable', {}, { sessionId });
|
||||
return { targetId, sessionId };
|
||||
}
|
||||
|
||||
export async function navigateAndWait(
|
||||
cdp: CdpConnection,
|
||||
sessionId: string,
|
||||
url: string,
|
||||
timeoutMs: number,
|
||||
): Promise<void> {
|
||||
const loadPromise = new Promise<void>((resolve, reject) => {
|
||||
const timer = setTimeout(() => reject(new Error('Page load timeout')), timeoutMs);
|
||||
const handler = (params: unknown) => {
|
||||
const event = params as { name?: string };
|
||||
if (event.name === 'load' || event.name === 'DOMContentLoaded') {
|
||||
clearTimeout(timer);
|
||||
cdp.off('Page.lifecycleEvent', handler);
|
||||
resolve();
|
||||
}
|
||||
};
|
||||
cdp.on('Page.lifecycleEvent', handler);
|
||||
});
|
||||
await cdp.send('Page.navigate', { url }, { sessionId });
|
||||
await loadPromise;
|
||||
}
|
||||
|
||||
export async function evaluateScript<T>(
|
||||
cdp: CdpConnection,
|
||||
sessionId: string,
|
||||
expression: string,
|
||||
timeoutMs: number = 30_000,
|
||||
): Promise<T> {
|
||||
const result = await cdp.send<{ result: { value?: T } }>(
|
||||
'Runtime.evaluate',
|
||||
{ expression, returnByValue: true, awaitPromise: true },
|
||||
{ sessionId, timeoutMs },
|
||||
);
|
||||
return result.result.value as T;
|
||||
}
|
||||
|
||||
export async function autoScroll(
|
||||
cdp: CdpConnection,
|
||||
sessionId: string,
|
||||
steps: number = 8,
|
||||
waitMs: number = 600,
|
||||
): Promise<void> {
|
||||
let lastHeight = await evaluateScript<number>(cdp, sessionId, 'document.body.scrollHeight');
|
||||
for (let i = 0; i < steps; i++) {
|
||||
await evaluateScript<void>(cdp, sessionId, 'window.scrollTo(0, document.body.scrollHeight)');
|
||||
await sleep(waitMs);
|
||||
const newHeight = await evaluateScript<number>(cdp, sessionId, 'document.body.scrollHeight');
|
||||
if (newHeight === lastHeight) break;
|
||||
lastHeight = newHeight;
|
||||
}
|
||||
await evaluateScript<void>(cdp, sessionId, 'window.scrollTo(0, 0)');
|
||||
}
|
||||
13
llm-wiki/deps/baoyu-url-to-markdown/scripts/constants.ts
Normal file
13
llm-wiki/deps/baoyu-url-to-markdown/scripts/constants.ts
Normal file
@@ -0,0 +1,13 @@
|
||||
import { resolveUrlToMarkdownChromeProfileDir } from "./paths.js";
|
||||
|
||||
export const DEFAULT_USER_AGENT =
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.0.0 Safari/537.36";
|
||||
|
||||
export const USER_DATA_DIR = resolveUrlToMarkdownChromeProfileDir();
|
||||
|
||||
export const DEFAULT_TIMEOUT_MS = 30_000;
|
||||
export const CDP_CONNECT_TIMEOUT_MS = 15_000;
|
||||
export const NETWORK_IDLE_TIMEOUT_MS = 1_500;
|
||||
export const POST_LOAD_DELAY_MS = 800;
|
||||
export const SCROLL_STEP_WAIT_MS = 600;
|
||||
export const SCROLL_MAX_STEPS = 8;
|
||||
@@ -0,0 +1,58 @@
|
||||
import { JSDOM, VirtualConsole } from "jsdom";
|
||||
import { Defuddle } from "defuddle/node";
|
||||
|
||||
import {
|
||||
type ConversionResult,
|
||||
type PageMetadata,
|
||||
isMarkdownUsable,
|
||||
normalizeMarkdown,
|
||||
pickString,
|
||||
} from "./markdown-conversion-shared.js";
|
||||
|
||||
export async function tryDefuddleConversion(
|
||||
html: string,
|
||||
url: string,
|
||||
baseMetadata: PageMetadata
|
||||
): Promise<{ ok: true; result: ConversionResult } | { ok: false; reason: string }> {
|
||||
try {
|
||||
const virtualConsole = new VirtualConsole();
|
||||
virtualConsole.on("jsdomError", (error: Error & { type?: string }) => {
|
||||
if (error.type === "css parsing" || /Could not parse CSS stylesheet/i.test(error.message)) {
|
||||
return;
|
||||
}
|
||||
console.warn(`[url-to-markdown] jsdom: ${error.message}`);
|
||||
});
|
||||
|
||||
const dom = new JSDOM(html, { url, virtualConsole });
|
||||
const result = await Defuddle(dom, url, { markdown: true });
|
||||
const markdown = normalizeMarkdown(result.content || "");
|
||||
|
||||
if (!isMarkdownUsable(markdown, html)) {
|
||||
return { ok: false, reason: "Defuddle returned empty or incomplete markdown" };
|
||||
}
|
||||
|
||||
return {
|
||||
ok: true,
|
||||
result: {
|
||||
metadata: {
|
||||
...baseMetadata,
|
||||
title: pickString(result.title, baseMetadata.title) ?? "",
|
||||
description: pickString(result.description, baseMetadata.description) ?? undefined,
|
||||
author: pickString(result.author, baseMetadata.author) ?? undefined,
|
||||
published: pickString(result.published, baseMetadata.published) ?? undefined,
|
||||
coverImage: pickString(result.image, baseMetadata.coverImage) ?? undefined,
|
||||
language: pickString(result.language, baseMetadata.language) ?? undefined,
|
||||
},
|
||||
markdown,
|
||||
rawHtml: html,
|
||||
conversionMethod: "defuddle",
|
||||
variables: result.variables,
|
||||
},
|
||||
};
|
||||
} catch (error) {
|
||||
return {
|
||||
ok: false,
|
||||
reason: error instanceof Error ? error.message : String(error),
|
||||
};
|
||||
}
|
||||
}
|
||||
135
llm-wiki/deps/baoyu-url-to-markdown/scripts/html-to-markdown.ts
Normal file
135
llm-wiki/deps/baoyu-url-to-markdown/scripts/html-to-markdown.ts
Normal file
@@ -0,0 +1,135 @@
|
||||
import {
|
||||
createMarkdownDocument,
|
||||
extractMetadataFromHtml,
|
||||
formatMetadataYaml,
|
||||
type ConversionResult,
|
||||
type PageMetadata,
|
||||
isYouTubeUrl,
|
||||
} from "./markdown-conversion-shared.js";
|
||||
import { tryDefuddleConversion } from "./defuddle-converter.js";
|
||||
import {
|
||||
convertWithLegacyExtractor,
|
||||
scoreMarkdownQuality,
|
||||
shouldCompareWithLegacy,
|
||||
} from "./legacy-converter.js";
|
||||
|
||||
export type { ConversionResult, PageMetadata };
|
||||
export { createMarkdownDocument, formatMetadataYaml };
|
||||
|
||||
export const absolutizeUrlsScript = String.raw`
|
||||
(function() {
|
||||
const baseUrl = document.baseURI || location.href;
|
||||
const htmlClone = document.documentElement.cloneNode(true);
|
||||
|
||||
function materializeShadowDom(sourceRoot, cloneRoot) {
|
||||
const sourceElements = Array.from(sourceRoot.querySelectorAll("*"));
|
||||
const cloneElements = Array.from(cloneRoot.querySelectorAll("*"));
|
||||
|
||||
for (let i = sourceElements.length - 1; i >= 0; i--) {
|
||||
const sourceEl = sourceElements[i];
|
||||
const cloneEl = cloneElements[i];
|
||||
const shadowRoot = sourceEl && sourceEl.shadowRoot;
|
||||
if (!shadowRoot || !cloneEl || !shadowRoot.innerHTML) continue;
|
||||
|
||||
if (cloneEl.tagName && cloneEl.tagName.includes("-")) {
|
||||
const wrapper = document.createElement("div");
|
||||
wrapper.setAttribute("data-shadow-host", cloneEl.tagName.toLowerCase());
|
||||
wrapper.innerHTML = shadowRoot.innerHTML;
|
||||
cloneEl.replaceWith(wrapper);
|
||||
} else {
|
||||
cloneEl.innerHTML = shadowRoot.innerHTML;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
function toAbsolute(url) {
|
||||
if (!url) return url;
|
||||
try { return new URL(url, baseUrl).href; } catch { return url; }
|
||||
}
|
||||
|
||||
function absAttr(root, sel, attr) {
|
||||
root.querySelectorAll(sel).forEach(el => {
|
||||
const v = el.getAttribute(attr);
|
||||
if (v) {
|
||||
const a = toAbsolute(v);
|
||||
if (a) el.setAttribute(attr, a);
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
function absSrcset(root, sel) {
|
||||
root.querySelectorAll(sel).forEach(el => {
|
||||
const s = el.getAttribute("srcset");
|
||||
if (!s) return;
|
||||
el.setAttribute("srcset", s.split(",").map(p => {
|
||||
const t = p.trim();
|
||||
if (!t) return "";
|
||||
const [url, ...d] = t.split(/\s+/);
|
||||
return d.length ? toAbsolute(url) + " " + d.join(" ") : toAbsolute(url);
|
||||
}).filter(Boolean).join(", "));
|
||||
});
|
||||
}
|
||||
|
||||
materializeShadowDom(document.documentElement, htmlClone);
|
||||
|
||||
htmlClone.querySelectorAll("img[data-src], video[data-src], audio[data-src], source[data-src]").forEach(el => {
|
||||
const ds = el.getAttribute("data-src");
|
||||
if (ds && (!el.getAttribute("src") || el.getAttribute("src") === "" || el.getAttribute("src")?.startsWith("data:"))) {
|
||||
el.setAttribute("src", ds);
|
||||
}
|
||||
});
|
||||
|
||||
absAttr(htmlClone, "a[href]", "href");
|
||||
absAttr(htmlClone, "img[src], video[src], audio[src], source[src], iframe[src]", "src");
|
||||
absAttr(htmlClone, "video[poster]", "poster");
|
||||
absSrcset(htmlClone, "img[srcset], source[srcset]");
|
||||
|
||||
return { html: "<!doctype html>\n" + htmlClone.outerHTML };
|
||||
})()
|
||||
`;
|
||||
|
||||
function shouldPreferDefuddle(result: ConversionResult): boolean {
|
||||
if (isYouTubeUrl(result.metadata.url)) {
|
||||
return true;
|
||||
}
|
||||
|
||||
const transcript = result.variables?.transcript?.trim();
|
||||
if (transcript) {
|
||||
return true;
|
||||
}
|
||||
|
||||
return /^##?\s+transcript\b/im.test(result.markdown);
|
||||
}
|
||||
|
||||
export async function extractContent(html: string, url: string): Promise<ConversionResult> {
|
||||
const capturedAt = new Date().toISOString();
|
||||
const baseMetadata = extractMetadataFromHtml(html, url, capturedAt);
|
||||
|
||||
const defuddleResult = await tryDefuddleConversion(html, url, baseMetadata);
|
||||
if (defuddleResult.ok) {
|
||||
if (shouldPreferDefuddle(defuddleResult.result)) {
|
||||
return defuddleResult.result;
|
||||
}
|
||||
|
||||
if (shouldCompareWithLegacy(defuddleResult.result.markdown)) {
|
||||
const legacyResult = convertWithLegacyExtractor(html, baseMetadata);
|
||||
const legacyScore = scoreMarkdownQuality(legacyResult.markdown);
|
||||
const defuddleScore = scoreMarkdownQuality(defuddleResult.result.markdown);
|
||||
|
||||
if (legacyScore > defuddleScore + 120) {
|
||||
return {
|
||||
...legacyResult,
|
||||
fallbackReason: "Legacy extractor produced higher-quality markdown than Defuddle",
|
||||
};
|
||||
}
|
||||
}
|
||||
|
||||
return defuddleResult.result;
|
||||
}
|
||||
|
||||
const fallbackResult = convertWithLegacyExtractor(html, baseMetadata);
|
||||
return {
|
||||
...fallbackResult,
|
||||
fallbackReason: defuddleResult.reason,
|
||||
};
|
||||
}
|
||||
629
llm-wiki/deps/baoyu-url-to-markdown/scripts/legacy-converter.ts
Normal file
629
llm-wiki/deps/baoyu-url-to-markdown/scripts/legacy-converter.ts
Normal file
@@ -0,0 +1,629 @@
|
||||
import { Readability } from "@mozilla/readability";
|
||||
import TurndownService from "turndown";
|
||||
import { gfm } from "turndown-plugin-gfm";
|
||||
|
||||
import {
|
||||
type AnyRecord,
|
||||
type ConversionResult,
|
||||
type PageMetadata,
|
||||
GOOD_CONTENT_LENGTH,
|
||||
MIN_CONTENT_LENGTH,
|
||||
extractPublishedTime,
|
||||
extractTextFromHtml,
|
||||
extractTitle,
|
||||
normalizeMarkdown,
|
||||
parseDocument,
|
||||
pickString,
|
||||
sanitizeHtml,
|
||||
} from "./markdown-conversion-shared.js";
|
||||
|
||||
interface ExtractionCandidate {
|
||||
title: string | null;
|
||||
byline: string | null;
|
||||
excerpt: string | null;
|
||||
published: string | null;
|
||||
html: string | null;
|
||||
textContent: string;
|
||||
method: string;
|
||||
}
|
||||
|
||||
const CONTENT_SELECTORS = [
|
||||
"article",
|
||||
"main article",
|
||||
"[role='main'] article",
|
||||
"[itemprop='articleBody']",
|
||||
".article-content",
|
||||
".article-body",
|
||||
".post-content",
|
||||
".entry-content",
|
||||
".story-body",
|
||||
"main",
|
||||
"[role='main']",
|
||||
"#content",
|
||||
".content",
|
||||
];
|
||||
|
||||
const REMOVE_SELECTORS = [
|
||||
"script",
|
||||
"style",
|
||||
"noscript",
|
||||
"template",
|
||||
"iframe",
|
||||
"svg",
|
||||
"path",
|
||||
"nav",
|
||||
"aside",
|
||||
"footer",
|
||||
"header",
|
||||
"form",
|
||||
".advertisement",
|
||||
".ads",
|
||||
".social-share",
|
||||
".related-articles",
|
||||
".comments",
|
||||
".newsletter",
|
||||
".cookie-banner",
|
||||
".cookie-consent",
|
||||
"[role='navigation']",
|
||||
"[aria-label*='cookie' i]",
|
||||
];
|
||||
|
||||
const NEXT_DATA_CONTENT_PATHS = [
|
||||
"props.pageProps.content.body",
|
||||
"props.pageProps.article.body",
|
||||
"props.pageProps.article.content",
|
||||
"props.pageProps.post.body",
|
||||
"props.pageProps.post.content",
|
||||
"props.pageProps.data.body",
|
||||
"props.pageProps.story.body.content",
|
||||
];
|
||||
|
||||
const LOW_QUALITY_MARKERS = [
|
||||
/Join The Conversation/i,
|
||||
/One Community\. Many Voices/i,
|
||||
/Read our community guidelines/i,
|
||||
/Create a free account to share your thoughts/i,
|
||||
/Become a Forbes Member/i,
|
||||
/Subscribe to trusted journalism/i,
|
||||
/\bComments\b/i,
|
||||
];
|
||||
|
||||
function generateExcerpt(excerpt: string | null, textContent: string | null): string | null {
|
||||
if (excerpt) return excerpt;
|
||||
if (!textContent) return null;
|
||||
const trimmed = textContent.trim();
|
||||
if (!trimmed) return null;
|
||||
return trimmed.length > 200 ? `${trimmed.slice(0, 200)}...` : trimmed;
|
||||
}
|
||||
|
||||
function parseJsonLdItem(item: AnyRecord): ExtractionCandidate | null {
|
||||
const type = Array.isArray(item["@type"]) ? item["@type"][0] : item["@type"];
|
||||
if (typeof type !== "string" || !["Article", "NewsArticle", "BlogPosting", "WebPage", "ReportageNewsArticle"].includes(type)) {
|
||||
return null;
|
||||
}
|
||||
|
||||
const rawContent =
|
||||
(typeof item.articleBody === "string" && item.articleBody) ||
|
||||
(typeof item.text === "string" && item.text) ||
|
||||
(typeof item.description === "string" && item.description) ||
|
||||
null;
|
||||
|
||||
if (!rawContent) return null;
|
||||
|
||||
const content = rawContent.trim();
|
||||
const htmlLike = /<\/?[a-z][\s\S]*>/i.test(content);
|
||||
const textContent = htmlLike ? extractTextFromHtml(content) : content;
|
||||
|
||||
if (textContent.length < MIN_CONTENT_LENGTH) return null;
|
||||
|
||||
return {
|
||||
title: pickString(item.headline, item.name),
|
||||
byline: extractAuthorFromJsonLd(item.author),
|
||||
excerpt: pickString(item.description),
|
||||
published: pickString(item.datePublished, item.dateCreated),
|
||||
html: htmlLike ? content : null,
|
||||
textContent,
|
||||
method: "json-ld",
|
||||
};
|
||||
}
|
||||
|
||||
function extractAuthorFromJsonLd(authorData: unknown): string | null {
|
||||
if (typeof authorData === "string") return authorData;
|
||||
if (!authorData || typeof authorData !== "object") return null;
|
||||
|
||||
if (Array.isArray(authorData)) {
|
||||
const names = authorData
|
||||
.map((author) => extractAuthorFromJsonLd(author))
|
||||
.filter((name): name is string => Boolean(name));
|
||||
return names.length > 0 ? names.join(", ") : null;
|
||||
}
|
||||
|
||||
const author = authorData as AnyRecord;
|
||||
return typeof author.name === "string" ? author.name : null;
|
||||
}
|
||||
|
||||
function flattenJsonLdItems(data: unknown): AnyRecord[] {
|
||||
if (!data || typeof data !== "object") return [];
|
||||
if (Array.isArray(data)) return data.flatMap(flattenJsonLdItems);
|
||||
|
||||
const item = data as AnyRecord;
|
||||
if (Array.isArray(item["@graph"])) {
|
||||
return (item["@graph"] as unknown[]).flatMap(flattenJsonLdItems);
|
||||
}
|
||||
|
||||
return [item];
|
||||
}
|
||||
|
||||
function tryJsonLdExtraction(document: Document): ExtractionCandidate | null {
|
||||
const scripts = document.querySelectorAll("script[type='application/ld+json']");
|
||||
|
||||
for (const script of scripts) {
|
||||
try {
|
||||
const data = JSON.parse(script.textContent ?? "");
|
||||
for (const item of flattenJsonLdItems(data)) {
|
||||
const extracted = parseJsonLdItem(item);
|
||||
if (extracted) return extracted;
|
||||
}
|
||||
} catch {
|
||||
// Ignore malformed blocks.
|
||||
}
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
function getByPath(value: unknown, path: string): unknown {
|
||||
let current = value;
|
||||
for (const part of path.split(".")) {
|
||||
if (!current || typeof current !== "object") return undefined;
|
||||
current = (current as AnyRecord)[part];
|
||||
}
|
||||
return current;
|
||||
}
|
||||
|
||||
function isContentBlockArray(value: unknown): value is AnyRecord[] {
|
||||
if (!Array.isArray(value) || value.length === 0) return false;
|
||||
return value.slice(0, 5).some((item) => {
|
||||
if (!item || typeof item !== "object") return false;
|
||||
const obj = item as AnyRecord;
|
||||
return "type" in obj || "text" in obj || "textHtml" in obj || "content" in obj;
|
||||
});
|
||||
}
|
||||
|
||||
function extractTextFromContentBlocks(blocks: AnyRecord[]): string {
|
||||
const parts: string[] = [];
|
||||
|
||||
function pushParagraph(text: string): void {
|
||||
const trimmed = text.trim();
|
||||
if (!trimmed) return;
|
||||
parts.push(trimmed, "\n\n");
|
||||
}
|
||||
|
||||
function walk(node: unknown): void {
|
||||
if (!node || typeof node !== "object") return;
|
||||
const block = node as AnyRecord;
|
||||
|
||||
if (typeof block.text === "string") {
|
||||
pushParagraph(block.text);
|
||||
return;
|
||||
}
|
||||
|
||||
if (typeof block.textHtml === "string") {
|
||||
pushParagraph(extractTextFromHtml(block.textHtml));
|
||||
return;
|
||||
}
|
||||
|
||||
if (Array.isArray(block.items)) {
|
||||
for (const item of block.items) {
|
||||
if (item && typeof item === "object") {
|
||||
const text = pickString((item as AnyRecord).text);
|
||||
if (text) parts.push(`- ${text}\n`);
|
||||
}
|
||||
}
|
||||
parts.push("\n");
|
||||
}
|
||||
|
||||
if (Array.isArray(block.components)) {
|
||||
for (const component of block.components) {
|
||||
walk(component);
|
||||
}
|
||||
}
|
||||
|
||||
if (Array.isArray(block.content)) {
|
||||
for (const child of block.content) {
|
||||
walk(child);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (const block of blocks) {
|
||||
walk(block);
|
||||
}
|
||||
|
||||
return parts.join("").replace(/\n{3,}/g, "\n\n").trim();
|
||||
}
|
||||
|
||||
function tryStringBodyExtraction(
|
||||
content: string,
|
||||
meta: AnyRecord,
|
||||
document: Document,
|
||||
method: string
|
||||
): ExtractionCandidate | null {
|
||||
if (!content || content.length < MIN_CONTENT_LENGTH) return null;
|
||||
|
||||
const isHtml = /<\/?[a-z][\s\S]*>/i.test(content);
|
||||
const html = isHtml ? sanitizeHtml(content) : null;
|
||||
const textContent = isHtml ? extractTextFromHtml(html) : content.trim();
|
||||
|
||||
if (textContent.length < MIN_CONTENT_LENGTH) return null;
|
||||
|
||||
return {
|
||||
title: pickString(meta.headline, meta.title, extractTitle(document)),
|
||||
byline: pickString(meta.byline, meta.author),
|
||||
excerpt: pickString(meta.description, meta.excerpt, generateExcerpt(null, textContent)),
|
||||
published: pickString(meta.datePublished, meta.publishedAt, extractPublishedTime(document)),
|
||||
html,
|
||||
textContent,
|
||||
method,
|
||||
};
|
||||
}
|
||||
|
||||
function tryNextDataExtraction(document: Document): ExtractionCandidate | null {
|
||||
try {
|
||||
const script = document.querySelector("script#__NEXT_DATA__");
|
||||
if (!script?.textContent) return null;
|
||||
|
||||
const data = JSON.parse(script.textContent) as AnyRecord;
|
||||
const pageProps = (getByPath(data, "props.pageProps") ?? {}) as AnyRecord;
|
||||
|
||||
for (const path of NEXT_DATA_CONTENT_PATHS) {
|
||||
const value = getByPath(data, path);
|
||||
|
||||
if (typeof value === "string") {
|
||||
const parentPath = path.split(".").slice(0, -1).join(".");
|
||||
const parent = (getByPath(data, parentPath) ?? {}) as AnyRecord;
|
||||
const meta = {
|
||||
...pageProps,
|
||||
...parent,
|
||||
title: parent.title ?? (pageProps.title as string | undefined),
|
||||
};
|
||||
|
||||
const candidate = tryStringBodyExtraction(value, meta, document, "next-data");
|
||||
if (candidate) return candidate;
|
||||
}
|
||||
|
||||
if (isContentBlockArray(value)) {
|
||||
const textContent = extractTextFromContentBlocks(value);
|
||||
if (textContent.length < MIN_CONTENT_LENGTH) continue;
|
||||
|
||||
return {
|
||||
title: pickString(
|
||||
getByPath(data, "props.pageProps.content.headline"),
|
||||
getByPath(data, "props.pageProps.article.headline"),
|
||||
getByPath(data, "props.pageProps.article.title"),
|
||||
getByPath(data, "props.pageProps.post.title"),
|
||||
pageProps.title,
|
||||
extractTitle(document)
|
||||
),
|
||||
byline: pickString(
|
||||
getByPath(data, "props.pageProps.author.name"),
|
||||
getByPath(data, "props.pageProps.article.author.name")
|
||||
),
|
||||
excerpt: pickString(
|
||||
getByPath(data, "props.pageProps.content.description"),
|
||||
getByPath(data, "props.pageProps.article.description"),
|
||||
pageProps.description,
|
||||
generateExcerpt(null, textContent)
|
||||
),
|
||||
published: pickString(
|
||||
getByPath(data, "props.pageProps.content.datePublished"),
|
||||
getByPath(data, "props.pageProps.article.datePublished"),
|
||||
getByPath(data, "props.pageProps.publishedAt"),
|
||||
extractPublishedTime(document)
|
||||
),
|
||||
html: null,
|
||||
textContent,
|
||||
method: "next-data",
|
||||
};
|
||||
}
|
||||
}
|
||||
} catch {
|
||||
return null;
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
function buildReadabilityCandidate(
|
||||
article: ReturnType<Readability["parse"]>,
|
||||
document: Document,
|
||||
method: string
|
||||
): ExtractionCandidate | null {
|
||||
const textContent = article?.textContent?.trim() ?? "";
|
||||
if (textContent.length < MIN_CONTENT_LENGTH) return null;
|
||||
|
||||
return {
|
||||
title: pickString(article?.title, extractTitle(document)),
|
||||
byline: pickString((article as { byline?: string } | null)?.byline),
|
||||
excerpt: pickString(article?.excerpt, generateExcerpt(null, textContent)),
|
||||
published: pickString((article as { publishedTime?: string } | null)?.publishedTime, extractPublishedTime(document)),
|
||||
html: article?.content ? sanitizeHtml(article.content) : null,
|
||||
textContent,
|
||||
method,
|
||||
};
|
||||
}
|
||||
|
||||
function tryReadability(document: Document): ExtractionCandidate | null {
|
||||
try {
|
||||
const strictClone = document.cloneNode(true) as Document;
|
||||
const strictResult = buildReadabilityCandidate(
|
||||
new Readability(strictClone).parse(),
|
||||
document,
|
||||
"readability"
|
||||
);
|
||||
if (strictResult) return strictResult;
|
||||
|
||||
const relaxedClone = document.cloneNode(true) as Document;
|
||||
return buildReadabilityCandidate(
|
||||
new Readability(relaxedClone, { charThreshold: 120 }).parse(),
|
||||
document,
|
||||
"readability-relaxed"
|
||||
);
|
||||
} catch {
|
||||
return null;
|
||||
}
|
||||
}
|
||||
|
||||
function trySelectorExtraction(document: Document): ExtractionCandidate | null {
|
||||
for (const selector of CONTENT_SELECTORS) {
|
||||
const element = document.querySelector(selector);
|
||||
if (!element) continue;
|
||||
|
||||
const clone = element.cloneNode(true) as Element;
|
||||
for (const removeSelector of REMOVE_SELECTORS) {
|
||||
for (const node of clone.querySelectorAll(removeSelector)) {
|
||||
node.remove();
|
||||
}
|
||||
}
|
||||
|
||||
const html = sanitizeHtml(clone.innerHTML);
|
||||
const textContent = extractTextFromHtml(html);
|
||||
if (textContent.length < MIN_CONTENT_LENGTH) continue;
|
||||
|
||||
return {
|
||||
title: extractTitle(document),
|
||||
byline: null,
|
||||
excerpt: generateExcerpt(null, textContent),
|
||||
published: extractPublishedTime(document),
|
||||
html,
|
||||
textContent,
|
||||
method: `selector:${selector}`,
|
||||
};
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
function tryBodyExtraction(document: Document): ExtractionCandidate | null {
|
||||
const body = document.body;
|
||||
if (!body) return null;
|
||||
|
||||
const clone = body.cloneNode(true) as Element;
|
||||
for (const removeSelector of REMOVE_SELECTORS) {
|
||||
for (const node of clone.querySelectorAll(removeSelector)) {
|
||||
node.remove();
|
||||
}
|
||||
}
|
||||
|
||||
const html = sanitizeHtml(clone.innerHTML);
|
||||
const textContent = extractTextFromHtml(html);
|
||||
if (!textContent) return null;
|
||||
|
||||
return {
|
||||
title: extractTitle(document),
|
||||
byline: null,
|
||||
excerpt: generateExcerpt(null, textContent),
|
||||
published: extractPublishedTime(document),
|
||||
html,
|
||||
textContent,
|
||||
method: "body-fallback",
|
||||
};
|
||||
}
|
||||
|
||||
function pickBestCandidate(candidates: ExtractionCandidate[]): ExtractionCandidate | null {
|
||||
if (candidates.length === 0) return null;
|
||||
|
||||
const methodOrder = [
|
||||
"readability",
|
||||
"readability-relaxed",
|
||||
"next-data",
|
||||
"json-ld",
|
||||
"selector:",
|
||||
"body-fallback",
|
||||
];
|
||||
|
||||
function methodRank(method: string): number {
|
||||
const idx = methodOrder.findIndex((entry) =>
|
||||
entry.endsWith(":") ? method.startsWith(entry) : method === entry
|
||||
);
|
||||
return idx === -1 ? methodOrder.length : idx;
|
||||
}
|
||||
|
||||
const ranked = [...candidates].sort((a, b) => {
|
||||
const rankA = methodRank(a.method);
|
||||
const rankB = methodRank(b.method);
|
||||
if (rankA !== rankB) return rankA - rankB;
|
||||
return (b.textContent.length ?? 0) - (a.textContent.length ?? 0);
|
||||
});
|
||||
|
||||
for (const candidate of ranked) {
|
||||
if (candidate.textContent.length >= GOOD_CONTENT_LENGTH) {
|
||||
return candidate;
|
||||
}
|
||||
}
|
||||
|
||||
for (const candidate of ranked) {
|
||||
if (candidate.textContent.length >= MIN_CONTENT_LENGTH) {
|
||||
return candidate;
|
||||
}
|
||||
}
|
||||
|
||||
return ranked[0];
|
||||
}
|
||||
|
||||
function extractFromHtml(html: string): ExtractionCandidate | null {
|
||||
const document = parseDocument(html);
|
||||
|
||||
const readabilityCandidate = tryReadability(document);
|
||||
const nextDataCandidate = tryNextDataExtraction(document);
|
||||
const jsonLdCandidate = tryJsonLdExtraction(document);
|
||||
const selectorCandidate = trySelectorExtraction(document);
|
||||
const bodyCandidate = tryBodyExtraction(document);
|
||||
|
||||
const candidates = [
|
||||
readabilityCandidate,
|
||||
nextDataCandidate,
|
||||
jsonLdCandidate,
|
||||
selectorCandidate,
|
||||
bodyCandidate,
|
||||
].filter((candidate): candidate is ExtractionCandidate => Boolean(candidate));
|
||||
|
||||
const winner = pickBestCandidate(candidates);
|
||||
if (!winner) return null;
|
||||
|
||||
return {
|
||||
...winner,
|
||||
title: winner.title ?? extractTitle(document),
|
||||
published: winner.published ?? extractPublishedTime(document),
|
||||
excerpt: winner.excerpt ?? generateExcerpt(null, winner.textContent),
|
||||
};
|
||||
}
|
||||
|
||||
const turndown = new TurndownService({
|
||||
headingStyle: "atx",
|
||||
hr: "---",
|
||||
bulletListMarker: "-",
|
||||
codeBlockStyle: "fenced",
|
||||
emDelimiter: "*",
|
||||
strongDelimiter: "**",
|
||||
linkStyle: "inlined",
|
||||
});
|
||||
|
||||
turndown.use(gfm);
|
||||
turndown.remove(["script", "style", "iframe", "noscript", "template", "svg", "path"]);
|
||||
|
||||
turndown.addRule("collapseFigure", {
|
||||
filter: "figure",
|
||||
replacement(content) {
|
||||
return `\n\n${content.trim()}\n\n`;
|
||||
},
|
||||
});
|
||||
|
||||
turndown.addRule("dropInvisibleAnchors", {
|
||||
filter(node) {
|
||||
return node.nodeName === "A" && !(node as Element).textContent?.trim();
|
||||
},
|
||||
replacement() {
|
||||
return "";
|
||||
},
|
||||
});
|
||||
|
||||
function convertHtmlToMarkdown(html: string): string {
|
||||
if (!html || !html.trim()) return "";
|
||||
|
||||
try {
|
||||
const sanitized = sanitizeHtml(html);
|
||||
return turndown.turndown(sanitized);
|
||||
} catch {
|
||||
return "";
|
||||
}
|
||||
}
|
||||
|
||||
function fallbackPlainText(html: string): string {
|
||||
const document = parseDocument(html);
|
||||
for (const selector of ["script", "style", "noscript", "template", "iframe", "svg", "path"]) {
|
||||
for (const el of document.querySelectorAll(selector)) {
|
||||
el.remove();
|
||||
}
|
||||
}
|
||||
const text = document.body?.textContent ?? document.documentElement?.textContent ?? "";
|
||||
return normalizeMarkdown(text.replace(/\s+/g, " "));
|
||||
}
|
||||
|
||||
function countBylines(markdown: string): number {
|
||||
return (markdown.match(/(^|\n)By\s+/g) || []).length;
|
||||
}
|
||||
|
||||
function countUsefulParagraphs(markdown: string): number {
|
||||
const paragraphs = normalizeMarkdown(markdown).split(/\n{2,}/);
|
||||
let count = 0;
|
||||
|
||||
for (const paragraph of paragraphs) {
|
||||
const trimmed = paragraph.trim();
|
||||
if (!trimmed) continue;
|
||||
if (/^!?\[[^\]]*\]\([^)]+\)$/.test(trimmed)) continue;
|
||||
if (/^#{1,6}\s+/.test(trimmed)) continue;
|
||||
if ((trimmed.match(/\b[\p{L}\p{N}']+\b/gu) || []).length < 8) continue;
|
||||
count++;
|
||||
}
|
||||
|
||||
return count;
|
||||
}
|
||||
|
||||
function countMarkerHits(markdown: string, markers: RegExp[]): number {
|
||||
let hits = 0;
|
||||
for (const marker of markers) {
|
||||
if (marker.test(markdown)) hits++;
|
||||
}
|
||||
return hits;
|
||||
}
|
||||
|
||||
export function scoreMarkdownQuality(markdown: string): number {
|
||||
const normalized = normalizeMarkdown(markdown);
|
||||
const wordCount = (normalized.match(/\b[\p{L}\p{N}']+\b/gu) || []).length;
|
||||
const usefulParagraphs = countUsefulParagraphs(normalized);
|
||||
const headingCount = (normalized.match(/^#{1,6}\s+/gm) || []).length;
|
||||
const markerHits = countMarkerHits(normalized, LOW_QUALITY_MARKERS);
|
||||
const bylineCount = countBylines(normalized);
|
||||
const staffCount = (normalized.match(/\bForbes Staff\b/gi) || []).length;
|
||||
|
||||
return (
|
||||
Math.min(wordCount, 4000) +
|
||||
usefulParagraphs * 40 +
|
||||
headingCount * 10 -
|
||||
markerHits * 180 -
|
||||
Math.max(0, bylineCount - 1) * 120 -
|
||||
Math.max(0, staffCount - 1) * 80
|
||||
);
|
||||
}
|
||||
|
||||
export function shouldCompareWithLegacy(markdown: string): boolean {
|
||||
const normalized = normalizeMarkdown(markdown);
|
||||
return (
|
||||
countMarkerHits(normalized, LOW_QUALITY_MARKERS) > 0 ||
|
||||
countBylines(normalized) > 1 ||
|
||||
countUsefulParagraphs(normalized) < 6
|
||||
);
|
||||
}
|
||||
|
||||
export function convertWithLegacyExtractor(html: string, baseMetadata: PageMetadata): ConversionResult {
|
||||
const extracted = extractFromHtml(html);
|
||||
|
||||
let markdown = extracted?.html ? convertHtmlToMarkdown(extracted.html) : "";
|
||||
if (!markdown.trim()) {
|
||||
markdown = extracted?.textContent?.trim() || fallbackPlainText(html);
|
||||
}
|
||||
|
||||
return {
|
||||
metadata: {
|
||||
...baseMetadata,
|
||||
title: pickString(extracted?.title, baseMetadata.title) ?? "",
|
||||
description: pickString(extracted?.excerpt, baseMetadata.description) ?? undefined,
|
||||
author: pickString(extracted?.byline, baseMetadata.author) ?? undefined,
|
||||
published: pickString(extracted?.published, baseMetadata.published) ?? undefined,
|
||||
},
|
||||
markdown: normalizeMarkdown(markdown),
|
||||
rawHtml: html,
|
||||
conversionMethod: extracted ? `legacy:${extracted.method}` : "legacy:plain-text",
|
||||
};
|
||||
}
|
||||
314
llm-wiki/deps/baoyu-url-to-markdown/scripts/main.ts
Normal file
314
llm-wiki/deps/baoyu-url-to-markdown/scripts/main.ts
Normal file
@@ -0,0 +1,314 @@
|
||||
import { createInterface } from "node:readline";
|
||||
import { writeFile, mkdir, access } from "node:fs/promises";
|
||||
import path from "node:path";
|
||||
import process from "node:process";
|
||||
|
||||
import { CdpConnection, getFreePort, findExistingChromePort, launchChrome, waitForChromeDebugPort, waitForNetworkIdle, waitForPageLoad, autoScroll, evaluateScript, killChrome } from "./cdp.js";
|
||||
import { absolutizeUrlsScript, extractContent, createMarkdownDocument, type ConversionResult } from "./html-to-markdown.js";
|
||||
import { localizeMarkdownMedia, countRemoteMedia } from "./media-localizer.js";
|
||||
import { resolveUrlToMarkdownDataDir } from "./paths.js";
|
||||
import { DEFAULT_TIMEOUT_MS, CDP_CONNECT_TIMEOUT_MS, NETWORK_IDLE_TIMEOUT_MS, POST_LOAD_DELAY_MS, SCROLL_STEP_WAIT_MS, SCROLL_MAX_STEPS } from "./constants.js";
|
||||
|
||||
function sleep(ms: number): Promise<void> {
|
||||
return new Promise((resolve) => setTimeout(resolve, ms));
|
||||
}
|
||||
|
||||
async function fileExists(filePath: string): Promise<boolean> {
|
||||
try {
|
||||
await access(filePath);
|
||||
return true;
|
||||
} catch {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
interface Args {
|
||||
url: string;
|
||||
output?: string;
|
||||
outputDir?: string;
|
||||
wait: boolean;
|
||||
timeout: number;
|
||||
downloadMedia: boolean;
|
||||
}
|
||||
|
||||
function parseArgs(argv: string[]): Args {
|
||||
const args: Args = { url: "", wait: false, timeout: DEFAULT_TIMEOUT_MS, downloadMedia: false };
|
||||
for (let i = 2; i < argv.length; i++) {
|
||||
const arg = argv[i];
|
||||
if (arg === "--wait" || arg === "-w") {
|
||||
args.wait = true;
|
||||
} else if (arg === "-o" || arg === "--output") {
|
||||
args.output = argv[++i];
|
||||
} else if (arg === "--timeout" || arg === "-t") {
|
||||
args.timeout = parseInt(argv[++i], 10) || DEFAULT_TIMEOUT_MS;
|
||||
} else if (arg === "--output-dir") {
|
||||
args.outputDir = argv[++i];
|
||||
} else if (arg === "--download-media") {
|
||||
args.downloadMedia = true;
|
||||
} else if (!arg.startsWith("-") && !args.url) {
|
||||
args.url = arg;
|
||||
}
|
||||
}
|
||||
return args;
|
||||
}
|
||||
|
||||
function generateSlug(title: string, url: string): string {
|
||||
const text = title || new URL(url).pathname.replace(/\//g, "-");
|
||||
return text
|
||||
.toLowerCase()
|
||||
.replace(/[^\w\s-]/g, "")
|
||||
.replace(/\s+/g, "-")
|
||||
.replace(/-+/g, "-")
|
||||
.replace(/^-|-$/g, "")
|
||||
.slice(0, 50) || "page";
|
||||
}
|
||||
|
||||
function formatTimestamp(): string {
|
||||
const now = new Date();
|
||||
const pad = (n: number) => n.toString().padStart(2, "0");
|
||||
return `${now.getFullYear()}${pad(now.getMonth() + 1)}${pad(now.getDate())}-${pad(now.getHours())}${pad(now.getMinutes())}${pad(now.getSeconds())}`;
|
||||
}
|
||||
|
||||
function deriveHtmlSnapshotPath(markdownPath: string): string {
|
||||
const parsed = path.parse(markdownPath);
|
||||
const basename = parsed.ext ? parsed.name : parsed.base;
|
||||
return path.join(parsed.dir, `${basename}-captured.html`);
|
||||
}
|
||||
|
||||
function extractTitleFromMarkdownDocument(document: string): string {
|
||||
const normalized = document.replace(/\r\n/g, "\n");
|
||||
const frontmatterMatch = normalized.match(/^---\n([\s\S]*?)\n---\n?/);
|
||||
if (frontmatterMatch) {
|
||||
const titleLine = frontmatterMatch[1]
|
||||
.split("\n")
|
||||
.find((line) => /^title:\s*/i.test(line));
|
||||
|
||||
if (titleLine) {
|
||||
const rawValue = titleLine.replace(/^title:\s*/i, "").trim();
|
||||
const unquoted = rawValue
|
||||
.replace(/^"(.*)"$/, "$1")
|
||||
.replace(/^'(.*)'$/, "$1")
|
||||
.replace(/\\"/g, '"');
|
||||
if (unquoted) return unquoted;
|
||||
}
|
||||
}
|
||||
|
||||
const headingMatch = normalized.match(/^#\s+(.+)$/m);
|
||||
return headingMatch?.[1]?.trim() ?? "";
|
||||
}
|
||||
|
||||
function buildDefuddleApiUrl(targetUrl: string): string {
|
||||
return `https://defuddle.md/${encodeURIComponent(targetUrl)}`;
|
||||
}
|
||||
|
||||
async function fetchDefuddleApiMarkdown(targetUrl: string): Promise<{ markdown: string; title: string }> {
|
||||
const apiUrl = buildDefuddleApiUrl(targetUrl);
|
||||
const response = await fetch(apiUrl, {
|
||||
headers: {
|
||||
accept: "text/markdown,text/plain;q=0.9,*/*;q=0.1",
|
||||
},
|
||||
});
|
||||
|
||||
if (!response.ok) {
|
||||
throw new Error(`defuddle.md returned ${response.status} ${response.statusText}`);
|
||||
}
|
||||
|
||||
const markdown = (await response.text()).replace(/\r\n/g, "\n").trim();
|
||||
if (!markdown) {
|
||||
throw new Error("defuddle.md returned empty markdown");
|
||||
}
|
||||
|
||||
return {
|
||||
markdown,
|
||||
title: extractTitleFromMarkdownDocument(markdown),
|
||||
};
|
||||
}
|
||||
|
||||
async function generateOutputPath(url: string, title: string, outputDir?: string): Promise<string> {
|
||||
const domain = new URL(url).hostname.replace(/^www\./, "");
|
||||
const slug = generateSlug(title, url);
|
||||
const dataDir = outputDir ? path.resolve(outputDir) : resolveUrlToMarkdownDataDir();
|
||||
const basePath = path.join(dataDir, domain, `${slug}.md`);
|
||||
|
||||
if (!(await fileExists(basePath))) {
|
||||
return basePath;
|
||||
}
|
||||
|
||||
const timestampSlug = `${slug}-${formatTimestamp()}`;
|
||||
return path.join(dataDir, domain, `${timestampSlug}.md`);
|
||||
}
|
||||
|
||||
async function waitForUserSignal(): Promise<void> {
|
||||
console.log("Page opened. Press Enter when ready to capture...");
|
||||
const rl = createInterface({ input: process.stdin, output: process.stdout });
|
||||
await new Promise<void>((resolve) => {
|
||||
rl.once("line", () => { rl.close(); resolve(); });
|
||||
});
|
||||
}
|
||||
|
||||
async function captureUrl(args: Args): Promise<ConversionResult> {
|
||||
const existingPort = await findExistingChromePort();
|
||||
const reusing = existingPort !== null;
|
||||
const port = existingPort ?? await getFreePort();
|
||||
const chrome = reusing ? null : await launchChrome(args.url, port, false);
|
||||
|
||||
if (reusing) console.log(`Reusing existing Chrome on port ${port}`);
|
||||
|
||||
let cdp: CdpConnection | null = null;
|
||||
let targetId: string | null = null;
|
||||
try {
|
||||
const wsUrl = await waitForChromeDebugPort(port, 30_000);
|
||||
cdp = await CdpConnection.connect(wsUrl, CDP_CONNECT_TIMEOUT_MS);
|
||||
|
||||
let sessionId: string;
|
||||
if (reusing) {
|
||||
const created = await cdp.send<{ targetId: string }>("Target.createTarget", { url: args.url });
|
||||
targetId = created.targetId;
|
||||
const attached = await cdp.send<{ sessionId: string }>("Target.attachToTarget", { targetId, flatten: true });
|
||||
sessionId = attached.sessionId;
|
||||
await cdp.send("Network.enable", {}, { sessionId });
|
||||
await cdp.send("Page.enable", {}, { sessionId });
|
||||
} else {
|
||||
const targets = await cdp.send<{ targetInfos: Array<{ targetId: string; type: string; url: string }> }>("Target.getTargets");
|
||||
const pageTarget = targets.targetInfos.find(t => t.type === "page" && t.url.startsWith("http"));
|
||||
if (!pageTarget) throw new Error("No page target found");
|
||||
targetId = pageTarget.targetId;
|
||||
const attached = await cdp.send<{ sessionId: string }>("Target.attachToTarget", { targetId, flatten: true });
|
||||
sessionId = attached.sessionId;
|
||||
await cdp.send("Network.enable", {}, { sessionId });
|
||||
await cdp.send("Page.enable", {}, { sessionId });
|
||||
}
|
||||
|
||||
if (args.wait) {
|
||||
await waitForUserSignal();
|
||||
} else {
|
||||
console.log("Waiting for page to load...");
|
||||
await Promise.race([
|
||||
waitForPageLoad(cdp, sessionId, 15_000),
|
||||
sleep(8_000)
|
||||
]);
|
||||
await waitForNetworkIdle(cdp, sessionId, NETWORK_IDLE_TIMEOUT_MS);
|
||||
await sleep(POST_LOAD_DELAY_MS);
|
||||
console.log("Scrolling to trigger lazy load...");
|
||||
await autoScroll(cdp, sessionId, SCROLL_MAX_STEPS, SCROLL_STEP_WAIT_MS);
|
||||
await sleep(POST_LOAD_DELAY_MS);
|
||||
}
|
||||
|
||||
console.log("Capturing page content...");
|
||||
const { html } = await evaluateScript<{ html: string }>(
|
||||
cdp, sessionId, absolutizeUrlsScript, args.timeout
|
||||
);
|
||||
|
||||
return await extractContent(html, args.url);
|
||||
} finally {
|
||||
if (reusing) {
|
||||
if (cdp && targetId) {
|
||||
try { await cdp.send("Target.closeTarget", { targetId }, { timeoutMs: 5_000 }); } catch {}
|
||||
}
|
||||
if (cdp) cdp.close();
|
||||
} else {
|
||||
if (cdp) {
|
||||
try { await cdp.send("Browser.close", {}, { timeoutMs: 5_000 }); } catch {}
|
||||
cdp.close();
|
||||
}
|
||||
if (chrome) killChrome(chrome);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
async function main(): Promise<void> {
|
||||
const args = parseArgs(process.argv);
|
||||
if (!args.url) {
|
||||
console.error("Usage: bun main.ts <url> [-o output.md] [--output-dir dir] [--wait] [--timeout ms] [--download-media]");
|
||||
process.exit(1);
|
||||
}
|
||||
|
||||
try {
|
||||
new URL(args.url);
|
||||
} catch {
|
||||
console.error(`Invalid URL: ${args.url}`);
|
||||
process.exit(1);
|
||||
}
|
||||
|
||||
if (args.output) {
|
||||
const stat = await import("node:fs").then(fs => fs.statSync(args.output!, { throwIfNoEntry: false }));
|
||||
if (stat?.isDirectory()) {
|
||||
console.error(`Error: -o path is a directory, not a file: ${args.output}`);
|
||||
process.exit(1);
|
||||
}
|
||||
}
|
||||
|
||||
console.log(`Fetching: ${args.url}`);
|
||||
console.log(`Mode: ${args.wait ? "wait" : "auto"}`);
|
||||
|
||||
let outputPath: string;
|
||||
let htmlSnapshotPath: string | null = null;
|
||||
let document: string;
|
||||
let conversionMethod: string;
|
||||
let fallbackReason: string | undefined;
|
||||
|
||||
try {
|
||||
const result = await captureUrl(args);
|
||||
outputPath = args.output || await generateOutputPath(args.url, result.metadata.title, args.outputDir);
|
||||
const outputDir = path.dirname(outputPath);
|
||||
htmlSnapshotPath = deriveHtmlSnapshotPath(outputPath);
|
||||
await mkdir(outputDir, { recursive: true });
|
||||
await writeFile(htmlSnapshotPath, result.rawHtml, "utf-8");
|
||||
|
||||
document = createMarkdownDocument(result);
|
||||
conversionMethod = result.conversionMethod;
|
||||
fallbackReason = result.fallbackReason;
|
||||
} catch (error) {
|
||||
const primaryError = error instanceof Error ? error.message : String(error);
|
||||
console.warn(`Primary capture failed: ${primaryError}`);
|
||||
console.warn("Trying defuddle.md API fallback...");
|
||||
|
||||
try {
|
||||
const remoteResult = await fetchDefuddleApiMarkdown(args.url);
|
||||
outputPath = args.output || await generateOutputPath(args.url, remoteResult.title, args.outputDir);
|
||||
await mkdir(path.dirname(outputPath), { recursive: true });
|
||||
|
||||
document = remoteResult.markdown;
|
||||
conversionMethod = "defuddle-api";
|
||||
fallbackReason = `Local browser capture failed: ${primaryError}`;
|
||||
} catch (remoteError) {
|
||||
const remoteMessage = remoteError instanceof Error ? remoteError.message : String(remoteError);
|
||||
throw new Error(`Local browser capture failed (${primaryError}); defuddle.md fallback failed (${remoteMessage})`);
|
||||
}
|
||||
}
|
||||
|
||||
if (args.downloadMedia) {
|
||||
const mediaResult = await localizeMarkdownMedia(document, {
|
||||
markdownPath: outputPath,
|
||||
log: console.log,
|
||||
});
|
||||
document = mediaResult.markdown;
|
||||
if (mediaResult.downloadedImages > 0 || mediaResult.downloadedVideos > 0) {
|
||||
console.log(`Downloaded: ${mediaResult.downloadedImages} images, ${mediaResult.downloadedVideos} videos`);
|
||||
}
|
||||
} else {
|
||||
const { images, videos } = countRemoteMedia(document);
|
||||
if (images > 0 || videos > 0) {
|
||||
console.log(`Remote media found: ${images} images, ${videos} videos`);
|
||||
}
|
||||
}
|
||||
|
||||
await writeFile(outputPath, document, "utf-8");
|
||||
|
||||
console.log(`Saved: ${outputPath}`);
|
||||
if (htmlSnapshotPath) {
|
||||
console.log(`Saved HTML: ${htmlSnapshotPath}`);
|
||||
} else {
|
||||
console.log("Saved HTML: unavailable (defuddle.md fallback)");
|
||||
}
|
||||
console.log(`Title: ${extractTitleFromMarkdownDocument(document) || "(no title)"}`);
|
||||
console.log(`Converter: ${conversionMethod}`);
|
||||
if (fallbackReason) {
|
||||
console.warn(`Fallback used: ${fallbackReason}`);
|
||||
}
|
||||
}
|
||||
|
||||
main().catch((err) => {
|
||||
console.error("Error:", err instanceof Error ? err.message : String(err));
|
||||
process.exit(1);
|
||||
});
|
||||
@@ -0,0 +1,305 @@
|
||||
import { parseHTML } from "linkedom";
|
||||
|
||||
export interface PageMetadata {
|
||||
url: string;
|
||||
title: string;
|
||||
description?: string;
|
||||
author?: string;
|
||||
published?: string;
|
||||
coverImage?: string;
|
||||
language?: string;
|
||||
captured_at: string;
|
||||
}
|
||||
|
||||
export interface ConversionResult {
|
||||
metadata: PageMetadata;
|
||||
markdown: string;
|
||||
rawHtml: string;
|
||||
conversionMethod: string;
|
||||
fallbackReason?: string;
|
||||
variables?: Record<string, string>;
|
||||
}
|
||||
|
||||
export type AnyRecord = Record<string, unknown>;
|
||||
|
||||
export const MIN_CONTENT_LENGTH = 120;
|
||||
export const GOOD_CONTENT_LENGTH = 900;
|
||||
|
||||
const PUBLISHED_TIME_SELECTORS = [
|
||||
"meta[property='article:published_time']",
|
||||
"meta[name='pubdate']",
|
||||
"meta[name='publishdate']",
|
||||
"meta[name='date']",
|
||||
"time[datetime]",
|
||||
];
|
||||
|
||||
const ARTICLE_TYPES = new Set([
|
||||
"Article",
|
||||
"NewsArticle",
|
||||
"BlogPosting",
|
||||
"WebPage",
|
||||
"ReportageNewsArticle",
|
||||
]);
|
||||
|
||||
export function pickString(...values: unknown[]): string | null {
|
||||
for (const value of values) {
|
||||
if (typeof value === "string") {
|
||||
const trimmed = value.trim();
|
||||
if (trimmed) return trimmed;
|
||||
}
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
export function normalizeMarkdown(markdown: string): string {
|
||||
return markdown
|
||||
.replace(/\r\n/g, "\n")
|
||||
.replace(/[ \t]+\n/g, "\n")
|
||||
.replace(/\n{3,}/g, "\n\n")
|
||||
.trim();
|
||||
}
|
||||
|
||||
export function parseDocument(html: string): Document {
|
||||
const normalized = /<\s*html[\s>]/i.test(html)
|
||||
? html
|
||||
: `<!doctype html><html><body>${html}</body></html>`;
|
||||
return parseHTML(normalized).document as unknown as Document;
|
||||
}
|
||||
|
||||
export function sanitizeHtml(html: string): string {
|
||||
const { document } = parseHTML(`<div id="__root">${html}</div>`);
|
||||
const root = document.querySelector("#__root");
|
||||
if (!root) return html;
|
||||
|
||||
for (const selector of ["script", "style", "iframe", "noscript", "template", "svg", "path"]) {
|
||||
for (const el of root.querySelectorAll(selector)) {
|
||||
el.remove();
|
||||
}
|
||||
}
|
||||
|
||||
return root.innerHTML;
|
||||
}
|
||||
|
||||
export function extractTextFromHtml(html: string): string {
|
||||
const { document } = parseHTML(`<!doctype html><html><body>${html}</body></html>`);
|
||||
for (const selector of ["script", "style", "noscript", "template", "iframe", "svg", "path"]) {
|
||||
for (const el of document.querySelectorAll(selector)) {
|
||||
el.remove();
|
||||
}
|
||||
}
|
||||
return document.body?.textContent?.replace(/\s+/g, " ").trim() ?? "";
|
||||
}
|
||||
|
||||
export function getMetaContent(document: Document, names: string[]): string | null {
|
||||
for (const name of names) {
|
||||
const element =
|
||||
document.querySelector(`meta[name="${name}"]`) ??
|
||||
document.querySelector(`meta[property="${name}"]`);
|
||||
const content = element?.getAttribute("content");
|
||||
if (content && content.trim()) return content.trim();
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
function normalizeLanguageTag(value: string | null): string | null {
|
||||
if (!value) return null;
|
||||
|
||||
const trimmed = value.trim();
|
||||
if (!trimmed) return null;
|
||||
|
||||
const primary = trimmed.split(/[,\s;]/, 1)[0]?.trim();
|
||||
if (!primary) return null;
|
||||
|
||||
return primary.replace(/_/g, "-");
|
||||
}
|
||||
|
||||
function flattenJsonLdItems(data: unknown): AnyRecord[] {
|
||||
if (!data || typeof data !== "object") return [];
|
||||
if (Array.isArray(data)) return data.flatMap(flattenJsonLdItems);
|
||||
|
||||
const item = data as AnyRecord;
|
||||
if (Array.isArray(item["@graph"])) {
|
||||
return (item["@graph"] as unknown[]).flatMap(flattenJsonLdItems);
|
||||
}
|
||||
|
||||
return [item];
|
||||
}
|
||||
|
||||
function parseJsonLdScripts(document: Document): AnyRecord[] {
|
||||
const results: AnyRecord[] = [];
|
||||
const scripts = document.querySelectorAll("script[type='application/ld+json']");
|
||||
|
||||
for (const script of scripts) {
|
||||
try {
|
||||
const data = JSON.parse(script.textContent ?? "");
|
||||
results.push(...flattenJsonLdItems(data));
|
||||
} catch {
|
||||
// Ignore malformed blocks.
|
||||
}
|
||||
}
|
||||
|
||||
return results;
|
||||
}
|
||||
|
||||
function isArticleType(item: AnyRecord): boolean {
|
||||
const value = Array.isArray(item["@type"]) ? item["@type"][0] : item["@type"];
|
||||
return typeof value === "string" && ARTICLE_TYPES.has(value);
|
||||
}
|
||||
|
||||
function extractAuthorFromJsonLd(authorData: unknown): string | null {
|
||||
if (typeof authorData === "string") return authorData;
|
||||
if (!authorData || typeof authorData !== "object") return null;
|
||||
|
||||
if (Array.isArray(authorData)) {
|
||||
const names = authorData
|
||||
.map((author) => extractAuthorFromJsonLd(author))
|
||||
.filter((name): name is string => Boolean(name));
|
||||
return names.length > 0 ? names.join(", ") : null;
|
||||
}
|
||||
|
||||
const author = authorData as AnyRecord;
|
||||
return typeof author.name === "string" ? author.name : null;
|
||||
}
|
||||
|
||||
function extractPrimaryJsonLdMeta(document: Document): Partial<PageMetadata> {
|
||||
for (const item of parseJsonLdScripts(document)) {
|
||||
if (!isArticleType(item)) continue;
|
||||
|
||||
return {
|
||||
title: pickString(item.headline, item.name) ?? undefined,
|
||||
description: pickString(item.description) ?? undefined,
|
||||
author: extractAuthorFromJsonLd(item.author) ?? undefined,
|
||||
published: pickString(item.datePublished, item.dateCreated) ?? undefined,
|
||||
coverImage:
|
||||
pickString(
|
||||
item.image,
|
||||
(item.image as AnyRecord | undefined)?.url,
|
||||
(Array.isArray(item.image) ? item.image[0] : undefined) as unknown
|
||||
) ?? undefined,
|
||||
};
|
||||
}
|
||||
|
||||
return {};
|
||||
}
|
||||
|
||||
export function extractPublishedTime(document: Document): string | null {
|
||||
for (const selector of PUBLISHED_TIME_SELECTORS) {
|
||||
const el = document.querySelector(selector);
|
||||
if (!el) continue;
|
||||
const value = el.getAttribute("content") ?? el.getAttribute("datetime");
|
||||
if (value && value.trim()) return value.trim();
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
export function extractTitle(document: Document): string | null {
|
||||
const ogTitle = document.querySelector("meta[property='og:title']")?.getAttribute("content");
|
||||
if (ogTitle && ogTitle.trim()) return ogTitle.trim();
|
||||
|
||||
const twitterTitle = document.querySelector("meta[name='twitter:title']")?.getAttribute("content");
|
||||
if (twitterTitle && twitterTitle.trim()) return twitterTitle.trim();
|
||||
|
||||
const title = document.querySelector("title")?.textContent?.trim();
|
||||
if (title) {
|
||||
const cleaned = title.split(/\s*[-|–—]\s*/)[0]?.trim();
|
||||
if (cleaned) return cleaned;
|
||||
}
|
||||
|
||||
const h1 = document.querySelector("h1")?.textContent?.trim();
|
||||
return h1 || null;
|
||||
}
|
||||
|
||||
export function extractMetadataFromHtml(html: string, url: string, capturedAt: string): PageMetadata {
|
||||
const document = parseDocument(html);
|
||||
const jsonLd = extractPrimaryJsonLdMeta(document);
|
||||
const timeEl = document.querySelector("time[datetime]");
|
||||
const htmlLang = normalizeLanguageTag(document.documentElement?.getAttribute("lang"));
|
||||
const metaLanguage = normalizeLanguageTag(
|
||||
pickString(
|
||||
getMetaContent(document, ["language", "content-language", "og:locale"]),
|
||||
document.querySelector("meta[http-equiv='content-language']")?.getAttribute("content")
|
||||
)
|
||||
);
|
||||
|
||||
return {
|
||||
url,
|
||||
title:
|
||||
pickString(
|
||||
getMetaContent(document, ["og:title", "twitter:title"]),
|
||||
jsonLd.title,
|
||||
document.querySelector("h1")?.textContent,
|
||||
document.title
|
||||
) ?? "",
|
||||
description:
|
||||
pickString(
|
||||
getMetaContent(document, ["description", "og:description", "twitter:description"]),
|
||||
jsonLd.description
|
||||
) ?? undefined,
|
||||
author:
|
||||
pickString(
|
||||
getMetaContent(document, ["author", "article:author", "twitter:creator"]),
|
||||
jsonLd.author
|
||||
) ?? undefined,
|
||||
published:
|
||||
pickString(
|
||||
timeEl?.getAttribute("datetime"),
|
||||
getMetaContent(document, ["article:published_time", "datePublished", "publishdate", "date"]),
|
||||
jsonLd.published,
|
||||
extractPublishedTime(document)
|
||||
) ?? undefined,
|
||||
coverImage:
|
||||
pickString(
|
||||
getMetaContent(document, ["og:image", "twitter:image", "twitter:image:src"]),
|
||||
jsonLd.coverImage
|
||||
) ?? undefined,
|
||||
language: pickString(htmlLang, metaLanguage) ?? undefined,
|
||||
captured_at: capturedAt,
|
||||
};
|
||||
}
|
||||
|
||||
export function isMarkdownUsable(markdown: string, html: string): boolean {
|
||||
const normalized = normalizeMarkdown(markdown);
|
||||
if (!normalized) return false;
|
||||
|
||||
const htmlTextLength = extractTextFromHtml(html).length;
|
||||
if (htmlTextLength < MIN_CONTENT_LENGTH) return true;
|
||||
|
||||
if (normalized.length >= 80) return true;
|
||||
return normalized.length >= Math.min(200, Math.floor(htmlTextLength * 0.2));
|
||||
}
|
||||
|
||||
export function isYouTubeUrl(url: string): boolean {
|
||||
try {
|
||||
const hostname = new URL(url).hostname.toLowerCase();
|
||||
return hostname === "youtu.be" || hostname.endsWith(".youtube.com") || hostname === "youtube.com";
|
||||
} catch {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
function escapeYamlValue(value: string): string {
|
||||
return value.replace(/\\/g, "\\\\").replace(/"/g, '\\"').replace(/\r?\n/g, "\\n");
|
||||
}
|
||||
|
||||
export function formatMetadataYaml(meta: PageMetadata): string {
|
||||
const lines = ["---"];
|
||||
lines.push(`url: ${meta.url}`);
|
||||
lines.push(`title: "${escapeYamlValue(meta.title)}"`);
|
||||
if (meta.description) lines.push(`description: "${escapeYamlValue(meta.description)}"`);
|
||||
if (meta.author) lines.push(`author: "${escapeYamlValue(meta.author)}"`);
|
||||
if (meta.published) lines.push(`published: "${escapeYamlValue(meta.published)}"`);
|
||||
if (meta.coverImage) lines.push(`coverImage: "${escapeYamlValue(meta.coverImage)}"`);
|
||||
if (meta.language) lines.push(`language: "${escapeYamlValue(meta.language)}"`);
|
||||
lines.push(`captured_at: "${escapeYamlValue(meta.captured_at)}"`);
|
||||
lines.push("---");
|
||||
return lines.join("\n");
|
||||
}
|
||||
|
||||
export function createMarkdownDocument(result: ConversionResult): string {
|
||||
const yaml = formatMetadataYaml(result.metadata);
|
||||
const escapedTitle = result.metadata.title.replace(/[.*+?^${}()|[\]\\]/g, "\\$&");
|
||||
const titleRegex = new RegExp(`^#\\s+${escapedTitle}\\s*(\\n|$)`, "i");
|
||||
const hasTitle = titleRegex.test(result.markdown.trimStart());
|
||||
const title = result.metadata.title && !hasTitle ? `\n\n# ${result.metadata.title}\n\n` : "\n\n";
|
||||
return yaml + title + result.markdown;
|
||||
}
|
||||
317
llm-wiki/deps/baoyu-url-to-markdown/scripts/media-localizer.ts
Normal file
317
llm-wiki/deps/baoyu-url-to-markdown/scripts/media-localizer.ts
Normal file
@@ -0,0 +1,317 @@
|
||||
import path from "node:path";
|
||||
import { mkdir, writeFile } from "node:fs/promises";
|
||||
|
||||
type MediaKind = "image" | "video";
|
||||
type MediaHint = "image" | "unknown";
|
||||
|
||||
type MarkdownLinkCandidate = {
|
||||
url: string;
|
||||
hint: MediaHint;
|
||||
};
|
||||
|
||||
export type LocalizeMarkdownMediaOptions = {
|
||||
markdownPath: string;
|
||||
log?: (message: string) => void;
|
||||
};
|
||||
|
||||
export type LocalizeMarkdownMediaResult = {
|
||||
markdown: string;
|
||||
downloadedImages: number;
|
||||
downloadedVideos: number;
|
||||
imageDir: string | null;
|
||||
videoDir: string | null;
|
||||
};
|
||||
|
||||
const MARKDOWN_LINK_RE = /(!?\[[^\]\n]*\])\((<)?(https?:\/\/[^)\s>]+)(>)?\)/g;
|
||||
const FRONTMATTER_COVER_RE = /^(coverImage:\s*")(https?:\/\/[^"]+)(")/m;
|
||||
|
||||
const IMAGE_EXTENSIONS = new Set([
|
||||
"jpg",
|
||||
"jpeg",
|
||||
"png",
|
||||
"webp",
|
||||
"gif",
|
||||
"bmp",
|
||||
"avif",
|
||||
"heic",
|
||||
"heif",
|
||||
"svg",
|
||||
]);
|
||||
|
||||
const VIDEO_EXTENSIONS = new Set(["mp4", "m4v", "mov", "webm", "mkv"]);
|
||||
|
||||
const MIME_EXTENSION_MAP: Record<string, string> = {
|
||||
"image/jpeg": "jpg",
|
||||
"image/jpg": "jpg",
|
||||
"image/png": "png",
|
||||
"image/webp": "webp",
|
||||
"image/gif": "gif",
|
||||
"image/bmp": "bmp",
|
||||
"image/avif": "avif",
|
||||
"image/heic": "heic",
|
||||
"image/heif": "heif",
|
||||
"image/svg+xml": "svg",
|
||||
"video/mp4": "mp4",
|
||||
"video/webm": "webm",
|
||||
"video/quicktime": "mov",
|
||||
"video/x-m4v": "m4v",
|
||||
};
|
||||
|
||||
const DOWNLOAD_USER_AGENT =
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.0.0 Safari/537.36";
|
||||
|
||||
function normalizeContentType(raw: string | null): string {
|
||||
return raw?.split(";")[0]?.trim().toLowerCase() ?? "";
|
||||
}
|
||||
|
||||
function normalizeExtension(raw: string | undefined | null): string | undefined {
|
||||
if (!raw) return undefined;
|
||||
const trimmed = raw.replace(/^\./, "").trim().toLowerCase();
|
||||
if (!trimmed) return undefined;
|
||||
if (trimmed === "jpeg") return "jpg";
|
||||
if (trimmed === "jpg") return "jpg";
|
||||
return trimmed;
|
||||
}
|
||||
|
||||
function resolveExtensionFromUrl(rawUrl: string): string | undefined {
|
||||
try {
|
||||
const parsed = new URL(rawUrl);
|
||||
const extFromPath = normalizeExtension(path.posix.extname(parsed.pathname));
|
||||
if (extFromPath) return extFromPath;
|
||||
const extFromFormat = normalizeExtension(parsed.searchParams.get("format"));
|
||||
if (extFromFormat) return extFromFormat;
|
||||
} catch {
|
||||
return undefined;
|
||||
}
|
||||
return undefined;
|
||||
}
|
||||
|
||||
function resolveKindFromContentType(contentType: string): MediaKind | undefined {
|
||||
if (!contentType) return undefined;
|
||||
if (contentType.startsWith("image/")) return "image";
|
||||
if (contentType.startsWith("video/")) return "video";
|
||||
return undefined;
|
||||
}
|
||||
|
||||
function resolveKindFromExtension(ext: string | undefined): MediaKind | undefined {
|
||||
if (!ext) return undefined;
|
||||
if (IMAGE_EXTENSIONS.has(ext)) return "image";
|
||||
if (VIDEO_EXTENSIONS.has(ext)) return "video";
|
||||
return undefined;
|
||||
}
|
||||
|
||||
function resolveMediaKind(
|
||||
rawUrl: string,
|
||||
contentType: string,
|
||||
extension: string | undefined,
|
||||
hint: MediaHint
|
||||
): MediaKind | undefined {
|
||||
const kindFromType = resolveKindFromContentType(contentType);
|
||||
if (kindFromType) return kindFromType;
|
||||
|
||||
const kindFromExtension = resolveKindFromExtension(extension);
|
||||
if (kindFromExtension) return kindFromExtension;
|
||||
|
||||
if (contentType && contentType !== "application/octet-stream") {
|
||||
return undefined;
|
||||
}
|
||||
|
||||
return hint === "image" ? "image" : undefined;
|
||||
}
|
||||
|
||||
function resolveOutputExtension(
|
||||
contentType: string,
|
||||
extension: string | undefined,
|
||||
kind: MediaKind
|
||||
): string {
|
||||
const extFromMime = normalizeExtension(MIME_EXTENSION_MAP[contentType]);
|
||||
if (extFromMime) return extFromMime;
|
||||
|
||||
const normalizedExt = normalizeExtension(extension);
|
||||
if (normalizedExt) return normalizedExt;
|
||||
|
||||
return kind === "video" ? "mp4" : "jpg";
|
||||
}
|
||||
|
||||
function safeDecodeURIComponent(value: string): string {
|
||||
try {
|
||||
return decodeURIComponent(value);
|
||||
} catch {
|
||||
return value;
|
||||
}
|
||||
}
|
||||
|
||||
function sanitizeFileSegment(input: string): string {
|
||||
return input
|
||||
.replace(/[^a-zA-Z0-9_-]+/g, "-")
|
||||
.replace(/-+/g, "-")
|
||||
.replace(/^[-_]+|[-_]+$/g, "")
|
||||
.slice(0, 48);
|
||||
}
|
||||
|
||||
function resolveFileStem(rawUrl: string, extension: string): string {
|
||||
try {
|
||||
const parsed = new URL(rawUrl);
|
||||
const base = path.posix.basename(parsed.pathname);
|
||||
if (!base) return "";
|
||||
const decodedBase = safeDecodeURIComponent(base);
|
||||
const normalizedExt = normalizeExtension(extension);
|
||||
const stripExt = normalizedExt ? new RegExp(`\\.${normalizedExt}$`, "i") : null;
|
||||
const rawStem = stripExt ? decodedBase.replace(stripExt, "") : decodedBase;
|
||||
return sanitizeFileSegment(rawStem);
|
||||
} catch {
|
||||
return "";
|
||||
}
|
||||
}
|
||||
|
||||
function buildFileName(kind: MediaKind, index: number, sourceUrl: string, extension: string): string {
|
||||
const stem = resolveFileStem(sourceUrl, extension);
|
||||
const prefix = kind === "image" ? "img" : "video";
|
||||
const serial = String(index).padStart(3, "0");
|
||||
const suffix = stem ? `-${stem}` : "";
|
||||
return `${prefix}-${serial}${suffix}.${extension}`;
|
||||
}
|
||||
|
||||
function collectMarkdownLinkCandidates(markdown: string): MarkdownLinkCandidate[] {
|
||||
const candidates: MarkdownLinkCandidate[] = [];
|
||||
const seen = new Set<string>();
|
||||
|
||||
const fmMatch = markdown.match(/^---\n([\s\S]*?)\n---/);
|
||||
if (fmMatch) {
|
||||
const coverMatch = fmMatch[1]?.match(FRONTMATTER_COVER_RE);
|
||||
if (coverMatch?.[2] && !seen.has(coverMatch[2])) {
|
||||
seen.add(coverMatch[2]);
|
||||
candidates.push({ url: coverMatch[2], hint: "image" });
|
||||
}
|
||||
}
|
||||
|
||||
MARKDOWN_LINK_RE.lastIndex = 0;
|
||||
let match: RegExpExecArray | null;
|
||||
while ((match = MARKDOWN_LINK_RE.exec(markdown))) {
|
||||
const label = match[1] ?? "";
|
||||
const rawUrl = match[3] ?? "";
|
||||
if (!rawUrl || seen.has(rawUrl)) continue;
|
||||
seen.add(rawUrl);
|
||||
candidates.push({
|
||||
url: rawUrl,
|
||||
hint: label.startsWith("![") ? "image" : "unknown",
|
||||
});
|
||||
}
|
||||
|
||||
return candidates;
|
||||
}
|
||||
|
||||
function rewriteMarkdownMediaLinks(markdown: string, replacements: Map<string, string>): string {
|
||||
if (replacements.size === 0) return markdown;
|
||||
MARKDOWN_LINK_RE.lastIndex = 0;
|
||||
|
||||
let result = markdown.replace(MARKDOWN_LINK_RE, (full, label, _openAngle, rawUrl) => {
|
||||
const localPath = replacements.get(rawUrl);
|
||||
if (!localPath) return full;
|
||||
return `${label}(${localPath})`;
|
||||
});
|
||||
|
||||
result = result.replace(FRONTMATTER_COVER_RE, (full, prefix, rawUrl, suffix) => {
|
||||
const localPath = replacements.get(rawUrl);
|
||||
if (!localPath) return full;
|
||||
return `${prefix}${localPath}${suffix}`;
|
||||
});
|
||||
|
||||
return result;
|
||||
}
|
||||
|
||||
export async function localizeMarkdownMedia(
|
||||
markdown: string,
|
||||
options: LocalizeMarkdownMediaOptions
|
||||
): Promise<LocalizeMarkdownMediaResult> {
|
||||
const log = options.log ?? (() => {});
|
||||
const markdownDir = path.dirname(options.markdownPath);
|
||||
const candidates = collectMarkdownLinkCandidates(markdown);
|
||||
|
||||
if (candidates.length === 0) {
|
||||
return {
|
||||
markdown,
|
||||
downloadedImages: 0,
|
||||
downloadedVideos: 0,
|
||||
imageDir: null,
|
||||
videoDir: null,
|
||||
};
|
||||
}
|
||||
|
||||
const replacements = new Map<string, string>();
|
||||
let downloadedImages = 0;
|
||||
let downloadedVideos = 0;
|
||||
|
||||
for (const candidate of candidates) {
|
||||
try {
|
||||
const response = await fetch(candidate.url, {
|
||||
method: "GET",
|
||||
redirect: "follow",
|
||||
headers: {
|
||||
"user-agent": DOWNLOAD_USER_AGENT,
|
||||
},
|
||||
});
|
||||
|
||||
if (!response.ok) {
|
||||
log(`[url-to-markdown] Skip media (${response.status}): ${candidate.url}`);
|
||||
continue;
|
||||
}
|
||||
|
||||
const sourceUrl = response.url || candidate.url;
|
||||
const contentType = normalizeContentType(response.headers.get("content-type"));
|
||||
const extension = resolveExtensionFromUrl(sourceUrl) ?? resolveExtensionFromUrl(candidate.url);
|
||||
const kind = resolveMediaKind(sourceUrl, contentType, extension, candidate.hint);
|
||||
if (!kind) {
|
||||
continue;
|
||||
}
|
||||
|
||||
const outputExtension = resolveOutputExtension(contentType, extension, kind);
|
||||
const nextIndex = kind === "image" ? downloadedImages + 1 : downloadedVideos + 1;
|
||||
const dirName = kind === "image" ? "imgs" : "videos";
|
||||
const targetDir = path.join(markdownDir, dirName);
|
||||
await mkdir(targetDir, { recursive: true });
|
||||
|
||||
const fileName = buildFileName(kind, nextIndex, sourceUrl, outputExtension);
|
||||
const absolutePath = path.join(targetDir, fileName);
|
||||
const relativePath = path.posix.join(dirName, fileName);
|
||||
const bytes = Buffer.from(await response.arrayBuffer());
|
||||
await writeFile(absolutePath, bytes);
|
||||
replacements.set(candidate.url, relativePath);
|
||||
|
||||
if (kind === "image") {
|
||||
downloadedImages = nextIndex;
|
||||
} else {
|
||||
downloadedVideos = nextIndex;
|
||||
}
|
||||
} catch (error) {
|
||||
const message = error instanceof Error ? error.message : String(error ?? "");
|
||||
log(`[url-to-markdown] Failed to download media ${candidate.url}: ${message}`);
|
||||
}
|
||||
}
|
||||
|
||||
return {
|
||||
markdown: rewriteMarkdownMediaLinks(markdown, replacements),
|
||||
downloadedImages,
|
||||
downloadedVideos,
|
||||
imageDir: downloadedImages > 0 ? path.join(markdownDir, "imgs") : null,
|
||||
videoDir: downloadedVideos > 0 ? path.join(markdownDir, "videos") : null,
|
||||
};
|
||||
}
|
||||
|
||||
export function countRemoteMedia(markdown: string): { images: number; videos: number; hasCoverImage: boolean } {
|
||||
const fmMatch = markdown.match(/^---\n([\s\S]*?)\n---/);
|
||||
const hasCoverImage = !!(fmMatch?.[1]?.match(FRONTMATTER_COVER_RE)?.[2]);
|
||||
const candidates = collectMarkdownLinkCandidates(markdown);
|
||||
let images = 0;
|
||||
let videos = 0;
|
||||
for (const c of candidates) {
|
||||
const ext = resolveExtensionFromUrl(c.url);
|
||||
const kind = resolveKindFromExtension(ext);
|
||||
if (kind === "video") {
|
||||
videos++;
|
||||
} else if (kind === "image" || c.hint === "image") {
|
||||
images++;
|
||||
}
|
||||
}
|
||||
return { images, videos, hasCoverImage };
|
||||
}
|
||||
14
llm-wiki/deps/baoyu-url-to-markdown/scripts/package.json
Normal file
14
llm-wiki/deps/baoyu-url-to-markdown/scripts/package.json
Normal file
@@ -0,0 +1,14 @@
|
||||
{
|
||||
"name": "baoyu-url-to-markdown-scripts",
|
||||
"private": true,
|
||||
"type": "module",
|
||||
"dependencies": {
|
||||
"@mozilla/readability": "^0.6.0",
|
||||
"baoyu-chrome-cdp": "file:./vendor/baoyu-chrome-cdp",
|
||||
"defuddle": "^0.12.0",
|
||||
"jsdom": "^24.1.3",
|
||||
"linkedom": "^0.18.12",
|
||||
"turndown": "^7.2.2",
|
||||
"turndown-plugin-gfm": "^1.0.2"
|
||||
}
|
||||
}
|
||||
29
llm-wiki/deps/baoyu-url-to-markdown/scripts/paths.ts
Normal file
29
llm-wiki/deps/baoyu-url-to-markdown/scripts/paths.ts
Normal file
@@ -0,0 +1,29 @@
|
||||
import os from "node:os";
|
||||
import path from "node:path";
|
||||
import process from "node:process";
|
||||
|
||||
const APP_DATA_DIR = "baoyu-skills";
|
||||
const URL_TO_MARKDOWN_DATA_DIR = "url-to-markdown";
|
||||
const PROFILE_DIR_NAME = "chrome-profile";
|
||||
|
||||
export function resolveUserDataRoot(): string {
|
||||
if (process.platform === "win32") {
|
||||
return process.env.APPDATA ?? path.join(os.homedir(), "AppData", "Roaming");
|
||||
}
|
||||
if (process.platform === "darwin") {
|
||||
return path.join(os.homedir(), "Library", "Application Support");
|
||||
}
|
||||
return process.env.XDG_DATA_HOME ?? path.join(os.homedir(), ".local", "share");
|
||||
}
|
||||
|
||||
export function resolveUrlToMarkdownDataDir(): string {
|
||||
const override = process.env.URL_DATA_DIR?.trim();
|
||||
if (override) return path.resolve(override);
|
||||
return path.join(process.cwd(), URL_TO_MARKDOWN_DATA_DIR);
|
||||
}
|
||||
|
||||
export function resolveUrlToMarkdownChromeProfileDir(): string {
|
||||
const override = process.env.BAOYU_CHROME_PROFILE_DIR?.trim() || process.env.URL_CHROME_PROFILE_DIR?.trim();
|
||||
if (override) return path.resolve(override);
|
||||
return path.join(resolveUserDataRoot(), APP_DATA_DIR, PROFILE_DIR_NAME);
|
||||
}
|
||||
9
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/package.json
vendored
Normal file
9
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/package.json
vendored
Normal file
@@ -0,0 +1,9 @@
|
||||
{
|
||||
"name": "baoyu-chrome-cdp",
|
||||
"private": true,
|
||||
"version": "0.1.0",
|
||||
"type": "module",
|
||||
"exports": {
|
||||
".": "./src/index.ts"
|
||||
}
|
||||
}
|
||||
307
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/src/index.test.ts
vendored
Normal file
307
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/src/index.test.ts
vendored
Normal file
@@ -0,0 +1,307 @@
|
||||
import assert from "node:assert/strict";
|
||||
import { spawn, type ChildProcess } from "node:child_process";
|
||||
import fs from "node:fs/promises";
|
||||
import http from "node:http";
|
||||
import os from "node:os";
|
||||
import path from "node:path";
|
||||
import process from "node:process";
|
||||
import test, { type TestContext } from "node:test";
|
||||
|
||||
import {
|
||||
discoverRunningChromeDebugPort,
|
||||
findChromeExecutable,
|
||||
findExistingChromeDebugPort,
|
||||
getFreePort,
|
||||
openPageSession,
|
||||
resolveSharedChromeProfileDir,
|
||||
waitForChromeDebugPort,
|
||||
} from "./index.ts";
|
||||
|
||||
function useEnv(
|
||||
t: TestContext,
|
||||
values: Record<string, string | null>,
|
||||
): void {
|
||||
const previous = new Map<string, string | undefined>();
|
||||
for (const [key, value] of Object.entries(values)) {
|
||||
previous.set(key, process.env[key]);
|
||||
if (value == null) {
|
||||
delete process.env[key];
|
||||
} else {
|
||||
process.env[key] = value;
|
||||
}
|
||||
}
|
||||
|
||||
t.after(() => {
|
||||
for (const [key, value] of previous.entries()) {
|
||||
if (value == null) {
|
||||
delete process.env[key];
|
||||
} else {
|
||||
process.env[key] = value;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
async function makeTempDir(prefix: string): Promise<string> {
|
||||
return fs.mkdtemp(path.join(os.tmpdir(), prefix));
|
||||
}
|
||||
|
||||
async function startDebugServer(port: number): Promise<http.Server> {
|
||||
const server = http.createServer((req, res) => {
|
||||
if (req.url === "/json/version") {
|
||||
res.writeHead(200, { "Content-Type": "application/json" });
|
||||
res.end(JSON.stringify({
|
||||
webSocketDebuggerUrl: `ws://127.0.0.1:${port}/devtools/browser/demo`,
|
||||
}));
|
||||
return;
|
||||
}
|
||||
|
||||
res.writeHead(404);
|
||||
res.end();
|
||||
});
|
||||
|
||||
await new Promise<void>((resolve, reject) => {
|
||||
server.once("error", reject);
|
||||
server.listen(port, "127.0.0.1", () => resolve());
|
||||
});
|
||||
|
||||
return server;
|
||||
}
|
||||
|
||||
async function closeServer(server: http.Server): Promise<void> {
|
||||
await new Promise<void>((resolve, reject) => {
|
||||
server.close((error) => {
|
||||
if (error) reject(error);
|
||||
else resolve();
|
||||
});
|
||||
});
|
||||
}
|
||||
|
||||
function shellPathForPlatform(): string | null {
|
||||
if (process.platform === "win32") return null;
|
||||
return "/bin/bash";
|
||||
}
|
||||
|
||||
async function startFakeChromiumProcess(port: number): Promise<ChildProcess | null> {
|
||||
const shell = shellPathForPlatform();
|
||||
if (!shell) return null;
|
||||
|
||||
const child = spawn(
|
||||
shell,
|
||||
[
|
||||
"-lc",
|
||||
`exec -a chromium-mock ${JSON.stringify(process.execPath)} -e 'setInterval(() => {}, 1000)' -- --remote-debugging-port=${port}`,
|
||||
],
|
||||
{ stdio: "ignore" },
|
||||
);
|
||||
|
||||
await new Promise((resolve) => setTimeout(resolve, 250));
|
||||
return child;
|
||||
}
|
||||
|
||||
async function stopProcess(child: ChildProcess | null): Promise<void> {
|
||||
if (!child) return;
|
||||
if (child.exitCode !== null || child.signalCode !== null) return;
|
||||
|
||||
child.kill("SIGTERM");
|
||||
await new Promise((resolve) => setTimeout(resolve, 100));
|
||||
if (child.exitCode === null && child.signalCode === null) child.kill("SIGKILL");
|
||||
if (child.exitCode !== null || child.signalCode !== null) return;
|
||||
await new Promise((resolve) => child.once("exit", resolve));
|
||||
}
|
||||
|
||||
test("getFreePort honors a fixed environment override and otherwise allocates a TCP port", async (t) => {
|
||||
useEnv(t, { TEST_FIXED_PORT: "45678" });
|
||||
assert.equal(await getFreePort("TEST_FIXED_PORT"), 45678);
|
||||
|
||||
const dynamicPort = await getFreePort();
|
||||
assert.ok(Number.isInteger(dynamicPort));
|
||||
assert.ok(dynamicPort > 0);
|
||||
});
|
||||
|
||||
test("findChromeExecutable prefers env overrides and falls back to candidate paths", async (t) => {
|
||||
const root = await makeTempDir("baoyu-chrome-bin-");
|
||||
t.after(() => fs.rm(root, { recursive: true, force: true }));
|
||||
|
||||
const envChrome = path.join(root, "env-chrome");
|
||||
const fallbackChrome = path.join(root, "fallback-chrome");
|
||||
await fs.writeFile(envChrome, "");
|
||||
await fs.writeFile(fallbackChrome, "");
|
||||
|
||||
useEnv(t, { BAOYU_CHROME_PATH: envChrome });
|
||||
assert.equal(
|
||||
findChromeExecutable({
|
||||
envNames: ["BAOYU_CHROME_PATH"],
|
||||
candidates: { default: [fallbackChrome] },
|
||||
}),
|
||||
envChrome,
|
||||
);
|
||||
|
||||
useEnv(t, { BAOYU_CHROME_PATH: null });
|
||||
assert.equal(
|
||||
findChromeExecutable({
|
||||
envNames: ["BAOYU_CHROME_PATH"],
|
||||
candidates: { default: [fallbackChrome] },
|
||||
}),
|
||||
fallbackChrome,
|
||||
);
|
||||
});
|
||||
|
||||
test("resolveSharedChromeProfileDir supports env overrides, WSL paths, and default suffixes", (t) => {
|
||||
useEnv(t, { BAOYU_SHARED_PROFILE: "/tmp/custom-profile" });
|
||||
assert.equal(
|
||||
resolveSharedChromeProfileDir({
|
||||
envNames: ["BAOYU_SHARED_PROFILE"],
|
||||
appDataDirName: "demo-app",
|
||||
profileDirName: "demo-profile",
|
||||
}),
|
||||
path.resolve("/tmp/custom-profile"),
|
||||
);
|
||||
|
||||
useEnv(t, { BAOYU_SHARED_PROFILE: null });
|
||||
assert.equal(
|
||||
resolveSharedChromeProfileDir({
|
||||
wslWindowsHome: "/mnt/c/Users/demo",
|
||||
appDataDirName: "demo-app",
|
||||
profileDirName: "demo-profile",
|
||||
}),
|
||||
path.join("/mnt/c/Users/demo", ".local", "share", "demo-app", "demo-profile"),
|
||||
);
|
||||
|
||||
const fallback = resolveSharedChromeProfileDir({
|
||||
appDataDirName: "demo-app",
|
||||
profileDirName: "demo-profile",
|
||||
});
|
||||
assert.match(fallback, /demo-app[\\/]demo-profile$/);
|
||||
});
|
||||
|
||||
test("findExistingChromeDebugPort reads DevToolsActivePort and validates it against a live endpoint", async (t) => {
|
||||
const root = await makeTempDir("baoyu-cdp-profile-");
|
||||
t.after(() => fs.rm(root, { recursive: true, force: true }));
|
||||
|
||||
const port = await getFreePort();
|
||||
const server = await startDebugServer(port);
|
||||
t.after(() => closeServer(server));
|
||||
|
||||
await fs.writeFile(path.join(root, "DevToolsActivePort"), `${port}\n/devtools/browser/demo\n`);
|
||||
|
||||
const found = await findExistingChromeDebugPort({ profileDir: root, timeoutMs: 1000 });
|
||||
assert.equal(found, port);
|
||||
});
|
||||
|
||||
test("discoverRunningChromeDebugPort reads DevToolsActivePort from the provided user-data dir", async (t) => {
|
||||
const root = await makeTempDir("baoyu-cdp-user-data-");
|
||||
t.after(() => fs.rm(root, { recursive: true, force: true }));
|
||||
|
||||
const port = await getFreePort();
|
||||
const server = await startDebugServer(port);
|
||||
t.after(() => closeServer(server));
|
||||
|
||||
await fs.writeFile(path.join(root, "DevToolsActivePort"), `${port}\n/devtools/browser/demo\n`);
|
||||
|
||||
const found = await discoverRunningChromeDebugPort({
|
||||
userDataDirs: [root],
|
||||
timeoutMs: 1000,
|
||||
});
|
||||
assert.deepEqual(found, {
|
||||
port,
|
||||
wsUrl: `ws://127.0.0.1:${port}/devtools/browser/demo`,
|
||||
});
|
||||
});
|
||||
|
||||
test("discoverRunningChromeDebugPort ignores unrelated debugging processes", async (t) => {
|
||||
if (process.platform === "win32") {
|
||||
t.skip("Process discovery fallback is not used on Windows.");
|
||||
return;
|
||||
}
|
||||
|
||||
const root = await makeTempDir("baoyu-cdp-user-data-");
|
||||
t.after(() => fs.rm(root, { recursive: true, force: true }));
|
||||
|
||||
const port = await getFreePort();
|
||||
const server = await startDebugServer(port);
|
||||
t.after(() => closeServer(server));
|
||||
|
||||
const fakeChromium = await startFakeChromiumProcess(port);
|
||||
t.after(async () => { await stopProcess(fakeChromium); });
|
||||
|
||||
const found = await discoverRunningChromeDebugPort({
|
||||
userDataDirs: [root],
|
||||
timeoutMs: 1000,
|
||||
});
|
||||
assert.equal(found, null);
|
||||
});
|
||||
|
||||
test("openPageSession reports whether it created a new target", async () => {
|
||||
const calls: string[] = [];
|
||||
const cdpExisting = {
|
||||
send: async <T>(method: string): Promise<T> => {
|
||||
calls.push(method);
|
||||
if (method === "Target.getTargets") {
|
||||
return {
|
||||
targetInfos: [{ targetId: "existing-target", type: "page", url: "https://gemini.google.com/app" }],
|
||||
} as T;
|
||||
}
|
||||
if (method === "Target.attachToTarget") return { sessionId: "session-existing" } as T;
|
||||
throw new Error(`Unexpected method: ${method}`);
|
||||
},
|
||||
};
|
||||
|
||||
const existing = await openPageSession({
|
||||
cdp: cdpExisting as never,
|
||||
reusing: false,
|
||||
url: "https://gemini.google.com/app",
|
||||
matchTarget: (target) => target.url.includes("gemini.google.com"),
|
||||
activateTarget: false,
|
||||
});
|
||||
|
||||
assert.deepEqual(existing, {
|
||||
sessionId: "session-existing",
|
||||
targetId: "existing-target",
|
||||
createdTarget: false,
|
||||
});
|
||||
assert.deepEqual(calls, ["Target.getTargets", "Target.attachToTarget"]);
|
||||
|
||||
const createCalls: string[] = [];
|
||||
const cdpCreated = {
|
||||
send: async <T>(method: string): Promise<T> => {
|
||||
createCalls.push(method);
|
||||
if (method === "Target.getTargets") return { targetInfos: [] } as T;
|
||||
if (method === "Target.createTarget") return { targetId: "created-target" } as T;
|
||||
if (method === "Target.attachToTarget") return { sessionId: "session-created" } as T;
|
||||
throw new Error(`Unexpected method: ${method}`);
|
||||
},
|
||||
};
|
||||
|
||||
const created = await openPageSession({
|
||||
cdp: cdpCreated as never,
|
||||
reusing: false,
|
||||
url: "https://gemini.google.com/app",
|
||||
matchTarget: (target) => target.url.includes("gemini.google.com"),
|
||||
activateTarget: false,
|
||||
});
|
||||
|
||||
assert.deepEqual(created, {
|
||||
sessionId: "session-created",
|
||||
targetId: "created-target",
|
||||
createdTarget: true,
|
||||
});
|
||||
assert.deepEqual(createCalls, ["Target.getTargets", "Target.createTarget", "Target.attachToTarget"]);
|
||||
});
|
||||
|
||||
test("waitForChromeDebugPort retries until the debug endpoint becomes available", async (t) => {
|
||||
const port = await getFreePort();
|
||||
|
||||
const serverPromise = (async () => {
|
||||
await new Promise((resolve) => setTimeout(resolve, 200));
|
||||
const server = await startDebugServer(port);
|
||||
t.after(() => closeServer(server));
|
||||
})();
|
||||
|
||||
const websocketUrl = await waitForChromeDebugPort(port, 4000, {
|
||||
includeLastError: true,
|
||||
});
|
||||
await serverPromise;
|
||||
|
||||
assert.equal(websocketUrl, `ws://127.0.0.1:${port}/devtools/browser/demo`);
|
||||
});
|
||||
523
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/src/index.ts
vendored
Normal file
523
llm-wiki/deps/baoyu-url-to-markdown/scripts/vendor/baoyu-chrome-cdp/src/index.ts
vendored
Normal file
@@ -0,0 +1,523 @@
|
||||
import { spawn, spawnSync, type ChildProcess } from "node:child_process";
|
||||
import fs from "node:fs";
|
||||
import net from "node:net";
|
||||
import os from "node:os";
|
||||
import path from "node:path";
|
||||
import process from "node:process";
|
||||
|
||||
export type PlatformCandidates = {
|
||||
darwin?: string[];
|
||||
win32?: string[];
|
||||
default: string[];
|
||||
};
|
||||
|
||||
type PendingRequest = {
|
||||
resolve: (value: unknown) => void;
|
||||
reject: (error: Error) => void;
|
||||
timer: ReturnType<typeof setTimeout> | null;
|
||||
};
|
||||
|
||||
type CdpSendOptions = {
|
||||
sessionId?: string;
|
||||
timeoutMs?: number;
|
||||
};
|
||||
|
||||
type FetchJsonOptions = {
|
||||
timeoutMs?: number;
|
||||
};
|
||||
|
||||
type FindChromeExecutableOptions = {
|
||||
candidates: PlatformCandidates;
|
||||
envNames?: string[];
|
||||
};
|
||||
|
||||
type ResolveSharedChromeProfileDirOptions = {
|
||||
envNames?: string[];
|
||||
appDataDirName?: string;
|
||||
profileDirName?: string;
|
||||
wslWindowsHome?: string | null;
|
||||
};
|
||||
|
||||
type FindExistingChromeDebugPortOptions = {
|
||||
profileDir: string;
|
||||
timeoutMs?: number;
|
||||
};
|
||||
|
||||
export type ChromeChannel = "stable" | "beta" | "canary" | "dev";
|
||||
|
||||
export type DiscoveredChrome = {
|
||||
port: number;
|
||||
wsUrl: string;
|
||||
};
|
||||
|
||||
type DiscoverRunningChromeOptions = {
|
||||
channels?: ChromeChannel[];
|
||||
userDataDirs?: string[];
|
||||
timeoutMs?: number;
|
||||
};
|
||||
|
||||
type LaunchChromeOptions = {
|
||||
chromePath: string;
|
||||
profileDir: string;
|
||||
port: number;
|
||||
url?: string;
|
||||
headless?: boolean;
|
||||
extraArgs?: string[];
|
||||
};
|
||||
|
||||
type ChromeTargetInfo = {
|
||||
targetId: string;
|
||||
url: string;
|
||||
type: string;
|
||||
};
|
||||
|
||||
type OpenPageSessionOptions = {
|
||||
cdp: CdpConnection;
|
||||
reusing: boolean;
|
||||
url: string;
|
||||
matchTarget: (target: ChromeTargetInfo) => boolean;
|
||||
enablePage?: boolean;
|
||||
enableRuntime?: boolean;
|
||||
enableDom?: boolean;
|
||||
enableNetwork?: boolean;
|
||||
activateTarget?: boolean;
|
||||
};
|
||||
|
||||
export type PageSession = {
|
||||
sessionId: string;
|
||||
targetId: string;
|
||||
createdTarget: boolean;
|
||||
};
|
||||
|
||||
export function sleep(ms: number): Promise<void> {
|
||||
return new Promise((resolve) => setTimeout(resolve, ms));
|
||||
}
|
||||
|
||||
export async function getFreePort(fixedEnvName?: string): Promise<number> {
|
||||
const fixed = fixedEnvName ? Number.parseInt(process.env[fixedEnvName] ?? "", 10) : NaN;
|
||||
if (Number.isInteger(fixed) && fixed > 0) return fixed;
|
||||
|
||||
return await new Promise((resolve, reject) => {
|
||||
const server = net.createServer();
|
||||
server.unref();
|
||||
server.on("error", reject);
|
||||
server.listen(0, "127.0.0.1", () => {
|
||||
const address = server.address();
|
||||
if (!address || typeof address === "string") {
|
||||
server.close(() => reject(new Error("Unable to allocate a free TCP port.")));
|
||||
return;
|
||||
}
|
||||
const port = address.port;
|
||||
server.close((err) => {
|
||||
if (err) reject(err);
|
||||
else resolve(port);
|
||||
});
|
||||
});
|
||||
});
|
||||
}
|
||||
|
||||
export function findChromeExecutable(options: FindChromeExecutableOptions): string | undefined {
|
||||
for (const envName of options.envNames ?? []) {
|
||||
const override = process.env[envName]?.trim();
|
||||
if (override && fs.existsSync(override)) return override;
|
||||
}
|
||||
|
||||
const candidates = process.platform === "darwin"
|
||||
? options.candidates.darwin ?? options.candidates.default
|
||||
: process.platform === "win32"
|
||||
? options.candidates.win32 ?? options.candidates.default
|
||||
: options.candidates.default;
|
||||
|
||||
for (const candidate of candidates) {
|
||||
if (fs.existsSync(candidate)) return candidate;
|
||||
}
|
||||
return undefined;
|
||||
}
|
||||
|
||||
export function resolveSharedChromeProfileDir(options: ResolveSharedChromeProfileDirOptions = {}): string {
|
||||
for (const envName of options.envNames ?? []) {
|
||||
const override = process.env[envName]?.trim();
|
||||
if (override) return path.resolve(override);
|
||||
}
|
||||
|
||||
const appDataDirName = options.appDataDirName ?? "baoyu-skills";
|
||||
const profileDirName = options.profileDirName ?? "chrome-profile";
|
||||
|
||||
if (options.wslWindowsHome) {
|
||||
return path.join(options.wslWindowsHome, ".local", "share", appDataDirName, profileDirName);
|
||||
}
|
||||
|
||||
const base = process.platform === "darwin"
|
||||
? path.join(os.homedir(), "Library", "Application Support")
|
||||
: process.platform === "win32"
|
||||
? (process.env.APPDATA ?? path.join(os.homedir(), "AppData", "Roaming"))
|
||||
: (process.env.XDG_DATA_HOME ?? path.join(os.homedir(), ".local", "share"));
|
||||
return path.join(base, appDataDirName, profileDirName);
|
||||
}
|
||||
|
||||
async function fetchWithTimeout(url: string, timeoutMs?: number): Promise<Response> {
|
||||
if (!timeoutMs || timeoutMs <= 0) return await fetch(url, { redirect: "follow" });
|
||||
|
||||
const ctl = new AbortController();
|
||||
const timer = setTimeout(() => ctl.abort(), timeoutMs);
|
||||
try {
|
||||
return await fetch(url, { redirect: "follow", signal: ctl.signal });
|
||||
} finally {
|
||||
clearTimeout(timer);
|
||||
}
|
||||
}
|
||||
|
||||
async function fetchJson<T = unknown>(url: string, options: FetchJsonOptions = {}): Promise<T> {
|
||||
const response = await fetchWithTimeout(url, options.timeoutMs);
|
||||
if (!response.ok) {
|
||||
throw new Error(`Request failed: ${response.status} ${response.statusText}`);
|
||||
}
|
||||
return await response.json() as T;
|
||||
}
|
||||
|
||||
async function isDebugPortReady(port: number, timeoutMs = 3_000): Promise<boolean> {
|
||||
try {
|
||||
const version = await fetchJson<{ webSocketDebuggerUrl?: string }>(
|
||||
`http://127.0.0.1:${port}/json/version`,
|
||||
{ timeoutMs }
|
||||
);
|
||||
return !!version.webSocketDebuggerUrl;
|
||||
} catch {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
function isPortListening(port: number, timeoutMs = 3_000): Promise<boolean> {
|
||||
return new Promise((resolve) => {
|
||||
const socket = new net.Socket();
|
||||
const timer = setTimeout(() => { socket.destroy(); resolve(false); }, timeoutMs);
|
||||
socket.once("connect", () => { clearTimeout(timer); socket.destroy(); resolve(true); });
|
||||
socket.once("error", () => { clearTimeout(timer); resolve(false); });
|
||||
socket.connect(port, "127.0.0.1");
|
||||
});
|
||||
}
|
||||
|
||||
function parseDevToolsActivePort(filePath: string): { port: number; wsPath: string } | null {
|
||||
try {
|
||||
const content = fs.readFileSync(filePath, "utf-8");
|
||||
const lines = content.split(/\r?\n/);
|
||||
const port = Number.parseInt(lines[0]?.trim() ?? "", 10);
|
||||
const wsPath = lines[1]?.trim();
|
||||
if (port > 0 && wsPath) return { port, wsPath };
|
||||
} catch {}
|
||||
return null;
|
||||
}
|
||||
|
||||
export async function findExistingChromeDebugPort(options: FindExistingChromeDebugPortOptions): Promise<number | null> {
|
||||
const timeoutMs = options.timeoutMs ?? 3_000;
|
||||
const parsed = parseDevToolsActivePort(path.join(options.profileDir, "DevToolsActivePort"));
|
||||
|
||||
if (parsed && parsed.port > 0 && await isDebugPortReady(parsed.port, timeoutMs)) return parsed.port;
|
||||
|
||||
if (process.platform === "win32") return null;
|
||||
|
||||
try {
|
||||
const result = spawnSync("ps", ["aux"], { encoding: "utf-8", timeout: 5_000 });
|
||||
if (result.status !== 0 || !result.stdout) return null;
|
||||
|
||||
const lines = result.stdout
|
||||
.split("\n")
|
||||
.filter((line) => line.includes(options.profileDir) && line.includes("--remote-debugging-port="));
|
||||
|
||||
for (const line of lines) {
|
||||
const portMatch = line.match(/--remote-debugging-port=(\d+)/);
|
||||
const port = Number.parseInt(portMatch?.[1] ?? "", 10);
|
||||
if (port > 0 && await isDebugPortReady(port, timeoutMs)) return port;
|
||||
}
|
||||
} catch {}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
export function getDefaultChromeUserDataDirs(channels: ChromeChannel[] = ["stable"]): string[] {
|
||||
const home = os.homedir();
|
||||
const dirs: string[] = [];
|
||||
|
||||
const channelDirs: Record<string, { darwin: string; linux: string; win32: string }> = {
|
||||
stable: {
|
||||
darwin: path.join(home, "Library", "Application Support", "Google", "Chrome"),
|
||||
linux: path.join(home, ".config", "google-chrome"),
|
||||
win32: path.join(process.env.LOCALAPPDATA ?? path.join(home, "AppData", "Local"), "Google", "Chrome", "User Data"),
|
||||
},
|
||||
beta: {
|
||||
darwin: path.join(home, "Library", "Application Support", "Google", "Chrome Beta"),
|
||||
linux: path.join(home, ".config", "google-chrome-beta"),
|
||||
win32: path.join(process.env.LOCALAPPDATA ?? path.join(home, "AppData", "Local"), "Google", "Chrome Beta", "User Data"),
|
||||
},
|
||||
canary: {
|
||||
darwin: path.join(home, "Library", "Application Support", "Google", "Chrome Canary"),
|
||||
linux: path.join(home, ".config", "google-chrome-canary"),
|
||||
win32: path.join(process.env.LOCALAPPDATA ?? path.join(home, "AppData", "Local"), "Google", "Chrome SxS", "User Data"),
|
||||
},
|
||||
dev: {
|
||||
darwin: path.join(home, "Library", "Application Support", "Google", "Chrome Dev"),
|
||||
linux: path.join(home, ".config", "google-chrome-dev"),
|
||||
win32: path.join(process.env.LOCALAPPDATA ?? path.join(home, "AppData", "Local"), "Google", "Chrome Dev", "User Data"),
|
||||
},
|
||||
};
|
||||
|
||||
const platform = process.platform === "darwin" ? "darwin" : process.platform === "win32" ? "win32" : "linux";
|
||||
|
||||
for (const ch of channels) {
|
||||
const entry = channelDirs[ch];
|
||||
if (entry) dirs.push(entry[platform]);
|
||||
}
|
||||
|
||||
return dirs;
|
||||
}
|
||||
|
||||
// Best-effort reuse of an already-running local CDP session discovered from
|
||||
// known Chrome user-data dirs. This is distinct from Chrome DevTools MCP's
|
||||
// prompt-based --autoConnect flow.
|
||||
export async function discoverRunningChromeDebugPort(options: DiscoverRunningChromeOptions = {}): Promise<DiscoveredChrome | null> {
|
||||
const channels = options.channels ?? ["stable", "beta", "canary", "dev"];
|
||||
const timeoutMs = options.timeoutMs ?? 3_000;
|
||||
|
||||
const userDataDirs = (options.userDataDirs ?? getDefaultChromeUserDataDirs(channels))
|
||||
.map((dir) => path.resolve(dir));
|
||||
for (const dir of userDataDirs) {
|
||||
const parsed = parseDevToolsActivePort(path.join(dir, "DevToolsActivePort"));
|
||||
if (!parsed) continue;
|
||||
if (await isPortListening(parsed.port, timeoutMs)) {
|
||||
return { port: parsed.port, wsUrl: `ws://127.0.0.1:${parsed.port}${parsed.wsPath}` };
|
||||
}
|
||||
}
|
||||
|
||||
if (process.platform !== "win32") {
|
||||
try {
|
||||
const result = spawnSync("ps", ["aux"], { encoding: "utf-8", timeout: 5_000 });
|
||||
if (result.status === 0 && result.stdout) {
|
||||
const lines = result.stdout
|
||||
.split("\n")
|
||||
.filter((line) =>
|
||||
line.includes("--remote-debugging-port=") &&
|
||||
userDataDirs.some((dir) => line.includes(dir))
|
||||
);
|
||||
|
||||
for (const line of lines) {
|
||||
const portMatch = line.match(/--remote-debugging-port=(\d+)/);
|
||||
const port = Number.parseInt(portMatch?.[1] ?? "", 10);
|
||||
if (port > 0 && await isDebugPortReady(port, timeoutMs)) {
|
||||
try {
|
||||
const version = await fetchJson<{ webSocketDebuggerUrl?: string }>(`http://127.0.0.1:${port}/json/version`, { timeoutMs });
|
||||
if (version.webSocketDebuggerUrl) return { port, wsUrl: version.webSocketDebuggerUrl };
|
||||
} catch {}
|
||||
}
|
||||
}
|
||||
}
|
||||
} catch {}
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
export async function waitForChromeDebugPort(
|
||||
port: number,
|
||||
timeoutMs: number,
|
||||
options?: { includeLastError?: boolean }
|
||||
): Promise<string> {
|
||||
const start = Date.now();
|
||||
let lastError: unknown = null;
|
||||
|
||||
while (Date.now() - start < timeoutMs) {
|
||||
try {
|
||||
const version = await fetchJson<{ webSocketDebuggerUrl?: string }>(
|
||||
`http://127.0.0.1:${port}/json/version`,
|
||||
{ timeoutMs: 5_000 }
|
||||
);
|
||||
if (version.webSocketDebuggerUrl) return version.webSocketDebuggerUrl;
|
||||
lastError = new Error("Missing webSocketDebuggerUrl");
|
||||
} catch (error) {
|
||||
lastError = error;
|
||||
}
|
||||
await sleep(200);
|
||||
}
|
||||
|
||||
if (options?.includeLastError && lastError) {
|
||||
throw new Error(
|
||||
`Chrome debug port not ready: ${lastError instanceof Error ? lastError.message : String(lastError)}`
|
||||
);
|
||||
}
|
||||
throw new Error("Chrome debug port not ready");
|
||||
}
|
||||
|
||||
export class CdpConnection {
|
||||
private ws: WebSocket;
|
||||
private nextId = 0;
|
||||
private pending = new Map<number, PendingRequest>();
|
||||
private eventHandlers = new Map<string, Set<(params: unknown) => void>>();
|
||||
private defaultTimeoutMs: number;
|
||||
|
||||
private constructor(ws: WebSocket, defaultTimeoutMs = 15_000) {
|
||||
this.ws = ws;
|
||||
this.defaultTimeoutMs = defaultTimeoutMs;
|
||||
|
||||
this.ws.addEventListener("message", (event) => {
|
||||
try {
|
||||
const data = typeof event.data === "string"
|
||||
? event.data
|
||||
: new TextDecoder().decode(event.data as ArrayBuffer);
|
||||
const msg = JSON.parse(data) as {
|
||||
id?: number;
|
||||
method?: string;
|
||||
params?: unknown;
|
||||
result?: unknown;
|
||||
error?: { message?: string };
|
||||
};
|
||||
|
||||
if (msg.method) {
|
||||
const handlers = this.eventHandlers.get(msg.method);
|
||||
if (handlers) {
|
||||
handlers.forEach((handler) => handler(msg.params));
|
||||
}
|
||||
}
|
||||
|
||||
if (msg.id) {
|
||||
const pending = this.pending.get(msg.id);
|
||||
if (pending) {
|
||||
this.pending.delete(msg.id);
|
||||
if (pending.timer) clearTimeout(pending.timer);
|
||||
if (msg.error?.message) pending.reject(new Error(msg.error.message));
|
||||
else pending.resolve(msg.result);
|
||||
}
|
||||
}
|
||||
} catch {}
|
||||
});
|
||||
|
||||
this.ws.addEventListener("close", () => {
|
||||
for (const [id, pending] of this.pending.entries()) {
|
||||
this.pending.delete(id);
|
||||
if (pending.timer) clearTimeout(pending.timer);
|
||||
pending.reject(new Error("CDP connection closed."));
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
static async connect(
|
||||
url: string,
|
||||
timeoutMs: number,
|
||||
options?: { defaultTimeoutMs?: number }
|
||||
): Promise<CdpConnection> {
|
||||
const ws = new WebSocket(url);
|
||||
await new Promise<void>((resolve, reject) => {
|
||||
const timer = setTimeout(() => reject(new Error("CDP connection timeout.")), timeoutMs);
|
||||
ws.addEventListener("open", () => {
|
||||
clearTimeout(timer);
|
||||
resolve();
|
||||
});
|
||||
ws.addEventListener("error", () => {
|
||||
clearTimeout(timer);
|
||||
reject(new Error("CDP connection failed."));
|
||||
});
|
||||
});
|
||||
return new CdpConnection(ws, options?.defaultTimeoutMs ?? 15_000);
|
||||
}
|
||||
|
||||
on(method: string, handler: (params: unknown) => void): void {
|
||||
if (!this.eventHandlers.has(method)) {
|
||||
this.eventHandlers.set(method, new Set());
|
||||
}
|
||||
this.eventHandlers.get(method)?.add(handler);
|
||||
}
|
||||
|
||||
off(method: string, handler: (params: unknown) => void): void {
|
||||
this.eventHandlers.get(method)?.delete(handler);
|
||||
}
|
||||
|
||||
async send<T = unknown>(method: string, params?: Record<string, unknown>, options?: CdpSendOptions): Promise<T> {
|
||||
const id = ++this.nextId;
|
||||
const message: Record<string, unknown> = { id, method };
|
||||
if (params) message.params = params;
|
||||
if (options?.sessionId) message.sessionId = options.sessionId;
|
||||
|
||||
const timeoutMs = options?.timeoutMs ?? this.defaultTimeoutMs;
|
||||
const result = await new Promise<unknown>((resolve, reject) => {
|
||||
const timer = timeoutMs > 0
|
||||
? setTimeout(() => {
|
||||
this.pending.delete(id);
|
||||
reject(new Error(`CDP timeout: ${method}`));
|
||||
}, timeoutMs)
|
||||
: null;
|
||||
this.pending.set(id, { resolve, reject, timer });
|
||||
this.ws.send(JSON.stringify(message));
|
||||
});
|
||||
|
||||
return result as T;
|
||||
}
|
||||
|
||||
close(): void {
|
||||
try {
|
||||
this.ws.close();
|
||||
} catch {}
|
||||
}
|
||||
}
|
||||
|
||||
export async function launchChrome(options: LaunchChromeOptions): Promise<ChildProcess> {
|
||||
await fs.promises.mkdir(options.profileDir, { recursive: true });
|
||||
|
||||
const args = [
|
||||
`--remote-debugging-port=${options.port}`,
|
||||
`--user-data-dir=${options.profileDir}`,
|
||||
"--no-first-run",
|
||||
"--no-default-browser-check",
|
||||
...(options.extraArgs ?? []),
|
||||
];
|
||||
if (options.headless) args.push("--headless=new");
|
||||
if (options.url) args.push(options.url);
|
||||
|
||||
return spawn(options.chromePath, args, { stdio: "ignore" });
|
||||
}
|
||||
|
||||
export function killChrome(chrome: ChildProcess): void {
|
||||
try {
|
||||
chrome.kill("SIGTERM");
|
||||
} catch {}
|
||||
setTimeout(() => {
|
||||
if (!chrome.killed) {
|
||||
try {
|
||||
chrome.kill("SIGKILL");
|
||||
} catch {}
|
||||
}
|
||||
}, 2_000).unref?.();
|
||||
}
|
||||
|
||||
export async function openPageSession(options: OpenPageSessionOptions): Promise<PageSession> {
|
||||
let targetId: string;
|
||||
let createdTarget = false;
|
||||
|
||||
if (options.reusing) {
|
||||
const created = await options.cdp.send<{ targetId: string }>("Target.createTarget", { url: options.url });
|
||||
targetId = created.targetId;
|
||||
createdTarget = true;
|
||||
} else {
|
||||
const targets = await options.cdp.send<{ targetInfos: ChromeTargetInfo[] }>("Target.getTargets");
|
||||
const existing = targets.targetInfos.find(options.matchTarget);
|
||||
if (existing) {
|
||||
targetId = existing.targetId;
|
||||
} else {
|
||||
const created = await options.cdp.send<{ targetId: string }>("Target.createTarget", { url: options.url });
|
||||
targetId = created.targetId;
|
||||
createdTarget = true;
|
||||
}
|
||||
}
|
||||
|
||||
const { sessionId } = await options.cdp.send<{ sessionId: string }>(
|
||||
"Target.attachToTarget",
|
||||
{ targetId, flatten: true }
|
||||
);
|
||||
|
||||
if (options.activateTarget ?? true) {
|
||||
await options.cdp.send("Target.activateTarget", { targetId });
|
||||
}
|
||||
if (options.enablePage) await options.cdp.send("Page.enable", {}, { sessionId });
|
||||
if (options.enableRuntime) await options.cdp.send("Runtime.enable", {}, { sessionId });
|
||||
if (options.enableDom) await options.cdp.send("DOM.enable", {}, { sessionId });
|
||||
if (options.enableNetwork) await options.cdp.send("Network.enable", {}, { sessionId });
|
||||
|
||||
return { sessionId, targetId, createdTarget };
|
||||
}
|
||||
2
llm-wiki/deps/d3.min.js
vendored
Normal file
2
llm-wiki/deps/d3.min.js
vendored
Normal file
File diff suppressed because one or more lines are too long
6
llm-wiki/deps/marked.min.js
vendored
Normal file
6
llm-wiki/deps/marked.min.js
vendored
Normal file
File diff suppressed because one or more lines are too long
3
llm-wiki/deps/purify.min.js
vendored
Normal file
3
llm-wiki/deps/purify.min.js
vendored
Normal file
File diff suppressed because one or more lines are too long
7
llm-wiki/deps/rough.min.js
vendored
Normal file
7
llm-wiki/deps/rough.min.js
vendored
Normal file
File diff suppressed because one or more lines are too long
1682
llm-wiki/deps/unicode/CaseFolding-17.0.0.txt
Normal file
1682
llm-wiki/deps/unicode/CaseFolding-17.0.0.txt
Normal file
File diff suppressed because it is too large
Load Diff
16368
llm-wiki/deps/unicode/DerivedNormalizationProps-17.0.0.txt
Normal file
16368
llm-wiki/deps/unicode/DerivedNormalizationProps-17.0.0.txt
Normal file
File diff suppressed because it is too large
Load Diff
40575
llm-wiki/deps/unicode/UnicodeData-17.0.0.txt
Normal file
40575
llm-wiki/deps/unicode/UnicodeData-17.0.0.txt
Normal file
File diff suppressed because it is too large
Load Diff
47
llm-wiki/deps/youtube-transcript/SKILL.md
Normal file
47
llm-wiki/deps/youtube-transcript/SKILL.md
Normal file
@@ -0,0 +1,47 @@
|
||||
---
|
||||
name: youtube-transcript
|
||||
description: Extract transcripts from YouTube videos. Use when the user asks for a transcript, subtitles, or captions of a YouTube video and provides a YouTube URL (youtube.com/watch?v=, youtu.be/, or similar). Supports output with or without timestamps.
|
||||
---
|
||||
|
||||
# YouTube Transcript
|
||||
|
||||
Extract transcripts from YouTube videos using the youtube-transcript-api.
|
||||
|
||||
## Usage
|
||||
|
||||
Run the script with a YouTube URL or video ID:
|
||||
|
||||
```bash
|
||||
uv run scripts/get_transcript.py "VIDEO_URL_OR_ID"
|
||||
```
|
||||
|
||||
With timestamps:
|
||||
|
||||
```bash
|
||||
uv run scripts/get_transcript.py "VIDEO_URL_OR_ID" --timestamps
|
||||
```
|
||||
|
||||
## Defaults
|
||||
|
||||
- **Without timestamps** (default): Plain text, one line per caption segment
|
||||
- **With timestamps**: `[MM:SS] text` format (or `[HH:MM:SS]` for longer videos)
|
||||
|
||||
## Supported URL Formats
|
||||
|
||||
- `https://www.youtube.com/watch?v=VIDEO_ID`
|
||||
- `https://youtu.be/VIDEO_ID`
|
||||
- `https://youtube.com/embed/VIDEO_ID`
|
||||
- Raw video ID (11 characters)
|
||||
|
||||
## Output
|
||||
|
||||
- CRITICAL: YOU MUST NEVER MODIFY THE RETURNED TRANSCRIPT
|
||||
- If the transcript is without timestamps, you SHOULD clean it up so that it is arranged by complete paragraphs and the lines don't cut in the middle of sentences.
|
||||
- If you were asked to save the transcript to a specific file, save it to the requested file.
|
||||
- If no output file was specified, use the YouTube video ID with a `-transcript.txt` suffix.
|
||||
|
||||
## Notes
|
||||
|
||||
- Fetches auto-generated or manually added captions (whichever is available)
|
||||
- Requires the video to have captions enabled
|
||||
- Falls back to auto-generated captions if manual ones aren't available
|
||||
72
llm-wiki/deps/youtube-transcript/scripts/get_transcript.py
Executable file
72
llm-wiki/deps/youtube-transcript/scripts/get_transcript.py
Executable file
@@ -0,0 +1,72 @@
|
||||
#!/usr/bin/env -S uv run --script
|
||||
# /// script
|
||||
# requires-python = ">=3.10"
|
||||
# dependencies = ["youtube-transcript-api>=1.0.0"]
|
||||
# ///
|
||||
"""
|
||||
Extract transcript from a YouTube video.
|
||||
|
||||
Usage:
|
||||
uv run scripts/get_transcript.py <video_id_or_url> [--timestamps]
|
||||
"""
|
||||
|
||||
import sys
|
||||
import re
|
||||
import argparse
|
||||
from youtube_transcript_api import YouTubeTranscriptApi
|
||||
|
||||
|
||||
def extract_video_id(url_or_id: str) -> str:
|
||||
"""Extract video ID from various YouTube URL formats or return as-is if already an ID."""
|
||||
patterns = [
|
||||
r'(?:youtube\.com/watch\?v=|youtu\.be/|youtube\.com/embed/|youtube\.com/v/)([a-zA-Z0-9_-]{11})',
|
||||
r'^([a-zA-Z0-9_-]{11})$'
|
||||
]
|
||||
for pattern in patterns:
|
||||
match = re.search(pattern, url_or_id)
|
||||
if match:
|
||||
return match.group(1)
|
||||
raise ValueError(f"Could not extract video ID from: {url_or_id}")
|
||||
|
||||
|
||||
def format_timestamp(seconds: float) -> str:
|
||||
"""Convert seconds to HH:MM:SS or MM:SS format."""
|
||||
hours = int(seconds // 3600)
|
||||
minutes = int((seconds % 3600) // 60)
|
||||
secs = int(seconds % 60)
|
||||
if hours > 0:
|
||||
return f"{hours:02d}:{minutes:02d}:{secs:02d}"
|
||||
return f"{minutes:02d}:{secs:02d}"
|
||||
|
||||
|
||||
def get_transcript(video_id: str, with_timestamps: bool = False) -> str:
|
||||
"""Fetch and format transcript for a YouTube video."""
|
||||
api = YouTubeTranscriptApi()
|
||||
transcript = api.fetch(video_id)
|
||||
|
||||
if with_timestamps:
|
||||
lines = [f"[{format_timestamp(snippet.start)}] {snippet.text}" for snippet in transcript.snippets]
|
||||
else:
|
||||
lines = [snippet.text for snippet in transcript.snippets]
|
||||
|
||||
return '\n'.join(lines)
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='Get YouTube video transcript')
|
||||
parser.add_argument('video', help='YouTube video URL or video ID')
|
||||
parser.add_argument('--timestamps', '-t', action='store_true',
|
||||
help='Include timestamps in output')
|
||||
args = parser.parse_args()
|
||||
|
||||
try:
|
||||
video_id = extract_video_id(args.video)
|
||||
transcript = get_transcript(video_id, with_timestamps=args.timestamps)
|
||||
print(transcript)
|
||||
except Exception as e:
|
||||
print(f"Error: {e}", file=sys.stderr)
|
||||
sys.exit(1)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
87
llm-wiki/install.ps1
Normal file
87
llm-wiki/install.ps1
Normal file
@@ -0,0 +1,87 @@
|
||||
#Requires -Version 5.1
|
||||
<#
|
||||
.SYNOPSIS
|
||||
llm-wiki Windows PowerShell install wrapper
|
||||
|
||||
.DESCRIPTION
|
||||
Fixes the combined encoding problem on Windows PowerShell 5.1:
|
||||
- console default is GB2312 (CP936) on Chinese Windows
|
||||
- $OutputEncoding defaults to ASCII (CP1252)
|
||||
- Python subprocess sys.stdout.encoding defaults to gbk (cp936)
|
||||
This wrapper forces UTF-8 across all three layers so install.sh Chinese
|
||||
output and hook-generated JSON are not garbled (issue #16).
|
||||
|
||||
Steps:
|
||||
1. chcp 65001 (console code page)
|
||||
2. [Console]::InputEncoding / OutputEncoding = UTF-8
|
||||
3. $OutputEncoding = UTF-8 (how PS decodes subprocess stdout)
|
||||
4. PYTHONIOENCODING=utf-8 (Python subprocess output)
|
||||
5. Invoke bash install.sh, forwarding all args
|
||||
|
||||
All Write-Host output is kept ASCII-only so this script works even when
|
||||
PowerShell 5.1 parses the .ps1 file under Chinese ANSI (GBK) codepage
|
||||
with no BOM. The actual Chinese UI comes from install.sh after handoff.
|
||||
|
||||
.EXAMPLE
|
||||
PS> powershell -ExecutionPolicy Bypass -File install.ps1 --platform claude
|
||||
|
||||
.EXAMPLE
|
||||
PS> powershell -ExecutionPolicy Bypass -File install.ps1 --platform codex --dry-run
|
||||
|
||||
.NOTES
|
||||
- Requires Git for Windows (Git Bash) or WSL to provide bash on PATH
|
||||
- PowerShell 7+ users default to UTF-8 and can run bash install.sh directly
|
||||
- This wrapper adjusts environment only; it does not alter install.sh logic
|
||||
#>
|
||||
|
||||
[CmdletBinding()]
|
||||
param(
|
||||
[Parameter(ValueFromRemainingArguments = $true)]
|
||||
[string[]]$RemainingArgs
|
||||
)
|
||||
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
# 1. Switch console code page to UTF-8
|
||||
$null = & chcp.com 65001
|
||||
|
||||
# 2. Console input/output encoding
|
||||
[Console]::InputEncoding = [System.Text.Encoding]::UTF8
|
||||
[Console]::OutputEncoding = [System.Text.Encoding]::UTF8
|
||||
|
||||
# 3. How PS decodes subprocess stdout bytes
|
||||
$OutputEncoding = [System.Text.Encoding]::UTF8
|
||||
|
||||
# 4. Force Python subprocess stdout/stderr to UTF-8
|
||||
$env:PYTHONIOENCODING = 'utf-8'
|
||||
|
||||
# 5. Detect bash
|
||||
$bashCmd = Get-Command bash -ErrorAction SilentlyContinue
|
||||
if (-not $bashCmd) {
|
||||
Write-Host "[llm-wiki] Error: bash not found on PATH." -ForegroundColor Red
|
||||
Write-Host " Install Git for Windows first: https://git-scm.com/download/win" -ForegroundColor Red
|
||||
exit 1
|
||||
}
|
||||
|
||||
# Script root (use $PSScriptRoot to avoid null $MyInvocation.MyCommand.Path under -File)
|
||||
$scriptDir = $PSScriptRoot
|
||||
if ([string]::IsNullOrEmpty($scriptDir)) {
|
||||
$scriptDir = Split-Path -Parent $PSCommandPath
|
||||
}
|
||||
$installSh = Join-Path -Path $scriptDir -ChildPath 'install.sh'
|
||||
|
||||
if (-not (Test-Path $installSh)) {
|
||||
Write-Host "[llm-wiki] Error: install.sh not found at $installSh" -ForegroundColor Red
|
||||
exit 1
|
||||
}
|
||||
|
||||
Write-Host "[llm-wiki] UTF-8 environment ready, launching install.sh..." -ForegroundColor Cyan
|
||||
|
||||
# Forward args
|
||||
if ($null -eq $RemainingArgs -or $RemainingArgs.Count -eq 0) {
|
||||
& bash $installSh
|
||||
} else {
|
||||
& bash $installSh @RemainingArgs
|
||||
}
|
||||
|
||||
exit $LASTEXITCODE
|
||||
726
llm-wiki/install.sh
Executable file
726
llm-wiki/install.sh
Executable file
@@ -0,0 +1,726 @@
|
||||
#!/bin/bash
|
||||
# llm-wiki unified installer
|
||||
set -euo pipefail
|
||||
|
||||
SKILL_NAME="llm-wiki"
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
SOURCE_REGISTRY_SCRIPT="$SCRIPT_DIR/scripts/source-registry.sh"
|
||||
ADAPTER_STATE_SCRIPT="$SCRIPT_DIR/scripts/adapter-state.sh"
|
||||
PLATFORM="auto"
|
||||
PLATFORM_EXPLICIT=0
|
||||
DRY_RUN=0
|
||||
TARGET_DIR=""
|
||||
INSTALL_HOOKS=0
|
||||
UNINSTALL_HOOKS=0
|
||||
UPGRADE=0
|
||||
WITH_OPTIONAL_ADAPTERS=0
|
||||
|
||||
# 这些项目都在运行时会被读取或链接:
|
||||
# - 入口与说明文件:README / CLAUDE / AGENTS / CHANGELOG
|
||||
# - 安装入口:install.sh / setup.sh
|
||||
# - 实际执行内容:SKILL.md / scripts / templates / deps
|
||||
# - scripts 运行时引用的唯一共享规则文件(只携带所需文件,不打包整个 packages)
|
||||
# - 平台薄入口:platforms(README、CLAUDE、AGENTS 都会引用)
|
||||
MANAGED_ITEMS=(
|
||||
"SKILL.md"
|
||||
"README.md"
|
||||
"CLAUDE.md"
|
||||
"AGENTS.md"
|
||||
"HERMES.md"
|
||||
"CHANGELOG.md"
|
||||
"install.sh"
|
||||
"setup.sh"
|
||||
"install.ps1"
|
||||
"scripts"
|
||||
"templates"
|
||||
"deps"
|
||||
"platforms"
|
||||
"packages/workbench-contracts/src/graph-rename-filename.js"
|
||||
)
|
||||
|
||||
DEP_SKILLS=()
|
||||
|
||||
list_companion_skill_sources() {
|
||||
case "$1" in
|
||||
claude)
|
||||
printf '%s\n' "platforms/claude/companions/llm-wiki-upgrade"
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
# 微信工具 URL 从共享配置读取,与 adapter-state.sh 保持一致
|
||||
source "$SCRIPT_DIR/scripts/shared-config.sh"
|
||||
source "$SCRIPT_DIR/scripts/runtime-context.sh"
|
||||
|
||||
info() { printf '\033[36m[信息]\033[0m %s\n' "$1"; }
|
||||
ok() { printf '\033[32m[完成]\033[0m %s\n' "$1"; }
|
||||
warn() { printf '\033[33m[警告]\033[0m %s\n' "$1"; }
|
||||
err() { printf '\033[31m[错误]\033[0m %s\n' "$1" >&2; }
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash install.sh --platform <claude|codex|openclaw|hermes|auto> [--dry-run]
|
||||
bash install.sh --platform claude --install-hooks
|
||||
bash install.sh --install-hooks
|
||||
bash install.sh --uninstall-hooks
|
||||
bash install.sh --upgrade [--platform <claude|codex|openclaw|hermes|auto>]
|
||||
bash install.sh --platform codex --with-optional-adapters
|
||||
|
||||
选项:
|
||||
--platform 目标平台。默认 auto;只有检测到唯一平台时才会自动安装。
|
||||
--dry-run 只打印安装计划,不写入文件。
|
||||
--target-dir 指定技能目标目录(直接传最终的 llm-wiki 目录)。
|
||||
--with-optional-adapters 显式启用网页 / X / YouTube / 公众号等可选提取器安装。
|
||||
--install-hooks 注册 Claude Code 的 SessionStart hook。
|
||||
--uninstall-hooks 移除 Claude Code 的 SessionStart hook。
|
||||
--upgrade 拉取最新代码并更新已安装的 llm-wiki(保留 hook 配置)。
|
||||
-h, --help 显示帮助。
|
||||
EOF
|
||||
}
|
||||
|
||||
hook_command_for_skill_dir() {
|
||||
printf 'bash %s/scripts/hook-session-start.sh\n' "$1"
|
||||
}
|
||||
|
||||
require_jq() {
|
||||
if ! command -v jq >/dev/null 2>&1; then
|
||||
err "注册或移除 hook 需要 jq"
|
||||
exit 1
|
||||
fi
|
||||
}
|
||||
|
||||
register_claude_session_hook() {
|
||||
local skill_dir="$1"
|
||||
local settings_dir settings_path backup_path hook_command tmp_file
|
||||
|
||||
[ -d "$skill_dir" ] || {
|
||||
err "未找到已安装的 llm-wiki:$skill_dir"
|
||||
exit 1
|
||||
}
|
||||
|
||||
require_jq
|
||||
|
||||
settings_dir="$HOME/.claude"
|
||||
settings_path="$settings_dir/settings.json"
|
||||
backup_path="$settings_dir/settings.json.bak.llm-wiki"
|
||||
hook_command="$(hook_command_for_skill_dir "$skill_dir")"
|
||||
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] register SessionStart hook: %s\n' "$hook_command"
|
||||
return 0
|
||||
fi
|
||||
|
||||
mkdir -p "$settings_dir"
|
||||
[ -f "$settings_path" ] || printf '{}\n' > "$settings_path"
|
||||
cp "$settings_path" "$backup_path"
|
||||
|
||||
if jq -e --arg cmd "$hook_command" '[ (.hooks.SessionStart // [])[]? | (.hooks // [])[]? | .command ] | index($cmd) != null' "$settings_path" > /dev/null; then
|
||||
ok "Claude Code SessionStart hook 已存在,跳过"
|
||||
return 0
|
||||
fi
|
||||
|
||||
tmp_file="$(mktemp)"
|
||||
jq --arg cmd "$hook_command" '
|
||||
.hooks = (.hooks // {}) |
|
||||
.hooks.SessionStart = ((.hooks.SessionStart // []) + [{"hooks":[{"type":"command","command":$cmd}]}])
|
||||
' "$settings_path" > "$tmp_file"
|
||||
mv "$tmp_file" "$settings_path"
|
||||
|
||||
ok "Claude Code SessionStart hook 已注册"
|
||||
}
|
||||
|
||||
uninstall_claude_session_hook() {
|
||||
local skill_dir="$1"
|
||||
local settings_dir settings_path backup_path hook_command tmp_file
|
||||
|
||||
require_jq
|
||||
|
||||
settings_dir="$HOME/.claude"
|
||||
settings_path="$settings_dir/settings.json"
|
||||
backup_path="$settings_dir/settings.json.bak.llm-wiki"
|
||||
hook_command="$(hook_command_for_skill_dir "$skill_dir")"
|
||||
|
||||
if [ ! -f "$settings_path" ]; then
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] uninstall SessionStart hook: %s\n' "$hook_command"
|
||||
return 0
|
||||
fi
|
||||
ok "未找到 Claude Code settings.json,跳过 hook 移除"
|
||||
return 0
|
||||
fi
|
||||
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] uninstall SessionStart hook: %s\n' "$hook_command"
|
||||
return 0
|
||||
fi
|
||||
|
||||
cp "$settings_path" "$backup_path"
|
||||
|
||||
tmp_file="$(mktemp)"
|
||||
jq --arg cmd "$hook_command" '
|
||||
.hooks = (.hooks // {}) |
|
||||
.hooks.SessionStart = (
|
||||
(.hooks.SessionStart // [])
|
||||
| map(.hooks = ((.hooks // []) | map(select(.command != $cmd))))
|
||||
| map(select((.hooks // []) | length > 0))
|
||||
) |
|
||||
if ((.hooks.SessionStart // []) | length) == 0 then del(.hooks.SessionStart) else . end |
|
||||
if (.hooks | length) == 0 then del(.hooks) else . end
|
||||
' "$settings_path" > "$tmp_file"
|
||||
mv "$tmp_file" "$settings_path"
|
||||
|
||||
ok "Claude Code SessionStart hook 已移除"
|
||||
}
|
||||
|
||||
load_dependency_skills() {
|
||||
local dep
|
||||
|
||||
DEP_SKILLS=()
|
||||
|
||||
while IFS= read -r dep; do
|
||||
[ -n "$dep" ] && DEP_SKILLS+=("$dep")
|
||||
done < <(bash "$SOURCE_REGISTRY_SCRIPT" unique-dependencies bundled)
|
||||
}
|
||||
|
||||
join_source_labels() {
|
||||
local category="$1"
|
||||
|
||||
bash "$SOURCE_REGISTRY_SCRIPT" list-by-category "$category" \
|
||||
| awk -F '\t' '
|
||||
BEGIN { separator = "" }
|
||||
NF {
|
||||
printf "%s%s", separator, $2
|
||||
separator = "、"
|
||||
}
|
||||
END {
|
||||
if (separator == "") {
|
||||
printf "-"
|
||||
}
|
||||
printf "\n"
|
||||
}
|
||||
'
|
||||
}
|
||||
|
||||
run_cmd() {
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] %s\n' "$*"
|
||||
return 0
|
||||
fi
|
||||
"$@"
|
||||
}
|
||||
|
||||
copy_item() {
|
||||
local source_path="$1"
|
||||
local target_path="$2"
|
||||
|
||||
run_cmd mkdir -p "$(dirname "$target_path")"
|
||||
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] copy %s -> %s\n' "$source_path" "$target_path"
|
||||
return 0
|
||||
fi
|
||||
|
||||
rm -rf "$target_path"
|
||||
cp -R "$source_path" "$target_path"
|
||||
}
|
||||
|
||||
detect_available_platforms() {
|
||||
local found=()
|
||||
|
||||
if [ -d "$HOME/.claude" ] || [ -d "$HOME/.claude/skills" ]; then
|
||||
found+=("claude")
|
||||
fi
|
||||
|
||||
if [ -d "$HOME/.codex" ] || [ -d "$HOME/.codex/skills" ] || [ -d "$HOME/.Codex" ] || [ -d "$HOME/.Codex/skills" ]; then
|
||||
found+=("codex")
|
||||
fi
|
||||
|
||||
if [ -d "$HOME/.openclaw" ] || [ -d "$HOME/.openclaw/skills" ]; then
|
||||
found+=("openclaw")
|
||||
fi
|
||||
|
||||
if [ -d "$HOME/.hermes" ] || [ -d "$HOME/.hermes/skills" ]; then
|
||||
found+=("hermes")
|
||||
fi
|
||||
|
||||
printf '%s\n' "${found[@]}"
|
||||
}
|
||||
|
||||
install_dependency_skills() {
|
||||
local skill_root="$1"
|
||||
local dep dep_target dep_source
|
||||
|
||||
for dep in "${DEP_SKILLS[@]}"; do
|
||||
dep_source="$SCRIPT_DIR/deps/$dep"
|
||||
dep_target="$skill_root/$dep"
|
||||
|
||||
if [ ! -d "$dep_source" ]; then
|
||||
warn "$dep:deps/ 中未找到源文件,跳过"
|
||||
continue
|
||||
fi
|
||||
|
||||
copy_item "$dep_source" "$dep_target"
|
||||
ok "$dep 已准备到 $dep_target"
|
||||
done
|
||||
}
|
||||
|
||||
install_companion_skills() {
|
||||
local platform="$1"
|
||||
local skill_root="$2"
|
||||
local skill_rel skill_source skill_target skill_name
|
||||
|
||||
while IFS= read -r skill_rel; do
|
||||
[ -n "$skill_rel" ] || continue
|
||||
|
||||
skill_source="$SCRIPT_DIR/$skill_rel"
|
||||
skill_name="$(basename "$skill_rel")"
|
||||
skill_target="$skill_root/$skill_name"
|
||||
|
||||
if [ ! -d "$skill_source" ]; then
|
||||
warn "$skill_name:仓库中未找到源文件,跳过"
|
||||
continue
|
||||
fi
|
||||
|
||||
copy_item "$skill_source" "$skill_target"
|
||||
ok "$skill_name 已安装到 $skill_target"
|
||||
done < <(list_companion_skill_sources "$platform")
|
||||
}
|
||||
|
||||
install_bundle() {
|
||||
local target_dir="$1"
|
||||
local item source_path target_path
|
||||
|
||||
for item in "${MANAGED_ITEMS[@]}"; do
|
||||
source_path="$SCRIPT_DIR/$item"
|
||||
target_path="$target_dir/$item"
|
||||
|
||||
if [ ! -e "$source_path" ]; then
|
||||
warn "$item:安装源文件缺失,跳过"
|
||||
continue
|
||||
fi
|
||||
|
||||
if [ "$source_path" = "$target_path" ] && [ -e "$target_path" ]; then
|
||||
continue
|
||||
fi
|
||||
|
||||
copy_item "$source_path" "$target_path"
|
||||
done
|
||||
|
||||
# 安装后校验:确保清单文件都已就位(Windows install.ps1 尤其重要)
|
||||
if [ "$DRY_RUN" -ne 1 ]; then
|
||||
for item in "${MANAGED_ITEMS[@]}"; do
|
||||
source_path="$SCRIPT_DIR/$item"
|
||||
target_path="$target_dir/$item"
|
||||
if [ -e "$source_path" ] && [ ! -e "$target_path" ]; then
|
||||
err "$item:已列入安装清单但未出现在目标目录,拷贝可能失败"
|
||||
exit 1
|
||||
fi
|
||||
done
|
||||
ok "已校验全部 ${#MANAGED_ITEMS[@]} 项安装清单文件"
|
||||
fi
|
||||
}
|
||||
|
||||
install_node_deps() {
|
||||
local skill_root="$1"
|
||||
local baoyu_dir="$skill_root/baoyu-url-to-markdown/scripts"
|
||||
|
||||
if [ ! -d "$baoyu_dir" ] || [ ! -f "$baoyu_dir/package.json" ]; then
|
||||
return 0
|
||||
fi
|
||||
|
||||
if [ -d "$baoyu_dir/node_modules" ]; then
|
||||
ok "baoyu-url-to-markdown 的 Node 依赖已存在"
|
||||
return 0
|
||||
fi
|
||||
|
||||
info "安装 baoyu-url-to-markdown 的 Node 依赖..."
|
||||
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
if command -v bun >/dev/null 2>&1; then
|
||||
printf '[dry-run] (cd %s && bun install)\n' "$baoyu_dir"
|
||||
elif command -v npm >/dev/null 2>&1; then
|
||||
printf '[dry-run] (cd %s && npm install)\n' "$baoyu_dir"
|
||||
else
|
||||
printf '[dry-run] 未找到 bun 或 npm,无法安装 Node 依赖\n'
|
||||
fi
|
||||
return 0
|
||||
fi
|
||||
|
||||
if command -v bun >/dev/null 2>&1; then
|
||||
(cd "$baoyu_dir" && bun install) || warn "bun install 失败,跳过(可手动粘贴文本作为替代)"
|
||||
elif command -v npm >/dev/null 2>&1; then
|
||||
(cd "$baoyu_dir" && npm install) || warn "npm install 失败,跳过(可手动粘贴文本作为替代)"
|
||||
else
|
||||
warn "未找到 bun 或 npm,无法安装 Node 依赖"
|
||||
echo " 推荐安装 bun:curl -fsSL https://bun.sh/install | bash"
|
||||
return 0
|
||||
fi
|
||||
|
||||
[ -d "$baoyu_dir/node_modules" ] && ok "baoyu-url-to-markdown 的 Node 依赖安装完成"
|
||||
}
|
||||
|
||||
install_uv_tools() {
|
||||
if ! command -v uv >/dev/null 2>&1; then
|
||||
warn "未找到 uv,跳过 wechat-article-to-markdown 安装"
|
||||
echo " 安装 uv:curl -LsSf https://astral.sh/uv/install.sh | sh"
|
||||
return 0
|
||||
fi
|
||||
|
||||
if command -v wechat-article-to-markdown >/dev/null 2>&1; then
|
||||
ok "wechat-article-to-markdown 已安装"
|
||||
return 0
|
||||
fi
|
||||
|
||||
info "安装 wechat-article-to-markdown..."
|
||||
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] uv tool install %s\n' "${WECHAT_TOOL_URL}"
|
||||
return 0
|
||||
fi
|
||||
|
||||
uv tool install "${WECHAT_TOOL_URL}" \
|
||||
|| warn "wechat-article-to-markdown 安装失败(可手动安装:uv tool install ${WECHAT_TOOL_URL})"
|
||||
|
||||
if command -v wechat-article-to-markdown >/dev/null 2>&1; then
|
||||
ok "wechat-article-to-markdown 安装完成"
|
||||
fi
|
||||
}
|
||||
|
||||
bootstrap_optional_adapters() {
|
||||
local skill_root="$1"
|
||||
|
||||
if [ "$WITH_OPTIONAL_ADAPTERS" -ne 1 ]; then
|
||||
return 0
|
||||
fi
|
||||
|
||||
load_dependency_skills
|
||||
install_dependency_skills "$skill_root"
|
||||
install_node_deps "$skill_root"
|
||||
install_uv_tools
|
||||
}
|
||||
|
||||
check_environment() {
|
||||
echo ""
|
||||
echo "================================"
|
||||
echo " 环境检查"
|
||||
echo "================================"
|
||||
echo ""
|
||||
|
||||
if command -v uv >/dev/null 2>&1; then
|
||||
ok "uv 已安装(可安装 wechat-article-to-markdown,并运行 youtube-transcript)"
|
||||
else
|
||||
warn "未找到 uv。wechat-article-to-markdown 和 youtube-transcript 需要 uv"
|
||||
echo " 可用 Homebrew 安装:brew install uv"
|
||||
fi
|
||||
|
||||
if command -v wechat-article-to-markdown >/dev/null 2>&1; then
|
||||
ok "wechat-article-to-markdown 已可用"
|
||||
else
|
||||
warn "未找到 wechat-article-to-markdown。无法自动提取微信公众号"
|
||||
echo " 可手动安装:uv tool install ${WECHAT_TOOL_URL}"
|
||||
fi
|
||||
|
||||
if command -v lsof >/dev/null 2>&1 && lsof -i :9222 -sTCP:LISTEN >/dev/null 2>&1; then
|
||||
ok "Chrome 调试端口 9222 已监听(可复用已登录会话)"
|
||||
else
|
||||
info "未检测到 Chrome 调试端口 9222。baoyu-url-to-markdown 仍可自动拉起临时浏览器"
|
||||
echo " 如需复用已登录会话,再执行:open -na \"Google Chrome\" --args --remote-debugging-port=9222"
|
||||
fi
|
||||
|
||||
echo ""
|
||||
echo "提示:即使部分外挂不可用,PDF / 本地文件 / 纯文本仍可直接进入主线。"
|
||||
}
|
||||
|
||||
print_source_boundary() {
|
||||
local core_sources optional_sources manual_sources
|
||||
|
||||
core_sources="$(join_source_labels core_builtin)"
|
||||
optional_sources="$(join_source_labels optional_adapter)"
|
||||
manual_sources="$(join_source_labels manual_only)"
|
||||
|
||||
echo ""
|
||||
echo "================================"
|
||||
echo " 来源边界"
|
||||
echo "================================"
|
||||
echo ""
|
||||
echo "核心主线:$core_sources"
|
||||
echo "可选外挂:$optional_sources"
|
||||
echo "手动入口:$manual_sources"
|
||||
}
|
||||
|
||||
print_adapter_states() {
|
||||
local output
|
||||
|
||||
echo ""
|
||||
echo "================================"
|
||||
echo " 外挂状态"
|
||||
echo "================================"
|
||||
echo ""
|
||||
|
||||
output="$(
|
||||
bash "$ADAPTER_STATE_SCRIPT" --skill-root "$SKILL_ROOT" --layout-mode installed_skill summary-human 2>&1
|
||||
)" || {
|
||||
warn "无法生成外挂状态摘要"
|
||||
printf '%s\n' "$output"
|
||||
return 0
|
||||
}
|
||||
|
||||
printf '%s\n' "$output"
|
||||
}
|
||||
|
||||
print_optional_adapter_hint() {
|
||||
local command
|
||||
|
||||
command="bash install.sh"
|
||||
if [ "$UPGRADE" -eq 1 ]; then
|
||||
command="$command --upgrade"
|
||||
fi
|
||||
command="$command --platform ${PLATFORM}"
|
||||
if [ -n "$TARGET_DIR" ]; then
|
||||
command="$command --target-dir ${TARGET_DIR}"
|
||||
fi
|
||||
command="$command --with-optional-adapters"
|
||||
|
||||
echo ""
|
||||
echo "提示:当前只准备了知识库核心主线。"
|
||||
echo "如需网页 / X / 微信公众号 / YouTube / 知乎自动提取,再运行:"
|
||||
echo " $command"
|
||||
}
|
||||
|
||||
print_claude_upgrade_hint() {
|
||||
local platform="$1"
|
||||
|
||||
if [ "$platform" != "claude" ]; then
|
||||
return 0
|
||||
fi
|
||||
|
||||
echo ""
|
||||
echo "提示:Claude Code 安装完成后,还可以直接用 /llm-wiki-upgrade 更新核心主线。"
|
||||
}
|
||||
|
||||
while [ $# -gt 0 ]; do
|
||||
case "$1" in
|
||||
--platform)
|
||||
[ $# -ge 2 ] || { err "--platform 需要一个值"; usage; exit 1; }
|
||||
PLATFORM="$2"
|
||||
PLATFORM_EXPLICIT=1
|
||||
shift 2
|
||||
;;
|
||||
--dry-run)
|
||||
DRY_RUN=1
|
||||
shift
|
||||
;;
|
||||
--target-dir)
|
||||
[ $# -ge 2 ] || { err "--target-dir 需要一个值"; usage; exit 1; }
|
||||
TARGET_DIR="$2"
|
||||
shift 2
|
||||
;;
|
||||
--with-optional-adapters)
|
||||
WITH_OPTIONAL_ADAPTERS=1
|
||||
shift
|
||||
;;
|
||||
--install-hooks)
|
||||
INSTALL_HOOKS=1
|
||||
shift
|
||||
;;
|
||||
--uninstall-hooks)
|
||||
UNINSTALL_HOOKS=1
|
||||
shift
|
||||
;;
|
||||
--upgrade)
|
||||
UPGRADE=1
|
||||
shift
|
||||
;;
|
||||
-h|--help)
|
||||
usage
|
||||
exit 0
|
||||
;;
|
||||
*)
|
||||
err "未知参数:$1"
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
done
|
||||
|
||||
if [ "$INSTALL_HOOKS" -eq 1 ] && [ "$UNINSTALL_HOOKS" -eq 1 ]; then
|
||||
err "--install-hooks 和 --uninstall-hooks 不能同时使用"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ "$UPGRADE" -eq 1 ]; then
|
||||
if [ -n "$TARGET_DIR" ] && [ "$PLATFORM" = "auto" ]; then
|
||||
err "自定义目标目录升级时请显式传入 --platform"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ "$PLATFORM" = "auto" ]; then
|
||||
detected_platforms=()
|
||||
for p in claude codex openclaw hermes; do
|
||||
skill_root_candidate="$(resolve_platform_skill_root "$p")"
|
||||
[ -d "$skill_root_candidate/$SKILL_NAME" ] && detected_platforms+=("$p")
|
||||
done
|
||||
|
||||
if [ "${#detected_platforms[@]}" -eq 0 ]; then
|
||||
err "没有检测到已安装的 llm-wiki,请先运行安装"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ "${#detected_platforms[@]}" -gt 1 ]; then
|
||||
err "检测到多个已安装平台:${detected_platforms[*]}。升级时请显式传入 --platform"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
PLATFORM="${detected_platforms[0]}"
|
||||
UPGRADE_PLATFORMS=("${detected_platforms[@]}")
|
||||
else
|
||||
UPGRADE_PLATFORMS=("$PLATFORM")
|
||||
fi
|
||||
|
||||
echo ""
|
||||
echo "================================"
|
||||
echo " llm-wiki 升级"
|
||||
echo "================================"
|
||||
echo ""
|
||||
|
||||
if [ -d "$SCRIPT_DIR/.git" ]; then
|
||||
info "从远程拉取最新代码..."
|
||||
if [ "$DRY_RUN" -eq 1 ]; then
|
||||
printf '[dry-run] git -C %s pull\n' "$SCRIPT_DIR"
|
||||
else
|
||||
git -C "$SCRIPT_DIR" pull || {
|
||||
err "git pull 失败,请检查网络或手动拉取后重试"
|
||||
exit 1
|
||||
}
|
||||
fi
|
||||
ok "代码已拉取到最新"
|
||||
else
|
||||
warn "当前目录不是 git 仓库,跳过 git pull"
|
||||
fi
|
||||
|
||||
upgrade_failures=0
|
||||
|
||||
for upgrade_platform in "${UPGRADE_PLATFORMS[@]}"; do
|
||||
upgrade_root="$(resolve_platform_skill_root "$upgrade_platform")"
|
||||
if [ -n "$TARGET_DIR" ]; then
|
||||
upgrade_target="$TARGET_DIR"
|
||||
upgrade_root="$(dirname "$upgrade_target")"
|
||||
else
|
||||
upgrade_target="$upgrade_root/$SKILL_NAME"
|
||||
fi
|
||||
|
||||
echo ""
|
||||
info "更新 $upgrade_platform 的 llm-wiki..."
|
||||
echo " 目标目录:$upgrade_target"
|
||||
|
||||
if [ ! -d "$upgrade_target" ]; then
|
||||
err "$upgrade_platform 尚未安装 llm-wiki:$upgrade_target"
|
||||
upgrade_failures=$((upgrade_failures + 1))
|
||||
continue
|
||||
fi
|
||||
|
||||
run_cmd mkdir -p "$upgrade_target"
|
||||
install_bundle "$upgrade_target"
|
||||
install_companion_skills "$upgrade_platform" "$upgrade_root"
|
||||
bootstrap_optional_adapters "$upgrade_root"
|
||||
ok "$upgrade_platform 的 llm-wiki 已更新"
|
||||
done
|
||||
|
||||
if [ "$upgrade_failures" -gt 0 ]; then
|
||||
echo ""
|
||||
err "llm-wiki 升级失败,请先确认目标目录存在且已完成安装"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
print_source_boundary
|
||||
if [ "$WITH_OPTIONAL_ADAPTERS" -eq 1 ]; then
|
||||
check_environment
|
||||
else
|
||||
print_optional_adapter_hint
|
||||
fi
|
||||
print_claude_upgrade_hint "$PLATFORM"
|
||||
|
||||
echo ""
|
||||
ok "llm-wiki 升级完成"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
if [ "$PLATFORM" = "auto" ] && { [ "$INSTALL_HOOKS" -eq 1 ] || [ "$UNINSTALL_HOOKS" -eq 1 ]; }; then
|
||||
PLATFORM="claude"
|
||||
fi
|
||||
|
||||
if [ "$PLATFORM" = "auto" ]; then
|
||||
detected_platforms=()
|
||||
while IFS= read -r platform_name; do
|
||||
[ -n "$platform_name" ] && detected_platforms+=("$platform_name")
|
||||
done < <(detect_available_platforms)
|
||||
if [ "${#detected_platforms[@]}" -eq 1 ]; then
|
||||
PLATFORM="${detected_platforms[0]}"
|
||||
elif [ "${#detected_platforms[@]}" -eq 0 ]; then
|
||||
err "没有检测到受支持的平台目录。请显式传入 --platform claude|codex|openclaw|hermes"
|
||||
exit 1
|
||||
else
|
||||
err "检测到多个可用平台:${detected_platforms[*]}。请显式传入 --platform"
|
||||
exit 1
|
||||
fi
|
||||
fi
|
||||
|
||||
SKILL_ROOT="$(resolve_platform_skill_root "$PLATFORM")"
|
||||
|
||||
if { [ "$INSTALL_HOOKS" -eq 1 ] || [ "$UNINSTALL_HOOKS" -eq 1 ]; } && [ "$PLATFORM" != "claude" ]; then
|
||||
err "只有 Claude Code 支持 SessionStart hook"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ -n "$TARGET_DIR" ]; then
|
||||
TARGET_SKILL_DIR="$TARGET_DIR"
|
||||
SKILL_ROOT="$(dirname "$TARGET_SKILL_DIR")"
|
||||
else
|
||||
TARGET_SKILL_DIR="$SKILL_ROOT/$SKILL_NAME"
|
||||
fi
|
||||
|
||||
if [ "$UNINSTALL_HOOKS" -eq 1 ]; then
|
||||
uninstall_claude_session_hook "$TARGET_SKILL_DIR"
|
||||
echo ""
|
||||
ok "llm-wiki hook 已移除"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
if [ "$INSTALL_HOOKS" -eq 1 ] && [ "$PLATFORM_EXPLICIT" -eq 0 ] && [ -z "$TARGET_DIR" ]; then
|
||||
register_claude_session_hook "$TARGET_SKILL_DIR"
|
||||
echo ""
|
||||
ok "llm-wiki hook 已准备完成"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
echo ""
|
||||
echo "================================"
|
||||
echo " llm-wiki 安装"
|
||||
echo "================================"
|
||||
echo ""
|
||||
echo "平台:$PLATFORM"
|
||||
echo "技能根目录:$SKILL_ROOT"
|
||||
echo "目标目录:$TARGET_SKILL_DIR"
|
||||
|
||||
run_cmd mkdir -p "$SKILL_ROOT"
|
||||
run_cmd mkdir -p "$TARGET_SKILL_DIR"
|
||||
|
||||
install_bundle "$TARGET_SKILL_DIR"
|
||||
install_companion_skills "$PLATFORM" "$SKILL_ROOT"
|
||||
bootstrap_optional_adapters "$SKILL_ROOT"
|
||||
print_source_boundary
|
||||
if [ "$WITH_OPTIONAL_ADAPTERS" -eq 1 ]; then
|
||||
check_environment
|
||||
print_adapter_states
|
||||
else
|
||||
print_optional_adapter_hint
|
||||
fi
|
||||
print_claude_upgrade_hint "$PLATFORM"
|
||||
|
||||
if [ "$INSTALL_HOOKS" -eq 1 ]; then
|
||||
register_claude_session_hook "$TARGET_SKILL_DIR"
|
||||
fi
|
||||
|
||||
echo ""
|
||||
ok "llm-wiki 已准备完成"
|
||||
@@ -0,0 +1,58 @@
|
||||
const CONTROL_OR_UNSAFE = /[\u0000-\u001f\u007f-\u009f<>:"/\\|?*]/u;
|
||||
const RESERVED_STEM = /^(?:con|prn|aux|nul|com[1-9]|lpt[1-9])$/iu;
|
||||
|
||||
/**
|
||||
* @typedef {"empty_name" | "illegal_character" | "trailing_dot_or_space" | "obsidian_breaking_token" | "windows_reserved_name"} GraphRenameFilenameSyntaxReason
|
||||
*/
|
||||
|
||||
/**
|
||||
* @typedef {{ ok: true, normalized_name: string } | { ok: false, reason: GraphRenameFilenameSyntaxReason }} GraphRenameFilenameSyntaxResult
|
||||
*/
|
||||
|
||||
/**
|
||||
* @param {string} input
|
||||
* @returns {GraphRenameFilenameSyntaxResult}
|
||||
*/
|
||||
export function validateGraphRenameFilenameSyntax(input) {
|
||||
const rawName = String(input ?? "");
|
||||
if (!rawName || !rawName.trim()) return { ok: false, reason: "empty_name" };
|
||||
|
||||
const withoutMarkdownExtension = /\.md$/iu.test(rawName)
|
||||
? rawName.slice(0, -3)
|
||||
: rawName;
|
||||
if (!withoutMarkdownExtension.trim() || withoutMarkdownExtension === "." || withoutMarkdownExtension === "..") {
|
||||
return { ok: false, reason: "empty_name" };
|
||||
}
|
||||
|
||||
const normalizedName = `${withoutMarkdownExtension}.md`;
|
||||
if (CONTROL_OR_UNSAFE.test(normalizedName)) return { ok: false, reason: "illegal_character" };
|
||||
if (/[ .]$/u.test(withoutMarkdownExtension)) return { ok: false, reason: "trailing_dot_or_space" };
|
||||
if (
|
||||
/[#|^]/u.test(normalizedName)
|
||||
|| normalizedName.includes("[[")
|
||||
|| normalizedName.includes("]]")
|
||||
|| normalizedName.includes("%%")
|
||||
) {
|
||||
return { ok: false, reason: "obsidian_breaking_token" };
|
||||
}
|
||||
|
||||
const deviceStem = withoutMarkdownExtension.split(".", 1)[0] ?? "";
|
||||
if (RESERVED_STEM.test(deviceStem)) return { ok: false, reason: "windows_reserved_name" };
|
||||
|
||||
return { ok: true, normalized_name: normalizedName };
|
||||
}
|
||||
|
||||
/**
|
||||
* @param {string} input
|
||||
* @returns {string}
|
||||
*/
|
||||
export function normalizeGraphRenameFilename(input) {
|
||||
const result = validateGraphRenameFilenameSyntax(input);
|
||||
if (!result.ok) {
|
||||
throw Object.assign(new Error(`invalid graph rename filename: ${result.reason}`), {
|
||||
code: "INVALID_REQUEST",
|
||||
reason: result.reason,
|
||||
});
|
||||
}
|
||||
return result.normalized_name;
|
||||
}
|
||||
37
llm-wiki/platforms/claude/CLAUDE.md
Normal file
37
llm-wiki/platforms/claude/CLAUDE.md
Normal file
@@ -0,0 +1,37 @@
|
||||
# Claude Code 入口
|
||||
|
||||
这是 Claude Code 的薄入口文件。共享说明看 [../../README.md](../../README.md),核心能力看 [../../SKILL.md](../../SKILL.md)。
|
||||
|
||||
## Claude 应该怎么装
|
||||
|
||||
优先执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform claude
|
||||
```
|
||||
|
||||
如果你还需要网页 / X / 微信公众号 / YouTube / 知乎自动提取,再执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform claude --with-optional-adapters
|
||||
```
|
||||
|
||||
如果你希望 Claude Code 在会话开始时自动感知当前知识库上下文,可以执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform claude --install-hooks
|
||||
```
|
||||
|
||||
默认安装位置:`~/.claude/skills/llm-wiki`
|
||||
|
||||
安装完成后,还会一并带上 `/llm-wiki-upgrade`。以后要更新核心主线,可以直接让 Claude 执行这个命令;如果还要刷新网页 / X / 微信公众号 / YouTube / 知乎自动提取能力,再继续执行带 `--with-optional-adapters` 的升级。
|
||||
|
||||
## 兼容入口
|
||||
|
||||
老用户仍然可以继续执行:
|
||||
|
||||
```bash
|
||||
bash setup.sh
|
||||
```
|
||||
|
||||
它现在会走同一套安装流程,不再单独维护另一份逻辑。若需要自动提取 URL 类来源,再显式追加 `--with-optional-adapters`。
|
||||
117
llm-wiki/platforms/claude/companions/llm-wiki-upgrade/SKILL.md
Normal file
117
llm-wiki/platforms/claude/companions/llm-wiki-upgrade/SKILL.md
Normal file
@@ -0,0 +1,117 @@
|
||||
---
|
||||
name: llm-wiki-upgrade
|
||||
version: 1.1.1
|
||||
description: |
|
||||
升级 llm-wiki 到最新版本。从 GitHub 拉取最新代码并通过官方 install.sh 升级核心主线。
|
||||
网页、X、微信公众号、YouTube、知乎自动提取依赖默认不刷新;需要时再显式开启。
|
||||
触发词:upgrade llm-wiki、更新 llm-wiki、llm-wiki 升级、llm-wiki update
|
||||
allowed-tools:
|
||||
- Bash
|
||||
- Read
|
||||
---
|
||||
|
||||
# /llm-wiki-upgrade
|
||||
|
||||
升级 llm-wiki skill 到最新版本。
|
||||
|
||||
## 升级流程
|
||||
|
||||
### Step 1:探测实际安装目录并读取当前版本
|
||||
|
||||
llm-wiki 可能装在 user 级(`$HOME/.claude/skills/llm-wiki`)或 project/vault 级(`<项目根>/.claude/skills/llm-wiki`,如 Obsidian 仓库、团队共享仓库)。这里自适应探测真实路径,后续所有步骤都基于它。`CLAUDE_PROJECT_DIR` 在 agent 的 Bash 工具里通常为空,所以用「从当前工作目录逐级向上查找」兜底,找不到再回退 user 级。
|
||||
|
||||
```bash
|
||||
SKILL_DIR=""
|
||||
# 1) Claude Code 注入的项目根(hooks/MCP 等场景)优先
|
||||
if [ -n "$CLAUDE_PROJECT_DIR" ] && [ -f "$CLAUDE_PROJECT_DIR/.claude/skills/llm-wiki/CHANGELOG.md" ]; then
|
||||
SKILL_DIR="$CLAUDE_PROJECT_DIR/.claude/skills/llm-wiki"
|
||||
fi
|
||||
# 2) 从当前工作目录逐级向上查找最近的 .claude/skills/llm-wiki(覆盖会话在 vault 子目录的场景)
|
||||
if [ -z "$SKILL_DIR" ]; then
|
||||
_d="$PWD"
|
||||
while [ "$_d" != "/" ]; do
|
||||
if [ -f "$_d/.claude/skills/llm-wiki/CHANGELOG.md" ]; then
|
||||
SKILL_DIR="$_d/.claude/skills/llm-wiki"
|
||||
break
|
||||
fi
|
||||
_d="$(dirname "$_d")"
|
||||
done
|
||||
fi
|
||||
# 3) 回退 user 级
|
||||
if [ -z "$SKILL_DIR" ] && [ -f "$HOME/.claude/skills/llm-wiki/CHANGELOG.md" ]; then
|
||||
SKILL_DIR="$HOME/.claude/skills/llm-wiki"
|
||||
fi
|
||||
OLD_VERSION=$(grep -m1 "^## v" "$SKILL_DIR/CHANGELOG.md" 2>/dev/null | grep -oE 'v[0-9]+\.[0-9]+\.[0-9]+' | head -1 || echo "unknown")
|
||||
echo "CURRENT_VERSION=$OLD_VERSION"
|
||||
echo "SKILL_DIR=$SKILL_DIR"
|
||||
```
|
||||
|
||||
如果 `SKILL_DIR` 为空(三个候选都没找到带 `CHANGELOG.md` 的 llm-wiki),告知用户尚未安装 llm-wiki,停止流程。
|
||||
|
||||
### Step 2:Clone 最新版本到临时目录
|
||||
|
||||
```bash
|
||||
TMP_DIR=$(mktemp -d)
|
||||
git clone --depth 1 https://github.com/sdyckjq-lab/llm-wiki-skill.git "$TMP_DIR/llm-wiki-skill" 2>&1
|
||||
echo "CLONE_EXIT=$?"
|
||||
```
|
||||
|
||||
如果 clone 失败(`CLONE_EXIT` 非 0),告知用户网络问题,停止流程。
|
||||
|
||||
### Step 3:读取新版本号
|
||||
|
||||
```bash
|
||||
NEW_VERSION=$(grep -m1 "^## v" "$TMP_DIR/llm-wiki-skill/CHANGELOG.md" 2>/dev/null | grep -oE 'v[0-9]+\.[0-9]+\.[0-9]+' | head -1 || echo "unknown")
|
||||
echo "NEW_VERSION=$NEW_VERSION"
|
||||
```
|
||||
|
||||
如果 `OLD_VERSION == NEW_VERSION`,告知用户已是最新版本,清理临时目录后结束:
|
||||
|
||||
```bash
|
||||
rm -rf "$TMP_DIR"
|
||||
```
|
||||
|
||||
### Step 4:执行官方升级
|
||||
|
||||
从临时目录(带 `.git`)执行 `install.sh --upgrade`。
|
||||
|
||||
注意:默认升级只更新知识库核心主线,不主动刷新网页、X、微信公众号、YouTube、知乎自动提取所需的可选依赖。
|
||||
|
||||
```bash
|
||||
bash "$TMP_DIR/llm-wiki-skill/install.sh" --upgrade --target-dir "$SKILL_DIR" --platform claude 2>&1
|
||||
echo "UPGRADE_EXIT=$?"
|
||||
```
|
||||
|
||||
如果 `UPGRADE_EXIT` 非 0,告知用户升级失败,展示关键信息,清理临时目录后停止流程。
|
||||
|
||||
### Step 5:清理临时目录
|
||||
|
||||
```bash
|
||||
rm -rf "$TMP_DIR"
|
||||
```
|
||||
|
||||
### Step 6:展示更新内容
|
||||
|
||||
读取 `$SKILL_DIR/CHANGELOG.md`,提取 `OLD_VERSION` 到 `NEW_VERSION` 之间的变更,提炼 3-5 条用户最关心的变化。
|
||||
|
||||
如果新版包含“默认只装核心主线 / 可选提取器显式开启”这类变化,要明确告诉用户:
|
||||
|
||||
- 现在默认升级不会主动刷新网页、X、微信公众号、YouTube、知乎自动提取能力
|
||||
- 如果用户需要这些自动提取能力,可以继续执行:
|
||||
|
||||
```bash
|
||||
bash "$SKILL_DIR/install.sh" --upgrade --target-dir "$SKILL_DIR" --platform claude --with-optional-adapters
|
||||
```
|
||||
|
||||
输出格式:
|
||||
|
||||
```text
|
||||
llm-wiki $NEW_VERSION 升级完成(从 $OLD_VERSION)
|
||||
|
||||
更新内容:
|
||||
- [变化1]
|
||||
- [变化2]
|
||||
- ...
|
||||
|
||||
如果需要开启或刷新网页 / X / 微信公众号 / YouTube / 知乎自动提取功能,可以告诉我执行带 --with-optional-adapters 的升级。
|
||||
```
|
||||
23
llm-wiki/platforms/codex/AGENTS.md
Normal file
23
llm-wiki/platforms/codex/AGENTS.md
Normal file
@@ -0,0 +1,23 @@
|
||||
# Codex 入口
|
||||
|
||||
<!-- llm-wiki context: 如有知识库,优先查阅 wiki/index.md -->
|
||||
|
||||
这是 Codex 的薄入口文件。共享说明看 [../../README.md](../../README.md),核心能力看 [../../SKILL.md](../../SKILL.md)。
|
||||
|
||||
## Codex 应该怎么装
|
||||
|
||||
执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform codex
|
||||
```
|
||||
|
||||
如果你还需要网页 / X / 微信公众号 / YouTube / 知乎自动提取,再执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform codex --with-optional-adapters
|
||||
```
|
||||
|
||||
默认安装位置:`~/.codex/skills/llm-wiki`
|
||||
|
||||
如果用户环境仍然在用旧的 `~/.Codex/skills`,安装器会自动兼容。
|
||||
31
llm-wiki/platforms/hermes/README.md
Normal file
31
llm-wiki/platforms/hermes/README.md
Normal file
@@ -0,0 +1,31 @@
|
||||
# Hermes 入口
|
||||
|
||||
这是 Hermes 的薄入口文件。共享说明看 [../../README.md](../../README.md),核心能力看 [../../SKILL.md](../../SKILL.md)。
|
||||
|
||||
## Hermes 应该怎么装
|
||||
|
||||
执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform hermes
|
||||
```
|
||||
|
||||
如果你还需要网页 / X / 微信公众号 / YouTube / 知乎自动提取,再执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform hermes --with-optional-adapters
|
||||
```
|
||||
|
||||
默认安装位置:`~/.hermes/skills/llm-wiki`
|
||||
|
||||
如果你的 Hermes 配了其他 skill 目录,改用:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform hermes --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
|
||||
之后升级同一个自定义目录时,也传同样的目标目录:
|
||||
|
||||
```bash
|
||||
bash install.sh --upgrade --platform hermes --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
31
llm-wiki/platforms/openclaw/README.md
Normal file
31
llm-wiki/platforms/openclaw/README.md
Normal file
@@ -0,0 +1,31 @@
|
||||
# OpenClaw 入口
|
||||
|
||||
这是 OpenClaw 的薄入口文件。共享说明看 [../../README.md](../../README.md),核心能力看 [../../SKILL.md](../../SKILL.md)。
|
||||
|
||||
## OpenClaw 应该怎么装
|
||||
|
||||
执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform openclaw
|
||||
```
|
||||
|
||||
如果你还需要网页 / X / 微信公众号 / YouTube / 知乎自动提取,再执行:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform openclaw --with-optional-adapters
|
||||
```
|
||||
|
||||
默认安装位置:`~/.openclaw/skills/llm-wiki`
|
||||
|
||||
如果你的 OpenClaw 不是这个目录,改用:
|
||||
|
||||
```bash
|
||||
bash install.sh --platform openclaw --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
|
||||
之后升级同一个自定义目录时,也传同样的目标目录:
|
||||
|
||||
```bash
|
||||
bash install.sh --upgrade --platform openclaw --target-dir <你的技能目录>/llm-wiki
|
||||
```
|
||||
424
llm-wiki/scripts/adapter-state.sh
Normal file
424
llm-wiki/scripts/adapter-state.sh
Normal file
@@ -0,0 +1,424 @@
|
||||
#!/bin/bash
|
||||
# 外挂状态检测脚本:统一判断可选外挂的安装/环境/运行状态
|
||||
# 五种状态:not_installed / env_unavailable(仅 uv 依赖的来源) / runtime_failed / unsupported / empty_result
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
PROJECT_ROOT="$(cd "$SCRIPT_DIR/.." && pwd)"
|
||||
SOURCE_REGISTRY_SCRIPT="$SCRIPT_DIR/source-registry.sh"
|
||||
# 微信工具 URL 从共享配置读取,与 install.sh 保持一致
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
source "$SCRIPT_DIR/runtime-context.sh"
|
||||
SKILL_ROOT_OVERRIDE=""
|
||||
LAYOUT_MODE_OVERRIDE=""
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/adapter-state.sh [--skill-root <path>] [--layout-mode <source_checkout|installed_skill|upgrade_target>] check <source_id>
|
||||
bash scripts/adapter-state.sh [--skill-root <path>] [--layout-mode <source_checkout|installed_skill|upgrade_target>] summary
|
||||
bash scripts/adapter-state.sh [--skill-root <path>] [--layout-mode <source_checkout|installed_skill|upgrade_target>] summary-human
|
||||
bash scripts/adapter-state.sh [--skill-root <path>] [--layout-mode <source_checkout|installed_skill|upgrade_target>] classify-run <source_id> <exit_code> <output_path>
|
||||
EOF
|
||||
}
|
||||
|
||||
resolve_optional_root() {
|
||||
resolve_optional_adapter_root "$PROJECT_ROOT" "$SKILL_ROOT_OVERRIDE" "$LAYOUT_MODE_OVERRIDE"
|
||||
}
|
||||
|
||||
dependency_installed() {
|
||||
local dependency_name="$1"
|
||||
local dependency_type="$2"
|
||||
local optional_root
|
||||
|
||||
case "$dependency_type" in
|
||||
bundled)
|
||||
optional_root="$(resolve_optional_root)"
|
||||
if [ -d "$optional_root/$dependency_name" ]; then
|
||||
return 0
|
||||
fi
|
||||
return 1
|
||||
;;
|
||||
install_time)
|
||||
command -v "$dependency_name" >/dev/null 2>&1
|
||||
;;
|
||||
none)
|
||||
return 0
|
||||
;;
|
||||
*)
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
has_uv() {
|
||||
command -v uv >/dev/null 2>&1
|
||||
}
|
||||
|
||||
chrome_debug_ready() {
|
||||
if command -v lsof >/dev/null 2>&1; then
|
||||
lsof -i :9222 -sTCP:LISTEN >/dev/null 2>&1
|
||||
return $?
|
||||
fi
|
||||
|
||||
return 1
|
||||
}
|
||||
|
||||
print_header() {
|
||||
printf '%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\n' \
|
||||
"source_id" \
|
||||
"source_label" \
|
||||
"state" \
|
||||
"state_label" \
|
||||
"detail" \
|
||||
"recovery_action" \
|
||||
"install_hint" \
|
||||
"fallback_hint"
|
||||
}
|
||||
|
||||
state_label() {
|
||||
case "$1" in
|
||||
available)
|
||||
printf '%s\n' "可用"
|
||||
;;
|
||||
not_installed)
|
||||
printf '%s\n' "未安装"
|
||||
;;
|
||||
env_unavailable)
|
||||
printf '%s\n' "环境不满足"
|
||||
;;
|
||||
runtime_failed)
|
||||
printf '%s\n' "运行失败"
|
||||
;;
|
||||
unsupported)
|
||||
printf '%s\n' "不支持自动提取"
|
||||
;;
|
||||
empty_result)
|
||||
printf '%s\n' "结果为空"
|
||||
;;
|
||||
*)
|
||||
printf '%s\n' "$1"
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
default_install_hint() {
|
||||
local source_id="$1"
|
||||
local adapter_name="$2"
|
||||
|
||||
case "$source_id" in
|
||||
web_article|x_twitter|zhihu_article)
|
||||
printf '%s\n' "重新运行当前平台的 llm-wiki 安装命令,并追加 --with-optional-adapters,确认 ${adapter_name} 已准备到技能目录"
|
||||
;;
|
||||
wechat_article)
|
||||
printf '%s\n' "先安装 uv,再执行:uv tool install ${WECHAT_TOOL_URL}"
|
||||
;;
|
||||
youtube_video)
|
||||
printf '%s\n' "重新运行当前平台的 llm-wiki 安装命令,并追加 --with-optional-adapters,确认 ${adapter_name} 已准备到技能目录"
|
||||
;;
|
||||
*)
|
||||
printf '%s\n' "-"
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
optional_hint() {
|
||||
local source_id="$1"
|
||||
|
||||
case "$source_id" in
|
||||
web_article|x_twitter|zhihu_article)
|
||||
printf '%s\n' '如需复用已登录的浏览器会话,可执行:open -na "Google Chrome" --args --remote-debugging-port=9222'
|
||||
;;
|
||||
wechat_article|youtube_video)
|
||||
printf '%s\n' "先安装 uv:brew install uv"
|
||||
;;
|
||||
*)
|
||||
printf '%s\n' "-"
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
emit_state_row() {
|
||||
local source_id="$1"
|
||||
local source_label="$2"
|
||||
local state="$3"
|
||||
local detail="$4"
|
||||
local recovery_action="$5"
|
||||
local install_hint="$6"
|
||||
local fallback_hint="$7"
|
||||
|
||||
printf '%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\n' \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"$state" \
|
||||
"$(state_label "$state")" \
|
||||
"$detail" \
|
||||
"$recovery_action" \
|
||||
"$install_hint" \
|
||||
"$fallback_hint"
|
||||
}
|
||||
|
||||
resolve_preflight_state() {
|
||||
local source_id="$1"
|
||||
local record
|
||||
local source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint
|
||||
local state detail recovery_action install_hint
|
||||
|
||||
record="$(bash "$SOURCE_REGISTRY_SCRIPT" get "$source_id")" || {
|
||||
echo "未知来源:$source_id" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
IFS=$'\t' read -r source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint <<EOF
|
||||
$record
|
||||
EOF
|
||||
|
||||
case "$source_category" in
|
||||
core_builtin)
|
||||
state="available"
|
||||
detail="核心主线可直接进入,不依赖外挂"
|
||||
recovery_action="直接继续主线"
|
||||
install_hint="-"
|
||||
;;
|
||||
manual_only)
|
||||
state="unsupported"
|
||||
detail="该来源当前只支持手动进入主线"
|
||||
recovery_action="直接走手动入口"
|
||||
install_hint="-"
|
||||
;;
|
||||
optional_adapter)
|
||||
case "$source_id" in
|
||||
wechat_article)
|
||||
if ! has_uv; then
|
||||
state="env_unavailable"
|
||||
detail="缺少 uv,当前无法准备微信公众号自动提取环境"
|
||||
recovery_action="先补环境;现在也可以直接走手动入口"
|
||||
install_hint="$(optional_hint "$source_id")"
|
||||
elif ! dependency_installed "$dependency_name" "$dependency_type"; then
|
||||
state="not_installed"
|
||||
detail="未找到 ${adapter_name}"
|
||||
recovery_action="先补安装;现在也可以直接走手动入口"
|
||||
install_hint="$(default_install_hint "$source_id" "$adapter_name")"
|
||||
else
|
||||
state="available"
|
||||
detail="${adapter_name} 已可用"
|
||||
recovery_action="继续自动提取"
|
||||
install_hint="-"
|
||||
fi
|
||||
;;
|
||||
web_article|x_twitter|zhihu_article)
|
||||
if ! dependency_installed "$dependency_name" "$dependency_type"; then
|
||||
state="not_installed"
|
||||
detail="未找到 ${adapter_name}"
|
||||
recovery_action="先补安装;现在也可以直接走手动入口"
|
||||
install_hint="$(default_install_hint "$source_id" "$adapter_name")"
|
||||
else
|
||||
state="available"
|
||||
if chrome_debug_ready; then
|
||||
detail="${adapter_name} 已可用,且已检测到可复用的 Chrome 调试会话"
|
||||
recovery_action="继续自动提取"
|
||||
install_hint="-"
|
||||
else
|
||||
detail="${adapter_name} 已可用;未检测到 9222,将在需要时自动拉起临时浏览器"
|
||||
recovery_action="继续自动提取;如需复用已登录会话,可先开启 Chrome 调试端口 9222"
|
||||
install_hint="$(optional_hint "$source_id")"
|
||||
fi
|
||||
fi
|
||||
;;
|
||||
youtube_video)
|
||||
if ! dependency_installed "$dependency_name" "$dependency_type"; then
|
||||
state="not_installed"
|
||||
detail="未找到 ${adapter_name}"
|
||||
recovery_action="先补安装;现在也可以直接走手动入口"
|
||||
install_hint="$(default_install_hint "$source_id" "$adapter_name")"
|
||||
elif ! has_uv; then
|
||||
state="env_unavailable"
|
||||
detail="缺少 uv,当前无法运行 YouTube 字幕提取"
|
||||
recovery_action="先补环境;现在也可以直接走手动入口"
|
||||
install_hint="$(optional_hint "$source_id")"
|
||||
else
|
||||
state="available"
|
||||
detail="${adapter_name} 已可用"
|
||||
recovery_action="继续自动提取"
|
||||
install_hint="-"
|
||||
fi
|
||||
;;
|
||||
*)
|
||||
if ! dependency_installed "$dependency_name" "$dependency_type"; then
|
||||
state="not_installed"
|
||||
detail="未找到 ${adapter_name}"
|
||||
recovery_action="先补安装;现在也可以直接走手动入口"
|
||||
install_hint="$(default_install_hint "$source_id" "$adapter_name")"
|
||||
else
|
||||
state="available"
|
||||
detail="${adapter_name} 已可用"
|
||||
recovery_action="继续自动提取"
|
||||
install_hint="-"
|
||||
fi
|
||||
;;
|
||||
esac
|
||||
;;
|
||||
*)
|
||||
echo "未知来源分类:$source_category" >&2
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
|
||||
emit_state_row \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"$state" \
|
||||
"$detail" \
|
||||
"$recovery_action" \
|
||||
"$install_hint" \
|
||||
"$fallback_hint"
|
||||
}
|
||||
|
||||
classify_run_state() {
|
||||
local source_id="$1"
|
||||
local exit_code="$2"
|
||||
local output_path="$3"
|
||||
|
||||
# 校验 exit_code 为整数,防止 set -e 下非数字参数导致脚本崩溃
|
||||
case "$exit_code" in
|
||||
''|*[!0-9-]*) echo "exit_code 必须是整数,收到:$exit_code" >&2; exit 1 ;;
|
||||
esac
|
||||
|
||||
local row
|
||||
local source_label state state_label_value detail recovery_action install_hint fallback_hint
|
||||
|
||||
row="$(resolve_preflight_state "$source_id")"
|
||||
IFS=$'\t' read -r _ source_label state state_label_value detail recovery_action install_hint fallback_hint <<EOF
|
||||
$row
|
||||
EOF
|
||||
|
||||
if [ "$state" != "available" ]; then
|
||||
emit_state_row \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"$state" \
|
||||
"$detail" \
|
||||
"$recovery_action" \
|
||||
"$install_hint" \
|
||||
"$fallback_hint"
|
||||
return 0
|
||||
fi
|
||||
|
||||
if [ "$exit_code" -ne 0 ]; then
|
||||
emit_state_row \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"runtime_failed" \
|
||||
"自动提取执行失败" \
|
||||
"可以先重试一次;如果还不行,就改走手动入口" \
|
||||
"-" \
|
||||
"$fallback_hint"
|
||||
return 0
|
||||
fi
|
||||
|
||||
if [ ! -f "$output_path" ] || ! grep -q '[^[:space:]]' "$output_path" 2>/dev/null; then
|
||||
emit_state_row \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"empty_result" \
|
||||
"自动提取完成,但没有拿到有效正文" \
|
||||
"请手动补全文本后继续主线" \
|
||||
"-" \
|
||||
"$fallback_hint"
|
||||
return 0
|
||||
fi
|
||||
|
||||
emit_state_row \
|
||||
"$source_id" \
|
||||
"$source_label" \
|
||||
"available" \
|
||||
"自动提取已拿到有效正文" \
|
||||
"继续进入主线" \
|
||||
"-" \
|
||||
"$fallback_hint"
|
||||
}
|
||||
|
||||
print_summary() {
|
||||
local source_id
|
||||
|
||||
print_header
|
||||
|
||||
while IFS=$'\t' read -r source_id _; do
|
||||
[ -n "$source_id" ] || continue
|
||||
resolve_preflight_state "$source_id"
|
||||
done <<EOF
|
||||
$(bash "$SOURCE_REGISTRY_SCRIPT" list | awk -F '\t' 'NR > 1 && ($3 == "optional_adapter" || $3 == "manual_only") { print $1 "\t" $2 }')
|
||||
EOF
|
||||
}
|
||||
|
||||
print_summary_human() {
|
||||
local row
|
||||
local source_id source_label state state_label_value detail recovery_action install_hint fallback_hint
|
||||
|
||||
while IFS= read -r row; do
|
||||
[ -n "$row" ] || continue
|
||||
|
||||
IFS=$'\t' read -r source_id source_label state state_label_value detail recovery_action install_hint fallback_hint <<EOF
|
||||
$row
|
||||
EOF
|
||||
|
||||
printf '%s\n' "- ${source_label}:${state_label_value}。${detail}。"
|
||||
printf '%s\n' " 下一步:${recovery_action}。"
|
||||
if [ "$install_hint" != "-" ]; then
|
||||
if [ "$state" = "available" ]; then
|
||||
printf '%s\n' " 补充说明:${install_hint}。"
|
||||
else
|
||||
printf '%s\n' " 安装提示:${install_hint}。"
|
||||
fi
|
||||
fi
|
||||
printf '%s\n' " 回退方式:${fallback_hint}。"
|
||||
done <<EOF
|
||||
$(print_summary | tail -n +2)
|
||||
EOF
|
||||
}
|
||||
|
||||
while [ $# -gt 0 ]; do
|
||||
case "$1" in
|
||||
--skill-root)
|
||||
[ $# -ge 2 ] || { usage; exit 1; }
|
||||
SKILL_ROOT_OVERRIDE="$2"
|
||||
shift 2
|
||||
;;
|
||||
--layout-mode)
|
||||
[ $# -ge 2 ] || { usage; exit 1; }
|
||||
LAYOUT_MODE_OVERRIDE="$2"
|
||||
shift 2
|
||||
;;
|
||||
*)
|
||||
break
|
||||
;;
|
||||
esac
|
||||
done
|
||||
|
||||
command_name="${1:-}"
|
||||
|
||||
case "$command_name" in
|
||||
check)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
print_header
|
||||
resolve_preflight_state "$2"
|
||||
;;
|
||||
summary)
|
||||
[ "$#" -eq 1 ] || { usage; exit 1; }
|
||||
print_summary
|
||||
;;
|
||||
summary-human)
|
||||
[ "$#" -eq 1 ] || { usage; exit 1; }
|
||||
print_summary_human
|
||||
;;
|
||||
classify-run)
|
||||
[ "$#" -eq 4 ] || { usage; exit 1; }
|
||||
print_header
|
||||
classify_run_state "$2" "$3" "$4"
|
||||
;;
|
||||
*)
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
234
llm-wiki/scripts/build-graph-data.sh
Executable file
234
llm-wiki/scripts/build-graph-data.sh
Executable file
@@ -0,0 +1,234 @@
|
||||
#!/bin/bash
|
||||
# build-graph-data.sh — build a path-identity graph and its sibling warning sidecar.
|
||||
#
|
||||
# Usage:
|
||||
# bash scripts/build-graph-data.sh <kb-root> [<kb-internal-dir>/graph-data.json]
|
||||
#
|
||||
# A custom output must remain inside the knowledge base, keep the graph-data.json
|
||||
# basename, and owns graph-warnings.json in the same existing directory.
|
||||
# Exit codes: 0 = valid graph produced (including data warnings); 1 = tool/input failure.
|
||||
|
||||
set -eu
|
||||
|
||||
SCRIPT_DIR="${BASH_SOURCE[0]%/*}"
|
||||
[ "$SCRIPT_DIR" = "${BASH_SOURCE[0]}" ] && SCRIPT_DIR="."
|
||||
SCRIPT_DIR="$(cd "$SCRIPT_DIR" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
usage() {
|
||||
cat <<'USAGE'
|
||||
Usage:
|
||||
bash scripts/build-graph-data.sh <kb-root> [<kb-internal-dir>/graph-data.json]
|
||||
|
||||
Custom output rules:
|
||||
- the destination directory must already exist inside the knowledge base
|
||||
- the graph filename must remain graph-data.json
|
||||
- graph-warnings.json is committed beside it as the unique paired warning file
|
||||
USAGE
|
||||
}
|
||||
|
||||
[ "$#" -ge 1 ] && [ "$#" -le 2 ] || {
|
||||
usage >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
command -v jq >/dev/null 2>&1 || {
|
||||
echo "ERROR: jq is not installed. Install it via:" >&2
|
||||
print_install_hint jq
|
||||
exit 1
|
||||
}
|
||||
command -v node >/dev/null 2>&1 || {
|
||||
echo "ERROR: node is not installed. Install it via:" >&2
|
||||
print_install_hint node
|
||||
exit 1
|
||||
}
|
||||
|
||||
WIKI_ROOT_INPUT="$1"
|
||||
[ -d "$WIKI_ROOT_INPUT" ] || {
|
||||
echo "ERROR: knowledge base does not exist or is not readable: $WIKI_ROOT_INPUT" >&2
|
||||
exit 1
|
||||
}
|
||||
WIKI_ROOT="$(cd "$WIKI_ROOT_INPUT" && pwd)"
|
||||
WIKI_DIR="$WIKI_ROOT/wiki"
|
||||
[ -d "$WIKI_DIR" ] || {
|
||||
echo "ERROR: wiki directory does not exist: $WIKI_DIR" >&2
|
||||
echo " Run init-wiki.sh before building the graph." >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
if [ "$#" -eq 2 ]; then
|
||||
OUTPUT_INPUT="$2"
|
||||
OUTPUT_PARENT="$(dirname "$OUTPUT_INPUT")"
|
||||
[ -d "$OUTPUT_PARENT" ] || {
|
||||
echo "ERROR: custom graph output directory does not exist: $OUTPUT_PARENT" >&2
|
||||
exit 1
|
||||
}
|
||||
OUTPUT="$(cd "$OUTPUT_PARENT" && pwd)/$(basename "$OUTPUT_INPUT")"
|
||||
else
|
||||
OUTPUT="$WIKI_ROOT/wiki/graph-data.json"
|
||||
fi
|
||||
|
||||
SKILL_DIR="$(cd "$SCRIPT_DIR/.." && pwd)"
|
||||
HELPER="$SCRIPT_DIR/graph-analysis.js"
|
||||
CLI="$SCRIPT_DIR/wiki-link-cli.js"
|
||||
BUNDLE="$SCRIPT_DIR/lib/graph-warning-bundle.js"
|
||||
[ -f "$HELPER" ] || {
|
||||
echo "ERROR: 找不到图谱分析 helper:$HELPER" >&2
|
||||
echo " Reinstall the skill and retry." >&2
|
||||
exit 1
|
||||
}
|
||||
[ -f "$CLI" ] || {
|
||||
echo "ERROR: shared wikilink resolver is missing: $CLI" >&2
|
||||
echo " Reinstall the skill and retry." >&2
|
||||
exit 1
|
||||
}
|
||||
[ -f "$BUNDLE" ] || {
|
||||
echo "ERROR: graph warning bundle helper is missing: $BUNDLE" >&2
|
||||
echo " Reinstall the skill and retry." >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
MAX_CONTENT_BYTES=$((2 * 1024 * 1024))
|
||||
MAX_CONTENT_LINES=500
|
||||
MAX_INSIGHT_NODES=250
|
||||
MAX_INSIGHT_EDGES=1000
|
||||
|
||||
TMPDIR="$(mktemp -d -t llm-wiki-graph.XXXXXX)"
|
||||
trap 'rm -rf "$TMPDIR"' EXIT
|
||||
SCAN_DIR="$TMPDIR/scan"
|
||||
mkdir -p "$SCAN_DIR"
|
||||
|
||||
GRAPH_FLAGS=""
|
||||
if [ "${LLM_WIKI_TEST_MODE:-0}" = "1" ]; then
|
||||
BUILD_DATE="2026-01-01T00:00:00Z"
|
||||
GRAPH_FLAGS="--test-mode"
|
||||
else
|
||||
BUILD_DATE="$(date -u +%Y-%m-%dT%H:%M:%SZ)"
|
||||
fi
|
||||
|
||||
if [ -n "$GRAPH_FLAGS" ]; then
|
||||
node "$CLI" graph "$WIKI_ROOT" "$SCAN_DIR" "$GRAPH_FLAGS" > "$TMPDIR/scan.out"
|
||||
else
|
||||
node "$CLI" graph "$WIKI_ROOT" "$SCAN_DIR" > "$TMPDIR/scan.out"
|
||||
fi
|
||||
|
||||
for SCAN_FILE in nodes.json edges.json warning-groups.json candidate-sets.json scan-metrics.json; do
|
||||
[ -f "$SCAN_DIR/$SCAN_FILE" ] || {
|
||||
echo "ERROR: graph scan did not produce $SCAN_FILE" >&2
|
||||
exit 1
|
||||
}
|
||||
done
|
||||
|
||||
WIKI_TITLE=""
|
||||
if [ -f "$WIKI_ROOT/purpose.md" ]; then
|
||||
WIKI_TITLE="$(awk '/^# / { sub(/^# +/, ""); print; exit }' "$WIKI_ROOT/purpose.md")"
|
||||
fi
|
||||
[ -n "$WIKI_TITLE" ] || WIKI_TITLE="$(basename "$WIKI_ROOT")"
|
||||
|
||||
TOTAL_SIZE="$(jq -r '.graph_source_bytes // 0' "$SCAN_DIR/scan-metrics.json")"
|
||||
DEGRADE=0
|
||||
if [ "$TOTAL_SIZE" -gt "$MAX_CONTENT_BYTES" ]; then
|
||||
DEGRADE=1
|
||||
fi
|
||||
|
||||
ANALYSIS_JSON="$TMPDIR/analysis.json"
|
||||
if ! node "$HELPER" \
|
||||
"$SCAN_DIR/nodes.json" \
|
||||
"$SCAN_DIR/edges.json" \
|
||||
"$ANALYSIS_JSON" \
|
||||
"$DEGRADE" \
|
||||
"$MAX_CONTENT_LINES" \
|
||||
"$MAX_INSIGHT_NODES" \
|
||||
"$MAX_INSIGHT_EDGES"; then
|
||||
echo "ERROR: graph analysis helper failed: $HELPER" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
jq -e '
|
||||
(.nodes | type) == "array" and
|
||||
(.edges | type) == "array" and
|
||||
(.insights | type) == "object" and
|
||||
(.learning | type) == "object"
|
||||
' "$ANALYSIS_JSON" > /dev/null 2>&1 || {
|
||||
echo "ERROR: graph analysis helper returned invalid JSON: $ANALYSIS_JSON" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
if [ "${LLM_WIKI_TEST_MODE:-0}" = "1" ]; then
|
||||
jq '.nodes | sort_by(.id)' "$ANALYSIS_JSON" > "$TMPDIR/nodes.sorted.json"
|
||||
jq '.edges | sort_by(.from, .to, .relation_type, .type)
|
||||
| to_entries
|
||||
| map(.value + {id: ("e" + ((.key + 1) | tostring))})' \
|
||||
"$ANALYSIS_JSON" > "$TMPDIR/edges.sorted.json"
|
||||
else
|
||||
jq '.nodes' "$ANALYSIS_JSON" > "$TMPDIR/nodes.sorted.json"
|
||||
jq '.edges' "$ANALYSIS_JSON" > "$TMPDIR/edges.sorted.json"
|
||||
fi
|
||||
|
||||
INITIAL_VIEW="$TMPDIR/initial-view.json"
|
||||
jq --slurpfile nodes "$TMPDIR/nodes.sorted.json" '
|
||||
. as $edges
|
||||
| ($nodes[0]) as $node_rows
|
||||
| (reduce $edges[] as $edge ({};
|
||||
.[$edge.from] = (.[$edge.from] // 0) + 1
|
||||
| .[$edge.to] = (.[$edge.to] // 0) + 1
|
||||
)) as $degree
|
||||
| ($node_rows | group_by(.community // "_")) as $groups
|
||||
| ([ $groups[] | max_by(($degree[.id] // 0)) | .id ]) as $representatives
|
||||
| ($node_rows
|
||||
| sort_by(-($degree[.id] // 0), .id)
|
||||
| map(.id)
|
||||
| map(select(. as $id | $representatives | index($id) | not))) as $rest
|
||||
| ($representatives + $rest)[0:30]
|
||||
' "$TMPDIR/edges.sorted.json" > "$INITIAL_VIEW"
|
||||
|
||||
NODE_COUNT="$(jq 'length' "$TMPDIR/nodes.sorted.json")"
|
||||
EDGE_COUNT="$(jq 'length' "$TMPDIR/edges.sorted.json")"
|
||||
INSIGHTS_DEGRADED="$(jq '.insights.meta.degraded == true' "$ANALYSIS_JSON")"
|
||||
|
||||
GRAPH_INPUT="$TMPDIR/graph-data.json"
|
||||
jq -n \
|
||||
--arg build_date "$BUILD_DATE" \
|
||||
--arg wiki_title "$WIKI_TITLE" \
|
||||
--argjson total_nodes "$NODE_COUNT" \
|
||||
--argjson total_edges "$EDGE_COUNT" \
|
||||
--slurpfile initial_view "$INITIAL_VIEW" \
|
||||
--slurpfile nodes "$TMPDIR/nodes.sorted.json" \
|
||||
--slurpfile edges "$TMPDIR/edges.sorted.json" \
|
||||
--slurpfile analysis "$ANALYSIS_JSON" \
|
||||
--argjson degraded "$DEGRADE" \
|
||||
--argjson insights_degraded "$INSIGHTS_DEGRADED" \
|
||||
'{
|
||||
meta: {
|
||||
build_date: $build_date,
|
||||
wiki_title: $wiki_title,
|
||||
total_nodes: $total_nodes,
|
||||
total_edges: $total_edges,
|
||||
initial_view: $initial_view[0],
|
||||
degraded: ($degraded == 1),
|
||||
insights_degraded: $insights_degraded
|
||||
},
|
||||
nodes: $nodes[0],
|
||||
edges: $edges[0],
|
||||
insights: $analysis[0].insights,
|
||||
learning: $analysis[0].learning
|
||||
}' > "$GRAPH_INPUT"
|
||||
|
||||
if ! node "$CLI" commit-pair \
|
||||
"$WIKI_ROOT" \
|
||||
"$GRAPH_INPUT" \
|
||||
"$SCAN_DIR/warning-groups.json" \
|
||||
"$SCAN_DIR/candidate-sets.json" \
|
||||
"$OUTPUT" > "$TMPDIR/commit.out"; then
|
||||
echo "ERROR: graph artifact pair commit failed for $OUTPUT" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
echo "Graph data generated: $OUTPUT"
|
||||
echo " Nodes: $NODE_COUNT"
|
||||
echo " Edges: $EDGE_COUNT"
|
||||
echo " Warning sidecar: $(dirname "$OUTPUT")/graph-warnings.json"
|
||||
[ "$DEGRADE" = "1" ] && echo " Warning: content embedding degraded above 2 MiB"
|
||||
[ "$INSIGHTS_DEGRADED" = "true" ] && echo " Warning: insights degraded for graph size"
|
||||
exit 0
|
||||
651
llm-wiki/scripts/build-graph-html.sh
Executable file
651
llm-wiki/scripts/build-graph-html.sh
Executable file
@@ -0,0 +1,651 @@
|
||||
#!/bin/bash
|
||||
# build-graph-html.sh — 生成共享 graph-engine 驱动的离线知识图谱 HTML
|
||||
#
|
||||
# 用法:
|
||||
# bash scripts/build-graph-html.sh <wiki_root>
|
||||
#
|
||||
# 前置:需要先运行 build-graph-data.sh 生成 wiki/graph-data.json
|
||||
#
|
||||
# 行为:
|
||||
# 1. 读取 packages/graph-engine/dist/engine.iife.js
|
||||
# 2. 验证并内嵌配对告警、graph-data.json 与可选 .wiki-graph-layout.json 钉位
|
||||
# 3. 注入离线启动脚本:创建 graph engine,持久化钉位到 localStorage
|
||||
# 4. 生成单文件 knowledge-graph.html
|
||||
#
|
||||
# 退出码:0 成功;1 依赖/文件缺失/参数错误
|
||||
|
||||
set -eu
|
||||
|
||||
SCRIPT_DIR="${BASH_SOURCE[0]%/*}"
|
||||
[ "$SCRIPT_DIR" = "${BASH_SOURCE[0]}" ] && SCRIPT_DIR="."
|
||||
SCRIPT_DIR="$(cd "$SCRIPT_DIR" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
print_usage() {
|
||||
cat <<'USAGE'
|
||||
用法:
|
||||
bash scripts/build-graph-html.sh <wiki_root>
|
||||
|
||||
示例:
|
||||
bash scripts/build-graph-html.sh /path/to/wiki-root
|
||||
USAGE
|
||||
}
|
||||
|
||||
die() {
|
||||
echo "ERROR: $1" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
ensure_file() {
|
||||
local file="$1"
|
||||
local label="${2:-文件}"
|
||||
[ -f "$file" ] || {
|
||||
echo "ERROR: 找不到${label} $file" >&2
|
||||
echo " 请先运行 npm run build -w @llm-wiki/graph-engine,或重装 skill。" >&2
|
||||
exit 1
|
||||
}
|
||||
}
|
||||
|
||||
json_for_script() {
|
||||
node - "$1" <<'NODE'
|
||||
const fs = require("node:fs");
|
||||
const text = fs.readFileSync(process.argv[2], "utf8");
|
||||
const escaped = text.replace(/[<>&\u2028\u2029]/g, (character) => (
|
||||
`\\u${character.codePointAt(0).toString(16).padStart(4, "0")}`
|
||||
));
|
||||
process.stdout.write(escaped);
|
||||
NODE
|
||||
}
|
||||
|
||||
script_for_inline() {
|
||||
perl -pe 's|//# sourceMappingURL=.*$||' "$1"
|
||||
}
|
||||
|
||||
html_escape_text() {
|
||||
printf '%s' "$1" | perl -pe 's/&/&/g; s/</</g; s/>/>/g; s/"/"/g; s/'"'"'/'/g'
|
||||
}
|
||||
|
||||
while [ "$#" -gt 0 ]; do
|
||||
case "$1" in
|
||||
-h|--help)
|
||||
print_usage
|
||||
exit 0
|
||||
;;
|
||||
--)
|
||||
shift
|
||||
break
|
||||
;;
|
||||
-*)
|
||||
die "未知选项: $1"
|
||||
;;
|
||||
*)
|
||||
break
|
||||
;;
|
||||
esac
|
||||
done
|
||||
|
||||
[ "$#" -eq 1 ] || {
|
||||
print_usage >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
WIKI_ROOT="$1"
|
||||
|
||||
command -v jq >/dev/null 2>&1 || {
|
||||
echo "ERROR: jq is not installed. Install it via:" >&2
|
||||
print_install_hint jq
|
||||
exit 1
|
||||
}
|
||||
|
||||
SKILL_DIR="$(cd "$SCRIPT_DIR/.." && pwd)"
|
||||
DATA="$WIKI_ROOT/wiki/graph-data.json"
|
||||
WARNINGS="$WIKI_ROOT/wiki/graph-warnings.json"
|
||||
LAYOUT="$WIKI_ROOT/.wiki-graph-layout.json"
|
||||
ENGINE="$SKILL_DIR/packages/graph-engine/dist/engine.iife.js"
|
||||
MARKED="$SKILL_DIR/deps/marked.min.js"
|
||||
PURIFY="$SKILL_DIR/deps/purify.min.js"
|
||||
OUTPUT="$WIKI_ROOT/wiki/knowledge-graph.html"
|
||||
WARNING_CLI="$SCRIPT_DIR/wiki-link-cli.js"
|
||||
|
||||
[ -f "$DATA" ] || {
|
||||
echo "ERROR: 未找到 $DATA" >&2
|
||||
echo " 请先运行 build-graph-data.sh 生成图谱数据" >&2
|
||||
exit 1
|
||||
}
|
||||
ensure_file "$ENGINE" "graph-engine IIFE 产物"
|
||||
ensure_file "$MARKED" "marked vendor"
|
||||
ensure_file "$PURIFY" "purify vendor"
|
||||
ensure_file "$WARNING_CLI" "warning verifier"
|
||||
|
||||
WIKI_TITLE=$(jq -r '.meta.wiki_title // "知识库"' "$DATA")
|
||||
NODE_COUNT=$(jq -r '.meta.total_nodes // 0' "$DATA")
|
||||
EDGE_COUNT=$(jq -r '.meta.total_edges // 0' "$DATA")
|
||||
BUILD_DATE=$(jq -r '.meta.build_date // ""' "$DATA")
|
||||
BUILD_DATE_SHORT="${BUILD_DATE:0:10}"
|
||||
[ -n "$BUILD_DATE_SHORT" ] || BUILD_DATE_SHORT="未知"
|
||||
WIKI_TITLE_HTML=$(html_escape_text "$WIKI_TITLE")
|
||||
NODE_COUNT_HTML=$(html_escape_text "$NODE_COUNT")
|
||||
EDGE_COUNT_HTML=$(html_escape_text "$EDGE_COUNT")
|
||||
BUILD_DATE_SHORT_HTML=$(html_escape_text "$BUILD_DATE_SHORT")
|
||||
|
||||
layout_json='{"version":2,"pins":{},"updatedAt":""}'
|
||||
if [ -f "$LAYOUT" ]; then
|
||||
if layout_json_candidate=$(jq -c '{version:(.version // 1), pins:(.pins // {}), updatedAt:(.updatedAt // "")}' "$LAYOUT" 2>/dev/null); then
|
||||
layout_json="$layout_json_candidate"
|
||||
else
|
||||
echo "WARN: 忽略损坏的钉位文件:$LAYOUT" >&2
|
||||
fi
|
||||
fi
|
||||
|
||||
output_dir="$(dirname "$OUTPUT")"
|
||||
mkdir -p "$output_dir"
|
||||
output_tmp="$OUTPUT.partial"
|
||||
output_next="$OUTPUT.next"
|
||||
warning_data_tmp="$(mktemp -t llm-wiki-warning.XXXXXX)"
|
||||
trap 'rm -f "$warning_data_tmp" "$output_tmp" "$output_next"' EXIT
|
||||
rm -f "$output_tmp" "$output_next"
|
||||
|
||||
node "$WARNING_CLI" warning-embed "$WIKI_ROOT" "$DATA" "$WARNINGS" "$warning_data_tmp" \
|
||||
|| die "告警详情验证失败,无法生成安全的离线载荷"
|
||||
|
||||
cat > "$output_tmp" <<HTML_HEAD
|
||||
<!doctype html>
|
||||
<html lang="zh-Hans">
|
||||
<head>
|
||||
<meta charset="utf-8">
|
||||
<meta name="viewport" content="width=device-width, initial-scale=1">
|
||||
<title>知识图谱 · ${WIKI_TITLE_HTML}</title>
|
||||
<style>
|
||||
:root {
|
||||
color-scheme: light;
|
||||
--page-bg: #f7f1e5;
|
||||
--panel: rgba(255, 252, 244, .86);
|
||||
--ink: #2f2924;
|
||||
--muted: #766b5f;
|
||||
--rule: rgba(79, 64, 46, .2);
|
||||
--accent: #a83f35;
|
||||
}
|
||||
* { box-sizing: border-box; }
|
||||
html, body { margin: 0; min-height: 100%; }
|
||||
body {
|
||||
min-height: 100vh;
|
||||
color: var(--ink);
|
||||
background: var(--page-bg);
|
||||
font-family: ui-sans-serif, system-ui, -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif;
|
||||
}
|
||||
.offline-shell {
|
||||
display: grid;
|
||||
grid-template-rows: auto auto minmax(0, 1fr);
|
||||
min-height: 100vh;
|
||||
}
|
||||
.offline-header {
|
||||
position: relative;
|
||||
z-index: 20;
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
gap: 16px;
|
||||
min-height: 64px;
|
||||
padding: 12px 18px;
|
||||
border-bottom: 1px solid var(--rule);
|
||||
background: var(--panel);
|
||||
backdrop-filter: blur(10px);
|
||||
}
|
||||
.offline-title { min-width: 0; }
|
||||
.offline-title h1 {
|
||||
margin: 0;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
white-space: nowrap;
|
||||
font-family: Georgia, "Times New Roman", serif;
|
||||
font-size: 20px;
|
||||
letter-spacing: 0;
|
||||
}
|
||||
.offline-title p {
|
||||
margin: 4px 0 0;
|
||||
color: var(--muted);
|
||||
font-size: 12px;
|
||||
}
|
||||
.offline-badges {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 8px;
|
||||
flex-wrap: wrap;
|
||||
justify-content: flex-end;
|
||||
color: var(--muted);
|
||||
font-size: 12px;
|
||||
}
|
||||
.offline-badges span {
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
min-height: 26px;
|
||||
padding: 4px 9px;
|
||||
border: 1px solid var(--rule);
|
||||
border-radius: 999px;
|
||||
background: rgba(255, 255, 255, .46);
|
||||
}
|
||||
.offline-theme-toggle {
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
min-height: 26px;
|
||||
border: 1px solid var(--rule);
|
||||
border-radius: 999px;
|
||||
background: rgba(255, 255, 255, .52);
|
||||
color: var(--ink);
|
||||
padding: 4px 10px;
|
||||
font: inherit;
|
||||
cursor: pointer;
|
||||
}
|
||||
.offline-theme-toggle:hover {
|
||||
background: rgba(168, 63, 53, .08);
|
||||
}
|
||||
.offline-toolbar-host {
|
||||
position: relative;
|
||||
z-index: 5;
|
||||
flex: 1 1 320px;
|
||||
min-width: 240px;
|
||||
min-height: 38px;
|
||||
}
|
||||
.offline-toolbar-host .graph-toolbar {
|
||||
position: static;
|
||||
inset: auto;
|
||||
justify-items: center;
|
||||
}
|
||||
.offline-toolbar-host .graph-toolbar-panel {
|
||||
position: absolute;
|
||||
top: 38px;
|
||||
left: 50%;
|
||||
transform: translateX(-50%);
|
||||
}
|
||||
.offline-main {
|
||||
position: relative;
|
||||
z-index: 1;
|
||||
grid-row: 3;
|
||||
min-height: 0;
|
||||
padding: 0;
|
||||
}
|
||||
#graph-root {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
min-height: 560px;
|
||||
}
|
||||
.offline-error {
|
||||
margin: 24px;
|
||||
padding: 16px;
|
||||
border: 1px solid rgba(168, 63, 53, .35);
|
||||
border-radius: 8px;
|
||||
background: rgba(168, 63, 53, .08);
|
||||
color: #7b2b24;
|
||||
font-size: 14px;
|
||||
line-height: 1.6;
|
||||
}
|
||||
.offline-storage-warning {
|
||||
margin: 12px 18px 0;
|
||||
}
|
||||
.offline-warning-banner {
|
||||
position: relative;
|
||||
z-index: 15;
|
||||
margin: 10px 18px 0;
|
||||
padding: 12px 14px;
|
||||
border: 1px solid rgba(168, 63, 53, .3);
|
||||
border-radius: 10px;
|
||||
background: rgba(255, 249, 237, .94);
|
||||
color: var(--ink);
|
||||
font-size: 13px;
|
||||
line-height: 1.55;
|
||||
}
|
||||
.offline-warning-banner[hidden] { display: none; }
|
||||
.offline-warning-summary { font-weight: 650; }
|
||||
.offline-warning-notice { margin-top: 6px; color: #7b2b24; }
|
||||
.offline-warning-details { margin-top: 8px; }
|
||||
.offline-warning-details > summary { cursor: pointer; color: var(--accent); }
|
||||
.offline-warning-group { margin: 10px 0 0 14px; }
|
||||
.offline-warning-group h3 { margin: 0; font-size: 13px; }
|
||||
.offline-warning-group ul { margin: 4px 0 0; padding-left: 20px; }
|
||||
@media (max-width: 720px) {
|
||||
.offline-header { align-items: flex-start; flex-direction: column; }
|
||||
.offline-toolbar-host { width: 100%; flex-basis: auto; }
|
||||
.offline-toolbar-host .graph-toolbar { justify-items: start; }
|
||||
.offline-toolbar-host .graph-toolbar-panel { left: 0; transform: none; }
|
||||
.offline-badges { justify-content: flex-start; }
|
||||
#graph-root { min-height: 520px; }
|
||||
}
|
||||
</style>
|
||||
</head>
|
||||
<body>
|
||||
<div class="offline-shell" data-llm-wiki-offline-graph="engine">
|
||||
<header class="offline-header">
|
||||
<div class="offline-title">
|
||||
<h1>${WIKI_TITLE_HTML} 知识舆图</h1>
|
||||
<p>国风知识库·数字山水图</p>
|
||||
</div>
|
||||
<div class="offline-toolbar-host" data-testid="offline-toolbar-host"></div>
|
||||
<div class="offline-badges" aria-label="图谱统计">
|
||||
<span>${NODE_COUNT_HTML} 节点</span>
|
||||
<span>${EDGE_COUNT_HTML} 关联</span>
|
||||
<span>${BUILD_DATE_SHORT_HTML}</span>
|
||||
<button class="offline-theme-toggle" type="button" data-testid="offline-theme-toggle" aria-label="切换墨夜主题">墨夜</button>
|
||||
</div>
|
||||
</header>
|
||||
<section class="offline-warning-banner" data-testid="offline-warning-banner" aria-label="图谱告警" hidden>
|
||||
<div class="offline-warning-summary" data-testid="offline-warning-summary"></div>
|
||||
<div class="offline-warning-notice" data-testid="offline-warning-unavailable" hidden></div>
|
||||
<div class="offline-warning-notice" data-testid="offline-warning-truncated" hidden></div>
|
||||
<details class="offline-warning-details" data-testid="offline-warning-details">
|
||||
<summary>查看告警详情</summary>
|
||||
<div data-testid="offline-warning-groups"></div>
|
||||
</details>
|
||||
</section>
|
||||
<main class="offline-main">
|
||||
<div id="graph-root" data-testid="offline-graph-root"></div>
|
||||
</main>
|
||||
</div>
|
||||
<script id="graph-data" type="application/json">
|
||||
HTML_HEAD
|
||||
json_for_script "$DATA" >> "$output_tmp"
|
||||
cat >> "$output_tmp" <<'HTML_MID'
|
||||
</script>
|
||||
<script id="graph-warning-data" type="application/json">
|
||||
HTML_MID
|
||||
cat "$warning_data_tmp" >> "$output_tmp"
|
||||
cat >> "$output_tmp" <<'HTML_WARNING_END'
|
||||
</script>
|
||||
<script id="graph-layout" type="application/json">
|
||||
HTML_WARNING_END
|
||||
printf '%s\n' "$layout_json" | perl -pe 's|</script>|<\/script>|gi' >> "$output_tmp"
|
||||
cat >> "$output_tmp" <<'HTML_ENGINE'
|
||||
</script>
|
||||
<script>
|
||||
HTML_ENGINE
|
||||
script_for_inline "$MARKED" >> "$output_tmp"
|
||||
printf '\n' >> "$output_tmp"
|
||||
script_for_inline "$PURIFY" >> "$output_tmp"
|
||||
printf '\n' >> "$output_tmp"
|
||||
script_for_inline "$ENGINE" >> "$output_tmp"
|
||||
cat >> "$output_tmp" <<'HTML_BOOT'
|
||||
</script>
|
||||
<script>
|
||||
(function () {
|
||||
var root = document.getElementById("graph-root");
|
||||
var toolbarHost = document.querySelector("[data-testid='offline-toolbar-host']");
|
||||
var dataEl = document.getElementById("graph-data");
|
||||
var warningDataEl = document.getElementById("graph-warning-data");
|
||||
var layoutEl = document.getElementById("graph-layout");
|
||||
var storageAvailable = true;
|
||||
function showError(message) {
|
||||
if (!root) return;
|
||||
root.innerHTML = "";
|
||||
if (toolbarHost) toolbarHost.innerHTML = "";
|
||||
var storageWarning = document.querySelector(".offline-storage-warning");
|
||||
if (storageWarning) storageWarning.remove();
|
||||
try {
|
||||
if (window.__LLM_WIKI_GRAPH_ENGINE__) window.__LLM_WIKI_GRAPH_ENGINE__.destroy();
|
||||
} catch (_) {}
|
||||
window.__LLM_WIKI_GRAPH_ENGINE__ = undefined;
|
||||
var box = document.createElement("div");
|
||||
box.className = "offline-error";
|
||||
box.textContent = message;
|
||||
root.appendChild(box);
|
||||
}
|
||||
function showStorageRecoveryHint() {
|
||||
if (document.querySelector(".offline-storage-warning")) return;
|
||||
var main = document.querySelector(".offline-main");
|
||||
if (!main || !root) return;
|
||||
var box = document.createElement("div");
|
||||
box.className = "offline-error offline-storage-warning";
|
||||
box.setAttribute("role", "status");
|
||||
box.textContent = "浏览器存储不可用。图谱仍可浏览,但刷新后主题与固定位置会恢复默认。";
|
||||
main.insertBefore(box, root);
|
||||
}
|
||||
function parseJson(el, fallback) {
|
||||
try { return el && el.textContent ? JSON.parse(el.textContent) : fallback; }
|
||||
catch (err) { return fallback; }
|
||||
}
|
||||
function safeRelativePath(value) {
|
||||
var text = String(value == null ? "" : value);
|
||||
if (!text || text.charAt(0) === "/" || text.indexOf("\\") >= 0 || text === ".." || text.indexOf("../") === 0 || text.indexOf("/../") >= 0) {
|
||||
return "(路径不可用)";
|
||||
}
|
||||
return text;
|
||||
}
|
||||
function appendTextList(parent, values) {
|
||||
if (!values.length) return;
|
||||
var list = document.createElement("ul");
|
||||
for (var i = 0; i < values.length; i++) {
|
||||
var item = document.createElement("li");
|
||||
item.textContent = values[i];
|
||||
list.appendChild(item);
|
||||
}
|
||||
parent.appendChild(list);
|
||||
}
|
||||
function renderWarnings(payload, modelWarnings) {
|
||||
var banner = document.querySelector("[data-testid='offline-warning-banner']");
|
||||
var summaryBox = document.querySelector("[data-testid='offline-warning-summary']");
|
||||
var unavailable = document.querySelector("[data-testid='offline-warning-unavailable']");
|
||||
var truncated = document.querySelector("[data-testid='offline-warning-truncated']");
|
||||
var details = document.querySelector("[data-testid='offline-warning-details']");
|
||||
var groupsBox = document.querySelector("[data-testid='offline-warning-groups']");
|
||||
if (!banner || !summaryBox || !payload) return;
|
||||
var summary = payload.summary || {};
|
||||
var warningById = {};
|
||||
for (var warningIndex = 0; warningIndex < (modelWarnings || []).length; warningIndex++) {
|
||||
var warning = modelWarnings[warningIndex];
|
||||
if (warning && warning.warning_id && !warningById[warning.warning_id]) warningById[warning.warning_id] = warning;
|
||||
}
|
||||
var warnings = Object.keys(warningById).sort().map(function (warningId) { return warningById[warningId]; });
|
||||
var hasWarningSummary = typeof summary.total_groups === "number"
|
||||
|| typeof summary.total_occurrences === "number";
|
||||
if (!hasWarningSummary && warnings.length === 0) return;
|
||||
if (!hasWarningSummary) {
|
||||
summary = { total_groups: warnings.length, total_occurrences: 0, error_occurrences: 0, warning_occurrences: 0, by_code: {} };
|
||||
for (var summaryIndex = 0; summaryIndex < warnings.length; summaryIndex++) {
|
||||
var summaryWarning = warnings[summaryIndex];
|
||||
var count = Number(summaryWarning.occurrence_count || 0);
|
||||
summary.total_occurrences += count;
|
||||
if (summaryWarning.severity === "error") summary.error_occurrences += count;
|
||||
else summary.warning_occurrences += count;
|
||||
summary.by_code[summaryWarning.code] = (summary.by_code[summaryWarning.code] || 0) + count;
|
||||
}
|
||||
}
|
||||
var codes = Object.keys(summary.by_code || {}).sort().map(function (code) {
|
||||
return code + ": " + summary.by_code[code];
|
||||
});
|
||||
summaryBox.textContent = "图谱告警 " + (summary.total_groups || 0) + " 组 · "
|
||||
+ (summary.total_occurrences || 0) + " 处 · 错误 " + (summary.error_occurrences || 0)
|
||||
+ " · 提示 " + (summary.warning_occurrences || 0)
|
||||
+ (codes.length ? " · " + codes.join(" · ") : "");
|
||||
banner.hidden = false;
|
||||
|
||||
if (payload.details_status !== "available") {
|
||||
if (unavailable) {
|
||||
unavailable.hidden = false;
|
||||
unavailable.textContent = "告警详情暂不可用,请重新构建图谱";
|
||||
}
|
||||
}
|
||||
if (payload.warning_details_truncated && truncated) {
|
||||
truncated.hidden = false;
|
||||
truncated.textContent = "详情过大,已精简;运行 check 查看完整报告"
|
||||
+ "(省略 " + (payload.omitted_group_count || 0) + " 组、"
|
||||
+ (payload.omitted_candidate_set_count || 0) + " 个候选集合)";
|
||||
}
|
||||
|
||||
var bundle = payload.bundle || { candidate_sets: [], groups: [] };
|
||||
var candidateSets = {};
|
||||
for (var setIndex = 0; setIndex < (bundle.candidate_sets || []).length; setIndex++) {
|
||||
var candidateSet = bundle.candidate_sets[setIndex];
|
||||
candidateSets[candidateSet.candidate_set_id] = candidateSet;
|
||||
}
|
||||
if (groupsBox) groupsBox.innerHTML = "";
|
||||
for (var groupIndex = 0; groupsBox && groupIndex < warnings.length; groupIndex++) {
|
||||
var group = warnings[groupIndex];
|
||||
var groupBox = document.createElement("section");
|
||||
groupBox.className = "offline-warning-group";
|
||||
groupBox.setAttribute("data-warning-id", group.warning_id);
|
||||
var title = document.createElement("h3");
|
||||
title.textContent = group.code + " · " + group.occurrence_count + " 处";
|
||||
groupBox.appendChild(title);
|
||||
if (group.message) {
|
||||
var message = document.createElement("div");
|
||||
message.textContent = group.message;
|
||||
groupBox.appendChild(message);
|
||||
}
|
||||
var set = candidateSets[group.candidate_set_id];
|
||||
appendTextList(groupBox, set ? (set.candidates || []).map(safeRelativePath) : []);
|
||||
appendTextList(groupBox, (group.occurrences || []).map(function (occurrence) {
|
||||
return safeRelativePath(occurrence.source_path) + ":" + occurrence.line + ":" + occurrence.column + " " + occurrence.raw_link;
|
||||
}));
|
||||
groupsBox.appendChild(groupBox);
|
||||
}
|
||||
if (details) details.hidden = warnings.length === 0;
|
||||
}
|
||||
function normalizeStorageSegment(value) {
|
||||
return String(value == null ? "" : value).trim().toLowerCase()
|
||||
.replace(/[^a-z0-9一-鿿]+/g, "-")
|
||||
.replace(/^-+|-+$/g, "")
|
||||
.slice(0, 48);
|
||||
}
|
||||
function hashString(value) {
|
||||
var input = String(value == null ? "" : value);
|
||||
var hash = 0;
|
||||
for (var i = 0; i < input.length; i++) {
|
||||
hash = ((hash << 5) - hash + input.charCodeAt(i)) >>> 0;
|
||||
}
|
||||
return hash.toString(36);
|
||||
}
|
||||
function storageNamespace(meta, pathname) {
|
||||
var title = normalizeStorageSegment(meta && meta.wiki_title ? meta.wiki_title : "");
|
||||
var basis = typeof pathname === "string" && pathname ? pathname : (meta && meta.wiki_title) || title || "default";
|
||||
return "llm-wiki:" + (title || "default") + ":" + hashString(basis);
|
||||
}
|
||||
function readStoredPins(key) {
|
||||
try {
|
||||
var raw = window.localStorage && window.localStorage.getItem(key);
|
||||
var parsed = raw ? JSON.parse(raw) : null;
|
||||
return parsed && typeof parsed === "object" ? parsed : {};
|
||||
} catch (_) {
|
||||
storageAvailable = false;
|
||||
return {};
|
||||
}
|
||||
}
|
||||
function writeStoredPins(key, pins) {
|
||||
try {
|
||||
if (window.localStorage) window.localStorage.setItem(key, JSON.stringify(pins || {}));
|
||||
} catch (_) {
|
||||
storageAvailable = false;
|
||||
showStorageRecoveryHint();
|
||||
}
|
||||
}
|
||||
function normalizeBakedPins(layout) {
|
||||
return window.LlmWikiGraphEngine.normalizeGraphLayoutFile(layout).pins;
|
||||
}
|
||||
function normalizeStoredPins(rawPins) {
|
||||
return window.LlmWikiGraphEngine.normalizeGraphPinMap(rawPins);
|
||||
}
|
||||
if (!root || !dataEl || !window.LlmWikiGraphEngine || !window.LlmWikiGraphEngine.createGraphEngine || !window.LlmWikiGraphEngine.projectGraphInput) {
|
||||
showError("图谱引擎加载失败。请确认 HTML 文件完整生成。");
|
||||
return;
|
||||
}
|
||||
var graphData = parseJson(dataEl, null);
|
||||
if (!graphData || !Array.isArray(graphData.nodes) || !Array.isArray(graphData.edges)) {
|
||||
showError("图谱数据格式不完整。请重新运行 build-graph-data.sh 与 build-graph-html.sh。");
|
||||
return;
|
||||
}
|
||||
var warningPayload = parseJson(warningDataEl, { details_status: "unavailable", summary: {} });
|
||||
var inputWarningGroups = warningPayload.details_status === "available" && warningPayload.bundle
|
||||
? (warningPayload.bundle.groups || [])
|
||||
: [];
|
||||
var projection = window.LlmWikiGraphEngine.projectGraphInput(graphData, inputWarningGroups);
|
||||
graphData = projection.data;
|
||||
renderWarnings(warningPayload, projection.warnings || []);
|
||||
var bakedLayout = parseJson(layoutEl, { pins: {} });
|
||||
var key = storageNamespace(graphData.meta || {}, window.location && window.location.pathname) + ":graph-pins";
|
||||
var themeKey = storageNamespace(graphData.meta || {}, window.location && window.location.pathname) + ":graph-theme";
|
||||
var pins = Object.assign({}, normalizeBakedPins(bakedLayout), normalizeStoredPins(readStoredPins(key)));
|
||||
var themeToggle = document.querySelector("[data-testid='offline-theme-toggle']");
|
||||
function readStoredTheme() {
|
||||
try {
|
||||
var value = window.localStorage && window.localStorage.getItem(themeKey);
|
||||
return value === "mo-ye" ? "mo-ye" : "shan-shui";
|
||||
} catch (_) {
|
||||
storageAvailable = false;
|
||||
return "shan-shui";
|
||||
}
|
||||
}
|
||||
function writeStoredTheme(theme) {
|
||||
try {
|
||||
if (window.localStorage) window.localStorage.setItem(themeKey, theme);
|
||||
} catch (_) {
|
||||
storageAvailable = false;
|
||||
showStorageRecoveryHint();
|
||||
}
|
||||
}
|
||||
function syncThemeToggle(theme) {
|
||||
if (!themeToggle) return;
|
||||
var next = theme === "mo-ye" ? "shan-shui" : "mo-ye";
|
||||
themeToggle.textContent = theme === "mo-ye" ? "山水" : "墨夜";
|
||||
themeToggle.setAttribute("aria-label", next === "mo-ye" ? "切换墨夜主题" : "切换山水主题");
|
||||
}
|
||||
var currentTheme = readStoredTheme();
|
||||
var engine = null;
|
||||
try {
|
||||
engine = window.LlmWikiGraphEngine.createGraphEngine(root, {
|
||||
data: graphData,
|
||||
pins: pins,
|
||||
theme: currentTheme,
|
||||
toolbarContainer: toolbarHost,
|
||||
capabilities: window.LlmWikiGraphEngine.createGraphOfflineCapabilities({
|
||||
persistPins: function (nextPins) {
|
||||
writeStoredPins(key, nextPins || {});
|
||||
return Promise.resolve();
|
||||
}
|
||||
}).capabilities
|
||||
});
|
||||
syncThemeToggle(currentTheme);
|
||||
if (themeToggle) {
|
||||
themeToggle.addEventListener("click", function () {
|
||||
currentTheme = currentTheme === "mo-ye" ? "shan-shui" : "mo-ye";
|
||||
engine.setTheme(currentTheme);
|
||||
writeStoredTheme(currentTheme);
|
||||
syncThemeToggle(currentTheme);
|
||||
});
|
||||
}
|
||||
window.__LLM_WIKI_GRAPH_ENGINE__ = engine;
|
||||
window.__LLM_WIKI_GRAPH_PINS_KEY__ = key;
|
||||
window.__LLM_WIKI_GRAPH_THEME_KEY__ = themeKey;
|
||||
if (!storageAvailable) showStorageRecoveryHint();
|
||||
} catch (_) {
|
||||
try { if (engine) engine.destroy(); } catch (_) {}
|
||||
showError("图谱引擎加载失败。请确认 HTML 文件完整生成。");
|
||||
return;
|
||||
}
|
||||
})();
|
||||
</script>
|
||||
</body>
|
||||
</html>
|
||||
HTML_BOOT
|
||||
|
||||
mv "$output_tmp" "$output_next"
|
||||
mv "$output_next" "$OUTPUT"
|
||||
|
||||
rm -f \
|
||||
"$output_dir/d3.min.js" \
|
||||
"$output_dir/rough.min.js" \
|
||||
"$output_dir/marked.min.js" \
|
||||
"$output_dir/purify.min.js" \
|
||||
"$output_dir/graph-wash.js" \
|
||||
"$output_dir/graph-wash-helpers.js" \
|
||||
"$output_dir/LICENSE-d3.txt" \
|
||||
"$output_dir/LICENSE-roughjs.txt" \
|
||||
"$output_dir/LICENSE-marked.txt" \
|
||||
"$output_dir/LICENSE-purify.txt"
|
||||
|
||||
output_size=$(wc -c < "$OUTPUT" | tr -d ' ')
|
||||
output_kb=$((output_size / 1024))
|
||||
|
||||
echo "交互式图谱已生成:"
|
||||
echo " - $OUTPUT (${output_kb} KB)"
|
||||
echo " 节点 $NODE_COUNT · 关联 $EDGE_COUNT"
|
||||
echo ""
|
||||
echo "查看方式:"
|
||||
echo " 双击 $OUTPUT"
|
||||
352
llm-wiki/scripts/cache.sh
Executable file
352
llm-wiki/scripts/cache.sh
Executable file
@@ -0,0 +1,352 @@
|
||||
#!/bin/bash
|
||||
# llm-wiki 缓存脚本
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/cache.sh check <file>
|
||||
bash scripts/cache.sh update <file> <source_page>
|
||||
bash scripts/cache.sh invalidate <file>
|
||||
EOF
|
||||
}
|
||||
|
||||
require_file() {
|
||||
local file_path="$1"
|
||||
|
||||
[ -n "$file_path" ] || {
|
||||
usage
|
||||
exit 1
|
||||
}
|
||||
|
||||
[ -f "$file_path" ] || {
|
||||
echo "文件不存在:$file_path" >&2
|
||||
exit 1
|
||||
}
|
||||
}
|
||||
|
||||
find_wiki_root() {
|
||||
local file_path="$1"
|
||||
local dir parent
|
||||
|
||||
dir="$(cd "$(dirname "$file_path")" && pwd)"
|
||||
|
||||
while true; do
|
||||
if [ -f "$dir/.wiki-cache.json" ] || [ -f "$dir/.wiki-schema.md" ]; then
|
||||
printf '%s\n' "$dir"
|
||||
return 0
|
||||
fi
|
||||
|
||||
parent="$(dirname "$dir")"
|
||||
[ "$parent" = "$dir" ] && return 1
|
||||
dir="$parent"
|
||||
done
|
||||
}
|
||||
|
||||
cache_file_path() {
|
||||
printf '%s/.wiki-cache.json\n' "$1"
|
||||
}
|
||||
|
||||
ensure_cache_file() {
|
||||
local cache_file="$1"
|
||||
|
||||
if [ ! -f "$cache_file" ]; then
|
||||
cat > "$cache_file" <<'EOF'
|
||||
{
|
||||
"version": 1,
|
||||
"entries": {}
|
||||
}
|
||||
EOF
|
||||
fi
|
||||
}
|
||||
|
||||
relative_path() {
|
||||
require_python_cmd
|
||||
|
||||
"$PYTHON_CMD" - "$1" "$2" <<'PY'
|
||||
import os
|
||||
import sys
|
||||
|
||||
print(os.path.relpath(os.path.realpath(sys.argv[2]), os.path.realpath(sys.argv[1])))
|
||||
PY
|
||||
}
|
||||
|
||||
normalized_source_page() {
|
||||
local wiki_root="$1"
|
||||
local source_page="$2"
|
||||
|
||||
if [ -z "$source_page" ]; then
|
||||
printf '%s\n' ""
|
||||
return 0
|
||||
fi
|
||||
|
||||
case "$source_page" in
|
||||
/*)
|
||||
require_python_cmd
|
||||
|
||||
"$PYTHON_CMD" - "$wiki_root" "$source_page" <<'PY'
|
||||
import os
|
||||
import sys
|
||||
|
||||
wiki_root = os.path.realpath(sys.argv[1])
|
||||
source_page = os.path.realpath(sys.argv[2])
|
||||
|
||||
try:
|
||||
common = os.path.commonpath([wiki_root, source_page])
|
||||
except ValueError:
|
||||
common = ""
|
||||
|
||||
if common == wiki_root:
|
||||
print(os.path.relpath(source_page, wiki_root))
|
||||
else:
|
||||
print(sys.argv[2])
|
||||
PY
|
||||
;;
|
||||
*)
|
||||
printf '%s\n' "$source_page"
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
file_hash() {
|
||||
require_python_cmd
|
||||
|
||||
"$PYTHON_CMD" - "$1" "$2" <<'PY'
|
||||
import hashlib
|
||||
import pathlib
|
||||
import sys
|
||||
|
||||
relative_path = sys.argv[1].encode("utf-8")
|
||||
file_path = pathlib.Path(sys.argv[2])
|
||||
content = file_path.read_bytes()
|
||||
|
||||
digest = hashlib.sha256(relative_path + b"\0" + content).hexdigest()
|
||||
print(f"sha256:{digest}")
|
||||
PY
|
||||
}
|
||||
|
||||
cache_check() {
|
||||
local file_path="$1"
|
||||
local wiki_root cache_file relative_path_value current_hash result
|
||||
|
||||
require_file "$file_path"
|
||||
wiki_root="$(find_wiki_root "$file_path")" || {
|
||||
echo "未找到知识库根目录:$file_path" >&2
|
||||
exit 1
|
||||
}
|
||||
cache_file="$(cache_file_path "$wiki_root")"
|
||||
|
||||
if [ ! -f "$cache_file" ]; then
|
||||
printf 'MISS\n'
|
||||
return 0
|
||||
fi
|
||||
|
||||
require_python_cmd
|
||||
|
||||
relative_path_value="$(relative_path "$wiki_root" "$file_path")"
|
||||
current_hash="$(file_hash "$relative_path_value" "$file_path")"
|
||||
|
||||
result="$(
|
||||
"$PYTHON_CMD" - "$cache_file" "$wiki_root" "$relative_path_value" "$current_hash" <<'PY'
|
||||
import hashlib
|
||||
import json
|
||||
import os
|
||||
import pathlib
|
||||
import sys
|
||||
|
||||
cache_file, wiki_root, relative_path, current_hash = sys.argv[1:5]
|
||||
|
||||
with open(cache_file, "r", encoding="utf-8") as fh:
|
||||
data = json.load(fh)
|
||||
|
||||
entry = data.get("entries", {}).get(relative_path)
|
||||
|
||||
# 无 cache entry → 尝试自愈(exact filename stem match + source_path 验证)
|
||||
if not entry:
|
||||
raw_stem = pathlib.Path(relative_path).stem
|
||||
sources_dir = os.path.join(wiki_root, "wiki", "sources")
|
||||
if os.path.isdir(sources_dir):
|
||||
for f in os.listdir(sources_dir):
|
||||
if pathlib.Path(f).stem == raw_stem and f.endswith(".md"):
|
||||
source_page = os.path.join("wiki", "sources", f)
|
||||
source_abs = os.path.join(wiki_root, source_page)
|
||||
# 验证 source 页面的 source_path frontmatter 是否指向当前 raw 文件
|
||||
source_path_match = False
|
||||
try:
|
||||
with open(source_abs, "r", encoding="utf-8") as sf:
|
||||
in_frontmatter = False
|
||||
for line in sf:
|
||||
stripped = line.strip()
|
||||
if stripped == "---":
|
||||
if in_frontmatter:
|
||||
break # end of frontmatter
|
||||
in_frontmatter = True
|
||||
continue
|
||||
if in_frontmatter and stripped.startswith("source_path:"):
|
||||
fm_value = stripped.split(":", 1)[1].strip()
|
||||
# 匹配相对路径的末尾部分
|
||||
if relative_path.endswith(fm_value) or fm_value.endswith(relative_path) or fm_value == relative_path:
|
||||
source_path_match = True
|
||||
break
|
||||
except (OSError, UnicodeDecodeError):
|
||||
pass
|
||||
if not source_path_match:
|
||||
# stem 匹配但 source_path 不一致 → 不信任,需要验证
|
||||
print("MISS:repaired_needs_verify")
|
||||
raise SystemExit(0)
|
||||
# stem + source_path 都匹配 → 安全自愈
|
||||
timestamp = __import__("datetime").datetime.now(__import__("datetime").timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
|
||||
entries = data.setdefault("entries", {})
|
||||
entries[relative_path] = {
|
||||
"hash": current_hash,
|
||||
"ingested_at": timestamp,
|
||||
"source_page": source_page,
|
||||
}
|
||||
tmp_file = cache_file + ".tmp"
|
||||
with open(tmp_file, "w", encoding="utf-8") as fh2:
|
||||
json.dump(data, fh2, ensure_ascii=False, indent=2)
|
||||
fh2.write("\n")
|
||||
os.replace(tmp_file, cache_file)
|
||||
print("HIT(repaired)")
|
||||
raise SystemExit(0)
|
||||
print("MISS:no_entry")
|
||||
raise SystemExit(0)
|
||||
|
||||
if entry.get("hash") != current_hash:
|
||||
print("MISS:hash_changed")
|
||||
raise SystemExit(0)
|
||||
|
||||
source_page = entry.get("source_page")
|
||||
if not source_page:
|
||||
print("MISS:no_entry")
|
||||
raise SystemExit(0)
|
||||
|
||||
source_path = source_page
|
||||
if not os.path.isabs(source_path):
|
||||
source_path = os.path.join(wiki_root, source_path)
|
||||
|
||||
if not os.path.isfile(source_path):
|
||||
print("MISS:no_source")
|
||||
else:
|
||||
print("HIT")
|
||||
PY
|
||||
)"
|
||||
|
||||
printf '%s\n' "$result"
|
||||
}
|
||||
|
||||
cache_update() {
|
||||
local file_path="$1"
|
||||
local source_page="$2"
|
||||
local wiki_root cache_file relative_path_value current_hash normalized_source timestamp
|
||||
|
||||
require_file "$file_path"
|
||||
wiki_root="$(find_wiki_root "$file_path")" || {
|
||||
echo "未找到知识库根目录:$file_path" >&2
|
||||
exit 1
|
||||
}
|
||||
cache_file="$(cache_file_path "$wiki_root")"
|
||||
ensure_cache_file "$cache_file"
|
||||
|
||||
require_python_cmd
|
||||
|
||||
relative_path_value="$(relative_path "$wiki_root" "$file_path")"
|
||||
current_hash="$(file_hash "$relative_path_value" "$file_path")"
|
||||
normalized_source="$(normalized_source_page "$wiki_root" "$source_page")"
|
||||
timestamp="$(date -u +"%Y-%m-%dT%H:%M:%SZ")"
|
||||
|
||||
"$PYTHON_CMD" - "$cache_file" "$relative_path_value" "$current_hash" "$timestamp" "$normalized_source" <<'PY'
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
|
||||
cache_file, relative_path, file_hash_value, timestamp, source_page = sys.argv[1:6]
|
||||
|
||||
with open(cache_file, "r", encoding="utf-8") as fh:
|
||||
data = json.load(fh)
|
||||
|
||||
entries = data.setdefault("entries", {})
|
||||
entries[relative_path] = {
|
||||
"hash": file_hash_value,
|
||||
"ingested_at": timestamp,
|
||||
"source_page": source_page,
|
||||
}
|
||||
|
||||
tmp_file = cache_file + ".tmp"
|
||||
with open(tmp_file, "w", encoding="utf-8") as fh:
|
||||
json.dump(data, fh, ensure_ascii=False, indent=2)
|
||||
fh.write("\n")
|
||||
os.replace(tmp_file, cache_file)
|
||||
PY
|
||||
|
||||
printf 'UPDATED\n'
|
||||
}
|
||||
|
||||
cache_invalidate() {
|
||||
local file_path="$1"
|
||||
local wiki_root cache_file relative_path_value
|
||||
|
||||
# 不调用 require_file:文件可能已被删除(级联删除场景)
|
||||
# 直接通过路径查找缓存条目
|
||||
wiki_root="$(find_wiki_root "$file_path")" || {
|
||||
echo "未找到知识库根目录:$file_path" >&2
|
||||
exit 1
|
||||
}
|
||||
cache_file="$(cache_file_path "$wiki_root")"
|
||||
|
||||
if [ ! -f "$cache_file" ]; then
|
||||
printf 'INVALIDATED\n'
|
||||
return 0
|
||||
fi
|
||||
|
||||
require_python_cmd
|
||||
|
||||
relative_path_value="$(relative_path "$wiki_root" "$file_path")"
|
||||
|
||||
"$PYTHON_CMD" - "$cache_file" "$relative_path_value" <<'PY'
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
|
||||
cache_file, relative_path = sys.argv[1:3]
|
||||
|
||||
with open(cache_file, "r", encoding="utf-8") as fh:
|
||||
data = json.load(fh)
|
||||
|
||||
data.setdefault("entries", {}).pop(relative_path, None)
|
||||
|
||||
tmp_file = cache_file + ".tmp"
|
||||
with open(tmp_file, "w", encoding="utf-8") as fh:
|
||||
json.dump(data, fh, ensure_ascii=False, indent=2)
|
||||
fh.write("\n")
|
||||
os.replace(tmp_file, cache_file)
|
||||
PY
|
||||
|
||||
printf 'INVALIDATED\n'
|
||||
}
|
||||
|
||||
command_name="${1:-}"
|
||||
|
||||
case "$command_name" in
|
||||
check)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
cache_check "$2"
|
||||
;;
|
||||
update)
|
||||
[ "$#" -eq 3 ] || { usage; exit 1; }
|
||||
cache_update "$2" "$3"
|
||||
;;
|
||||
invalidate)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
cache_invalidate "$2"
|
||||
;;
|
||||
*)
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
100
llm-wiki/scripts/create-source-page.sh
Executable file
100
llm-wiki/scripts/create-source-page.sh
Executable file
@@ -0,0 +1,100 @@
|
||||
#!/bin/bash
|
||||
# llm-wiki source 页面写入脚本
|
||||
# 原子写入 source 页面 + 自动更新缓存,绑定为一项操作
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/create-source-page.sh <raw_file> <output_path> <content_file>
|
||||
|
||||
参数:
|
||||
raw_file : 原始素材文件路径(绝对或相对路径)
|
||||
output_path : 目标页面路径(相对于知识库根目录,如 wiki/sources/2026-04-16-rlhf.md)
|
||||
content_file : 包含待写入内容的临时文件路径
|
||||
EOF
|
||||
}
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
|
||||
# 参数校验
|
||||
if [ "$#" -ne 3 ]; then
|
||||
usage
|
||||
exit 1
|
||||
fi
|
||||
|
||||
raw_file="$1"
|
||||
output_path="$2"
|
||||
content_file="$3"
|
||||
|
||||
# raw_file 和 content_file 必须存在
|
||||
if [ ! -f "$raw_file" ]; then
|
||||
echo "ERROR: 原始素材文件不存在:$raw_file" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ ! -f "$content_file" ]; then
|
||||
echo "ERROR: 内容文件不存在:$content_file" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# 通过 cache.sh 的 find_wiki_root 逻辑找到知识库根目录
|
||||
# 复用 cache.sh 里的函数
|
||||
source_cache_helpers() {
|
||||
# 内联 find_wiki_root(与 cache.sh 保持一致)
|
||||
find_wiki_root() {
|
||||
local file_path="$1"
|
||||
local dir parent
|
||||
|
||||
dir="$(cd "$(dirname "$file_path")" && pwd)"
|
||||
|
||||
while true; do
|
||||
if [ -f "$dir/.wiki-cache.json" ] || [ -f "$dir/.wiki-schema.md" ]; then
|
||||
printf '%s\n' "$dir"
|
||||
return 0
|
||||
fi
|
||||
|
||||
parent="$(dirname "$dir")"
|
||||
[ "$parent" = "$dir" ] && return 1
|
||||
dir="$parent"
|
||||
done
|
||||
}
|
||||
}
|
||||
|
||||
source_cache_helpers
|
||||
|
||||
wiki_root="$(find_wiki_root "$raw_file")" || {
|
||||
echo "ERROR: 未找到知识库根目录:$raw_file" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
# 拼接完整目标路径
|
||||
full_output="$wiki_root/$output_path"
|
||||
|
||||
# 确保目标目录存在
|
||||
mkdir -p "$(dirname "$full_output")"
|
||||
|
||||
# 第一步:原子写入(临时文件 + rename,防止写一半崩溃)
|
||||
tmp_output="${full_output}.tmp.$$"
|
||||
if ! cp "$content_file" "$tmp_output"; then
|
||||
rm -f "$tmp_output" 2>/dev/null || true
|
||||
echo "ERROR: 写入临时文件失败" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if ! mv "$tmp_output" "$full_output"; then
|
||||
rm -f "$tmp_output" 2>/dev/null || true
|
||||
echo "ERROR: 原子重命名失败" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# 第二步:更新缓存
|
||||
if ! bash "$SCRIPT_DIR/cache.sh" update "$raw_file" "$output_path"; then
|
||||
# 缓存更新失败 → 回滚:删除已写入的文件
|
||||
rm -f "$full_output"
|
||||
echo "ERROR: 缓存更新失败,已回滚写入" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
echo "SUCCESS"
|
||||
68
llm-wiki/scripts/delete-helper.sh
Executable file
68
llm-wiki/scripts/delete-helper.sh
Executable file
@@ -0,0 +1,68 @@
|
||||
#!/bin/bash
|
||||
# llm-wiki 删除辅助脚本
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/delete-helper.sh scan-refs <wiki_root> <素材文件名>
|
||||
EOF
|
||||
}
|
||||
|
||||
scan_refs() {
|
||||
local wiki_root="$1"
|
||||
local needle="$2"
|
||||
local wiki_dir="$wiki_root/wiki"
|
||||
|
||||
[ -n "$needle" ] || {
|
||||
echo "素材文件名不能为空" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
[ -d "$wiki_dir" ] || {
|
||||
echo "知识库目录不存在:$wiki_dir" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
require_python_cmd
|
||||
|
||||
{
|
||||
grep -rlF --include='*.md' -- "$needle" "$wiki_dir" 2>/dev/null || true
|
||||
} | "$PYTHON_CMD" -c '
|
||||
import os
|
||||
import sys
|
||||
|
||||
wiki_root = os.path.realpath(sys.argv[1])
|
||||
seen = []
|
||||
|
||||
for line in sys.stdin:
|
||||
path = line.strip()
|
||||
if not path:
|
||||
continue
|
||||
real_path = os.path.realpath(path)
|
||||
if real_path in seen:
|
||||
continue
|
||||
seen.append(real_path)
|
||||
|
||||
for path in sorted(seen):
|
||||
print(os.path.relpath(path, wiki_root))
|
||||
' "$wiki_root"
|
||||
}
|
||||
|
||||
command_name="${1:-}"
|
||||
|
||||
case "$command_name" in
|
||||
scan-refs)
|
||||
[ "$#" -eq 3 ] || { usage; exit 1; }
|
||||
scan_refs "$2" "$3"
|
||||
;;
|
||||
*)
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
737
llm-wiki/scripts/graph-analysis.js
Normal file
737
llm-wiki/scripts/graph-analysis.js
Normal file
@@ -0,0 +1,737 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const fs = require("fs");
|
||||
const path = require("path");
|
||||
const { extractFrontmatter, parseSourcesFrontmatter, sortedUnique } = require("./lib/source-signal-eligibility");
|
||||
|
||||
function readJson(filePath) {
|
||||
return JSON.parse(fs.readFileSync(filePath, "utf8"));
|
||||
}
|
||||
|
||||
function writeJson(filePath, value) {
|
||||
fs.writeFileSync(filePath, `${JSON.stringify(value, null, 2)}\n`, "utf8");
|
||||
}
|
||||
|
||||
function roundNumber(value, digits = 3) {
|
||||
const factor = 10 ** digits;
|
||||
return Math.round(value * factor) / factor;
|
||||
}
|
||||
|
||||
function clamp01(value) {
|
||||
return Math.max(0, Math.min(1, value));
|
||||
}
|
||||
|
||||
function sortedPairKey(a, b) {
|
||||
return a < b ? `${a}\t${b}` : `${b}\t${a}`;
|
||||
}
|
||||
|
||||
function normalizeBody(text, degraded, maxLines) {
|
||||
const { body } = extractFrontmatter(text);
|
||||
const normalized = body.replace(/^\s+/, "").replace(/\s+$/, "");
|
||||
if (!degraded) return normalized;
|
||||
return normalized.split(/\r?\n/).slice(0, maxLines).join("\n").replace(/\s+$/, "");
|
||||
}
|
||||
|
||||
function loadNodeDetails(nodes, degraded, maxLines) {
|
||||
const byId = {};
|
||||
|
||||
for (const node of nodes) {
|
||||
const hasPreloadedContent = Object.prototype.hasOwnProperty.call(node, "_content");
|
||||
const raw = hasPreloadedContent
|
||||
? String(node._content == null ? "" : node._content)
|
||||
: fs.readFileSync(node._file_path || node.source_path, "utf8");
|
||||
const frontmatter = extractFrontmatter(raw);
|
||||
const parsedSources = parseSourcesFrontmatter(frontmatter.frontmatter);
|
||||
const preloadedSignals = node._signals && typeof node._signals === "object"
|
||||
? node._signals
|
||||
: null;
|
||||
const normalizedNode = {
|
||||
...node,
|
||||
content: normalizeBody(raw, degraded, maxLines),
|
||||
_signals: preloadedSignals || {
|
||||
sources: parsedSources.sources,
|
||||
sourceSignalAvailable: parsedSources.signalAvailable,
|
||||
sourceFieldPresent: parsedSources.hasField,
|
||||
sourceFieldParsed: parsedSources.parsed
|
||||
}
|
||||
};
|
||||
byId[node.id] = normalizedNode;
|
||||
}
|
||||
|
||||
return byId;
|
||||
}
|
||||
|
||||
function buildInlinks(edges) {
|
||||
const inlinks = new Map();
|
||||
|
||||
for (const edge of edges) {
|
||||
if (!inlinks.has(edge.to)) inlinks.set(edge.to, new Set());
|
||||
inlinks.get(edge.to).add(edge.from);
|
||||
}
|
||||
|
||||
return inlinks;
|
||||
}
|
||||
|
||||
function intersectionCount(setA, setB) {
|
||||
if (!setA || !setB) return 0;
|
||||
let small = setA;
|
||||
let large = setB;
|
||||
if (setB.size < setA.size) {
|
||||
small = setB;
|
||||
large = setA;
|
||||
}
|
||||
|
||||
let count = 0;
|
||||
for (const value of small) {
|
||||
if (large.has(value)) count += 1;
|
||||
}
|
||||
return count;
|
||||
}
|
||||
|
||||
function typeAffinity(typeA, typeB) {
|
||||
const pair = [typeA || "other", typeB || "other"].sort().join(":");
|
||||
switch (pair) {
|
||||
case "entity:entity":
|
||||
case "entity:topic":
|
||||
return 1;
|
||||
case "topic:topic":
|
||||
return 0.8;
|
||||
case "entity:source":
|
||||
return 0.6;
|
||||
case "source:source":
|
||||
return 0.3;
|
||||
default:
|
||||
return 0.5;
|
||||
}
|
||||
}
|
||||
|
||||
function computePairMetrics(nodesById, edges) {
|
||||
const inlinks = buildInlinks(edges);
|
||||
const pairMetrics = new Map();
|
||||
|
||||
for (const edge of edges) {
|
||||
const pairKey = sortedPairKey(edge.from, edge.to);
|
||||
if (pairMetrics.has(pairKey)) continue;
|
||||
|
||||
const fromNode = nodesById[edge.from];
|
||||
const toNode = nodesById[edge.to];
|
||||
if (!fromNode || !toNode) continue;
|
||||
|
||||
const fromInlinks = inlinks.get(edge.from) || new Set();
|
||||
const toInlinks = inlinks.get(edge.to) || new Set();
|
||||
const sharedInlinks = intersectionCount(fromInlinks, toInlinks);
|
||||
const coCitation = sharedInlinks / Math.max(fromInlinks.size, toInlinks.size, 1);
|
||||
const affinity = typeAffinity(fromNode.type, toNode.type);
|
||||
|
||||
const signals = [coCitation, affinity];
|
||||
let sourceOverlap = null;
|
||||
const sourceSignalAvailable = Boolean(
|
||||
fromNode._signals.sourceSignalAvailable && toNode._signals.sourceSignalAvailable
|
||||
);
|
||||
|
||||
if (sourceSignalAvailable) {
|
||||
const fromSources = new Set(fromNode._signals.sources);
|
||||
const toSources = new Set(toNode._signals.sources);
|
||||
const overlap = intersectionCount(fromSources, toSources);
|
||||
const minSize = Math.min(fromSources.size, toSources.size);
|
||||
sourceOverlap = minSize > 0 ? overlap / minSize : 0;
|
||||
signals.push(sourceOverlap);
|
||||
}
|
||||
|
||||
const weight = clamp01(signals.reduce((sum, value) => sum + value, 0) / signals.length);
|
||||
|
||||
pairMetrics.set(pairKey, {
|
||||
weight: roundNumber(weight),
|
||||
signals: {
|
||||
co_citation: roundNumber(coCitation),
|
||||
source_overlap: sourceOverlap == null ? null : roundNumber(sourceOverlap),
|
||||
type_affinity: roundNumber(affinity)
|
||||
},
|
||||
source_signal_available: sourceSignalAvailable
|
||||
});
|
||||
}
|
||||
|
||||
return pairMetrics;
|
||||
}
|
||||
|
||||
function buildUndirectedGraph(nodeIds, pairMetrics) {
|
||||
const adjacency = new Map();
|
||||
const degrees = new Map();
|
||||
|
||||
for (const nodeId of nodeIds) {
|
||||
adjacency.set(nodeId, new Map());
|
||||
degrees.set(nodeId, 0);
|
||||
}
|
||||
|
||||
for (const [pairKey, metrics] of pairMetrics.entries()) {
|
||||
const [left, right] = pairKey.split("\t");
|
||||
if (!adjacency.has(left) || !adjacency.has(right)) continue;
|
||||
const weight = metrics.weight;
|
||||
adjacency.get(left).set(right, weight);
|
||||
adjacency.get(right).set(left, weight);
|
||||
degrees.set(left, degrees.get(left) + weight);
|
||||
degrees.set(right, degrees.get(right) + weight);
|
||||
}
|
||||
|
||||
return { adjacency, degrees };
|
||||
}
|
||||
|
||||
function runLocalMove(graph) {
|
||||
const nodes = Array.from(graph.nodes.keys()).sort();
|
||||
const communities = new Map();
|
||||
const totals = new Map();
|
||||
let moved = false;
|
||||
|
||||
for (const nodeId of nodes) {
|
||||
communities.set(nodeId, nodeId);
|
||||
totals.set(nodeId, graph.degrees.get(nodeId) || 0);
|
||||
}
|
||||
|
||||
if (graph.m2 === 0) {
|
||||
return { communities, changed: false };
|
||||
}
|
||||
|
||||
let changedInPass = true;
|
||||
let passCount = 0;
|
||||
while (changedInPass && passCount < 50) {
|
||||
passCount++;
|
||||
changedInPass = false;
|
||||
|
||||
for (const nodeId of nodes) {
|
||||
const degree = graph.degrees.get(nodeId) || 0;
|
||||
const currentCommunity = communities.get(nodeId);
|
||||
const neighborCommunities = new Map();
|
||||
|
||||
for (const [neighborId, weight] of graph.nodes.get(nodeId).entries()) {
|
||||
const communityId = communities.get(neighborId);
|
||||
neighborCommunities.set(communityId, (neighborCommunities.get(communityId) || 0) + weight);
|
||||
}
|
||||
|
||||
totals.set(currentCommunity, (totals.get(currentCommunity) || 0) - degree);
|
||||
if ((neighborCommunities.get(currentCommunity) || 0) === 0) {
|
||||
neighborCommunities.set(currentCommunity, 0);
|
||||
}
|
||||
|
||||
let bestCommunity = currentCommunity;
|
||||
let bestGain = 0;
|
||||
|
||||
const candidates = Array.from(neighborCommunities.keys()).sort();
|
||||
for (const communityId of candidates) {
|
||||
const inWeight = neighborCommunities.get(communityId) || 0;
|
||||
const gain = inWeight - ((totals.get(communityId) || 0) * degree) / graph.m2;
|
||||
if (gain > bestGain + 1e-9) {
|
||||
bestGain = gain;
|
||||
bestCommunity = communityId;
|
||||
}
|
||||
}
|
||||
|
||||
communities.set(nodeId, bestCommunity);
|
||||
totals.set(bestCommunity, (totals.get(bestCommunity) || 0) + degree);
|
||||
|
||||
if (bestCommunity !== currentCommunity) {
|
||||
changedInPass = true;
|
||||
moved = true;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return { communities, changed: moved };
|
||||
}
|
||||
|
||||
function aggregateGraph(graph, communities) {
|
||||
const communityIds = sortedUnique(Array.from(communities.values()));
|
||||
const aggregatedNodes = new Map();
|
||||
const aggregatedDegrees = new Map();
|
||||
const members = new Map();
|
||||
|
||||
for (const communityId of communityIds) {
|
||||
aggregatedNodes.set(communityId, new Map());
|
||||
aggregatedDegrees.set(communityId, 0);
|
||||
members.set(communityId, []);
|
||||
}
|
||||
|
||||
for (const [nodeId, communityId] of communities.entries()) {
|
||||
members.get(communityId).push(...(graph.members.get(nodeId) || [nodeId]));
|
||||
}
|
||||
|
||||
for (const [nodeId, neighbors] of graph.nodes.entries()) {
|
||||
const sourceCommunity = communities.get(nodeId);
|
||||
for (const [neighborId, weight] of neighbors.entries()) {
|
||||
if (nodeId > neighborId) continue;
|
||||
const targetCommunity = communities.get(neighborId);
|
||||
const current = aggregatedNodes.get(sourceCommunity).get(targetCommunity) || 0;
|
||||
aggregatedNodes.get(sourceCommunity).set(targetCommunity, current + weight);
|
||||
if (sourceCommunity !== targetCommunity) {
|
||||
const mirrored = aggregatedNodes.get(targetCommunity).get(sourceCommunity) || 0;
|
||||
aggregatedNodes.get(targetCommunity).set(sourceCommunity, mirrored + weight);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (const [communityId, neighbors] of aggregatedNodes.entries()) {
|
||||
let degree = 0;
|
||||
for (const [neighborId, weight] of neighbors.entries()) {
|
||||
degree += neighborId === communityId ? weight * 2 : weight;
|
||||
}
|
||||
aggregatedDegrees.set(communityId, degree);
|
||||
}
|
||||
|
||||
return {
|
||||
nodes: aggregatedNodes,
|
||||
degrees: aggregatedDegrees,
|
||||
members,
|
||||
m2: Array.from(aggregatedDegrees.values()).reduce((sum, value) => sum + value, 0)
|
||||
};
|
||||
}
|
||||
|
||||
function runLouvain(nodeIds, pairMetrics) {
|
||||
const baseGraph = buildUndirectedGraph(nodeIds, pairMetrics);
|
||||
let graph = {
|
||||
nodes: baseGraph.adjacency,
|
||||
degrees: baseGraph.degrees,
|
||||
members: new Map(nodeIds.map((nodeId) => [nodeId, [nodeId]])),
|
||||
m2: Array.from(baseGraph.degrees.values()).reduce((sum, value) => sum + value, 0)
|
||||
};
|
||||
|
||||
let bestMembers = graph.members;
|
||||
|
||||
while (true) {
|
||||
const phase = runLocalMove(graph);
|
||||
const nextGraph = aggregateGraph(graph, phase.communities);
|
||||
bestMembers = nextGraph.members;
|
||||
|
||||
if (!phase.changed || nextGraph.nodes.size === graph.nodes.size) {
|
||||
break;
|
||||
}
|
||||
|
||||
graph = nextGraph;
|
||||
}
|
||||
|
||||
const finalCommunities = new Map();
|
||||
for (const [communityId, members] of bestMembers.entries()) {
|
||||
for (const nodeId of members) {
|
||||
finalCommunities.set(nodeId, communityId);
|
||||
}
|
||||
}
|
||||
|
||||
return finalCommunities;
|
||||
}
|
||||
|
||||
function buildDirectedDegree(edges) {
|
||||
const degree = new Map();
|
||||
for (const edge of edges) {
|
||||
degree.set(edge.from, (degree.get(edge.from) || 0) + 1);
|
||||
degree.set(edge.to, (degree.get(edge.to) || 0) + 1);
|
||||
}
|
||||
return degree;
|
||||
}
|
||||
|
||||
function chooseCommunityLabels(nodeIds, communityAssignments, nodesById, edges) {
|
||||
const groups = new Map();
|
||||
const degree = buildDirectedDegree(edges);
|
||||
|
||||
for (const nodeId of nodeIds) {
|
||||
const communityId = communityAssignments.get(nodeId) || nodeId;
|
||||
if (!groups.has(communityId)) groups.set(communityId, []);
|
||||
groups.get(communityId).push(nodeId);
|
||||
}
|
||||
|
||||
const labeledAssignments = new Map();
|
||||
|
||||
for (const members of groups.values()) {
|
||||
members.sort();
|
||||
if (members.length === 1) {
|
||||
labeledAssignments.set(members[0], null);
|
||||
continue;
|
||||
}
|
||||
|
||||
const memberNodes = members.map((memberId) => nodesById[memberId]);
|
||||
const topics = memberNodes.filter((node) => node && node.type === "topic");
|
||||
const candidates = topics.length ? topics : memberNodes;
|
||||
candidates.sort((left, right) => {
|
||||
const degreeDiff = (degree.get(right.id) || 0) - (degree.get(left.id) || 0);
|
||||
if (degreeDiff !== 0) return degreeDiff;
|
||||
return left.id.localeCompare(right.id);
|
||||
});
|
||||
|
||||
const label = candidates[0] ? candidates[0].id : members[0];
|
||||
for (const memberId of members) {
|
||||
labeledAssignments.set(memberId, label);
|
||||
}
|
||||
}
|
||||
|
||||
return labeledAssignments;
|
||||
}
|
||||
|
||||
function buildInsights(nodesById, edges, pairMetrics, communityAssignments, options) {
|
||||
const directedDegree = buildDirectedDegree(edges);
|
||||
const undirectedPairs = new Map();
|
||||
const adjacency = new Map();
|
||||
|
||||
for (const nodeId of Object.keys(nodesById)) {
|
||||
adjacency.set(nodeId, new Set());
|
||||
}
|
||||
|
||||
for (const edge of edges) {
|
||||
const pairKey = sortedPairKey(edge.from, edge.to);
|
||||
if (!undirectedPairs.has(pairKey)) {
|
||||
undirectedPairs.set(pairKey, {
|
||||
from: pairKey.split("\t")[0],
|
||||
to: pairKey.split("\t")[1],
|
||||
weight: pairMetrics.get(pairKey)?.weight || 0
|
||||
});
|
||||
}
|
||||
adjacency.get(edge.from)?.add(edge.to);
|
||||
adjacency.get(edge.to)?.add(edge.from);
|
||||
}
|
||||
|
||||
const isolatedNodes = Object.values(nodesById)
|
||||
.filter((node) => (directedDegree.get(node.id) || 0) <= 1)
|
||||
.sort((left, right) => left.id.localeCompare(right.id))
|
||||
.map((node) => ({
|
||||
id: node.id,
|
||||
label: node.label,
|
||||
degree: directedDegree.get(node.id) || 0,
|
||||
community: communityAssignments.get(node.id) || null
|
||||
}));
|
||||
|
||||
const bridgeNodes = [];
|
||||
for (const node of Object.values(nodesById).sort((left, right) => left.id.localeCompare(right.id))) {
|
||||
const ownCommunity = communityAssignments.get(node.id) || null;
|
||||
const connectedCommunities = sortedUnique(
|
||||
Array.from(adjacency.get(node.id) || [])
|
||||
.map((neighborId) => communityAssignments.get(neighborId) || null)
|
||||
.filter((c) => c && c !== ownCommunity)
|
||||
);
|
||||
|
||||
if (connectedCommunities.length >= 2) {
|
||||
bridgeNodes.push({
|
||||
id: node.id,
|
||||
label: node.label,
|
||||
community: ownCommunity,
|
||||
connected_communities: connectedCommunities,
|
||||
community_count: connectedCommunities.length
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
const communityMembers = new Map();
|
||||
for (const node of Object.values(nodesById)) {
|
||||
const communityId = communityAssignments.get(node.id) || null;
|
||||
if (!communityId) continue;
|
||||
if (!communityMembers.has(communityId)) communityMembers.set(communityId, []);
|
||||
communityMembers.get(communityId).push(node.id);
|
||||
}
|
||||
|
||||
const sparseCommunities = [];
|
||||
for (const [communityId, members] of Array.from(communityMembers.entries()).sort((left, right) => left[0].localeCompare(right[0]))) {
|
||||
if (members.length < 3) continue;
|
||||
|
||||
const memberSet = new Set(members);
|
||||
let internalEdges = 0;
|
||||
for (const pair of undirectedPairs.values()) {
|
||||
if (memberSet.has(pair.from) && memberSet.has(pair.to)) internalEdges += 1;
|
||||
}
|
||||
|
||||
const possibleEdges = (members.length * (members.length - 1)) / 2;
|
||||
const density = possibleEdges === 0 ? 0 : internalEdges / possibleEdges;
|
||||
if (density < 0.15) {
|
||||
sparseCommunities.push({
|
||||
id: communityId,
|
||||
label: nodesById[communityId]?.label || communityId,
|
||||
node_count: members.length,
|
||||
density: roundNumber(density),
|
||||
members: members.sort(),
|
||||
internal_edges: internalEdges
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
const surprisingConnections = Array.from(undirectedPairs.values())
|
||||
.filter((pair) => {
|
||||
const fromCommunity = communityAssignments.get(pair.from) || null;
|
||||
const toCommunity = communityAssignments.get(pair.to) || null;
|
||||
return fromCommunity && toCommunity && fromCommunity !== toCommunity && pair.weight >= 0.75;
|
||||
})
|
||||
.sort((left, right) => {
|
||||
if (right.weight !== left.weight) return right.weight - left.weight;
|
||||
if (left.from !== right.from) return left.from.localeCompare(right.from);
|
||||
return left.to.localeCompare(right.to);
|
||||
})
|
||||
.slice(0, 8)
|
||||
.map((pair) => ({
|
||||
from: pair.from,
|
||||
to: pair.to,
|
||||
weight: pair.weight,
|
||||
from_community: communityAssignments.get(pair.from) || null,
|
||||
to_community: communityAssignments.get(pair.to) || null
|
||||
}));
|
||||
|
||||
const degraded = options.nodeCount > options.maxInsightNodes || options.edgeCount > options.maxInsightEdges;
|
||||
if (degraded) {
|
||||
return {
|
||||
surprising_connections: [],
|
||||
isolated_nodes: isolatedNodes,
|
||||
bridge_nodes: [],
|
||||
sparse_communities: [],
|
||||
meta: {
|
||||
degraded: true,
|
||||
node_count: options.nodeCount,
|
||||
edge_count: options.edgeCount,
|
||||
max_insight_nodes: options.maxInsightNodes,
|
||||
max_insight_edges: options.maxInsightEdges
|
||||
}
|
||||
};
|
||||
}
|
||||
|
||||
return {
|
||||
surprising_connections: surprisingConnections,
|
||||
isolated_nodes: isolatedNodes,
|
||||
bridge_nodes: bridgeNodes,
|
||||
sparse_communities: sparseCommunities,
|
||||
meta: {
|
||||
degraded: false,
|
||||
node_count: options.nodeCount,
|
||||
edge_count: options.edgeCount,
|
||||
max_insight_nodes: options.maxInsightNodes,
|
||||
max_insight_edges: options.maxInsightEdges
|
||||
}
|
||||
};
|
||||
}
|
||||
|
||||
function buildLearning(analyzedNodes, analyzedEdges) {
|
||||
const degreeMap = new Map();
|
||||
for (const edge of analyzedEdges) {
|
||||
degreeMap.set(edge.from, (degreeMap.get(edge.from) || 0) + 1);
|
||||
degreeMap.set(edge.to, (degreeMap.get(edge.to) || 0) + 1);
|
||||
}
|
||||
|
||||
const communityGroups = new Map();
|
||||
for (const node of analyzedNodes) {
|
||||
if (node.community == null) continue;
|
||||
if (!communityGroups.has(node.community)) communityGroups.set(node.community, []);
|
||||
communityGroups.get(node.community).push(node);
|
||||
}
|
||||
|
||||
const communities = [];
|
||||
for (const [cid, members] of communityGroups.entries()) {
|
||||
const memberIds = new Set(members.map(n => n.id));
|
||||
let totalWeight = 0;
|
||||
for (const edge of analyzedEdges) {
|
||||
if (memberIds.has(edge.from) && memberIds.has(edge.to)) totalWeight += edge.weight;
|
||||
}
|
||||
const isWeak = members.length < 3;
|
||||
const startNode = members.slice().sort((a, b) => {
|
||||
const degDiff = (degreeMap.get(b.id) || 0) - (degreeMap.get(a.id) || 0);
|
||||
if (degDiff !== 0) return degDiff;
|
||||
return a.id.localeCompare(b.id);
|
||||
})[0];
|
||||
|
||||
communities.push({
|
||||
id: cid,
|
||||
label: (members.find(n => n.id === cid) || members[0]).label,
|
||||
node_count: members.length,
|
||||
source_count: members.filter(n => n.type === "source").length,
|
||||
internal_edge_weight: roundNumber(totalWeight),
|
||||
is_primary: false,
|
||||
is_weak: isWeak,
|
||||
recommended_start_node_id: startNode.id
|
||||
});
|
||||
}
|
||||
|
||||
communities.sort((a, b) => {
|
||||
if (b.node_count !== a.node_count) return b.node_count - a.node_count;
|
||||
if (b.internal_edge_weight !== a.internal_edge_weight) return b.internal_edge_weight - a.internal_edge_weight;
|
||||
return a.id.localeCompare(b.id);
|
||||
});
|
||||
|
||||
if (communities.length > 0) communities[0].is_primary = true;
|
||||
|
||||
const primary = communities.length > 0 ? communities[0] : null;
|
||||
const startNodeId = primary ? primary.recommended_start_node_id : null;
|
||||
|
||||
let pathNodeIds = [];
|
||||
let pathDegraded = false;
|
||||
if (primary && !primary.is_weak && startNodeId) {
|
||||
const primaryMemberIds = new Set(communityGroups.get(primary.id).map(n => n.id));
|
||||
const neighbors = analyzedEdges
|
||||
.filter(e => (e.from === startNodeId && primaryMemberIds.has(e.to)) ||
|
||||
(e.to === startNodeId && primaryMemberIds.has(e.from)))
|
||||
.map(e => e.from === startNodeId ? e.to : e.from);
|
||||
pathNodeIds = [startNodeId, ...sortedUnique(neighbors).filter(id => id !== startNodeId)];
|
||||
if (pathNodeIds.length < 2) pathDegraded = true;
|
||||
} else {
|
||||
pathDegraded = true;
|
||||
}
|
||||
|
||||
let communityNodeIds = [];
|
||||
let communityDegraded = false;
|
||||
if (primary && !primary.is_weak) {
|
||||
communityNodeIds = communityGroups.get(primary.id).map(n => n.id).sort();
|
||||
} else {
|
||||
communityDegraded = true;
|
||||
}
|
||||
|
||||
const globalNodeIds = analyzedNodes.slice().sort((a, b) => {
|
||||
const degDiff = (degreeMap.get(b.id) || 0) - (degreeMap.get(a.id) || 0);
|
||||
if (degDiff !== 0) return degDiff;
|
||||
return a.id.localeCompare(b.id);
|
||||
}).map(n => n.id);
|
||||
|
||||
const defaultMode = "global";
|
||||
|
||||
return {
|
||||
version: 1,
|
||||
entry: {
|
||||
recommended_start_node_id: startNodeId,
|
||||
recommended_start_reason: startNodeId ? "community_hub" : null,
|
||||
default_mode: defaultMode
|
||||
},
|
||||
views: {
|
||||
path: {
|
||||
enabled: !pathDegraded,
|
||||
start_node_id: pathDegraded ? null : startNodeId,
|
||||
node_ids: pathDegraded ? [] : pathNodeIds,
|
||||
degraded: pathDegraded
|
||||
},
|
||||
community: {
|
||||
enabled: !communityDegraded,
|
||||
community_id: primary && !communityDegraded ? primary.id : null,
|
||||
label: primary && !communityDegraded ? primary.label : null,
|
||||
node_ids: communityDegraded ? [] : communityNodeIds,
|
||||
is_weak: primary ? primary.is_weak : false,
|
||||
degraded: communityDegraded
|
||||
},
|
||||
global: {
|
||||
enabled: true,
|
||||
node_ids: globalNodeIds,
|
||||
degraded: false
|
||||
}
|
||||
},
|
||||
communities,
|
||||
degraded: {
|
||||
path_to_community: pathDegraded,
|
||||
community_to_global: communityDegraded
|
||||
}
|
||||
};
|
||||
}
|
||||
|
||||
function analyzeGraph(nodes, edges, options = {}) {
|
||||
const degraded = options.degraded === true;
|
||||
const maxLines = options.maxLines || 500;
|
||||
const maxInsightNodes = options.maxInsightNodes || 250;
|
||||
const maxInsightEdges = options.maxInsightEdges || 1000;
|
||||
|
||||
const nodesById = loadNodeDetails(nodes, degraded, maxLines);
|
||||
const pairMetrics = computePairMetrics(nodesById, edges);
|
||||
const nodeIds = nodes.map((node) => node.id);
|
||||
const communityAssignments = chooseCommunityLabels(
|
||||
nodeIds,
|
||||
runLouvain(nodeIds, pairMetrics),
|
||||
nodesById,
|
||||
edges
|
||||
);
|
||||
|
||||
const analyzedNodes = nodes.map((node) => ({
|
||||
id: node.id,
|
||||
label: node.label,
|
||||
type: node.type,
|
||||
source_path: node.source_path,
|
||||
community: communityAssignments.get(node.id) || null,
|
||||
content: nodesById[node.id].content
|
||||
}));
|
||||
|
||||
const analyzedEdges = edges.map((edge) => {
|
||||
const pairKey = sortedPairKey(edge.from, edge.to);
|
||||
const metrics = pairMetrics.get(pairKey) || {
|
||||
weight: 0,
|
||||
signals: { co_citation: 0, source_overlap: null, type_affinity: 0.5 },
|
||||
source_signal_available: false
|
||||
};
|
||||
|
||||
return {
|
||||
id: edge.id,
|
||||
from: edge.from,
|
||||
to: edge.to,
|
||||
type: edge.type,
|
||||
confidence: edge.confidence || edge.type,
|
||||
relation_type: edge.relation_type || "依赖",
|
||||
weight: metrics.weight,
|
||||
source_signal_available: metrics.source_signal_available,
|
||||
signals: metrics.signals
|
||||
};
|
||||
});
|
||||
|
||||
const insights = buildInsights(nodesById, analyzedEdges, pairMetrics, communityAssignments, {
|
||||
nodeCount: analyzedNodes.length,
|
||||
edgeCount: analyzedEdges.length,
|
||||
maxInsightNodes,
|
||||
maxInsightEdges
|
||||
});
|
||||
|
||||
const learning = buildLearning(analyzedNodes, analyzedEdges);
|
||||
|
||||
return { nodes: analyzedNodes, edges: analyzedEdges, insights, learning };
|
||||
}
|
||||
|
||||
function main(argv) {
|
||||
if (argv.length < 7) {
|
||||
console.error("Usage: node graph-analysis.js <nodes.json> <edges.json> <output.json> <degraded:0|1> <max-lines> <max-insight-nodes> <max-insight-edges>");
|
||||
process.exit(1);
|
||||
}
|
||||
|
||||
const timer = setTimeout(() => {
|
||||
console.error("ERROR: graph analysis timed out (120s)");
|
||||
process.exit(2);
|
||||
}, 120_000);
|
||||
timer.unref();
|
||||
|
||||
const [, , nodesPath, edgesPath, outputPath, degradedRaw, maxLinesRaw, maxInsightNodesRaw, maxInsightEdgesRaw] = argv;
|
||||
|
||||
for (const p of [nodesPath, edgesPath]) {
|
||||
if (!fs.existsSync(p)) {
|
||||
console.error(`ERROR: File not found: ${p}`);
|
||||
process.exit(1);
|
||||
}
|
||||
}
|
||||
|
||||
const analyzed = analyzeGraph(readJson(nodesPath), readJson(edgesPath), {
|
||||
degraded: degradedRaw === "1",
|
||||
maxLines: Number(maxLinesRaw) || 500,
|
||||
maxInsightNodes: Number(maxInsightNodesRaw) || 250,
|
||||
maxInsightEdges: Number(maxInsightEdgesRaw) || 1000
|
||||
});
|
||||
|
||||
writeJson(outputPath, analyzed);
|
||||
clearTimeout(timer);
|
||||
}
|
||||
|
||||
if (require.main === module) {
|
||||
try {
|
||||
main(process.argv);
|
||||
} catch (error) {
|
||||
const code = error && error.code;
|
||||
if (code === "ENOENT") {
|
||||
console.error(`ERROR: File not found: ${error.path || "(unknown)"}`);
|
||||
} else if (error instanceof SyntaxError) {
|
||||
console.error(`ERROR: Invalid JSON in input: ${error.message}`);
|
||||
} else {
|
||||
console.error(`ERROR: ${error && error.message ? error.message : String(error)}`);
|
||||
}
|
||||
process.exit(1);
|
||||
}
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
analyzeGraph,
|
||||
buildInsights,
|
||||
buildLearning,
|
||||
chooseCommunityLabels,
|
||||
computePairMetrics,
|
||||
extractFrontmatter,
|
||||
normalizeBody,
|
||||
parseSourcesFrontmatter,
|
||||
runLouvain,
|
||||
typeAffinity
|
||||
};
|
||||
46
llm-wiki/scripts/hook-session-start.sh
Executable file
46
llm-wiki/scripts/hook-session-start.sh
Executable file
@@ -0,0 +1,46 @@
|
||||
#!/bin/bash
|
||||
# SessionStart hook: 会话开始时注入 wiki 上下文(只触发一次)
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
WIKI_PATH=""
|
||||
|
||||
if [ -f "$HOME/.llm-wiki-path" ]; then
|
||||
WIKI_PATH="$(cat "$HOME/.llm-wiki-path")"
|
||||
fi
|
||||
|
||||
if [ -z "$WIKI_PATH" ] && [ -f .wiki-schema.md ]; then
|
||||
WIKI_PATH="$(pwd)"
|
||||
fi
|
||||
|
||||
if [ -z "$WIKI_PATH" ] || [ ! -f "$WIKI_PATH/.wiki-schema.md" ]; then
|
||||
printf '{}\n'
|
||||
exit 0
|
||||
fi
|
||||
|
||||
require_python_cmd
|
||||
|
||||
"$PYTHON_CMD" - "$WIKI_PATH" <<'PY'
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
|
||||
# 防御性:即使上游 shared-config.sh 未设置 PYTHONIOENCODING,
|
||||
# 此处也强制 stdout 为 UTF-8,避免 Agent 接到 gbk 字节
|
||||
if hasattr(sys.stdout, "reconfigure"):
|
||||
sys.stdout.reconfigure(encoding="utf-8")
|
||||
|
||||
wiki_path = os.path.realpath(sys.argv[1])
|
||||
message = f"[llm-wiki] 检测到知识库: {wiki_path}/index.md,回答问题时优先查阅 wiki 内容获取上下文"
|
||||
|
||||
print(json.dumps({
|
||||
"hookSpecificOutput": {
|
||||
"hookEventName": "SessionStart",
|
||||
"additionalContext": message,
|
||||
}
|
||||
}, ensure_ascii=False))
|
||||
PY
|
||||
95
llm-wiki/scripts/init-wiki.sh
Executable file
95
llm-wiki/scripts/init-wiki.sh
Executable file
@@ -0,0 +1,95 @@
|
||||
#!/bin/bash
|
||||
# llm-wiki 初始化脚本
|
||||
# 自动创建知识库的目录结构
|
||||
# 用法:bash init-wiki.sh <知识库路径> <主题>
|
||||
|
||||
set -e
|
||||
|
||||
WIKI_ROOT="${1:-$HOME/Documents/我的知识库}"
|
||||
TOPIC="${2:-我的知识库}"
|
||||
LANGUAGE="${3:-中文}"
|
||||
DATE=$(date +%Y-%m-%d)
|
||||
SKILL_DIR="$(cd "$(dirname "$0")/.." && pwd)"
|
||||
|
||||
# 安全的模板变量替换函数(用 perl 替代 sed,避免中文/空格/特殊字符问题)
|
||||
replace_vars() {
|
||||
local input_file="$1"
|
||||
local output_file="$2"
|
||||
TOPIC_VALUE="$TOPIC" \
|
||||
DATE_VALUE="$DATE" \
|
||||
WIKI_ROOT_VALUE="$WIKI_ROOT" \
|
||||
LANGUAGE_VALUE="$LANGUAGE" \
|
||||
perl -pe '
|
||||
s/\{\{TOPIC\}\}/$ENV{TOPIC_VALUE}/g;
|
||||
s/\{\{DATE\}\}/$ENV{DATE_VALUE}/g;
|
||||
s/\{\{WIKI_ROOT\}\}/$ENV{WIKI_ROOT_VALUE}/g;
|
||||
s/\{\{LANGUAGE\}\}/$ENV{LANGUAGE_VALUE}/g;
|
||||
' "$input_file" > "$output_file"
|
||||
}
|
||||
|
||||
echo "正在创建知识库..."
|
||||
echo " 路径:$WIKI_ROOT"
|
||||
echo " 主题:$TOPIC"
|
||||
echo " 语言:$LANGUAGE"
|
||||
echo ""
|
||||
|
||||
# 创建目录结构(包含小红书和知乎)
|
||||
mkdir -p "$WIKI_ROOT"/raw/{articles,tweets,wechat,xiaohongshu,zhihu,pdfs,notes,assets}
|
||||
mkdir -p "$WIKI_ROOT"/wiki/{entities,topics,sources,comparisons,synthesis,synthesis/sessions,queries}
|
||||
|
||||
cat > "$WIKI_ROOT/.gitignore" <<'EOF'
|
||||
.wiki-tmp/
|
||||
EOF
|
||||
|
||||
echo "[完成] 目录结构已创建"
|
||||
|
||||
# 从模板生成文件
|
||||
replace_vars "$SKILL_DIR/templates/schema-template.md" "$WIKI_ROOT/.wiki-schema.md"
|
||||
echo "[完成] Schema 文件已生成"
|
||||
|
||||
replace_vars "$SKILL_DIR/templates/index-template.md" "$WIKI_ROOT/index.md"
|
||||
echo "[完成] 索引文件已生成"
|
||||
|
||||
replace_vars "$SKILL_DIR/templates/log-template.md" "$WIKI_ROOT/log.md"
|
||||
echo "[完成] 日志文件已生成"
|
||||
|
||||
replace_vars "$SKILL_DIR/templates/overview-template.md" "$WIKI_ROOT/wiki/overview.md"
|
||||
echo "[完成] 总览文件已生成"
|
||||
|
||||
if [ "$LANGUAGE" = "English" ]; then
|
||||
replace_vars "$SKILL_DIR/templates/purpose-en-template.md" "$WIKI_ROOT/purpose.md"
|
||||
else
|
||||
replace_vars "$SKILL_DIR/templates/purpose-template.md" "$WIKI_ROOT/purpose.md"
|
||||
fi
|
||||
echo "[完成] 研究方向文件已生成"
|
||||
|
||||
cat > "$WIKI_ROOT/.wiki-cache.json" <<'EOF'
|
||||
{
|
||||
"version": 1,
|
||||
"entries": {}
|
||||
}
|
||||
EOF
|
||||
echo "[完成] 缓存文件已生成"
|
||||
|
||||
echo ""
|
||||
echo "知识库创建完成!"
|
||||
echo ""
|
||||
echo "目录结构:"
|
||||
echo " $WIKI_ROOT/"
|
||||
echo " ├── raw/ (原始素材)"
|
||||
echo " │ ├── articles/ 网页文章"
|
||||
echo " │ ├── tweets/ X/Twitter"
|
||||
echo " │ ├── wechat/ 微信公众号"
|
||||
echo " │ ├── xiaohongshu/ 小红书"
|
||||
echo " │ ├── zhihu/ 知乎"
|
||||
echo " │ ├── pdfs/ PDF"
|
||||
echo " │ ├── notes/ 笔记"
|
||||
echo " │ └── assets/ 图片等附件"
|
||||
echo " ├── wiki/ (知识库)"
|
||||
echo " ├── index.md (索引)"
|
||||
echo " ├── log.md (日志)"
|
||||
echo " ├── purpose.md (研究方向)"
|
||||
echo " ├── .wiki-cache.json (缓存)"
|
||||
echo " └── .wiki-schema.md (配置)"
|
||||
echo ""
|
||||
echo "下一步:给 agent 一个链接或文件,开始构建知识库!"
|
||||
625
llm-wiki/scripts/lib/graph-warning-bundle.js
Normal file
625
llm-wiki/scripts/lib/graph-warning-bundle.js
Normal file
@@ -0,0 +1,625 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const fs = require("node:fs");
|
||||
const fsp = require("node:fs/promises");
|
||||
const path = require("node:path");
|
||||
const zlib = require("node:zlib");
|
||||
const { normalizeRelativePosixPath } = require("./wiki-file-discovery");
|
||||
|
||||
const DEFAULT_WARNING_DETAILS_REF = "wiki/graph-warnings.json";
|
||||
const OFFLINE_WARNING_LIMIT_BYTES = 2 * 1024 * 1024;
|
||||
function sha256(bytes) {
|
||||
return crypto.createHash("sha256").update(bytes).digest("hex");
|
||||
}
|
||||
|
||||
function canonicalize(value) {
|
||||
if (Array.isArray(value)) return value.map(canonicalize);
|
||||
if (!value || typeof value !== "object") return value;
|
||||
const result = {};
|
||||
for (const key of Object.keys(value).sort()) {
|
||||
if (value[key] !== undefined) result[key] = canonicalize(value[key]);
|
||||
}
|
||||
return result;
|
||||
}
|
||||
|
||||
function canonicalBytes(value) {
|
||||
return Buffer.from(JSON.stringify(canonicalize(value)), "utf8");
|
||||
}
|
||||
|
||||
function serializeJsonForHtmlScript(value) {
|
||||
const json = JSON.stringify(canonicalize(value));
|
||||
return Buffer.from(json.replace(/[<>&\u2028\u2029]/g, (character) => (
|
||||
`\\u${character.codePointAt(0).toString(16).padStart(4, "0")}`
|
||||
)), "utf8");
|
||||
}
|
||||
|
||||
function compareText(left, right) {
|
||||
return String(left).localeCompare(String(right), "en");
|
||||
}
|
||||
|
||||
function assertRelativeContentPath(value, fieldName) {
|
||||
if (typeof value !== "string" || !value || value.includes("\\")) {
|
||||
throw new Error(`${fieldName} must be a POSIX knowledge-base-relative path`);
|
||||
}
|
||||
let normalized;
|
||||
try {
|
||||
normalized = normalizeRelativePosixPath(value);
|
||||
} catch (_) {
|
||||
throw new Error(`${fieldName} must be a POSIX knowledge-base-relative path`);
|
||||
}
|
||||
if (normalized !== value || path.posix.isAbsolute(value)) {
|
||||
throw new Error(`${fieldName} must be a POSIX knowledge-base-relative path`);
|
||||
}
|
||||
return value;
|
||||
}
|
||||
|
||||
function validateDetailsRef(detailsRef) {
|
||||
assertRelativeContentPath(detailsRef, "details_ref");
|
||||
if (path.posix.basename(detailsRef) !== "graph-warnings.json") {
|
||||
throw new Error("details_ref must name graph-warnings.json");
|
||||
}
|
||||
return detailsRef;
|
||||
}
|
||||
|
||||
function normalizeOccurrence(occurrence) {
|
||||
if (!occurrence || typeof occurrence !== "object") {
|
||||
throw new Error("warning occurrence must be an object");
|
||||
}
|
||||
assertRelativeContentPath(occurrence.source_path, "source_path");
|
||||
return canonicalize(occurrence);
|
||||
}
|
||||
|
||||
function normalizeCandidateSets(candidateSets) {
|
||||
if (!Array.isArray(candidateSets)) throw new Error("candidateSets must be an array");
|
||||
const seen = new Set();
|
||||
return candidateSets.map((candidateSet) => {
|
||||
if (!candidateSet || typeof candidateSet !== "object" || !candidateSet.candidate_set_id) {
|
||||
throw new Error("candidate_set_id is required");
|
||||
}
|
||||
if (seen.has(candidateSet.candidate_set_id)) {
|
||||
throw new Error(`duplicate candidate_set_id: ${candidateSet.candidate_set_id}`);
|
||||
}
|
||||
seen.add(candidateSet.candidate_set_id);
|
||||
const candidates = Array.from(new Set((candidateSet.candidates || []).map((candidate) => (
|
||||
assertRelativeContentPath(candidate, "candidate path")
|
||||
)))).sort(compareText);
|
||||
if (candidateSet.candidate_count !== candidates.length) {
|
||||
throw new Error(`candidate_count does not match candidates for ${candidateSet.candidate_set_id}`);
|
||||
}
|
||||
return canonicalize({ ...candidateSet, candidates });
|
||||
}).sort((left, right) => compareText(left.candidate_set_id, right.candidate_set_id));
|
||||
}
|
||||
|
||||
function normalizeGroups(groups, candidateSetIds) {
|
||||
if (!Array.isArray(groups)) throw new Error("groups must be an array");
|
||||
const seen = new Set();
|
||||
const seenOccurrences = new Set();
|
||||
return groups.map((group) => {
|
||||
if (!group || typeof group !== "object" || !group.warning_id) {
|
||||
throw new Error("warning_id is required");
|
||||
}
|
||||
if (seen.has(group.warning_id)) throw new Error(`duplicate warning_id: ${group.warning_id}`);
|
||||
seen.add(group.warning_id);
|
||||
if (group.candidate_set_id && !candidateSetIds.has(group.candidate_set_id)) {
|
||||
throw new Error(`warning references missing candidate set: ${group.candidate_set_id}`);
|
||||
}
|
||||
if (!Number.isSafeInteger(group.occurrence_count) || group.occurrence_count < 0) {
|
||||
throw new Error(`invalid occurrence_count for ${group.warning_id}`);
|
||||
}
|
||||
const occurrences = (group.occurrences || []).map(normalizeOccurrence)
|
||||
.sort((left, right) => compareText(left.occurrence_id, right.occurrence_id));
|
||||
for (const occurrence of occurrences) {
|
||||
if (seenOccurrences.has(occurrence.occurrence_id)) {
|
||||
throw new Error(`duplicate occurrence_id: ${occurrence.occurrence_id}`);
|
||||
}
|
||||
seenOccurrences.add(occurrence.occurrence_id);
|
||||
}
|
||||
if (group.occurrence_count !== occurrences.length) {
|
||||
throw new Error(`occurrence_count does not match occurrences for ${group.warning_id}`);
|
||||
}
|
||||
return canonicalize({ ...group, occurrences });
|
||||
}).sort((left, right) => compareText(left.warning_id, right.warning_id));
|
||||
}
|
||||
|
||||
function sortGraphCollections(graphData) {
|
||||
const graph = structuredClone(graphData || {});
|
||||
if (graph.meta && typeof graph.meta === "object") delete graph.meta.warning_summary;
|
||||
if (Array.isArray(graph.nodes)) graph.nodes.sort((left, right) => compareText(left.id, right.id));
|
||||
if (Array.isArray(graph.edges)) {
|
||||
graph.edges.sort((left, right) => compareText(
|
||||
`${left.id || ""}\0${left.from || ""}\0${left.to || ""}`,
|
||||
`${right.id || ""}\0${right.from || ""}\0${right.to || ""}`
|
||||
));
|
||||
}
|
||||
if (graph.learning && Array.isArray(graph.learning.communities)) {
|
||||
graph.learning.communities.sort((left, right) => compareText(left.id, right.id));
|
||||
}
|
||||
return canonicalize(graph);
|
||||
}
|
||||
|
||||
function graphBuildIdentityProjection(graphData) {
|
||||
const graph = sortGraphCollections(graphData);
|
||||
if (graph.meta && typeof graph.meta === "object") delete graph.meta.build_date;
|
||||
return canonicalize(graph);
|
||||
}
|
||||
|
||||
function canonicalWarningDetailBytes(bundle) {
|
||||
return canonicalBytes({
|
||||
version: bundle.version,
|
||||
build_id: bundle.build_id,
|
||||
candidate_sets: bundle.candidate_sets,
|
||||
groups: bundle.groups
|
||||
});
|
||||
}
|
||||
|
||||
function summarizeWarningGroups(groups) {
|
||||
const byCode = {};
|
||||
let errorOccurrences = 0;
|
||||
let warningOccurrences = 0;
|
||||
for (const group of groups) {
|
||||
byCode[group.code] = (byCode[group.code] || 0) + group.occurrence_count;
|
||||
if (group.severity === "error") errorOccurrences += group.occurrence_count;
|
||||
else warningOccurrences += group.occurrence_count;
|
||||
}
|
||||
return canonicalize({
|
||||
total_groups: groups.length,
|
||||
total_occurrences: errorOccurrences + warningOccurrences,
|
||||
error_occurrences: errorOccurrences,
|
||||
warning_occurrences: warningOccurrences,
|
||||
by_code: byCode
|
||||
});
|
||||
}
|
||||
|
||||
function summaryCountsMatch(summary, groups) {
|
||||
const actual = canonicalize({
|
||||
total_groups: summary.total_groups,
|
||||
total_occurrences: summary.total_occurrences,
|
||||
error_occurrences: summary.error_occurrences,
|
||||
warning_occurrences: summary.warning_occurrences,
|
||||
by_code: summary.by_code
|
||||
});
|
||||
return canonicalBytes(actual).equals(canonicalBytes(summarizeWarningGroups(groups)));
|
||||
}
|
||||
|
||||
function assembleGraphArtifactPair({
|
||||
graphData,
|
||||
groups,
|
||||
candidateSets,
|
||||
detailsRef = DEFAULT_WARNING_DETAILS_REF
|
||||
}) {
|
||||
const validatedDetailsRef = validateDetailsRef(detailsRef);
|
||||
const candidate_sets = normalizeCandidateSets(candidateSets);
|
||||
const normalizedGroups = normalizeGroups(groups, new Set(candidate_sets.map((item) => item.candidate_set_id)));
|
||||
const graphWithoutSummary = sortGraphCollections(graphData);
|
||||
const build_id = sha256(canonicalBytes({
|
||||
graph_without_warning_summary: graphBuildIdentityProjection(graphWithoutSummary),
|
||||
warning_details: { candidate_sets, groups: normalizedGroups }
|
||||
}));
|
||||
const detailProjection = {
|
||||
version: 1,
|
||||
build_id,
|
||||
candidate_sets,
|
||||
groups: normalizedGroups
|
||||
};
|
||||
const details_sha256 = sha256(canonicalBytes(detailProjection));
|
||||
const counts = summarizeWarningGroups(normalizedGroups);
|
||||
const summary = canonicalize({
|
||||
build_id,
|
||||
...counts,
|
||||
details_ref: validatedDetailsRef,
|
||||
details_sha256
|
||||
});
|
||||
const normalizedGraph = canonicalize({
|
||||
...graphWithoutSummary,
|
||||
meta: { ...(graphWithoutSummary.meta || {}), warning_summary: summary }
|
||||
});
|
||||
const warningBundle = canonicalize({
|
||||
version: 1,
|
||||
build_id,
|
||||
summary,
|
||||
candidate_sets,
|
||||
groups: normalizedGroups
|
||||
});
|
||||
return { graphData: normalizedGraph, warningBundle };
|
||||
}
|
||||
|
||||
function summariesMatch(left, right) {
|
||||
return Boolean(left && right && canonicalBytes(left).equals(canonicalBytes(right)));
|
||||
}
|
||||
|
||||
function graphWithoutWarningSummary(graphData) {
|
||||
return sortGraphCollections(graphData);
|
||||
}
|
||||
|
||||
function recalculateBuildId(graphData, warningBundle) {
|
||||
return sha256(canonicalBytes({
|
||||
graph_without_warning_summary: graphBuildIdentityProjection(graphData),
|
||||
warning_details: {
|
||||
candidate_sets: warningBundle.candidate_sets,
|
||||
groups: warningBundle.groups
|
||||
}
|
||||
}));
|
||||
}
|
||||
|
||||
function parseArtifactBytes(bytes) {
|
||||
return JSON.parse(Buffer.isBuffer(bytes) ? bytes.toString("utf8") : String(bytes));
|
||||
}
|
||||
|
||||
function validateArtifactObjects({ graphData, warningBundle, expectedDetailsRef }) {
|
||||
const summary = graphData && graphData.meta && graphData.meta.warning_summary;
|
||||
if (!summary || typeof summary !== "object") {
|
||||
return { status: "unavailable", reason: "invalid", summary: summary || null };
|
||||
}
|
||||
|
||||
try {
|
||||
validateDetailsRef(summary.details_ref);
|
||||
} catch (_) {
|
||||
return { status: "unavailable", reason: "invalid", summary };
|
||||
}
|
||||
if (summary.details_ref !== expectedDetailsRef) {
|
||||
return { status: "unavailable", reason: "details_ref_mismatch", summary };
|
||||
}
|
||||
if (!warningBundle || typeof warningBundle !== "object" || warningBundle.version !== 1) {
|
||||
return { status: "unavailable", reason: "invalid", summary };
|
||||
}
|
||||
if (summary.build_id !== warningBundle.build_id || !summariesMatch(summary, warningBundle.summary)) {
|
||||
return { status: "unavailable", reason: "build_id_mismatch", summary };
|
||||
}
|
||||
|
||||
let normalizedSets;
|
||||
let normalizedGroups;
|
||||
try {
|
||||
normalizedSets = normalizeCandidateSets(warningBundle.candidate_sets);
|
||||
normalizedGroups = normalizeGroups(
|
||||
warningBundle.groups,
|
||||
new Set(normalizedSets.map((item) => item.candidate_set_id))
|
||||
);
|
||||
} catch (_) {
|
||||
return { status: "unavailable", reason: "invalid", summary };
|
||||
}
|
||||
const canonicalBundle = canonicalize({
|
||||
...warningBundle,
|
||||
candidate_sets: normalizedSets,
|
||||
groups: normalizedGroups
|
||||
});
|
||||
if (!summaryCountsMatch(summary, normalizedGroups)) {
|
||||
return { status: "unavailable", reason: "invalid", summary };
|
||||
}
|
||||
const actualDetailsSha256 = sha256(canonicalWarningDetailBytes(canonicalBundle));
|
||||
if (summary.details_sha256 !== actualDetailsSha256) {
|
||||
return { status: "unavailable", reason: "details_sha256_mismatch", summary };
|
||||
}
|
||||
if (recalculateBuildId(graphData, canonicalBundle) !== summary.build_id) {
|
||||
return { status: "unavailable", reason: "build_id_mismatch", summary };
|
||||
}
|
||||
|
||||
return { status: "available", graphData, warningBundle: canonicalBundle };
|
||||
}
|
||||
|
||||
function isWithinRoot(rootPath, candidatePath) {
|
||||
return candidatePath === rootPath || candidatePath.startsWith(`${rootPath}${path.sep}`);
|
||||
}
|
||||
|
||||
async function validateArtifactDestinations({ kbRoot, graphPath, warningPath, detailsRef }) {
|
||||
const rootReal = await fsp.realpath(kbRoot);
|
||||
const graphAbsolute = path.resolve(graphPath);
|
||||
const warningAbsolute = path.resolve(warningPath);
|
||||
if (path.basename(graphAbsolute) !== "graph-data.json") {
|
||||
throw new Error("graph destination basename must be graph-data.json");
|
||||
}
|
||||
if (path.basename(warningAbsolute) !== "graph-warnings.json") {
|
||||
throw new Error("warning destination basename must be graph-warnings.json");
|
||||
}
|
||||
|
||||
const graphParentReal = await fsp.realpath(path.dirname(graphAbsolute));
|
||||
const warningParentReal = await fsp.realpath(path.dirname(warningAbsolute));
|
||||
if (!isWithinRoot(rootReal, graphParentReal) || !isWithinRoot(rootReal, warningParentReal)) {
|
||||
throw new Error("artifact destination must remain inside the knowledge base");
|
||||
}
|
||||
if (graphParentReal !== warningParentReal) {
|
||||
throw new Error("graph-data.json and graph-warnings.json must be sibling artifacts");
|
||||
}
|
||||
const graphFinal = path.join(graphParentReal, "graph-data.json");
|
||||
const warningFinal = path.join(warningParentReal, "graph-warnings.json");
|
||||
for (const finalPath of [graphFinal, warningFinal]) {
|
||||
try {
|
||||
const stat = await fsp.lstat(finalPath);
|
||||
if (stat.isSymbolicLink() || !stat.isFile()) {
|
||||
throw new Error(`artifact destination is not a regular file: ${finalPath}`);
|
||||
}
|
||||
} catch (error) {
|
||||
if (error.code !== "ENOENT") throw error;
|
||||
}
|
||||
}
|
||||
|
||||
const normalizedDetailsRef = validateDetailsRef(detailsRef);
|
||||
const detailsAbsolute = path.resolve(rootReal, ...normalizedDetailsRef.split("/"));
|
||||
const detailsParentReal = await fsp.realpath(path.dirname(detailsAbsolute));
|
||||
const resolvedDetails = path.join(detailsParentReal, path.basename(detailsAbsolute));
|
||||
if (!isWithinRoot(rootReal, detailsParentReal) || resolvedDetails !== warningFinal) {
|
||||
throw new Error("details_ref does not resolve to the final sibling graph-warnings.json");
|
||||
}
|
||||
const expectedDetailsRef = path.relative(rootReal, warningFinal).split(path.sep).join("/");
|
||||
if (normalizedDetailsRef !== expectedDetailsRef) {
|
||||
throw new Error("details_ref does not match the final warning destination");
|
||||
}
|
||||
return { rootReal, graphFinal, warningFinal, outputParent: graphParentReal, expectedDetailsRef };
|
||||
}
|
||||
|
||||
async function writeSyncedFile(filePath, bytes) {
|
||||
const handle = await fsp.open(filePath, "wx", 0o600);
|
||||
try {
|
||||
await handle.writeFile(bytes);
|
||||
await handle.sync();
|
||||
} finally {
|
||||
await handle.close();
|
||||
}
|
||||
}
|
||||
|
||||
async function fsyncDirectory(directoryPath) {
|
||||
let handle;
|
||||
try {
|
||||
handle = await fsp.open(directoryPath, fs.constants.O_RDONLY);
|
||||
await handle.sync();
|
||||
} catch (error) {
|
||||
if (!["EINVAL", "ENOTSUP", "EBADF", "EPERM", "EISDIR"].includes(error.code)) throw error;
|
||||
} finally {
|
||||
if (handle) await handle.close();
|
||||
}
|
||||
}
|
||||
|
||||
function operationDirectoryName(name) {
|
||||
return /^[a-f0-9]{64}-[0-9a-f]{8}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{12}$/i.test(name);
|
||||
}
|
||||
|
||||
async function pruneOldOperationDirectories(buildRoot, currentDirectory, now) {
|
||||
const entries = await fsp.readdir(buildRoot, { withFileTypes: true });
|
||||
for (const entry of entries) {
|
||||
if (!entry.isDirectory() || !operationDirectoryName(entry.name)) continue;
|
||||
const candidate = path.join(buildRoot, entry.name);
|
||||
if (candidate === currentDirectory) continue;
|
||||
const stat = await fsp.stat(candidate);
|
||||
if (now - stat.mtimeMs > 24 * 60 * 60 * 1000) {
|
||||
await fsp.rm(candidate, { recursive: true, force: true });
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
async function commitGraphArtifactPair({ kbRoot, graphPath, warningPath, pair, hooks = {} }) {
|
||||
if (!pair || !pair.graphData || !pair.warningBundle) throw new Error("artifact pair is required");
|
||||
const summary = pair.graphData.meta && pair.graphData.meta.warning_summary;
|
||||
if (!summary) throw new Error("graph warning summary is required");
|
||||
const destinations = await validateArtifactDestinations({
|
||||
kbRoot,
|
||||
graphPath,
|
||||
warningPath,
|
||||
detailsRef: summary.details_ref
|
||||
});
|
||||
const stat = hooks.stat || ((target) => fsp.stat(target));
|
||||
const tempParent = path.join(destinations.rootReal, ".wiki-tmp");
|
||||
await fsp.mkdir(tempParent, { recursive: true, mode: 0o700 });
|
||||
const tempParentReal = await fsp.realpath(tempParent);
|
||||
if (!isWithinRoot(destinations.rootReal, tempParentReal)) {
|
||||
throw new Error("temporary graph build directory escapes knowledge base");
|
||||
}
|
||||
const buildRoot = path.join(tempParentReal, "graph-build");
|
||||
await fsp.mkdir(buildRoot, { recursive: true, mode: 0o700 });
|
||||
|
||||
const [tempDevice, graphDevice, warningDevice] = await Promise.all([
|
||||
stat(tempParentReal),
|
||||
stat(path.dirname(destinations.graphFinal)),
|
||||
stat(path.dirname(destinations.warningFinal))
|
||||
]);
|
||||
if (tempDevice.dev !== graphDevice.dev || tempDevice.dev !== warningDevice.dev) {
|
||||
throw new Error("graph artifact destinations must use the same filesystem device as .wiki-tmp");
|
||||
}
|
||||
|
||||
const graphBytes = Buffer.from(`${JSON.stringify(pair.graphData, null, 2)}\n`, "utf8");
|
||||
const warningBytes = Buffer.from(`${JSON.stringify(pair.warningBundle, null, 2)}\n`, "utf8");
|
||||
let graphObject;
|
||||
let warningObject;
|
||||
try {
|
||||
graphObject = parseArtifactBytes(graphBytes);
|
||||
warningObject = parseArtifactBytes(warningBytes);
|
||||
} catch (error) {
|
||||
throw new Error(`invalid artifact pair JSON: ${error.message}`);
|
||||
}
|
||||
const preflight = validateArtifactObjects({
|
||||
graphData: graphObject,
|
||||
warningBundle: warningObject,
|
||||
expectedDetailsRef: destinations.expectedDetailsRef
|
||||
});
|
||||
if (preflight.status !== "available") {
|
||||
throw new Error(`invalid artifact pair: ${preflight.reason}`);
|
||||
}
|
||||
|
||||
const operationDirectory = path.join(
|
||||
buildRoot,
|
||||
`${summary.build_id}-${crypto.randomUUID()}`
|
||||
);
|
||||
await fsp.mkdir(operationDirectory, { recursive: false, mode: 0o700 });
|
||||
const tempGraph = path.join(operationDirectory, "graph-data.json");
|
||||
const tempWarning = path.join(operationDirectory, "graph-warnings.json");
|
||||
|
||||
await writeSyncedFile(tempGraph, graphBytes);
|
||||
await writeSyncedFile(tempWarning, warningBytes);
|
||||
const verifiedTemporary = validateArtifactObjects({
|
||||
graphData: parseArtifactBytes(await fsp.readFile(tempGraph)),
|
||||
warningBundle: parseArtifactBytes(await fsp.readFile(tempWarning)),
|
||||
expectedDetailsRef: destinations.expectedDetailsRef
|
||||
});
|
||||
if (verifiedTemporary.status !== "available") {
|
||||
throw new Error(`temporary artifact verification failed: ${verifiedTemporary.reason}`);
|
||||
}
|
||||
|
||||
await fsp.rename(tempWarning, destinations.warningFinal);
|
||||
await fsyncDirectory(destinations.outputParent);
|
||||
if (hooks.afterWarningReplace) await hooks.afterWarningReplace();
|
||||
await fsp.rename(tempGraph, destinations.graphFinal);
|
||||
await fsyncDirectory(destinations.outputParent);
|
||||
await fsp.rm(operationDirectory, { recursive: true, force: true });
|
||||
await pruneOldOperationDirectories(
|
||||
buildRoot,
|
||||
operationDirectory,
|
||||
hooks.now ? hooks.now() : Date.now()
|
||||
);
|
||||
}
|
||||
|
||||
async function verifyGraphArtifactPair({ kbRoot, graphPath, warningPath }) {
|
||||
let graphData;
|
||||
try {
|
||||
graphData = parseArtifactBytes(await fsp.readFile(graphPath));
|
||||
} catch (_) {
|
||||
return { status: "unavailable", reason: "invalid", summary: null };
|
||||
}
|
||||
const summary = graphData && graphData.meta && graphData.meta.warning_summary;
|
||||
if (!summary || typeof summary !== "object") {
|
||||
return { status: "unavailable", reason: "invalid", summary: summary || null };
|
||||
}
|
||||
|
||||
let destinations;
|
||||
try {
|
||||
destinations = await validateArtifactDestinations({
|
||||
kbRoot,
|
||||
graphPath,
|
||||
warningPath,
|
||||
detailsRef: summary.details_ref
|
||||
});
|
||||
} catch (error) {
|
||||
return {
|
||||
status: "unavailable",
|
||||
reason: error.message.includes("details_ref") ? "details_ref_mismatch" : "invalid",
|
||||
summary
|
||||
};
|
||||
}
|
||||
|
||||
let warningBytes;
|
||||
try {
|
||||
warningBytes = await fsp.readFile(destinations.warningFinal);
|
||||
} catch (error) {
|
||||
return {
|
||||
status: "unavailable",
|
||||
reason: error.code === "ENOENT" ? "missing" : "invalid",
|
||||
summary
|
||||
};
|
||||
}
|
||||
let warningBundle;
|
||||
try {
|
||||
warningBundle = parseArtifactBytes(warningBytes);
|
||||
} catch (_) {
|
||||
return { status: "unavailable", reason: "invalid", summary };
|
||||
}
|
||||
return validateArtifactObjects({
|
||||
graphData,
|
||||
warningBundle,
|
||||
expectedDetailsRef: destinations.expectedDetailsRef
|
||||
});
|
||||
}
|
||||
|
||||
function canonicalOfflineBundle(bundle) {
|
||||
const candidate_sets = (bundle.candidate_sets || []).map((candidateSet) => canonicalize({
|
||||
...candidateSet,
|
||||
candidates: (candidateSet.candidates || []).slice().sort(compareText)
|
||||
})).sort((left, right) => compareText(left.candidate_set_id, right.candidate_set_id));
|
||||
const groups = (bundle.groups || []).map((group) => canonicalize({
|
||||
...group,
|
||||
occurrences: (group.occurrences || []).slice()
|
||||
.sort((left, right) => compareText(left.occurrence_id, right.occurrence_id))
|
||||
})).sort((left, right) => compareText(left.warning_id, right.warning_id));
|
||||
return canonicalize({ ...bundle, candidate_sets, groups });
|
||||
}
|
||||
|
||||
function offlinePayload(summary, bundle, truncated, omittedGroupCount, omittedCandidateSetCount) {
|
||||
return canonicalize({
|
||||
summary,
|
||||
details_status: "available",
|
||||
details_unavailable_reason: null,
|
||||
warning_details_truncated: truncated,
|
||||
omitted_group_count: omittedGroupCount,
|
||||
omitted_candidate_set_count: omittedCandidateSetCount,
|
||||
bundle
|
||||
});
|
||||
}
|
||||
|
||||
function compressedPayloadBytes(payload) {
|
||||
const scriptBytes = serializeJsonForHtmlScript(payload);
|
||||
return {
|
||||
scriptBytes,
|
||||
compressedBytes: zlib.gzipSync(scriptBytes, { level: 9 }).length
|
||||
};
|
||||
}
|
||||
|
||||
function prepareOfflineWarningPayload({
|
||||
summary,
|
||||
bundle,
|
||||
maxCompressedBytes = OFFLINE_WARNING_LIMIT_BYTES
|
||||
}) {
|
||||
if (!Number.isSafeInteger(maxCompressedBytes) || maxCompressedBytes <= 0) {
|
||||
throw new Error("maxCompressedBytes must be a positive integer");
|
||||
}
|
||||
const completeBundle = canonicalOfflineBundle(bundle);
|
||||
let payload = offlinePayload(summary, completeBundle, false, 0, 0);
|
||||
let { scriptBytes, compressedBytes } = compressedPayloadBytes(payload);
|
||||
if (compressedBytes <= maxCompressedBytes) return { payload, scriptBytes, compressedBytes };
|
||||
|
||||
const compactBundle = canonicalOfflineBundle({
|
||||
...completeBundle,
|
||||
groups: completeBundle.groups.map((group) => ({
|
||||
...group,
|
||||
occurrences: group.occurrences.slice(0, 20)
|
||||
})),
|
||||
candidate_sets: completeBundle.candidate_sets.map((candidateSet) => ({
|
||||
...candidateSet,
|
||||
candidates: candidateSet.candidates.slice(0, 20)
|
||||
}))
|
||||
});
|
||||
let omittedGroupCount = 0;
|
||||
let omittedCandidateSetCount = 0;
|
||||
const refresh = () => {
|
||||
payload = offlinePayload(summary, compactBundle, true, omittedGroupCount, omittedCandidateSetCount);
|
||||
({ scriptBytes, compressedBytes } = compressedPayloadBytes(payload));
|
||||
return compressedBytes <= maxCompressedBytes;
|
||||
};
|
||||
if (refresh()) return { payload, scriptBytes, compressedBytes };
|
||||
|
||||
for (let index = compactBundle.groups.length - 1; index >= 0; index -= 1) {
|
||||
while (compactBundle.groups[index].occurrences.length > 0) {
|
||||
compactBundle.groups[index].occurrences.pop();
|
||||
if (refresh()) return { payload, scriptBytes, compressedBytes };
|
||||
}
|
||||
}
|
||||
for (let index = compactBundle.candidate_sets.length - 1; index >= 0; index -= 1) {
|
||||
while (compactBundle.candidate_sets[index].candidates.length > 0) {
|
||||
compactBundle.candidate_sets[index].candidates.pop();
|
||||
if (refresh()) return { payload, scriptBytes, compressedBytes };
|
||||
}
|
||||
}
|
||||
|
||||
while (compactBundle.groups.length > 0) {
|
||||
compactBundle.groups.pop();
|
||||
omittedGroupCount += 1;
|
||||
if (refresh()) return { payload, scriptBytes, compressedBytes };
|
||||
}
|
||||
while (compactBundle.candidate_sets.length > 0) {
|
||||
compactBundle.candidate_sets.pop();
|
||||
omittedCandidateSetCount += 1;
|
||||
if (refresh()) return { payload, scriptBytes, compressedBytes };
|
||||
}
|
||||
if (!refresh()) {
|
||||
throw new Error("offline warning summary exceeds the compressed payload limit");
|
||||
}
|
||||
return { payload, scriptBytes, compressedBytes };
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
DEFAULT_WARNING_DETAILS_REF,
|
||||
OFFLINE_WARNING_LIMIT_BYTES,
|
||||
assembleGraphArtifactPair,
|
||||
canonicalWarningDetailBytes,
|
||||
commitGraphArtifactPair,
|
||||
prepareOfflineWarningPayload,
|
||||
serializeJsonForHtmlScript,
|
||||
verifyGraphArtifactPair
|
||||
};
|
||||
158
llm-wiki/scripts/lib/source-signal-eligibility.js
Normal file
158
llm-wiki/scripts/lib/source-signal-eligibility.js
Normal file
@@ -0,0 +1,158 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const SCAN_KINDS = [
|
||||
{ subdir: "entities", pageType: "entity", applicable: true },
|
||||
{ subdir: "topics", pageType: "topic", applicable: true },
|
||||
{ subdir: "sources", pageType: "source", applicable: true },
|
||||
{ subdir: "comparisons", pageType: "comparison", applicable: true },
|
||||
{ subdir: "queries", pageType: "query", applicable: false },
|
||||
{ subdir: "synthesis", pageType: "synthesis", applicable: false }
|
||||
];
|
||||
|
||||
function sortedUnique(values) {
|
||||
return Array.from(new Set(values)).sort();
|
||||
}
|
||||
|
||||
function extractFrontmatter(text) {
|
||||
if (!text.startsWith("---\n") && !text.startsWith("---\r\n")) {
|
||||
return { hasFrontmatter: false, frontmatter: "", body: text };
|
||||
}
|
||||
|
||||
const match = text.match(/^---\r?\n([\s\S]*?)\r?\n---(?:\r?\n|$)([\s\S]*)$/);
|
||||
if (!match) {
|
||||
return { hasFrontmatter: false, frontmatter: "", body: text };
|
||||
}
|
||||
|
||||
return {
|
||||
hasFrontmatter: true,
|
||||
frontmatter: match[1],
|
||||
body: match[2]
|
||||
};
|
||||
}
|
||||
|
||||
function normalizeSourceToken(token) {
|
||||
const trimmed = String(token || "").trim();
|
||||
if (!trimmed) return null;
|
||||
|
||||
let value = trimmed;
|
||||
if ((value.startsWith('"') && value.endsWith('"')) || (value.startsWith("'") && value.endsWith("'"))) {
|
||||
value = value.slice(1, -1).trim();
|
||||
}
|
||||
|
||||
return value || null;
|
||||
}
|
||||
|
||||
function parseInlineSources(raw) {
|
||||
const trimmed = raw.trim();
|
||||
if (trimmed === "[]") return { ok: true, values: [] };
|
||||
if (!(trimmed.startsWith("[") && trimmed.endsWith("]"))) {
|
||||
return { ok: false, values: [] };
|
||||
}
|
||||
|
||||
const inner = trimmed.slice(1, -1).trim();
|
||||
if (!inner) return { ok: true, values: [] };
|
||||
|
||||
const values = inner
|
||||
.split(",")
|
||||
.map(normalizeSourceToken)
|
||||
.filter(Boolean);
|
||||
|
||||
return { ok: true, values };
|
||||
}
|
||||
|
||||
function parseSourcesFrontmatter(frontmatter) {
|
||||
if (!frontmatter) {
|
||||
return { hasField: false, parsed: false, sources: [], signalAvailable: false };
|
||||
}
|
||||
|
||||
const lines = frontmatter.split(/\r?\n/);
|
||||
|
||||
for (let index = 0; index < lines.length; index += 1) {
|
||||
const match = lines[index].match(/^sources:\s*(.*)$/);
|
||||
if (!match) continue;
|
||||
|
||||
const rest = match[1].trim();
|
||||
if (rest) {
|
||||
if (!rest.startsWith("[")) {
|
||||
const single = normalizeSourceToken(rest);
|
||||
return {
|
||||
hasField: true,
|
||||
parsed: Boolean(single),
|
||||
sources: single ? [single] : [],
|
||||
signalAvailable: Boolean(single)
|
||||
};
|
||||
}
|
||||
|
||||
const parsedInline = parseInlineSources(rest);
|
||||
return {
|
||||
hasField: true,
|
||||
parsed: parsedInline.ok,
|
||||
sources: parsedInline.ok ? sortedUnique(parsedInline.values) : [],
|
||||
signalAvailable: parsedInline.ok && parsedInline.values.length > 0
|
||||
};
|
||||
}
|
||||
|
||||
const collected = [];
|
||||
let parsed = true;
|
||||
let consumed = 0;
|
||||
|
||||
for (let cursor = index + 1; cursor < lines.length; cursor += 1) {
|
||||
const line = lines[cursor];
|
||||
if (!line.trim()) {
|
||||
consumed += 1;
|
||||
continue;
|
||||
}
|
||||
if (/^[^\s-]/.test(line)) break;
|
||||
const itemMatch = line.match(/^\s*-\s*(.+)$/);
|
||||
if (!itemMatch) {
|
||||
parsed = false;
|
||||
consumed += 1;
|
||||
continue;
|
||||
}
|
||||
const token = normalizeSourceToken(itemMatch[1]);
|
||||
if (token) collected.push(token);
|
||||
consumed += 1;
|
||||
}
|
||||
|
||||
index += consumed;
|
||||
return {
|
||||
hasField: true,
|
||||
parsed,
|
||||
sources: parsed ? sortedUnique(collected) : [],
|
||||
signalAvailable: parsed && collected.length > 0
|
||||
};
|
||||
}
|
||||
|
||||
return { hasField: false, parsed: false, sources: [], signalAvailable: false };
|
||||
}
|
||||
|
||||
function evaluateSourceSignalEligibility({ pageType, frontmatter }) {
|
||||
const kind = SCAN_KINDS.find((k) => k.pageType === pageType);
|
||||
if (!kind || !kind.applicable) {
|
||||
return { eligible: false, reason: "not_applicable", sources: [] };
|
||||
}
|
||||
|
||||
const parsed = parseSourcesFrontmatter(frontmatter);
|
||||
|
||||
if (!parsed.hasField) {
|
||||
return { eligible: false, reason: "missing_sources", sources: [] };
|
||||
}
|
||||
if (!parsed.parsed) {
|
||||
return { eligible: false, reason: "invalid_sources", sources: [] };
|
||||
}
|
||||
if (parsed.sources.length === 0) {
|
||||
return { eligible: false, reason: "empty_sources", sources: [] };
|
||||
}
|
||||
|
||||
return { eligible: true, reason: "ok", sources: parsed.sources };
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
SCAN_KINDS,
|
||||
extractFrontmatter,
|
||||
evaluateSourceSignalEligibility,
|
||||
normalizeSourceToken,
|
||||
parseSourcesFrontmatter,
|
||||
sortedUnique
|
||||
};
|
||||
68
llm-wiki/scripts/lib/unicode-case-folding.js
Normal file
68
llm-wiki/scripts/lib/unicode-case-folding.js
Normal file
@@ -0,0 +1,68 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
const { loadUnicode17NfcNormalizer } = require("./unicode-normalization");
|
||||
|
||||
const TABLE_PATH = path.join(__dirname, "../../deps/unicode/CaseFolding-17.0.0.txt");
|
||||
const EXPECTED_HASH = "ff8d8fefbf123574205085d6714c36149eb946d717a0c585c27f0f4ef58c4183";
|
||||
|
||||
let cached = null;
|
||||
|
||||
function sha256(buffer) {
|
||||
return crypto.createHash("sha256").update(buffer).digest("hex");
|
||||
}
|
||||
|
||||
function parseUnicode17CaseFolding(text, normalizeNfc = loadUnicode17NfcNormalizer()) {
|
||||
const mappings = new Map();
|
||||
|
||||
for (const rawLine of text.split(/\r?\n/)) {
|
||||
const line = rawLine.replace(/#.*/, "").trim();
|
||||
if (!line) continue;
|
||||
|
||||
const [sourceHex, status, targetHex] = line.split(";").map((part) => part.trim());
|
||||
if (status !== "C" && status !== "F") continue;
|
||||
|
||||
mappings.set(
|
||||
Number.parseInt(sourceHex, 16),
|
||||
targetHex
|
||||
.split(/\s+/)
|
||||
.filter(Boolean)
|
||||
.map((value) => String.fromCodePoint(Number.parseInt(value, 16)))
|
||||
.join("")
|
||||
);
|
||||
}
|
||||
|
||||
return (value) => {
|
||||
let folded = "";
|
||||
for (const character of normalizeNfc(String(value))) {
|
||||
folded += mappings.get(character.codePointAt(0)) || character;
|
||||
}
|
||||
return normalizeNfc(folded);
|
||||
};
|
||||
}
|
||||
|
||||
function loadUnicode17CaseFolder() {
|
||||
if (cached) return cached;
|
||||
|
||||
const content = fs.readFileSync(TABLE_PATH);
|
||||
if (sha256(content) !== EXPECTED_HASH) {
|
||||
throw new Error(`Unicode runtime data hash mismatch for ${path.basename(TABLE_PATH)}`);
|
||||
}
|
||||
|
||||
cached = parseUnicode17CaseFolding(content.toString("utf8"));
|
||||
return cached;
|
||||
}
|
||||
|
||||
function defaultCaseFoldUnicode17(value) {
|
||||
return loadUnicode17CaseFolder()(value);
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
TABLE_PATH,
|
||||
defaultCaseFoldUnicode17,
|
||||
loadUnicode17CaseFolder,
|
||||
parseUnicode17CaseFolding
|
||||
};
|
||||
362
llm-wiki/scripts/lib/unicode-normalization.js
Normal file
362
llm-wiki/scripts/lib/unicode-normalization.js
Normal file
@@ -0,0 +1,362 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
|
||||
const UNICODE_DATA_PATH = path.join(__dirname, "../../deps/unicode/UnicodeData-17.0.0.txt");
|
||||
const DERIVED_NORMALIZATION_PROPS_PATH = path.join(
|
||||
__dirname,
|
||||
"../../deps/unicode/DerivedNormalizationProps-17.0.0.txt"
|
||||
);
|
||||
|
||||
const EXPECTED_HASHES = {
|
||||
[UNICODE_DATA_PATH]: "2e1efc1dcb59c575eedf5ccae60f95229f706ee6d031835247d843c11d96470c",
|
||||
[DERIVED_NORMALIZATION_PROPS_PATH]: "71fd6a206a2c0cdd41feb6b7f656aa31091db45e9cedc926985d718397f9e488"
|
||||
};
|
||||
|
||||
const HANGUL = {
|
||||
SBase: 0xac00,
|
||||
LBase: 0x1100,
|
||||
VBase: 0x1161,
|
||||
TBase: 0x11a7,
|
||||
LCount: 19,
|
||||
VCount: 21,
|
||||
TCount: 28
|
||||
};
|
||||
HANGUL.NCount = HANGUL.VCount * HANGUL.TCount;
|
||||
HANGUL.SCount = HANGUL.LCount * HANGUL.NCount;
|
||||
|
||||
let cachedTables = null;
|
||||
let cachedNormalizer = null;
|
||||
|
||||
function sha256(buffer) {
|
||||
return crypto.createHash("sha256").update(buffer).digest("hex");
|
||||
}
|
||||
|
||||
function verifyRuntimeFile(filePath) {
|
||||
const actualHash = sha256(fs.readFileSync(filePath));
|
||||
const expectedHash = EXPECTED_HASHES[filePath];
|
||||
|
||||
if (actualHash !== expectedHash) {
|
||||
throw new Error(`Unicode runtime data hash mismatch for ${path.basename(filePath)}`);
|
||||
}
|
||||
}
|
||||
|
||||
function parseCodePointRange(rangeText) {
|
||||
const [startHex, endHex] = rangeText.split("..");
|
||||
return {
|
||||
start: Number.parseInt(startHex, 16),
|
||||
end: Number.parseInt(endHex || startHex, 16)
|
||||
};
|
||||
}
|
||||
|
||||
function expandRange(start, end, callback) {
|
||||
for (let codePoint = start; codePoint <= end; codePoint += 1) {
|
||||
callback(codePoint);
|
||||
}
|
||||
}
|
||||
|
||||
function parseDecomposition(rawField) {
|
||||
if (!rawField) return null;
|
||||
if (rawField.startsWith("<")) return null;
|
||||
return rawField.split(/\s+/).filter(Boolean).map((value) => Number.parseInt(value, 16));
|
||||
}
|
||||
|
||||
function pairKey(left, right) {
|
||||
return `${left}:${right}`;
|
||||
}
|
||||
|
||||
function lookupRangeValue(ranges, codePoint) {
|
||||
let low = 0;
|
||||
let high = ranges.length - 1;
|
||||
|
||||
while (low <= high) {
|
||||
const middle = Math.floor((low + high) / 2);
|
||||
const entry = ranges[middle];
|
||||
|
||||
if (codePoint < entry.start) {
|
||||
high = middle - 1;
|
||||
} else if (codePoint > entry.end) {
|
||||
low = middle + 1;
|
||||
} else {
|
||||
return entry.value;
|
||||
}
|
||||
}
|
||||
|
||||
return 0;
|
||||
}
|
||||
|
||||
function getCanonicalCombiningClass(tables, codePoint) {
|
||||
return tables.combiningClasses.get(codePoint) || lookupRangeValue(tables.combiningClassRanges, codePoint);
|
||||
}
|
||||
|
||||
function isHangulSyllable(codePoint) {
|
||||
return codePoint >= HANGUL.SBase && codePoint < HANGUL.SBase + HANGUL.SCount;
|
||||
}
|
||||
|
||||
function isHangulL(codePoint) {
|
||||
return codePoint >= HANGUL.LBase && codePoint < HANGUL.LBase + HANGUL.LCount;
|
||||
}
|
||||
|
||||
function isHangulV(codePoint) {
|
||||
return codePoint >= HANGUL.VBase && codePoint < HANGUL.VBase + HANGUL.VCount;
|
||||
}
|
||||
|
||||
function isHangulT(codePoint) {
|
||||
return codePoint > HANGUL.TBase && codePoint < HANGUL.TBase + HANGUL.TCount;
|
||||
}
|
||||
|
||||
function decomposeHangul(codePoint) {
|
||||
const sIndex = codePoint - HANGUL.SBase;
|
||||
const lIndex = Math.floor(sIndex / HANGUL.NCount);
|
||||
const vIndex = Math.floor((sIndex % HANGUL.NCount) / HANGUL.TCount);
|
||||
const tIndex = sIndex % HANGUL.TCount;
|
||||
|
||||
const result = [
|
||||
HANGUL.LBase + lIndex,
|
||||
HANGUL.VBase + vIndex
|
||||
];
|
||||
|
||||
if (tIndex !== 0) {
|
||||
result.push(HANGUL.TBase + tIndex);
|
||||
}
|
||||
|
||||
return result;
|
||||
}
|
||||
|
||||
function composeHangul(left, right) {
|
||||
if (isHangulL(left) && isHangulV(right)) {
|
||||
const lIndex = left - HANGUL.LBase;
|
||||
const vIndex = right - HANGUL.VBase;
|
||||
return HANGUL.SBase + (lIndex * HANGUL.NCount) + (vIndex * HANGUL.TCount);
|
||||
}
|
||||
|
||||
if (
|
||||
isHangulSyllable(left)
|
||||
&& ((left - HANGUL.SBase) % HANGUL.TCount === 0)
|
||||
&& isHangulT(right)
|
||||
) {
|
||||
return left + (right - HANGUL.TBase);
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
function parseUnicode17NormalizationData(unicodeDataText, derivedPropsText) {
|
||||
const combiningClasses = new Map();
|
||||
const combiningClassRanges = [];
|
||||
const canonicalDecompositions = new Map();
|
||||
const compositionExclusions = new Set();
|
||||
const compositionMap = new Map();
|
||||
|
||||
let pendingRange = null;
|
||||
|
||||
for (const rawLine of unicodeDataText.split(/\r?\n/)) {
|
||||
if (!rawLine) continue;
|
||||
const fields = rawLine.split(";");
|
||||
if (fields.length < 6) continue;
|
||||
|
||||
const codePoint = Number.parseInt(fields[0], 16);
|
||||
const name = fields[1];
|
||||
const canonicalCombiningClass = Number.parseInt(fields[3], 10) || 0;
|
||||
const decomposition = parseDecomposition(fields[5]);
|
||||
|
||||
if (name.endsWith(", First>")) {
|
||||
pendingRange = {
|
||||
start: codePoint,
|
||||
combiningClass: canonicalCombiningClass,
|
||||
decomposition
|
||||
};
|
||||
continue;
|
||||
}
|
||||
|
||||
if (name.endsWith(", Last>") && pendingRange) {
|
||||
if (pendingRange.combiningClass !== 0) {
|
||||
combiningClassRanges.push({
|
||||
start: pendingRange.start,
|
||||
end: codePoint,
|
||||
value: pendingRange.combiningClass
|
||||
});
|
||||
}
|
||||
|
||||
if (pendingRange.decomposition) {
|
||||
expandRange(pendingRange.start, codePoint, (rangeCodePoint) => {
|
||||
canonicalDecompositions.set(rangeCodePoint, pendingRange.decomposition);
|
||||
});
|
||||
}
|
||||
|
||||
pendingRange = null;
|
||||
continue;
|
||||
}
|
||||
|
||||
if (canonicalCombiningClass !== 0) {
|
||||
combiningClasses.set(codePoint, canonicalCombiningClass);
|
||||
}
|
||||
if (decomposition) {
|
||||
canonicalDecompositions.set(codePoint, decomposition);
|
||||
}
|
||||
}
|
||||
|
||||
combiningClassRanges.sort((left, right) => left.start - right.start);
|
||||
|
||||
for (const rawLine of derivedPropsText.split(/\r?\n/)) {
|
||||
const line = rawLine.replace(/#.*/, "").trim();
|
||||
if (!line) continue;
|
||||
|
||||
const [rangeText, property] = line.split(";").map((part) => part.trim());
|
||||
if (property !== "Full_Composition_Exclusion") continue;
|
||||
|
||||
const { start, end } = parseCodePointRange(rangeText);
|
||||
expandRange(start, end, (codePoint) => {
|
||||
compositionExclusions.add(codePoint);
|
||||
});
|
||||
}
|
||||
|
||||
for (const [composite, decomposition] of canonicalDecompositions.entries()) {
|
||||
if (compositionExclusions.has(composite)) continue;
|
||||
if (decomposition.length !== 2) continue;
|
||||
compositionMap.set(pairKey(decomposition[0], decomposition[1]), composite);
|
||||
}
|
||||
|
||||
return Object.freeze({
|
||||
combiningClasses,
|
||||
combiningClassRanges,
|
||||
canonicalDecompositions,
|
||||
compositionExclusions,
|
||||
compositionMap
|
||||
});
|
||||
}
|
||||
|
||||
function recursivelyDecompose(codePoint, tables, output) {
|
||||
if (isHangulSyllable(codePoint)) {
|
||||
for (const part of decomposeHangul(codePoint)) {
|
||||
recursivelyDecompose(part, tables, output);
|
||||
}
|
||||
return;
|
||||
}
|
||||
|
||||
const decomposition = tables.canonicalDecompositions.get(codePoint);
|
||||
if (!decomposition) {
|
||||
output.push(codePoint);
|
||||
return;
|
||||
}
|
||||
|
||||
for (const part of decomposition) {
|
||||
recursivelyDecompose(part, tables, output);
|
||||
}
|
||||
}
|
||||
|
||||
function reorderSegment(segment, combiningClasses) {
|
||||
if (segment.length <= 1) return segment;
|
||||
|
||||
const starterCount = combiningClasses[0] === 0 ? 1 : 0;
|
||||
const head = segment.slice(0, starterCount);
|
||||
const marks = segment.slice(starterCount).map((codePoint, index) => ({
|
||||
codePoint,
|
||||
ccc: combiningClasses[starterCount + index],
|
||||
index
|
||||
}));
|
||||
|
||||
marks.sort((left, right) => {
|
||||
if (left.ccc !== right.ccc) return left.ccc - right.ccc;
|
||||
return left.index - right.index;
|
||||
});
|
||||
|
||||
return head.concat(marks.map((item) => item.codePoint));
|
||||
}
|
||||
|
||||
function canonicalOrder(codePoints, tables) {
|
||||
const ordered = [];
|
||||
let segment = [];
|
||||
let classes = [];
|
||||
|
||||
function flush() {
|
||||
if (segment.length === 0) return;
|
||||
ordered.push(...reorderSegment(segment, classes));
|
||||
segment = [];
|
||||
classes = [];
|
||||
}
|
||||
|
||||
for (const codePoint of codePoints) {
|
||||
const ccc = getCanonicalCombiningClass(tables, codePoint);
|
||||
if (ccc === 0 && segment.length > 0) {
|
||||
flush();
|
||||
}
|
||||
segment.push(codePoint);
|
||||
classes.push(ccc);
|
||||
}
|
||||
|
||||
flush();
|
||||
return ordered;
|
||||
}
|
||||
|
||||
function recompose(codePoints, tables) {
|
||||
if (codePoints.length === 0) return [];
|
||||
|
||||
const result = [codePoints[0]];
|
||||
let starterIndex = getCanonicalCombiningClass(tables, codePoints[0]) === 0 ? 0 : -1;
|
||||
let starter = starterIndex === 0 ? codePoints[0] : null;
|
||||
let lastCombiningClass = getCanonicalCombiningClass(tables, codePoints[0]);
|
||||
|
||||
for (let index = 1; index < codePoints.length; index += 1) {
|
||||
const codePoint = codePoints[index];
|
||||
const combiningClass = getCanonicalCombiningClass(tables, codePoint);
|
||||
let composite = null;
|
||||
|
||||
if (starter !== null) {
|
||||
composite = composeHangul(starter, codePoint) || tables.compositionMap.get(pairKey(starter, codePoint)) || null;
|
||||
}
|
||||
|
||||
if (composite !== null && (lastCombiningClass < combiningClass || lastCombiningClass === 0)) {
|
||||
result[starterIndex] = composite;
|
||||
starter = composite;
|
||||
continue;
|
||||
}
|
||||
|
||||
result.push(codePoint);
|
||||
lastCombiningClass = combiningClass;
|
||||
|
||||
if (combiningClass === 0) {
|
||||
starterIndex = result.length - 1;
|
||||
starter = codePoint;
|
||||
}
|
||||
}
|
||||
|
||||
return result;
|
||||
}
|
||||
|
||||
function normalizeNfcUnicode17(value, tables) {
|
||||
const input = String(value);
|
||||
const decomposed = [];
|
||||
|
||||
for (const character of input) {
|
||||
recursivelyDecompose(character.codePointAt(0), tables, decomposed);
|
||||
}
|
||||
|
||||
const ordered = canonicalOrder(decomposed, tables);
|
||||
return String.fromCodePoint(...recompose(ordered, tables));
|
||||
}
|
||||
|
||||
function loadUnicode17NfcNormalizer() {
|
||||
if (cachedNormalizer) return cachedNormalizer;
|
||||
|
||||
verifyRuntimeFile(UNICODE_DATA_PATH);
|
||||
verifyRuntimeFile(DERIVED_NORMALIZATION_PROPS_PATH);
|
||||
|
||||
cachedTables ||= parseUnicode17NormalizationData(
|
||||
fs.readFileSync(UNICODE_DATA_PATH, "utf8"),
|
||||
fs.readFileSync(DERIVED_NORMALIZATION_PROPS_PATH, "utf8")
|
||||
);
|
||||
cachedNormalizer = (value) => normalizeNfcUnicode17(value, cachedTables);
|
||||
return cachedNormalizer;
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
DERIVED_NORMALIZATION_PROPS_PATH,
|
||||
UNICODE_DATA_PATH,
|
||||
loadUnicode17NfcNormalizer,
|
||||
normalizeNfcUnicode17,
|
||||
parseUnicode17NormalizationData
|
||||
};
|
||||
204
llm-wiki/scripts/lib/wiki-file-discovery.js
Normal file
204
llm-wiki/scripts/lib/wiki-file-discovery.js
Normal file
@@ -0,0 +1,204 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
|
||||
const GRAPH_PAGE_TYPES = Object.freeze({
|
||||
entities: "entity",
|
||||
topics: "topic",
|
||||
sources: "source",
|
||||
comparisons: "comparison",
|
||||
synthesis: "synthesis",
|
||||
queries: "query"
|
||||
});
|
||||
|
||||
const ROOT_EDITABLE_MARKDOWN = new Set(["index.md", "log.md", "purpose.md"]);
|
||||
const EXCLUDED_DIRECTORY_NAMES = new Set([".obsidian", ".git", ".wiki-tmp", "node_modules"]);
|
||||
const EXCLUDED_BASENAMES = new Set(["graph-data.json", "graph-warnings.json"]);
|
||||
|
||||
function sha256(text) {
|
||||
return crypto.createHash("sha256").update(text).digest("hex");
|
||||
}
|
||||
|
||||
function normalizeRelativePosixPath(pathValue) {
|
||||
const value = String(pathValue || "").replaceAll("\\", "/");
|
||||
if (!value) {
|
||||
throw new Error("Path must not be empty");
|
||||
}
|
||||
if (value.startsWith("/")) {
|
||||
throw new Error("Path must be relative");
|
||||
}
|
||||
|
||||
const normalized = path.posix.normalize(value);
|
||||
if (
|
||||
normalized === "."
|
||||
|| normalized === ".."
|
||||
|| normalized.startsWith("../")
|
||||
|| normalized.includes("/../")
|
||||
) {
|
||||
throw new Error("Path escapes knowledge-base root");
|
||||
}
|
||||
|
||||
return normalized.replace(/^\.\//, "");
|
||||
}
|
||||
|
||||
function isWithinRoot(rootRealPath, candidateAbsolutePath) {
|
||||
return candidateAbsolutePath === rootRealPath || candidateAbsolutePath.startsWith(`${rootRealPath}${path.sep}`);
|
||||
}
|
||||
|
||||
function resolveInsideKnowledgeBase(kbRoot, relativePath) {
|
||||
const rootRealPath = fs.realpathSync.native(kbRoot);
|
||||
const normalized = normalizeRelativePosixPath(relativePath);
|
||||
const absolutePath = path.resolve(rootRealPath, ...normalized.split("/"));
|
||||
|
||||
if (!isWithinRoot(rootRealPath, absolutePath)) {
|
||||
throw new Error(`Path escapes knowledge-base root: ${relativePath}`);
|
||||
}
|
||||
|
||||
return absolutePath;
|
||||
}
|
||||
|
||||
function isGeneratedArtifact(relativePath) {
|
||||
const basename = path.posix.basename(relativePath);
|
||||
if (EXCLUDED_BASENAMES.has(basename)) return true;
|
||||
return /^knowledge-graph(?:[^/]*)\.html$/i.test(basename);
|
||||
}
|
||||
|
||||
function isRenameStagingFile(relativePath) {
|
||||
return path.posix.basename(relativePath).startsWith(".llm-wiki-rename-");
|
||||
}
|
||||
|
||||
function isMarkdown(relativePath) {
|
||||
return relativePath.toLowerCase().endsWith(".md");
|
||||
}
|
||||
|
||||
function isAttachment(relativePath) {
|
||||
return !isMarkdown(relativePath);
|
||||
}
|
||||
|
||||
function graphTypeFor(relativePath) {
|
||||
const parts = relativePath.split("/");
|
||||
return parts[0] === "wiki" ? (GRAPH_PAGE_TYPES[parts[1]] || null) : null;
|
||||
}
|
||||
|
||||
function isGraphSource(relativePath) {
|
||||
return isMarkdown(relativePath) && graphTypeFor(relativePath) !== null;
|
||||
}
|
||||
|
||||
function isLintSource(relativePath) {
|
||||
return relativePath === "index.md" || (relativePath.startsWith("wiki/") && isMarkdown(relativePath));
|
||||
}
|
||||
|
||||
function isRenameEditableSource(relativePath) {
|
||||
return ROOT_EDITABLE_MARKDOWN.has(relativePath) || (relativePath.startsWith("wiki/") && isMarkdown(relativePath));
|
||||
}
|
||||
|
||||
function isRenameReadOnlySource(relativePath) {
|
||||
return isMarkdown(relativePath) && !isRenameEditableSource(relativePath);
|
||||
}
|
||||
|
||||
function fileSetSignature(items) {
|
||||
return sha256(items.map((item) => `${item.path}\0${item.kind}\0${item.size}\0${item.mtimeNs}`).join("\n"));
|
||||
}
|
||||
|
||||
function fileKindFor(relativePath) {
|
||||
return isMarkdown(relativePath) ? "markdown" : "attachment";
|
||||
}
|
||||
|
||||
function walkKnowledgeBase(rootRealPath, directoryAbsolutePath, results) {
|
||||
const entries = fs.readdirSync(directoryAbsolutePath, { withFileTypes: true })
|
||||
.sort((left, right) => left.name.localeCompare(right.name, "en"));
|
||||
|
||||
for (const entry of entries) {
|
||||
const absolutePath = path.join(directoryAbsolutePath, entry.name);
|
||||
const relativePath = path.relative(rootRealPath, absolutePath).split(path.sep).join("/");
|
||||
const topLevelName = relativePath.split("/")[0];
|
||||
|
||||
if (entry.isDirectory()) {
|
||||
if (
|
||||
entry.name.startsWith(".")
|
||||
|| EXCLUDED_DIRECTORY_NAMES.has(entry.name)
|
||||
|| EXCLUDED_DIRECTORY_NAMES.has(topLevelName)
|
||||
) {
|
||||
continue;
|
||||
}
|
||||
if (entry.isSymbolicLink && entry.isSymbolicLink()) {
|
||||
continue;
|
||||
}
|
||||
const resolvedDirectoryPath = fs.realpathSync.native(absolutePath);
|
||||
if (!isWithinRoot(rootRealPath, resolvedDirectoryPath)) {
|
||||
continue;
|
||||
}
|
||||
walkKnowledgeBase(rootRealPath, absolutePath, results);
|
||||
continue;
|
||||
}
|
||||
|
||||
if (entry.isSymbolicLink && entry.isSymbolicLink()) {
|
||||
continue;
|
||||
}
|
||||
if (!entry.isFile()) {
|
||||
continue;
|
||||
}
|
||||
if (EXCLUDED_DIRECTORY_NAMES.has(topLevelName)) {
|
||||
continue;
|
||||
}
|
||||
|
||||
const normalizedPath = normalizeRelativePosixPath(relativePath);
|
||||
if (entry.name.startsWith(".") && normalizedPath !== ".wiki-schema.md") {
|
||||
continue;
|
||||
}
|
||||
if (isGeneratedArtifact(normalizedPath) || isRenameStagingFile(normalizedPath)) {
|
||||
continue;
|
||||
}
|
||||
if (!isMarkdown(normalizedPath) && !isAttachment(normalizedPath)) {
|
||||
continue;
|
||||
}
|
||||
|
||||
const resolvedFilePath = fs.realpathSync.native(absolutePath);
|
||||
if (!isWithinRoot(rootRealPath, resolvedFilePath)) {
|
||||
continue;
|
||||
}
|
||||
|
||||
const stat = fs.statSync(absolutePath, { bigint: true });
|
||||
results.push({
|
||||
path: normalizedPath,
|
||||
absolutePath,
|
||||
kind: fileKindFor(normalizedPath),
|
||||
editable: isRenameEditableSource(normalizedPath),
|
||||
graphType: graphTypeFor(normalizedPath),
|
||||
size: Number(stat.size),
|
||||
mtimeNs: String(stat.mtimeNs)
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
function discoverKnowledgeBaseFiles(kbRoot) {
|
||||
const rootRealPath = fs.realpathSync.native(kbRoot);
|
||||
const inventory = [];
|
||||
walkKnowledgeBase(rootRealPath, rootRealPath, inventory);
|
||||
inventory.sort((left, right) => left.path.localeCompare(right.path, "en"));
|
||||
|
||||
const graphSources = inventory.filter((item) => item.kind === "markdown" && isGraphSource(item.path));
|
||||
const lintSources = inventory.filter((item) => item.kind === "markdown" && isLintSource(item.path));
|
||||
const renameEditableSources = inventory.filter((item) => item.kind === "markdown" && isRenameEditableSource(item.path));
|
||||
const renameReadOnlySources = inventory.filter((item) => item.kind === "markdown" && isRenameReadOnlySource(item.path));
|
||||
const targets = inventory.map(({ size, mtimeNs, ...item }) => item);
|
||||
|
||||
return {
|
||||
graphSources,
|
||||
lintSources,
|
||||
renameEditableSources,
|
||||
renameReadOnlySources,
|
||||
targets,
|
||||
fileSetSha256: fileSetSignature(inventory)
|
||||
};
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
GRAPH_PAGE_TYPES,
|
||||
discoverKnowledgeBaseFiles,
|
||||
normalizeRelativePosixPath,
|
||||
resolveInsideKnowledgeBase
|
||||
};
|
||||
452
llm-wiki/scripts/lib/wiki-link-index.js
Normal file
452
llm-wiki/scripts/lib/wiki-link-index.js
Normal file
@@ -0,0 +1,452 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
const { loadUnicode17CaseFolder } = require("./unicode-case-folding");
|
||||
const {
|
||||
validateGraphRenameFilenameSyntax
|
||||
} = require("../../packages/workbench-contracts/src/graph-rename-filename.js");
|
||||
const {
|
||||
discoverKnowledgeBaseFiles,
|
||||
normalizeRelativePosixPath
|
||||
} = require("./wiki-file-discovery");
|
||||
const { extractFrontmatter, parseSourcesFrontmatter } = require("./source-signal-eligibility");
|
||||
const { parseWikilinks, renderWikilinkReplacement } = require("./wikilink-parser");
|
||||
|
||||
function sha256(text) {
|
||||
return crypto.createHash("sha256").update(text).digest("hex");
|
||||
}
|
||||
|
||||
function stableId(prefix, value) {
|
||||
return `${prefix}-${sha256(value).slice(0, 16)}`;
|
||||
}
|
||||
|
||||
function portablePathKey(pathValue, fold = loadUnicode17CaseFolder()) {
|
||||
return fold(normalizeRelativePosixPath(pathValue));
|
||||
}
|
||||
|
||||
function buildWikiTargetIndex(inventory) {
|
||||
const exactPaths = new Map();
|
||||
const portablePaths = new Map();
|
||||
const portableBasenames = new Map();
|
||||
|
||||
for (const item of inventory) {
|
||||
exactPaths.set(item.path, item);
|
||||
|
||||
const pathKey = portablePathKey(item.path);
|
||||
const pathItems = portablePaths.get(pathKey) || [];
|
||||
pathItems.push(item);
|
||||
portablePaths.set(pathKey, pathItems);
|
||||
|
||||
if (item.kind === "markdown") {
|
||||
const basenameKey = portablePathKey(path.posix.basename(item.path, ".md"));
|
||||
const basenameItems = portableBasenames.get(basenameKey) || [];
|
||||
basenameItems.push(item);
|
||||
portableBasenames.set(basenameKey, basenameItems);
|
||||
}
|
||||
}
|
||||
|
||||
const portableCollisions = Array.from(portablePaths.values())
|
||||
.filter((items) => items.length > 1)
|
||||
.map((items) => {
|
||||
const candidates = items.map((item) => item.path).sort();
|
||||
return {
|
||||
collision_id: stableId("portable-collision", candidates.join("\n")),
|
||||
candidate_set_id: stableId("candidate-set", candidates.join("\n")),
|
||||
candidates
|
||||
};
|
||||
})
|
||||
.sort((left, right) => left.candidates.join("\n").localeCompare(right.candidates.join("\n"), "en"));
|
||||
|
||||
return { exactPaths, portablePaths, portableBasenames, portableCollisions };
|
||||
}
|
||||
|
||||
function normalizeExplicitTarget(target) {
|
||||
const normalized = normalizeRelativePosixPath(target);
|
||||
const extension = path.posix.extname(normalized);
|
||||
if (!extension) {
|
||||
return `${normalized}.md`;
|
||||
}
|
||||
return normalized;
|
||||
}
|
||||
|
||||
function warningSeverity(code) {
|
||||
if (code === "pending_wikilink" || code === "noncanonical_wikilink") {
|
||||
return "warning";
|
||||
}
|
||||
return "error";
|
||||
}
|
||||
|
||||
function resolveWikilink(occurrence, sourcePath, index) {
|
||||
if (occurrence.link_kind === "same_page_anchor") {
|
||||
return {
|
||||
status: "resolved",
|
||||
target_path: sourcePath,
|
||||
creates_edge: false,
|
||||
warning_code: null,
|
||||
candidate_paths: [],
|
||||
target_key: sourcePath
|
||||
};
|
||||
}
|
||||
|
||||
const rawTarget = occurrence.page_target;
|
||||
const explicitPath = rawTarget.includes("/") || occurrence.link_kind === "attachment_wikilink" || rawTarget.endsWith(".md");
|
||||
const targetKey = rawTarget ? normalizeRelativePosixPath(rawTarget) : sourcePath;
|
||||
|
||||
let candidates = [];
|
||||
let warningCode = null;
|
||||
|
||||
if (explicitPath) {
|
||||
const normalizedTarget = normalizeExplicitTarget(rawTarget);
|
||||
const exactMatch = index.exactPaths.get(normalizedTarget);
|
||||
if (exactMatch) {
|
||||
candidates = [exactMatch];
|
||||
} else {
|
||||
candidates = index.portablePaths.get(portablePathKey(normalizedTarget)) || [];
|
||||
if (candidates.length === 1) {
|
||||
warningCode = "noncanonical_wikilink";
|
||||
}
|
||||
}
|
||||
} else {
|
||||
const basename = rawTarget.replace(/\.md$/i, "");
|
||||
candidates = index.portableBasenames.get(portablePathKey(basename)) || [];
|
||||
}
|
||||
|
||||
if (candidates.length === 0) {
|
||||
return {
|
||||
status: "missing",
|
||||
target_path: null,
|
||||
creates_edge: false,
|
||||
warning_code: occurrence.pending ? "pending_wikilink" : (occurrence.link_kind === "attachment_wikilink" ? null : "broken_wikilink"),
|
||||
candidate_paths: [],
|
||||
target_key: targetKey
|
||||
};
|
||||
}
|
||||
|
||||
if (candidates.length > 1) {
|
||||
return {
|
||||
status: "ambiguous",
|
||||
target_path: null,
|
||||
creates_edge: false,
|
||||
warning_code: "ambiguous_wikilink",
|
||||
candidate_paths: candidates.map((item) => item.path).sort(),
|
||||
target_key: targetKey
|
||||
};
|
||||
}
|
||||
|
||||
const [target] = candidates;
|
||||
const createsEdge = Boolean(
|
||||
target.kind === "markdown"
|
||||
&& target.graphType
|
||||
&& target.path !== sourcePath
|
||||
&& occurrence.link_kind !== "attachment_wikilink"
|
||||
);
|
||||
|
||||
return {
|
||||
status: "resolved",
|
||||
target_path: target.path,
|
||||
creates_edge: createsEdge,
|
||||
warning_code: warningCode,
|
||||
candidate_paths: [],
|
||||
target_key: targetKey
|
||||
};
|
||||
}
|
||||
|
||||
function warningMessage(code, targetKey) {
|
||||
switch (code) {
|
||||
case "ambiguous_wikilink":
|
||||
return `Ambiguous wikilink: ${targetKey}`;
|
||||
case "broken_wikilink":
|
||||
return `Broken wikilink: ${targetKey}`;
|
||||
case "pending_wikilink":
|
||||
return `Pending wikilink: ${targetKey}`;
|
||||
case "noncanonical_wikilink":
|
||||
return `Noncanonical wikilink: ${targetKey}`;
|
||||
case "portable_path_collision":
|
||||
return "Portable path collision";
|
||||
default:
|
||||
return code;
|
||||
}
|
||||
}
|
||||
|
||||
function addWarningGroup(groupMap, candidateSetMap, code, resolution, occurrenceRecord) {
|
||||
const candidatePaths = resolution.candidate_paths || [];
|
||||
const candidateSetId = candidatePaths.length > 0
|
||||
? stableId("candidate-set", candidatePaths.join("\n"))
|
||||
: null;
|
||||
|
||||
if (candidateSetId && !candidateSetMap.has(candidateSetId)) {
|
||||
candidateSetMap.set(candidateSetId, {
|
||||
candidate_set_id: candidateSetId,
|
||||
candidate_count: candidatePaths.length,
|
||||
candidates: candidatePaths
|
||||
});
|
||||
}
|
||||
|
||||
const warningKey = `${code}\0${resolution.target_key || ""}\0${candidateSetId || ""}`;
|
||||
const warningId = stableId("warning", warningKey);
|
||||
if (!groupMap.has(warningId)) {
|
||||
groupMap.set(warningId, {
|
||||
warning_id: warningId,
|
||||
code,
|
||||
severity: warningSeverity(code),
|
||||
message: warningMessage(code, resolution.target_key || ""),
|
||||
target_key: resolution.target_key || undefined,
|
||||
candidate_set_id: candidateSetId || undefined,
|
||||
occurrence_count: 0,
|
||||
occurrences: []
|
||||
});
|
||||
}
|
||||
|
||||
const group = groupMap.get(warningId);
|
||||
group.occurrence_count += 1;
|
||||
group.occurrences.push(occurrenceRecord);
|
||||
}
|
||||
|
||||
function scanPolicySources(inventory, policy) {
|
||||
if (policy === "graph") return inventory.graphSources;
|
||||
if (policy === "lint") return inventory.lintSources;
|
||||
if (policy === "rename") {
|
||||
return inventory.renameEditableSources.concat(inventory.renameReadOnlySources)
|
||||
.sort((left, right) => left.path.localeCompare(right.path, "en"));
|
||||
}
|
||||
throw new Error(`Unknown scan policy: ${policy}`);
|
||||
}
|
||||
|
||||
function parseImagePaths(frontmatter) {
|
||||
if (!frontmatter) return [];
|
||||
const lines = frontmatter.split(/\r?\n/);
|
||||
for (let index = 0; index < lines.length; index += 1) {
|
||||
const match = lines[index].match(/^image_paths:\s*(.*)$/);
|
||||
if (!match) continue;
|
||||
const inline = match[1].trim();
|
||||
if (inline) {
|
||||
if (inline === "[]") return [];
|
||||
if (!inline.startsWith("[") || !inline.endsWith("]")) return [];
|
||||
return inline.slice(1, -1).split(",")
|
||||
.map((value) => value.trim().replace(/^['"]|['"]$/g, ""))
|
||||
.filter(Boolean);
|
||||
}
|
||||
const values = [];
|
||||
for (let cursor = index + 1; cursor < lines.length; cursor += 1) {
|
||||
if (!lines[cursor].trim()) continue;
|
||||
const item = lines[cursor].match(/^\s*-\s*(.+?)\s*$/);
|
||||
if (!item) break;
|
||||
values.push(item[1].trim().replace(/^['"]|['"]$/g, ""));
|
||||
}
|
||||
return values.filter(Boolean);
|
||||
}
|
||||
return [];
|
||||
}
|
||||
|
||||
function scanKnowledgeBaseLinks(kbRoot, policy) {
|
||||
const inventory = discoverKnowledgeBaseFiles(kbRoot);
|
||||
const index = buildWikiTargetIndex(inventory.targets);
|
||||
const sources = scanPolicySources(inventory, policy);
|
||||
const candidateSetMap = new Map();
|
||||
const groupMap = new Map();
|
||||
const occurrences = [];
|
||||
const edges = [];
|
||||
const sourceDocuments = [];
|
||||
const stalePendingWrappers = [];
|
||||
const edgeByEndpoints = new Map();
|
||||
const metrics = {
|
||||
inventory_walks: 1,
|
||||
target_index_builds: 1,
|
||||
source_files_parsed: 0,
|
||||
files_read: 0,
|
||||
files_parsed: 0,
|
||||
graph_source_bytes: 0,
|
||||
utf8_bytes_scanned: 0,
|
||||
position_bytes_advanced: 0
|
||||
};
|
||||
|
||||
for (const collision of index.portableCollisions) {
|
||||
candidateSetMap.set(collision.candidate_set_id, {
|
||||
candidate_set_id: collision.candidate_set_id,
|
||||
candidate_count: collision.candidates.length,
|
||||
candidates: collision.candidates
|
||||
});
|
||||
groupMap.set(collision.collision_id, {
|
||||
warning_id: collision.collision_id,
|
||||
code: "portable_path_collision",
|
||||
severity: "error",
|
||||
message: "Portable path collision",
|
||||
id: collision.collision_id,
|
||||
candidate_set_id: collision.candidate_set_id,
|
||||
occurrence_count: 0,
|
||||
occurrences: []
|
||||
});
|
||||
}
|
||||
|
||||
for (const source of sources) {
|
||||
const buffer = fs.readFileSync(source.absolutePath);
|
||||
const rawContent = buffer.toString("utf8");
|
||||
const frontmatter = extractFrontmatter(rawContent);
|
||||
const parsedSources = parseSourcesFrontmatter(frontmatter.frontmatter);
|
||||
const heading = frontmatter.body.match(/^#\s+(.+?)\s*$/m);
|
||||
sourceDocuments.push({
|
||||
source_path: source.path,
|
||||
graph_type: source.graphType,
|
||||
label: heading ? heading[1].trim() : path.posix.basename(source.path, ".md"),
|
||||
_content: rawContent,
|
||||
_signals: {
|
||||
sources: parsedSources.sources,
|
||||
sourceSignalAvailable: parsedSources.signalAvailable,
|
||||
sourceFieldPresent: parsedSources.hasField,
|
||||
sourceFieldParsed: parsedSources.parsed,
|
||||
imagePaths: parseImagePaths(frontmatter.frontmatter)
|
||||
}
|
||||
});
|
||||
metrics.files_read += 1;
|
||||
metrics.files_parsed += 1;
|
||||
metrics.source_files_parsed += 1;
|
||||
if (source.graphType) metrics.graph_source_bytes += buffer.length;
|
||||
|
||||
const parsed = parseWikilinks(buffer, source.path);
|
||||
metrics.utf8_bytes_scanned += parsed.metrics.utf8_bytes_scanned;
|
||||
metrics.position_bytes_advanced += parsed.metrics.position_bytes_advanced;
|
||||
for (const occurrence of parsed.occurrences) {
|
||||
const resolution = resolveWikilink(occurrence, source.path, index);
|
||||
const resolutionCandidateSetId = resolution.candidate_paths.length > 0
|
||||
? stableId("candidate-set", resolution.candidate_paths.join("\n"))
|
||||
: null;
|
||||
const occurrenceRecord = {
|
||||
occurrence_id: stableId(
|
||||
"occurrence",
|
||||
`${occurrence.source_path}\0${occurrence.file_sha256}\0${occurrence.start_byte}\0${occurrence.end_byte}\0${occurrence.raw_link}`
|
||||
),
|
||||
source_path: occurrence.source_path,
|
||||
line: occurrence.line,
|
||||
column: occurrence.column,
|
||||
start_byte: occurrence.start_byte,
|
||||
end_byte: occurrence.end_byte,
|
||||
raw_link: occurrence.raw_link,
|
||||
file_sha256: occurrence.file_sha256,
|
||||
link_kind: occurrence.link_kind,
|
||||
read_only: source.editable === false
|
||||
};
|
||||
|
||||
occurrences.push({
|
||||
...occurrence,
|
||||
read_only: source.editable === false,
|
||||
resolution: {
|
||||
...resolution,
|
||||
candidate_paths: undefined,
|
||||
candidate_set_id: resolutionCandidateSetId || undefined
|
||||
}
|
||||
});
|
||||
|
||||
if (occurrence.pending && resolution.status === "resolved") {
|
||||
stalePendingWrappers.push({
|
||||
source_path: source.path,
|
||||
raw_link: occurrence.raw_link,
|
||||
replacement: renderWikilinkReplacement(occurrence, occurrence.page_target)
|
||||
});
|
||||
} else if (resolution.warning_code) {
|
||||
addWarningGroup(groupMap, candidateSetMap, resolution.warning_code, resolution, occurrenceRecord);
|
||||
}
|
||||
|
||||
if (resolution.creates_edge && resolution.target_path) {
|
||||
const edgeKey = `${source.path}\0${resolution.target_path}`;
|
||||
if (!edgeByEndpoints.has(edgeKey)) {
|
||||
const edge = {
|
||||
from: source.path,
|
||||
to: resolution.target_path,
|
||||
relation_type: occurrence.relation_type || "依赖",
|
||||
confidence: occurrence.confidence || "EXTRACTED",
|
||||
_relation_explicit: Boolean(occurrence.relation_type),
|
||||
_confidence_explicit: Boolean(occurrence.confidence)
|
||||
};
|
||||
edgeByEndpoints.set(edgeKey, edge);
|
||||
edges.push(edge);
|
||||
} else {
|
||||
const edge = edgeByEndpoints.get(edgeKey);
|
||||
if (!edge._confidence_explicit && occurrence.confidence) {
|
||||
edge.confidence = occurrence.confidence;
|
||||
edge._confidence_explicit = true;
|
||||
}
|
||||
if (!edge._relation_explicit && occurrence.relation_type) {
|
||||
edge.relation_type = occurrence.relation_type;
|
||||
edge._relation_explicit = true;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
const candidate_sets = Array.from(candidateSetMap.values())
|
||||
.sort((left, right) => left.candidate_set_id.localeCompare(right.candidate_set_id, "en"));
|
||||
const groups = Array.from(groupMap.values())
|
||||
.map((group) => ({
|
||||
...group,
|
||||
occurrences: group.occurrences.slice().sort((left, right) => {
|
||||
if (left.source_path !== right.source_path) {
|
||||
return left.source_path.localeCompare(right.source_path, "en");
|
||||
}
|
||||
return left.start_byte - right.start_byte;
|
||||
})
|
||||
}))
|
||||
.sort((left, right) => left.warning_id.localeCompare(right.warning_id, "en"));
|
||||
|
||||
edges.sort((left, right) => {
|
||||
const leftKey = `${left.from}\0${left.to}\0${left.relation_type}`;
|
||||
const rightKey = `${right.from}\0${right.to}\0${right.relation_type}`;
|
||||
return leftKey.localeCompare(rightKey, "en");
|
||||
});
|
||||
for (const edge of edges) {
|
||||
delete edge._confidence_explicit;
|
||||
delete edge._relation_explicit;
|
||||
}
|
||||
|
||||
stalePendingWrappers.sort((left, right) => left.source_path.localeCompare(right.source_path, "en"));
|
||||
|
||||
return {
|
||||
inventory,
|
||||
edges,
|
||||
candidate_sets,
|
||||
groups,
|
||||
occurrences: policy === "graph" ? [] : occurrences,
|
||||
source_documents: sourceDocuments,
|
||||
stale_pending_wrappers: stalePendingWrappers,
|
||||
metrics
|
||||
};
|
||||
}
|
||||
|
||||
function validatePortableMarkdownFilename(sourcePath, newName, inventoryOrTargets) {
|
||||
const targets = Array.isArray(inventoryOrTargets)
|
||||
? inventoryOrTargets
|
||||
: inventoryOrTargets.targets;
|
||||
const syntax = validateGraphRenameFilenameSyntax(String(newName ?? ""));
|
||||
if (!syntax.ok) return syntax;
|
||||
const normalizedName = syntax.normalized_name;
|
||||
|
||||
const sourceDir = path.posix.dirname(sourcePath);
|
||||
const targetPath = sourceDir === "." ? normalizedName : `${sourceDir}/${normalizedName}`;
|
||||
const targetPortableKey = portablePathKey(targetPath);
|
||||
const collisions = targets
|
||||
.filter((item) => item.path !== sourcePath && portablePathKey(item.path) === targetPortableKey)
|
||||
.map((item) => item.path)
|
||||
.sort();
|
||||
|
||||
if (collisions.length > 0) {
|
||||
return { ok: false, reason: "portable_path_collision", collision_paths: collisions };
|
||||
}
|
||||
|
||||
return {
|
||||
ok: true,
|
||||
normalized_name: normalizedName,
|
||||
target_path: targetPath,
|
||||
requires_transit: portablePathKey(sourcePath) === targetPortableKey && sourcePath !== targetPath
|
||||
};
|
||||
}
|
||||
|
||||
module.exports = {
|
||||
buildWikiTargetIndex,
|
||||
portablePathKey,
|
||||
resolveWikilink,
|
||||
scanKnowledgeBaseLinks,
|
||||
validatePortableMarkdownFilename
|
||||
};
|
||||
305
llm-wiki/scripts/lib/wikilink-parser.js
Normal file
305
llm-wiki/scripts/lib/wikilink-parser.js
Normal file
@@ -0,0 +1,305 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const crypto = require("node:crypto");
|
||||
const path = require("node:path");
|
||||
|
||||
function sha256(buffer) {
|
||||
return crypto.createHash("sha256").update(buffer).digest("hex");
|
||||
}
|
||||
|
||||
function countCodePoints(value) {
|
||||
return Array.from(value).length;
|
||||
}
|
||||
|
||||
function extractLineAnnotations(lineText) {
|
||||
const confidenceMatch = lineText.match(/<!--\s*confidence:\s*([A-Z]+)\s*-->/);
|
||||
const relationTypeMatch = lineText.match(/<!--\s*relation(?:_type)?:\s*([^>]+?)\s*-->/);
|
||||
|
||||
return {
|
||||
confidence: confidenceMatch ? confidenceMatch[1] : null,
|
||||
relation_type: relationTypeMatch ? relationTypeMatch[1].trim() : null
|
||||
};
|
||||
}
|
||||
|
||||
function parseFenceCandidate(lineText) {
|
||||
const match = lineText.match(/^( {0,3})(`{3,}|~{3,})(.*)$/);
|
||||
if (!match) return null;
|
||||
return {
|
||||
marker: match[2][0],
|
||||
length: match[2].length,
|
||||
rest: match[3]
|
||||
};
|
||||
}
|
||||
|
||||
function collectInlineBacktickRuns(text) {
|
||||
const positionsByLength = new Map();
|
||||
let fence = null;
|
||||
let lineStartIndex = 0;
|
||||
|
||||
while (lineStartIndex <= text.length) {
|
||||
const nextNewlineIndex = text.indexOf("\n", lineStartIndex);
|
||||
const lineEndIndex = nextNewlineIndex === -1 ? text.length : nextNewlineIndex;
|
||||
const lineText = text.slice(lineStartIndex, lineEndIndex);
|
||||
const fenceCandidate = parseFenceCandidate(lineText);
|
||||
let handledAsFence = false;
|
||||
|
||||
if (fence) {
|
||||
handledAsFence = true;
|
||||
if (
|
||||
fenceCandidate
|
||||
&& fence.marker === fenceCandidate.marker
|
||||
&& fenceCandidate.length >= fence.length
|
||||
&& /^[ \t]*$/.test(fenceCandidate.rest)
|
||||
) {
|
||||
fence = null;
|
||||
}
|
||||
} else if (
|
||||
fenceCandidate
|
||||
&& !(fenceCandidate.marker === "`" && fenceCandidate.rest.includes("`"))
|
||||
) {
|
||||
fence = { marker: fenceCandidate.marker, length: fenceCandidate.length };
|
||||
handledAsFence = true;
|
||||
}
|
||||
|
||||
if (!handledAsFence) {
|
||||
for (let index = 0; index < lineText.length;) {
|
||||
if (lineText[index] !== "`") {
|
||||
index += String.fromCodePoint(lineText.codePointAt(index)).length;
|
||||
continue;
|
||||
}
|
||||
|
||||
let runLength = 1;
|
||||
while (lineText[index + runLength] === "`") {
|
||||
runLength += 1;
|
||||
}
|
||||
const positions = positionsByLength.get(runLength) || [];
|
||||
positions.push(lineStartIndex + index);
|
||||
positionsByLength.set(runLength, positions);
|
||||
index += runLength;
|
||||
}
|
||||
}
|
||||
|
||||
if (nextNewlineIndex === -1) break;
|
||||
lineStartIndex = nextNewlineIndex + 1;
|
||||
}
|
||||
|
||||
return { positionsByLength, cursorsByLength: new Map() };
|
||||
}
|
||||
|
||||
function consumeInlineBacktickRun(runIndex, runLength, absoluteIndex) {
|
||||
const positions = runIndex.positionsByLength.get(runLength) || [];
|
||||
let cursor = runIndex.cursorsByLength.get(runLength) || 0;
|
||||
while (cursor < positions.length && positions[cursor] <= absoluteIndex) {
|
||||
cursor += 1;
|
||||
}
|
||||
runIndex.cursorsByLength.set(runLength, cursor);
|
||||
return cursor < positions.length;
|
||||
}
|
||||
|
||||
function parseOccurrence(rawLink, sourcePath, fileSha256, line, column, startByte, annotations) {
|
||||
let innerStart = 0;
|
||||
let innerEnd = rawLink.length;
|
||||
let embedded = false;
|
||||
let pending = false;
|
||||
|
||||
if (rawLink.startsWith("[待创建: [[")) {
|
||||
innerStart = "[待创建: [[".length;
|
||||
innerEnd = rawLink.length - "]]]".length;
|
||||
pending = true;
|
||||
} else if (rawLink.startsWith("[To create: [[")) {
|
||||
innerStart = "[To create: [[".length;
|
||||
innerEnd = rawLink.length - "]]]".length;
|
||||
pending = true;
|
||||
} else if (rawLink.startsWith("![[")) {
|
||||
innerStart = "![[".length;
|
||||
innerEnd = rawLink.length - "]]".length;
|
||||
embedded = true;
|
||||
} else {
|
||||
innerStart = "[[".length;
|
||||
innerEnd = rawLink.length - "]]".length;
|
||||
}
|
||||
|
||||
const inner = rawLink.slice(innerStart, innerEnd);
|
||||
const pipeIndex = inner.indexOf("|");
|
||||
const targetAndAnchorRaw = pipeIndex >= 0 ? inner.slice(0, pipeIndex) : inner;
|
||||
const displayRaw = pipeIndex >= 0 ? inner.slice(pipeIndex + 1) : null;
|
||||
const anchorIndex = targetAndAnchorRaw.indexOf("#");
|
||||
const targetRaw = anchorIndex >= 0 ? targetAndAnchorRaw.slice(0, anchorIndex) : targetAndAnchorRaw;
|
||||
const anchor = anchorIndex >= 0 ? targetAndAnchorRaw.slice(anchorIndex + 1).trim() : null;
|
||||
const display = displayRaw === null ? null : displayRaw.trim();
|
||||
|
||||
const leadingWhitespace = (targetRaw.match(/^\s*/) || [""])[0].length;
|
||||
const trailingWhitespace = (targetRaw.match(/\s*$/) || [""])[0].length;
|
||||
const targetStartInRaw = innerStart + leadingWhitespace;
|
||||
const targetEndInRaw = innerStart + targetRaw.length - trailingWhitespace;
|
||||
const pageTarget = targetRaw.trim();
|
||||
const extension = path.posix.extname(pageTarget);
|
||||
|
||||
let linkKind = "page_wikilink";
|
||||
if (pageTarget === "" && anchor) {
|
||||
linkKind = "same_page_anchor";
|
||||
} else if (extension && extension.toLowerCase() !== ".md") {
|
||||
linkKind = "attachment_wikilink";
|
||||
}
|
||||
|
||||
return {
|
||||
occurrence_id: `${sourcePath}\0${fileSha256}\0${startByte}\0${startByte + Buffer.byteLength(rawLink, "utf8")}\0${rawLink}`,
|
||||
source_path: sourcePath,
|
||||
file_sha256: fileSha256,
|
||||
raw_link: rawLink,
|
||||
line,
|
||||
column,
|
||||
start_byte: startByte,
|
||||
end_byte: startByte + Buffer.byteLength(rawLink, "utf8"),
|
||||
link_kind: linkKind,
|
||||
embedded,
|
||||
pending,
|
||||
page_target: pageTarget,
|
||||
anchor,
|
||||
display,
|
||||
confidence: annotations.confidence,
|
||||
relation_type: annotations.relation_type,
|
||||
target_start_in_raw: targetStartInRaw,
|
||||
target_end_in_raw: targetEndInRaw
|
||||
};
|
||||
}
|
||||
|
||||
function parseWikilinks(buffer, sourcePath) {
|
||||
const text = buffer.toString("utf8");
|
||||
const fileSha256 = sha256(buffer);
|
||||
const occurrences = [];
|
||||
const inlineBacktickRuns = collectInlineBacktickRuns(text);
|
||||
|
||||
let fence = null;
|
||||
let inlineDelimiter = 0;
|
||||
let lineNumber = 1;
|
||||
let lineStartIndex = 0;
|
||||
let positionBytesAdvanced = 0;
|
||||
|
||||
while (lineStartIndex <= text.length) {
|
||||
const nextNewlineIndex = text.indexOf("\n", lineStartIndex);
|
||||
const lineEndIndex = nextNewlineIndex === -1 ? text.length : nextNewlineIndex;
|
||||
const lineText = text.slice(lineStartIndex, lineEndIndex);
|
||||
const annotations = extractLineAnnotations(lineText);
|
||||
const fenceCandidate = parseFenceCandidate(lineText);
|
||||
let handledAsFence = false;
|
||||
|
||||
if (fence) {
|
||||
handledAsFence = true;
|
||||
if (
|
||||
fenceCandidate
|
||||
&& fence.marker === fenceCandidate.marker
|
||||
&& fenceCandidate.length >= fence.length
|
||||
&& /^[ \t]*$/.test(fenceCandidate.rest)
|
||||
) {
|
||||
fence = null;
|
||||
}
|
||||
} else if (
|
||||
inlineDelimiter === 0
|
||||
&& fenceCandidate
|
||||
&& !(fenceCandidate.marker === "`" && fenceCandidate.rest.includes("`"))
|
||||
) {
|
||||
fence = { marker: fenceCandidate.marker, length: fenceCandidate.length };
|
||||
handledAsFence = true;
|
||||
}
|
||||
|
||||
if (handledAsFence) {
|
||||
positionBytesAdvanced += Buffer.byteLength(lineText, "utf8");
|
||||
} else {
|
||||
let column = 1;
|
||||
|
||||
for (let index = 0; index < lineText.length;) {
|
||||
if (lineText[index] === "`") {
|
||||
let runLength = 1;
|
||||
while (lineText[index + runLength] === "`") {
|
||||
runLength += 1;
|
||||
}
|
||||
const hasEqualLengthCloser = consumeInlineBacktickRun(
|
||||
inlineBacktickRuns,
|
||||
runLength,
|
||||
lineStartIndex + index
|
||||
);
|
||||
if (inlineDelimiter === 0) {
|
||||
if (hasEqualLengthCloser) {
|
||||
inlineDelimiter = runLength;
|
||||
}
|
||||
} else if (runLength === inlineDelimiter) {
|
||||
inlineDelimiter = 0;
|
||||
}
|
||||
index += runLength;
|
||||
column += runLength;
|
||||
positionBytesAdvanced += runLength;
|
||||
continue;
|
||||
}
|
||||
|
||||
if (inlineDelimiter > 0) {
|
||||
const symbol = String.fromCodePoint(lineText.codePointAt(index));
|
||||
const symbolBytes = Buffer.byteLength(symbol, "utf8");
|
||||
index += symbol.length;
|
||||
column += 1;
|
||||
positionBytesAdvanced += symbolBytes;
|
||||
continue;
|
||||
}
|
||||
|
||||
let rawLink = null;
|
||||
let endIndex = null;
|
||||
|
||||
if (lineText.startsWith("[待创建: [[", index) || lineText.startsWith("[To create: [[", index)) {
|
||||
const wrapperPrefix = lineText.startsWith("[待创建: [[", index) ? "[待创建: [[" : "[To create: [[";
|
||||
const closeInner = lineText.indexOf("]]]", index + wrapperPrefix.length);
|
||||
if (closeInner >= 0) {
|
||||
rawLink = lineText.slice(index, closeInner + 3);
|
||||
endIndex = closeInner + 3;
|
||||
}
|
||||
} else if (lineText.startsWith("![[", index) || lineText.startsWith("[[", index)) {
|
||||
const closeInner = lineText.indexOf("]]", index + 2);
|
||||
if (closeInner >= 0) {
|
||||
rawLink = lineText.slice(index, closeInner + 2);
|
||||
endIndex = closeInner + 2;
|
||||
}
|
||||
}
|
||||
|
||||
if (rawLink && endIndex !== null) {
|
||||
const startByte = positionBytesAdvanced;
|
||||
const rawLinkBytes = Buffer.byteLength(rawLink, "utf8");
|
||||
occurrences.push(parseOccurrence(rawLink, sourcePath, fileSha256, lineNumber, column, startByte, annotations));
|
||||
index = endIndex;
|
||||
column += countCodePoints(rawLink);
|
||||
positionBytesAdvanced += rawLinkBytes;
|
||||
continue;
|
||||
}
|
||||
|
||||
const symbol = String.fromCodePoint(lineText.codePointAt(index));
|
||||
const symbolBytes = Buffer.byteLength(symbol, "utf8");
|
||||
index += symbol.length;
|
||||
column += 1;
|
||||
positionBytesAdvanced += symbolBytes;
|
||||
}
|
||||
}
|
||||
|
||||
if (nextNewlineIndex === -1) {
|
||||
break;
|
||||
}
|
||||
|
||||
lineStartIndex = nextNewlineIndex + 1;
|
||||
positionBytesAdvanced += 1;
|
||||
lineNumber += 1;
|
||||
}
|
||||
|
||||
return {
|
||||
source_path: sourcePath,
|
||||
file_sha256: fileSha256,
|
||||
occurrences,
|
||||
metrics: {
|
||||
utf8_bytes_scanned: buffer.length,
|
||||
position_bytes_advanced: positionBytesAdvanced
|
||||
}
|
||||
};
|
||||
}
|
||||
|
||||
function renderWikilinkReplacement(occurrence, replacementTarget) {
|
||||
return `${occurrence.raw_link.slice(0, occurrence.target_start_in_raw)}${replacementTarget}${occurrence.raw_link.slice(occurrence.target_end_in_raw)}`;
|
||||
}
|
||||
|
||||
module.exports = { parseWikilinks, renderWikilinkReplacement };
|
||||
114
llm-wiki/scripts/lint-fix.sh
Executable file
114
llm-wiki/scripts/lint-fix.sh
Executable file
@@ -0,0 +1,114 @@
|
||||
#!/bin/bash
|
||||
# lint-fix.sh — 自动修复 lint 发现的低风险问题
|
||||
# 用法:bash scripts/lint-fix.sh <wiki_root> [--dry-run]
|
||||
# 修复范围:仅处理确定性修复(补 index 条目),不做高风险操作(删页面、改内容)
|
||||
# 退出码:0 = 完成,1 = 参数错误
|
||||
|
||||
set -u
|
||||
shopt -s nullglob
|
||||
|
||||
WIKI_ROOT="${1:-.}"
|
||||
DRY_RUN=false
|
||||
[ "${2:-}" = "--dry-run" ] && DRY_RUN=true
|
||||
|
||||
WIKI_DIR="$WIKI_ROOT/wiki"
|
||||
INDEX_FILE="$WIKI_ROOT/index.md"
|
||||
|
||||
if [ ! -d "$WIKI_DIR" ]; then
|
||||
echo "ERROR: wiki directory not found: $WIKI_DIR" >&2
|
||||
exit 1
|
||||
fi
|
||||
if [ ! -f "$INDEX_FILE" ]; then
|
||||
echo "ERROR: index.md not found: $INDEX_FILE" >&2
|
||||
exit 1
|
||||
fi
|
||||
|
||||
FIXED=0
|
||||
|
||||
index_has_entry() {
|
||||
local entry="$1"
|
||||
grep -ohE "\[\[[^]]+\]\]" "$INDEX_FILE" 2>/dev/null | \
|
||||
sed -e 's/\[\[//g' -e 's/\]\]//g' -e 's/|.*//' | \
|
||||
grep -Fxq "$entry"
|
||||
}
|
||||
|
||||
# Insert a [[link]] entry after the matching section header in index.md.
|
||||
# If no matching section is found, appends to end of file as fallback.
|
||||
insert_under_section() {
|
||||
local index_file="$1"
|
||||
local section_pattern="$2"
|
||||
local entry="$3"
|
||||
|
||||
# Find the line number of the section header
|
||||
local line_num
|
||||
line_num=$(grep -n -i -E "^#.*($section_pattern)" "$index_file" 2>/dev/null | head -1 | cut -d: -f1)
|
||||
|
||||
if [ -n "$line_num" ]; then
|
||||
# Scan from section header to find insert point:
|
||||
# last "- [[" line before next "##" header or EOF
|
||||
local total_lines last_list_line offset
|
||||
total_lines=$(wc -l < "$index_file" | tr -d ' ')
|
||||
last_list_line="$line_num"
|
||||
offset=$((line_num + 1))
|
||||
while [ "$offset" -le "$total_lines" ]; do
|
||||
local cur_line
|
||||
cur_line=$(sed -n "${offset}p" "$index_file")
|
||||
case "$cur_line" in
|
||||
"##"*) break ;;
|
||||
"- [["*) last_list_line="$offset" ;;
|
||||
esac
|
||||
offset=$((offset + 1))
|
||||
done
|
||||
# Insert after the last list item
|
||||
local tmp_file
|
||||
tmp_file=$(mktemp "${index_file}.tmp.XXXXXX") || return 1
|
||||
awk -v insert_after="$last_list_line" -v entry="$entry" '
|
||||
{ print }
|
||||
NR == insert_after { print "- [[" entry "]]" }
|
||||
' "$index_file" > "$tmp_file" && mv "$tmp_file" "$index_file"
|
||||
else
|
||||
# Fallback: append to end of file
|
||||
printf '\n- [[%s]]\n' "$entry" >> "$index_file"
|
||||
fi
|
||||
}
|
||||
|
||||
echo "=== lint-fix: low-risk auto-repair ==="
|
||||
echo ""
|
||||
|
||||
# Fix 1: Add unlisted pages to index.md
|
||||
# Only adds pages that exist in wiki/ but are not referenced in index.md
|
||||
# Skips derived pages (queries/, sessions/)
|
||||
echo "--- Checking for unlisted pages ---"
|
||||
for _subdir in entities topics sources comparisons synthesis; do
|
||||
for f in "$WIKI_DIR"/$_subdir/*.md; do
|
||||
[ -f "$f" ] || continue
|
||||
BASENAME=$(basename "$f" .md)
|
||||
# Skip derived pages
|
||||
case "$f" in
|
||||
*/queries/*|*/sessions/*) continue ;;
|
||||
esac
|
||||
if ! index_has_entry "$BASENAME"; then
|
||||
SECTION_PATTERN=""
|
||||
case "$_subdir" in
|
||||
entities) SECTION_PATTERN="实体页|Entities" ;;
|
||||
topics) SECTION_PATTERN="主题页|Topics" ;;
|
||||
sources) SECTION_PATTERN="素材摘要|Sources" ;;
|
||||
comparisons) SECTION_PATTERN="对比分析|Comparisons" ;;
|
||||
synthesis) SECTION_PATTERN="综合分析|Synthesis" ;;
|
||||
esac
|
||||
if [ "$DRY_RUN" = true ]; then
|
||||
echo " [dry-run] Would add [[$BASENAME]] under $_subdir section"
|
||||
else
|
||||
insert_under_section "$INDEX_FILE" "$SECTION_PATTERN" "$BASENAME"
|
||||
echo " Fixed: added [[$BASENAME]] under $_subdir section"
|
||||
fi
|
||||
FIXED=$((FIXED + 1))
|
||||
fi
|
||||
done
|
||||
done
|
||||
[ "$FIXED" -eq 0 ] && echo " (all pages already listed)"
|
||||
echo ""
|
||||
|
||||
echo "=== lint-fix complete: $FIXED fix(es) applied ==="
|
||||
[ "$DRY_RUN" = true ] && echo "(dry-run mode — no files were modified)"
|
||||
exit 0
|
||||
250
llm-wiki/scripts/lint-runner.sh
Executable file
250
llm-wiki/scripts/lint-runner.sh
Executable file
@@ -0,0 +1,250 @@
|
||||
#!/bin/bash
|
||||
# lint-runner.sh — render the single shared path-aware wikilink report.
|
||||
#
|
||||
# Usage:
|
||||
# bash scripts/lint-runner.sh <kb-root>
|
||||
# bash scripts/lint-runner.sh <kb-root> --strict
|
||||
# bash scripts/lint-runner.sh <kb-root> --json
|
||||
# bash scripts/lint-runner.sh <kb-root> --strict --json
|
||||
#
|
||||
# Exit codes: 0 complete report; 1 tool/input failure; 2 strict report contains an error.
|
||||
|
||||
set -u
|
||||
|
||||
SCRIPT_DIR="${BASH_SOURCE[0]%/*}"
|
||||
[ "$SCRIPT_DIR" = "${BASH_SOURCE[0]}" ] && SCRIPT_DIR="."
|
||||
SCRIPT_DIR="$(cd "$SCRIPT_DIR" && pwd)"
|
||||
CLI="$SCRIPT_DIR/wiki-link-cli.js"
|
||||
|
||||
usage() {
|
||||
cat <<'USAGE'
|
||||
Usage:
|
||||
bash scripts/lint-runner.sh <kb-root> [--strict] [--json]
|
||||
USAGE
|
||||
}
|
||||
|
||||
[ "$#" -ge 1 ] || {
|
||||
usage >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
WIKI_ROOT="$1"
|
||||
shift
|
||||
STRICT=0
|
||||
FORMAT=text
|
||||
SEEN_STRICT=0
|
||||
SEEN_JSON=0
|
||||
for FLAG in "$@"; do
|
||||
case "$FLAG" in
|
||||
--strict)
|
||||
[ "$SEEN_STRICT" -eq 0 ] || { echo "ERROR: duplicate argument: --strict" >&2; exit 1; }
|
||||
STRICT=1
|
||||
SEEN_STRICT=1
|
||||
;;
|
||||
--json)
|
||||
[ "$SEEN_JSON" -eq 0 ] || { echo "ERROR: duplicate argument: --json" >&2; exit 1; }
|
||||
FORMAT=json
|
||||
SEEN_JSON=1
|
||||
;;
|
||||
*)
|
||||
echo "ERROR: unknown argument: $FLAG" >&2
|
||||
usage >&2
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
done
|
||||
|
||||
[ -d "$WIKI_ROOT/wiki" ] || {
|
||||
echo "ERROR: wiki directory does not exist: $WIKI_ROOT/wiki" >&2
|
||||
exit 1
|
||||
}
|
||||
[ -f "$WIKI_ROOT/index.md" ] || {
|
||||
echo "ERROR: index.md does not exist: $WIKI_ROOT/index.md" >&2
|
||||
exit 1
|
||||
}
|
||||
[ -f "$CLI" ] || {
|
||||
echo "ERROR: shared wikilink checker is missing: $CLI" >&2
|
||||
exit 1
|
||||
}
|
||||
command -v node >/dev/null 2>&1 || { echo "ERROR: node is required" >&2; exit 1; }
|
||||
|
||||
REPORT_FILE="$(mktemp -t llm-wiki-lint.XXXXXX)"
|
||||
trap 'rm -f "$REPORT_FILE"' EXIT
|
||||
if ! node "$CLI" check "$WIKI_ROOT" --json > "$REPORT_FILE"; then
|
||||
exit 1
|
||||
fi
|
||||
|
||||
node - "$REPORT_FILE" "$WIKI_ROOT" "$FORMAT" <<'NODE'
|
||||
"use strict";
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
|
||||
const [reportPath, kbRoot, format] = process.argv.slice(2);
|
||||
const report = JSON.parse(fs.readFileSync(reportPath, "utf8"));
|
||||
const targets = report.inventory.targets;
|
||||
const targetPaths = new Set(targets.map((item) => item.path));
|
||||
const metadata = new Map(report.source_metadata.map((item) => [item.source_path, item]));
|
||||
const resolvedOccurrences = report.occurrences.filter((item) => (
|
||||
item.resolution && item.resolution.status === "resolved" && item.resolution.target_path
|
||||
));
|
||||
const incoming = new Map();
|
||||
for (const occurrence of resolvedOccurrences) {
|
||||
const target = occurrence.resolution.target_path;
|
||||
if (target === occurrence.source_path) continue;
|
||||
if (!incoming.has(target)) incoming.set(target, new Set());
|
||||
incoming.get(target).add(occurrence.source_path);
|
||||
}
|
||||
|
||||
const orphanPages = report.inventory.lintSources
|
||||
.filter((item) => ["entity", "topic", "source"].includes(item.graphType))
|
||||
.map((item) => item.path)
|
||||
.filter((item) => !incoming.has(item))
|
||||
.sort();
|
||||
|
||||
const indexOccurrences = report.occurrences.filter((item) => item.source_path === "index.md");
|
||||
const indexResolvedTargetPaths = Array.from(new Set(indexOccurrences
|
||||
.filter((item) => item.resolution && item.resolution.status === "resolved")
|
||||
.map((item) => item.resolution.target_path)))
|
||||
.sort();
|
||||
const indexMissingTargets = Array.from(new Set(indexOccurrences
|
||||
.filter((item) => item.resolution && item.resolution.status === "missing" && item.resolution.warning_code)
|
||||
.map((item) => item.resolution.target_key)))
|
||||
.sort();
|
||||
const indexed = new Set(indexResolvedTargetPaths);
|
||||
const indexUnlistedPaths = report.inventory.lintSources
|
||||
.filter((item) => ["entity", "topic", "source", "comparison", "synthesis"].includes(item.graphType))
|
||||
.map((item) => item.path)
|
||||
.filter((item) => !item.includes("/sessions/") && !indexed.has(item))
|
||||
.sort();
|
||||
|
||||
const imageIssues = [];
|
||||
for (const [sourcePath, item] of metadata.entries()) {
|
||||
if (item.graph_type !== "source") continue;
|
||||
for (const imagePath of item._signals.imagePaths || []) {
|
||||
if (!targetPaths.has(imagePath)) imageIssues.push({ source_path: sourcePath, image_path: imagePath });
|
||||
}
|
||||
}
|
||||
imageIssues.sort((left, right) => `${left.source_path}\0${left.image_path}`.localeCompare(`${right.source_path}\0${right.image_path}`, "en"));
|
||||
|
||||
const sourceSignal = {
|
||||
applicable_total: 0,
|
||||
ok: 0,
|
||||
missing_sources: 0,
|
||||
empty_sources: 0,
|
||||
invalid_sources: 0,
|
||||
not_applicable: 0,
|
||||
pages: []
|
||||
};
|
||||
for (const item of report.source_metadata) {
|
||||
if (!item.graph_type) continue;
|
||||
const applicable = ["entity", "topic", "source", "comparison"].includes(item.graph_type);
|
||||
let reason;
|
||||
if (!applicable) reason = "not_applicable";
|
||||
else if (!item._signals.sourceFieldPresent) reason = "missing_sources";
|
||||
else if (!item._signals.sourceFieldParsed) reason = "invalid_sources";
|
||||
else if (!item._signals.sources.length) reason = "empty_sources";
|
||||
else reason = "ok";
|
||||
sourceSignal[reason] += 1;
|
||||
if (reason !== "not_applicable") sourceSignal.applicable_total += 1;
|
||||
sourceSignal.pages.push({ path: item.source_path, reason, source_count: item._signals.sources.length });
|
||||
}
|
||||
sourceSignal.pages.sort((left, right) => left.path.localeCompare(right.path, "en"));
|
||||
|
||||
const derived = {
|
||||
orphan_count: orphanPages.length,
|
||||
orphan_paths: orphanPages,
|
||||
broken_count: report.groups.filter((group) => group.code === "broken_wikilink")
|
||||
.reduce((sum, group) => sum + group.occurrence_count, 0),
|
||||
index_missing_count: indexMissingTargets.length,
|
||||
index_missing_targets: indexMissingTargets,
|
||||
index_unlisted_count: indexUnlistedPaths.length,
|
||||
index_unlisted_paths: indexUnlistedPaths,
|
||||
index_resolved_target_paths: indexResolvedTargetPaths,
|
||||
image_issue_count: imageIssues.length,
|
||||
image_issues: imageIssues,
|
||||
source_signal: sourceSignal
|
||||
};
|
||||
const output = {
|
||||
derived,
|
||||
stale_pending_wrappers: report.stale_pending_wrappers,
|
||||
warning_report: report
|
||||
};
|
||||
|
||||
if (format === "json") {
|
||||
process.stdout.write(`${JSON.stringify(output, null, 2)}\n`);
|
||||
process.exit(0);
|
||||
}
|
||||
|
||||
function displayPage(relativePath) {
|
||||
return relativePath.replace(/^wiki\//, "").replace(/\.md$/, "");
|
||||
}
|
||||
function section(title, rows, emptyText) {
|
||||
console.log(`--- ${title} ---`);
|
||||
if (rows.length === 0) console.log(` ${emptyText}`);
|
||||
else for (const row of rows) console.log(` ${row}`);
|
||||
console.log("");
|
||||
}
|
||||
function warningRows(code) {
|
||||
const candidateSets = new Map(report.candidate_sets.map((item) => [item.candidate_set_id, item]));
|
||||
const rows = [];
|
||||
for (const group of report.groups.filter((item) => item.code === code)) {
|
||||
rows.push(`${group.target_key || group.id || group.warning_id}(${group.occurrence_count} 处)`);
|
||||
const candidateSet = candidateSets.get(group.candidate_set_id);
|
||||
if (candidateSet) {
|
||||
for (const candidate of candidateSet.candidates) rows.push(` 候选: ${candidate}`);
|
||||
}
|
||||
for (const occurrence of group.occurrences) {
|
||||
rows.push(` ${occurrence.source_path}:${occurrence.line}:${occurrence.column} ${occurrence.raw_link}`);
|
||||
}
|
||||
}
|
||||
return rows;
|
||||
}
|
||||
|
||||
console.log("=== llm-wiki lint 报告 ===");
|
||||
const now = new Date();
|
||||
const parts = new Intl.DateTimeFormat("sv-SE", {
|
||||
year: "numeric", month: "2-digit", day: "2-digit", hour: "2-digit", minute: "2-digit", hour12: false
|
||||
}).formatToParts(now).reduce((result, item) => ({ ...result, [item.type]: item.value }), {});
|
||||
console.log(`时间:${parts.year}-${parts.month}-${parts.day} ${parts.hour}:${parts.minute}`);
|
||||
console.log(`检查路径:${path.join(kbRoot, "wiki")}`);
|
||||
console.log("");
|
||||
|
||||
section("孤立页面(没有被其他页面引用)", orphanPages.map((item) => `孤立: ${displayPage(item)}`), "(无孤立页面)");
|
||||
section("断链(被链接但不存在的页面)", warningRows("broken_wikilink").map((item) => item.startsWith(" ") ? item : `断链: [[${item.replace(/(.*$/, "")}]]`), "(无断链)");
|
||||
section("index 一致性(index.md 有记录但文件缺失)", indexMissingTargets.map((item) => `index 有但文件缺失: ${item}`), "(index 与文件一致)");
|
||||
section("反向 index 一致性(文件存在但 index.md 未收录)", indexUnlistedPaths.map((item) => `未收录: ${displayPage(item)}`), "(所有页面均已收录)");
|
||||
section("图片资产一致性(image_paths 声明但文件缺失)", imageIssues.map((item) => `缺失: ${path.posix.basename(item.source_path, ".md")} → ${item.image_path}`), "(无缺失图片)");
|
||||
|
||||
console.log("--- source-signal 覆盖情况 ---");
|
||||
console.log(` 已参与:${sourceSignal.ok}`);
|
||||
console.log(` 缺少 sources 字段:${sourceSignal.missing_sources}`);
|
||||
console.log(` sources 为空:${sourceSignal.empty_sources}`);
|
||||
console.log(` sources 格式无效:${sourceSignal.invalid_sources}`);
|
||||
console.log(` 当前不参与:${sourceSignal.not_applicable}`);
|
||||
for (const [reason, label] of [
|
||||
["missing_sources", "缺少 sources 字段"],
|
||||
["empty_sources", "sources 为空"],
|
||||
["invalid_sources", "sources 格式无效"]
|
||||
]) {
|
||||
const pages = sourceSignal.pages.filter((item) => item.reason === reason);
|
||||
if (!pages.length) continue;
|
||||
console.log("");
|
||||
console.log(` ${label}:`);
|
||||
for (const page of pages) console.log(` - ${page.path}`);
|
||||
}
|
||||
console.log("");
|
||||
|
||||
section("歧义链接(同名候选,未建边)", warningRows("ambiguous_wikilink"), "(无歧义链接)");
|
||||
section("待创建链接(尚未建边)", warningRows("pending_wikilink"), "(无待创建链接)");
|
||||
section("非规范路径链接(已按实际路径建边)", warningRows("noncanonical_wikilink"), "(无非规范路径链接)");
|
||||
section("可移植路径冲突", warningRows("portable_path_collision"), "(无可移植路径冲突)");
|
||||
section("待创建包装清理(目标现已存在)", report.stale_pending_wrappers.map((item) => `${item.source_path}: ${item.raw_link} → ${item.replacement}`), "(无待清理包装)");
|
||||
console.log("=== 机械检查完成。矛盾检测、交叉引用、置信度抽查由 AI 继续执行 ===");
|
||||
NODE
|
||||
RENDER_STATUS=$?
|
||||
[ "$RENDER_STATUS" -eq 0 ] || exit 1
|
||||
|
||||
if [ "$STRICT" -eq 1 ] && jq -e 'any(.groups[]; .severity == "error")' "$REPORT_FILE" > /dev/null 2>&1; then
|
||||
exit 2
|
||||
fi
|
||||
exit 0
|
||||
77
llm-wiki/scripts/runtime-context.sh
Normal file
77
llm-wiki/scripts/runtime-context.sh
Normal file
@@ -0,0 +1,77 @@
|
||||
#!/bin/bash
|
||||
# 共享运行场景解析:供 install.sh 和 adapter-state.sh 复用
|
||||
|
||||
resolve_platform_skill_root() {
|
||||
case "$1" in
|
||||
claude)
|
||||
printf '%s\n' "$HOME/.claude/skills"
|
||||
;;
|
||||
codex)
|
||||
if [ -d "$HOME/.codex/skills" ] || [ ! -d "$HOME/.Codex/skills" ]; then
|
||||
printf '%s\n' "$HOME/.codex/skills"
|
||||
else
|
||||
printf '%s\n' "$HOME/.Codex/skills"
|
||||
fi
|
||||
;;
|
||||
openclaw)
|
||||
printf '%s\n' "$HOME/.openclaw/skills"
|
||||
;;
|
||||
hermes)
|
||||
printf '%s\n' "$HOME/.hermes/skills"
|
||||
;;
|
||||
*)
|
||||
echo "不支持的平台:$1" >&2
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
detect_layout_mode() {
|
||||
local bundle_root="$1"
|
||||
|
||||
if [ -e "$bundle_root/.git" ]; then
|
||||
printf '%s\n' "source_checkout"
|
||||
return 0
|
||||
fi
|
||||
|
||||
printf '%s\n' "installed_skill"
|
||||
}
|
||||
|
||||
resolve_layout_mode() {
|
||||
local bundle_root="$1"
|
||||
local override_mode="${2:-}"
|
||||
|
||||
if [ -n "$override_mode" ]; then
|
||||
printf '%s\n' "$override_mode"
|
||||
return 0
|
||||
fi
|
||||
|
||||
detect_layout_mode "$bundle_root"
|
||||
}
|
||||
|
||||
resolve_optional_adapter_root() {
|
||||
local bundle_root="$1"
|
||||
local skill_root_override="${2:-}"
|
||||
local override_mode="${3:-}"
|
||||
local layout_mode
|
||||
|
||||
if [ -n "$skill_root_override" ]; then
|
||||
printf '%s\n' "$skill_root_override"
|
||||
return 0
|
||||
fi
|
||||
|
||||
layout_mode="$(resolve_layout_mode "$bundle_root" "$override_mode")"
|
||||
|
||||
case "$layout_mode" in
|
||||
source_checkout)
|
||||
printf '%s\n' "$bundle_root/deps"
|
||||
;;
|
||||
installed_skill|upgrade_target)
|
||||
printf '%s\n' "$(dirname "$bundle_root")"
|
||||
;;
|
||||
*)
|
||||
echo "未知运行模式:$layout_mode" >&2
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
83
llm-wiki/scripts/shared-config.sh
Normal file
83
llm-wiki/scripts/shared-config.sh
Normal file
@@ -0,0 +1,83 @@
|
||||
#!/bin/bash
|
||||
# 共享配置:被 install.sh / hook-session-start.sh / cache.sh / delete-helper.sh 等引用
|
||||
# 微信公众号提取工具的 Git 仓库地址
|
||||
WECHAT_TOOL_URL="git+https://github.com/jackwener/wechat-article-to-markdown.git"
|
||||
|
||||
# Python 命令检测:Windows 默认安装为 python.exe,不存在 python3 命令
|
||||
# (Microsoft Store 的 python3 是安装提示 stub,运行会失败)
|
||||
_python_version_check='import sys; sys.exit(0 if sys.version_info >= (3, 8) else 1)'
|
||||
|
||||
_python_cmd_is_valid() {
|
||||
local candidate="$1"
|
||||
|
||||
command -v "$candidate" >/dev/null 2>&1 && "$candidate" -c "$_python_version_check" >/dev/null 2>&1
|
||||
}
|
||||
|
||||
_detect_python_cmd() {
|
||||
# 要求 Python 3.8+(见 README Windows 小节与下方错误消息)
|
||||
if _python_cmd_is_valid python3; then
|
||||
echo "python3"
|
||||
elif _python_cmd_is_valid python; then
|
||||
echo "python"
|
||||
else
|
||||
echo ""
|
||||
fi
|
||||
}
|
||||
|
||||
require_python_cmd() {
|
||||
local detected_cmd
|
||||
|
||||
if [ "${PYTHON_CMD_READY:-0}" = "1" ]; then
|
||||
return 0
|
||||
fi
|
||||
|
||||
if [ -n "${PYTHON_CMD:-}" ] && _python_cmd_is_valid "$PYTHON_CMD"; then
|
||||
export PYTHON_CMD
|
||||
PYTHON_CMD_READY=1
|
||||
return 0
|
||||
fi
|
||||
|
||||
detected_cmd="$(_detect_python_cmd)"
|
||||
if [ -z "$detected_cmd" ]; then
|
||||
echo "[llm-wiki] 错误:找不到可用的 Python 3,请先安装 Python 3.8+ 并加入 PATH" >&2
|
||||
return 1
|
||||
fi
|
||||
|
||||
PYTHON_CMD="$detected_cmd"
|
||||
export PYTHON_CMD
|
||||
PYTHON_CMD_READY=1
|
||||
}
|
||||
|
||||
# 统一 Python 子进程 stdout/stderr 编码为 UTF-8
|
||||
# Windows 中文环境下 Python 无 TTY 时 sys.stdout.encoding 默认 gbk (cp936),
|
||||
# 会导致 Agent 通过 subprocess 读取的 JSON / 输出出现乱码 (issue #16)
|
||||
export PYTHONIOENCODING="${PYTHONIOENCODING:-utf-8}"
|
||||
|
||||
# 输出指定工具的跨平台安装提示,缩进 2 空格便于嵌套在 ERROR 消息下;
|
||||
# 输出走 stderr,与 ERROR 消息保持同一通道。
|
||||
print_install_hint() {
|
||||
local tool="$1"
|
||||
case "$tool" in
|
||||
jq)
|
||||
echo " macOS: brew install jq" >&2
|
||||
echo " Linux/WSL: sudo apt-get install jq (Debian/Ubuntu)" >&2
|
||||
echo " sudo dnf install jq (RHEL/Fedora)" >&2
|
||||
echo " Windows: winget install jqlang.jq (or choco install jq)" >&2
|
||||
;;
|
||||
node)
|
||||
echo " macOS: brew install node" >&2
|
||||
echo " Linux/WSL: sudo apt-get install nodejs npm" >&2
|
||||
echo " Windows: winget install OpenJS.NodeJS (or choco install nodejs)" >&2
|
||||
;;
|
||||
uv)
|
||||
echo " macOS/Linux: curl -LsSf https://astral.sh/uv/install.sh | sh (official)" >&2
|
||||
echo " brew install uv (alternative)" >&2
|
||||
echo " Windows: powershell -c \"irm https://astral.sh/uv/install.ps1 | iex\" (official)" >&2
|
||||
echo " winget install --id=astral-sh.uv -e (alternative)" >&2
|
||||
;;
|
||||
*)
|
||||
echo " unknown tool: $tool" >&2
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
10
llm-wiki/scripts/source-record-contract.tsv
Normal file
10
llm-wiki/scripts/source-record-contract.tsv
Normal file
@@ -0,0 +1,10 @@
|
||||
field_name requiredness filled_by value_rule
|
||||
source_id required router 必须匹配 source-registry.tsv 中的 source_id
|
||||
source_label required router 必须匹配 source-registry.tsv 中的 source_label
|
||||
source_category required router 必须匹配 source-registry.tsv 中的 source_category
|
||||
input_mode required caller_or_router 只能是 url / file / text / asset
|
||||
raw_dir required router 必须是 raw/ 下的相对目录
|
||||
original_ref required caller 保存原始 URL、文件路径或用户粘贴说明
|
||||
ingest_text required adapter_or_user 进入主线前必须是非空文本
|
||||
adapter_name required_may_be_empty router_or_adapter 核心主线和手动入口留空;外挂来源写实际 adapter 名称
|
||||
fallback_hint required router 必须给出用户可执行的手动回退提示
|
||||
|
349
llm-wiki/scripts/source-registry.sh
Executable file
349
llm-wiki/scripts/source-registry.sh
Executable file
@@ -0,0 +1,349 @@
|
||||
#!/bin/bash
|
||||
# 统一来源总表读取与验证脚本
|
||||
# 权威数据文件:source-registry.tsv(来源定义)、source-record-contract.tsv(字段契约)
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
CONTRACT_FILE="$SCRIPT_DIR/source-record-contract.tsv"
|
||||
REGISTRY_FILE="$SCRIPT_DIR/source-registry.tsv"
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/source-registry.sh fields
|
||||
bash scripts/source-registry.sh list
|
||||
bash scripts/source-registry.sh get <source_id>
|
||||
bash scripts/source-registry.sh match-url <url>
|
||||
bash scripts/source-registry.sh match-file <path>
|
||||
bash scripts/source-registry.sh list-by-category <core_builtin|optional_adapter|manual_only>
|
||||
bash scripts/source-registry.sh unique-dependencies <bundled|install_time|none>
|
||||
bash scripts/source-registry.sh validate
|
||||
EOF
|
||||
}
|
||||
|
||||
require_file() {
|
||||
local file="$1"
|
||||
|
||||
[ -f "$file" ] || {
|
||||
echo "缺少文件:$file" >&2
|
||||
exit 1
|
||||
}
|
||||
}
|
||||
|
||||
expect_header() {
|
||||
local file="$1"
|
||||
local expected="$2"
|
||||
local actual
|
||||
|
||||
actual="$(head -n 1 "$file")"
|
||||
[ "$actual" = "$expected" ] || {
|
||||
echo "表头不匹配:$file" >&2
|
||||
echo "期望:$expected" >&2
|
||||
echo "实际:$actual" >&2
|
||||
exit 1
|
||||
}
|
||||
}
|
||||
|
||||
validate_contract() {
|
||||
require_file "$CONTRACT_FILE"
|
||||
expect_header "$CONTRACT_FILE" $'field_name\trequiredness\tfilled_by\tvalue_rule'
|
||||
|
||||
awk -F '\t' '
|
||||
BEGIN {
|
||||
required["source_id"] = 1
|
||||
required["source_label"] = 1
|
||||
required["source_category"] = 1
|
||||
required["input_mode"] = 1
|
||||
required["raw_dir"] = 1
|
||||
required["original_ref"] = 1
|
||||
required["ingest_text"] = 1
|
||||
required["adapter_name"] = 1
|
||||
required["fallback_hint"] = 1
|
||||
}
|
||||
NR == 1 { next }
|
||||
{
|
||||
if ($1 == "" || $2 == "" || $3 == "" || $4 == "") {
|
||||
printf("source-record-contract.tsv 第 %d 行存在空字段\n", NR) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
seen[$1] += 1
|
||||
}
|
||||
END {
|
||||
for (field in required) {
|
||||
if (seen[field] != 1) {
|
||||
printf("source-record-contract.tsv 缺少或重复字段:%s\n", field) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
}
|
||||
|
||||
exit failed ? 1 : 0
|
||||
}
|
||||
' "$CONTRACT_FILE"
|
||||
}
|
||||
|
||||
validate_registry() {
|
||||
require_file "$REGISTRY_FILE"
|
||||
expect_header "$REGISTRY_FILE" $'source_id\tsource_label\tsource_category\tinput_mode\tmatch_rule\traw_dir\tadapter_name\tdependency_name\tdependency_type\tfallback_hint'
|
||||
|
||||
awk -F '\t' '
|
||||
NR == 1 { next }
|
||||
{
|
||||
if ($1 == "" || $2 == "" || $3 == "" || $4 == "" || $5 == "" || $6 == "" || $10 == "") {
|
||||
printf("source-registry.tsv 第 %d 行存在空字段\n", NR) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($3 != "core_builtin" && $3 != "optional_adapter" && $3 != "manual_only") {
|
||||
printf("source-registry.tsv 第 %d 行存在未知分类:%s\n", NR, $3) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($4 != "url" && $4 != "file" && $4 != "text" && $4 != "asset") {
|
||||
printf("source-registry.tsv 第 %d 行存在未知输入模式:%s\n", NR, $4) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($4 == "url" && $5 !~ /^url_host:/) {
|
||||
printf("source-registry.tsv 第 %d 行 URL 来源必须声明 url_host 规则:%s\n", NR, $5) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($4 == "file" && $5 !~ /^file_ext:/) {
|
||||
printf("source-registry.tsv 第 %d 行文件来源必须声明 file_ext 规则:%s\n", NR, $5) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($4 == "text" && $5 !~ /^text:/) {
|
||||
printf("source-registry.tsv 第 %d 行文本来源必须声明 text 规则:%s\n", NR, $5) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($4 == "asset" && $5 !~ /^asset:/) {
|
||||
printf("source-registry.tsv 第 %d 行附件来源必须声明 asset 规则:%s\n", NR, $5) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if ($6 !~ /^raw\//) {
|
||||
printf("source-registry.tsv 第 %d 行 raw_dir 必须位于 raw/ 下:%s\n", NR, $6) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if (seen[$1]++) {
|
||||
printf("source-registry.tsv source_id 重复:%s\n", $1) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
category_seen[$3] = 1
|
||||
|
||||
if ($3 == "optional_adapter") {
|
||||
if ($7 == "-" || $8 == "-" || $9 == "none") {
|
||||
printf("source-registry.tsv 第 %d 行 optional_adapter 缺少依赖信息\n", NR) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
} else if ($7 != "-" || $8 != "-" || $9 != "none") {
|
||||
printf("source-registry.tsv 第 %d 行非外挂来源不应声明依赖\n", NR) > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
}
|
||||
END {
|
||||
if (!category_seen["core_builtin"]) {
|
||||
print "source-registry.tsv 缺少 core_builtin 来源" > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if (!category_seen["optional_adapter"]) {
|
||||
print "source-registry.tsv 缺少 optional_adapter 来源" > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
if (!category_seen["manual_only"]) {
|
||||
print "source-registry.tsv 缺少 manual_only 来源" > "/dev/stderr"
|
||||
failed = 1
|
||||
}
|
||||
|
||||
exit failed ? 1 : 0
|
||||
}
|
||||
' "$REGISTRY_FILE"
|
||||
}
|
||||
|
||||
print_contract() {
|
||||
validate_contract
|
||||
cat "$CONTRACT_FILE"
|
||||
}
|
||||
|
||||
print_registry() {
|
||||
validate_registry
|
||||
cat "$REGISTRY_FILE"
|
||||
}
|
||||
|
||||
get_source() {
|
||||
local source_id="$1"
|
||||
|
||||
validate_registry
|
||||
|
||||
awk -F '\t' -v source_id="$source_id" '
|
||||
NR == 1 { next }
|
||||
$1 == source_id {
|
||||
print
|
||||
found = 1
|
||||
}
|
||||
END {
|
||||
exit found ? 0 : 1
|
||||
}
|
||||
' "$REGISTRY_FILE"
|
||||
}
|
||||
|
||||
extract_url_host() {
|
||||
local url="$1"
|
||||
local rest host
|
||||
|
||||
rest="${url#*://}"
|
||||
if [ "$rest" = "$url" ]; then
|
||||
rest="$url"
|
||||
fi
|
||||
|
||||
rest="${rest#*@}"
|
||||
host="${rest%%/*}"
|
||||
host="${host%%\?*}"
|
||||
host="${host%%#*}"
|
||||
host="${host%%:*}"
|
||||
|
||||
printf '%s\n' "$host" | tr '[:upper:]' '[:lower:]'
|
||||
}
|
||||
|
||||
host_matches_pattern() {
|
||||
local host="$1"
|
||||
local pattern="$2"
|
||||
|
||||
case "$host" in
|
||||
"$pattern"|*."$pattern")
|
||||
return 0
|
||||
;;
|
||||
*)
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
match_url() {
|
||||
local url="$1"
|
||||
local host row source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint
|
||||
local fallback_row=""
|
||||
local pattern pattern_list
|
||||
|
||||
validate_registry
|
||||
host="$(extract_url_host "$url")"
|
||||
|
||||
while IFS=$'\t' read -r source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint; do
|
||||
[ "$source_id" = "source_id" ] && continue
|
||||
[ "$input_mode" = "url" ] || continue
|
||||
|
||||
pattern_list="${match_rule#url_host:}"
|
||||
if [ "$pattern_list" = "*" ]; then
|
||||
fallback_row="$(printf '%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\n' "$source_id" "$source_label" "$source_category" "$input_mode" "$match_rule" "$raw_dir" "$adapter_name" "$dependency_name" "$dependency_type" "$fallback_hint")"
|
||||
continue
|
||||
fi
|
||||
|
||||
for pattern in ${pattern_list//,/ }; do
|
||||
if host_matches_pattern "$host" "$pattern"; then
|
||||
printf '%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\n' "$source_id" "$source_label" "$source_category" "$input_mode" "$match_rule" "$raw_dir" "$adapter_name" "$dependency_name" "$dependency_type" "$fallback_hint"
|
||||
return 0
|
||||
fi
|
||||
done
|
||||
done < "$REGISTRY_FILE"
|
||||
|
||||
[ -n "$fallback_row" ] || return 1
|
||||
printf '%s\n' "$fallback_row"
|
||||
}
|
||||
|
||||
match_file() {
|
||||
local path="$1"
|
||||
local lowered_path source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint
|
||||
local extension_list extension
|
||||
|
||||
validate_registry
|
||||
lowered_path="$(printf '%s\n' "$path" | tr '[:upper:]' '[:lower:]')"
|
||||
|
||||
while IFS=$'\t' read -r source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint; do
|
||||
[ "$source_id" = "source_id" ] && continue
|
||||
[ "$input_mode" = "file" ] || continue
|
||||
|
||||
extension_list="${match_rule#file_ext:}"
|
||||
for extension in ${extension_list//,/ }; do
|
||||
case "$lowered_path" in
|
||||
*"$extension")
|
||||
printf '%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\t%s\n' "$source_id" "$source_label" "$source_category" "$input_mode" "$match_rule" "$raw_dir" "$adapter_name" "$dependency_name" "$dependency_type" "$fallback_hint"
|
||||
return 0
|
||||
;;
|
||||
esac
|
||||
done
|
||||
done < "$REGISTRY_FILE"
|
||||
|
||||
return 1
|
||||
}
|
||||
|
||||
list_by_category() {
|
||||
local category="$1"
|
||||
|
||||
validate_registry
|
||||
|
||||
awk -F '\t' -v category="$category" '
|
||||
NR == 1 { next }
|
||||
$3 == category { print }
|
||||
' "$REGISTRY_FILE"
|
||||
}
|
||||
|
||||
list_unique_dependencies() {
|
||||
local dependency_type="$1"
|
||||
|
||||
validate_registry
|
||||
|
||||
awk -F '\t' -v dependency_type="$dependency_type" '
|
||||
NR == 1 { next }
|
||||
$9 == dependency_type && $8 != "-" { print $8 }
|
||||
' "$REGISTRY_FILE" | sort -u
|
||||
}
|
||||
|
||||
command_name="${1:-}"
|
||||
|
||||
case "$command_name" in
|
||||
fields)
|
||||
[ "$#" -eq 1 ] || { usage; exit 1; }
|
||||
print_contract
|
||||
;;
|
||||
list)
|
||||
[ "$#" -eq 1 ] || { usage; exit 1; }
|
||||
print_registry
|
||||
;;
|
||||
get)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
get_source "$2"
|
||||
;;
|
||||
match-url)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
match_url "$2"
|
||||
;;
|
||||
match-file)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
match_file "$2"
|
||||
;;
|
||||
list-by-category)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
list_by_category "$2"
|
||||
;;
|
||||
unique-dependencies)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
list_unique_dependencies "$2"
|
||||
;;
|
||||
validate)
|
||||
[ "$#" -eq 1 ] || { usage; exit 1; }
|
||||
validate_contract
|
||||
validate_registry
|
||||
;;
|
||||
*)
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
10
llm-wiki/scripts/source-registry.tsv
Normal file
10
llm-wiki/scripts/source-registry.tsv
Normal file
@@ -0,0 +1,10 @@
|
||||
source_id source_label source_category input_mode match_rule raw_dir adapter_name dependency_name dependency_type fallback_hint
|
||||
local_pdf PDF / 本地 PDF core_builtin file file_ext:.pdf raw/pdfs - - none 直接提供文件路径即可进入主线
|
||||
local_document Markdown/文本/HTML core_builtin file file_ext:.md,.txt,.html raw/notes - - none 直接提供文件路径即可进入主线
|
||||
plain_text 纯文本粘贴 core_builtin text text:inline raw/notes - - none 直接粘贴正文即可进入主线
|
||||
x_twitter X/Twitter optional_adapter url url_host:x.com,twitter.com raw/tweets baoyu-url-to-markdown baoyu-url-to-markdown bundled 自动提取失败时,改为复制全文粘贴
|
||||
wechat_article 微信公众号 optional_adapter url url_host:mp.weixin.qq.com raw/wechat wechat-article-to-markdown wechat-article-to-markdown install_time 自动提取失败时,在浏览器打开后复制全文粘贴
|
||||
youtube_video YouTube optional_adapter url url_host:youtube.com,youtu.be raw/articles youtube-transcript youtube-transcript bundled 自动提取失败时,提供字幕文件或手动粘贴文本
|
||||
zhihu_article 知乎 optional_adapter url url_host:zhihu.com raw/zhihu baoyu-url-to-markdown baoyu-url-to-markdown bundled 自动提取失败时,改为复制全文粘贴
|
||||
xiaohongshu_post 小红书 manual_only url url_host:xiaohongshu.com,xhslink.com raw/xiaohongshu - - none 请先从 App 或网页复制内容,再粘贴进来
|
||||
web_article 网页文章 optional_adapter url url_host:* raw/articles baoyu-url-to-markdown baoyu-url-to-markdown bundled 自动提取失败时,改为复制全文或保存为本地文件后继续
|
||||
|
83
llm-wiki/scripts/source-signal-coverage.js
Normal file
83
llm-wiki/scripts/source-signal-coverage.js
Normal file
@@ -0,0 +1,83 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const fs = require("fs");
|
||||
const path = require("path");
|
||||
const {
|
||||
SCAN_KINDS,
|
||||
extractFrontmatter,
|
||||
evaluateSourceSignalEligibility
|
||||
} = require("./lib/source-signal-eligibility");
|
||||
|
||||
function scanWiki(wikiRoot) {
|
||||
const wikiDir = path.join(wikiRoot, "wiki");
|
||||
if (!fs.existsSync(wikiDir)) {
|
||||
console.error(`ERROR: wiki 目录不存在:${wikiDir}`);
|
||||
process.exit(1);
|
||||
}
|
||||
|
||||
const pages = [];
|
||||
const summary = {
|
||||
applicable_total: 0,
|
||||
ok: 0,
|
||||
missing_sources: 0,
|
||||
empty_sources: 0,
|
||||
invalid_sources: 0,
|
||||
not_applicable: 0
|
||||
};
|
||||
|
||||
for (const kind of SCAN_KINDS) {
|
||||
const dir = path.join(wikiDir, kind.subdir);
|
||||
if (!fs.existsSync(dir)) continue;
|
||||
|
||||
const files = fs.readdirSync(dir)
|
||||
.filter((f) => f.endsWith(".md"))
|
||||
.sort();
|
||||
|
||||
for (const file of files) {
|
||||
const id = path.basename(file, ".md");
|
||||
if (["index", "log", "purpose", ".wiki-schema", "README"].includes(id)) continue;
|
||||
|
||||
const filePath = path.join(dir, file);
|
||||
const raw = fs.readFileSync(filePath, "utf8");
|
||||
const { frontmatter } = extractFrontmatter(raw);
|
||||
const result = evaluateSourceSignalEligibility({
|
||||
pageType: kind.pageType,
|
||||
frontmatter
|
||||
});
|
||||
|
||||
pages.push({
|
||||
path: path.relative(wikiRoot, filePath),
|
||||
id,
|
||||
pageType: kind.pageType,
|
||||
eligible: result.eligible,
|
||||
reason: result.reason,
|
||||
sourceCount: result.sources.length
|
||||
});
|
||||
|
||||
summary[result.reason] += 1;
|
||||
if (result.reason !== "not_applicable") {
|
||||
summary.applicable_total += 1;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return { summary, pages };
|
||||
}
|
||||
|
||||
function main(argv) {
|
||||
if (argv.length < 3) {
|
||||
console.error("Usage: node scripts/source-signal-coverage.js <wiki_root>");
|
||||
process.exit(1);
|
||||
}
|
||||
|
||||
const wikiRoot = path.resolve(argv[2]);
|
||||
const result = scanWiki(wikiRoot);
|
||||
console.log(JSON.stringify(result, null, 2));
|
||||
}
|
||||
|
||||
if (require.main === module) {
|
||||
main(process.argv);
|
||||
}
|
||||
|
||||
module.exports = { scanWiki };
|
||||
144
llm-wiki/scripts/validate-step1.sh
Executable file
144
llm-wiki/scripts/validate-step1.sh
Executable file
@@ -0,0 +1,144 @@
|
||||
#!/bin/bash
|
||||
# 验证 ingest Step 1 的 JSON 输出格式
|
||||
# 用法:bash validate-step1.sh <json_file>
|
||||
# 返回:0 = 格式正确,1 = 格式有问题(触发回退)
|
||||
|
||||
SCRIPT_DIR="${BASH_SOURCE[0]%/*}"
|
||||
[ "$SCRIPT_DIR" = "${BASH_SOURCE[0]}" ] && SCRIPT_DIR="."
|
||||
SCRIPT_DIR="$(cd "$SCRIPT_DIR" && pwd)"
|
||||
# shellcheck disable=SC1091
|
||||
source "$SCRIPT_DIR/shared-config.sh"
|
||||
|
||||
JSON_FILE="$1"
|
||||
|
||||
# 参数检查
|
||||
[ -z "$1" ] && { echo "ERROR: usage: validate-step1.sh <json_file>"; exit 1; }
|
||||
|
||||
# 检查 jq 是否可用(必需依赖)
|
||||
command -v jq >/dev/null 2>&1 || {
|
||||
echo "ERROR: jq is not installed. Install it via:" >&2
|
||||
print_install_hint jq
|
||||
exit 1
|
||||
}
|
||||
|
||||
# 检查文件是否存在
|
||||
[ -f "$JSON_FILE" ] || { echo "ERROR: file not found: $JSON_FILE"; exit 1; }
|
||||
|
||||
# 检查是否是有效 JSON
|
||||
jq empty "$JSON_FILE" 2>/dev/null || { echo "ERROR: invalid JSON format"; exit 1; }
|
||||
|
||||
# 检查必需字段存在且类型正确
|
||||
jq -e '.entities | type == "array"' "$JSON_FILE" >/dev/null 2>&1 || { echo "ERROR: 'entities' must be an array"; exit 1; }
|
||||
jq -e '.topics | type == "array"' "$JSON_FILE" >/dev/null 2>&1 || { echo "ERROR: 'topics' must be an array"; exit 1; }
|
||||
jq -e '.connections | type == "array"' "$JSON_FILE" >/dev/null 2>&1 || { echo "ERROR: 'connections' must be an array"; exit 1; }
|
||||
jq -e '.contradictions | type == "array"' "$JSON_FILE" >/dev/null 2>&1 || { echo "ERROR: 'contradictions' must be an array"; exit 1; }
|
||||
jq -e '.new_vs_existing | type == "object"' "$JSON_FILE" >/dev/null 2>&1 || { echo "ERROR: 'new_vs_existing' must be an object"; exit 1; }
|
||||
|
||||
# 检查每个 entity 的必需子字段
|
||||
VALID_CONFIDENCE="EXTRACTED|INFERRED|AMBIGUOUS|UNVERIFIED"
|
||||
|
||||
ENTITY_COUNT=$(jq '.entities | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$ENTITY_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
NON_OBJECT_ENTITY_COUNT=$(jq '[.entities[] | select(type != "object")] | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$NON_OBJECT_ENTITY_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $NON_OBJECT_ENTITY_COUNT entity/entities must be objects"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# name, type, confidence 必须存在且非空
|
||||
BAD_ENTITY_COUNT=$(jq '
|
||||
[.entities[] | select(
|
||||
(.name // "" | length) == 0 or
|
||||
(.type // "" | length) == 0 or
|
||||
(.confidence // "" | length) == 0
|
||||
)] | length
|
||||
' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$BAD_ENTITY_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $BAD_ENTITY_COUNT entity/entities missing required fields (name/type/confidence)"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# confidence 值必须是四个有效值之一
|
||||
INVALID=$(jq -r '.entities[]? | (.confidence // "MISSING")' "$JSON_FILE" 2>/dev/null | \
|
||||
grep -v -E "^($VALID_CONFIDENCE)$" | head -3)
|
||||
if [ -n "$INVALID" ]; then
|
||||
echo "ERROR: invalid entity confidence value(s): $INVALID"
|
||||
echo " Valid values: EXTRACTED | INFERRED | AMBIGUOUS | UNVERIFIED"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# EXTRACTED 和 INFERRED 必须提供 evidence 字段
|
||||
NO_EVIDENCE_COUNT=$(jq '
|
||||
[.entities[] | select(
|
||||
(.confidence == "EXTRACTED" or .confidence == "INFERRED") and
|
||||
((.evidence // "" | length) == 0)
|
||||
)] | length
|
||||
' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$NO_EVIDENCE_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "WARN: $NO_EVIDENCE_COUNT entity/entities with EXTRACTED/INFERRED confidence missing 'evidence' field"
|
||||
fi
|
||||
fi
|
||||
|
||||
# 检查每个 topic 的必需子字段
|
||||
TOPIC_COUNT=$(jq '.topics | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$TOPIC_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
NON_OBJECT_TOPIC_COUNT=$(jq '[.topics[] | select(type != "object")] | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$NON_OBJECT_TOPIC_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $NON_OBJECT_TOPIC_COUNT topic(s) must be objects"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
BAD_TOPIC_COUNT=$(jq '
|
||||
[.topics[] | select(
|
||||
(.name // "" | length) == 0
|
||||
)] | length
|
||||
' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$BAD_TOPIC_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $BAD_TOPIC_COUNT topic(s) missing required 'name' field"
|
||||
exit 1
|
||||
fi
|
||||
fi
|
||||
|
||||
# 检查每个 connection 的必需子字段(from, to, confidence)
|
||||
CONN_COUNT=$(jq '.connections | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$CONN_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
NON_OBJECT_CONN_COUNT=$(jq '[.connections[] | select(type != "object")] | length' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$NON_OBJECT_CONN_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $NON_OBJECT_CONN_COUNT connection(s) must be objects"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
BAD_CONN_COUNT=$(jq '
|
||||
[.connections[] | select(
|
||||
(.from // "" | length) == 0 or
|
||||
(.to // "" | length) == 0 or
|
||||
(.confidence // "" | length) == 0
|
||||
)] | length
|
||||
' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$BAD_CONN_COUNT" -gt 0 ] 2>/dev/null; then
|
||||
echo "ERROR: $BAD_CONN_COUNT connection(s) missing required fields (from/to/confidence)"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
INVALID_CONN_CONF=$(jq -r '.connections[]? | (.confidence // "MISSING")' "$JSON_FILE" 2>/dev/null | \
|
||||
grep -v -E "^($VALID_CONFIDENCE)$" | head -3)
|
||||
if [ -n "$INVALID_CONN_CONF" ]; then
|
||||
echo "ERROR: invalid connection confidence value(s): $INVALID_CONN_CONF"
|
||||
echo " Valid values: EXTRACTED | INFERRED | AMBIGUOUS | UNVERIFIED"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# EXTRACTED 和 INFERRED connections 必须提供 evidence
|
||||
NO_CONN_EVIDENCE=$(jq '
|
||||
[.connections[] | select(
|
||||
(.confidence == "EXTRACTED" or .confidence == "INFERRED") and
|
||||
((.evidence // "" | length) == 0)
|
||||
)] | length
|
||||
' "$JSON_FILE" 2>/dev/null)
|
||||
if [ "$NO_CONN_EVIDENCE" -gt 0 ] 2>/dev/null; then
|
||||
echo "WARN: $NO_CONN_EVIDENCE connection(s) with EXTRACTED/INFERRED confidence missing 'evidence' field"
|
||||
fi
|
||||
fi
|
||||
|
||||
echo "OK: Step 1 JSON validation passed"
|
||||
exit 0
|
||||
267
llm-wiki/scripts/wiki-compat.sh
Executable file
267
llm-wiki/scripts/wiki-compat.sh
Executable file
@@ -0,0 +1,267 @@
|
||||
#!/bin/bash
|
||||
# 旧知识库兼容脚本:惰性默认、目录检查、按需创建
|
||||
# 原则:migration_required=no,只有确实无法兼容时才引入显式迁移
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
SOURCE_REGISTRY_SCRIPT="$SCRIPT_DIR/source-registry.sh"
|
||||
|
||||
LEGACY_REQUIRED_RAW_DIRS=(
|
||||
"raw/articles"
|
||||
"raw/tweets"
|
||||
"raw/wechat"
|
||||
"raw/pdfs"
|
||||
"raw/notes"
|
||||
"raw/assets"
|
||||
)
|
||||
|
||||
REQUIRED_PATHS=(
|
||||
".wiki-schema.md"
|
||||
"index.md"
|
||||
"log.md"
|
||||
"raw"
|
||||
"wiki"
|
||||
"wiki/entities"
|
||||
"wiki/topics"
|
||||
"wiki/sources"
|
||||
"wiki/comparisons"
|
||||
"wiki/synthesis"
|
||||
"wiki/overview.md"
|
||||
)
|
||||
|
||||
usage() {
|
||||
cat <<'EOF'
|
||||
用法:
|
||||
bash scripts/wiki-compat.sh inspect <wiki_root>
|
||||
bash scripts/wiki-compat.sh validate <wiki_root>
|
||||
bash scripts/wiki-compat.sh ensure-source-dir <wiki_root> <source_id>
|
||||
EOF
|
||||
}
|
||||
|
||||
trim() {
|
||||
printf '%s' "$1" | awk '{ gsub(/^[[:space:]]+|[[:space:]]+$/, "", $0); printf "%s", $0 }'
|
||||
}
|
||||
|
||||
require_wiki_root() {
|
||||
local wiki_root="$1"
|
||||
|
||||
[ -n "$wiki_root" ] || {
|
||||
usage
|
||||
exit 1
|
||||
}
|
||||
|
||||
[ -d "$wiki_root" ] || {
|
||||
echo "知识库不存在:$wiki_root" >&2
|
||||
exit 1
|
||||
}
|
||||
}
|
||||
|
||||
schema_field_value() {
|
||||
local wiki_root="$1"
|
||||
local field_name="$2"
|
||||
local default_value="$3"
|
||||
local schema_path value
|
||||
|
||||
schema_path="$wiki_root/.wiki-schema.md"
|
||||
|
||||
if [ ! -f "$schema_path" ]; then
|
||||
printf '%s\n' "$default_value"
|
||||
return 0
|
||||
fi
|
||||
|
||||
value="$(
|
||||
awk -v field_name="$field_name" '
|
||||
$0 ~ "^-[[:space:]]*" field_name "[::]" {
|
||||
line = $0
|
||||
sub("^-[[:space:]]*" field_name "[::][[:space:]]*", "", line)
|
||||
print line
|
||||
exit
|
||||
}
|
||||
' "$schema_path"
|
||||
)"
|
||||
|
||||
value="$(trim "$value")"
|
||||
|
||||
if [ -n "$value" ]; then
|
||||
printf '%s\n' "$value"
|
||||
else
|
||||
printf '%s\n' "$default_value"
|
||||
fi
|
||||
}
|
||||
|
||||
resolved_language() {
|
||||
local wiki_root="$1"
|
||||
local raw_value
|
||||
|
||||
raw_value="$(schema_field_value "$wiki_root" "语言" "")"
|
||||
|
||||
case "$raw_value" in
|
||||
English|english|EN|en)
|
||||
printf 'en\n'
|
||||
;;
|
||||
*)
|
||||
printf 'zh\n'
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
resolved_schema_version() {
|
||||
local wiki_root="$1"
|
||||
|
||||
schema_field_value "$wiki_root" "版本" "1.0"
|
||||
}
|
||||
|
||||
is_legacy_required_raw_dir() {
|
||||
case "$1" in
|
||||
raw/articles|raw/tweets|raw/wechat|raw/pdfs|raw/notes|raw/assets)
|
||||
return 0
|
||||
;;
|
||||
*)
|
||||
return 1
|
||||
;;
|
||||
esac
|
||||
}
|
||||
|
||||
missing_optional_raw_dirs() {
|
||||
local wiki_root="$1"
|
||||
local raw_dir
|
||||
local missing=()
|
||||
|
||||
while IFS= read -r raw_dir; do
|
||||
[ -n "$raw_dir" ] || continue
|
||||
|
||||
if is_legacy_required_raw_dir "$raw_dir"; then
|
||||
continue
|
||||
fi
|
||||
|
||||
if [ ! -d "$wiki_root/$raw_dir" ]; then
|
||||
missing+=("$raw_dir")
|
||||
fi
|
||||
done < <(
|
||||
bash "$SOURCE_REGISTRY_SCRIPT" list | awk -F '\t' 'NR > 1 { print $6 }' | LC_ALL=C sort -u
|
||||
)
|
||||
|
||||
if [ "${#missing[@]}" -eq 0 ]; then
|
||||
printf '%s\n' '-'
|
||||
else
|
||||
local IFS=,
|
||||
printf '%s\n' "${missing[*]}"
|
||||
fi
|
||||
}
|
||||
|
||||
file_presence() {
|
||||
local wiki_root="$1"
|
||||
local relative_path="$2"
|
||||
|
||||
if [ -e "$wiki_root/$relative_path" ]; then
|
||||
printf 'present\n'
|
||||
else
|
||||
printf 'missing\n'
|
||||
fi
|
||||
}
|
||||
|
||||
validate_layout() {
|
||||
local wiki_root="$1"
|
||||
local failed=0
|
||||
local path
|
||||
|
||||
require_wiki_root "$wiki_root"
|
||||
|
||||
for path in "${REQUIRED_PATHS[@]}"; do
|
||||
if [ ! -e "$wiki_root/$path" ]; then
|
||||
echo "缺少必要路径:$path" >&2
|
||||
failed=1
|
||||
fi
|
||||
done
|
||||
|
||||
for path in "${LEGACY_REQUIRED_RAW_DIRS[@]}"; do
|
||||
if [ ! -d "$wiki_root/$path" ]; then
|
||||
echo "缺少必要旧目录:$path" >&2
|
||||
failed=1
|
||||
fi
|
||||
done
|
||||
|
||||
if [ "$failed" -ne 0 ]; then
|
||||
exit 1
|
||||
fi
|
||||
}
|
||||
|
||||
source_raw_dir() {
|
||||
local source_id="$1"
|
||||
local record raw_dir
|
||||
|
||||
record="$(
|
||||
bash "$SOURCE_REGISTRY_SCRIPT" get "$source_id" 2>/dev/null
|
||||
)" || {
|
||||
echo "未知来源:$source_id" >&2
|
||||
exit 1
|
||||
}
|
||||
|
||||
IFS=$'\t' read -r _ _ _ _ _ raw_dir _ _ _ _ <<EOF
|
||||
$record
|
||||
EOF
|
||||
|
||||
printf '%s\n' "$raw_dir"
|
||||
}
|
||||
|
||||
print_inspect() {
|
||||
local wiki_root="$1"
|
||||
local schema_version language optional_dirs legacy_mode purpose_file cache_file
|
||||
|
||||
validate_layout "$wiki_root"
|
||||
|
||||
schema_version="$(resolved_schema_version "$wiki_root")"
|
||||
language="$(resolved_language "$wiki_root")"
|
||||
optional_dirs="$(missing_optional_raw_dirs "$wiki_root")"
|
||||
purpose_file="$(file_presence "$wiki_root" "purpose.md")"
|
||||
cache_file="$(file_presence "$wiki_root" ".wiki-cache.json")"
|
||||
|
||||
if [ "$schema_version" = "1.0" ] || [ "$optional_dirs" != "-" ] || [ "$purpose_file" = "missing" ] || [ "$cache_file" = "missing" ]; then
|
||||
legacy_mode="yes"
|
||||
else
|
||||
legacy_mode="no"
|
||||
fi
|
||||
|
||||
printf 'wiki_root=%s\n' "$wiki_root"
|
||||
printf 'schema_version=%s\n' "$schema_version"
|
||||
printf 'language=%s\n' "$language"
|
||||
printf 'legacy_mode=%s\n' "$legacy_mode"
|
||||
printf 'migration_required=no\n'
|
||||
printf 'missing_optional_raw_dirs=%s\n' "$optional_dirs"
|
||||
printf 'purpose_file=%s\n' "$purpose_file"
|
||||
printf 'cache_file=%s\n' "$cache_file"
|
||||
}
|
||||
|
||||
ensure_source_dir() {
|
||||
local wiki_root="$1"
|
||||
local source_id="$2"
|
||||
local raw_dir
|
||||
|
||||
validate_layout "$wiki_root"
|
||||
raw_dir="$(source_raw_dir "$source_id")"
|
||||
|
||||
mkdir -p "$wiki_root/$raw_dir"
|
||||
printf '%s\n' "$wiki_root/$raw_dir"
|
||||
}
|
||||
|
||||
command_name="${1:-}"
|
||||
|
||||
case "$command_name" in
|
||||
inspect)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
print_inspect "$2"
|
||||
;;
|
||||
validate)
|
||||
[ "$#" -eq 2 ] || { usage; exit 1; }
|
||||
print_inspect "$2" > /dev/null
|
||||
;;
|
||||
ensure-source-dir)
|
||||
[ "$#" -eq 3 ] || { usage; exit 1; }
|
||||
ensure_source_dir "$2" "$3"
|
||||
;;
|
||||
*)
|
||||
usage
|
||||
exit 1
|
||||
;;
|
||||
esac
|
||||
371
llm-wiki/scripts/wiki-link-cli.js
Normal file
371
llm-wiki/scripts/wiki-link-cli.js
Normal file
@@ -0,0 +1,371 @@
|
||||
#!/usr/bin/env node
|
||||
"use strict";
|
||||
|
||||
const fs = require("node:fs");
|
||||
const path = require("node:path");
|
||||
const {
|
||||
assembleGraphArtifactPair,
|
||||
commitGraphArtifactPair,
|
||||
prepareOfflineWarningPayload,
|
||||
serializeJsonForHtmlScript,
|
||||
verifyGraphArtifactPair
|
||||
} = require("./lib/graph-warning-bundle");
|
||||
const { normalizeRelativePosixPath } = require("./lib/wiki-file-discovery");
|
||||
const { scanKnowledgeBaseLinks, validatePortableMarkdownFilename } = require("./lib/wiki-link-index");
|
||||
const { renderWikilinkReplacement } = require("./lib/wikilink-parser");
|
||||
|
||||
function usage() {
|
||||
return [
|
||||
"Usage:",
|
||||
" node scripts/wiki-link-cli.js graph <kb-root> <output-dir> [--test-mode]",
|
||||
" node scripts/wiki-link-cli.js commit-pair <kb-root> <graph-input> <warning-groups> <candidate-sets> <graph-path>",
|
||||
" node scripts/wiki-link-cli.js warning-embed <kb-root> <graph-path> <warning-path> <output-path>",
|
||||
" node scripts/wiki-link-cli.js check <kb-root> [--strict] [--json]",
|
||||
" node scripts/wiki-link-cli.js rename-scan <kb-root> <source-path> <new-name>"
|
||||
].join("\n");
|
||||
}
|
||||
|
||||
function sanitizeEntries(entries) {
|
||||
return entries.map((item) => ({
|
||||
path: item.path,
|
||||
kind: item.kind,
|
||||
editable: item.editable,
|
||||
graphType: item.graphType
|
||||
}));
|
||||
}
|
||||
|
||||
function sanitizeInventory(inventory) {
|
||||
return {
|
||||
graphSources: sanitizeEntries(inventory.graphSources),
|
||||
lintSources: sanitizeEntries(inventory.lintSources),
|
||||
renameEditableSources: sanitizeEntries(inventory.renameEditableSources),
|
||||
renameReadOnlySources: sanitizeEntries(inventory.renameReadOnlySources),
|
||||
targets: sanitizeEntries(inventory.targets),
|
||||
fileSetSha256: inventory.fileSetSha256
|
||||
};
|
||||
}
|
||||
|
||||
function hasStrictErrors(report) {
|
||||
return report.groups.some((group) => group.severity === "error");
|
||||
}
|
||||
|
||||
function buildCheckReport(kbRoot, policy) {
|
||||
const scan = scanKnowledgeBaseLinks(kbRoot, policy);
|
||||
return {
|
||||
policy,
|
||||
inventory: sanitizeInventory(scan.inventory),
|
||||
edges: scan.edges,
|
||||
candidate_sets: scan.candidate_sets,
|
||||
groups: scan.groups,
|
||||
occurrences: scan.occurrences,
|
||||
source_metadata: scan.source_documents.map(({ _content, ...document }) => document),
|
||||
stale_pending_wrappers: scan.stale_pending_wrappers,
|
||||
metrics: scan.metrics
|
||||
};
|
||||
}
|
||||
|
||||
function writeJson(filePath, value) {
|
||||
fs.writeFileSync(filePath, `${JSON.stringify(value, null, 2)}\n`, "utf8");
|
||||
}
|
||||
|
||||
function writeGraphScanFiles(kbRoot, outputDir) {
|
||||
const scan = scanKnowledgeBaseLinks(kbRoot, "graph");
|
||||
fs.mkdirSync(outputDir, { recursive: true });
|
||||
const nodes = scan.source_documents
|
||||
.filter((document) => document.graph_type)
|
||||
.map((document) => ({
|
||||
id: document.source_path,
|
||||
label: document.label,
|
||||
type: document.graph_type,
|
||||
source_path: document.source_path,
|
||||
_content: document._content,
|
||||
_signals: document._signals
|
||||
}))
|
||||
.sort((left, right) => left.id.localeCompare(right.id, "en"));
|
||||
const edges = scan.edges.map((edge, index) => ({
|
||||
id: `e${index + 1}`,
|
||||
from: edge.from,
|
||||
to: edge.to,
|
||||
type: edge.confidence,
|
||||
confidence: edge.confidence,
|
||||
relation_type: edge.relation_type
|
||||
}));
|
||||
writeJson(path.join(outputDir, "nodes.json"), nodes);
|
||||
writeJson(path.join(outputDir, "edges.json"), edges);
|
||||
writeJson(path.join(outputDir, "warning-groups.json"), scan.groups);
|
||||
writeJson(path.join(outputDir, "candidate-sets.json"), scan.candidate_sets);
|
||||
writeJson(path.join(outputDir, "scan-metrics.json"), scan.metrics);
|
||||
return { nodes, edges, scan };
|
||||
}
|
||||
|
||||
async function commitPair(args) {
|
||||
const graphData = JSON.parse(fs.readFileSync(args.graphInput, "utf8"));
|
||||
const groups = JSON.parse(fs.readFileSync(args.warningGroups, "utf8"));
|
||||
const candidateSets = JSON.parse(fs.readFileSync(args.candidateSets, "utf8"));
|
||||
const kbRootReal = fs.realpathSync.native(args.kbRoot);
|
||||
const requestedGraphPath = path.resolve(args.graphPath);
|
||||
const graphPath = path.join(
|
||||
fs.realpathSync.native(path.dirname(requestedGraphPath)),
|
||||
path.basename(requestedGraphPath)
|
||||
);
|
||||
const warningPath = path.join(path.dirname(graphPath), "graph-warnings.json");
|
||||
const detailsRef = path.relative(kbRootReal, warningPath).split(path.sep).join("/");
|
||||
const pair = assembleGraphArtifactPair({ graphData, groups, candidateSets, detailsRef });
|
||||
await commitGraphArtifactPair({
|
||||
kbRoot: kbRootReal,
|
||||
graphPath,
|
||||
warningPath,
|
||||
pair
|
||||
});
|
||||
}
|
||||
|
||||
async function writeWarningEmbed(args) {
|
||||
const verified = await verifyGraphArtifactPair({
|
||||
kbRoot: args.kbRoot,
|
||||
graphPath: args.graphPath,
|
||||
warningPath: args.warningPath
|
||||
});
|
||||
let payload;
|
||||
let scriptBytes;
|
||||
if (verified.status === "available") {
|
||||
const prepared = prepareOfflineWarningPayload({
|
||||
summary: verified.graphData.meta.warning_summary,
|
||||
bundle: verified.warningBundle
|
||||
});
|
||||
payload = prepared.payload;
|
||||
scriptBytes = prepared.scriptBytes;
|
||||
} else {
|
||||
payload = {
|
||||
summary: sanitizeUnavailableSummary(verified.summary),
|
||||
details_status: "unavailable",
|
||||
details_unavailable_reason: verified.reason,
|
||||
warning_details_truncated: false,
|
||||
omitted_group_count: 0,
|
||||
omitted_candidate_set_count: 0
|
||||
};
|
||||
scriptBytes = serializeJsonForHtmlScript(payload);
|
||||
}
|
||||
fs.writeFileSync(args.outputPath, scriptBytes);
|
||||
}
|
||||
|
||||
function sanitizeUnavailableSummary(summary) {
|
||||
if (!summary || typeof summary !== "object") return {};
|
||||
const safe = {};
|
||||
for (const key of ["build_id", "details_sha256"]) {
|
||||
if (typeof summary[key] === "string" && /^[a-f0-9]{64}$/.test(summary[key])) {
|
||||
safe[key] = summary[key];
|
||||
}
|
||||
}
|
||||
for (const key of ["total_groups", "total_occurrences", "error_occurrences", "warning_occurrences"]) {
|
||||
if (Number.isSafeInteger(summary[key]) && summary[key] >= 0) safe[key] = summary[key];
|
||||
}
|
||||
if (summary.by_code && typeof summary.by_code === "object" && !Array.isArray(summary.by_code)) {
|
||||
safe.by_code = Object.fromEntries(
|
||||
Object.entries(summary.by_code)
|
||||
.filter(([, count]) => Number.isSafeInteger(count) && count >= 0),
|
||||
);
|
||||
}
|
||||
if (typeof summary.details_ref === "string") {
|
||||
try {
|
||||
const normalized = normalizeRelativePosixPath(summary.details_ref);
|
||||
if (normalized === summary.details_ref && path.posix.basename(normalized) === "graph-warnings.json") {
|
||||
safe.details_ref = normalized;
|
||||
}
|
||||
} catch (_) {
|
||||
// Never copy an invalid or machine-local path into an offline artifact.
|
||||
}
|
||||
}
|
||||
return safe;
|
||||
}
|
||||
|
||||
function replacementTargetForOccurrence(occurrence, targetPath) {
|
||||
return targetPath;
|
||||
}
|
||||
|
||||
function buildRenameScanReport(kbRoot, sourcePath, newName) {
|
||||
const scan = scanKnowledgeBaseLinks(kbRoot, "rename");
|
||||
const candidateSets = new Map(scan.candidate_sets.map((item) => [item.candidate_set_id, item.candidates]));
|
||||
const sourceEntry = scan.inventory.graphSources.find((item) => item.path === sourcePath);
|
||||
if (!sourceEntry) {
|
||||
throw new Error(`Source is not a formal graph page: ${sourcePath}`);
|
||||
}
|
||||
|
||||
const validation = validatePortableMarkdownFilename(sourcePath, newName, scan.inventory.targets);
|
||||
if (!validation.ok) {
|
||||
throw new Error(`Invalid target name (${validation.reason}): ${newName}`);
|
||||
}
|
||||
|
||||
const renameTargetPath = validation.target_path;
|
||||
const editable = [];
|
||||
const readOnly = [];
|
||||
const ambiguous = [];
|
||||
|
||||
for (const occurrence of scan.occurrences) {
|
||||
const destination = occurrence.read_only ? readOnly : editable;
|
||||
const resolution = occurrence.resolution;
|
||||
|
||||
if (resolution.status === "resolved" && resolution.target_path === sourcePath) {
|
||||
destination.push({
|
||||
source_path: occurrence.source_path,
|
||||
file_sha256: occurrence.file_sha256,
|
||||
start_byte: occurrence.start_byte,
|
||||
end_byte: occurrence.end_byte,
|
||||
raw_link: occurrence.raw_link,
|
||||
replacement: renderWikilinkReplacement(
|
||||
occurrence,
|
||||
replacementTargetForOccurrence(occurrence, renameTargetPath)
|
||||
)
|
||||
});
|
||||
continue;
|
||||
}
|
||||
|
||||
const candidatePaths = candidateSets.get(resolution.candidate_set_id) || [];
|
||||
if (resolution.status === "ambiguous" && candidatePaths.includes(sourcePath)) {
|
||||
const rendered_candidates = candidatePaths.map((candidatePath) => ({
|
||||
candidate_path: candidatePath,
|
||||
replacement: renderWikilinkReplacement(
|
||||
occurrence,
|
||||
candidatePath === sourcePath
|
||||
? replacementTargetForOccurrence(occurrence, renameTargetPath)
|
||||
: candidatePath
|
||||
)
|
||||
}));
|
||||
ambiguous.push({
|
||||
source_path: occurrence.source_path,
|
||||
classification: occurrence.read_only ? "read_only" : "editable",
|
||||
read_only: occurrence.read_only,
|
||||
file_sha256: occurrence.file_sha256,
|
||||
start_byte: occurrence.start_byte,
|
||||
end_byte: occurrence.end_byte,
|
||||
raw_link: occurrence.raw_link,
|
||||
candidate_paths: candidatePaths,
|
||||
rendered_candidates
|
||||
});
|
||||
}
|
||||
}
|
||||
|
||||
return {
|
||||
file_set_sha256: scan.inventory.fileSetSha256,
|
||||
source_path: sourcePath,
|
||||
target_path: renameTargetPath,
|
||||
validation,
|
||||
editable_occurrences: editable,
|
||||
read_only_occurrences: readOnly,
|
||||
ambiguous_occurrences: ambiguous,
|
||||
metrics: scan.metrics
|
||||
};
|
||||
}
|
||||
|
||||
function assertExactFlags(flags, allowedFlags) {
|
||||
const seen = new Set();
|
||||
for (const flag of flags) {
|
||||
if (!allowedFlags.has(flag)) {
|
||||
throw new Error(`Unknown argument: ${flag}`);
|
||||
}
|
||||
if (seen.has(flag)) {
|
||||
throw new Error(`Duplicate argument: ${flag}`);
|
||||
}
|
||||
seen.add(flag);
|
||||
}
|
||||
return seen;
|
||||
}
|
||||
|
||||
function parseArguments(command, rest) {
|
||||
if (command === "graph") {
|
||||
if (rest.length < 2 || rest.length > 3 || rest[0].startsWith("--") || rest[1].startsWith("--")) {
|
||||
throw new Error("graph requires <kb-root> <output-dir> [--test-mode]");
|
||||
}
|
||||
const flags = assertExactFlags(rest.slice(2), new Set(["--test-mode"]));
|
||||
return { kbRoot: rest[0], outputDir: rest[1], testMode: flags.has("--test-mode") };
|
||||
}
|
||||
|
||||
if (command === "check") {
|
||||
if (rest.length < 1 || rest[0].startsWith("--")) {
|
||||
throw new Error("check requires <kb-root> [--strict] [--json]");
|
||||
}
|
||||
const flags = assertExactFlags(rest.slice(1), new Set(["--strict", "--json"]));
|
||||
return { kbRoot: rest[0], strict: flags.has("--strict"), json: flags.has("--json") };
|
||||
}
|
||||
|
||||
if (command === "commit-pair") {
|
||||
if (rest.length !== 5 || rest.some((value) => value.startsWith("--"))) {
|
||||
throw new Error("commit-pair requires <kb-root> <graph-input> <warning-groups> <candidate-sets> <graph-path>");
|
||||
}
|
||||
return {
|
||||
kbRoot: rest[0],
|
||||
graphInput: rest[1],
|
||||
warningGroups: rest[2],
|
||||
candidateSets: rest[3],
|
||||
graphPath: rest[4]
|
||||
};
|
||||
}
|
||||
|
||||
if (command === "warning-embed") {
|
||||
if (rest.length !== 4 || rest.some((value) => value.startsWith("--"))) {
|
||||
throw new Error("warning-embed requires <kb-root> <graph-path> <warning-path> <output-path>");
|
||||
}
|
||||
return { kbRoot: rest[0], graphPath: rest[1], warningPath: rest[2], outputPath: rest[3] };
|
||||
}
|
||||
|
||||
if (command === "rename-scan") {
|
||||
if (rest.length !== 3 || rest.some((value) => value.startsWith("--"))) {
|
||||
throw new Error("rename-scan requires <kb-root> <source-path> <new-name>");
|
||||
}
|
||||
return { kbRoot: rest[0], sourcePath: rest[1], newName: rest[2] };
|
||||
}
|
||||
|
||||
throw new Error(`Unknown command: ${command}`);
|
||||
}
|
||||
|
||||
async function main(argv) {
|
||||
const [command, ...rest] = argv;
|
||||
|
||||
if (!command) {
|
||||
console.error(usage());
|
||||
return 1;
|
||||
}
|
||||
|
||||
try {
|
||||
const args = parseArguments(command, rest);
|
||||
if (command === "graph") {
|
||||
const result = writeGraphScanFiles(args.kbRoot, args.outputDir);
|
||||
process.stdout.write(`Graph scan wrote ${result.nodes.length} nodes and ${result.edges.length} edges to ${args.outputDir}\n`);
|
||||
return 0;
|
||||
}
|
||||
|
||||
if (command === "commit-pair") {
|
||||
await commitPair(args);
|
||||
process.stdout.write(`Graph artifact pair committed: ${args.graphPath}\n`);
|
||||
return 0;
|
||||
}
|
||||
|
||||
if (command === "warning-embed") {
|
||||
await writeWarningEmbed(args);
|
||||
return 0;
|
||||
}
|
||||
|
||||
if (command === "check") {
|
||||
const report = buildCheckReport(args.kbRoot, "lint");
|
||||
|
||||
process.stdout.write(`${JSON.stringify(report, null, 2)}\n`);
|
||||
return args.strict && hasStrictErrors(report) ? 2 : 0;
|
||||
}
|
||||
|
||||
if (command === "rename-scan") {
|
||||
const report = buildRenameScanReport(args.kbRoot, args.sourcePath, args.newName);
|
||||
process.stdout.write(`${JSON.stringify(report, null, 2)}\n`);
|
||||
return 0;
|
||||
}
|
||||
} catch (error) {
|
||||
console.error(error.message);
|
||||
return 1;
|
||||
}
|
||||
}
|
||||
|
||||
main(process.argv.slice(2)).then(
|
||||
(code) => { process.exitCode = code; },
|
||||
(error) => {
|
||||
console.error(error && error.message ? error.message : String(error));
|
||||
process.exitCode = 1;
|
||||
}
|
||||
);
|
||||
8
llm-wiki/setup.sh
Executable file
8
llm-wiki/setup.sh
Executable file
@@ -0,0 +1,8 @@
|
||||
# 已废弃:请使用 bash install.sh --platform claude
|
||||
#!/bin/bash
|
||||
# Claude 旧入口兼容包装
|
||||
set -euo pipefail
|
||||
|
||||
SCRIPT_DIR="$(cd "$(dirname "$0")" && pwd)"
|
||||
|
||||
exec bash "$SCRIPT_DIR/install.sh" --platform claude "$@"
|
||||
30
llm-wiki/templates/entity-template.md
Normal file
30
llm-wiki/templates/entity-template.md
Normal file
@@ -0,0 +1,30 @@
|
||||
---
|
||||
tags: [实体]
|
||||
created: {{DATE}}
|
||||
updated: {{DATE}}
|
||||
sources: []
|
||||
---
|
||||
|
||||
# {{ENTITY_NAME}}
|
||||
|
||||
> 一句话描述这个实体是什么
|
||||
|
||||
## 简介
|
||||
|
||||
(这个实体的基本介绍)
|
||||
|
||||
## 关键信息
|
||||
|
||||
- **类型**:(人物 / 组织 / 概念 / 工具 / 事件)
|
||||
- **领域**:(所属领域)
|
||||
- **相关概念**:(关联的其他实体)
|
||||
|
||||
## 详细内容
|
||||
|
||||
(从素材中提取的关于这个实体的详细信息)
|
||||
|
||||
## 不同素材中的观点
|
||||
|
||||
(不同素材对同一个实体的不同描述或评价,标注来源)
|
||||
|
||||
## 相关页面
|
||||
51
llm-wiki/templates/index-en-template.md
Normal file
51
llm-wiki/templates/index-en-template.md
Normal file
@@ -0,0 +1,51 @@
|
||||
# Wiki Index
|
||||
|
||||
> Last updated: {{DATE}}
|
||||
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
- Topic: {{TOPIC}}
|
||||
- Total sources: 0
|
||||
- Total wiki pages: 0
|
||||
|
||||
---
|
||||
|
||||
## Entity Pages
|
||||
|
||||
> People, organizations, concepts, tools
|
||||
|
||||
(none yet)
|
||||
|
||||
---
|
||||
|
||||
## Topic Pages
|
||||
|
||||
> Research topics, knowledge domains
|
||||
|
||||
(none yet)
|
||||
|
||||
---
|
||||
|
||||
## Source Summaries
|
||||
|
||||
> One summary page per ingested source
|
||||
|
||||
(none yet)
|
||||
|
||||
---
|
||||
|
||||
## Comparisons
|
||||
|
||||
> Side-by-side analysis of options, tools, viewpoints
|
||||
|
||||
(none yet)
|
||||
|
||||
---
|
||||
|
||||
## Synthesis
|
||||
|
||||
> Deep cross-source analysis
|
||||
|
||||
(none yet)
|
||||
51
llm-wiki/templates/index-template.md
Normal file
51
llm-wiki/templates/index-template.md
Normal file
@@ -0,0 +1,51 @@
|
||||
# 知识库索引
|
||||
|
||||
> 最后更新:{{DATE}}
|
||||
|
||||
---
|
||||
|
||||
## 概览
|
||||
|
||||
- 主题:{{TOPIC}}
|
||||
- 素材总数:0
|
||||
- Wiki 页面总数:0
|
||||
|
||||
---
|
||||
|
||||
## 实体页
|
||||
|
||||
> 人物、组织、概念、工具等
|
||||
|
||||
(暂无)
|
||||
|
||||
---
|
||||
|
||||
## 主题页
|
||||
|
||||
> 研究主题、知识领域
|
||||
|
||||
(暂无)
|
||||
|
||||
---
|
||||
|
||||
## 素材摘要
|
||||
|
||||
> 每个消化过的素材都有一篇摘要
|
||||
|
||||
(暂无)
|
||||
|
||||
---
|
||||
|
||||
## 对比分析
|
||||
|
||||
> 对比不同方案、工具、观点
|
||||
|
||||
(暂无)
|
||||
|
||||
---
|
||||
|
||||
## 综合分析
|
||||
|
||||
> 跨素材的深度分析
|
||||
|
||||
(暂无)
|
||||
11
llm-wiki/templates/log-en-template.md
Normal file
11
llm-wiki/templates/log-en-template.md
Normal file
@@ -0,0 +1,11 @@
|
||||
# Operation Log
|
||||
|
||||
> Records all changes to this wiki
|
||||
|
||||
---
|
||||
|
||||
## {{DATE}} — Initialized
|
||||
|
||||
- **Action**: Created wiki
|
||||
- **Topic**: {{TOPIC}}
|
||||
- **Status**: Done
|
||||
11
llm-wiki/templates/log-template.md
Normal file
11
llm-wiki/templates/log-template.md
Normal file
@@ -0,0 +1,11 @@
|
||||
# 操作日志
|
||||
|
||||
> 记录知识库的所有变更历史
|
||||
|
||||
---
|
||||
|
||||
## {{DATE}} — 初始化
|
||||
|
||||
- **操作**:创建知识库
|
||||
- **主题**:{{TOPIC}}
|
||||
- **状态**:完成
|
||||
41
llm-wiki/templates/overview-en-template.md
Normal file
41
llm-wiki/templates/overview-en-template.md
Normal file
@@ -0,0 +1,41 @@
|
||||
# {{TOPIC}} — Wiki Overview
|
||||
|
||||
> Created: {{DATE}}
|
||||
|
||||
---
|
||||
|
||||
## About this wiki
|
||||
|
||||
This wiki collects all knowledge and sources about **{{TOPIC}}**.
|
||||
|
||||
Each source is digested and organized by AI into interlinked wiki pages. Browse by:
|
||||
|
||||
- **Entity pages**: people, organizations, concepts, tools
|
||||
- **Topic pages**: synthesis around a research theme
|
||||
- **Source summaries**: key takeaways from each source
|
||||
- **Comparisons**: side-by-side analysis of options or viewpoints
|
||||
- **Synthesis**: deep cross-source insights
|
||||
|
||||
---
|
||||
|
||||
## Knowledge map
|
||||
|
||||
(Will show major coverage areas as sources accumulate)
|
||||
|
||||
---
|
||||
|
||||
## Quick navigation
|
||||
|
||||
| Type | Count | View |
|
||||
|------|-------|------|
|
||||
| Sources | 0 | [[Source Summaries]] |
|
||||
| Entities | 0 | [[Entity Pages]] |
|
||||
| Topics | 0 | [[Topic Pages]] |
|
||||
| Comparisons | 0 | [[Comparisons]] |
|
||||
| Synthesis | 0 | [[Synthesis]] |
|
||||
|
||||
---
|
||||
|
||||
## Recent updates
|
||||
|
||||
(none yet)
|
||||
41
llm-wiki/templates/overview-template.md
Normal file
41
llm-wiki/templates/overview-template.md
Normal file
@@ -0,0 +1,41 @@
|
||||
# {{TOPIC}} — 知识库总览
|
||||
|
||||
> 创建于 {{DATE}}
|
||||
|
||||
---
|
||||
|
||||
## 关于这个知识库
|
||||
|
||||
这里收集了关于 **{{TOPIC}}** 的所有知识和素材。
|
||||
|
||||
每个素材都经过 AI 消化和整理,形成了互相链接的 wiki 页面。你可以通过以下方式浏览:
|
||||
|
||||
- **实体页**:人物、组织、概念、工具的详细介绍
|
||||
- **主题页**:围绕某个研究主题的综合分析
|
||||
- **素材摘要**:每篇素材的核心观点提取
|
||||
- **对比分析**:不同方案、工具、观点的横向比较
|
||||
- **综合分析**:跨素材的深度洞察
|
||||
|
||||
---
|
||||
|
||||
## 知识地图
|
||||
|
||||
(随着素材积累,这里会展示知识库覆盖的主要方向)
|
||||
|
||||
---
|
||||
|
||||
## 快速导航
|
||||
|
||||
| 类型 | 数量 | 查看 |
|
||||
|------|------|------|
|
||||
| 素材 | 0 | [[素材摘要]] |
|
||||
| 实体 | 0 | [[实体页]] |
|
||||
| 主题 | 0 | [[主题页]] |
|
||||
| 对比 | 0 | [[对比分析]] |
|
||||
| 综合 | 0 | [[综合分析]] |
|
||||
|
||||
---
|
||||
|
||||
## 最近更新
|
||||
|
||||
(暂无)
|
||||
16
llm-wiki/templates/purpose-en-template.md
Normal file
16
llm-wiki/templates/purpose-en-template.md
Normal file
@@ -0,0 +1,16 @@
|
||||
# Research Purpose and Direction
|
||||
|
||||
## Core Goal
|
||||
<!-- What problem should this wiki solve, and who does it help? -->
|
||||
[To fill]
|
||||
|
||||
## Key Questions
|
||||
<!-- The 3-5 questions you most want this wiki to answer -->
|
||||
1. [To fill]
|
||||
2. [To fill]
|
||||
3. [To fill]
|
||||
|
||||
## Research Scope
|
||||
<!-- What should be covered here, and what stays out of scope? -->
|
||||
**Include:** [To fill]
|
||||
**Exclude:** [To fill]
|
||||
16
llm-wiki/templates/purpose-template.md
Normal file
16
llm-wiki/templates/purpose-template.md
Normal file
@@ -0,0 +1,16 @@
|
||||
# 研究目的与方向
|
||||
|
||||
## 核心目标
|
||||
<!-- 这个知识库要解决什么问题?帮助谁? -->
|
||||
[待填写]
|
||||
|
||||
## 关键问题
|
||||
<!-- 你最想知道答案的 3-5 个问题 -->
|
||||
1. [待填写]
|
||||
2. [待填写]
|
||||
3. [待填写]
|
||||
|
||||
## 研究范围
|
||||
<!-- 涵盖哪些领域/主题?不涵盖什么? -->
|
||||
**涵盖:** [待填写]
|
||||
**不涵盖:** [待填写]
|
||||
19
llm-wiki/templates/query-template.md
Normal file
19
llm-wiki/templates/query-template.md
Normal file
@@ -0,0 +1,19 @@
|
||||
---
|
||||
type: query
|
||||
derived: true
|
||||
title: "{{TITLE}}"
|
||||
created: {{DATE}}
|
||||
updated: {{DATE}}
|
||||
tags: [{{TAGS}}]
|
||||
sources: [{{SOURCES}}]
|
||||
related: [{{RELATED}}]
|
||||
---
|
||||
|
||||
## 问题
|
||||
{{QUESTION}}
|
||||
|
||||
## 回答
|
||||
{{ANSWER}}
|
||||
|
||||
## 引用来源
|
||||
{{SOURCE_LINKS}}
|
||||
185
llm-wiki/templates/schema-template.md
Normal file
185
llm-wiki/templates/schema-template.md
Normal file
@@ -0,0 +1,185 @@
|
||||
# Wiki Schema(知识库配置规范)
|
||||
|
||||
> 这个文件告诉 AI 如何维护你的知识库。你和 AI 可以一起调整它。
|
||||
|
||||
## 知识库信息
|
||||
|
||||
- 主题:{{TOPIC}}
|
||||
- 创建日期:{{DATE}}
|
||||
- 语言:{{LANGUAGE}}
|
||||
- 版本:1.1
|
||||
|
||||
## 目录结构
|
||||
|
||||
```
|
||||
{{WIKI_ROOT}}/
|
||||
├── raw/ # 原始素材(AI 只读,不会修改)
|
||||
│ ├── articles/ # 网页文章
|
||||
│ ├── tweets/ # X/Twitter 内容
|
||||
│ ├── wechat/ # 微信公众号文章
|
||||
│ ├── xiaohongshu/ # 小红书内容
|
||||
│ ├── zhihu/ # 知乎内容
|
||||
│ ├── pdfs/ # PDF 文件
|
||||
│ ├── notes/ # 手写笔记
|
||||
│ └── assets/ # 图片等附件
|
||||
├── wiki/ # 知识库主体(AI 写,你看)
|
||||
│ ├── entities/ # 实体页(人物、组织、概念)
|
||||
│ ├── topics/ # 主题页(研究主题、知识领域)
|
||||
│ ├── sources/ # 素材摘要页(每个素材一篇摘要)
|
||||
│ ├── comparisons/ # 对比分析页
|
||||
│ └── synthesis/ # 综合分析页
|
||||
├── index.md # 内容索引(目录)
|
||||
├── log.md # 操作日志(时间线)
|
||||
└── .wiki-schema.md # 本文件(配置规范)
|
||||
```
|
||||
|
||||
## 页面命名规范
|
||||
|
||||
- 实体页:`wiki/entities/{名称}.md`
|
||||
- 例:`wiki/entities/知识构建.md`、`wiki/entities/Transformer.md`
|
||||
- 主题页:`wiki/topics/{主题名}.md`
|
||||
- 例:`wiki/topics/AI编程工具.md`、`wiki/topics/大语言模型.md`
|
||||
- 素材摘要:`wiki/sources/{日期}-{短标题}.md`
|
||||
- 例:`wiki/sources/2026-04-05-karpathy-llm-wiki.md`
|
||||
- 对比分析:`wiki/comparisons/{对比主题}.md`
|
||||
- 例:`wiki/comparisons/工具选型.md`
|
||||
- 综合分析:`wiki/synthesis/{分析主题}.md`
|
||||
- 例:`wiki/synthesis/AI工具选型建议.md`
|
||||
|
||||
## 交叉引用规范
|
||||
|
||||
- 页面间使用 `[[页面名]]` 语法(Obsidian 兼容的双向链接)
|
||||
- 素材引用格式:`[来源: 素材标题](../sources/xxx.md)`
|
||||
- 每个页面底部维护"相关页面"列表
|
||||
|
||||
## 页面格式规范
|
||||
|
||||
每个 wiki 页面应包含:
|
||||
|
||||
```markdown
|
||||
---
|
||||
tags: [标签1, 标签2]
|
||||
created: YYYY-MM-DD
|
||||
updated: YYYY-MM-DD
|
||||
sources: [关联素材列表]
|
||||
---
|
||||
|
||||
# 页面标题
|
||||
|
||||
> 一句话摘要
|
||||
|
||||
## 正文内容
|
||||
|
||||
...
|
||||
|
||||
## 相关页面
|
||||
|
||||
- [[另一个页面]]
|
||||
- [[又一个页面]]
|
||||
```
|
||||
|
||||
## Ingest(消化素材)规则
|
||||
|
||||
### 分级处理
|
||||
|
||||
根据素材长度和信息密度自动分级:
|
||||
|
||||
**完整处理**(素材 > 1000 字):
|
||||
1. 每个新素材**必须**生成摘要页(`wiki/sources/` 下)
|
||||
2. 从素材中提取 3-5 个关键概念
|
||||
3. 检查是否需要创建新的实体页(`wiki/entities/`)
|
||||
4. 检查是否需要创建或更新主题页(`wiki/topics/`)
|
||||
5. 更新 `index.md`(添加新条目)
|
||||
6. 更新 `log.md`(记录操作)
|
||||
7. 更新 `overview.md`(如果知识库全貌有变化)
|
||||
|
||||
**简化处理**(素材 < 1000 字,如短推文、小红书笔记):
|
||||
1. 生成摘要页(`wiki/sources/` 下)
|
||||
2. 提取 1-3 个关键概念
|
||||
3. 如果关键概念已有实体页,追加信息;如果没有,在摘要页中标记 `[待创建]`
|
||||
4. 更新 `index.md` 和 `log.md`
|
||||
5. 跳过主题页和 overview 更新
|
||||
|
||||
### 来源边界
|
||||
|
||||
这套边界和安装输出、状态说明、回归测试保持一致。
|
||||
|
||||
| 分类 | 当前来源 | 处理原则 |
|
||||
|------|----------|----------|
|
||||
| 核心主线 | `PDF / 本地 PDF`、`Markdown/文本/HTML`、`纯文本粘贴` | 不依赖外挂,直接进入主线 |
|
||||
| 可选外挂 | `网页文章`、`X/Twitter`、`微信公众号`、`YouTube`、`知乎` | 先自动提取;失败时退回手动入口 |
|
||||
| 手动入口 | `小红书` | 只接受用户手动粘贴 |
|
||||
|
||||
### 素材类型路由
|
||||
|
||||
| 来源 | raw 目录 | 提取方式 |
|
||||
|------|----------|----------|
|
||||
| 网页文章 | `raw/articles/` | baoyu-url-to-markdown skill |
|
||||
| X/Twitter | `raw/tweets/` | baoyu-url-to-markdown skill(需 Chrome 登录) |
|
||||
| 微信公众号 | `raw/wechat/` | wechat-article-to-markdown |
|
||||
| YouTube | `raw/articles/` | youtube-transcript skill |
|
||||
| 小红书 | `raw/xiaohongshu/` | 用户手动粘贴内容 |
|
||||
| 知乎 | `raw/zhihu/` | 用户手动粘贴内容 或 baoyu-url-to-markdown skill |
|
||||
| PDF / 本地 PDF | `raw/pdfs/` | 直接读取 |
|
||||
| Markdown/文本/HTML | `raw/notes/` | 直接读取 |
|
||||
| 纯文本粘贴 | `raw/notes/` | 直接使用 |
|
||||
|
||||
## 别名词表(Alias Table)
|
||||
|
||||
用于 query 和 digest 时自动展开搜索。搜索任意一个词,会同时搜索同一行的所有别名。
|
||||
AI 在 ingest 时如果发现新的同义词关系,可以建议用户添加。
|
||||
|
||||
格式:每行一组同义词,用 `=` 分隔。
|
||||
|
||||
```
|
||||
LLM = 大语言模型 = 大模型 = Large Language Model
|
||||
RAG = 检索增强生成 = Retrieval Augmented Generation
|
||||
fine-tuning = 微调 = 精调
|
||||
prompt engineering = 提示工程 = 提示词工程
|
||||
```
|
||||
|
||||
维护原则:
|
||||
- 只收录在你的知识库里**实际出现过**的同义词,不要预填一堆用不到的
|
||||
- 每组控制在 5 个以内,太多说明概念本身需要拆分
|
||||
- 中英文混用时把最常用的放第一个
|
||||
- ingest 发现新的同义词关系时,AI 应主动建议添加到此表
|
||||
|
||||
## Query(查询)规则
|
||||
|
||||
1. 先读 `index.md`,定位相关条目
|
||||
2. 用 Grep 在 `wiki/` 下搜索关键词
|
||||
3. 阅读相关页面后综合回答
|
||||
4. 回答中标注来源页面(引用链接)
|
||||
5. 有价值的分析建议保存为新的 wiki 页面
|
||||
|
||||
## Lint(健康检查)规则
|
||||
|
||||
1. 检查范围:随机抽查 10 个页面 + 最近更新的 10 个页面
|
||||
2. 检查项:
|
||||
- 页面间矛盾(不同页面说法不一致)
|
||||
- 孤立页面(没有其他页面链接到它)
|
||||
- 缺失概念页(被 `[[某概念]]` 链接但实际不存在)
|
||||
- 缺少交叉引用(相关页面之间没有互相链接)
|
||||
- index 一致性(index.md 记录与实际文件是否对应)
|
||||
3. 输出中文报告,对每个问题给出修复建议
|
||||
4. 如果发现问题,询问用户是否自动修复
|
||||
|
||||
## 关系类型词汇表(可选,用于手动标注知识图谱)
|
||||
|
||||
这张表提供 graph 工作流生成的 `wiki/knowledge-graph.md` 里**可选**的关系类型词汇。
|
||||
AI 生成图谱时默认全部用 `-->`(无标注),不自动判断关系类型。如果你想让图谱
|
||||
更清楚地表达节点之间的语义,可以用编辑器把最重要的几条箭头改写成带标注的形式:
|
||||
|
||||
| 类型关键词 | 含义 | Mermaid 写法示例 |
|
||||
|-----------|------|-----------------|
|
||||
| 实现 | A 是 B 的具体实现 | `A -->|实现| B` |
|
||||
| 依赖 | A 依赖 B 才能工作 | `A -->|依赖| B` |
|
||||
| 对比 | A 与 B 是同类可以比较 | `A -->|对比| B` |
|
||||
| 矛盾 | A 与 B 存在观点冲突 | `A -->|矛盾| B` |
|
||||
| 衍生 | A 从 B 演化而来 | `A -->|衍生| B` |
|
||||
|
||||
使用原则:
|
||||
- 只标最重要的 3-5 条关系,不要强行给所有箭头打标
|
||||
- 不确定的关系保持默认 `-->` 箭头
|
||||
- 自定义类型控制在 2 个以内,避免词汇表膨胀
|
||||
- 标注后在 Obsidian / VS Code(Markdown Preview Enhanced)/ Typora 里重新渲染就能看到标签
|
||||
51
llm-wiki/templates/source-template.md
Normal file
51
llm-wiki/templates/source-template.md
Normal file
@@ -0,0 +1,51 @@
|
||||
---
|
||||
tags: [素材摘要]
|
||||
created: {{DATE}}
|
||||
updated: {{DATE}}
|
||||
sources: []
|
||||
source_type: {{TYPE}}
|
||||
source_path: {{RAW_PATH}}
|
||||
images: 0
|
||||
image_paths: []
|
||||
---
|
||||
|
||||
# {{SOURCE_TITLE}}
|
||||
|
||||
> 一句话总结这篇素材的核心观点
|
||||
|
||||
## 基本信息
|
||||
|
||||
- **来源类型**:{{TYPE}}(文章 / 推文 / 公众号 / PDF / 笔记 / 视频)
|
||||
- **原文位置**:{{RAW_PATH}}
|
||||
- **消化日期**:{{DATE}}
|
||||
|
||||
## 核心观点
|
||||
|
||||
(3-5 个要点,每个要点用 1-2 句话说清楚)
|
||||
|
||||
1. **要点一**:...
|
||||
2. **要点二**:...
|
||||
3. **要点三**:...
|
||||
|
||||
## 关键概念
|
||||
|
||||
(素材中提到的重要概念,链接到或标注需要创建的实体页)
|
||||
|
||||
- [[概念1]]
|
||||
- [[概念2]]
|
||||
|
||||
## 与其他素材的关联
|
||||
|
||||
(这篇素材和已有素材之间有什么联系?是补充、反驳、还是扩展?)
|
||||
|
||||
- 与 [[另一篇素材]] 的关系:...
|
||||
|
||||
## 原文精彩摘录
|
||||
|
||||
(值得原样保留的 2-3 段原文)
|
||||
|
||||
> 摘录一...
|
||||
|
||||
> 摘录二...
|
||||
|
||||
## 相关页面
|
||||
25
llm-wiki/templates/synthesis-template.md
Normal file
25
llm-wiki/templates/synthesis-template.md
Normal file
@@ -0,0 +1,25 @@
|
||||
# {{TOPIC}} 结晶化
|
||||
|
||||
日期:{{DATE}}
|
||||
来源:对话/工作会话
|
||||
置信度:INFERRED
|
||||
|
||||
## 核心洞见
|
||||
|
||||
<!-- 3-5 条关键洞见,每条一行 -->
|
||||
|
||||
## 关键决策
|
||||
|
||||
<!-- 做了什么决定,为什么这么决定 -->
|
||||
|
||||
## 涉及概念
|
||||
|
||||
<!-- 列出本次会话涉及的重要概念,每个用 [[概念名]] 格式链接 -->
|
||||
|
||||
## 参考资料
|
||||
|
||||
<!-- 对话中提到的文章、工具、项目 -->
|
||||
|
||||
## 待跟进
|
||||
|
||||
<!-- 还没解决的问题,或者下一步要验证的假设 -->
|
||||
35
llm-wiki/templates/topic-template.md
Normal file
35
llm-wiki/templates/topic-template.md
Normal file
@@ -0,0 +1,35 @@
|
||||
---
|
||||
tags: [主题]
|
||||
created: {{DATE}}
|
||||
updated: {{DATE}}
|
||||
sources: []
|
||||
---
|
||||
|
||||
# {{TOPIC_NAME}}
|
||||
|
||||
> 一句话概括这个主题的核心问题或方向
|
||||
|
||||
## 核心观点
|
||||
|
||||
(从多个素材中综合出来的关于这个主题的核心认知)
|
||||
|
||||
## 素材汇总
|
||||
|
||||
(列出所有讨论过这个主题的素材,标注每篇的核心贡献)
|
||||
|
||||
| 素材 | 核心贡献 | 详见 |
|
||||
|------|----------|------|
|
||||
| (素材名) | (一句话) | [[素材摘要页]] |
|
||||
|
||||
## 关键概念
|
||||
|
||||
(这个主题涉及的关键概念,链接到对应实体页)
|
||||
|
||||
- [[概念1]] — 简要说明
|
||||
- [[概念2]] — 简要说明
|
||||
|
||||
## 未解决的问题
|
||||
|
||||
(素材中提到但没有答案的问题,或素材之间存在矛盾的地方)
|
||||
|
||||
## 相关页面
|
||||
Reference in New Issue
Block a user