sre weekly 525, 526, 527
This commit is contained in:

@@ -0,0 +1,65 @@
|
||||
# The Post-Incident Review Meeting: three meetings in a trench coat
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/05/12/three-meetings-in-a-trench-coat/
|
||||
|
||||
## 简介
|
||||
|
||||
People hold post-incident reviews for three separate purposes. When the people that care about each one collide, things can go off the rails.
|
||||
|
||||
## 正文
|
||||
|
||||
Most companies hold a single post-incident review (PIR) meeting for each incident. They schedule an hour, invite the responders and a handful of observers, walk through the timeline, discuss what went wrong, generate a list of action items, and move on. It feels productive. The calendar invite says “PIR Meeting,” and the meeting does PIR-meeting things.
|
||||
|
||||
The purpose of a post-incident review is to learn. Not to assign blame. Not to generate action items. Not to produce a document for the compliance folder. Documentation and action items are *side effects* of the review process, but they aren’t the point. The point is learning, both individual and organizational, so that you have a better understanding of how your systems actually work and you’re better prepared for the next incident. Because there *will* be a next incident.
|
||||
|
||||
But what most companies call “the PIR meeting” is really three distinct functions crammed into a single calendar invite (or, as I’m fond of describing it, “three meetings in a trench coat”):
|
||||
|
||||
**A working meeting** where the people who responded to the incident sit down together and reconcile their understanding of what happened. They fill gaps in the timeline, surface things they knew but didn’t write down, and pressure-test the contributing factors.
|
||||
|
||||
**An action items meeting** where problems that the incident surfaced are named. The goal should be to identify what needs attention, not to propose solutions; the people best positioned to design fixes may not even be in the room.
|
||||
|
||||
**A presentation** where the findings and lessons are shared with a broader audience beyond the people who lived the incident. This is the meeting’s contribution to organizational learning: spreading what was learned to people who weren’t in the room.
|
||||
|
||||
Each of these three functions has a different optimal participant list, a different facilitator posture, a different conversational mode, and a different relationship to time pressure. The working meeting is a small group, collaborative and sometimes messy, exploring what happened without a fixed agenda. The action items meeting shifts into problem-identification mode: what did this incident reveal that needs attention? The presentation is structured and scripted, aimed at an audience that wasn’t in the room for the incident.
|
||||
|
||||
If you treated them as three separate meetings, you’d probably invite three different (though overlapping) sets of people to them. Which means that in a single combined meeting, either you haven’t invited everyone who should be there for each function, or some of the people you invited are sitting through parts of the meeting that they don’t need to.
|
||||
|
||||
Also, the three functions aren’t equally important: the working discussion is the foundation that the other two depend on. When they’re collapsed into a single session, the results are predictable.
|
||||
|
||||
# What happens when the three functions compete
|
||||
|
||||
When these three functions share a single meeting, the action items tend to dominate, because “what are we going to do about this?” feels like a more urgent conversation than “what can we learn from this?” Especially under time pressure, the room gravitates toward the concrete and seemingly actionable, at the expense of the exploratory and uncertain. Someone says “we should add monitoring for this,” and the conversation shifts from understanding what happened to debating what to build. Once that shift happens, it’s hard to get back.
|
||||
|
||||
Meanwhile, the broader audience sits passively through a working discussion that wasn’t designed for them. The observers are theoretically “learning,” but when the conversation is a detailed working discussion among the responders, observers tend to drift to Slack and email, half paying attention at best. The presentation function doesn’t just get less time in a combined meeting; it gets less attention.
|
||||
|
||||
And the tyranny of the one-hour calendar block hangs over everything (especially if your hour only has 53 minutes). The working discussion goes where the work takes it. You can’t predict how long it needs based on the severity or complexity of the incident. Sometimes there’s a lot to learn from a small incident; sometimes there’s surprisingly little to discuss about a big one. A one-hour combined meeting trying to do the work of three distinct functions will likely shortchange all of them.
|
||||
|
||||
# A diagnostic, not a prescription
|
||||
|
||||
The three-meeting frame isn’t a prescription to hold three meetings for every incident. Even at companies with the most mature incident practices, most incidents get a single meeting. That’s fine.
|
||||
|
||||
The frame is a diagnostic tool. If your review meetings feel rushed, performative, or dominated by action items, the problem might be that you’re asking one meeting to do the work of three. Recognizing the three functions helps you protect the one that the other two depend on (the working discussion) when they share a calendar invite, and invest in separate meetings for the incidents that warrant it.
|
||||
|
||||
# Protecting the learning conversation
|
||||
|
||||
Understanding without follow-through is just conversation. But follow-through without understanding is just busywork. The action items that come out of a review are only as good as the understanding that produced them.
|
||||
|
||||
When you do hold a combined meeting, the simplest tool for protecting the learning conversation is to explicitly defer discussion of action items. “We’re going to defer discussing action items until the last fifteen minutes. If something comes up that feels like an action item, note it and we’ll come back to it.” Then enforce the boundary. During the working session, when someone says “we should add monitoring for this,” the facilitator says “noted; write that down so we can come back to it.” The first few times feel awkward. It gets easier, and the room gets better results.
|
||||
|
||||
In my experience, which is shared by other leading practitioners in the LFI (learning from incidents) community, teams generate fewer and better action items when they let the understanding generated in the working session settle and marinate a bit before they start digging into “what needs to change?” When people have time to sit with the understanding before jumping to “what are we going to do about this?”, they move past the reactive fixes and toward improvements that address broader patterns. If possible, you should defer the action items discussion until 24 hours after the working meeting; that’s not always practical, but the separation produces higher-quality outcomes.
|
||||
|
||||
# The pattern is older than software
|
||||
|
||||
Separating these functions has parallels in other fields. The NTSB (the U.S. National Transportation Safety Board) separates its investigation from its public hearings from its final recommendations. Hospitals hold weekly morbidity and mortality conferences where cases are presented to the broader department, informed by detailed case review that happens separately. In both fields, the investigation, the discussion, and the recommendations are distinct phases. The principle applies whether you’re investigating a plane crash, a surgical complication, or a database outage.
|
||||
|
||||
None of this is exotic or expensive. It’s a matter of recognizing that a single meeting is trying to do three different jobs, naming those jobs, and deciding which one matters most when they compete.
|
||||
|
||||
For most incidents, this means giving the working discussion room to breathe, and keeping action items from taking over before understanding has had a chance to develop.
|
||||
|
||||
*I’m writing a book on [Incident Management for DevOps and SRE](https://im4ds.com). Sign up to be notified when it’s available.*
|
||||
|
||||
*If your company needs help building or improving its incident management capabilities, my consulting practice is [Great Circle](https://greatcircle.com/im).*
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,263 @@
|
||||
# Incident Report: Exercises, Cleanups, and Evacuations
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Fred Hebert — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/incident-report-exercises-cleanups-and-evacuations
|
||||
|
||||
## 简介
|
||||
|
||||
In December, Honeycomb had a major incident, and they posted a pretty detailed write-up on their status page. That was just an interim report though, and this post goes into a ton more detail.
|
||||
|
||||
## 正文
|
||||
|
||||
# Incident Report: Exercises, Cleanups, and Evacuations
|
||||
|
||||
On December 5th, 2025, we suffered a major outage in our EU region, with the last recovery steps for it extending until December 17th, 2025. For multiple hours, all of Honeycomb’s event ingestion endpoints were down. Most of the duration was spent in a degraded mode where only Activity Log data was impacted. A general timeline is available on our status page, but in this report, we’ll look at a broader analysis of what happened.
|
||||
|
||||

|
||||
|
||||
By: [Fred Hebert](https://www.honeycomb.io/author/fred-hebert)
|
||||
|
||||
|
||||
|
||||
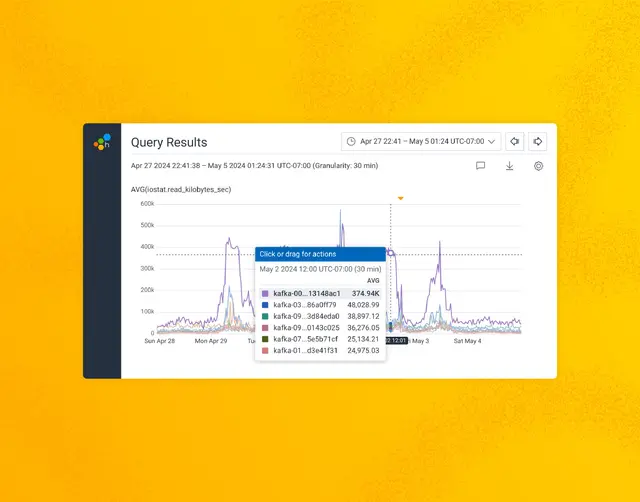
#### Investigating Mysterious Kafka Broker I/O When Using Confluent Tiered Storage
|
||||
|
||||
Earlier this year, we upgraded from Confluent Platform 7.0.10 to 7.6.0. While the upgrade went smoothly, there was one thing that was different from previous upgrades: due to changes in the metadata format for Confluent’s Tiered Storage feature, all of our tiered storage metadata files had to be converted to a newer format.
|
||||
|
||||
[Read More](https://www.honeycomb.io/blog/investigating-kafka-tiered-storage)
|
||||
|
||||
|
||||
|
||||
Every year, Honeycomb runs disaster recovery scenarios in multiple environments, including in production. Although each of our instances runs in a single region, on at least three Availability Zones (AZs), we have multiple plans for partial regional failures, and particularly, zonal failures. One of these tests was run on December 5th, and after its successful completion came its cleanup steps.
|
||||
|
||||
Because tolerating zonal failures creates and shifts workloads in new zones that are inherently imbalanced once the failure is over, some work is required to gradually shift workloads back in proper balance. During one of these steps, while following our runbook, we ended up purposefully destroying Kafka brokers. In all previous runs in pre-production environments, this step went fine. In production, however, it caused multiple topic partitions to go fully leaderless, which caused major problems at multiple levels:
|
||||
|
||||
- The topics we use to transmit all ingested events had multiple partitions that were damaged, some of which irreversibly so;
|
||||
- The topics used by some of our consumer groups to track where they were at were partially damaged;
|
||||
- Metadata topics used by Kafka and the Confluent addons we use (such as those used to manage tiered storage) were also partially damaged, with some partitions fully broken.
|
||||
|
||||
The first element in the list was our top priority: each Honeycomb team and environment is assigned multiple partitions, and while we can sustain some partitions becoming unavailable, if all partitions assigned to a team are unavailable, then we fail to ingest any data for them. But worse than that is the damage these partitions had received.
|
||||
|
||||
To be brief, Kafka maintains an internal set of offsets that are available to consumers for them to reliably consume data. Retriever, our query engine, takes these offsets and uses them in multiple places internally to track consistency of which events it has processed. If all Kafka brokers for a topic partition are lost, the ensuing leader election needs to be “dirty,” which can partially or completely roll back the offsets. This breaks all Retriever ingestion in the foreseeable future, possibly requiring to delete the environment and start again from scratch.
|
||||
|
||||
The early response then was split in two: find the teams and environments whose partition assignment needed to be moved (and impact communicated), and see if we could salvage the impacted partitions without offset/data loss.
|
||||
|
||||
Roughly one hour into the incident, the impacted customers were found. The Kafka recovery was a bit trickier: we couldn’t do *any* random leader election and had to salvage as much data as possible from the offsets that may still exist.
|
||||
|
||||
Through the alerting noise, we noticed that our ingest service, Shepherd, had entered a crashloop spiral more than an hour earlier due to increased memory buffering for events that were to be written on the broken partitions.
|
||||
|
||||
Various options to repair ingest for apps on broken partitions were considered, such as adding new ones to all datasets, booting Retrievers in the wrong partitions to create room, and so on. In the end, the impacted partitions were marked read-only on the producer side, which fixed ingest’s crashlooping. Reassignments were then run to bring everything back to normal for customers.
|
||||
|
||||
Later in the night, a list of leaderless Retriever partitions (all read-only) with their offsets was established. Roughly a third of the partitions were impacted, but a single one had complete data loss, roughly 2.5% of our cluster.
|
||||
|
||||
As the system was then relatively stable but far from solid, a plan for the night and checking back on Saturday was put in place. The Kafka autobalancer was turned off, and a manual reassignment plan to bring back some balance was put in place, left to run overnight.
|
||||
|
||||
Completing reassignments to fresh hosts, for tiered storage specifically, can sometimes take multiple hours of idle-looking time to scan S3 buckets for historical data before any transfer would show up at the network level. We found it concerning to see disk usage going up, but decided to wait.
|
||||
|
||||
Around midnight PT, one partition still showed no sign of recovery: the disk was filling too fast on the brokers for comfort, and so local retention was reduced on Kafka, aiming to use the S3 tiered storage for any longer retention need. A status update was posted, and the group disbanded for the night.
|
||||
|
||||
## Weekend response
|
||||
|
||||
Early on Saturday morning, responders noticed that the Kafka balancing jobs did not progress, and disk usage hadn’t improved. Estimates showed we were losing 5% of disk capacity per hour, with only 30% free. To avoid running out of disk on brokers and potentially suffering major data loss that propagates to Retriever, plans were put in place to shut down all ingest at the ALB layer if we reached 95% usage. This left us five hours to figure out a way to free space.
|
||||
|
||||
At that point, the main reassignments were cancelled, and there was an attempt to move smaller partitions to free up space. Responders found out that two topics had broken topic partitions that could be relevant: `_confluent-tier-state` and `__consumer_offsets`. The theory was that since we were trying to move topics and their data to tiered storage, having these broken could prevent proper offloading and uploading of data.
|
||||
|
||||
The moment these were repaired, triggers about our SLO processing fired, complaining of ~18h of late data. Our SLO processing service had been unable to see new data had come in based on how it implemented its consumption, and repairing the metadata topics unblocked it. It started catching up.
|
||||
|
||||
After multiple efforts, at 7 a.m. PT, with 5.07% of disk storage free, ingest was turned off. Disk usage stabilized, but did not empty—which would have been our expectation if we were uploading older data to S3 and not replacing it with new ingest.
|
||||
|
||||
Honeycomb engineers decided to bring up new Kafka brokers, with new Retrievers, and create brand new partitions to send ingest to.
|
||||
|
||||
As this was being rolled out, an engineer came in and suggested we turn off tiered storage altogether to unstick the cleanup process and allow freeing disk space. This is something that had worked in 2021 during an old outage. We turned off tiered storage and disk space was instantly restored.
|
||||
|
||||
We reopened ingest, and customer impact ended then. Later in the day, as part of cleanup, the team stopped work to manually fix Retriever topic partitions that were fully damaged and truncated them, leaving them in read-only mode. This created a gap where older data was unavailable for querying as Retriever struggled with the offset reset, but it wasn’t lost and we would remediate this problem in the following days.
|
||||
|
||||
## Second week response
|
||||
|
||||
Since Kafka was still in a rough but functional state, most of Monday’s response focused on two elements:
|
||||
|
||||
1. Extending the retention of the Honeycomb MySQL readonly replica’s binlog, since Activity Log could no longer publish events to Kafka.
|
||||
2. Salvaging the damaged Kafka topic partition for Retriever.
|
||||
|
||||
The broken partition was fully offline. Being read-only, no traffic was being lost, but the historical data was not available for querying, although queries succeeded overall, just with partial results.
|
||||
|
||||
Regardless, a series of small tweaks and fixes were put in place to allow the Retriever nodes to idle live and let old data be queried despite “broken” offsets.
|
||||
|
||||
On Tuesday, work was done to try and bring back tiered storage; this first required deleting all the old S3 data, which took multiple hours. We did not manage to turn tiered storage back on.
|
||||
|
||||
In parallel, work was done to unfreeze builds that hadn’t moved since Friday. Activity Log repairs got delayed due to more urgent remediation efforts on Generally Available Honeycomb features, though data retention would be available until Friday. We attempted to repair their partitions on Wednesday. After failing to do dirty leader elections in Kafka, we decided to delete the topics involved and recreate them.
|
||||
|
||||
This is when things got *weird*. The delete operation timed out, and suddenly, none of our Kafka brokers could do anything administrative other than list topics. Describing, reassigning, or modifying them would just time out. The cluster was in a far worse state than expected, and responders on the call became uncomfortable.
|
||||
|
||||
To move past the feeling, we decided to split approaches: one lane to try and salvage the cluster with non-risky operations and ZooKeeper surgery, and one lane to plan a full evacuation of the cluster to a new one.
|
||||
|
||||
Managers and directors were called in to help align the rest of the organization on these efforts. Wednesday afternoon was spent preparing the evacuation efforts (described below) with the support of directors and engineering from all teams that would interact with Kafka either for operations, or through their product area.
|
||||
|
||||
Thursday involved the elaboration of multiple evacuation plans, and a division of work while Kafka SMEs kept trying to see what could safely be done about the cluster. Later in the day, even changes such as rebooting the Kafka controller host to shift its responsibility to another broker were seen as high-reward but high-risk, and because evacuation efforts could benefit from prolonged steady state, we tabled these efforts.
|
||||
|
||||
On Friday, we realized we wouldn’t be ready in time for Activity Log data to be salvaged in the MySQL binlog, which had a maximal storage time of seven days. Since the feature is still in beta and rushing to save more data through alternative replication means would drag people away from the Kafka evacuation, we chose to try a hail mary approach suggested by AWS support where we’d set up a new replica that was one week old from a snapshot, freeze it with manual replication, and hope that this would trigger AWS’ feature where stalled replication extends binlog retention to up to 30 days.
|
||||
|
||||
## Evacuation
|
||||
|
||||
An evacuation would essentially ask that we consider the current Kafka cluster as no longer worth salvaging. A new Kafka cluster would be needed, with brand new topics and partitions, all empty with reset offsets. This, in turn, implies modifying or ensuring all of our software components can properly shift from the old to the new cluster without data loss, which would require deep code changes. For example, Retriever needed to be edited so that it was allowed to reset its offset tracking, something that would require changes in some of its internals and a lot of consideration for complicated scenarios.
|
||||
|
||||
This sort of effort would be expected to take weeks if not months in normal time, but the incoming holidays break and an already tired team made the deadline short. It was also unclear if the cluster, as it stood in its unmanageable state, would be up for long enough to complete the migration.
|
||||
|
||||
We therefore planned for five options presented summarily here, depending on how much of the preconditions we’d meet:
|
||||
|
||||
1. The existing Kafka cluster dies at the current state of the world. We have a full outage and must recover from scratch. At least four to eight hours of hard downtime expected, higher ongoing costs.
|
||||
2. The existing Kafka cluster dies but we have managed to make Retriever able to handle offset resets; we can recover from scratch without leaving old partitions behind.
|
||||
3. The existing Kafka cluster dies while we were ready to migrate to a new cluster. We can reset it, but ingest would be down for one to two hours, querying estimated down for up to three to eight hours.
|
||||
4. We’re ready to migrate most things except some minor elements we haven’t had the time to prepare. Zero downtime for ingest, one hour downtime for primary querying and alerting, but may take anywhere between two to eight hours of work—and we were unsure what the impact would be on less critical services.
|
||||
5. Full migration as we’re ready. Similar to the previous option, but more testing has happened, we pick some slightly safer implementation details across all applications, and reduce uncertainty.
|
||||
|
||||
Roughly midday on Friday, the Storage team managed to make the offset reset mechanism work for Retriever. This made the first scenario no longer be a concern.
|
||||
|
||||
Our platform team had made good progress on the feature flags to switch readers and writers, and also made it possible to boot a second Kafka cluster without interfering with the other ones nor any other environments.
|
||||
|
||||
As we progressed through the work on Friday and firefought on some parallel events in the US, we thought we could ambitiously hit the 4th or 5th scenario on Monday afternoon, with a full dress rehearsal in one of our EU pre-prod clusters.
|
||||
|
||||
The dress rehearsal went well with people from more than half a dozen teams on the call. There was some friction around code changes and builds that needed ironing out, but the plan mostly worked fine and was completed within four hours.
|
||||
|
||||
Tuesday required some work to fix issues where domain names for a new Kafka clusters’ NLB wouldn’t fit AWS’ limits, but we managed to fix everything in time. The migration ran in two hours with no significant problem and up to one hour of delayed signal at most.
|
||||
|
||||
We cleaned up the older clusters, and caught up with bits of Activity Log in the EU region. As it turns out, the replica trick didn’t work. To minimize lost data, we booted an instance from Tuesday December 9th, and replicated from there. This kept data loss on the Activity Log from December 5th at ~6 p.m. ET to December 9th at ~6 p.m. ET, and the rest was saved.
|
||||
|
||||
## Analysis
|
||||
|
||||
This incident was draining, **described as “the worst incident of my career”** by many. However, a great part of working for Honeycomb is how caring the organization is toward our incident response team. Frankly, it's at a level many of us hadn’t seen at prior companies.
|
||||
|
||||
Some engineers mentioned wanting to keep response sustainable, while others felt that it should have required faster escalation.
|
||||
|
||||
Coordination proved challenging. Before this happened, multiple senior engineers mentioned feeling like they automatically grabbed the lead when they entered the room, which they mentioned being something they need to think more about.
|
||||
|
||||
Communication with the public was challenging. We aren’t necessarily used to running such long events, and decided to be explicit about potential losses and pending recovery of Activity Log. While the situation was internally dire, the Activity Log is actually a beta feature; customers let us know that we were giving too much information about minor features.
|
||||
|
||||
### Documentation fragmentation issues
|
||||
|
||||
Many of the elements in play for this outage were already known. Similar outages had been seen in recent years, with high level plans for workarounds, RFCs and migrations that would ease up on these conditions, and processes to run similar exercises safely. Ultimately, these documents’ existence was either unknown (outside of the people who were involved in writing and reviewing them), or inaccessible (blocked by ineffective search on some document systems). Interviews with members of staff revealed a frustration with our documentation situation, spread across multiple areas.
|
||||
|
||||
We see a need to better consolidate our information as we keep growing.
|
||||
|
||||
### Bumpable roadmap effects
|
||||
|
||||
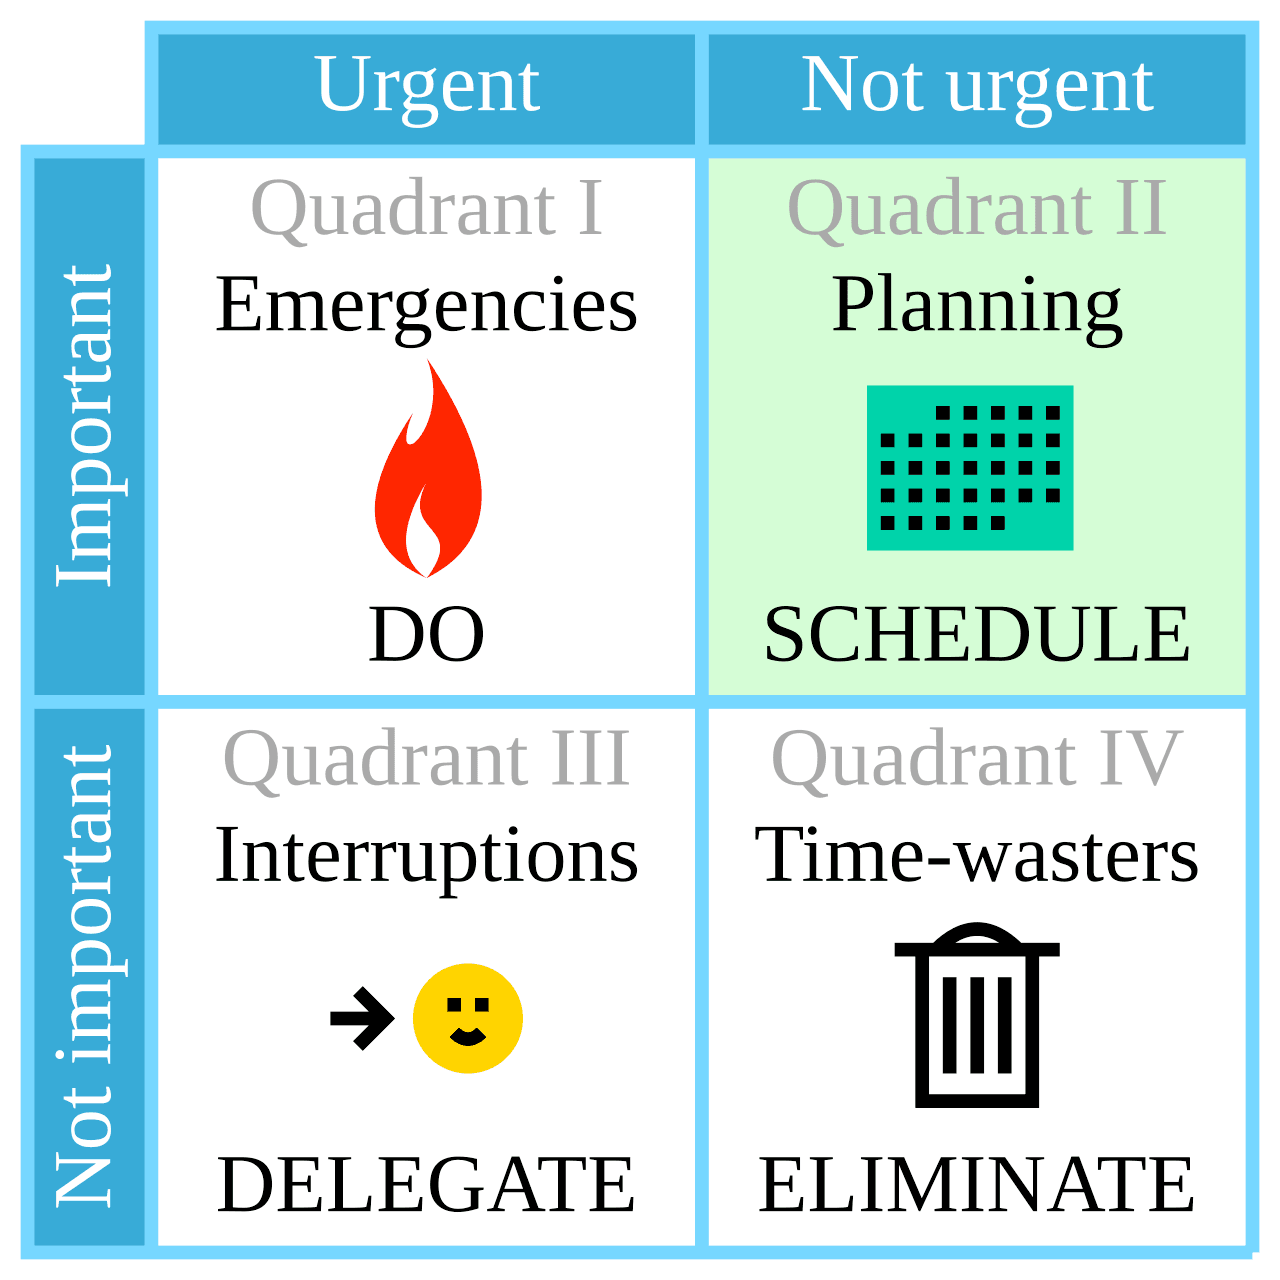
When you are given multiple competing tasks of high importance, the one with a deadline further out or a higher level of uncertainty is easier to defer than the one with a more urgent deadline or well-understood scope. This is often represented as the [Eisenhower matrix](https://en.wikipedia.org/wiki/Time_management#Eisenhower_method):
|
||||
|
||||
|
||||
|
||||
[By Cmglee - Own work, CC BY-SA 4.0](https://commons.wikimedia.org/w/index.php?curid=141867635)
|
||||
|
||||
When caught between a clear urgent project that has well-understood customer benefits, it becomes difficult to say no to it in favor of an internally controlled project whose benefits are going to be less obvious or more contextual.
|
||||
|
||||
This gets even muddier when you have to prioritize multiple projects from the same quadrant. It’s at these levels where we can see teams with agency in their own schedules adapt to pressures by deferring or prioritizing some projects without going back up to leadership to arbiter common issues of this type.
|
||||
|
||||
We could think of the bumpable mechanism as an extra dimension over that matrix: how much control and flexibility there is across competing projects, which makes it possible to reframe or reorder their respective urgency and importance.
|
||||
|
||||
In general, being flexible with deadlines is a good thing. It lets us reprioritize as new information becomes available and as we find we need to adjust our plans. However, it appears to be challenging for teams to avoid repeatedly deferring more flexible pieces of work that are locally controlled or have wider margins. This is a convenient and rational way to locally manage tradeoffs.
|
||||
|
||||
We cannot counter all bumping—it plays a useful role to our ability to adapt and adjust—but may want to seek ways of knowing when bumping can become a reflex more than a strategic tool.
|
||||
|
||||
### Sociotechnical misalignment
|
||||
|
||||
A few years ago, Honeycomb was small enough that critical knowledge only existed within single engineers’ minds. We have since then taken measures to ensure all components have owners and that critical knowledge has multiple people behind it. While this helped, such measures need frequent adjusting.
|
||||
|
||||
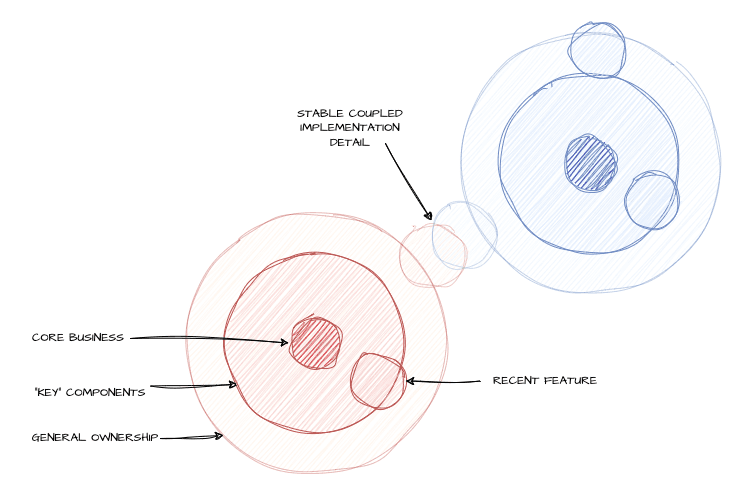
Something interesting that came up in the incident is that many key interventions came from people who no longer own the components they helped with. People were able to help because they were here back when teams’ ownership was less well-defined, despite having since moved to different roles. That these people were all able to offer meaningful support is a *strength* of this organization. It also shows, however, that there is some drift or gap between the socio- and the -technical part of the system.
|
||||
|
||||
For example, in creating one team to manage one part of the system and assigning ownership of the other elements to another team, any existing coupling between these components does not vanish. So while both teams can grow a stronger expertise on their respective piece of software, the details get lost:
|
||||
|
||||
|
||||
|
||||
The challenge is that engineers need and often want to move to different work over time, both for growth and motivational reasons. Deep systems knowledge also has value, sometimes in very specific and infrequent situations. Both forces compete with each other, and compromises around quick training or leaving docs and runbooks do not fully replace thorough understanding, even if that’s only what teams have time for. This can be supported by good engineering practices, fighting tech debt, and solid observability to make it easier to get your bearings faster, but sometimes the business will, either implicitly or explicitly, accept the risk.
|
||||
|
||||
The principle is that the socio- parts (teams) may be more siloed than -technical parts. Isolating one without untangling the other will lead to drift, and drift to surprises. There is no easy fix for it, and incidents such as this one are great opportunities to bring some of that deep knowledge back, in a way that inherently feels practical to everyone involved.
|
||||
|
||||
## Conclusion
|
||||
|
||||
In wanting to move past a simple explanation of “don’t destroy the Kafka cluster next time”, we have to look at a very large set of influences. This incident involved a long term response during a stressful situation, including planning, implementing, and executing a full Kafka evacuation in less than five business days. We could only accomplish this through a very rapid reorganization within Honeycomb.
|
||||
|
||||
We hope that this document provides a sufficient explanation behind how events unfolded for one of our biggest outages in recent memory. Documenting our response and some of its challenges can be of use for other organizations who may encounter similar situations.
|
||||
|
||||
An additional hope of ours is that by highlighting some of the key elements that we identified in our reviews and were in play within our broader organizational context, we can provide insights that can also help other organizations. We think the patterns uncovered do have the ability to carry meaning elsewhere.
|
||||
|
||||
## Appendix I: Technical Explanations
|
||||
|
||||
This section aims to explain the mechanisms involved in a Kafka cluster. On their own, they are not considered explanations of *why* the outage happened, but contributors to *how* its events unfold.
|
||||
|
||||
We assume some familiarity with the concepts described in [Confluent's Introduction to Kafka](https://docs.confluent.io/kafka/introduction.html).
|
||||
|
||||
### What are Kafka offsets?
|
||||
|
||||
On disk, Kafka will store data such that each message has an offset (a relative order since the start of the topic), a position (to skip around files more easily), a timestamp (to know when the data was written), and then the messages’ contents. These are put in a “log” on disk, broken down by topic and partition. Consumers can then ask to stream the log’s data, being handed the above data (including the offset and message).
|
||||
|
||||
In practice, consumers will generally ask for an offset bigger than the last one they had seen in the stream previously. If the log gets truncated (offsets reset at 0) consumers will often just start processing again from either the start or the end of the stream.
|
||||
|
||||
The timestamps can in theory be used to help make decisions, but are not accurate enough on their own to ensure ordering. Because clocks on computers are not reliable enough at a small enough granularity, it is possible for multiple messages to share the same timestamp, but not the same offsets.
|
||||
|
||||
### Why do offsets matter to Retriever?
|
||||
|
||||
Generally, Kafka consumers know about the offsets, but they don’t necessarily store them long term, outside of knowing where you were at.
|
||||
|
||||
For example, every time you migrate a Kafka cluster (something kind of rare), offsets get reset and lost. To make that work in complex workloads, there are migration systems that will create topics that map the new cluster’s offsets to the old cluster’s offsets (or vice versa) in order to let consumers switch from one to the other transparently.
|
||||
|
||||
Overall, the expectation is that you use offsets to track where you’re at in a topic, and if the offsets reset, you can choose to either start from 0 again, or from the newest offset.
|
||||
|
||||
Retriever is one of these systems where each bit of data we consume from Kafka gets stored again into its own column format, both on disk and on S3. When doing this, Retriever also stores the last offset seen, once globally on its own, but also within each segment metadata file it has about any data it stores.
|
||||
|
||||
This is a safety mechanism that ensures Retriever never skips ahead or back in time when it shouldn’t, which could result in duplicated or missing events, which could in turn mess with investigations or alerting.
|
||||
|
||||
The problem then is that when the offsets reset on purpose (and not because of a bug), either due to a migration or a Kafka failure that required recreating topics or topic partitions, Retriever detects the unexpected values and *refuses to process data* to avoid corrupting its content.
|
||||
|
||||
This, in turn, means that Retriever goes down hard and becomes unavailable for querying or new updates. If this happens on one partition, marking it read-only makes the rest of the cluster handle its burdens. If this happens on all partitions, no traffic can make it out of Kafka and to Retriever.
|
||||
|
||||
If Retriever cannot process events within a few days (as configured by the Kafka cluster’s retention), then the messages are eventually pruned and the data is irreversibly lost.
|
||||
|
||||
Reducing Retriever’s dependence on offsets can either take one of two forms:
|
||||
|
||||
1. make it process offsets *and* timestamps, such that if the offset goes back but timestamps are greater, we know the partition has reset; otherwise, follow offsets
|
||||
2. have Retriever able to reset the offset counts it tracks back to zero such that it will safely keep processing messages, but without overwriting old ones it has on disk or references in MySQL
|
||||
|
||||
Both represent a significant risk to implement, because any bug can irreversibly damage and corrupt data Retriever has stored. In this incident, the evacuation work ended up implementing the second solution as a one-time operation.
|
||||
|
||||
### What is tiered storage?
|
||||
|
||||
Our system sees a lot of data. Tiered storage is a closed-source commercial feature of Confluent that lets Kafka split its storage into two tiers: a local one (hot) and a remote one on S3 (cold). New and fresh data that will be streamed to most live consumers is read from the hot storage, whereas older data (up to a few days old) is stored in S3.
|
||||
|
||||
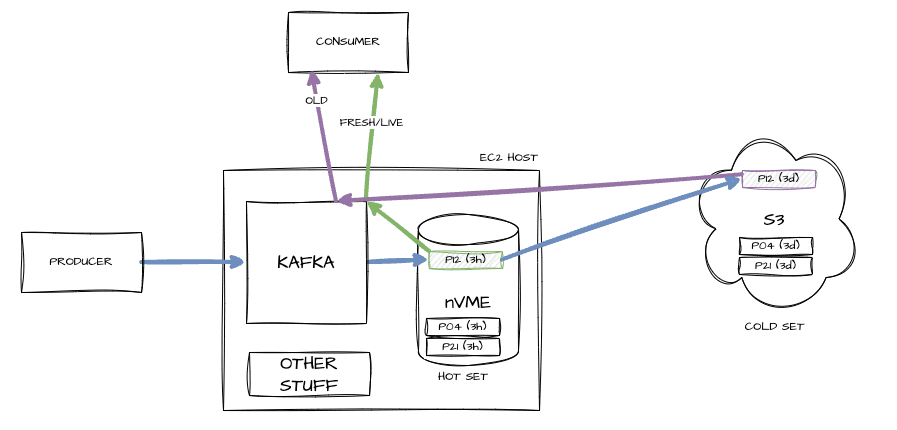
|
||||
|
||||
This lets us have fewer hosts with fast access for live streaming, and elastic (but slower) storage for occasionally recovering older data.
|
||||
|
||||
### How did Kafka partitions break down?
|
||||
|
||||
At a steady state, our Kafka clusters in production have various brokers, over three availability zones, with each topic partition replicated across one broker per availability zone (AZ). Here’s an example of what this looks like with six brokers:
|
||||
|
||||
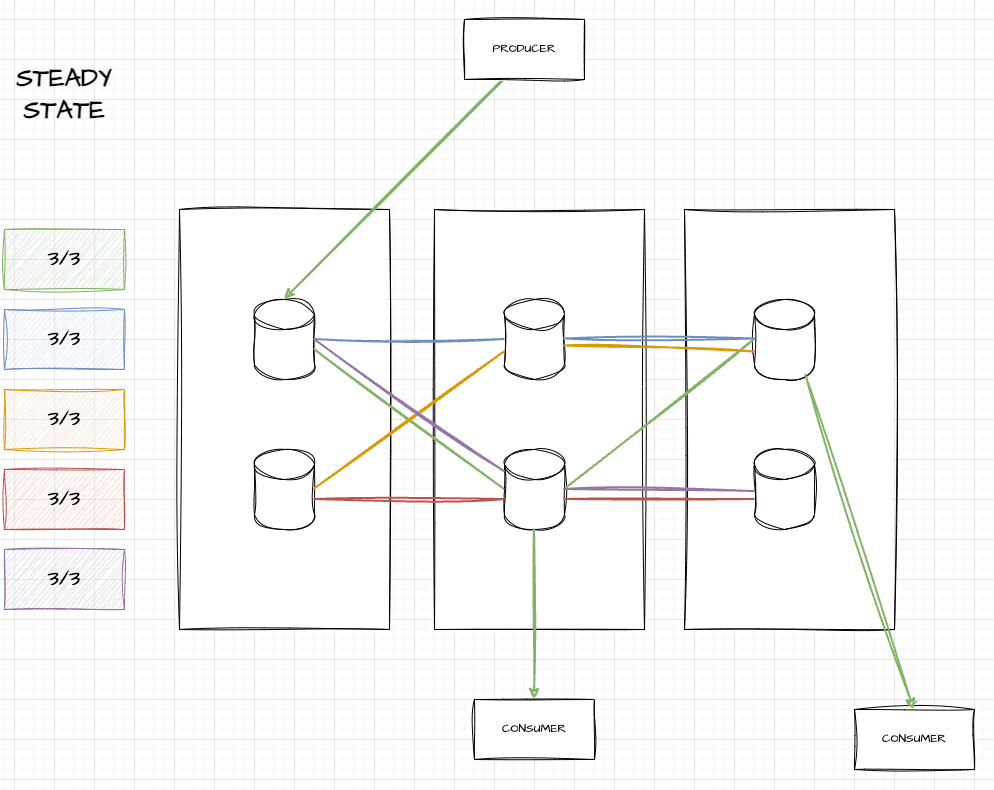
|
||||
|
||||
In this image, you can see five topic partitions (green, blue, yellow, red, and purple), each of which touch three brokers and span three AZs. If you’re a producer of the green topic, you write to the leader (in the leftmost AZ), but can consume from any of them.
|
||||
|
||||
When an AZ fails, all brokers in that AZ die and vanish. The auto-scaling group (ASG) in AWS detects that we only have four out of six nodes, and boots two new ones in functional AZs. Once they’re up, Kafka can start replicating data there:
|
||||
|
||||
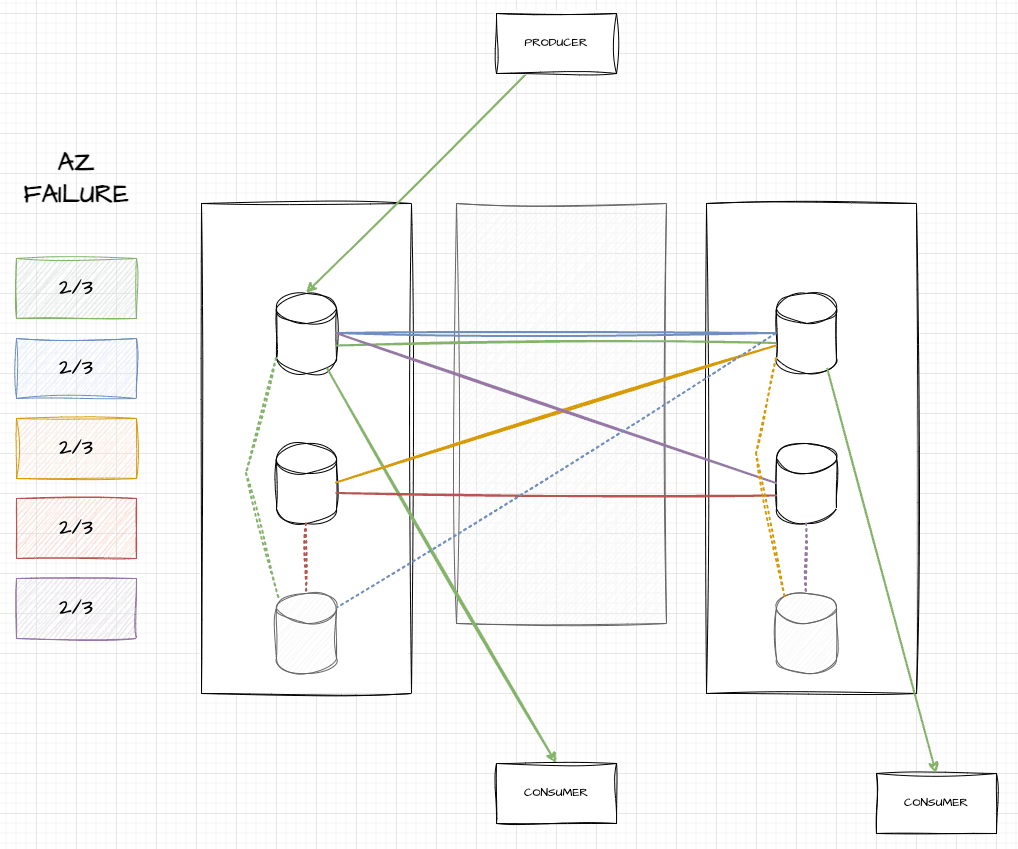
|
||||
|
||||
As seen here, two grayed out hosts have been added, and for a while, data will be replicated from in-sync replicas (ISRs) to those out of sync, represented by dotted lines. During that time, consumers can move to any ISR to get up-to-date data and be fine. These ISRs may be a bit more stressed, but overall, things stay up.
|
||||
|
||||
When we killed hosts in the cleanup, *older* brokers accidentally got killed. This can further reduce redundancy, but in some unlucky cases, may fully remove all brokers that owned a topic partition:
|
||||
|
||||
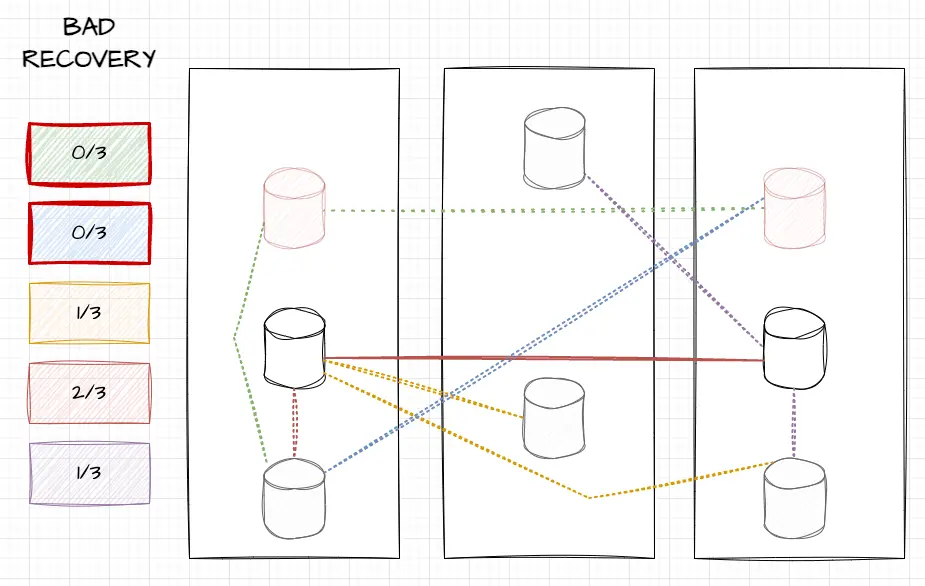
|
||||
|
||||
In this image, you can see that we killed the top two brokers (in pale red) which were in sync. Only two out of six old brokers remain, and only they have in sync data. You can see that topic partitions yellow and purple have only one healthy broker (middle-left for yellow, middle-right for purple), red was on both middle brokers and is fine, but green and blue were on neither of the remaining hosts.
|
||||
|
||||
In these cases, red and blue would find themselves leaderless. The only thing telling how much data they could find would be to know how far behind the new greyed out brokers were, and whether critical metadata had the time to be replicated.
|
||||
|
||||
### Why did it only happen in prod?
|
||||
|
||||
The key lies in the topology of the clusters. While the production cluster has many nodes, our pre-production clusters in the EU only have fewer nodes, in a way that makes this far less likely.
|
||||
|
||||
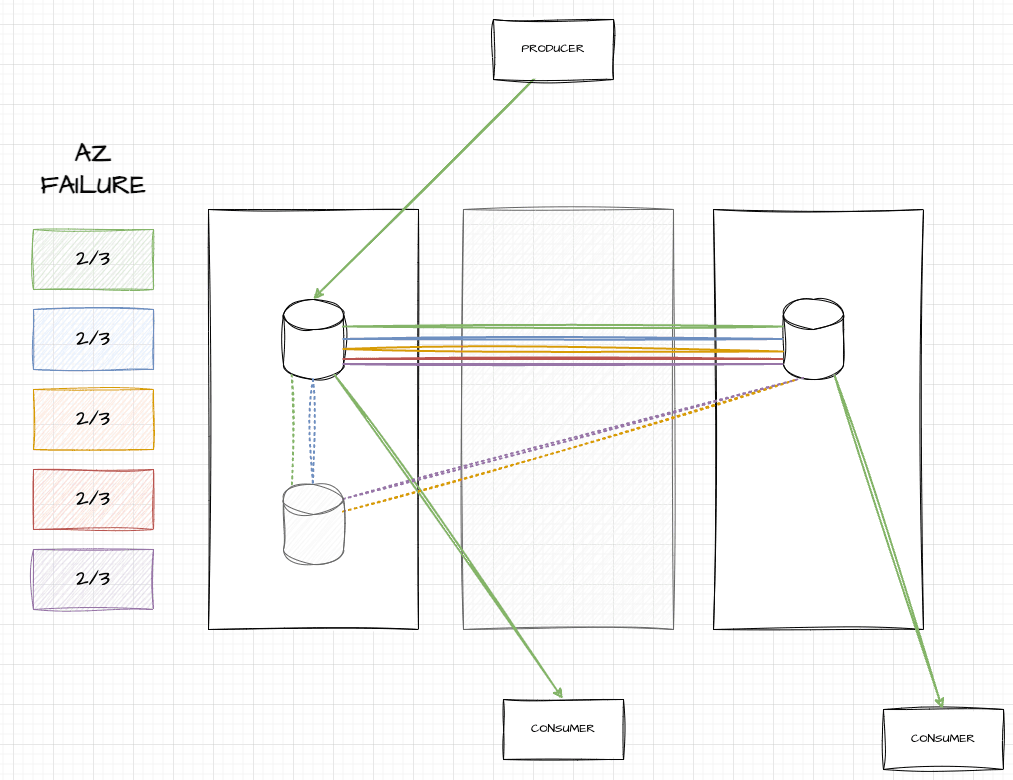
Here’s an example with the smallest cluster possible, with only three nodes. When an AZ failure happens there, only one node gets killed, and once again, all topic partitions have two out of three brokers present:
|
||||
|
||||
|
||||
|
||||
The key difference happens because we only killed one host during the failure test. Since only one was killed during the test, only one needs to be killed as part of the clean up (either of the black-outlined nodes above). By killing a single broker, we hit a total of two, and it follows that no partition will go below a single broker left, which will remain a safe leader.
|
||||
|
||||
This means that so long as you start the AZ failure with a healthy cluster, it is difficult to break the cluster. We ran four tests in pre-production clusters, but since the issue was structurally unlikely to be reproduced there, the flaw remained hidden. On top of all the other risks of doing an AZ failover like this (database failovers, large amounts of connection interruptions across multiple services, etc.) and our frequent chaos engineering around Kafka, this made everything seem adequate on that front. With limited time and resources, other aspects of the exercise that seemed riskier were what drew the attention of people running it.
|
||||
|
||||
While running multiple tests in a cluster more similar to production might still not have caught the issue, the likelihood would have been much higher.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Core dump epidemiology: fixing an 18-year-old bug
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Nathan Bronson — OpenAI
|
||||
- **链接**: https://openai.com/index/core-dump-epidemiology-data-infrastructure-bug/
|
||||
|
||||
## 简介
|
||||
|
||||
They had a weird problem, and they only really got to the bottom of it when they zoomed out and looked at the effects at the fleet level.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,82 @@
|
||||
# The Authority Gap in Human-in-the-Loop
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Dan Leiva — CEOWORLD Magazine
|
||||
- **链接**: https://ceoworld.biz/2026/07/11/the-authority-gap-in-human-in-the-loop/
|
||||
|
||||
## 简介
|
||||
|
||||
Is the human reviewer able to live up to the assurance they’re supposed to provide?
|
||||
|
||||
> They are being asked to catch an error at the one moment they have the least context to catch it.
|
||||
|
||||
## 正文
|
||||
|
||||
# The Authority Gap in Human-in-the-Loop
|
||||
|
||||
Most boards have been given the same reassurance about AI risk. There is a human in the loop. Someone reviews the model’s output before it reaches a customer, a patient, a trade, or a public system. That sentence has become the standard answer to the standard question: what happens if the AI gets it wrong?
|
||||
|
||||
It is also, in most organizations, incomplete. A human sitting at the end of an automated process is not the same as a human with the authority, the visibility, and the timing to actually change the outcome. Boards that treat human-in-the-loop as a control are underwriting a risk they have not actually inspected.
|
||||
|
||||
Amazon’s retail platform went down four times in one week in late 2026, including one six-hour outage, after an AI agent acted on inaccurate guidance it had pulled from an outdated internal wiki page. The pattern had already surfaced earlier in the year. Each incident was treated as isolated. By the time leadership reviewed the failure, the root-cause diagnosis had reportedly been stripped from the materials before the meeting. The automation didn’t fail. The operating model around it did.
|
||||
|
||||
This isn’t a story about a bad model. It is a story about where oversight was placed, and where it was missing.
|
||||
|
||||
**The reassurance that is not a control**
|
||||
|
||||
Human-in-the-loop, as most organizations practice it, means a person is positioned somewhere in the workflow with the ability to approve, reject, or escalate. That sounds like governance. It functions, in practice, like a checkpoint with no real leverage.
|
||||
|
||||
The person reviewing the output usually didn’t see the thousand small decisions the system made to arrive at it. They see a summary, a recommendation, a completed action. They are being asked to catch an error at the one moment they have the least context to catch it. This is not human oversight. It is human liability, positioned downstream of the actual decision.
|
||||
|
||||
That is the difference between real authority and symbolic presence. A human-in-the-loop step that cannot interrupt, redirect, or override the system in time to matter is not oversight. It’s a signature on a decision that has already been made.
|
||||
|
||||
**Small decisions compound before anyone looks**
|
||||
|
||||
The failure pattern that boards miss is rarely one catastrophic call. It is hundreds of small, defensible decisions accumulating faster than any review cycle can catch them.
|
||||
|
||||
A pricing algorithm shades a discount slightly upward for a segment with declining margin sensitivity. A claims model closes borderline cases a fraction faster to hit a cycle-time target. A lending model tightens an approval threshold half a point in a region with thinner data. Each individual adjustment clears its own internal check. None of them, on its own, would trigger an escalation.
|
||||
|
||||
Run for a quarter, these adjustments are no longer small. They are a pattern. And the humans nominally in the loop were never shown the pattern, because the review structure was built to catch single bad decisions, not compounding ones. By the time a regulator, a journalist, or a customer surfaces the pattern, the organization is explaining after the fact what it should have been measuring in real time.
|
||||
|
||||
This is the same failure that shows up in Amazon’s outage sequence. No single incident looked large enough to change the operating model. The pattern was the risk, and the pattern was invisible to whoever was checking the boxes.
|
||||
|
||||
**Oversight has to sit where the leverage is, not where the process ends**
|
||||
|
||||
Most human-in-the-loop designs place the human at the end: the final approval, the last screen before the action goes live. That is the point in the process with the least ability to change anything. The system has already made its recommendation. The human is choosing between rubber-stamping it or overriding a machine that has, by design, more data and more speed than they do.
|
||||
|
||||
The better question for any board evaluating AI risk is not whether a human reviews the output. It’s where in the sequence a human can still change the outcome, and whether that point has been deliberately engineered or simply inherited from wherever the workflow happened to end.
|
||||
|
||||
I use a three-class model to force this decision explicitly for every AI-enabled process. Class one is autonomous: the system decides and acts, appropriate only for low-stakes, reversible, well-understood decisions. Class two is assisted: the system recommends, a human decides, and the human genuinely has the time and context to exercise judgment. Class three is human-owned: the system informs, but the decision and the accountability sit entirely with a named person. This is especially important in regulated industries.
|
||||
|
||||
Most organizations deploy AI as if every decision were class one, then bolt on a human-in-the-loop step to make it look like class two. That mismatch, not the model itself, is where the risk lives.
|
||||
|
||||
**Accountability has to be architecture, not a job description**
|
||||
|
||||
The instinct, once a failure surfaces, is to add a reviewer. Put a person on it. That instinct treats accountability as a staffing problem. It is an operating model problem.
|
||||
|
||||
A named reviewer without a defined authority to pause the system, without a required escalation path, and without protection from blame for using that authority, will approve almost everything that reaches their screen. Not from negligence. From the structural reality that catching an anomaly buried inside thousands of clean transactions requires time, context, and standing that most review roles are never given.
|
||||
|
||||
I call this the Red Button Protocol: a mechanism for human interruption that only functions if it has four properties built in from the start. Authority, so a named role can actually pause the system. Immediacy, so the interruption changes the outcome the customer or counterparty experiences right now, not in next month’s audit. Traceability, so every use of that authority is logged with its reasoning and its result. Protection, so the person who presses it is not penalized for slowing the system down.
|
||||
|
||||
Without those four properties, human-in-the-loop is a title, not a control. Boards approving AI governance frameworks should ask whether their reviewers have all four, not whether a reviewer exists.
|
||||
|
||||
**The real leadership question is trust, not safety**
|
||||
|
||||
Treating human-in-the-loop as a safety net misframes the entire challenge. A safety net implies the goal is to catch failures after they happen. The actual leadership task is building a system that earns trust before failure ever tests it: customers who believe the organization can explain its decisions, regulators who believe the controls are real rather than cosmetic, and employees who believe they have genuine standing to intervene.
|
||||
|
||||
That trust is not produced by a checkpoint. It is produced by a designed structure of ownership, escalation, and consequence, one that names who is accountable for what a chain of automated decisions produces, not just what each individual step contains.
|
||||
|
||||
The leaders who get this right are not the ones who deploy the most AI. They are the ones who can answer, in under sixty seconds, exactly where in their systems a human still has the authority to stop the machine, and why that point was chosen on purpose.
|
||||
|
||||
If your answer requires a search through documentation to find that point, you already have your answer. Oversight is not happening. A signature is.
|
||||
|
||||
Written by [**Dan Leiva**](https://ceoworld.biz/author/dan-leiva/).
|
||||
|
||||
[CEOWORLD magazine on Google News](https://news.google.com/publications/CAAqJggKIiBDQklTRWdnTWFnNEtER05sYjNkdmNteGtMbUpwZWlnQVAB?hl=en-US&gl=US&ceid=US:en)
|
||||
|
||||
**Follow [CEOWORLD magazine](https://ceoworld.biz/) on:** [Google News](https://news.google.com/publications/CAAqJggKIiBDQklTRWdnTWFnNEtER05sYjNkdmNteGtMbUpwZWlnQVAB?hl=en-US&gl=US&ceid=US:en), [LinkedIn](https://www.linkedin.com/company/ceoworldmagazine/), [Twitter](https://twitter.com/ceoworld), and [Facebook](https://www.facebook.com/ceoworldmag).
|
||||
|
||||
|
||||
**Note**: The views expressed are those of the authors and do not necessarily reflect those of CEOWORLD magazine, its Editorial Board, or management. Content is provided "as is," may contain monetized links, and is not professional advice. See our [Ethics & Guidelines](https://ceoworld.biz/publishers-trust-statement/) for details. Reproduction requires prior written permission.
|
||||
|
||||
Contact **[\[email protected\]](https://ceoworld.biz/cdn-cgi/l/email-protection#167f787079567573796179647a7238747f6c)** for inquiries or media requests.
|
||||
66
sreweekly/markdown/525/05-the-treachery-of-postmortems.md
Normal file
66
sreweekly/markdown/525/05-the-treachery-of-postmortems.md
Normal file
@@ -0,0 +1,66 @@
|
||||
# The Treachery of Postmortems
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Will Gallego — Resilience in Software Foundation
|
||||
- **链接**: https://resilienceinsoftware.org/news/11547831
|
||||
|
||||
## 简介
|
||||
|
||||
> The problem is, as an industry we more often than not mistake capturing and archiving information for developing meaningful insights.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
# The Treachery of Postmortems
|
||||
|
||||
Postmortems, retrospectives, incident reviews—these are all different names for roughly the same thing. We're surprised by the improbable (an incident), and are looking to gain some insight from that unexpected turn of events. The problem is, as an industry we more often than not mistake capturing and archiving information for developing meaningful insights.
|
||||
|
||||
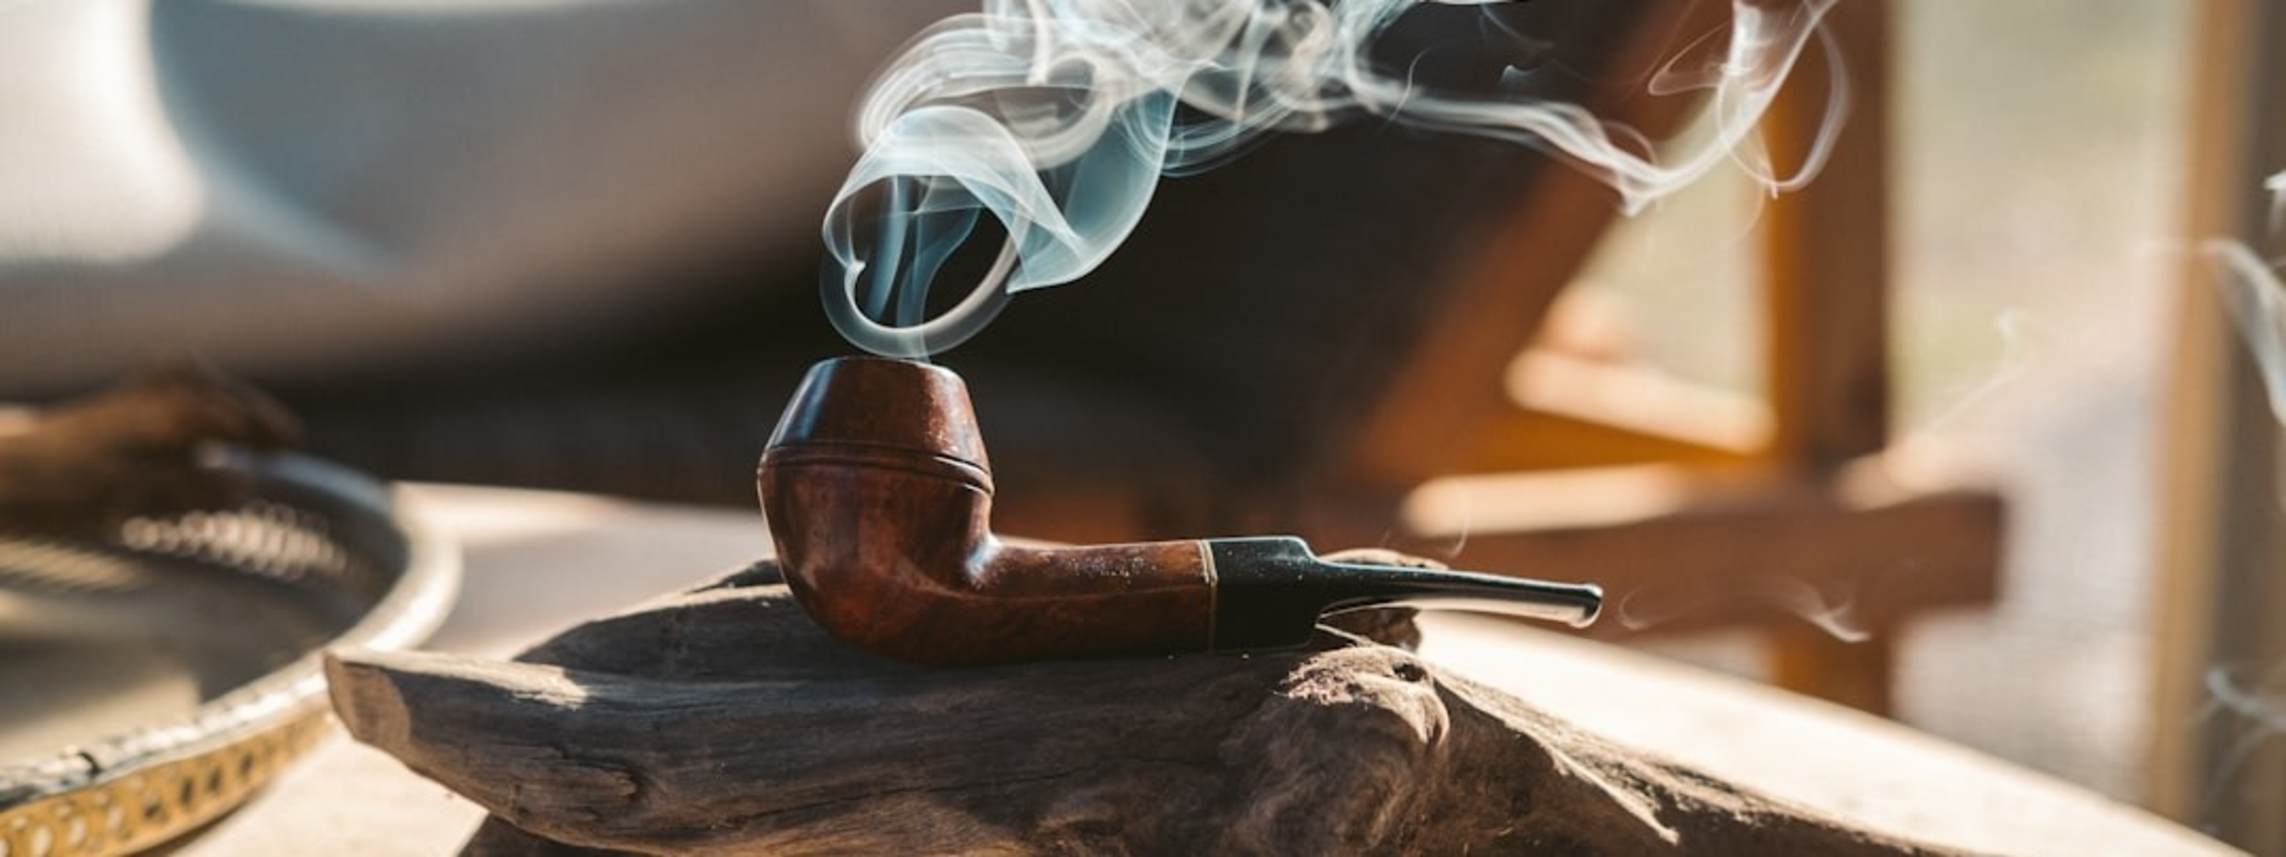
Take the famous painting "The Treachery of Images" created almost a century ago. It is unmistakably a pipe, with a long stem and bright sheen over well polished wood. But underneath in French, it reads "Ceci n'est pas une pipe" ("This is not a pipe"). Can you stuff the chamber on it and smoke it, smell the cooled embers, or even pick it up? No, because it's only the representation of the object, not the object itself.
|
||||
|
||||
Much like that pipe, the documents we share and call postmortems are only representative of an attempt at shared learning, the mechanical motions meant to mimic what's needed for learning. To our own detriment, we've conflated generating a postmortem with learning, and in doing so substitute the transcription of events with the meaningful work in understanding what has happened. Even worse, AI summarizations of events are done without human intervention and treated as the insight itself.
|
||||
|
||||
## Documentation as Performative Insights
|
||||
|
||||
Tech loves a solid incident retro document. People want information, answers to the questions surrounding the seemingly impossible: How did this happen? Our post incident docs tend towards generating “action items” in the hopes of ensuring it never happens again or just necessary PR in a public blog post to shore up the worries of a customer base or investors. These are common and understandable, but they fall short of actual learning.
|
||||
|
||||
The majority of those docs are fairly formulaic as well, a reason we see frequent use of cookie cutter templates for them. State the facts (that are worth stating), find a few choice parts, and sprinkle in a few comments, maybe drop in some dashboard screen caps for good measure. And there you have it! Your document is ready, you've captured the learning, and once again the world is made right. Right?
|
||||
|
||||
Except your retrospective, postmortem, or however you want to name it is merely data capture, which is not the same thing as a learning review.
|
||||
|
||||
## What's Wrong with Postmortem Docs?
|
||||
|
||||
We often confuse the creation of a shareable document as the goal. So what's missing?
|
||||
|
||||
A frequent failure mode, even for the best of us, is that we tend towards quick answers when disaster strikes. “Tell me the one thing we could do to make sure this never happens again, so we can address it and completely close that gap.” Unfortunately, that's not how incidents work. The sole output of an incident being a document (that likely contains recommended action items) provides a myopic view of the events.
|
||||
|
||||
There's a bias to quickly skim and move on when it's only a doc, or perhaps ignore it altogether. "I'll read it later," you say, filing it in your inbox or browser bookmarks. Weeks go by, you rediscover it, except now it doesn't hold the same weight it might have earlier. The new normal takes hold, informing what is critical and what can be ignored, information that seemed pressing at the time feeling trivial or inconsequential now. A whole host of new problems have arisen, we can't worry about something we've already "solved!"
|
||||
|
||||
That doesn't mean writing a doc is inherently wrong. We should write them, focusing on capturing discussions as they happen rather than curating a predisposed view. Allowing postmortems to be editable as well means we're continuously incorporating ideas. We should use them as a means of bringing folks in, adding to them, and allowing differing or disagreeing points of view to be surfaced.
|
||||
|
||||
If we're only writing an artifact and stopping, we're failing to make good on better understanding our system. Instead, we can use timelines, interviews, questions, graphs and figures, early suggestions, and everything else that helps develop the doc as a jumping off point.
|
||||
|
||||
## A Cure for the Common Review
|
||||
|
||||
What makes a post incident review discussion so useful? It's the chance to question assumptions and recalibrate mental models, both individual and collective. If we're taking the opinion of a few people as sacrosanct, we're missing out on what others see, in and out of the incident. So the solution for the everyday is walking the untread path.
|
||||
|
||||
Writing a postmortem can be a lonely exercise, but there's a remedy: make it a communal activity with individual interviews. If you can spare fifteen minutes or more, let participants walk you through the timeline as they see it. Those gaps, the places where folks differ or question alternative narratives, that's where they have their "aha!" moments. Most importantly let the interviewee talk and avoid correcting their answers (a common pitfall). That may seem counterintuitive but once you've nudged them you've inadvertently closed a door on all the potential misconceptions you might have trouble finding otherwise, insights you can develop as a team together in larger discussions.
|
||||
|
||||
Share the responsibility of discussion lead. Time is a luxury and not every incident is going to garner a corresponding meeting, but that doesn't mean all is lost. Some of that roteness comes from the same people writing the reviews every time. Pass the proverbial conch shell to another member of the team, specifically someone not involved in the incident or less experienced in writing. When they get stuck, if the timeline is not quite fitting together or the gaps in the runbook make themselves present, that's a great opportunity to level up. Likewise, if you can switch recitation of events between participants, you can avoid the risk of a soliloquy. It requires a little more courage, the potential to be wrong in front of a room of your colleagues, but that's also a great way to reinforce the blame awareness that's so core to a review.
|
||||
|
||||
Another pitfall I've fallen into is accidentally leading the witness, in both interview and discussion. It's tempting in interviews and various discussions to present data to folks to prime them. This sounds reasonable—you want them to be able to recall things, so why not present questions ahead of time? The rub is that priming will root them more in what you think is important. "Walk me through the event" and "What happened next?" are wonderfully simple starting points that will often surprise you as to where they will lead.
|
||||
|
||||
You're level setting without even realizing it, giving your team the chance to learn through others' lived experience. This may seem obvious, but the divide between what you read on a digital doc while your code compiles and the additional attention from a shared conversation is light years apart. Those retro docs you see shared externally, that you pore over at the virtual water cooler and say "Would have loved to be a fly on the wall in that room." You have a chance to!
|
||||
|
||||
## Post Postmortem
|
||||
|
||||
Is your team ready for the next incident? Hard to say. Resilience is adapting to the unexpected, and by definition, once you know it, it isn't unexpected. Finding time to invest in these actions are equally fraught with uncertainty. What we can do is avoid fooling ourselves with the treacherous recitative work that only seems like learning.
|
||||
|
||||
We're performing these tasks with the hopes they're not performative. If that's a sincere belief, then it also only makes sense for us to extract the most knowledge from these unplanned exercises. The greatest irony in all of this is that our most frequent discussions about incident reviews are the ones conducted elsewhere, the large corporations who fail hard and leave us to speculate past the information presented to the details that are too salacious for public consumption. We don't have to be constrained by that internally though! We're putting so much effort into capturing data, we should make good on realizing everything that comes with it, treating it as a platform to launch these larger discussions and better prepare for the next incident.
|
||||
|
||||
|
||||
|
||||
|
||||
**Will Gallego**
|
||||
|
||||
Secretary, Resilience in Software Foundation
|
||||
@@ -0,0 +1,120 @@
|
||||
# AI Won’t Keep You from Hitting the Scalability Wall
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Bru Woodring — Prismatic
|
||||
- **链接**: https://prismatic.io/blog/ai-wont-keep-you-from-hitting-the-scalability-wall/
|
||||
|
||||
## 简介
|
||||
|
||||
> AI lowers the barrier to entry. True. But it also lowers the barrier to overcommitment.The question isn’t “Can AI help us build this faster?” The question is: “Should we own the infrastructure required to keep this alive for the next five years?”
|
||||
|
||||
## 正文
|
||||
|
||||
There's an idea making the rounds in B2B SaaS product and engineering meetings right now. It sounds reasonable. It feels optimistic. And it's leading companies straight into the same trap they've always fallen into, just at an accelerated rate.
|
||||
|
||||
The idea is that "We can use AI to build our integrations."
|
||||
|
||||
Two years ago, adding in-house dev for an ERP integration to the roadmap meant a three-month research-and-dev cycle. Today, the sentiment is often: "We can knock that out in a weekend." And in the early stages, it's often correct. Modern AI coding agents are remarkably good at generating boilerplate code, interpreting API documentation, and suggesting data mapping logic.
|
||||
|
||||
AI can help you go from zero to integrated faster than ever before. That's completely true.
|
||||
|
||||
But a focus on speed-to-build hides a deeper issue. Every integration you ship is an asset, but it comes with a long-term maintenance commitment. That's right. AI-assisted custom integration builds still hit the same scalability wall that has frustrated B2B SaaS engineering teams for years. In many cases, these builds defer the pain. But, since AI can encourage teams to say "yes" to more integration requests, they sometimes amplify it. As a result, your team may hit the wall sooner and harder.
|
||||
|
||||
AI, done right, builds integrations faster. It doesn't handle everything else that makes the integration run reliably at scale.
|
||||
|
||||
## Everything's great at the beginning
|
||||
|
||||
When you use AI to build a custom integration, you're generally optimizing for the near term. You're cutting down the time it takes to write the initial code, map the first few fields, and get something working. Everything moves quickly, and it feels like a massive win.
|
||||
|
||||
But the scalability wall doesn't show up now; it comes later and is composed of blocks that AI doesn't touch.
|
||||
|
||||
- **API tracking** – Third-party APIs are part of living systems. Their vendors deprecate endpoints, change rate limits, update authentication requirements, and release breaking changes with varying degrees of notice. Your AI coding agent helped you ship the integration. But, it won't proactively monitor the Salesforce or NetSuite changelog for you, and it won't be on call when a "backward-compatible" update breaks something.
|
||||
- **The ownership gap** – If an AI-assisted build handles 90% of the logic but hallucinates an edge case in a retry loop, your senior devs are the ones debugging when it fails in production (not the AI). AI accelerates the build, but the accountability remains with the team.
|
||||
- **Infrastructure overhead** – Code is only one part of an integration. You still need to build and maintain everything around it: auth, logging, alerting, SOC 2-compliant data handling, and customer-facing configuration UIs. AI doesn't generate that operational layer.
|
||||
- **Customer requirements multiply** – The second customer who wants your Salesforce integration doesn't want exactly what the first customer wanted. So you modify it. Then a third customer needs the original version, but with different field mappings. Now you have three versions of the same integration – each slightly different, each with its own maintenance obligation, none of them happy with anything less than individual attention. Multiply that pattern across your catalog, and you understand how teams can end up maintaining[twenty-five versions of a single integration](https://prismatic.io/blog/we-built-twenty-five-versions-of-a-single-integration/) , with all the pain that entails.
|
||||
|
||||
None of these are new problems. They've existed as long as B2B SaaS teams have been building integrations in-house. AI is simply making it easier to get to these problems faster.
|
||||
|
||||
## Why AI feels like the answer
|
||||
|
||||
When AI coding tools emerged as serious productivity multipliers, it was natural to look at the integration backlog problem and see a solution. If the bottleneck is build speed, and AI makes you faster, the math seems straightforward.
|
||||
|
||||
But the bottleneck was never the build speed.
|
||||
|
||||
The bottleneck was (and is) the ongoing cost of ownership. It's the time your devs lose every time a third-party API changes. It's the afternoon that disappears when an integration fails, and your customers know before you do. It's the engineering lead explaining, again, that the roadmap has slipped because, well…integrations. It's the growing stack of tech debt that you keep working around.
|
||||
|
||||
AI lowers the barrier to entry. True. But it also lowers the barrier to overcommitment. When it becomes faster and easier to build integrations, teams build more of them. What starts as a productivity boost turns against you. Instead of five integrations, you build fifteen. Instead of "not yet," you say "we can probably do that quickly." Before you know it, you've accepted the maintenance commitment of all those integrations.
|
||||
|
||||
The scalability wall exists because the relationship between the number of custom integrations and the dev resources required to maintain them is essentially linear. If it takes one engineer to maintain five integrations, you eventually reach a point where your team is no longer building your core product. Instead, it has morphed into the integration maintenance department. AI-assisted development shifts the starting line, but it doesn't change the slope.
|
||||
|
||||
By building faster without a stable, managed foundation, you are simply accelerating your arrival at the point where maintenance debt overwhelms new feature development.
|
||||
|
||||
## What happens as you attempt to scale
|
||||
|
||||
The scalability wall doesn't arrive with a big announcement. In most cases, it grows over time as the following occurs:
|
||||
|
||||
- **Technical debt accrues under deadline pressure** – When teams race to ship, they take shortcuts. Values are hardcoded that should be configurable. Error handling is skipped. Testing is abbreviated. Code gets tightly coupled in ways that make future changes expensive. The worst part is that this debt doesn't disappear when an integration deploys. Instead, every dev who touches that code later inherits the results of less-than-optimal decisions made in the moment.
|
||||
- **Roadmaps are held hostage** – Then you try to maintain a custom integration catalog while building something new. Teams that were supposed to be shipping product features find themselves in firefighting mode, chasing failures, handling escalations, and applying patches to code that was never meant to live this long. Some teams report spending 70% or more of their integration-related engineering time on maintenance, monitoring, and debugging rather than building new value. One organization found half of its R&D team dedicated to maintaining hundreds of integrations. That's not an integration strategy. That's an integration crisis in the offing.
|
||||
- **Zombie integrations proliferate** – Some integration requests are legitimate but point to integrations that shouldn't be built and maintained without a deliberate strategy. When AI makes it easy to say yes, teams say yes, and ship integrations that live in production forever, draining engineering bandwidth. The customer who requested it may have churned. The use case may have changed. But the[zombie](https://prismatic.io/blog/how-to-audit-and-deprecate-zombie-integrations-for-b2b-saas/) is still there, still running, still using resources.
|
||||
|
||||
## The right question to ask before you build
|
||||
|
||||
The question isn't "Can AI help us build this faster?" The question is: "Should we own the infrastructure required to keep this alive for the next five years?"
|
||||
|
||||
Because that's what you're agreeing to. Not just the initial capital investment, but the day-to-day maintenance, dealing with customer edge cases, implementing security patches, monitoring everything, and handling all the tickets. Every custom in-house integration your team ships is a product you now own – with all the ongoing obligations that come with it.
|
||||
|
||||
If the answer to the second question above is, "We're not sure we can sustain this at scale," then the solution requires a different architecture approach.
|
||||
|
||||
### Generating deterministic results
|
||||
|
||||
To understand what a different architecture looks like, let's drill into what AI is – and what an integration platform is.
|
||||
|
||||
AI is generative. It creates a solution/provides an answer at a specific moment, shaped by the context it's given. That makes it powerful for accelerating builds. It also makes it inherently variable. And non-deterministic outputs in business-critical data flows often introduce risks that careful, platform-tested infrastructure doesn't have.
|
||||
|
||||
An embedded iPaaS like Prismatic is deterministic. It provides a standardized infrastructure designed to handle the full lifecycle of an integration – not just the initial build, but auth rotation, retry logic, customer-specific configs, monitoring, logging, and deployment at scale.
|
||||
|
||||

|
||||
|
||||
The most successful teams use both. AI for efficiency: writing custom logic, generating complex data mappings, and accelerating new builds. And the integration platform for scalability: handling the operational layer that the AI should not reinvent every time.
|
||||
|
||||
By wrapping integration logic in a platform like Prismatic, you decouple the build from the maintenance. When a third-party API changes, you don't have to hunt through dozens of AI-generated scripts – you update the relevant component, and it propagates across your ecosystem.
|
||||
|
||||
## What it looks like to escape the wall
|
||||
|
||||
The teams that get over (or around) the scalability wall don't do it by building faster. They do it by changing what they're building on.
|
||||
|
||||
An embedded iPaaS like Prismatic handles the infrastructure that breaks at scale, so your team can focus on integration logic rather than plumbing.
|
||||
|
||||
- **The platform does the heavy lifting** – Auth flows, retry logic, webhooks, auto-scaling compute, logging, config wizards, SOC 2-compliant data handling – all of it is provided and maintained by the platform. Your devs don't build it. They don't maintain it. That alone can reduce the code your team writes by 80% or more compared to in-house builds. What remains is the business logic – the part that actually delivers value to customers.
|
||||
- **Build once, deploy to many** – When you productize integrations on a standard platform, you're not building a new integration for every customer. You're deploying a configurable integration that adapts to each customer's credentials, endpoints, and data mapping. One integration serves dozens (or hundreds) of customers. Updates apply across the board. That's a fundamentally different approach than maintaining twenty-five customer-specific variations in parallel.
|
||||
- **Non-engineers can own more of the lifecycle** – Deployment, configuration, and first-level support don't need to involve engineering when customers and customer-facing teams have the right tools. Support staff can investigate issues without pulling an engineer from the roadmap. Customers can activate and configure integrations themselves from an embedded marketplace. Engineering stays focused on building, not on the operational overhead.
|
||||
- **Gain visibility across your entire catalog** – When all integrations run on a single platform, monitoring and alerting work across all of them at once. You identify issues before customers do. You troubleshoot with full log access. You have a level of visibility into what is happening that's uncommon with custom in-house development.
|
||||
|
||||
## AI still has a role, but it's bounded
|
||||
|
||||
None of this is an argument against AI. It's an argument for using AI where it's genuinely useful (and an argument against using it to solve problems it wasn't designed to solve).
|
||||
|
||||
Prismatic is built to work with AI. Devs can write TypeScript in their IDE with full AI assistance through the [MCP dev server](https://prismatic.io/docs/dev-tools/prism-mcp/). AI-powered component generation with [Prismatic Skills](https://prismatic.io/docs/custom-connectors/get-started/ai-assisted-development/) accelerates custom connector builds. The embedded workflow builder's [AI Copilot](https://prismatic.io/blog/ai-copilot-for-embedded-workflow-builder-early-access/) lets your customers describe what they need in plain language and watch workflows come to life. The [MCP flow server](https://prismatic.io/docs/ai/model-context-protocol/) gives AI agents access to structured, production-ready integration flows – built on infrastructure that handles auth, monitoring, and multi-tenancy at enterprise scale.
|
||||
|
||||
The difference is that the AI is accelerating the creation of code running on a scalable foundation, rather than accelerating the accrual of tech debt.
|
||||
|
||||
When you use AI inside a platform designed for scale, it works in your favor. When you use AI to build faster on a custom architecture that doesn't scale, you hit the wall sooner, but with more integrations already built.
|
||||
|
||||
## Build a sustainable integration approach
|
||||
|
||||
If you're evaluating how AI fits into your integration approach, here are the essentials:
|
||||
|
||||
- **Adopt a tiered model** – Not every integration deserves the same treatment. Productize high-volume integrations on the platform to make them reusable and maintainable. Build to bespoke requirements where the contract value justifies the build. Empower customers to create their own workflows for the long tail of idiosyncratic requests that no integration catalog can anticipate. And employ in-app agentic functionality as needed to make your workflows the structured, deterministic tools that AI agents can discover and invoke.
|
||||
- **Use AI for development velocity** – AI excels at accelerating new builds and helping developers handle complex logic. Let the platform own everything else (auth, retries, logging, alerting, deployment, and the customer configuration experience). Don't ask AI to recreate that operational layer for every new integration.
|
||||
- **Track the metrics that matter after Day 1** – Build speed matters. But so do maintenance hours, average activation time, support ticket volume, and the amount of engineering time freed up for core product work. Those last two numbers are where a sustainable integration strategy shows up in the data.
|
||||
- **Audit regularly** – As your catalog grows, so does the population of integrations that may no longer justify their maintenance burden. Retire integrations before they become a drain on the team.
|
||||
|
||||
## Faster doesn't equate to scalable
|
||||
|
||||
The "we can just use AI to build this faster" idea comes from a real place. Integration backlogs, customer pressure, and competitive urgency are all part of it. And AI absolutely speeds up individual builds. In the short term, that matters.
|
||||
|
||||
But velocity without a stable foundation means you hit the scalability wall faster.
|
||||
|
||||
Velocity doesn't make third-party APIs more stable. It doesn't reduce the maintenance burden as your catalog grows. And it doesn't change the question that every integration request brings your team: "Are we prepared to own this forever?"
|
||||
|
||||
If your team is feeling the weight of a growing integration catalog, or if you're about to accelerate into that territory with AI-assisted builds, [check out our free trial](https://prismatic.io/free-trial/) or [explore our docs](https://prismatic.io/docs/) to see how we can help.
|
||||
@@ -0,0 +1,95 @@
|
||||
# Building Cross-Team SLO Contracts for Performance Accountability
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Ujjwal Gulecha — DZone
|
||||
- **链接**: https://dzone.com/articles/building-cross-team-SLO-contracts
|
||||
|
||||
## 简介
|
||||
|
||||
> Cross-team latency problems are accountability problems, not just profiling problems. An SLO contract is one way to solve this.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# Building Cross-Team SLO Contracts for Performance Accountability
|
||||
|
||||
Cross-team latency problems are accountability problems, not just profiling problems. An SLO contract is one way to solve this.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
If you have ever developed a popular website in a microservice architecture, then most likely you have come across this case when, at first, your latency seems to increase. Then you check your dashboard and notice that the [P90 latency](https://dzone.com/articles/mastering-latency-with-p90-p99-and-mean-response-t) has increased by 300ms in the past two weeks. It is very likely you will want to analyze the individual spans and see that one of your upstream dependencies, which belongs to another team, is slower. You could write them a ticket or even page them to fix the problem. They agree to it, but they also say that all is well on their end. Still, your service-level objective (SLO) is being violated.
|
||||
|
||||
This is exactly the accountability gap that latency alone cannot solve. The page owner is the one who is responsible for the end-to-end [latency](https://dzone.com/articles/latency-tax-cloud-native-systems) of the page and may also have some dependencies which they do not have complete control over. However, the dependency owner does not have a formal agreement to maintain a specific latency profile per service, and quite fairly so. Everyone is technically following their own objectives while the customer experience is going down the drain.
|
||||
|
||||
For a Tier-0 consumer surface at Doordash, I was in charge of running a latency maintenance, improvement, and optimization plan for multiple years. This page was reliant on more than twenty backend [microservices](https://dzone.com/articles/design-patterns-for-microservices), each one being owned by a different team. Besides all the optimizations, a good SLO contract between our services and other services is what helped maintain the performance.
|
||||
|
||||
## What exactly is an SLO contract?
|
||||
|
||||
You can think of an SLO contract as a formal written contract specifying the terms and conditions between a service that is a consumer and one of its dependent services. It may identify a single or several endpoints that have a latency budget at a given percentile, how that budget is measured, and the actions following a failure to meet the budget. It is usually agreed upon by the teams' engineering managers and is possibly stored in a Google Doc, [GitHub](https://github.com/), or any other durable location. Essentially, it transforms a vague expectation into a definite commitment between teams. The consumer team is given a reliable figure for them to allocate their own e2e latency budget, whereas the dependency team receives a clear understanding of what they need to defend and also the liberty to optimize everything else. An SLO is the minimum performance level that one team guarantees to another.
|
||||
|
||||
## Elements of a contract
|
||||
|
||||
Make it brief. A good contract should be contained on a single page. Nobody reads lengthy contracts, and contracts that are not read do not lead to a change in behavior.
|
||||
|
||||
The main components that need to be included in such a contract are (but not limited to): the endpoint or RPC method that is going to be measured, the latency target and percentile, the method used for measuring and the exact name of the metric, the traffic conditions under which the contract is applicable, the duration of the contract, the escalation path when the contract is violated.
|
||||
|
||||
Here's an example:
|
||||
|
||||
JSON
|
||||
|
||||
|
||||
JSON
|
||||
|
||||
|
||||
|
||||
```
|
||||
SLO Contract: Recommendations API -> Promotions Service
|
||||
Endpoint: POST /v1/promotions/lookup
|
||||
Target: p95 latency ≤ 800ms
|
||||
Measurement: server-side histogram, recorded at Promotions Service
|
||||
metric: promotions_lookup_duration_seconds, bucket 0.8
|
||||
Conditions: traffic up to 12,000 RPS, payload size ≤ 4KB
|
||||
Effective: 2024-Q3 through 2025-Q2 (renewed quarterly)
|
||||
Escalation: If breached for two consecutive weeks at p95,
|
||||
Promotions on-call posts in #recs-promotions-slo with
|
||||
root cause within 5 business days. Sustained breach
|
||||
(4+ weeks) triggers a joint review with both EMs.
|
||||
Signed: [Recs EM] [Promotions EM]
|
||||
```
|
||||
## The hard part: How to negotiate a contract
|
||||
|
||||
Creating the contract is really not a challenge; you can even reference past data and also future plans. But the difficult part is to get all the teams to agree with the numbers. I have discussed and agreed on these quite a bit, and I want to share some points that really worked.
|
||||
|
||||
Begin with your e2e budget. If your web page has a 1.5-second p95 latency target, and the user request flow involves a call to four downstream services that run one after another, then those four services together can take no longer than about 1.2 seconds, allowing time for network, serialization, and your own processing. Do the math before the meeting. If you haven't figured out the breakdown of your own budget, then you're probably not ready to negotiate.
|
||||
|
||||
Have your data ready and explain the effect to everyone in a comprehensible way. Get the actual current latency distribution for the dependency endpoint for the last 30 days. Display p50 p95 p99. Then explain what the actual penalty is. For instance, if a 300ms delay on your page results in a loss of $20M in company annualized revenue, present it and provide evidence. This is a figure that both engineering teams and management can agree upon. Understanding each other's position is very important.
|
||||
|
||||
## Operationalizing it
|
||||
|
||||
Signing a contract and then forgetting about it is not a situation that you want to end up with. There are obviously certain things that you must do, like having a dashboard with the right metrics, relevant metrics, and the histogram bucket boundaries for these metrics. I would suggest reviewing compliance regularly in a monthly performance review meeting. The team that depends on you for its review of all the outbound contracts is its own ops review.
|
||||
|
||||
You should consider treating any breach as a real signal. In fact, the escalation path should be triggered in case a contract is breached. A breach should be taken seriously, and a lightweight postmortem might be justified so that things could be done to root cause and fix what was broken. Actually, one of the things that most contracts have is a clause that states that they will expire. At renewal, the two teams will examine the compliance of the contract over the entire period, determine whether the assumptions that they made at the time of signing are still valid, and then decide if they want to renew the contract as it is, tighten the contract, loosen the contract, or terminate the contract. If the dependency is no longer the critical path that ultimately contributes to latency, then it might be okay to terminate the contract.
|
||||
|
||||
## The compounding effect
|
||||
|
||||
Composing your initial contract is really the most challenging part. A brand new contract involves a lot of explaining, and the ground rules are set. But the second one is a piece of cake. At the platform where I was, the regimen was initiated with a lone contract between the homepage team and a single service downstream.
|
||||
|
||||
Very quickly, this method proved to be the best fit for the entire organization whenever there was an inter-team latency dependency on a critical path. The contract-supported payload size tracking tool become a piece of infrastructure utilized by each and every team; and our team was not the only one using it. Even the contract system itself turned out to be the reference model for other departments of the company when they got to the point of formalizing their own performance accountability.
|
||||
|
||||
## When should you not use this
|
||||
|
||||
I wouldn't recommend SLO contracts for every situation. They're overhead, and overhead has to be justified. Skip them for small organizations. If the consumer and dependency are owned by the same team or by two teams in the same group with the same manager, a contract adds process without changing incentives. A regular sync meeting is fine. Skip them for fast-changing dependencies. If the dependency service is in early development and its API surface is still in flux, wait until the dependency stabilizes. Skip them for low-criticality paths. The endpoint has to be on a critical path that matters to a real SLO.
|
||||
|
||||
teams
|
||||
Performance
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
78
sreweekly/markdown/525/08-none-yet.md
Normal file
78
sreweekly/markdown/525/08-none-yet.md
Normal file
@@ -0,0 +1,78 @@
|
||||
# None Yet
|
||||
|
||||
- **期号**: SRE Weekly Issue #525(2026-07-12)
|
||||
- **作者**: Tim Irving
|
||||
- **链接**: https://read.zerosevzero.com/p/none-yet
|
||||
|
||||
## 简介
|
||||
|
||||
A guide for building an incident management process at a small company, with a focus on what not to include from the start.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
A reader asked what a small company should build for incident management on day one. Here is the entire policy.
|
||||
|
||||
**Incident Policy, v1**
|
||||
|
||||
**When to declare.** Declare an incident when a problem needs more attention than you can give it alone. The question is never how bad it is. The question is whether you need people. If unsure, declare. Nobody will ever be criticised for declaring an incident that turned out to be nothing.
|
||||
|
||||
**What happens when you declare.** For the people involved, normal work is suspended. One channel per incident. One person drives: they say who does what, and they say when it’s over. Whoever declares, drives, until they hand it to someone else.
|
||||
|
||||
**Who is on call.** One person, one week at a time, on a roster we build together. If you’re not on the roster this week, you’re off. Off means off.
|
||||
|
||||
**Communication.** The driver, or someone they pick, posts what we know, what we’re doing, and when the next update lands. Guesses are labelled as guesses. If customers are affected, tell them in plain words before they find out for themselves.
|
||||
|
||||
**Afterwards.** Within a week, the driver, or someone they pick, writes a short record. What happened, what we learned, what we’ll change. Anything we’ll change goes in the backlog like any other work, or it will not happen.
|
||||
|
||||
**The count.** Every incident goes on the list. Date, duration, what broke, what fixed it. A spreadsheet is fine.
|
||||
|
||||
**Amendments**
|
||||
|
||||
None yet.
|
||||
|
||||
If your first reaction is that this cannot be enough, good. Hold onto that.
|
||||
|
||||
Every incident process you have ever worked under is a record of wounds. Each rule in the big binder at the big company exists because one day, somewhere, its absence hurt. The severity matrix followed a fight. The commander role followed a shambles. The comms template followed a customer finding out the hard way. Process is what an organisation writes down after it bleeds, and a company that has not bled yet has almost nothing to write. Copy the binder anyway and you inherit its injuries without its history. The document above is short because your scars are few. It will not stay that way.
|
||||
|
||||
Most of the page explains itself. Three lines do not.
|
||||
|
||||
Declare an incident when a problem needs more attention than you can give it alone.
|
||||
|
||||
|
||||
A declaration is not a verdict on severity. It is a mode switch. The moment someone declares, the rules of normal work suspend for the people involved: one channel, one driver, updates on a clock. That is all an incident is at this size. A signal that says stop what you are doing, I need you.
|
||||
|
||||
Which is why declaring has to be cheap. The engineer who declares at 2am over something that resolves itself by 2:15 has not cried wolf. They have tested the machinery, and the machinery worked. Say so in public. The alternative is a team that hesitates before pulling the handle, and hesitation is the most expensive failure mode available to you right now.
|
||||
|
||||
One person drives: they say who does what, and they say when it’s over.
|
||||
|
||||
|
||||
Note what this line does not say. It does not say incident commander. There is no role here, no training, no rotation of certified humans. There is a rule that at any moment exactly one person is driving, and everyone knows who. The named role comes later, and you will find it below, filed with the other things you do not need yet. The rule and the role are different sizes. Confusing them is how a fifteen-person company ends up with a forty-slide onboarding deck for a job nobody holds.
|
||||
|
||||
If you’re not on the roster this week, you’re off. Off means off.
|
||||
|
||||
|
||||
The roster looks like the part where a burden gets imposed. It is the opposite. At fifteen people, everyone is already on call, all the time, informally and without end. The pager in everyone’s head never stops. A roster does not create the on state. It creates the off state. Its product is the fourteen people allowed to sleep tonight because it is not their week.
|
||||
|
||||
This is also why the policy says a roster we build together, not a roster I have built. Write the thing with the team in the room, not for them. People defend rules they watched get made, and an on-call roster runs on that goodwill and nothing else.
|
||||
|
||||
Now for what is missing, which is most of the discipline. Everything absent from the policy is absent on purpose, and none of it is absent forever. Simple systems that work grow into complex systems that work; it does not run the other way. So every omission below carries an expiry date, written as an injury. When the absence of a thing has hurt you twice, it has earned its place in the document.
|
||||
|
||||
**Severity.** A severity matrix is a treaty, and treaties follow wars. Yours arrives the week two incidents both claim to be the most important thing in the company, or the month your services outgrow anyone’s ability to judge a response by feel.
|
||||
|
||||
**Incident commander.** Someone always drives; that rule is already on the page. The role gets a name the day two people both believe they are driving, or the day nobody does. Training and rotation follow the title, not the other way around.
|
||||
|
||||
**Blameless.** You do not legislate blamelessness at fifteen people. You model it. The written rule arrives the morning after somebody breaks the norm you never wrote down, and not a day before.
|
||||
|
||||
**Tooling.** The spreadsheet is the tool. Automation gets bought one manual step at a time, each purchase justified by the incident where that step cost minutes you did not have. When the spreadsheet starts lying to you, you may go shopping.
|
||||
|
||||
**Reporting.** Five incidents is a stack of anecdotes. Five hundred is a dataset. When the count can hold a trend, start reporting, because the people you report to fund trajectories, not moments. Until then, the count is not for them. It is a letter to the company you will be at fifty people.
|
||||
|
||||
Which leaves the last section, where two words are doing the most work on the page. None yet. Not none needed. Not none ever.
|
||||
|
||||
The amendments section is the only part of the document guaranteed to grow.
|
||||
|
||||
I love the ‘not yet’ approach to mature the guides / roles as need builds.
|
||||
|
||||
this weirdly made me want to be on call 😅
|
||||
77
sreweekly/markdown/526/01-the-incident-metrics-mirage.md
Normal file
77
sreweekly/markdown/526/01-the-incident-metrics-mirage.md
Normal file
@@ -0,0 +1,77 @@
|
||||
# The incident metrics mirage
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/05/26/incident-metrics-mirage/
|
||||
|
||||
## 简介
|
||||
|
||||
The section on fire department metrics does an incredible job of explaining why MTTR isn’t a useful metric.
|
||||
|
||||
## 正文
|
||||
|
||||
Most companies that invest in improving their incident management see something counterintuitive in the first few months: their incident count goes up. And someone in the leadership chain, looking at the dashboard, asks with concern: “Why are things getting worse?”
|
||||
|
||||
The good news is, they’re probably not. What you’re really seeing is evidence that your incident culture is getting better and stronger.
|
||||
|
||||
Incident count doesn’t measure system health; it measures how willing people are to declare an incident. When you invest in your incident management program by giving people better training, tools, and processes for handling incidents, they put those things to work, and more situations get treated as incidents. Problems that used to be handled informally (a “spicy bug” that someone handled without declaring an incident, a degradation that the on-call engineer white-knuckled through without telling anyone) now enter your incident process. The company is getting visibility into problems that used to go unnoticed, and using incident management practices and tools to address problems it would have struggled with before.
|
||||
|
||||
And it’s a self-reinforcing cycle; the more people use these skills and tools, the more comfortable they get with them, and the more they’re inclined to use them. That’s a good thing, as the way to build the skills and confidence to handle big incidents is by handling lots of little ones; the small incidents are an invaluable training ground.
|
||||
|
||||
In most companies, you’re dealing with increases in multiple dimensions simultaneously: number of users, number of products, number of features in those products, usage of those features, number of engineers, level of training and experience of those engineers, and many more. With all those factors increasing, why would you expect incident count to decrease? In a very real sense, rising incident counts can be a sign of success, not failure.
|
||||
|
||||
The question to ask isn’t “why are we having more incidents?”, it’s “why aren’t we?” And from there, other good questions follow: are we handling our incidents well, do we have the tools and training that we need, are we learning everything we can from every incident, are we preventing future incidents, are we better prepared to handle those we can’t prevent?
|
||||
|
||||
But what happens if leadership decides that rising incident count is a problem and sets a target to bring it down? People get the message: fewer incidents is better. So marginal incidents stop getting declared. The “spicy bugs” go back to being handled quietly. The degradations get white-knuckled through again. The number on the dashboard goes down, but the company has lost both the visibility its incident process was providing and the benefits of handling those situations with proper coordination, communication, and prioritization. The problems didn’t go away; you just stopped applying your best tools to them.
|
||||
|
||||
# The Goodhart’s Law problem
|
||||
|
||||
This pattern has a name: Goodhart’s Law. When a metric becomes a target, it ceases to be a good metric. And it’s not just an incident count problem; it recurs across every incident metric companies reach for.
|
||||
|
||||
The logic is straightforward. You focus on a particular metric because you think it captures something you care about. You set a target for the metric because you want to improve. And then smart, well-intentioned people find ways to hit the target. Some of those ways involve actually improving the thing you care about. But some involve optimizing the number without improving the underlying reality, and over time, the second category tends to dominate.
|
||||
|
||||
Make incident count a target for reduction, and marginal incidents stop getting declared. Make MTTR a target, and people close incidents prematurely. Make action item completion rate a target, and people write easy action items instead of hard ones. In every case, the metric looks better while the thing you actually care about (learning, reliability, preparedness) stays the same or gets worse.
|
||||
|
||||
This is human nature. Smart people optimize for what gets measured; that’s how incentives work. You’re not going to prevent it by writing sternly worded memos about gaming the system. You can only manage it by choosing metrics carefully and then paying attention to the behaviors driven by your focus on those particular metrics. Adjust when those behaviors aren’t what you intended, and be willing to retire the metric when it’s doing more harm than good.
|
||||
|
||||
# MTTR: the metric everybody loves and nobody should trust
|
||||
|
||||
Mean Time to Recovery is the most misleading incident metric in the industry. Leadership loves it because it’s a single number that appears to capture “how fast we fix things.” But it’s deeply flawed, both mathematically and in the incentives it creates.
|
||||
|
||||
Incident durations follow a power-law distribution: most incidents resolve quickly, while a small number take much longer. When you average power-law data, you get a number that describes nobody’s actual experience. Let’s imagine that last month you had ten incidents, nine of which resolved in about ten minutes each, and one that took six hours. That gives you an MTTR of 45 minutes, but that’s nowhere close to what any of those incidents actually took; it’s way off of both ten minutes and six hours.
|
||||
|
||||
Google SRE Štěpán Davidovič, in [*Incident Metrics in SRE: Critically Evaluating MTTR and Friends*](https://www.oreilly.com/library/view/incident-metrics-in/9781098103163/) (O’Reilly, 2023), used Monte Carlo simulations to demonstrate that even with a substantial dataset, MTTR can’t reliably tell you whether your incident response is actually improving. The math doesn’t just give you a misleading number; it can’t even detect real improvement when it’s happening.
|
||||
|
||||
There’s also a flattening problem: MTTR treats all incidents as interchangeable, as if the only thing that matters about an incident is how long it took. A six-hour incident where page load times were degraded but the service was still usable somehow scores worse than a one-hour total outage.
|
||||
|
||||
The incentive problems are even worse than the mathematical ones. MTTR incentivizes speed over understanding. Thorough incident response sometimes means deliberately slowing down: carefully analyzing symptoms, verifying that a fix actually works, understanding the contributing factors well enough to prevent recurrence. MTTR punishes all of that. A team that’s genuinely improving (catching issues earlier, preventing cascades, tackling more complex problems) can see its MTTR stay flat or even go up. The metric undermines morale and leadership confidence even as the team does better work.
|
||||
|
||||
# What fire departments get right about metrics
|
||||
|
||||
Here’s a lesson that most software companies could learn from fire departments.
|
||||
|
||||
Well-managed fire departments decompose their response timeline into segments and set targets only on the segments they can actually control, and expect to be fairly consistent across their incidents. Dispatch time (how long from answering the 911 call to notifying the fire crew) gets a target. Turnout time (how long from notification to crews leaving the station) gets a target. Drive time (from the crews leaving the station to arrival at the incident scene) gets a target. These are process steps that are largely consistent from one call to the next, and if they’re too slow, you can do something about it: hire more dispatchers, change how crews stage at the firehouse, build more stations.
|
||||
|
||||
What fire departments don’t set targets for is how long it takes to put out the fire. That depends on the fire. A dumpster fire and a fully involved warehouse fire are different problems with different durations, and no fixed target could meaningfully apply to both.
|
||||
|
||||
How long it takes to set up an incident channel, how long it takes responders to acknowledge pages, how long it takes the responders to join the channel and get started: these are your equivalent to the fire department’s dispatch chain. They’re largely consistent from one incident to the next, and you can set targets for them. If you’re not meeting the targets, there are obvious adjustments you can make: auto-create incident channels, set and enforce clearer on-call expectations, and so forth.
|
||||
|
||||
On the other hand, the time to find the contributing factors, the time to implement a durable fix, and the total time for the incident: those depend on the details of the particular incident. A misconfigured feature flag and a cascading database failure are different problems. Track trends, investigate outliers, learn from reviews. But don’t set targets. Targets on metrics you can’t control produce gaming, demoralization, or both.
|
||||
|
||||
# Start with questions, not metrics
|
||||
|
||||
The most useful thing is to stop asking “what should we measure?” and start asking “what questions are we trying to answer?”
|
||||
|
||||
Are incidents being handled well? Are we learning from them? Is the incident management program serving the business? Is our on-call workload sustainable? Each of these questions leads you to seek different evidence, some quantitative, some qualitative, and the answers are more useful than any single number on a dashboard.
|
||||
|
||||
These aren’t easy questions to answer, but they’re better than an easy number that misleads you (like MTTR).
|
||||
|
||||
Your dashboards should make you curious, not confident. When you see a trend, the right response isn’t “we know what’s happening.” It’s “we should dig in and find out why.”
|
||||
|
||||
And if your incident count went up this quarter? Before you panic, ask why. You might find that your increased focus on incident management is doing exactly what it’s supposed to do.
|
||||
|
||||
*This is one of the topics I cover in depth in my upcoming book, Incident Management for DevOps and SRE. If you’d like to hear when it’s available, you can sign up at [im4ds.com](https://im4ds.com).*
|
||||
|
||||
*If your company needs help with incident management right now, my consulting practice is [GreatCircle.com/im](https://greatcircle.com/im).*
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,81 @@
|
||||
# Could vs. Should: The First Year Managing an SRE Team
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Reid Savage — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/could-should-first-year-managing-sre-team
|
||||
|
||||
## 简介
|
||||
|
||||
Full disclosure on this one, the author is my former (awesome) boss, and I think I may be that staff engineer they mentioned…
|
||||
|
||||
## 正文
|
||||
|
||||
# Could vs. Should: The First Year Managing an SRE Team
|
||||
|
||||
A first-time engineering manager reflects on the first year leading Honeycomb's SRE team, from a chaotic first week through a year of lessons. Their advice for new managers: invest in relationships, seek feedback relentlessly, and never stop asking questions.
|
||||
|
||||

|
||||
|
||||
By: [Reid Savage](https://www.honeycomb.io/author/reid)
|
||||
|
||||
|
||||
|
||||
#### Uncertainty and Change Are Everywhere in Software Development
|
||||
|
||||
The following is what I’ve come to as a set of theory and practice for adapting to what is, and continues to be, one of the most rapid changes to how work is done in arguably any career. It’s worth noting that none of this is predicated on whether you are an AI believer or a skeptic. Even if you believe that 90% of what people are claiming about AI is just hype, the remaining 10% still has the ability to radically change what it means to be a software developer.
|
||||
|
||||
[Read Now](https://www.honeycomb.io/blog/uncertainty-and-change-are-everywhere-in-software-development)
|
||||
|
||||
|
||||
|
||||
As of today, I’ve drafted this post upwards of 10 times—it’s old enough that the version I first started working on was called “Reflections on 1 Year of SRE Management” (I’m currently at 2.5 years). But everything I learned during that first year became critical for the next. I had been thinking about the fact that Site Reliability Engineering (SRE) teams and [engineering management roles](https://www.honeycomb.io/blog/an-engineering-managers-bill-of-rights-and-responsibilities) have one important thing in common: there are many things you *could* do, but only some are things you *should* do, and it’s hard to define which is which. Both roles require tons of context (which I love) and tons of ambiguity (which I also love), with the occasional high-pressure situation to make things interesting.
|
||||
|
||||
Now, I manage a second team along with the first: the one behind [Honeycomb Private Cloud](https://www.honeycomb.io/platform/private-cloud). The experience I gained in my first year was critical for being ready to face the challenge of managing two teams. In this post, I talk about what I learned in that first year, what I got wrong (and right), and what I wish I’d known when I started.
|
||||
|
||||
## Jumping in the deep end
|
||||
|
||||
My first week as engineering manager for SRE was during an engineering team offsite at KubeCon. It was half conference, half team building and roadmapping, and I was terrified. “I have to sit in a whole room of people and figure out how to entertain them for several hours? And it has to be *productive*?!” After several years of being fully remote, I feared there was no way it wouldn’t be a disaster.
|
||||
|
||||
It went fine. Everyone was exhausted from KubeCon (we all resolved to never do a conference and *then* an offsite again). And with some prodding from my manager, I kept it simple: got people talking with basic agenda items, brought stickies and pens, and wrote it all down. Our roadmap of ideas was so long I had to walk across the table to get a picture of it all.
|
||||
|
||||
|
||||
|
||||
(A year later, we looked back at the list, and it turned out we worked on all these things—in roughly that order—and had completed most of them. I hope to harness that universe energy again someday.)
|
||||
|
||||
The rest of the year was a pressure cooker of learning. I was desperately trying to:
|
||||
|
||||
- Understand [what the org expected of us](https://www.honeycomb.io/blog/nothing-prepares-you-first-director-role) , and what the team expected to be doing
|
||||
- Build trust with my team and boss
|
||||
- Acquire basic management skills (e.g., coaching, facilitating, etc.)
|
||||
- Acquire advanced management skills (e.g., change management, strategic thinking, etc.)
|
||||
- Learn what my manager expected of me
|
||||
- Learn what the word “manager” even meant. As much as I appreciate [apophatic theology](https://en.wikipedia.org/wiki/Apophatic_theology) , we can do better than negative definitions like “managers do everything but write code.” Also: very not true in 2026. 🙃
|
||||
|
||||
At the end of the first year, I had gone from “I’m ready for this; throw me in the deep end” to “Oh god, I’m in the deep end” to “Oh boy, I’m in the deep end!” But it wasn’t without problems.
|
||||
|
||||
## Leverage AI-powered observability with Honeycomb Intelligence
|
||||
|
||||
Learn more about Honeycomb MCP, Canvas, and Anomaly Detection.
|
||||
|
||||
## Missteps, and things that helped
|
||||
|
||||
**I ran a lot of bad meetings.** Or, at least ones that I would beat myself up about; ones where there was low participation, or awkwardly long non-productive silences. From the team’s perspective, they were just “meh,” but I wanted to do better. I found that the more I tried to engineer the perfect thing to say or design the perfect exercise, the less people wanted to participate. I learned to work backwards from the goal of the meeting (Buy-in? Agreement? Technical design? Information? Reflection?), start with the lightest possible process that allows for full participation, and make sure the next steps are clear.
|
||||
|
||||
**I held on to feedback for too long.** It would either get old enough that it was awkward at best to bring up, or the situation would repeat, which was not ideal. I focused on lowering my own bar for bringing feedback via lots of trust-building. I don’t want there to be any friction in feedback given to me, or from me to others! An exercise that helped with this was forcing *everyone*, at least once, to give me constructive feedback (either about me or about team processes) in a 1:1 setting. I let people take time to think about it, but I didn’t let anyone off the hook and I kept it as a recurring agenda item until they gave me at least one thing that could be better (this might have helped my own comfort more than it helped theirs, but was still a valuable exercise in trust).
|
||||
|
||||
**I stopped weighing in on technical decisions.** There are plenty of former-engineers/now-managers who get caught in the trap of trying to create the same type of value they used to, but I swung the pendulum a bit too far. I would completely recuse myself from technical decisions, despite having 8+ years of direct experience in this field. In some way, this was great for learning how to facilitate and build team ownership. However, it did the opposite for our outcomes: some projects hit roadblocks I could have pointed out, and some decisions were ambiguous. I learned to use context to decide whether to make a call: unilaterally, recommending a direction, sharing advice, or staying quiet. If I was worried about biasing the team, I would state exactly what I was doing and why so we could directly talk about the reasoning, rather than have the invisible weight of the manager’s opinion hanging in the room.
|
||||
|
||||
But overall, the thing I tried hardest to do and that helped me the most was to seek out feedback in all forms, and to read a lot. **If you’re not paying attention to the results of your actions and reflecting on them, you will not grow as a manager.**
|
||||
|
||||
## The next year
|
||||
|
||||
The second year brought lots of challenges, including a sudden staff engineer departure, massive contract negotiations (with fun internal negotiations too!), and some interesting parts of managing an SRE team specifically. In my next post or two, we’ll catch up to today, covering the rapid strategic shifts to AI and what I learned from managing two teams.
|
||||
|
||||
In the meantime, here is my advice for managers who may be in their first year or who are building their managerial base:
|
||||
|
||||
- Build relationships with your peers and your team, as strong and high-trust as possible. Your role will become impossible without this.
|
||||
- Ask for feedback, and find it in things that don’t look like feedback.
|
||||
- Ask three people what they see your role as, and what they think your team does: your boss, their boss, and your reports.
|
||||
- Ask people for book recommendations, and read them.
|
||||
|
||||
And most importantly: *ask questions far more than you give orders*.
|
||||
@@ -0,0 +1,94 @@
|
||||
# Why we got rid of our small-PR rule
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Quentin Rousseau — Rootly
|
||||
- **链接**: https://rootly.com/blog/why-we-got-rid-of-our-small-pr-rule
|
||||
|
||||
## 简介
|
||||
|
||||
Rootly grapples with how to evolve their PR review process with the increase in LLM-generated code.
|
||||
|
||||
> The harder bugs hide in context, shared boundaries, and rollout paths.
|
||||
|
||||
## 正文
|
||||
|
||||
For two years, we enforced a strict small-PR culture at Rootly. Stacked PRs, atomic changes, never more than a couple hundred lines. It all made sense: smaller diffs are easier to review, easier to revert, easier to reason about.
|
||||
|
||||
Then AI started writing [most of our code](https://rootly.com/blog/what-broke-when-engineering-went-fully-agent-based).
|
||||
|
||||
## What broke
|
||||
|
||||
When a human writes code, small PRs make sense. You think in increments. You build a data model, wire up an endpoint, add a frontend component. Each step is a natural review boundary.
|
||||
|
||||
AI agents don’t work that way. They think in features. You describe what you want, and they produce the whole thing: migration, model, service, controller, tests, frontend. Splitting that output into a stack of five PRs creates busywork with no upside. The reviewer still needs to understand the full feature to evaluate any single piece. And now they’re doing it across five tabs instead of one.
|
||||
|
||||
We tried making it work. We asked agents to produce stacked PRs. The results were technically correct but contextually worse. Each PR referenced code that didn’t exist yet in the base branch. Review comments on PR #2 often depended on decisions made in PR #4. Reviewers were doing more mental gymnastics, not less.
|
||||
|
||||
The small-PR rule was optimized for human writing speed. AI removed that constraint, and the rule became overhead.
|
||||
|
||||
## What we do instead
|
||||
|
||||
We stopped reviewing AI code the way we reviewed human code. Line-by-line review of a 2,000-line AI-generated PR is rarely the best use of time. The syntax is usually fine. The patterns are usually consistent. The variable names are usually reasonable. The harder bugs hide in context, shared boundaries, and rollout paths.
|
||||
|
||||
AI bugs are context bugs. The code works, but it’s applied to the wrong thing. A migration that drops a column still in use by a background job. A service that writes to a table another team reads from. A feature flag check that gates the happy path but not the error path.
|
||||
|
||||
So we shifted the review mindset: read the risky paths closely, then ask what could go wrong.
|
||||
|
||||
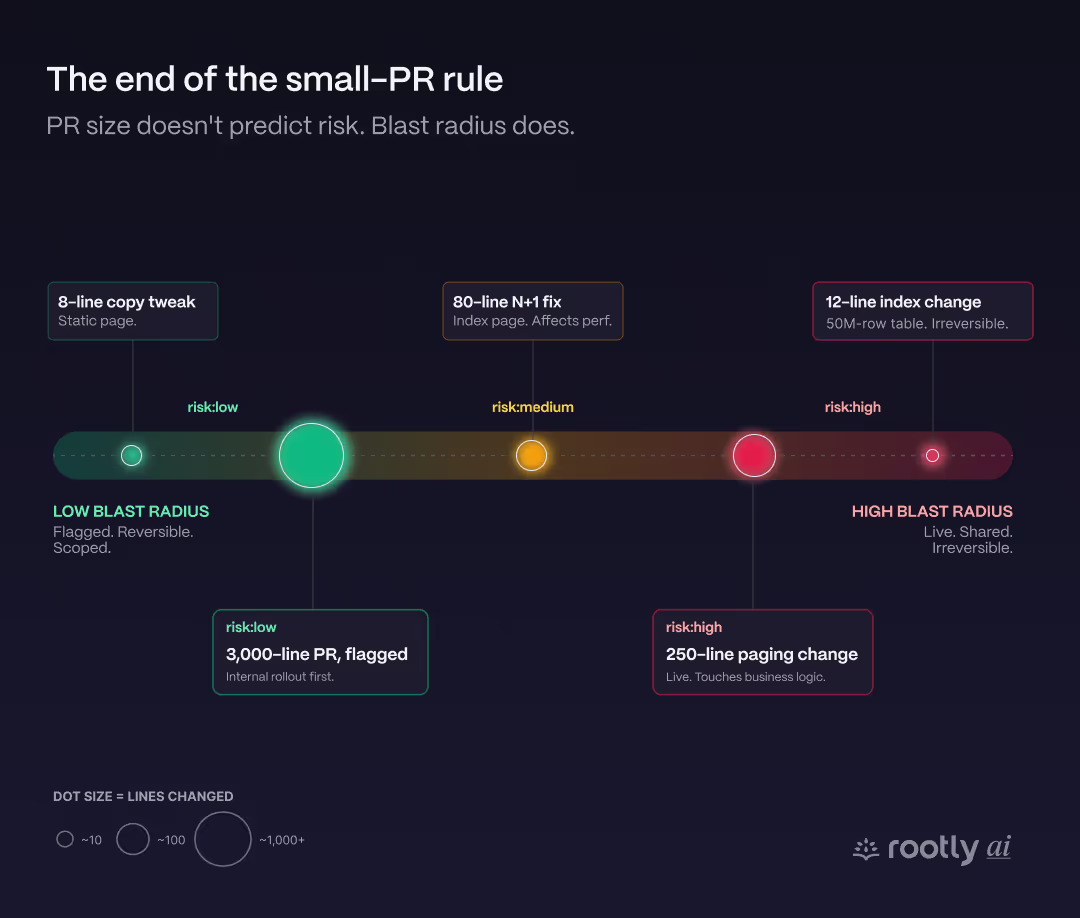
|
||||
|
||||
### AI reviewing AI
|
||||
|
||||
We built an internal AI code reviewer. It reads every PR against our engineering standards and produces a structured review: a risk assessment, a standardization score, a confidence score, and specific findings grouped by severity.
|
||||
|
||||
The key design choice: it doesn’t try to be a human reviewer. It doesn’t bikeshed variable names or suggest refactors. It answers one question per PR: “If this change has a bug, what user-facing behavior breaks?” That answer drives the risk classification, which tells the human reviewer how much time to spend.
|
||||
|
||||
It flags database migrations, security-sensitive changes, and modifications to core workflows like paging and incident creation. It distinguishes between changes that alter what the system does versus changes that affect how fast or how something looks. A N+1 query fix on an index page and a change to escalation policy execution logic both touch core code, but they carry very different risk profiles.
|
||||
|
||||
The human reviewer gets a structured starting point instead of a raw diff. For a **`risk:low`** PR that scores 5/5 on standards compliance, the review is a quick sanity check. For a **`risk:high`** PR with a 3/5 confidence score, the reviewer knows exactly which findings to dig into and where the AI reviewer wasn’t sure.
|
||||
|
||||
### Feature flags as the real review gate
|
||||
|
||||
The most important shift: we moved the safety boundary from “merge” to “rollout.”
|
||||
|
||||
Every significant feature ships behind a flag. The PR gets merged. The code exists in production. But it’s off. The real review happens during progressive rollout: enable for the team first, then a handful of customers, then 10%, then everyone.
|
||||
|
||||
If something breaks at 10%, you kill the flag first. Often that means no immediate rollback, no revert, no hotfix. The blast radius was scoped from the start. Stateful changes still need a real rollback plan.
|
||||
|
||||
This changes how you think about risk. A PR with a subtle bug in a gated feature is low-stakes. A one-line config change that’s live immediately is high-stakes. The size of the diff stopped being the useful signal. The blast radius is.
|
||||
|
||||
### Risk labels over line counts
|
||||
|
||||
Every PR at Rootly gets a risk label: **`risk:low`**, **`risk:medium`**, or **`risk:high`**. This replaced the old proxy of “is the PR small enough?” with a direct question: what happens if this breaks?
|
||||
|
||||
A 3,000-line PR behind a feature flag, with no migration, no shared contract changes, shipping to internal users first? **`risk:low`**. Ship it.
|
||||
|
||||
A 12-line PR that alters a database index on a table with 50 million rows? **`risk:high`**. That gets the careful review, the off-hours deploy window, the monitoring dashboard open on a second screen.
|
||||
|
||||
The label forces the author to think about blast radius at PR creation time, not during review. And it gives reviewers an immediate signal for how much scrutiny a PR actually needs. A **`risk:low`** PR from an AI agent that passes CI? Skim the migration check, confirm the flag boundary, approve, move on. A **`risk:high`** PR? That’s where you spend your review budget.
|
||||
|
||||
## The PR template that replaced line counts
|
||||
|
||||
Our PR template encodes this whole philosophy. It doesn’t ask “is this PR small enough?” It asks the questions that actually predict production incidents:
|
||||
|
||||
**Why** and **What** sections force the author to explain motivation and scope of impact. For AI-authored PRs, the human who prompted the agent fills these in. We explicitly instruct AI assistants not to generate these sections, because the whole point is capturing context the AI doesn’t have: why this change, why now, what’s the business reason.
|
||||
|
||||
**Rollback/Revert Plan** is a required field. Every PR needs to describe how to safely undo itself, including any data fixes. This is the single most useful thing in the template. When something goes wrong at 2 AM, nobody wants to reverse-engineer a rollback from a diff.
|
||||
|
||||
The **Standard Checklist** asks the questions that catch real production issues:
|
||||
|
||||
- Risk level label added?
|
||||
- Revertible? Are migrations reversible? Up and down tested?
|
||||
- Access control verified?
|
||||
- Exceptions logged with context?
|
||||
|
||||
Then there’s a full **Deployment Process Checklist**: document the rollout plan in Linear, document the rollback plan in the PR, validate on staging, get the deploy queue bot, validate in production. Each step has a template to fill out so nothing gets skipped.
|
||||
|
||||
None of these items care about PR size. They care about whether the change can be safely deployed and safely reverted. A 200-line PR with an irreversible migration and no rollback plan fails this template harder than a 3,000-line feature behind a flag with a clean revert path.
|
||||
|
||||
## What we learned
|
||||
|
||||
Killing the small-PR rule felt uncomfortable at first. It was one of those engineering practices that felt virtuous. But practices exist to serve outcomes, and the outcome we cared about was shipping reliable software quickly.
|
||||
|
||||
I wrote more about this shift toward production-side safety in [Stop Trying to Review AI’s Code Faster: Bet on Rollbacks Instead](https://rootly.com/blog/stop-trying-to-review-ais-code-faster-bet-on-rollbacks-instead). The short version: at Rootly, when 80%+ of PRs by count are AI-authored, your investment in review has diminishing returns. Your investment in rollback infrastructure has compounding ones.
|
||||
|
||||
Small PRs were the right answer for a team of humans writing code by hand. They’re the wrong answer for a team orchestrating AI agents that ship complete features. The discipline didn’t disappear. It moved downstream, to flags, scoped rollouts, and systems that make it safe to be wrong.
|
||||
@@ -0,0 +1,39 @@
|
||||
# The Severities We Refuse to Name
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Tim Irving
|
||||
- **链接**: https://read.zerosevzero.com/p/the-severities-we-refuse-to-name
|
||||
|
||||
## 简介
|
||||
|
||||
> The ladder does not end at SEV-3. It does not end at SEV-4. It ends somewhere below, in a category we have decided not to name.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
Every severity scale is a map of what an organisation is willing to admit.
|
||||
|
||||
The top of the ladder is well-lit and well-trodden. The bottom, less so. Walk down it slowly and you notice the lighting getting worse.
|
||||
|
||||
SEV-0 is the incident that ends one company and starts another in its place - the same logo, the same office, the same payroll, but a different company, the way a building is a different building after a fire even if the bricks are the same. You learn about a SEV-0 the way you learn about anything serious in this industry: late, indirect, and from someone who would rather not be telling you. The principal engineer at the bar who says "we don't deploy on Fridays anymore" and does not explain why. The staff engineer who flinches, fractionally, at the mention of a particular subsystem. The runbook with a section so over-engineered it could only have been written by someone who watched the previous version fail. SEV-0 is the inheritance nobody hands you. The architecture remembers. The taxonomy does not.
|
||||
|
||||
SEV-1 is the one everyone understands. The site is down. The money has stopped. Your company is mentioned by name on a news site. Someone senior is awake who should not be awake, and someone junior is typing with the terrible precision of a person who knows their commit history will be read aloud in a room next week. SEV-1 is loud, expensive, and - because of the noise and the cost - honest. You cannot hide a SEV-1. The category works because the incident refuses to be ignored.
|
||||
|
||||
SEV-2 is the incident that does not sleep, and arranges for you not to either. It is too big to ignore and too small to escalate to someone important. It is real enough that the channel stays open through the night. So you hold the line for four hours, sometimes eight, and you watch the clock the whole time, because the longer it runs the more likely it becomes that someone important will have to be woken anyway, and at that point the incident is no longer a SEV-2. SEV-2 is the severity that is partly defined by how quickly you can make it stop being one. It is where you learn that incident management is a clock-management problem.
|
||||
|
||||
SEV-3 is the workhorse. It is where most of incident management actually lives - the elevated error rates, the latency creep, the integration partner who has chosen today to have feelings about their API contract. It is also, by volume and by neglect, the severity most likely to be ignored. Not rejected. Not triaged and deprioritised. Ignored. Left in the channel like a glass on a counter that someone will get to eventually. And then four hours pass, and the glass is still there, and the customers who were patient at hour one are no longer patient at hour four, and the SEV-3 is no longer a SEV-3. It has become a SEV-2 by sheer laziness - not because the incident got worse, but because nobody made it better while making it better was still cheap. If you want to know whether an organisation's incident management is real or performative, watch how it handles a SEV-3 on a Friday afternoon. The answer is usually: it doesn't.
|
||||
|
||||
|
||||
|
||||
SEV-4 is the severity that half the industry claims to have and nobody actually runs. It is the incident too small to mobilise for and too real to dismiss - the queue that backed up for six minutes, the endpoint that five-hundred'd for a fraction of a percent of traffic, the alert that fired and resolved before the channel filled. In theory this is where the organisation learns. In practice it is where the organisation files and forgets, because the cost of taking a SEV-4 seriously is higher than the cost of shipping something else instead. So the category quietly empties. And in some places - I worked inside one - it never existed to begin with. The scale goes one, two, three, and then straight to the end. A house with no ground floor. Everyone who worked there understood why without ever quite saying it.
|
||||
|
||||
SEV-5 is the category we do not have, because having it would mean admitting what it contains. It is the documentation that went stale in 2023 and is still being cited in 2026. It is the monitoring nobody trusts, because the thresholds were set by someone who left three reorgs ago. It is the single engineer who understands the billing pipeline and is currently interviewing at a competitor. It is the runbook that has been wrong for fourteen months, and the team that has learned to work around the wrongness, and the new hire who will inherit the workaround as the thing itself. None of this will page you. All of it will kill you. The reason we do not have a severity for slow erosion is that a severity implies a response, and the response to slow erosion is structural, and structural responses require someone willing to say aloud that the house is on fire even though nothing is visibly burning.
|
||||
|
||||
The ladder does not end at SEV-3. It does not end at SEV-4. It ends somewhere below, in a category we have decided not to name.
|
||||
|
||||
It will wait there, whether we name it or not.
|
||||
|
||||
Interesting, we were just talking with @adhorn about severity and categorisation of incidents in general - if severity is even the "right" measure.
|
||||
|
||||
Also - awesome graphics across posts!!
|
||||
@@ -0,0 +1,13 @@
|
||||
# The New Complexity Crisis: Why Modern Platforms Fail Differently Than Monoliths
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Vivek Kadam — Communications of the ACM
|
||||
- **链接**: https://cacm.acm.org/blogcacm/the-new-complexity-crisis-why-modern-platforms-fail-differently-than-monoliths/
|
||||
|
||||
## 简介
|
||||
|
||||
The shift to distributed systems over monoliths can increase complexity. We don’t need to go back to the old way, says this article, but we do need to build with operability in mind.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,66 @@
|
||||
# Your service catalog is already wrong
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Spiros Economakis
|
||||
- **链接**: https://thereliabilityengineering.substack.com/p/your-service-catalog-is-already-wrong
|
||||
|
||||
## 简介
|
||||
|
||||
> Every service catalog is declared by hand and drifts from reality within weeks. That was a productivity tax when humans read it. Now that agents act on it, a stale catalog is a production risk.
|
||||
|
||||
I’m not so sure about the solution offered, but the risk is real. Humans can already act on incorrect service catalog information, but agents can do it much more quickly.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
Open your service catalog and pick a service at random. Check the owner, the dependencies, the on-call. There is a good chance at least one of those is wrong. Not because anyone was careless, but because the catalog was declared once and production kept moving.
|
||||
|
||||
This is the quiet failure at the center of every developer portal, and it is about to get expensive.
|
||||
|
||||
## **Declared, not observed**
|
||||
|
||||
Almost every [service catalog](https://www.nofire.ai/glossary/service-catalog) is populated by declaration. An engineer writes an entry, usually a YAML file, describing a service, its owner, and what it depends on. Backstage, Cortex, Compass, and Roadie are all built on this assumption: that humans will keep the catalog accurate.
|
||||
|
||||
They will not. Not because they are lazy, but because the work is invisible and never finished. A team reorganizes. A dependency shifts. A new service ships on a Friday. The `catalog-info.yaml` is correct the day it is written and drifts from there. In practice the gap opens within about two weeks, and it compounds.
|
||||
|
||||
You already know this, because you have lived it. The real dependency graph gets discovered during the incident, at 3am, when the catalog turns out to have been describing a system that no longer exists.
|
||||
|
||||
## **The stakes just changed**
|
||||
|
||||
For years a stale catalog was a productivity tax. An engineer hit a wrong entry, lost twenty minutes, noticed, and corrected course. Annoying, survivable.
|
||||
|
||||
That calculus breaks the moment the reader of the catalog is no longer only human. Coding agents, deployment agents, and incident-response agents now read the catalog and act on what it says. The twenty-minute detour a person would have caught becomes an action taken in production, on a dependency that moved months ago.
|
||||
|
||||
This is the same shift we keep coming back to: the move from **observe to control**. Once software is acting on your production estate, the accuracy of the context it reads stops being a convenience and becomes a safety property. The catalog nobody maintains has quietly become the context layer every agent that touches production depends on.
|
||||
|
||||
## **Observe the catalog instead of declaring it**
|
||||
|
||||
The fix is not more discipline. It is a different architecture.
|
||||
|
||||
A service catalog should be **observed, not declared**. Instead of asking humans to describe production in YAML, derive the catalog from what production is actually doing: read the repositories, the distributed traces, the deploy events, and the incident history, and reconcile the catalog on every change. Ownership comes from deploy history and contributor activity. Dependencies come from the observed call graph. Readiness is scored from real SLOs, alerts, and incidents. Blast radius is calculated from live topology.
|
||||
|
||||
If that sounds familiar, it is because it is the same foundation as the [Production Context Graph](https://www.nofire.ai/glossary/production-context-graph). The service catalog is simply the graph made legible: the view a human or an agent reaches for when the question is “what is this service, who owns it, and what breaks if it fails.” It is the context half of the [Context and Control Model](https://www.nofire.ai/glossary/context-and-control-model), made concrete.
|
||||
|
||||
## **Every fact carries where it came from**
|
||||
|
||||
There is one more requirement, and it matters most now that agents are in the loop. Every fact in the catalog has to carry its provenance. Each dependency is labeled runtime (observed from the live call graph), synthesized (inferred from patterns), or intent (declared in code), each with a confidence score. Where there is no evidence, the catalog says so rather than filling the gap.
|
||||
|
||||
That is the difference between a catalog a human tolerates and one an agent can safely act on. A person can sense when an entry looks off. An agent needs the catalog to tell it, explicitly, how much to trust each fact before it acts.
|
||||
|
||||
## **Where to start**
|
||||
|
||||
If you are running Backstage, Cortex, Compass, or Roadie, the catalog is not your enemy. The declaration model is. You can keep the portal and change how it stays true.
|
||||
|
||||
- See the approach applied to your own stack: [the self-maintaining service catalog](https://www.nofire.ai/product/service-catalog) .
|
||||
- Go deeper on the architecture and the migration path in the [Service Catalog guide](https://www.nofire.ai/resources) .
|
||||
|
||||
Your catalog is going to be read by something that acts on it. It should reflect what is running, not what someone declared six months ago.
|
||||
|
||||
### **Follow me on**
|
||||
|
||||
### **Contact me!**
|
||||
|
||||
- If you want to start adopting a culture of reliability and AI, feel free to [Contact me](https://mentors.to/spirosoik) .
|
||||
|
||||
The line about a stale catalog going from a productivity tax to a production risk the moment agents act on it is the real shift. A person hitting a wrong entry loses twenty minutes and shrugs it off, an agent hitting the same wrong entry just executes on it.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Building Service Topology at Scale: Architecture, Challenges, and Lessons Learned
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Parth Jain, Rakesh Sukumar, Yingwu Zhao, Renzo Sanchez-Silva, and Nathan Fisher
|
||||
- **链接**: https://netflixtechblog.com/building-service-topology-at-scale-architecture-challenges-and-lessons-learned-f4b792f3f0d8
|
||||
|
||||
## 简介
|
||||
|
||||
> What you’ll learn in this post isn’t a success story, it’s a learning journey. We’ll walk through the architecture decisions that enabled scale, the production challenges that tested those decisions, the optimization methodology that guided us through, and the lessons that apply to any distributed system.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,138 @@
|
||||
# Incident Response in the Age of AI (Incident Fest)
|
||||
|
||||
- **期号**: SRE Weekly Issue #526(2026-07-19)
|
||||
- **作者**: Sam Salter — Uptime Labs
|
||||
- **链接**: https://www.uptimelabs.io/articles/incident-response-ai
|
||||
|
||||
## 简介
|
||||
|
||||
A summary of Uptime Labs’s Incident Fest, with a lot of interesting tidbits around AI, incidents, and the evolving interplay between them.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
### Ready to make incident response your competitive advantage?
|
||||
|
||||
See how Uptime Labs builds provable, scalable incident response capability across your organisation.
|
||||
|
||||
[Incident Fest](https://www.uptimelabs.io/incident-fest-26/home) is our fun, free virtual festival. More importantly, it’s a place for incident responders to share their stories and learn from others.
|
||||
|
||||
This year, we were delighted to welcome a variety of exceptionally talented speakers to the stage to discuss the evolving (and not always harmonious) AI/incident response relationship. Note that these are a few highlights, so please go and watch the full talk recordings after!
|
||||
|
||||
## The Theme
|
||||
|
||||

|
||||
|
||||
|
||||
## Where AI Offers Wins
|
||||
|
||||
All three speakers were upfront that AI is already pulling real weight in incident response:
|
||||
|
||||
- **Stu Rimell (Uptime Labs)** noted that LLM tooling "is starting to show promise in addressing the low-hanging fruit of incident response" i.e. auto-summarising chat threads, intervention suggestions, remedial PRs.
|
||||
- On code itself: "AI is a tremendous tool for understanding code"
|
||||
- On freeing up attention: "the idea of being able to offload some or most of that cognitive load is legitimately exciting", letting responders focus on the genuinely hard & novel parts of an incident instead of the rote ones.
|
||||
- **J. Paul Reed (Chime)** cited research showing an upside when an AI's diagnostic suggestions were correct - the humans using it "performed 53 to 67% better than when they worked without AI assistance".
|
||||
- **Sylvain Kalache (Rootly)** pointed to Meta's agentic mutation-testing tool (thousands of synthetic bugs generated, 73% accepted by engineers as valid tests) calling it "a massive win that would have been impossible to do manually or extremely resource-intensive"
|
||||
- His summary: "AI-assisted coding is not going anywhere. It's here to stay" - the goal isn't resistance; it's building the muscle to use it well.
|
||||
|
||||
In other words, AI offers a variety of exciting, innovative ways to make engineers’ lives easier. The question then becomes ‘how do we enable AI safely in the short and long term?’ - which is the question the festival aims to unpack carefully.
|
||||
|
||||
|
||||
## **The Leftover Principle (Stu Rimell, Uptime Labs)**
|
||||
|
||||
Stu opened with a story: he’d just landed in Seattle for SREcon and his rideshare app was convinced he was standing on the street outside the terminal when he was actually three floors up in the parking garage. GPS is a solved problem - *until the moment it isn’t*, and you’re back to reading signs and asking strangers for directions.
|
||||
|
||||

|
||||
|
||||
*(editors note: Stu was thankfully able to eventually leave the car park and get captured in this instantly iconic photo in Seattle)*
|
||||
|
||||
Stu’s story, he said, is exactly what it feels like every time automation reaches the edge of what it can do.
|
||||
|
||||
The Leftover Principle describes the tasks left over once automation has done all it can, or was designed to do.
|
||||
|
||||
- Leftover tasks tend to be either too trivial to bother automating or too rare, complex and novel to automate at all.
|
||||
- Incidents fall squarely into that second (gnarlier!) category.
|
||||
|
||||
### **Historical grounding**
|
||||
|
||||
The concept traces back to [Alphonse Chapanis](https://en.wikipedia.org/wiki/Alphonse_Chapanis): the ‘godfather of human factors,’ who redesigned the B-52 cockpit after pilots kept retracting the landing gear instead of the flaps. Then, it passed to David Woods and Erik Hollnagel, who pushed back on ‘automate everything; thinking. The canonical reference is Lisanne Bainbridge’s 1983 paper [*Ironies of Automation*](https://ckrybus.com/static/papers/Bainbridge_1983_Automatica.pdf) - required reading, Stu notes. Its key paradox: the more you automate, the *more* important the human role becomes, not less.
|
||||
|
||||
At London’s [OOPS](https://luma.com/calendar/cal-fwsQhbMXAJgtV2H?period=past) community meetup, Stu heard two approaches emerging: auto-diagnosis and copilot mode. LLM tooling shows promise on the low-hanging fruit; complex scenarios remain human territory.
|
||||
|
||||

|
||||
|
||||
|
||||
### The Four Dragons
|
||||
|
||||
- **Harder leftovers** : what’s left is rarer and more novel by definition -*that’s why it wasn’t automated already*
|
||||
- **Skill atrophy** : less practice erodes skills; Bainbridge warned systems would end up ‘riding on skills which later generations of operators cannot be expected to have’
|
||||
- **Situational context loss** : arriving only at the leftover point is ‘like coming into an argument halfway through’
|
||||
- **Accountability gap** : humans remain accountable for incidents even as their expertise to actually exercise that accountability erodes. The risk is ending up in a job that's "very boring but very responsible", with no real opportunity to build or maintain the incident response skills that responsibility demands.
|
||||
|
||||
Stu backed this with numbers: [GitHub’s weekly commits](https://quasa.io/media/github-s-ai-agent-tsunami-275-million-commits-a-week-14-billion-projected-for-2026-and-the-platform-is-starting-to-crack) jumped from 19 million to 275 million, and the [2026 Faros AI Engineering Report](https://www.faros.ai/research/ai-acceleration-whiplash) found incidents per PR up almost 250%.
|
||||
|
||||
“The dream of being able to sleep through on-call, as one AI SRE vendor advertises, is for some a pleasant one, but for some it’s a horrific nightmare.”
|
||||
|
||||
Ultimately, ‘augment, don’t replace’ is a decent rule of thumb. Copilot beats that fantasy; lean on [Klein et al.'s 2004 team-player challenges](https://ieeexplore.ieee.org/document/1363742); and above all, practice: game days, tabletops, chaos engineering, the way pilots keep training despite autopilot. It’s the [gap Uptime Labs is built to close](https://www.uptimelabs.io/).
|
||||
|
||||
|
||||
## **Vibe Firefightin’: When AI Has Entered the Incident Bridge (J. Paul Reed, Chime)**
|
||||
|
||||
J. Paul Reed, who holds a master’s in human factors and system safety, covered ironies of automation and AI, joint cognitive systems, and tips for the incident bridge.
|
||||
|
||||
“We were doing agentic stuff without AI long before AI came along.”
|
||||
|
||||
### **Ironies of automation and AI**
|
||||
|
||||
Manual skills deteriorate when unused; automation forces a speed-versus-correctness trade-off, so we spot-check for *acceptability* rather than *correctness*. Tracing an AI’s reasoning can be flatly impossible.
|
||||
|
||||
Forty years after [Bainbridge](https://ckrybus.com/static/papers/Bainbridge_1983_Automatica.pdf), researcher [Mica Endsley extended this to AI](https://www.tandfonline.com/doi/full/10.1080/00140139.2023.2243404): the more capable AI seems, the worse we get at compensating for its shortcomings (see: fatal Tesla Autopilot disengagements). Plus, the more naturally it talks, the harder it is to judge if it’s lying.
|
||||
|
||||
“It’s become sort of… the ‘*you’re absolutely right’* joke…
|
||||
|
||||
### **Joint cognitive systems**
|
||||
|
||||
Incidents are worked by people, data, automation and AI, all acting as ‘agents.’ Coordination depends on autonomy, authority, directed attention and interpredictability: AI still falls short on the last two. As [Dave Woods](<https://en.wikipedia.org/wiki/David_Woods_(safety_researcher)>) puts it: “Technologists often mistake connectivity… for coordination.”
|
||||
|
||||
### **Tips for the bridge**
|
||||
|
||||
Tell your incident commander when you’re using AI; post your interpretation, not AI slop; engage the AI rather than letting it broadcast unsolicited answers; and ask for explanations, not recommendations. In [Woods’ study of nurses using AI diagnostics](https://ai-frontiers.org/articles/how-ai-can-degrade-human-performance-in-high-stakes-settings), correct AI boosted performance 53-67%, but misleading AI made it 96-120% worse than no AI at all.
|
||||
|
||||
|
||||
## **More Code, More Incidents? Staying Reliable When AI Writes the Code (Sylvain Kalache, Rootly)**
|
||||
|
||||
Sylvain, who leads Rootly AI Labs, framed the talk around a formula: incident rate = C × P
|
||||
|
||||
*(C represents the volume of changes; P the odds of introducing a failure)*
|
||||
|
||||
### **C is climbing fast**
|
||||
|
||||
Coding-assistant-heavy developers ship 10x more code, PRs have doubled in size and Rootly’s data shows incidents per customer tripled since 2023. Subsequently, [Amazon](https://www.theregister.com/2026/03/10/amazon_ai_coding_outages) and even [Anthropic](https://www.techtimes.com/articles/318514/20260616/claude-outage-tenth-disruption-12-days-exposes-anthropic-infrastructure-strain.htm) have had rough reliability stretches tied to this. Plus, there’s less help available, since `git blame` might now lead to a shrug:
|
||||
|
||||
“Hey, sorry, mate, I didn’t really write this piece of code. I just prompted it. You are on your own.”
|
||||
|
||||
### **P is climbing too**
|
||||
|
||||
[CodeRabbit’s research](https://www.coderabbit.ai/blog/state-of-ai-vs-human-code-generation-report) found AI-generated code ships with meaningfully more bugs. Favourites: AI tests that validate already-broken logic rather than real intent; a Vercel agent that hallucinated a repo ID and deployed the wrong codebase; and slopsquatting, where attackers [pre-register package names that LLMs are likely to hallucinate](https://www.aikido.dev/blog/slopsquatting-ai-package-hallucination-attacks). His point: every AI screwup has a human equivalent, just ~10x faster - blameless culture should extend to LLMs too.
|
||||
|
||||
### **Keeping P low**
|
||||
|
||||
The fundamentals (deploys, observability, resilience) matter more than ever. Rootly risk-triages PRs by blast radius and revertibility, and requires every PR to document its *why* (human-only) and a revert plan. [Intercom](https://www.intercom.com/blog/the-safety-of-speed-shipping-code-at-intercom/) ships 180x/day behind flags that can be killed in under a minute, and [Meta’s agentic mutation testing](https://engineering.fb.com/2026/02/11/developer-tools/the-death-of-traditional-testing-agentic-development-jit-testing-revival/) generated thousands of synthetic bugs, 73% of which were accepted as valid tests.
|
||||
|
||||
Sylvain summed up the tension:
|
||||
|
||||
“Your manager is like, ‘chop, chop, chop - you need to do more with less because you have AI by your side.’”
|
||||
|
||||
Like pilots training for an engine failure they’ll likely never face, teams need to keep practising incident response as AI takes over more of it (which is why Rootly partnered with Uptime Labs on [Rootly Academy](https://rootly.com/rootly-academy)).
|
||||
|
||||
|
||||
|
||||
Sylvain’s closing line: C is out of your control. P is your job.
|
||||
|
||||
|
||||
## For the Full Experience, Visit the Festival!
|
||||
|
||||
Instead of overpriced beers and dubious headliners, come and explore [Incident Fest](https://www.uptimelabs.io/incident-fest-26/home) in the comfort of your own home. As well as recordings of these excellent talks, there’s a poll booth, an incident challenge with prizes and more!
|
||||
|
||||
|
||||
121
sreweekly/markdown/527/01-minus-two-minutes.md
Normal file
121
sreweekly/markdown/527/01-minus-two-minutes.md
Normal file
@@ -0,0 +1,121 @@
|
||||
# Minus Two Minutes
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Tim Irving
|
||||
- **链接**: https://read.zerosevzero.com/p/minus-two-minutes
|
||||
|
||||
## 简介
|
||||
|
||||
Amazing idea: negative time to detection. It’s when you know an incident is coming even before the impact actually begins. Some incident management and metrics systems aren’t designed to track it, and some incident processes ignore or even penalize it.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
At 1:24 in the morning on 26 March 2024, the lights went out on a container ship called the Dali, and the Francis Scott Key Bridge had about five minutes left to stand.
|
||||
|
||||
The ship had left its berth at Seagirt a little before, bound for Sri Lanka, two harbour pilots aboard and the better part of five thousand containers stacked on deck. Then a complete blackout. Not a flicker. Nearly a hundred thousand tonnes of steel turned into dead weight in the channel, carried by its own momentum and the current and aimed, with the indifference of physics, at one of the piers holding the bridge up.
|
||||
|
||||
What happened in the time it had left is the only part of the night the spreadsheets cannot hold.
|
||||
|
||||
At around 1:27, the crew got a mayday out. A pilot came over the radio and asked, in the panicked voice of a man watching something he has no way to stop, for the bridge to be closed to traffic. The dispatcher who took it did not open a ticket or convene a working group. He told the officers to hold all traffic until somebody got the ship back under control. Maryland Transportation Authority cars rolled to both ends of the span and stopped the traffic where it sat. Somewhere on the recording a voice remembers the men working on the deck and asks whether anyone can reach the foreman and get them off in time.
|
||||
|
||||
There were eight of them, filling potholes for a contractor called Brawner Builders at one in the morning on a bridge the whole city drove over without thinking. The officers had time to stop the cars. They did not have time for the men. At 1:29 the bow met the pier and the central span came down in something close to thirty seconds, and it took the crew into the Patapsco with it. Six of them did not come back up.
|
||||
|
||||
Read the timeline again, because the number that matters is the gap. Roughly two minutes between the mayday and the collapse. Two minutes in which the people responsible for that bridge knew, with total clarity, that it was going to be struck, and acted on that knowledge before a single beam had moved. The response to the incident began before the incident happened. By the time the structure gave way, the most consequential decision of the night had already been made and carried out. The cars were stopped. The mayor would say afterwards that the mayday saved many lives, and he was right, and you can prove it by counting the empty lanes.
|
||||
|
||||
Now try to log it.
|
||||
|
||||
Open whatever your shop uses to record incidents and find me the field for that. There is a time you detected the problem, a time you resolved it, and a duration in between, and the whole apparatus assumes, without once saying so aloud, that detection comes after things start to break. Time to impact is meant to be a positive number. The bridge does not offer a positive number. The bridge offers minus two minutes, and most tooling, handed minus two minutes, will reject it, blink, and quietly record a zero.
|
||||
|
||||
That zero is the lie this entire piece is about. The two minutes that decided who lived are the one interval the instrument cannot see.
|
||||
|
||||
What the bridge gave us has a name. Negative time to impact: the response reaches the world before the damage does, and the blast radius comes out at zero because somebody got there first. It has a quieter sibling, negative time to detect, where you clock the trouble before it has even started to go wrong, reading the trajectory and calling it while every dial still says green. The fact that we need names for these at all should worry you.
|
||||
|
||||
Strip the jargon back and the ideas are almost insultingly simple. Time to detect is the gap between a thing starting to go wrong and somebody noticing. Time to impact is the gap before the trouble lands on someone who never asked for it. Both are assumed, always, to be positive numbers. The trouble comes first, you arrive second, and the whole grammar of the discipline takes it for granted that you are late. Turn either one negative and you have described the best work anyone in this field ever does. The pilot on the Dali was working in negative time. So is every team that ever caught a poisonous change and pulled it back before it reached more than a handful of users. They were responding to an incident that had not happened yet.
|
||||
|
||||
|
||||
|
||||
Here is the problem, and it is not a software problem, though software is where you will find the body. Every tool we have built to manage incidents encodes the same little machine, and the machine has three stops. Something breaks. You notice. You fix it. Detected, mitigated, resolved, with a clutch of timestamps hung off each stop so we can compute the famous numbers. We cannot even agree what the R in MTTR stands for, repair or recovery or resolution, and we will argue about it in good faith at a conference until the bar closes, but every faction agrees on the one thing that matters here. Whatever the R is, it comes after the break. The clock is bolted to the floor and it only counts up. There is no field for the response that arrived before the failure, because the schema was built by people who never imagined you might be early.
|
||||
|
||||
You can watch this happen in a room. Describe negative time to detect to a dozen competent engineers and half of them will stall, not because they are slow but because you have handed them an idea their model has no slot for. You can watch them try to file it under “detected” and find nothing in front of it. The blank look is not stupidity. It is data. A vocabulary that cannot hold an idea makes the idea hard to think, and a profession that cannot think an idea has no way to reward the people who keep doing it anyway.
|
||||
|
||||
So we have built an entire measurement discipline on the quiet assumption that we are always too late, and then we act surprised when being early shows up as nothing at all. The tool did not decide that detection comes after the break. People decided that. People who believed, somewhere underneath the process diagrams, that the correct moment to respond to a fire is the moment you can finally smell the smoke.
|
||||
|
||||
I know the type. I used to be one of them.
|
||||
|
||||
The world I am about to describe is mostly gone now, paved over by continuous delivery and pipelines that ship a hundred times a day, and good riddance to most of it. But there was a time, not so long ago, when change was a scheduled event. You did not ship on a Tuesday afternoon because you felt like it. You booked a window. A slot, approved weeks out by a committee that met on Thursdays, in which you were permitted to touch production while the rest of the company slept. Two in the morning on a Saturday, four hours, rollback plan attached. The window was sacred. The window was the whole liturgy.
|
||||
|
||||
And every so often a team would blow straight through it.
|
||||
|
||||
Not the good teams. The good teams were home in bed by three. The ones who overran were the ones who had planned the work on the back of a serviette, brought the wrong people, or brought no people, and discovered at the worst possible hour that step seven of eleven did not do what the runbook promised. By rule, any change that ran past its window stopped being a change and became an incident. That was the bright line, and I was the person standing on it with a clipboard.
|
||||
|
||||
Here is the part I am not proud of. These teams could see the wall coming. They were not always competent but they were not blind, and somewhere around hour two of a four-hour window a sensible engineer can do the arithmetic and work out that this is not going to land. So they would call. Sometimes hours before the window closed, they would try to pull an incident manager onto a bridge, to get help standing by for the moment it tipped over. And I would tell them no. Not yet. The window has not ended. This is your change and your mess, and I am not the cleanup squad for an afternoon of bad planning. Come back when it breaks.
|
||||
|
||||
I thought I was defending something. The integrity of the process. The principle that the incident channel was not a crutch for people who could not run a deployment. It felt like rigour. It felt like holding the line.
|
||||
|
||||
It was a boomerang, and I had thrown it myself. The second the clock struck the end of the window, the thing I had refused to look at became, by definition, an incident, and it landed on the side of my head with the full weight of however many hours I had spent insisting it was not my problem. Except now the team was exhausted, the change had been bleeding quietly into production for half the night, and the easy rollback we could have run at hour two was a tangled horror at hour five. I had not prevented anything. I had taken a recoverable situation, made everyone watch it deteriorate until a clock gave me permission, and then run the incident I could have got ahead of, slower and sicker and later than it ever needed to be.
|
||||
|
||||
That is the whole disease in one anecdote. Those teams planned like clowns, and they were still right about the one thing that mattered. They read the trajectory and called it before the impact. That is negative time to detect, delivered by the least disciplined people in the building, and I sent it back with a lecture about planning. I had been handed the exact response this entire essay is in praise of, and I refused it on principle, because the principle said you do not get to call it an incident until it has finished becoming one.
|
||||
|
||||
I was a clock bolted to the floor. I only counted up.
|
||||
|
||||
|
||||
|
||||
Here is the cruel arithmetic of doing this well. The better you are at it, the less it looks like you did anything at all. A fire put out before it spreads is indistinguishable, on the incident report, from a fire that was never going to spread. Stop the disaster early enough and you have not averted a catastrophe, you have merely had a quiet night, and quiet nights do not get budget, and they do not get thanks, and after enough of them somebody starts asking what they are paying you for. This is the prevention paradox, and it is the structural condition of the entire trade. The reward for being early is to be doubted.
|
||||
|
||||
The purest case the world has ever run was Y2K.
|
||||
|
||||
For most of the 1990s an enormous body of people went line by line through the planet’s ageing software, expanding two-digit years into four, because a great many systems built when memory was expensive had no way to tell 2000 apart from 1900. The bill ran to somewhere between three and six hundred billion dollars, depending on whose accounting you trust, with the better part of a decade of labour behind it. Then midnight came on the first of January, and the planes stayed in the sky, and the grids held, and the banks opened on Monday as if nothing had happened. Which, as far as anyone could see, it had not.
|
||||
|
||||
So the verdict came in fast and it came in cruel. Hoax. Hysteria. The greatest racket consultants ever ran. People who had not slept properly since 1997 read in the paper that they had spent six hundred billion dollars frightening themselves over a calendar. And the maddening part, the part that makes Y2K the perfect parable and not merely a sad one, is that the sceptics could not be cleanly proven wrong. A few countries spent almost nothing and rolled into the new century about as smoothly as the ones that had spent fortunes. There is no second Earth where nobody did the work, sitting in a lab so we can compare. A disaster that was prevented and a disaster that was never coming leave behind precisely the same evidence, which is to say none, and an absence will not testify on your behalf.
|
||||
|
||||
You do not need a calendar rolling over to see it. It happens in your pipeline every week. A change goes out to one percent of traffic, the error rate lifts its head, and a guardrail or a human paying attention rolls it back before it ever reaches the other ninety-nine. The blast radius is a rounding error. Nobody writes a postmortem for it, because there is no post and there was no mortem, and the engineer whose instinct caught it does not get an incident with their name on it the way they would have if they had let it burn and put it out heroically at three in the morning. We have built a discipline that pays out for the heroic recovery and stays silent on the quiet save, and then we wonder why people learn to wait for the fire.
|
||||
|
||||
If you want the shape of the thing in something heavier than software, put two volcanoes side by side.
|
||||
|
||||
In 1991 Mount Pinatubo in the Philippines woke up after five centuries. Volcanologists from the local institute and the United States Geological Survey watched it for weeks, read the seismographs and the gas, called the big eruption before it came, and moved more than sixty thousand people off the mountain. The eruption was one of the largest of the century. A few hundred died, most of them under roofs that gave way beneath wet ash. The forecast is reckoned to have saved somewhere between five and twenty thousand lives, and the whole monitoring effort cost under a million and a half dollars. Those saved thousands are not a figure you will find on any memorial, because saved lives do not gather in one place to be counted. They went home. The catastrophe is invisible precisely because it did not happen.
|
||||
|
||||
You want to know what it would have looked like if it had. Look six years earlier and a continent across.
|
||||
|
||||
In 1985 the Nevado del Ruiz volcano in Colombia gave every warning a mountain can give. Scientists had watched it for months. A hazard map went out in October marking the town of Armero, in the valley below, as sitting directly in the path of any mudflow the eruption would throw down. The map was correct in every particular. When the volcano erupted on the thirteenth of November, the authorities, weighing the cost of evacuating a profitable farming town against the embarrassment of a false alarm, decided to wait. A storm took out the communications that night. A priest reportedly told a frightened parishioner to enjoy the ash, it was a beautiful thing and she would never see its like again. The lahars reached Armero near midnight and buried it under five metres of mud moving at the speed of a car. The town held some twenty-nine thousand people. About twenty-three thousand of them died. The detection had worked perfectly. The response was the thing that was withheld.
|
||||
|
||||
That is what Pinatubo’s saved thousands would have looked like, laid out in a valley. Same class of event, same chain of cause, the detection achieved in both cases. The only variable that moved between a quiet evacuation and a buried town was whether anyone acted on the warning before the impact arrived.
|
||||
|
||||
And in case that reads as a fluke of two different mountains, the same mountain settled it. Four years after it buried Armero, Nevado del Ruiz stirred again, and this time the monitoring was watched and the evacuation was ordered and the valley was emptied. Nobody died. The hazard had not changed. The mountain was the mountain. The response was the variable, and when the response came before the impact, the death toll was a number the instruments record as nothing at all.
|
||||
|
||||
|
||||
|
||||
A volcano observatory is a serious place full of serious instruments, and you do not have one. What you have is a web form, and the web form does not merely fail to notice your best work. It deletes it on purpose, and it hands you the pen and makes you sign.
|
||||
|
||||
Here is how it goes. You have just done the good thing, the early thing. A change went sideways, somebody read the trajectory and called it, the rollback ran, and the failure was pulled back before a single customer felt a thing. The impact, in the only sense that matters, never happened. So you go to write it down, because writing it down is the job, and the tool asks you for the time the impact began and the time it ended, and you discover that the moment you were proudest of is a moment the form was built to reject.
|
||||
|
||||
Because the response landed before the impact, the end comes before the start. You enter what happened and the field turns red. End time cannot be before start time. The tool has rules, and the first rule, written by someone who never once imagined you might be early, is that nothing ends before it begins. So you sit there with the adrenaline still draining out of you, being told by a dialog box that the night did not happen the way you watched it happen. And you do the only thing the form will accept. You drag the start forward until it agrees with the end, the duration computes out to zero, and the form goes quiet and lets you save. You have been conscripted into falsifying your own timeline by a validation rule. The lie has two authors, and you are the one who pressed save.
|
||||
|
||||
Multiply that by a quarter. Every clean save the team made, every early call that worked, every fire smelled before it caught, each one filed as a zero, because zero is the only number the schema will hold. Then somebody senior opens the dashboard and finds a flat line along the bottom of the impact graph. Nothing to see. A quiet quarter, which from that altitude is never the good news it looks like. I have watched this land on people who deserved a great deal better: teams that pulled the cord while every dashboard still glowed green, that took a thing which would have cost the company a full day of broken payroll and turned it into a non-event by getting in front of it, and whose work arrived on the executive’s desk wearing the exact same face as no work at all. The context, the counterfactual, the cost they had quietly eaten so the business would not have to, was gone the instant the duration clamped to zero. The machine did it on everyone’s behalf and called it data hygiene.
|
||||
|
||||
Hand that machine a negative number, the one figure that says what actually happened, and it gives you back a zero and files it under routine. That is not a measurement failing to capture something. That is a measurement manufacturing the opposite of the truth, signing your name to it, and carrying it upstairs to the people who decide what you are worth.
|
||||
|
||||
|
||||
|
||||
You will want, by now, to fix the form.
|
||||
|
||||
It is the natural instinct of anyone who has read this far and works for a living. Find the validation rule. Let the field accept a negative number. Add a checkbox for responded before impact and a column for the counterfactual, ship it next sprint, and the problem is solved. And you should do it. It will take an afternoon, and it is worth the afternoon, and I am not going to stand here and tell you better tooling is a waste of time after five movements spent cursing a dialog box.
|
||||
|
||||
But the field was never the disease. The field is a symptom. It is where the disease shows on the skin, and the disease is the assumption: that you are, by your nature, late. That response is a thing which happens to you after the break, in the wreckage, by torchlight. The entire discipline is built on it. The metrics assume it, the tools enforce it, the war stories celebrate it, and somewhere a long way down, the people doing the work come to believe it about themselves. We have organised a whole profession around the conviction that its practitioners arrive second.
|
||||
|
||||
The negative number is heresy because it says otherwise. It says the response can come first. It says the best people in this trade are not the ones who run fastest toward a fire already burning, but the ones who can read a building and call it before there is any smoke to smell, and that those two things are not the same skill and never were. The recovery at three in the morning is cleanup. Skilled, necessary, the kind that saves the quarter and earns the bonus, but cleanup, and cleanup means there was already something to clean. The response that lands before the impact is the only version of the work that leaves nothing behind it, because it got there before the wreckage could be made. That is the summit. That is the whole of it.
|
||||
|
||||
So here is the verdict, and it is not a complaint about a form. Any instrument that reads zero when the work is at its best is not measuring the work badly. It is measuring the wrong thing. It is pointed at failure, and at the cleaning up of failure, and it is calling that reliability, and reliability is not the speed of your recovery. Reliability is the disaster that never arrived: the lanes that stayed empty, the town that went home, the quarter with nothing on the graph. We have built our rulers to measure the wreckage, named the absence of wreckage a quiet quarter, and gone looking for someone to blame for the quiet.
|
||||
|
||||
|
||||
|
||||
Which brings it back to the water.
|
||||
|
||||
The Dali was bearing down at eight knots in the dark and there was nothing anyone could do about the bridge. The bridge was already lost the moment the lights went out. What was not yet lost was everyone who would have been on it two minutes later, the ordinary traffic of a city that does not stop at one in the morning, and they are alive because a dispatcher with no time and no script said hold the cars, and the cars held. Six men still died, the ones already out on the deck, the ones the warning reached too late because they were standing on the impact before anyone knew it was coming. The pre-impact response is not a miracle. It does not always win, and it did not fully win that night.
|
||||
|
||||
But the lanes were empty. That is the evidence. That is what the most important work of that entire night looks like in the record it leaves behind: a stretch of empty road and a clock that ran backwards. Minus two minutes, the truest number anyone produced on the Patapsco that night, and the one number no system we have built will agree to write down. Learn to write it down. Until then we will keep measuring our people by the wreckage they leave, and paying our best ones in zeros, and wondering, from the calm of an empty graph, what exactly it is they do.
|
||||
|
||||
acceptance of the gap 🙏
|
||||
|
||||
I go through life the same way... You do sports, you don't drink, you don't smoke, you read the trouble early and thankfully mostly it works. The disasters don't arrive. The lanes stay empty. But the same wiring that keeps you ahead of the fire is the wiring that won't switch off, and the prize for a lifetime of prevention is that you become an anxious person who can't look at a quiet day without bracing for something. You get the empty graph. You just can't enjoy it 😭
|
||||
@@ -0,0 +1,59 @@
|
||||
# The on-call cost of AI-generated code
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/06/09/on-call-cost-of-ai-generated-code/
|
||||
|
||||
## 简介
|
||||
|
||||
> The key question is, when that new code breaks in production at 3am, how well can the on-call engineers debug it?
|
||||
|
||||
## 正文
|
||||
|
||||
If your engineers are using AI coding assistants, your team is almost certainly shipping more code than they were before adopting these tools. That’s not surprising: the whole point of these tools is to accelerate how fast code moves from idea to production. The velocity story is real, and it’s the story most companies focus on.
|
||||
|
||||
The key question is, when that new code breaks in production at 3am, how well can the on-call engineers debug it?
|
||||
|
||||
# The understanding gap
|
||||
|
||||
I’ve [written before](https://greatcircle.com/blog/2026/06/04/ai-ops-tools-ironies-of-automation/) about how AI tools are quietly thinning the understanding that teams have of their own systems. The short version: AI-assisted development shifts how code gets produced in ways that leave the team with shallower collective knowledge of the codebase. Not because anyone is doing something wrong. Good teams still do design reviews, still do code review, still write documentation.
|
||||
|
||||
But when AI generates code, the team reviews the output rather than participating in the implementation choices. The understanding they build is real, but it’s not as deep as what they’d have if they’d built it together. TR Jordan of Tern [captures the shift well](https://tern.sh/blog/stop-reading-prs/): the old deal was that if it was worth your time to write the code, it was worth my time to read it. When the code is AI-generated, there’s so much more code to review that the deal breaks down, and the knowledge-sharing that used to be baked into the process has to be rebuilt deliberately.
|
||||
|
||||
During normal operations, that’s fine. Teams have time to read through unfamiliar code, query the AI, run experiments, consult documentation. The pace is forgiving.
|
||||
|
||||
# When thinner understanding meets time pressure
|
||||
|
||||
The pager goes off at 3am, and within minutes the response becomes a team effort: the on-call engineer pulls in teammates, the incident tech lead drives the investigation, subject matter experts get paged. But the team’s effectiveness under pressure depends on their collective understanding of the systems and code involved. That understanding is exactly what’s gotten thinner as the code volume has increased and more of the codebase has been shaped by AI.
|
||||
|
||||
This doesn’t mean the team is helpless. They can still read the code, still query the AI about what it does, still use their debugging tools. But there’s a difference between understanding code well enough to work with it during the normal course of development and understanding it well enough to reason about its failure modes at 3am, under time pressure, with customers affected. The first is a comfortable margin. The second is where gaps in understanding become visible.
|
||||
|
||||
The more of the codebase that’s been shaped by AI, the more the incident response team is working in territory they know less deeply than they would have if they’d built it all themselves. Each individual piece of AI-generated code might be fine. But in aggregate, the team’s ratio of “code in production” to “code we understand deeply enough to debug under pressure” has shifted. And it’s shifted in the wrong direction for incident response.
|
||||
|
||||
# From valuable to essential
|
||||
|
||||
Firefighters deal with a version of this problem every time they respond to a fire in a building they’ve never been inside. They don’t know the floor plan, the hazards, or the building’s history. What they rely on instead are general diagnostic skills: understanding building types and construction methods, knowing how fire behaves, reading smoke conditions and other indicators. They’ve trained specifically for navigating the unfamiliar, because in their line of work, the unfamiliar is the norm. And they don’t just rely on those skills in the moment. Between calls, they prepare: conducting familiarization visits to buildings in their district, having informal “what if?” discussions over the kitchen table, running whiteboard sessions, reviewing and updating pre-incident plans. They build as much understanding as they can before the alarm sounds, knowing it won’t be complete but also knowing that every bit of preparation helps.
|
||||
|
||||
The [Google SRE book](https://sre.google/sre-book/accelerating-sre-on-call/) describes an analogous training approach for software engineers: building the general skill of dropping into an unfamiliar system under pressure. Using diagnostic tools and debugging surfaces. Following requests across service boundaries. Drawing inferences from logs and metrics. Making that process reflexive enough to work when the stakes are high and the clock is running.
|
||||
|
||||
That skill set has always been valuable, but AI-assisted development makes it essential. When a growing share of your production code was written or substantially shaped by AI, the ability to debug systems you didn’t build is no longer just a nice-to-have that distinguished your strongest engineers; it’s a core competency your entire on-call team needs.
|
||||
|
||||
Of course, this assumes you’ve invested in the infrastructure to support those skills: diagnostic tooling, distributed tracing, structured logging, debugging surfaces that actually reveal what’s happening across service boundaries. If your company is shipping more AI-generated code, the case for investing in observability infrastructure gets stronger, not weaker. The skills and the tooling go together.
|
||||
|
||||
# What this means for your company
|
||||
|
||||
If your company is adopting AI coding tools, the question isn’t whether the understanding gap exists. It’s whether your incident management practices account for it.
|
||||
|
||||
**Invest in general diagnostic skills.** Don’t just train engineers on specific systems; train them to navigate unfamiliar ones. Structured debugging exercises, shadowing across teams, and practice with diagnostic tooling all build the kind of transferable skill that matters most when the code is unfamiliar.
|
||||
|
||||
**Don’t assume familiarity will come from the work itself.** When teams hand-wrote most of their code, system understanding was a natural byproduct of the development process. AI-assisted development weakens that link. Companies need to explicitly invest in building the shared understanding that used to come for free. Some of that investment is formal: structured on-call ramp-up, cross-team shadowing, and light-weight training exercises. But some of it is informal, and just as important: engineers walking each other through recent changes, pairing on debugging sessions, having “what would we do if X broke?” conversations over lunch.
|
||||
|
||||
**Build understanding between incidents.** Firefighters build a lot of their knowledge around the kitchen table between calls. Software teams need the equivalent, and they need to protect the time for it. Dedicate a regular slot in your weekly team meetings for disaster role-playing or system walkthroughs. Google’s SRE teams have done this for years with a practice they call [“Wheel of Misfortune”](https://sre.google/sre-book/accelerating-sre-on-call/#xref_training_disaster-rpg). The key is, it’s not a big-deal formal exercise, it’s just how they spend the last ten minutes of a weekly meeting.
|
||||
|
||||
**Treat this as an organizational capability problem.** Adopting AI coding tools for velocity gains is an organizational decision. So is investing in the operational readiness to match. That’s not an argument against AI tools; it’s an argument for thinking about the full picture. Shipping more and faster is valuable. But the cost shows up at 3am, when code your team doesn’t fully understand breaks in production and the clock starts running.
|
||||
|
||||
*I’m writing a book on incident management for DevOps and SRE that covers this and much more. Sign up at [im4ds.com](https://im4ds.com) to be notified when it’s available.*
|
||||
|
||||
*If your company needs help preventing, preparing for, responding to, and learning from incidents, my consulting practice is [greatcircle.com/im](https://greatcircle.com/im).*
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,150 @@
|
||||
# Transforming How We Run Kafka at Honeycomb
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Josh Parsons — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/transforming-how-we-run-kafka-honeycomb
|
||||
|
||||
## 简介
|
||||
|
||||
This article focuses heavily on how Honeycomb built and tested a plan for what I can personally assure you must have been a very complex migration. I especially like how they drew lessons from their incident late last year.
|
||||
|
||||
## 正文
|
||||
|
||||
# Transforming How We Run Kafka at Honeycomb
|
||||
|
||||
We just completed a large-scale, multi-month Kafka migration project. We couldn't have done it without learning from past mistakes, prioritizing rollback safety, and building shared knowledge across the team through repeated migration practice.
|
||||
|
||||

|
||||
|
||||
By: [Josh Parsons](https://www.honeycomb.io/author/josh-parsons)
|
||||
|
||||
|
||||
|
||||
#### Production Is Where the Rigor Goes
|
||||
|
||||
In early February, Martin Fowler and the good folks at Thoughtworks sponsored a small, invite-only unconference in Deer Valley, Utah—birthplace of the Agile Manifesto—to talk about how software engineering is changing in the AI-native era. The longer I sit with this recap, the more troubled I am by what it doesn't say. I worry that the most respected minds in software are unintentionally replicating a serious blind spot that has haunted software engineering for decades: relegating production to the realm of bugs and incidents.
|
||||
|
||||
[Read Now](https://www.honeycomb.io/blog/production-is-where-the-rigor-goes)
|
||||
|
||||
|
||||
|
||||
We recently wrapped up a large-scale, multi-month Kafka migration project. We used to run self-hosted Confluent Platform and ZooKeeper as clusters of AWS EC2 instances, and now all of our Kafka clusters run open-source Apache Kafka 4.1.1 running in KRaft mode and deployed to AWS EKS.
|
||||
|
||||
There are insights and lessons within the story of how we did this migration that are worth sharing. In this blog post, I highlight key themes that set this project up for success: why committing to learning from and building on past incidents and experiences matter in projects like this, why it’s important to design any kind of Kafka migration with rollback and safety top of mind, and how our sociotechnical processes support Kafka migration execution in ways that build teams’ confidence.
|
||||
|
||||
*A note to our customers: this post describes work related to a [May 7, 2026, scheduled maintenance event](https://status.honeycomb.io/incidents/cn4kr4z29tp5) on our US instance. We missed the mark on timely, proactive communication to you about that event, and we sincerely apologize for the negative impact it had on you. We have a [separate post](https://www.honeycomb.io/blog/honeycomb-incident-report-kafka-maintenance-on-may-4-7-2026) detailing our response to the customer impact of the event, including how we will improve our processes to ensure we provide additional mitigations and support to prevent similar communication issues in the future. Because the engineering work to prepare for and execute this migration was extensive, we’ve chosen to address the external and internal aspects of this event in separate posts; the omission of the external perspective from this post is not intended to minimize the customer-facing impact.*
|
||||
|
||||
## Kafka’s purpose at Honeycomb
|
||||
|
||||
At Honeycomb, Kafka is the [beating heart](https://www.honeycomb.io/blog/scaling-kafka-observability-pipelines) of our observability data ingestion pipeline. It sits between customer observability data arriving at our edge and services like [Retriever](https://www.honeycomb.io/blog/virtualizing-storage-engine) writing that data to our columnar store, ready for customers to query in Honeycomb. Kafka has been a great fit for our needs because we have to move and process millions of observability events per second through our systems, and Kafka’s capabilities and guarantees afford us numerous critical benefits:
|
||||
|
||||
- Lets us decouple data ingestion from data processing in a way that allows us to update our core ingestion path services several times a day without causing downtime for our customers
|
||||
- Provides strong data buffering, reliability, and durability guarantees to ensure customer data isn’t lost when we accept it
|
||||
- Allows us to flexibly scale in order to meet growing ingest demand
|
||||
- Gives multiple consuming services the ability to read the same data stream independently, so all of our services can be in agreement about the data we’re receiving
|
||||
|
||||
# The second edition is here!
|
||||
|
||||
Grab your free copy of Observability Engineering
|
||||
|
||||
and learn the foundationals of observability
|
||||
|
||||
from the experts.
|
||||
|
||||
## Why we migrated
|
||||
|
||||
Prioritizing a large-scale Kafka migration requires substantial cross-team and cross-functional alignment. Asking for resources across multiple teams for a project that we knew would take several quarters to execute is not a thing that can be wished for and hoped into existence. We had to be very clear about the problems we were solving and why this project aligned with business objectives. So what were our reasons?
|
||||
|
||||
First, there were technical capabilities we had to be able to prove as engineering developed [Honeycomb Private Cloud](https://www.honeycomb.io/platform/private-cloud). Installations of Honeycomb Private Cloud require Kafka to be running on AWS EKS as part of its packaged deliverable. The way we had been running Kafka in our SaaS infrastructure would simply not have worked for Honeycomb Private Cloud installations. For long-term maintainability and sustainability of operating Kafka, we had to be able to run Kafka the same way and prove that running Kafka on Kubernetes would be able to handle production scales of traffic. Additionally, it has become increasingly more viable to deploy and run Kafka on Kubernetes in production-scale environments (we use [Strimzi](https://strimzi.io/) for the orchestration and management layer).
|
||||
|
||||
Second, migrating Kafka presented an opportunity to better align our current internal operational patterns and, in turn, sunset older legacy patterns that our administration of Kafka depended on. Our Honeycomb services are built and deployed to Kubernetes, and we determined that we could use a lot of those same patterns for Kafka.
|
||||
|
||||
Finally, migrating gave us a level of deep operational control and flexibility that we wanted. For example, we were finding that the time to recover from our weekly practice of replacing Kafka brokers was gradually getting worse. A couple of years ago, this took 8 to 12 hours in production, and before the migration started, this took 48 to 72 hours. The issue centered on Confluent Platform’s Tiered Storage functionality, a solution that we depended on, but also a closed-source one that gave us no means to fix issues directly without support from Confluent. Migrating to open-source Apache Kafka gave us more agency to fix issues like this if we ever encountered them.
|
||||
|
||||
## Functional requirements will constrain migration options
|
||||
|
||||
Deeply understanding the behavior of the services that depend on and interact with Kafka dictated our viable migration target options, as well as the means to execute the migration. One of the most impactful of these functional requirements came from Retriever, which consumes then writes the data coming out of Kafka into our columnar store. The way Retriever handles Kafka offset management precluded us from using common Kafka migration tooling options.
|
||||
|
||||
Retriever ingestion workers don’t commit their partition offsets back to Kafka, but instead maintain their offsets internally. Why is that? Because Retriever has strict semantic delivery requirements (it’s effectively the exactly-once semantic) and strict data guarantees it has to uphold; Retriever cannot consume a message it has already serialized and written to the columnar store. Precise offset tracking and management is critically important to us.
|
||||
|
||||
Additionally, as described in [Chapter 13 of Observability Engineering, Second Edition](https://www.honeycomb.io/observability-engineering-oreilly-book), Retriever uses parallel ingestion workers to consume a single Kafka partition: one consumer uploads finalized segments to the columnar store and the other consumer spot-checks that the resulting segment data produced is identical between the pair. We operate our system as not just exactly-once, but exactly-twice (across the pair). This design matters because Retriever checkpoints its Kafka partition offset to its local disk, and all ingestion workers will use these checkpoints when Retrievers need to be restarted due to a deployment or when a Retriever node instance is replaced. Retrievers can resume consuming from the checkpoint on the backup it restores from when it comes back online. In contrast, using a pair of consumer groups would result in divergent offsets being committed.
|
||||
|
||||
This dependence on internally managed and precise offset management meant that cross-cluster mirroring solutions like [Kafka’s MirrorMaker 2](https://cwiki.apache.org/confluence/display/KAFKA/KIP-382%3A+MirrorMaker+2.0) were not appropriate for our use case, because of its use of offset translation mechanisms. If we had used this to replicate messages between clusters, Retriever would not have been able to use its checkpoints to reliably retrieve the next messages from their respectively assigned partitions.
|
||||
|
||||
It’s important to pay close attention to your Kafka dependencies’ functional requirements, as they will constrain how you can execute your migrations.
|
||||
|
||||
## Non-functional requirements will constrain them too
|
||||
|
||||
We maintain a 99.99% ingest availability SLO and tune our systems to maintain very fast end-to-end ingest latencies. When you send an event into Honeycomb, we need to be available to accept it and you need to be able to query that event in Honeycomb within one minute. We are particularly sensitive to all sources of latencies throughout the ingestion path, including Kafka disk I/O latencies.
|
||||
|
||||
This means that we ruled out using some managed Kafka solutions that use [diskless topics](https://cwiki.apache.org/confluence/display/KAFKA/KIP-1150%3A+Diskless+Topics), like Confluent’s Warpstream, because we can’t trade higher latencies for more cost-effective data transfer and storage. We optimized our choices for the most performant, lowest latency storage solutions for fresh data. We determined that using an EKS instance’s NVMe instance store rather than high IOPS provisioned EBS volumes (like io2) guarantees the lowest possible read and write latencies. By choosing NVMe instance stores over EBS volumes, we accept another tradeoff: Broker replacement and data recovery will take longer when using NVMe instance stores because all of the buffered data has to be rematerialized from scratch. EBS volumes can be detached and reattached during replacement, speeding up this process, but incurring an ongoing cost in dollars and latency (there are no EBS savings plans).
|
||||
|
||||
Every implementation decision you make, like what storage approach to use for Kafka data, needs to be informed by your non-functional requirements. Any Kafka migration evaluation must factor all requirements, and they should constrain which options you can use. Making the right design choices early in the process will pay off when you need to design the safety mechanisms of migration execution.
|
||||
|
||||
## Build on institutional knowledge and wisdom
|
||||
|
||||
When I joined Honeycomb in January 2025, a wealth of history, knowledge, and wisdom were documented and left for me to leverage. I came with my own style and opinions on how we might achieve our goals, but it was vitally important to build on my predecessors’ wisdom. I prioritized understanding why we had designed Kafka the way we did to inform how I wanted to proceed. When I put together my proposal and evaluated the best options we had, I arrived at the same conclusions my predecessors did. This alignment gave me the confidence that I was thinking about the problem space and the potential solutions correctly.
|
||||
|
||||
Making the effort to find documented knowledge and history will help inform your decisions when you’re considering a Kafka migration of your own.
|
||||
|
||||
## Applying lessons from incidents pays dividends
|
||||
|
||||
Before we started our migration work, in December 2025, we had [a major incident](https://www.honeycomb.io/blog/incident-report-exercises-cleanups-and-evacuations) that affected one of our production Kafka clusters. This was a stressful incident for many of us, which required completely evacuating the Confluent Platform Kafka cluster that we were on. I paid close attention to the mechanics of the emergency evacuation, because if you look at it from the right perspective, evacuation kind of looks like steady-state migration, but under time pressure and duress.
|
||||
|
||||
I was part of the incident response team for that incident, and I participated in the subsequent incident review and public report. We learned something new about our architecture through the incident that we had speculated might be true, but had never actually tried to do. Retriever could reset its checkpointed partition offsets to zero, and then be pointed at a new Kafka cluster. Retriever would then resume reading messages from the beginning of the partition on the new cluster. We could do this deterministically and dynamically via a feature flag, without dropping data or losing data continuity.
|
||||
|
||||
Why was this finding meaningful? The experience of the incident opened up a Kafka migration path that we thought we could not do, but because of the outcome of the incident, we learned this was actually a viable path for us to consider. We could execute a coordinated sequence of cutovers without dropping any customer data while maintaining full data continuity.
|
||||
|
||||
This pathway was made possible because of the lessons we learned from the incident. Learning from your past incidents is vital because if you are able to learn from them, you can build on those lessons in your migration designs and turn a stressful process into a more robust, safe, repeatable set of procedures.
|
||||
|
||||
## Seizing the opportunity to level everyone up
|
||||
|
||||
Running Kafka ourselves meant confronting all of the implications of vendor independence with Kafka. Deciding to do the migration meant we were accepting terms of operational responsibility. We had to make sure that the teams who would be interacting with and operating Kafka would have the right resources to do that. The knowledge and expertise had to be set up to scale; these things could not just live in my head.
|
||||
|
||||
It was just as important to execute the migrations as it was to create the bridges of scalable knowledge between the old and new ways of operating Kafka. It was an opportunity to build something internally with broad value: a pedagogical library resource within internal documentation that would teach Honeycomb bees about the fundamentals of Kafka, how Kafka fits into our architecture, and how to operate and interact with our new Kafka clusters. Committing to building out a reliable foundation of knowledge benefits everyone, whether they are brand new to Kafka or they are joining an on-call rotation that will be on the hook to operate Kafka. You don’t want to be left in a position where you’re scrambling to hire to fill a knowledge or expertise gap if you can help it.
|
||||
|
||||
## Prioritizing rollback procedures
|
||||
|
||||
The functional and non-functional requirements that constrained our options combined with the lessons of the Kafka incident in December directed us to make sure that our migrations’ safety guardrails and rollback scenarios were robust. We pushed some of our earlier migrations out to ensure we got the safety guardrails and rollback steps right. The stakes were too high, and we could not find ourselves caught flatfooted if we had to stop and reverse course during a botched production migration. If we had to make a decision to roll back because something went sideways, we were going to be prepared.
|
||||
|
||||
We run one Kafka cluster in each of our environments, consisting of three tiers of environments in two different regions: Kibble, the lowest environment; Dogfood, the next tier up; and finally the Prod clusters—six clusters in total. We exercised our rollback design in one of our Kibble [environments](https://www.honeycomb.io/blog/kubernetes-migration#:~:text=We%20needed%20an,Kubernetes-shaped%20service.). We migrated it fully forward, then fully backward, then partially forward and backward with our rollback procedures, then finally, fully forward a second time. When we explicitly migrated backwards to prepare for the rollback test, that procedure took over four hours.
|
||||
|
||||
Kafka migrations like these are big time and resource commitments, but dedicating time to the practice of migration execution was crucially important to us to ensure we got the processes nailed down as much as possible. This was another commitment we had made to learn directly from our migration experiences and use that as a feedback loop back into our migration processes.
|
||||
|
||||
## The practice of execution reduces uncertainty and creates learning opportunities
|
||||
|
||||
The original template of our migration procedure came directly from the emergency evacuation runbook we created during the December Kafka incident, which laid out the multi-team choreography and process of the evacuation itself. We followed the procedure and recorded the experience of every migration we did in a multi-tab document. For each migration—whether Kibbles, Dogfoods, or Prod clusters—we had a corresponding “What did we learn?” tab in the document. Whenever we encountered something new or weird during the migration, we added a bullet point to that tab in real time. We reviewed what we learned a day or two after each migration, and we used those lessons to refine the template for the next migration. This refinement feedback loop allowed us to do some really crucial things that greatly reduced the process’s uncertainty and created strong learning opportunities for us as we executed each one.
|
||||
|
||||
First, we defined very clear roles and responsibilities, and we optimized how our team coordinated execution. Running a migration resembled running an incident: We coordinated in real time on Zoom; we had a migration lead and a communication lead; and we assigned key runbook responsibilities to other people. But early migrations were also massive, multi-team efforts. The original migration required coordination across seven teams. Because we had multiple migrations to do, we didn’t want all seven teams to have to be present for every migration. So over time, our team practiced and gradually took ownership of running other teams’ runbooks for later migrations. Eventually, our team was the only team required to run the migration. We built our confidence by having each person on our team rotate what they did each time. All of us got firsthand experience running every critical piece of a complex and choreographed process.
|
||||
|
||||
Secondly, it created opportunities to surface confusing or ambiguous things or invalid assumptions about the procedure. We gained valuable experience documenting these things, and we refined our processes well enough to take our migration executions from four to five hours down to executions of two to three hours.
|
||||
|
||||
Finally, it allowed us to identify and define what telemetry we needed out of Kafka and Kubernetes to make sure we could explore how Kafka was behaving in real time. We created and deployed a telemetry pipeline consisting of OpenTelemetry Collectors deployed to the EKS clusters running Kafka, which scraped Prometheus JMX metrics, extracted information through the Kafka Admin API, and gathered Kubernetes node metrics and events. We sent all of that directly to Honeycomb. We built out tactical Honeycomb Boards that centered on key signals we needed to verify during the migration. We used these visualizations as checkpoints to continue or pause if something didn’t look right.
|
||||
|
||||
All of us gained confidence along the way, and none of us had to play hero when we had to troubleshoot things. We saw no clearer evidence of the growth of our team’s confidence and expertise when the team executed a full Kafka migration while I was on PTO.
|
||||
|
||||
## My team saw their growth for themselves
|
||||
|
||||
I took a few days off a week before we did the production migrations. We had one remaining non-production migration to do. I considered pushing my PTO back to be there for the migration just as I had for all of the others, but my manager pushed back against this temptation and made me remember 1) I should prioritize my own care and 2) having the team do the last non-production migration without me in the room was a perfect opportunity for the team to see for themselves how far they had come.
|
||||
|
||||
Before this project, I was the de facto “Kafka expert” on the team. Throughout the course of the project, I had seen my team grow in confidence, in knowledge, and in comfort by virtue of them being directly involved with each migration’s design and execution. I am still there and available to answer deep Kafka questions, but the rest of my team can meaningfully do this too.
|
||||
|
||||
I arranged for the team to execute the last non-production migration while I was on PTO. I had every confidence they could do this migration without me there. Do you want to know how that migration went? They executed it flawlessly, with no emergent issues to troubleshoot whatsoever, and they set a record for the fastest turn-up. I was so immensely proud of the team for achieving that. It gave us the confidence that we were going to succeed when we executed the production migrations.
|
||||
|
||||
## The full impact of generalizing migration procedures
|
||||
|
||||
Designing the migration processes for repeatability and generalizability were both important components of this migration. We now have the ability to use our migration procedure in the future for any number of migration modalities: self-hosted to managed, EKS-to-EKS cluster, evacuation and disaster recovery, etc. The overarching simplicity of the designs that make them generalizable come with some important tradeoffs worth weighing. We accept some reductions in consume availability for that conceptual simplicity, and that’s a deliberate choice because it is informed by what our services and systems tolerate.
|
||||
|
||||
I said earlier that we uncovered a new migration pathway during the December Kafka incident. Refining that evacuation procedure made under duress took a lot of time and effort to guarantee data safety and continuity for future migrations. The shape of the process’s design was dictated by what our services and systems could tolerate, and in our case, that meant the tolerances of services dependent on offset preservation. By cutting over the producers first, letting the consumers finish reading from the old cluster, followed by cutting over the consumers and resetting their checkpointed offsets, we end up creating a window of downtime between the producer cutover and the consumer cutover. We haven’t interrupted produce requests or lost any of our customers’ data, but fresh data won’t be seen by the consumers during that window and, in turn, customers will see that gap.
|
||||
|
||||
Guaranteeing data safety and continuity as well as accepting a window of downtime to achieve that has a material effect on what success looks like. A migration procedure that has been mechanically executed well does not guarantee a successful migration sociotechnically. As we mentioned at the beginning, how effective we are in communicating scope of impact and expectations to our colleagues and customers matters just as much as smooth mechanical execution. Succeeding in one does not guarantee success in other areas of impact.
|
||||
|
||||
Your mixture of sociotechnical system tolerances combined with what tradeoffs you’re willing to accept will likely differ. Projects of this scale need to account for as many of these impacts as possible.
|
||||
|
||||
## You can do difficult things
|
||||
|
||||
Learning from your experiences, both historical and present, is essential to build on when you undertake a project of this magnitude. If Kafka is as vitally important to your architecture as it is ours, you have to build in rollback and safety, and you have to explicitly exercise those procedures to help your migration teams gain the required confidence when you have to adapt and respond to unforeseen situations.
|
||||
|
||||
If the Kafka knowledge of your organization lives in one or two people’s heads, Kafka migration projects are a great opportunity to start to build those foundations of learning that need to scale to others. Your teams need the agency and the confidence that wisdom, knowledge, and experience will give them. Find and build on those sources if you need to undertake something like this.
|
||||
|
||||
Success is not guaranteed, and your circumstances and experiences will vary from ours. But one thing I can say is that we can still do difficult things, and you can too. Kafka can be intimidating to dig into because it often serves as the beating heart of critical data streams. But if you are thoughtful about your migration designs, and your team is eager to learn and participate, you can bring them along and show them that they can do this.
|
||||
189
sreweekly/markdown/527/04-making-768-servers-look-like-1.md
Normal file
189
sreweekly/markdown/527/04-making-768-servers-look-like-1.md
Normal file
@@ -0,0 +1,189 @@
|
||||
# Making 768 servers look like 1
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Ben Dicken — PlanetScaleThis article is published by this issue’s sponsor, but their sponsorship did not influence its inclusion in the newsletter.
|
||||
- **链接**: https://planetscale.com/blog/making-768-servers-look-like-1
|
||||
|
||||
## 简介
|
||||
|
||||
An in-depth introduction to sharding in PostgreSQL. Sure, you probably know all about sharding, but I definitely learned some interesting bits from this one even so.
|
||||
|
||||
## 正文
|
||||
|
||||
This is 768 servers.
|
||||
|
||||
To some, that looks like a lot of computers. To those managing the infrastructure for apps with millions of customers, executing millions of queries per second, pretty normal. Products at this scale frequently require thousands of servers working in unison.
|
||||
|
||||
The most difficult infrastructure component to scale is almost always the database. A single database server cannot handle such demand, so we must spread the queries and data out across many servers with database sharding.
|
||||
|
||||
Database sharding is the best way to scale a Postgres or MySQL database for anything beyond a few terabytes of data. Let's look at how we go from a small single-node database, to one with a few terabytes spread across four shards, all the way up to one that is sharded across 768 servers and storing a petabyte of data.
|
||||
|
||||
## [Growing pains](https://planetscale.com#growing-pains)
|
||||
|
||||
To understand why sharding is a necessary part of scaling relational databases, we must understand the bottlenecks of less scalable approaches.
|
||||
|
||||
Consider first a simple application architecture.
|
||||
|
||||
Most applications you've ever used function in this way, or at least did early in their existence. The software running on a client device connects to an app server over the internet. This app server lives in a data center and handles authentication, page loads, and all the server-side logic for how your application behaves. All the persisted data like user accounts, posts, settings, and messages get stored in and retrieved from the database server (where "database server" is typically Postgres or MySQL, though the focus of this article is Postgres).
|
||||
|
||||
Even with a large database servers (10s of CPU cores, 100s of gigabytes of RAM) bottlenecks arise pretty quickly. Typically, it is either CPU constraints due to high query volume, or I/O constraints (IOPS) due to a high volume of reads and writes.
|
||||
|
||||
This is summed up nicely by the Universal Scalability Law:
|
||||
|
||||
In short, the USL states that resource *contention* causes scalability to grow sub-linearly with increasing resources, and at a certain point, *incoherence* causes performance degradation. This is true for Postgres, as with any software system attempting to scale out across many threads or processes on a larger server.
|
||||
|
||||
One way to solve this, at least in the short term, is leveraging read-replicas.
|
||||
|
||||
In this configuration, you maintain the original server as a *primary* and add additional *replicas* as shown above.
|
||||
|
||||
The primary sends a continuous stream of messages to every replica to ensure they stay up-to-date with the data changes on the primary. Writes (`INSERT`, `UPDATE`, `DELETE`) can only go to the primary. If writes were allowed to any server, we could end up with conflicting data. Solving this requires complex and slow consensus algorithms, which is possible, but in most cases not ideal for optimal performance.
|
||||
|
||||
However, app servers can send read (`SELECT`) queries to the replicas. Since most apps have a much higher percent of reads compared to writes, this provides a lot more scalability. (Replicas are also necessary for high availability and data durability, even if query traffic does not require them).
|
||||
|
||||
The database can scale to handle more traffic by adding replicas. An extreme example of this is [OpenAI's use of 50 replicas on a single Primary](https://openai.com/index/scaling-postgresql/).
|
||||
|
||||
It turns out, scaling servers vertically (increasing CPU / RAM) and adding replicas can only take you so far. There are several bottlenecks that cannot be solved in this way
|
||||
|
||||
### [1) Writes limited to one server](https://planetscale.com#1-writes-limited-to-one-server)
|
||||
|
||||
With high enough write volume, no amount of additional read-only replicas will alleviate an issue. Before Postgres can acknowledge a committed write, it must record the change in its write-ahead log (WAL) and flush that log to durable storage. The WAL is a shared resource amongst all connections on the primary. This is essentially a single write bottleneck across your entire database, even if you have tens of replicas.
|
||||
|
||||
### [2) Replicas do not increase data capacity](https://planetscale.com#2-replicas-do-not-increase-data-capacity)
|
||||
|
||||
A replica is a full copy of the primary's data, including all indexes. Adding replicas gives us more places to run reads, but it does not distribute the data.
|
||||
|
||||
### [3) Backups](https://planetscale.com#3-backups)
|
||||
|
||||
Backups are an important part of data durability and RPO / RTO guarantees. Taking a backup of a large, monolithic database to object storage can take hours or even days due to the bandwidth limitations of node-to-storage communication. This is unacceptably long for many organizations that rely on frequent and validated backups.
|
||||
|
||||
The most proven way to handle this is sharding.
|
||||
|
||||
## [Sharding, with a "d"](https://planetscale.com#sharding-with-a-d)
|
||||
|
||||
Sharding solves these three bottlenecks by distributing the data and queries across many distinct primaries. For data, it is useful because a single node can only store so much and is limited on write throughput. For queries, this is useful because the network interconnects and CPUs can only process so many queries at a time.
|
||||
|
||||
Sharding is useful at all scales past a few terabytes of data. For example, with 2 terabytes of data, we may choose a setup with four shards, each storing 500 gigabytes and handling 1/4th of the total query traffic. When we needed to store a petabyte of data (one million gigabytes), we'd need many more shards. In this case, we can use 256 shards, each with a primary + 2 replicas, and each responsible for storing ~4 terabytes. This requires 256 * 3 = 768 servers!
|
||||
|
||||
Without a good system in place, this adds significant complexity to our app's backend. With so much going on, how does the system...
|
||||
|
||||
- Decide which data goes to which server?
|
||||
- Decide which queries go to which server?
|
||||
- Handle queries that need to talk to multiple shards simultaneously?
|
||||
- Take backups across this spread-out database?
|
||||
- Monitor system-wide health?
|
||||
- Respond to a failing server?
|
||||
|
||||
There's a lot that could be said in addressing each one of those concerns. But the question to address here in this article is the following:
|
||||
|
||||
How can these 768 servers look like 1 cohesive database to our apps?
|
||||
|
||||
We want to allow the application servers to go from interacting with a complex system, like this:
|
||||
|
||||
To instead interacting with it over a single connection string, making it appear as if it's interfacing with one large, scalable database:
|
||||
|
||||
While in reality, utilizing tens or hundreds of shards. [Neki](https://planetscale.com/neki) for Postgres and [Vitess](https://vitess.io) for MySQL solve this. Let's see how.
|
||||
|
||||
## [The proxy layer](https://planetscale.com#the-proxy-layer)
|
||||
|
||||
The most important amongst several critical pieces here is the proxy layer.
|
||||
|
||||
Proxies are middleware servers that sit between two services. In our case, these two services are the application servers and database servers.
|
||||
|
||||
Proxies are frequently used with Postgres databases. Even when there's no sharding, they are useful for connection pooling and request queuing. For regular (unsharded) Postgres, PgBouncer is a popular proxy that people use to multiplex 1000s of app connections across fewer direct Postgres connections.
|
||||
|
||||
PgBouncer has a simple goal. It's built to accept a large number of connections from many clients and route them through a smaller pool of connections that it continually maintains with Postgres. The query queuing is useful for traffic surges and during database failover, so requests can resume when the new primary comes online. We have a whole [blog on PgBouncer](https://planetscale.com/blog/scaling-postgres-connections-with-pgbouncer) if you want to learn more.
|
||||
|
||||
Sharding Postgres requires an even more sophisticated proxy. The biggest difference is that, in addition to multiplexing and buffering, the proxy must understand how data is distributed across servers and route SQL queries to the correct shards. Because of this, we refer to it as a *router*.
|
||||
|
||||
When inserting data, the router must be aware of how data is to be distributed. This is known as the [sharding strategy](https://planetscale.com/blog/database-sharding#sharding-strategy).
|
||||
|
||||
A common approach is to shard incoming rows based on a hash of an id column. When inserting row like this into the database:
|
||||
|
||||
```
|
||||
INSERT INTO users (id, username, email) VALUES
|
||||
(1, 'ada', 'ada@example.com'),
|
||||
(2, 'grace', 'grace@example.com'),
|
||||
(3, 'linus', 'linus@example.com'),
|
||||
(4, 'margaret', 'margaret@example.com'),
|
||||
(5, 'dennis', 'dennis@example.com'),
|
||||
(6, 'barbara', 'barbara@example.com'),
|
||||
(7, 'donald', 'donald@example.com'),
|
||||
(8, 'james', 'james@example.com');
|
||||
```
|
||||
Each of the four shards is assigned a range of IDs that it's responsible for storing, and the router sends the inserts to the correct shard. The insertions first get sent to the router, where it computes a hash of each ID, then forwards it along to the correct shard.
|
||||
|
||||
When it comes to reads, some queries are simple enough such that the router passes them along to a single shard.
|
||||
|
||||
```
|
||||
SELECT email from user where id = 4;
|
||||
```
|
||||
In this case, all the router needs to do is have an internal mapping of which user IDs live in which servers, and forward that query on. Based on the example above, this would be the first (top) shard.
|
||||
|
||||
Some cases are more complex.
|
||||
|
||||
```
|
||||
SELECT email FROM user
|
||||
WHERE id BETWEEN 3 AND 5;
|
||||
```
|
||||
Users with this range of IDs are spread out across several shards. The router must understand the data topology, create a plan for distributing the query to all shards that may contain matching results, aggregate the results back at the router, and send the full result set to the client.
|
||||
|
||||
Ultimately, this means the router itself must have a full query parser and routing planner built in.
|
||||
|
||||
The router must be able to perform query parsing, planning, connection pooling, and buffering, all within a single system. Complex software is hard to get right.
|
||||
|
||||
## [How does it know?](https://planetscale.com#how-does-it-know)
|
||||
|
||||
Every database is unique, with its own schema, tables, and query patterns. How then can a router generically know which data, and which queries, go where?
|
||||
|
||||
In both [Neki](https://planetscale.com/neki) and [Vitess](https://vitess.io/docs/reference/features/vschema/), these are specified via JSON files representing the data topology of the system. Vitess' VSchema and Neki's data topology give engineers a ton of flexibility to describe precisely how tables and queries should be distributed. Below is a simplified example of how we would specify a sharding scheme for a `user` table:
|
||||
|
||||
```
|
||||
{
|
||||
"shard_indexes": {
|
||||
"user_hash": {
|
||||
"type": "hash"
|
||||
}
|
||||
},
|
||||
"tables": {
|
||||
"user": {
|
||||
"shard_by": "user_hash",
|
||||
"column": "id"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
This metadata is stored in the router, and tells it that the `user` table is sharded on its `id` column using the `user_hash` shard index. This `user_hash` shard index uses the router's built-in value hashing. For each incoming row, it hashed the ID, and uses this to send it to the correct shard to be stored.
|
||||
|
||||
Since this is all communicated to the router via text and JSON, AI agents are great for configuration and optimization here.
|
||||
|
||||
## [Many proxies, one database](https://planetscale.com#many-proxies-one-database)
|
||||
|
||||
At a scale of 256 shards spanning 768 servers and millions of queries per second, we cannot route all of this traffic through a single proxy. We need many! Perhaps 10, perhaps 100, depending on the shape of the traffic.
|
||||
|
||||
We'd still like our apps to think of this as a single server. This is where a Network Load Balancer (NLB) helps.
|
||||
|
||||
NLBs have a simple job: Allow connections via a single host/IP, and assign each connection to one of many destinations. This is how traffic is distributed across the routers. Once assigned, a connection remains with the same proxy for its lifetime.
|
||||
|
||||
In some cases, an NLB is not necessary. Eliminating an NLB adds slightly more complexity to the app server's connection logic, as it will have to be aware of each router's host, but eliminates a network hop, keeping round-trip latency to a minimum.
|
||||
|
||||
## [The full picture](https://planetscale.com#the-full-picture)
|
||||
|
||||
Now all the pieces are in place to make 768 servers storing 1,000 terabytes of data appear as a single, monolithic database to our apps.
|
||||
|
||||
1. An app server is told "connect to the database at `mydb.pscale.com` "
|
||||
2. A DNS lookup is performed, returning the NLB's IP address: `123.152.100.4`
|
||||
3. The app requests to connect to the database at `123.152.100.4`
|
||||
4. This routes the connection first through the NLB, then to one of the N proxies
|
||||
5. The app begins sending database queries, which go app -> NLB (optional) -> proxy -> shards. The complex routing logic is hidden from the application. (NLB not pictured below, for simplicity)
|
||||
|
||||
This example shows scaling up to 1 petabyte, but sharding should begin long before this scale. The precise recommendations depend on each database's size, schema, and QPS, but we recommend sharding Postgres and MySQL for anything beyond a few terabytes of data. That's the point where you typically begin hitting the bottlenecks described earlier: long backups, write bottlenecks, etc. If you are facing challenges scaling relational databases, Neki and Vitess are the solutions.
|
||||
|
||||
[Vitess](https://planetscale.com/vitess) for MySQL has been used for over a decade to scale the world's biggest relational databases. We have years of experience operating large, sharded databases for our customers, and are the core maintainers of the Vitess project. [Neki](https://planetscale.com/neki) was developed by the same expert maintainers of Vitess, bringing an even more powerful sharding system to Postgres.
|
||||
|
||||
## [What about everything else?](https://planetscale.com#what-about-everything-else)
|
||||
|
||||
We've only scratched the surface of everything sharding systems like Neki and Vitess provide. There are so many other interesting details. What's the best way to shard data? How do sharded databases handle failures? How do you change the number of shards? How do you take backups across 256 shards at the same time?
|
||||
|
||||
Stay tuned for more here. Follow our [RSS feed](https://planetscale.com/blog/feed.atom) or on [X](https://x.com/planetscale) to stay in the loop.
|
||||
|
||||
Happy sharding.
|
||||
@@ -0,0 +1,85 @@
|
||||
# The cost of saying yes has changed
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Dalia Abuadas — GitHub
|
||||
- **链接**: https://github.blog/engineering/the-cost-of-saying-yes-has-changed/
|
||||
|
||||
## 简介
|
||||
|
||||
I started out ready to hate this one, but by the end, I came around; there’s a lot to think about. It’s about how coding agents change the economics of saying no or yes to taking on projects.
|
||||
|
||||
> Cheap to write is not the same as cheap to own
|
||||
|
||||
## 正文
|
||||
|
||||
###
|
||||
[Dalia Abuadas](https://github.blog/author/dmabuada/)
|
||||
|
||||
|
||||
|
||||
|
||||
Dalia is a software engineer on GitHub's Copilot Agent Control Plane team, building the subagent governance layer for Copilot customers.
|
||||
|
||||
The cost of writing code dropped; the cost of owning it didn’t. A framework for deciding which changes are actually cheap in the AI era.
|
||||
|
||||
|
|
||||
|
||||
6 minutes
|
||||
|
||||
|
||||
The most expensive part of a small feature request used to be writing the code. Now it’s usually the meeting about whether or not to write the code.
|
||||
|
||||
That’s a real shift, and it quietly breaks a lot of engineering instincts. Engineers learn early that most “small asks” aren’t small: they need tests, a rollout plan, someone to think through the edge cases and own the behavior after it ships. A two-hour change can become a two-week distraction if it touches the wrong part of the system. So we push back. Is this really needed? Does it belong in this release? Does it change a contract we already agreed to? I’m not giving that instinct up.
|
||||
|
||||
But it rests on an assumption that’s quietly breaking, which is that writing the first version of the code is the expensive step. For a specific class of change, it no longer is. If you can tell those changes apart from the rest, you can replace “is this in scope?” with a question you can answer in thirty minutes instead of a two-day debate.
|
||||
|
||||
Here’s a pattern I keep seeing. Someone asks for a small change such as surfacing a `last_active_at` timestamp that already exists in the backend on a settings page. The team spends forty minutes in a thread. One person says it sounds risky. Someone remembers a related migration from two years ago. Someone mentions the deadline. Eventually we land on “probably a day or two, could be more,” with low confidence, primarily because nobody has actually tried it.
|
||||
|
||||
That process made sense when trying was the expensive part. You had to stop what you were doing, load the context into your head, make the change by hand, write the tests, then discover the second- and third-order consequences. When the first attempt is cheap, defending the boundary can cost more than crossing it.
|
||||
|
||||
An agent can produce that first patch in the time the thread takes to warm up. It’s not free and definitely not automatically correct. But it is cheap enough that the smart move is often to stop guessing and look at a real diff.
|
||||
|
||||
The mistake is to treat the generated patch as the deliverable. It isn’t. It’s a probe. It turns an abstract scope argument into a concrete artifact you can interrogate:
|
||||
|
||||
- Does it touch the files you expected, or does it sprawl across five packages?
|
||||
- Are the tests obvious, or does the change resist being tested?
|
||||
- Does it preserve the existing abstractions?
|
||||
- Does it quietly require a new product decision?
|
||||
- Would you be comfortable owning this behavior six months from now?
|
||||
|
||||
Those are better questions than “does this feel like scope creep?” because now you’re arguing from evidence instead of vibes. If the `last_active_at` field comes back as a four-line diff with a passing test, ship it. The debate was the expensive part. However, if that same request comes back touching the auth middleware, you’ve learned the request was never small. Not only that, you learned this in thirty minutes instead of two days.
|
||||
|
||||
This is not letting the AI decide. It’s using the AI to make human judgment cheaper and better-informed.
|
||||
|
||||
Here’s the trap, and it’s the most important distinction of the AI era. A **change is not cheap just because the code was cheap to generate. It’s cheap only if a human can confidently review and own the result.**
|
||||
|
||||
A thousand-line diff that technically passes but nobody wants to own is not a cheap change. It’s a deferred cost. So the dividing line in that case isn’t “can an agent write this?” It’s “can a person validate it?”
|
||||
|
||||
- Adding a display field that already exists in the backend is usually cheap.
|
||||
- Changing authorization behavior is not cheap, no matter how clean the diff.
|
||||
- Refactoring a well-tested helper is usually cheap.
|
||||
- Changing data-retention semantics is not cheap.
|
||||
|
||||
Plenty of changes still deserve a hard no even when the code is trivial. This includes anything that moves the product contract, creates a support burden, or touches privacy, billing, or compliance. AI lowers the cost of *producing* a candidate. It does nothing to lower the cost of *owning* one.
|
||||
|
||||
Traditionally, scope discipline happened before implementation, because implementation was the expensive thing to protect. Now some of that discipline can move to review. That doesn’t mean skipping planning. It means being precise about which planning actually pays off.
|
||||
|
||||
Before relitigating a small change, ask for a constrained attempt. The constraints are the whole point.
|
||||
|
||||
Produce the smallest possible patch. Keep it behind the existing feature flag. Don’t change the public contract. Add or update tests. List every file you touched and call out anything risky.
|
||||
|
||||
If the agent can’t produce a clean patch under those constraints, the request was bigger than you thought, and you know it carries a real ownership cost before anyone commits to it. If it can, that tells you something too. Either way you’ve replaced “is this in scope?” with “here’s what it costs. Do we want to pay it?”
|
||||
|
||||
The best engineers in an AI-assisted world won’t be the ones who say yes to everything, and they won’t be the ones who reflexively say no. They’ll be the ones who can price uncertainty fast. They’ll know when a request is a product decision wearing an implementation costume, when review will be harder than writing, and when a change is small enough that the fastest responsible answer is to just try it.
|
||||
|
||||
That last one is genuinely new. “Try it and see” used to mean pulling a developer off other work. Now, for the right kind of task, it means handing an agent a bounded assignment and using the result to make a better call. Less time guessing, more time supervising. Less time treating implementation as a black box, more time evaluating concrete artifacts.
|
||||
|
||||
Scope creep is still real. But “no, because any new code is too expensive” is a much weaker argument than it was two years ago. The cost of producing code has dropped. The cost of understanding, reviewing, and owning it didn’t. So the question worth asking shifted from “is this more work?” to “where’s the real cost?” And sometimes, for a small, bounded change, the real cost is just finding out.
|
||||
|
||||
The cost of saying yes has changed. The cost of saying no should change with it.
|
||||
|
||||
Why shorter outputs can cost more, and how GitHub Copilot reduces wasted work across the complete coding task.
|
||||
|
||||
We built a plugin for the GitHub Accessibility Scanner to make sure your alt text is actually accessible. Here’s how it works.
|
||||
|
||||
Developers are owning more of the delivery system around code, not just code itself. Join us during GitHub Universe to meet other devs, learn something new, and explore what’s next.
|
||||
@@ -0,0 +1,28 @@
|
||||
# It WOULDN’T Let Them Pull UP!!? | The Strange Story Of Lufthansa Flight 1829
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Mentour Pilot
|
||||
- **链接**: https://www.youtube.com/watch?v=HpJM0_4PQaM&t=2797
|
||||
|
||||
## 简介
|
||||
|
||||
In this commercial airliner near miss, a system designed for reliability (alpha floor protection) was the cause of an incident (uncommanded pitch down), giving an excellent case study in automation.
|
||||
|
||||
> Do we know when it works, how it works, how to get the most out of it, and how to find a way around it if it turns against us?
|
||||
|
||||
## 正文
|
||||
|
||||
About
|
||||
Press
|
||||
Copyright
|
||||
Contact us
|
||||
Creators
|
||||
Advertise
|
||||
Developers
|
||||
Terms
|
||||
Privacy
|
||||
Policy & Safety
|
||||
How YouTube works
|
||||
Test new features
|
||||
NFL Sunday Ticket
|
||||
© 2026 Google LLC
|
||||
@@ -0,0 +1,166 @@
|
||||
# When the Message Broker Becomes the Bottleneck: Scaling Push and SMS With MongoDB Polling
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Pavel Zavialov — DevOps.com
|
||||
- **链接**: https://devops.com/when-the-message-broker-becomes-the-bottleneck-scaling-push-and-sms-with-mongodb-polling/
|
||||
|
||||
## 简介
|
||||
|
||||
Conventional wisdom says a database makes a bad queue and you should reach for a real broker but these folks went the other direction, tearing out RabbitMQ in favor of polling MongoDB. They included a section at the end of everything they had to build themselves to make polling work.
|
||||
|
||||
## 正文
|
||||
|
||||
## TL;DR — Key Takeaways
|
||||
|
||||
- Wheely extracted push, SMS and status notifications from its Ruby monolith into a centralized, stateless Go service after fragmented delivery logic became difficult to scale and manage.
|
||||
- When its shared RabbitMQ cluster struggled with large campaign spikes, the team used MongoDB as a persistent polling queue with atomic task claiming, retries, exponential backoff, idempotency and dead-letter handling.
|
||||
- The new architecture handled several times the previous peak volume without broker-related delivery failures, but introduced polling latency, database overhead and additional functionality for the team to maintain
|
||||
|
||||
A back-end team extracted notification delivery from a large Ruby monolith into a centralized Go service, only to discover that their shared RabbitMQ cluster could not reliably support the new workload. Here’s how they solved the problem using MongoDB as a polling queue and the trade-offs that came with it.
|
||||
|
||||
### The Scaling Problem Inside the Monolith
|
||||
|
||||
Back in 2019, the engineering team at Wheely, a popular ride-hailing platform, had a coordination problem that emerged with the product. User-facing notifications such as push alerts, SMS confirmations and status updates were scattered around the large Ruby monolith. Various parts of the codebase made direct attempts to send messages without a shared logic, unified retry strategy and consistent way to track delivery outcomes. As the system continued to grow, new back-end microservices were introduced, with each one requiring its own path to the user’s device.
|
||||
|
||||
Push campaigns made things worse. Sending thousands of notifications at once exposed limits that routine traffic had never revealed. The monolith wasn’t designed as a notification delivery system, and scaling it that way implied additional risks to the core business logic already implemented there.
|
||||
|
||||
The team needed a dedicated, centralized service that could serve as a single point of entry for all outbound communications, both for the monolith and future microservices alike.
|
||||
|
||||
### Why the Existing Message Broker Wasn’t Enough
|
||||
|
||||
The natural architecture for this kind of service involves a message broker. The monolith and microservices publish notification events, workers consume them and delivery happens asynchronously. The team’s infrastructure already had RabbitMQ in place, so the initial design assumed it would handle this workload.
|
||||
|
||||
In practice, the shared RabbitMQ cluster proved unreliable under the notification service’s workload. Unstable behavior of the cluster during large push campaigns caused several delivery failures, which were difficult to diagnose, hard to retry correctly and disruptive to other services that used the same broker.
|
||||
|
||||
### RabbitMQ Internals
|
||||
|
||||
To understand why RabbitMQ turned out to be a bottleneck, it’s worth taking a quick look at its internal architecture.
|
||||
|
||||
RabbitMQ is built on top of the Erlang virtual machine: BEAM, where almost every broker component runs as a separate Erlang process. Queues, connections, channels and consumers are independent lightweight processes, communicating with each other via messaging.
|
||||
|
||||
This model provides strong fault tolerance and scalability in various scenarios. However, under a very heavy load, the overhead of managing these processes can become noticeable. Moreover, RabbitMQ is also sensitive to the type of load it receives.
|
||||
|
||||
- The first factor is the number of queues. Each queue is a separate Erlang process with its own internal data structures. As the number of queues increases, more memory is used, the Erlang VM scheduler starts working harder and there is an additional operational overhead from operating the broker.
|
||||
- Second, the length of the queue matters. RabbitMQ was designed as a system to process continuous message flow, not to store very large backlogs for long periods. If producers write faster than consumers can read, the queue starts growing quickly. It results in higher memory usage, puts additional pressure on the disk for persistent messages and significantly increases delivery delay.
|
||||
- Finally, RabbitMQ clusters are sensitive to network conditions. Replication between nodes, synchronization of queues after recovery and network latency can all significantly impact the system’s performance and cluster recovery time after failures.
|
||||
|
||||
These characteristics are not flaws in RabbitMQ; they simply define the type of loads it is best suited to handle. When designing a high-load system, it is important to consider not only the broker’s capabilities but also the workload profile it will need to support.
|
||||
|
||||
### Why RabbitMQ Was No Longer the Right Fit
|
||||
|
||||
RabbitMQ had handled its role well for a long period. The problem was not with the broker itself, but the change in workload that took place over time.
|
||||
|
||||
- First, the system was increasingly dealing with large-scale push and SMS campaigns. A single campaign generated tens of thousands of individual messages, all arriving in RabbitMQ practically at the same time. This created sharp load spikes, made queues grow and increased delivery delays.
|
||||
- Second, some consumers were still running inside the Ruby monolith. Compared to the newer Go services, they were slower at processing messages, allowing queues to accumulate much faster than they could be drained. Simply increasing the number of consumers wasn’t a practical option. Performance of the monolith had already become a limiting factor, and scaling it would have been complicated due to the current system’s architecture.
|
||||
- Finally, RabbitMQ served as a shared infrastructure component for various services. Every new communication-related feature added load to the same cluster, making it an increasingly critical point of failure.
|
||||
|
||||
### Extracting a Centralized Go Notification Service
|
||||
|
||||
The new service was implemented as a single, stateless API responsible for accepting send requests and handling everything else: Routing to the target provider, retrying failed deliveries and recording the outcome. The monolith and other microservices sent requests to a single endpoint without having to manage the delivery process themselves.
|
||||
|
||||
Go was chosen for the implementation of the new service. It was containerized and deployed using Docker on the existing AWS infrastructure, consistent with the rest of the microservices on the platform.
|
||||
|
||||
On the mobile side, the service integrates with the Apple Push Notification service (APNs) and Firebase Cloud Messaging (FCM). SMS delivery was handled via integration with one or more third-party providers.
|
||||
|
||||
### Using MongoDB as a Polling Queue
|
||||
|
||||
Since it was not possible to rely on any broker, it was necessary to find some alternative way of buffering delivery tasks and processing them. The alternative chosen by the team was the usage of MongoDB as a polling queue. MongoDB was one of the tools used in the current stack.
|
||||
|
||||
When a notification request arrives, the service writes a document to a dedicated MongoDB collection. Each document represented a single delivery task and contained all the information needed to be processed independently: The recipient, the message payload, the channel, the current status and metadata to retry tracking.
|
||||
|
||||
A simplified document life cycle looked like this:
|
||||
|
||||
`pending → processing → delivered`
|
||||
|
||||
`↘ retry → (back to pending, up to N attempts)`
|
||||
|
||||
`↘ failed (dead-letter)`
|
||||
|
||||
Workers polled the collection at short intervals, querying for documents in the pending state. To process two workers trying to process the same task, MongoDB’s atomic `findOneAndUpdate` operation was used to transition a document from `pending` to `processing` in a single step. Only one worker succeeded in claiming any given record.
|
||||
|
||||
Retry policy was embedded in the document itself. Each failed attempt incremented a counter, as well as updated a retry_after timestamp using an exponential backoff strategy. Workers excluded documents whose retry_after time had not yet passed. Documents that reached the maximum retry count were moved to the failed state rather than being tried to be processed again.
|
||||
|
||||
Idempotency was maintained by creating a stable identifier for each delivery task when it was created. In case the same request arrived twice due to the retry on the caller’s side, the service could detect the duplicate before writing a second document.
|
||||
|
||||
Processed and failed records were either archived into another collection or dropped after the retention window.
|
||||
|
||||
Index design was critical. The collection required compound indexes covering status, channel and scheduling fields for efficient polling queries. Without the right indexes, polling at scale would have caused unacceptable read load on MongoDB.
|
||||
|
||||
### Optimizing MongoDB for a Write-Heavy Workload
|
||||
|
||||
Using MongoDB as a persistent queue required careful data model design.
|
||||
|
||||
- First, we separated the queue into a write-heavy collection, fully isolated from the rest of the application data. This way, it was possible to optimize it independently by choosing its own indexes, configuring a dedicated retention policy and ensuring that intensive writes did not affect the rest of the system.
|
||||
- At the same time, we attempted to implement an append-heavy data model. Messages were created once and then updated just a few times while moving through the delivery pipeline before being either archived or deleted. This life cycle aligned well with MongoDB’s strengths and helped maintain stable write performance.
|
||||
- Queue documents were intentionally kept compact. They included only information needed for routing, delivery and status tracking. This reduced the amount of data transferred, lowered disk and replication load and allowed more of the working set to fit in memory.
|
||||
- Indexes required particular attention. We deliberately limited them to those needed for efficient polling and status-based lookups. Any additional index increases the write cost, as MongoDB must update it on every insert or update. For write-heavy workloads, keeping the number of indexes minimal becomes more important than maximizing read performance.
|
||||
- Messages were polled in batches instead of one at a time. During each poll cycle, the worker would claim only a certain number of tasks, which significantly reduces the number of database operations, thereby making the load more predictable in case of many incoming messages.
|
||||
- Finally, to prevent the collection from growing indefinitely, we either periodically archived processed messages or automatically removed them using TTL indexes. This kept both the collection and its indexes relatively small, improving write speed and the efficiency of polling queries.
|
||||
|
||||
It was the combination of these decisions that made MongoDB an efficient and predictable persistent queue for this workload. Observability relied on tooling already in use at Wheely: The ELK stack for log aggregation and Datadog for metrics and alerting.
|
||||
|
||||
### The Trade-Offs We Accepted
|
||||
|
||||
MongoDB was not built to be a message broker, and using it as one comes at a cost.
|
||||
|
||||
During each poll cycle, database read operations were generated regardless of whether the queue was empty. At scale, it added measurable load to MongoDB. This load was then associated directly with notifications throughput instead of being isolated in a dedicated broker. Despite a careful index design and a sensible polling interval, it was still possible to reduce but not eliminate this overhead.
|
||||
|
||||
Polling introduces inherent latency. A message written to the queue would not be processed until the next poll cycle. It is a reasonable decision for most notification use cases, but it was a deliberate compromise compared to the near-immediate delivery that one can expect from a properly functioning broker.
|
||||
|
||||
The team also had to implement, test and maintain functionality that mature message brokers typically provide out of the box: Atomic claiming, retry scheduling, dead-letter handling, duplicate suppression and observability. Each of these capabilities added complexity to the service itself.
|
||||
|
||||
There was also an organizational risk. Solutions described as temporary often become permanent. Teams adopting this pattern should clearly define under what conditions that would justify migrating to a dedicated broker, and they should build sufficient observability to detect when those conditions are met.
|
||||
|
||||
A dedicated message broker continues to be the right choice in the case of a stable infrastructure, when the team has the operational expertise to operate it and the delivery latency requirements are strict. This architectural approach was chosen based on specific sets of constraints, not as a general recommendation.
|
||||
|
||||
### Operational Results and Lessons
|
||||
|
||||
After the migration, the service handled notification volumes several times higher than the previous peak without delivery failures caused by broker instability. The service achieved a much better delivery success rate and now serves as the shared communication layer for multiple back-end services across the platform.
|
||||
|
||||
Three lessons worth carrying forward:
|
||||
|
||||
- First, architecture must reflect the maturity of the infrastructure it runs on. A theoretically correct design built on an operationally unreliable dependency can perform worse than a pragmatic design built on infrastructure the team already operates well.
|
||||
- Second, database polling can be a viable delivery mechanism, but it requires a thorough implementation. Idempotence, atomic claiming, backoff, dead-letter handling and observability are not optional additions; but are the key to making the pattern safe. Skipping even one of them leads to failure modes that are difficult to diagnose under load.
|
||||
- Third, extracting a shared capability from a monolith is an operational change, not just a code refactoring exercise. The migration required a careful cutover strategy to avoid interrupting live delivery. The organizational and operational work was at least as significant as the engineering work.
|
||||
|
||||
### Architecture Diagram
|
||||
|
||||
[Monolith/Microservices]
|
||||
│ send request
|
||||
|
||||
▼
|
||||
|
||||
[Notification Service API]
|
||||
│ write task
|
||||
|
||||
▼
|
||||
|
||||
[MongoDB — pending queue]
|
||||
│ poll + claim (findOneAndUpdate)
|
||||
|
||||
▼
|
||||
|
||||
[Worker pool]
|
||||
│ │
|
||||
|
||||
▼ ▼
|
||||
|
||||
[APNs/FCM] [SMS Provider(s)]
|
||||
│ update status
|
||||
|
||||
▼
|
||||
|
||||
[MongoDB — delivered/retry/failed]
|
||||
## Frequently Asked Questions
|
||||
|
||||
## Wheely extracted push, SMS and status notifications from its Ruby monolith into a centralized, stateless Go service after fragmented delivery logic became difficult to scale and manage. When its shared RabbitMQ cluster struggled with large campaign spikes, the team used MongoDB as a persistent polling queue with atomic task claiming, retries, exponential backoff, idempotency and dead-letter handling. The new architecture handled several times the previous peak volume without broker-related delivery failures, but introduced polling latency, database overhead and additional functionality for the team to maintain
|
||||
|
||||
Notification logic was scattered throughout the monolith, with no unified retry strategy, shared delivery rules or consistent method for tracking outcomes. A centralized service gave the monolith and newer microservices one entry point for outbound communications.
|
||||
|
||||
## Why wasn’t RabbitMQ suitable for the new workload?
|
||||
|
||||
Large push and SMS campaigns generated tens of thousands of messages almost simultaneously. This caused sharp traffic spikes, growing queues and delivery delays, while slower consumers inside the monolith struggled to drain the backlog.
|
||||
|
||||
## How did MongoDB function as a notification queue?
|
||||
|
||||
Each delivery request was stored as a document. Workers polled for pending tasks and used MongoDB’s atomic findOneAndUpdate operation to claim them, preventing multiple workers from processing the same notification. Failed tasks were rescheduled using exponential backoff or moved to a failed state after reaching the retry limit.
|
||||
@@ -0,0 +1,89 @@
|
||||
# Runbooks + RAG: How I Gave My AI SRE Agent the Context It Was Missing
|
||||
|
||||
- **期号**: SRE Weekly Issue #527(2026-07-26)
|
||||
- **作者**: Akhilesh Rao Meesala — HackerNoon
|
||||
- **链接**: https://hackernoon.com/runbooks-rag-how-i-gave-my-ai-sre-agent-the-context-it-was-missing
|
||||
|
||||
## 简介
|
||||
|
||||
A detailed description of their approach, including how they tested it and the weak points they’re still iterating on.
|
||||
|
||||
## 正文
|
||||
|
||||
*In [my previous article](https://hackernoon.com/i-built-an-ai-sre-agent-that-diagnoses-incidents-before-i-open-my-laptop?ref=hackernoon.com), I described building a semi-autonomous SRE agent that investigates incidents and drafts fixes for human approval. This one is about the part of that build I have not told yet: how the agent knows what it knows, and how many tries it took to get there.*
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
There is a pattern to AI DevOps demos. The agent gets a clean alert, queries a metric, finds an obvious anomaly, and produces a confident diagnosis. Everyone applauds. Then someone points it at a real environment and it confidently recommends restarting a service that has been deprecated for two years.
|
||||
|
||||
The gap between the demo and production is not intelligence. It is context.
|
||||
|
||||
An LLM knows what Kubernetes is. It does not know that your `payments-api` has a flaky liveness probe everyone ignores, that the checkout team owns the retry policy, or that the last three "database incidents" were actually cache misconfigurations. That knowledge lives in your runbooks, your postmortems, your architecture docs, and the heads of your senior engineers.
|
||||
|
||||
The agent I described in my previous article already pulled in runbook context when an incident required it. What I did not cover is how it got there. My first build had none of that knowledge, and my second attempt delivered it badly. Here is the path to runbooks plus retrieval-augmented generation, and what I learned about keeping an agent's knowledge honest.
|
||||
|
||||
## The Two Knowledge Planes
|
||||
|
||||
An SRE agent needs two fundamentally different kinds of knowledge, and they should be architected separately.
|
||||
|
||||
**The live plane** is the current state of the world: metrics from Prometheus, container logs, Kubernetes events, deploy history, alert payloads. This data is fresh, factual, and machine-generated. The agent gets it through scoped, read-only tools at investigation time.
|
||||
|
||||
**The organizational plane** is everything your team knows that no dashboard shows: runbooks, SOPs, playbooks, postmortems, architecture docs, service ownership, escalation rules. This data is slow-moving, human-written, and full of judgment calls. It answers questions the live plane cannot: is this symptom normal for this service? Who do I page? What did we do last time?
|
||||
|
||||
My first build wired up the live plane and stuffed a summary of the organizational plane into the system prompt. That failed in two ways. The prompt grew until it crowded out the actual investigation, and it was perpetually stale because nobody updates a system prompt when they update a runbook.
|
||||
|
||||
## Retrieval Instead of Stuffing
|
||||
|
||||
The fix was boring and effective: treat organizational knowledge as a retrieval problem.
|
||||
|
||||
All of it — runbooks, postmortems, architecture notes, ownership maps — lives as markdown in a git repository. A pipeline chunks the documents, embeds them, and loads them into a vector database. On every merge to main, the embeddings for changed files are rebuilt. The knowledge base is never more than one merge behind reality.
|
||||
|
||||
At incident time, the agent does not receive the whole library. It retrieves what the incident is about. A latency alert on `checkout-api` pulls the checkout runbook, the postmortems that mention checkout, and the architecture doc describing its dependencies. Nothing about the batch pipeline, nothing about the mobile gateway.
|
||||
|
||||
The investigation loop looks like this:
|
||||
|
||||
1. Alert arrives; the agent identifies affected services from routing metadata
|
||||
2. Retrieval: runbooks, postmortems, and docs relevant to those services
|
||||
3. Live investigation: metrics, logs, deploy diffs through read-only tools
|
||||
4. Correlation: live signals interpreted *in light of* retrieved knowledge
|
||||
5. If evidence is thin, retrieve more or escalate to a human
|
||||
|
||||
Step 4 is where the value concentrates. Raw telemetry says "cache hit ratio dropped." The retrieved postmortem says "we saw this exact pattern in March; the cause was a TTL misconfiguration; the fix was PR #1203." Those two together are a diagnosis. Either alone is a guess.
|
||||
|
||||
## The Incident That Proved It
|
||||
|
||||
During testing, I injected a failure the agent had never seen: connection resets on a service that sat behind a third-party API. The live signals were ambiguous — error rates up, latency ragged, no recent deploy on the affected service itself.
|
||||
|
||||
The retrieval layer surfaced a postmortem from a previous incident that described the third-party provider's monthly maintenance window and its signature: connection resets starting precisely on the hour. The agent checked the timestamp, matched the pattern, and its response changed from "probable network issue, investigating" to "this matches the vendor maintenance pattern documented in the June postmortem; recommended action is the mitigation from that document; no code change needed."
|
||||
|
||||
That answer did not come from the model being smart. It came from a two-paragraph postmortem someone wrote months earlier, retrieved at the right moment. The agent's job was recognizing that the document and the telemetry described the same event.
|
||||
|
||||
## Keeping the Knowledge Honest
|
||||
|
||||
RAG introduces a new failure mode: the agent is now only as good as the documents you feed it. Three rules kept mine trustworthy.
|
||||
|
||||
**Runbooks live in git, next to the services they describe.** Updating the agent's behavior means merging a PR, which means code review. Tribal knowledge gets the same rigor as code. Stale runbooks get caught in review, not at 3 AM.
|
||||
|
||||
**Postmortems are the highest-value documents in the corpus.** They encode symptom-to-cause mappings that exist nowhere else. My agent writes a structured postmortem after every resolved incident — published to Confluence for humans, with a markdown copy committed to the git corpus for the agent. Every incident makes the next investigation smarter. The knowledge base compounds.
|
||||
|
||||
**Retrieved content is context, not command.** A runbook that says "restart the service immediately" does not make the agent restart anything. Retrieved documents inform the diagnosis; actions still go through the same scoped tools, validation hooks, and human approval I described in the previous article. This matters for safety — documents can be wrong, outdated, or in a worst case, poisoned. The knowledge layer gets no authority, only influence.
|
||||
|
||||
## What Still Breaks
|
||||
|
||||
Honesty section. Three problems I have not fully solved:
|
||||
|
||||
**Retrieval misses.** If an incident's vocabulary does not match the runbook's vocabulary, the right document does not surface. An alert about "connection pool exhaustion" will not retrieve a runbook titled "database saturation issues" unless the embeddings happen to bridge the gap. I now write runbooks with symptoms in the first paragraph, which helps but does not eliminate it.
|
||||
|
||||
**Conflicting documents.** Two runbooks, written two years apart, recommending opposite mitigations. The agent has no way to know which one is current unless the corpus tells it. I added a `last_validated` date to every runbook header and taught the retrieval layer to prefer recency — a crude fix for a real problem.
|
||||
|
||||
**Confidence laundering.** A retrieved document can make a weak diagnosis sound strong. "As documented in the runbook" is persuasive even when the runbook is only loosely relevant. The agent now cites which documents shaped its hypothesis, so the human reviewing the diagnosis can check whether the citation actually supports it.
|
||||
|
||||
## The Takeaway
|
||||
|
||||
If your AI DevOps agent works in demos and fails in production, the missing ingredient is probably not a better model. It is the organizational knowledge your team already wrote down, retrieved at the right moment, and kept honest by the same review process you use for code.
|
||||
|
||||
Live telemetry tells the agent what is happening. Runbooks and postmortems tell it what that means *here*, in your system, with your history. An agent with both is a useful colleague. An agent with only the first is a demo.
|
||||
|
||||
If you have built a knowledge layer for an agent — especially if you have solved retrieval misses better than I have — I would love to hear how.
|
||||
Reference in New Issue
Block a user