sreweekly: 528 期数据 + 全文抓取(articles/pages + markdown 正文扩充)
This commit is contained in:

@@ -0,0 +1,71 @@
|
||||
# Content Ingestion & Podcast Video Incident Report
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Jim Whitehead, Ulrik Mikaelsson, John Lagomarsino, and Saunak Jai Chakrabarti — Spotify
|
||||
- **链接**: https://engineering.atspotify.com/2026/7/content-ingestion-and-podcast-video-incident-report/
|
||||
|
||||
## 简介
|
||||
|
||||
Spotify has had some difficulty around podcast publishing, and they shared this analysis of the worst incident.
|
||||
|
||||
## 正文
|
||||
|
||||
# Content Ingestion & Podcast Video Incident Report
|
||||
|
||||
|
||||
|
||||
Over the past two months, podcast creators have experienced a series of reliability issues on Spotify. This report covers the most significant of these, the June 24 publishing delay, in full detail and describes the broader reliability program now underway across our publishing pipeline.
|
||||
|
||||
## What happened?
|
||||
|
||||
When a podcast creator publishes a new episode, the audio and video content goes through a series of processing steps before it becomes available to Spotify users. These steps include transcoding (converting media into the formats our apps need) and content analysis.
|
||||
|
||||
On June 24, our video transcoding infrastructure reached maximum capacity. This created a backlog that delayed the publication of video podcast episodes for several hours. Creators reported that their episodes were not appearing on Spotify as expected. A queue built up and video podcast episodes that would normally be published within minutes were delayed for hours. Understandably, some creators re-uploaded episodes that had not appeared, which added further load. That is on us, not them: the system should have confirmed their upload was received and queued, and it did not.
|
||||
|
||||
|
||||
|
||||
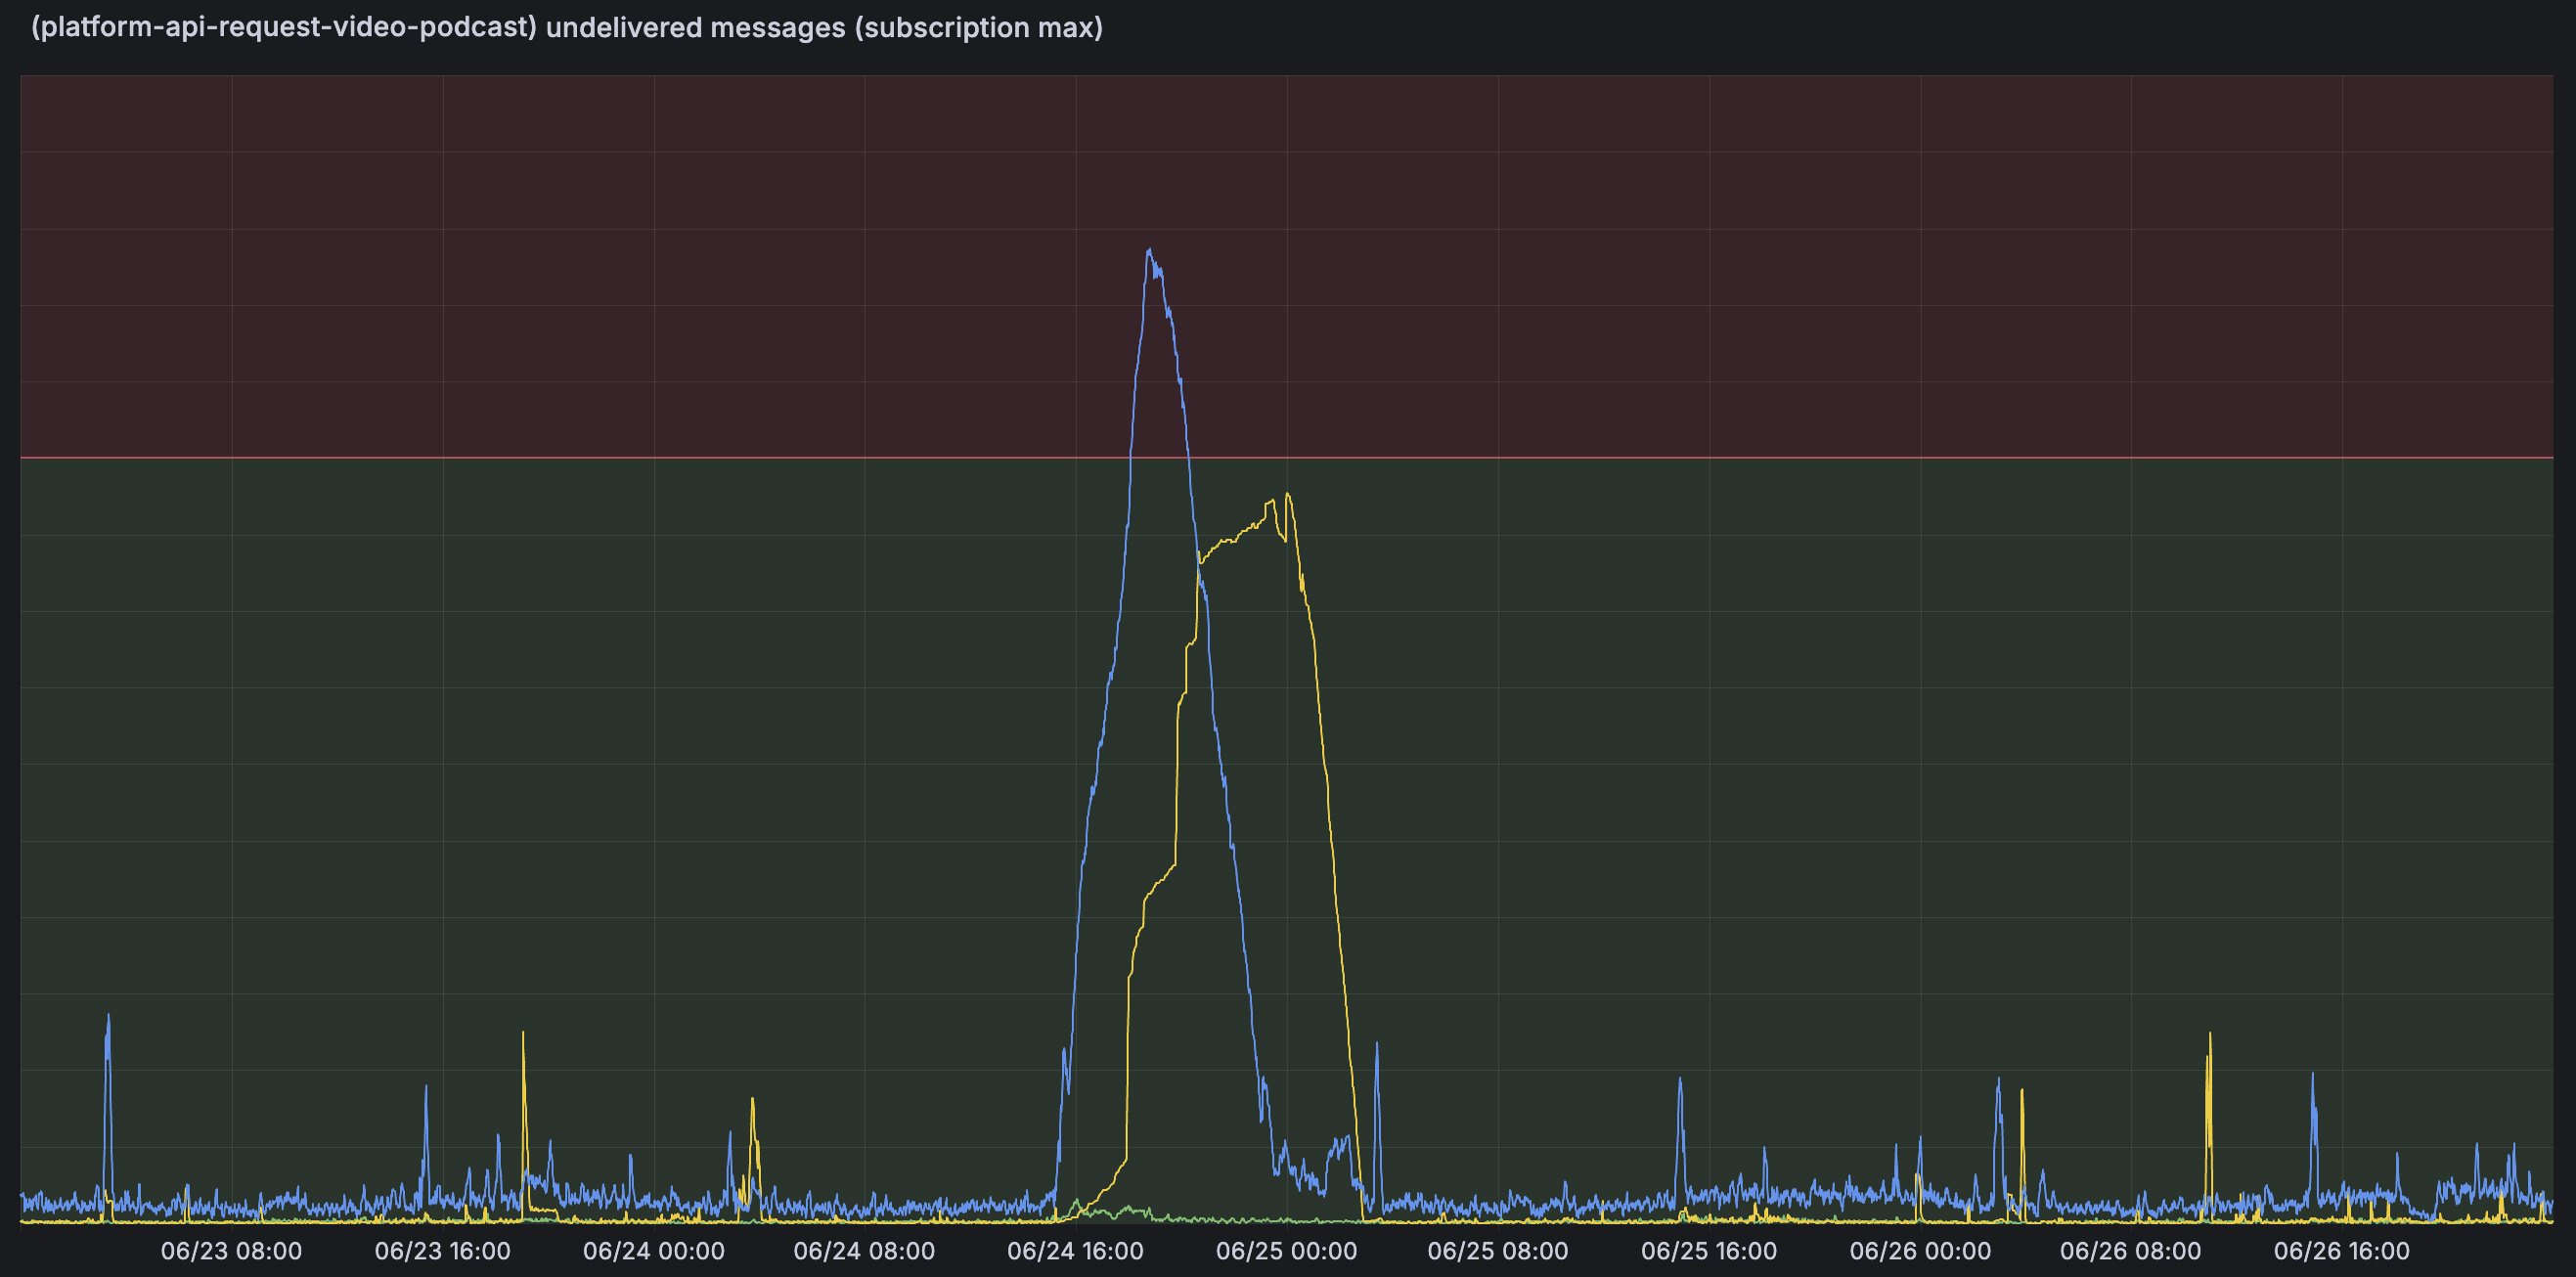
The image above shows the build-up and subsequent emptying of the medium-priority (used for new episodes - shown in blue) and low-priority (used for updates to older episodes - shown in yellow) queues.
|
||||
|
||||
Four factors converged to create this situation:
|
||||
|
||||
- **Our transcoding infrastructure was running with insufficient headroom to handle large spikes of content delivery** . During typical periods of content submission our transcoding systems were able to scale and support both low-priority transcoding as well as the high-priority publication of new content. However, there wasn’t sufficient headroom to scale and support large spikes caused by the bulk delivery of new content.
|
||||
|
||||
- **A scheduled batch processing job was running.** On occasion, we need to re-process existing episodes to be compatible with changes or additions to Spotify’s playback systems. During the June 24 disruption, a routine batch job processing existing content was consuming additional capacity alongside the regular processing for new episodes. While this job appeared fine earlier in the day, it became problematic when combined with increased content submissions.
|
||||
|
||||
- **Recent improvements increased per-item processing cost.** We had recently changed our video transcoding to deliver better quality at lower bitrates. That change increased the time and processing power each episode requires, and we did not fully account for that added demand in our capacity planning.
|
||||
|
||||
- **A software bug was underutilizing available compute resources.** Following a recent infrastructure migration to more powerful hardware, a bug in our resource scheduling caused our systems to underuse available processing capacity, reducing throughput by about 10%.
|
||||
|
||||
When we identified the issue, we stopped the batch job, deployed a fix for the resource scheduling bug, and added additional processing capacity overnight. By the following morning, all backlogs had cleared and publishing was operating normally. We subsequently added further capacity to provide the headroom that had been missing.
|
||||
|
||||
## Timeline (UTC)
|
||||
|
||||
- **13:30** — Early alerts fire in our internal monitoring. Not immediately recognized as a broader capacity issue.
|
||||
- **15:00** — Video podcast delivery spike pushes transcoding close to maximum capacity.
|
||||
- **16:35** — Batch processing job stopped to free capacity.
|
||||
- **17:31** — First Creator report of an issue impacting podcast video publishing received.
|
||||
- **17:34** — Automated alerts confirm queue backlog exceeding thresholds. Incident response begins.
|
||||
- **19:00** — Creator reports escalated to incident team.
|
||||
- **20:49** — Software fix deployed to improve resource utilization.
|
||||
- **00:14 (Jun 25)** — Additional processing cluster brought online.
|
||||
- **01:02** — All queues cleared.
|
||||
- **07:30** — Full confirmation: all publishing pipelines operating normally.
|
||||
|
||||
One thing this timeline makes plain: roughly four hours passed between the first alerts and formal incident response. We want to do better. Engineers investigating the early alerts stopped the batch job at 16:35, but we did not recognize the full scope of the capacity problem until queues breached thresholds at 17:34. The monitoring improvements described below exist to close exactly that gap.
|
||||
|
||||
## Where do we go from here?
|
||||
|
||||
We have already taken several steps to address this specific incident:
|
||||
|
||||
- Increased our transcoding capacity by approximately 67%, providing significantly more headroom for traffic spikes and batch operations.
|
||||
- Fixed the resource scheduling bug that was leaving under-utilized compute capacity.
|
||||
- Improved our monitoring to alert earlier when capacity is approaching limits.
|
||||
|
||||
Beyond this specific incident, we are investing in broader improvements to the reliability of our podcast publishing pipeline. We've formed a dedicated cross-team effort focused on:
|
||||
|
||||
- Building better capacity planning that accounts for not just steady-state traffic, but also burst capacity and incident recovery.
|
||||
- Improving prioritization across our publishing systems so that real-time content from creators is always processed ahead of background operations.
|
||||
- Extending rate limiting and backpressure mechanisms throughout the pipeline to handle unexpected load gracefully.
|
||||
- During this incident, many creators learned something was wrong from their audiences before they heard anything from us. We are improving our processes and technical capabilities so creators get notified as soon as possible when things aren’t working.
|
||||
|
||||
When a creator hits publish, their audience is waiting, and hours matter. We fell short repeatedly this summer, and we know a report like this only counts if the next incident is handled better than the last. The work above is how we intend to earn that trust back.
|
||||
@@ -0,0 +1,169 @@
|
||||
# The Pulse: Quitting Spotify Podcasts over reliability
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Gergely Orosz — The Pragmatic Engineer
|
||||
- **链接**: https://blog.pragmaticengineer.com/the-pulse-quitting-spotify-podcasts-over-reliability/
|
||||
|
||||
## 简介
|
||||
|
||||
…and here’s where it gets interesting. This post shares the user point of view on the Spotify issues, including fact-checking their published timeline.
|
||||
|
||||
## 正文
|
||||
|
||||
*Hi, this is Gergely with a bonus, free issue of the Pragmatic Engineer Newsletter. In every issue, I cover Big Tech and startups through the lens of senior engineers and engineering leaders. Today, we cover one out of four topics of* *last week's The Pulse issue**. Full subscribers received the article below seven days ago. If you’ve been forwarded this email, you can* *subscribe here**.*
|
||||
|
||||
You can no longer watch The Pragmatic Engineer Podcast as *video* in the Spotify app (only as audio) because I have quit publishing video on that streaming platform. This comes after I decided that reliability takes a back seat within that team – and across much of Spotify. Unlike on other platforms such as YouTube, Apple Podcasts, and Substack, I’ve recently encountered a series of reliability issues around Spotify being unable to process video episodes. Even though I enjoyed a direct link with the Podcasts team there, things haven’t improved.
|
||||
|
||||
So from now, I will no longer be publishing video episodes on Spotify. You can find videos of my in-depth chats with guests only [on YouTube](https://www.youtube.com/@pragmaticengineer?ref=blog.pragmaticengineer.com). *Apologies for any inconvenience this change causes!* Audio episodes of the podcast can still be found [on Spotify](https://open.spotify.com/show/2Bho9xCbOQMWMJ7UKmqCzD?ref=blog.pragmaticengineer.com) via the RSS podcast feed hosted [on Substack](https://pragmaticpodcast.com/?ref=blog.pragmaticengineer.com).
|
||||
|
||||
Honestly, the decision to quit the streaming giant wasn’t hard, and I reckon there’s a point here about the risk of deprioritizing reliable operations at major companies in order to push on things like AI adoption, as Spotify seems to be doing.
|
||||
|
||||
Some context: for the first two years of The Pragmatic Engineer Podcast, it was published on three podcast platforms:
|
||||
|
||||
1. **Substack’s podcast platform (audio)** : this is where the[“master” RSS feed](https://api.substack.com/feed/podcast/458709.rss) is served to the likes of Apple Podcasts, the web, Overcast, Pocket Casts, etc
|
||||
2. **YouTube (video):** video episodes uploaded individually
|
||||
3. **Spotify (video + audio):** every video episode *was* uploaded individually and then served as video or audio episodes from the platform.
|
||||
|
||||
As someone hosting a podcast, there are good reasons to bother doing three separate uploads:
|
||||
|
||||
- **Most podcast platforms don’t support video.** There will always be a need for a platform that serves the master RSS feed for audio versions while the video ones are elsewhere.
|
||||
- **YouTube doesn’t integrate with anything.** YouTube is the leader in video podcast distribution, and uploading there directly makes sense.
|
||||
- **I had a direct line to the Spotify team, which was a big plus.** Starting out the podcast, I had the unusual privilege of contact with the podcasts team, thanks to the newsletter gaining a decently-size audience. I was persuaded to take the plunge with them.
|
||||
|
||||
For eighteen months, nothing *major* went wrong. The admin portal for podcast publishers (called ‘Spotify Creators’) was pretty wonky; it gave intermittent errors, and was unable to remember me when I signed in, so, each Wednesday, I’d have to sign in with a code sent to my email to publish an episode.
|
||||
|
||||
But overall, things worked, until it all went suddenly downhill…
|
||||
|
||||
### **Unable to publish Spotify podcast episodes 3 out of 5 weeks**
|
||||
|
||||
From late May, I did not include links to Spotify on new episode announcements because their podcasts product or platform seemingly had outages every time one published on Wednesdays at around 9am PST / 12pm EST / 6pm EU time.
|
||||
|
||||
**Outage #1 (20 May): podcast publishing broke**, my episode would not process on Spotify for 2+ hours. When uploading a video file to Spotify, there’s a processing pipeline that runs to create chunks of the podcast in different video and audio formats. This pipeline appeared to stop running, meaning new episodes were not published.
|
||||
|
||||
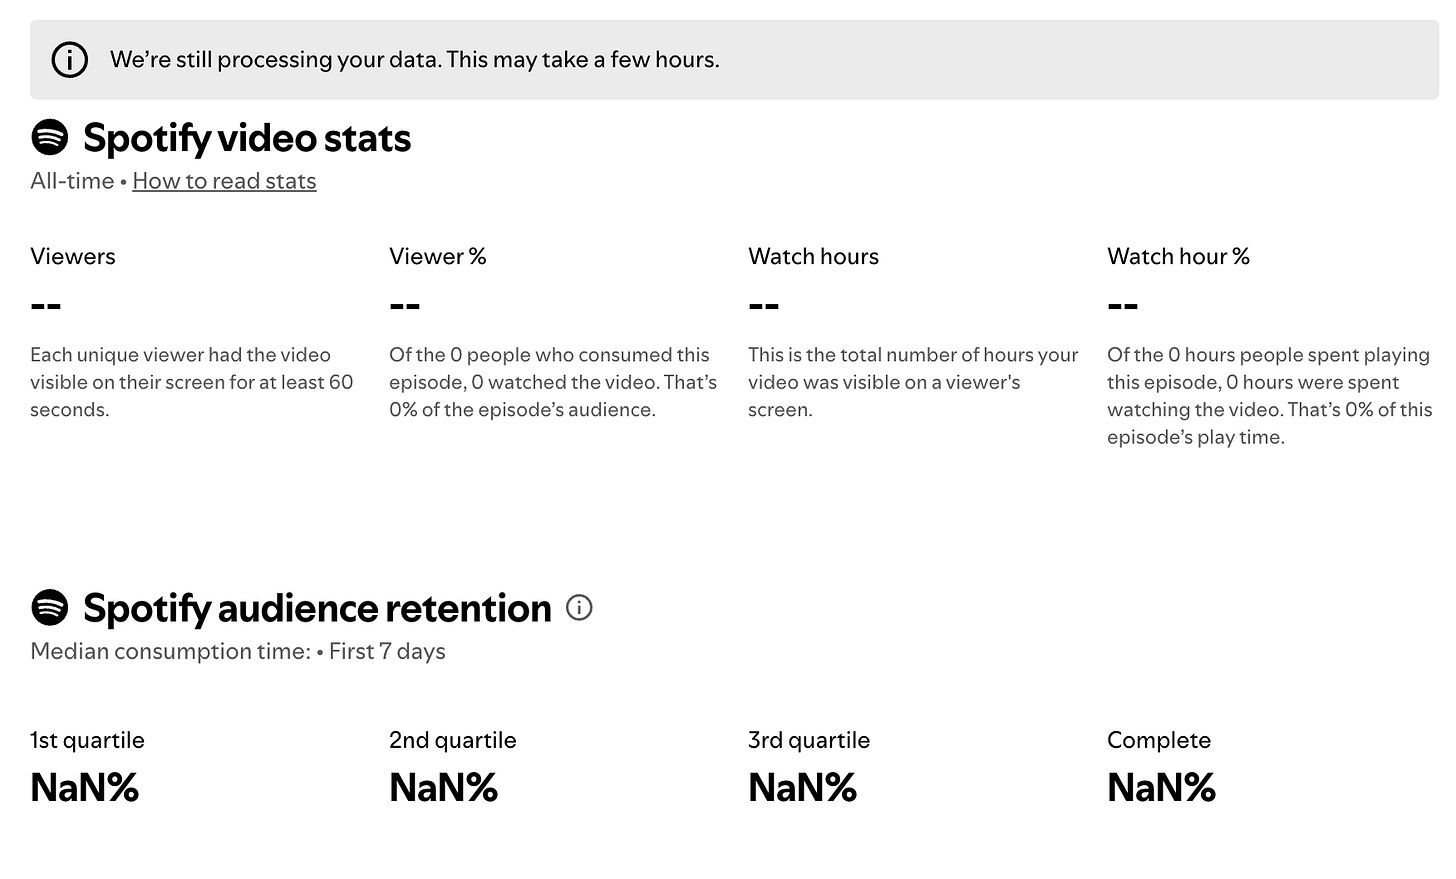
It was not just the publishing that broke: the Creator portal looked absurd, with NaN% values everywhere, during the outage:
|
||||
|
||||
|
||||
|
||||
|
||||
*During outage #1*
|
||||
I emailed the Spotify team to alert them about the outage and also [complained online](https://x.com/GergelyOrosz/status/2057127878517526860?s=20&ref=blog.pragmaticengineer.com). I got a response, confirming the outage and pledging to do better:
|
||||
|
||||
“The issue was in one of our podcast publishing metadata pipelines. A small subset of episodes completed normal media processing but then missed a downstream publish update because a newly introduced validation signal was not correctly wired into the logic that wakes up the publishing path. In simpler terms: the episode could become eligible to publish, but the final propagation step was not reliably triggered for that class of episodes.
|
||||
|
||||
We identified the root cause, deployed a fix, and reprocessed the affected episodes with all-clear called early this morning. We’re also tightening the system so that fields used for publishing eligibility cannot be added without also triggering the relevant downstream updates.
|
||||
|
||||
Separately, we’re reviewing how partial creator-impacting publishing delays are surfaced, because even when this is not a broad platform outage, it is still a bad experience for publishers like yourself.
|
||||
|
||||
Apologies again that you hit this. It was a real bug, not a wide outage, but it hit some of our most relevant creators.”
|
||||
|
||||
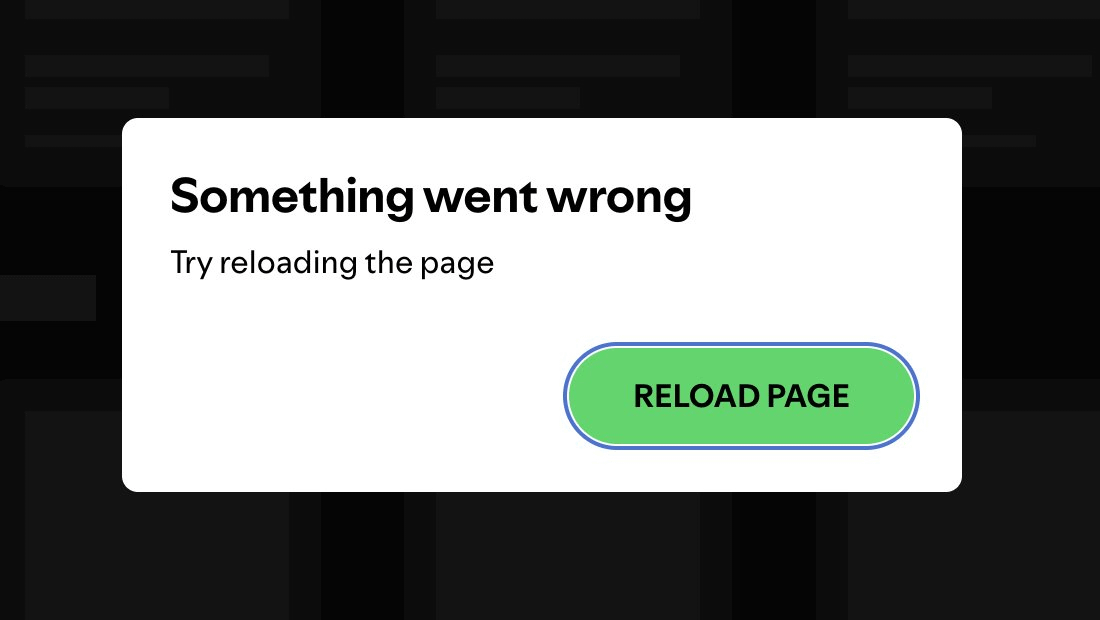
**Outage #2 (17 June): Spotify down.** Four weeks later, when attempting to publish a video episode, all of Spotify went down for many users, [including myself.](https://x.com/GergelyOrosz/status/2067285989710582271?s=20&ref=blog.pragmaticengineer.com)
|
||||
|
||||
|
||||
|
||||
Spotify does not maintain a status page, so it’s impossible to tell how widespread the outage was. I didn’t include a Spotify link in that week’s announcement either.
|
||||
|
||||
**Outage #3 (24 June): podcast publishing broke – again.** Outage #3 in five weeks; *deja vu*. This time, it was episode publishing not working, yet again. After waiting two hours for the episode to publish on Spotify, I yet again sent out the announcement with no Spotify link.
|
||||
|
||||
I also emailed the Spotify Podcasts team, who confirmed the outage. I said I was considering stopping publishing video episodes, and to switch to audio-only publishing (which means pointing Spotify to my master RSS feed.) I said that an apology was appreciated but it wasn’t enough to make it worth publishing video episodes there.
|
||||
|
||||
**I also asked for the incident review because I had the feeling that reliability was not all that important on this podcast product.** For the first outage I got a vague description of what happened, and promises of improvements that were never done – e.g. during this second outage, there was no improved communications to creators, which I was told would happen, after outage #1.
|
||||
|
||||
Internally, Spotify’s team surely conducted an incident review as per usual, so I figured I’d hear back in about two weeks’ time, and assumed a reply would be forthcoming because I’d made clear I was ready to leave Spotify Podcasts if reliability didn’t improve.
|
||||
|
||||
### **No incident review three weeks later, so I quit Spotify**
|
||||
|
||||
The incident review had never arrived as promised by three weeks later, even though there had been time for it to be completed. It was yet another sign of a platform that has become unreliable. Also, the creator portal occasionally threw up this error:
|
||||
|
||||
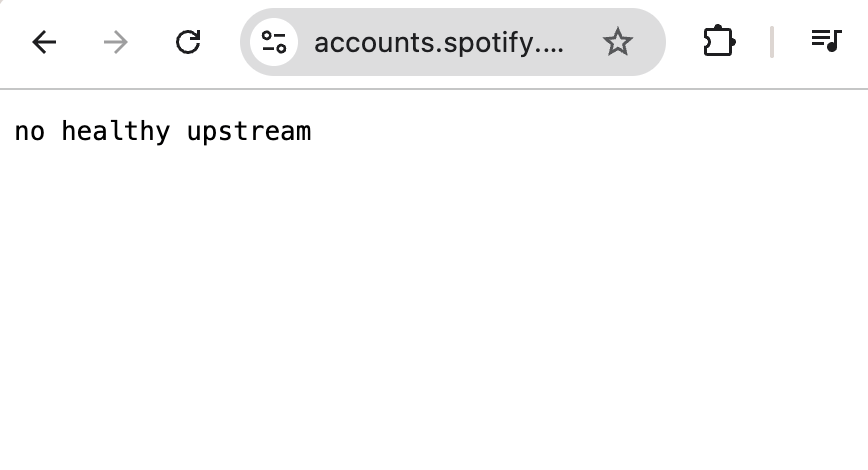
|
||||
|
||||
|
||||
*Spotify’s creator portal on 16 July*
|
||||
I checked my Spotify stats: stream plays had been trending downwards unsurprisingly, given the ongoing outages, while the other podcast platforms didn’t show the decline. It made me decide “enough is enough” and to move off Spotify.
|
||||
|
||||
Staying on their platform depended on seeing an incident review, but they didn’t prioritize transparency, still had no status page, and nobody had built a feature for episode-processing status like YouTube has had for years. So, I pulled the plug and left:
|
||||
|
||||
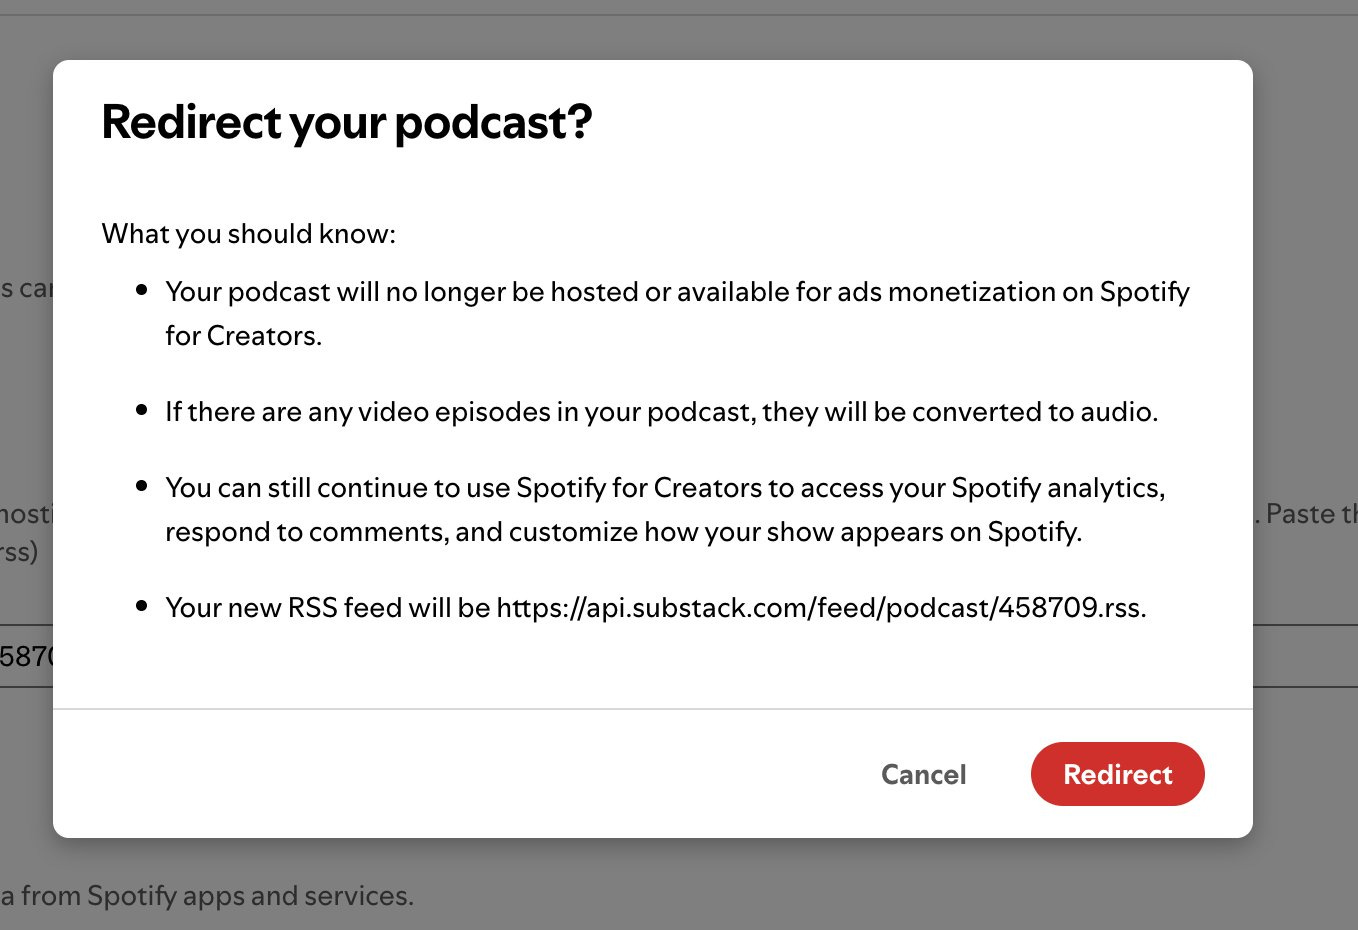
|
||||
|
||||
After I made the switch away from Spotify, the platform’s creators portal became buggier than ever, as in these examples:
|
||||
|
||||
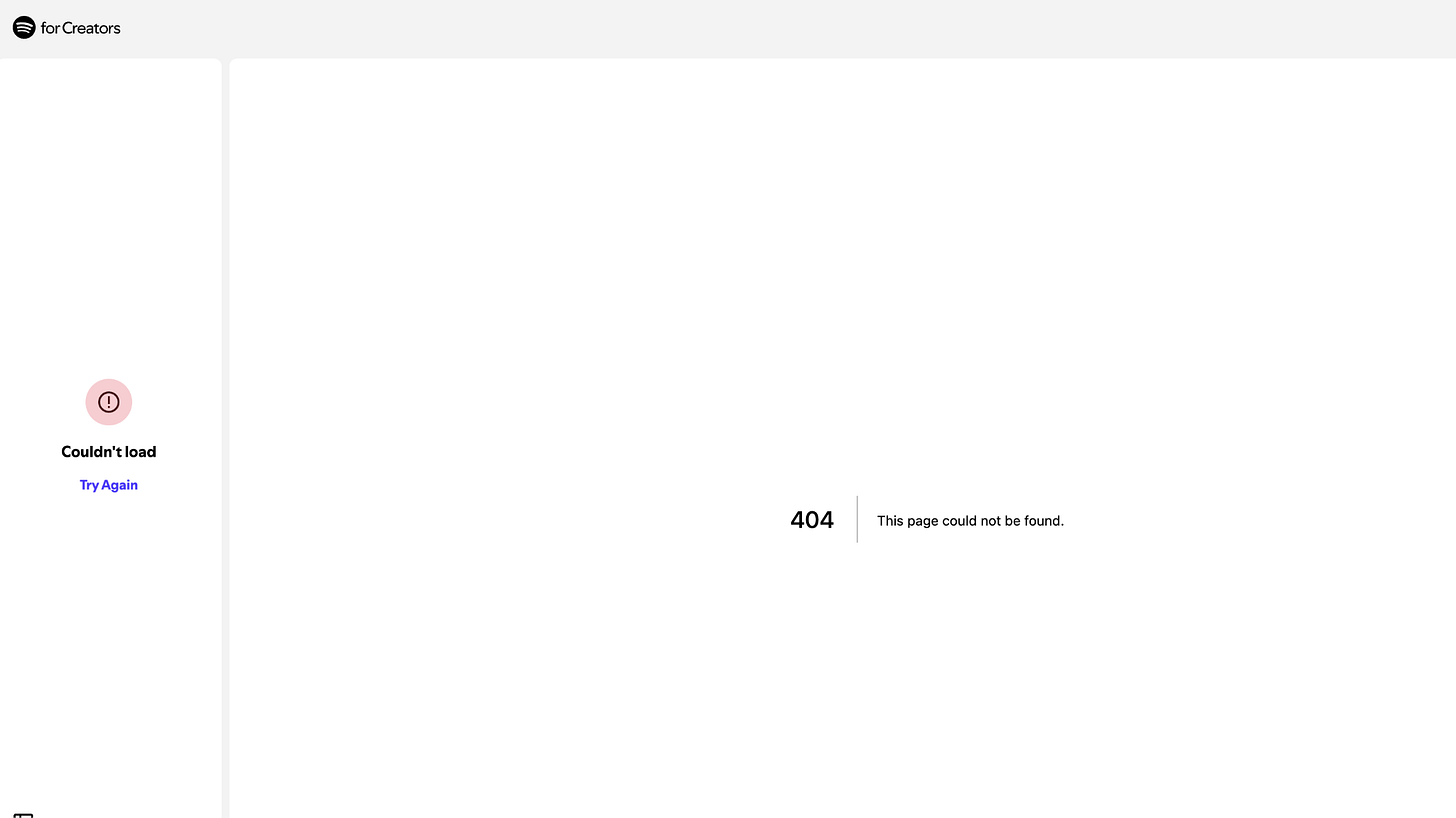
|
||||
|
||||
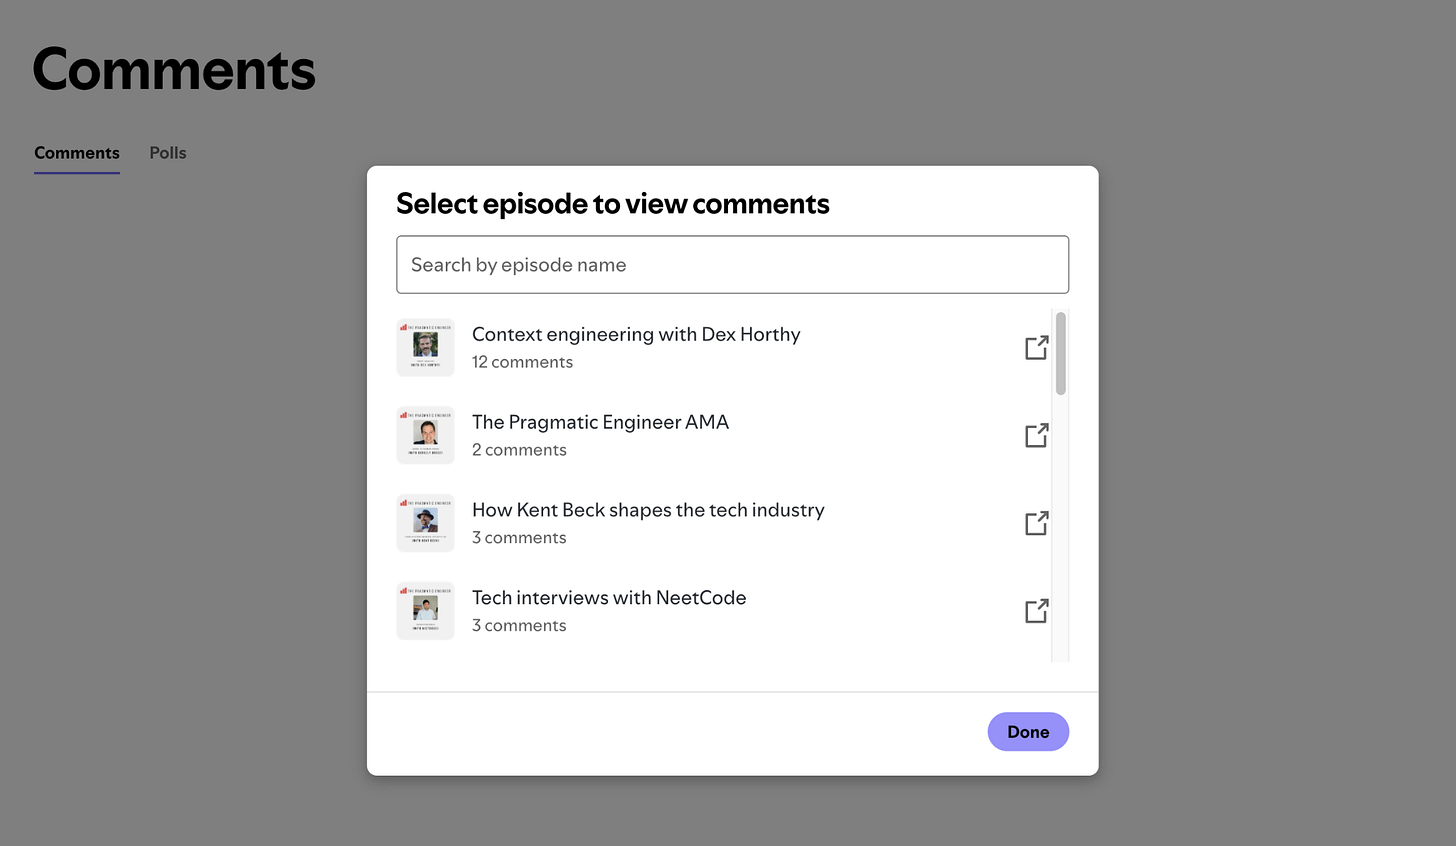
Comments disappeared:
|
||||
|
||||
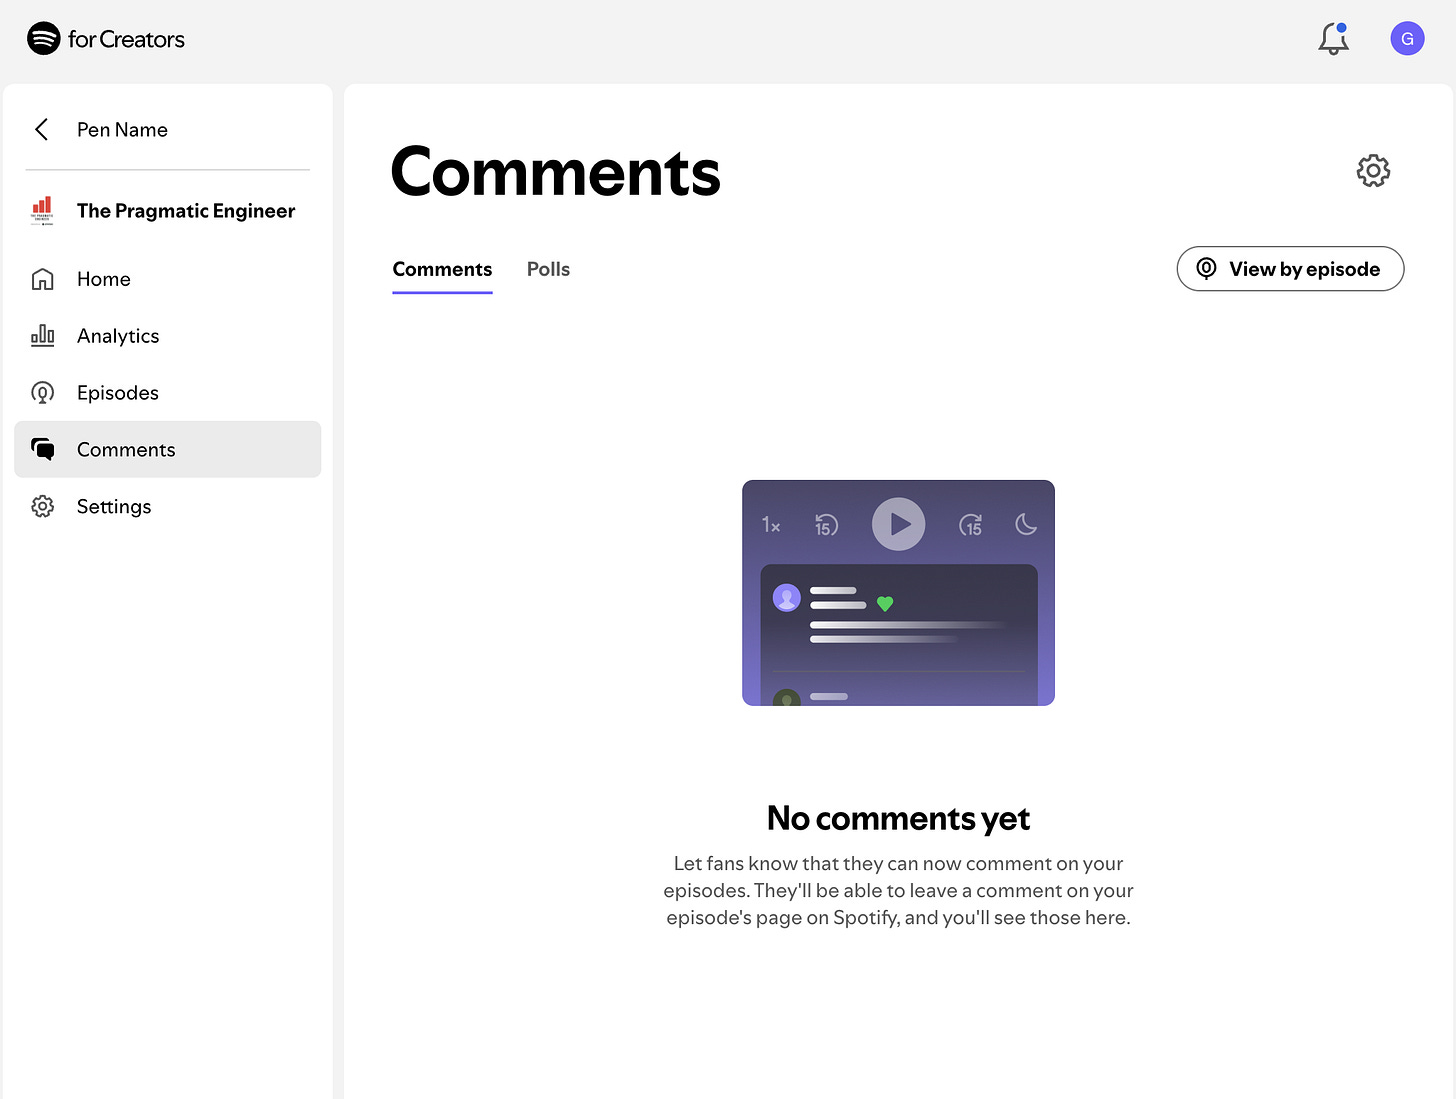
|
||||
|
||||
|
||||
*My show had no comments, suddenly*
|
||||
… even though other parts of the UI showed dozens of comments:
|
||||
|
||||
|
||||
|
||||
|
||||
*Zero comments, yet episodes with comments*
|
||||
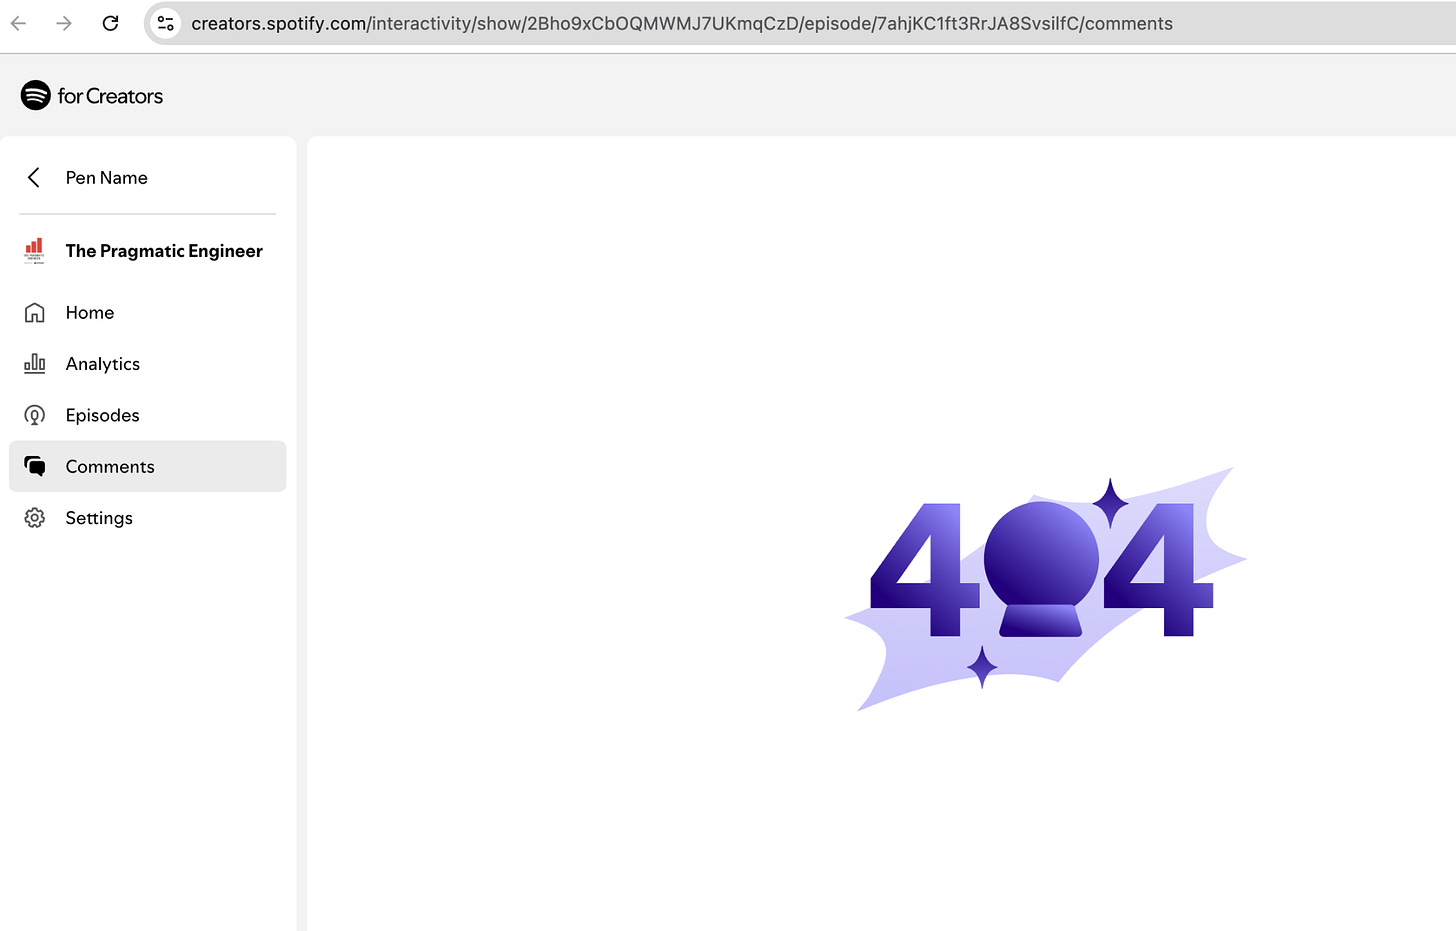
Episode links directed to 404 pages:
|
||||
|
||||
|
||||
|
||||
A day or two later, these issues disappeared: I assume no one had tested the flow of moving away from Spotify Podcasts to an RSS feed, and it’s why the experience was so poor.
|
||||
|
||||
### **Incident review finally published, but with a wrong timeline**
|
||||
|
||||
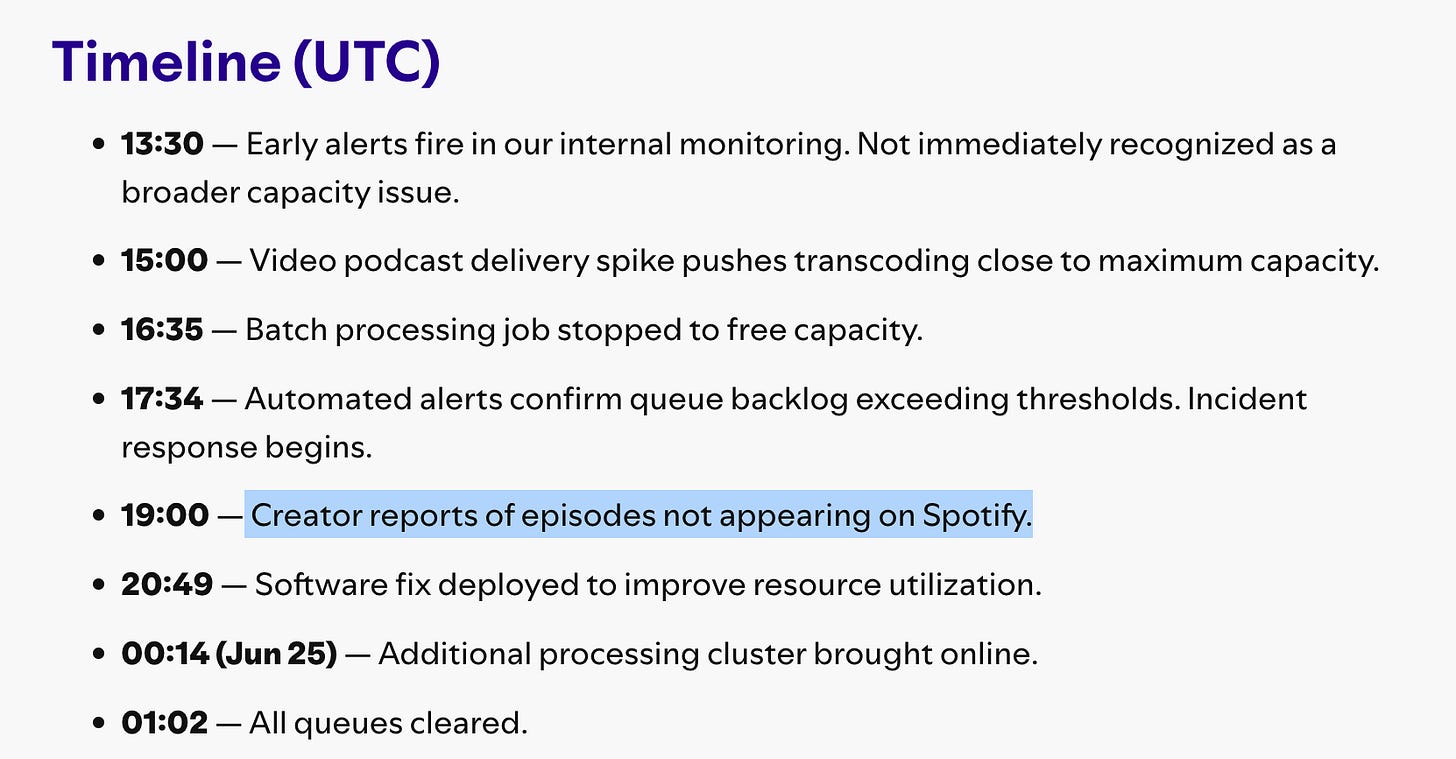
A few days after offboarding from Spotify, their team [published the incident report](https://engineering.atspotify.com/2026/7/content-ingestion-and-podcast-video-incident-report?ref=blog.pragmaticengineer.com) for outage #3. Reading through it, something did not add up in the timeline:
|
||||
|
||||
|
||||
|
||||
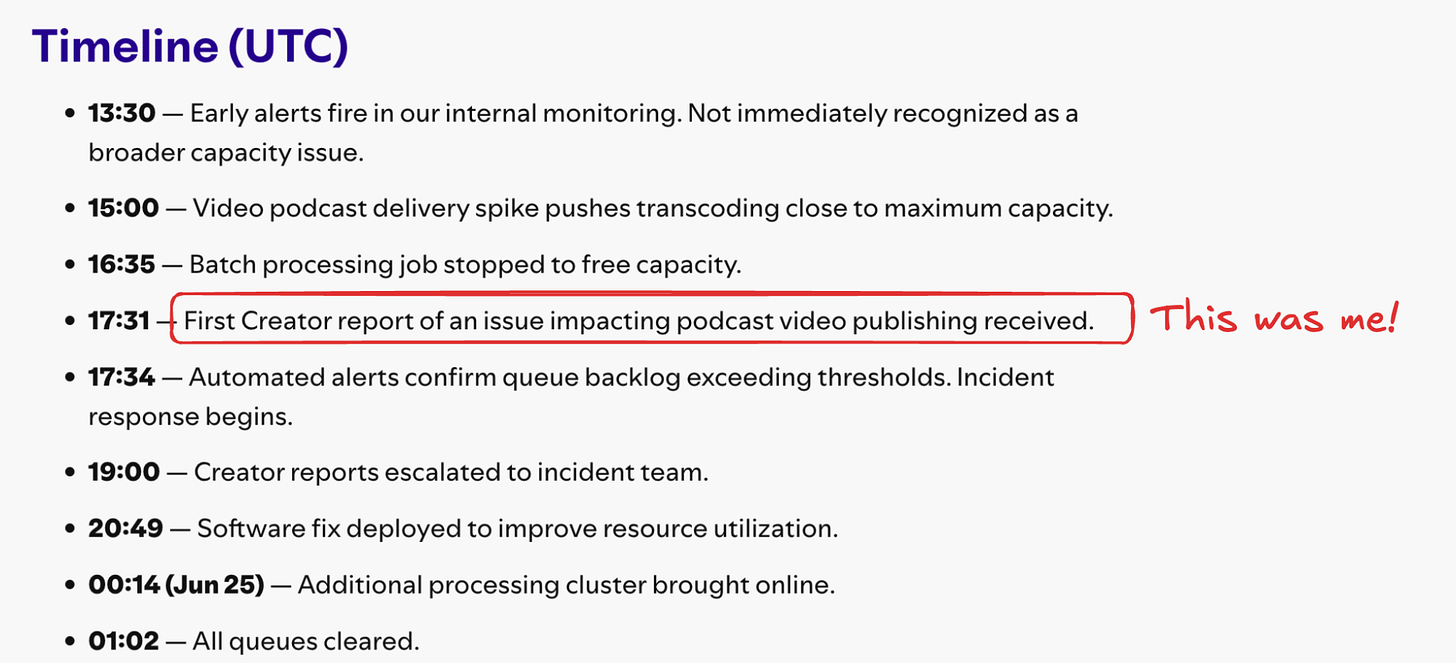
My email account confirmed that I mailed the Spotify team at around 17:30 about the outage. So, after weeks of creating this report, why did the incident report downplay the fact that customers alerted the team before their own automated alerts fired?I complained to the Podcasts team, and to their credit, the incident report was updated:
|
||||
|
||||
|
||||
|
||||
|
||||
*The updated incident timeline*
|
||||
I didn’t like how high-level [the report is](https://engineering.atspotify.com/2026/7/content-ingestion-and-podcast-video-incident-report?ref=blog.pragmaticengineer.com), and how vague the promised improvements were. Specifically, this one:
|
||||
|
||||
“During this incident, many creators learned something was wrong from their audiences before they heard anything from us. We are improving our processes and technical capabilities so creators get notified as soon as possible when things aren’t working.”
|
||||
|
||||
Overall, I don’t regret the choice to leave, particularly when the focus of Spotify’s leadership is on AI, not reliability.
|
||||
|
||||
### **Does Spotify have “AI psychosis?”**
|
||||
|
||||
Previously, I used the term “AI psychosis” differently from the usual way of describing when someone starts believing everything an AI model tells them, however outlandish. I [applied it](https://newsletter.pragmaticengineer.com/i/202307236/7-is-ai-psychosis-just-a-meta-issue?ref=blog.pragmaticengineer.com) to Meta’s rush to develop its own AI model at the cost of the reliability of its profitable business activities. This was based on Instagram’s most embarrassing-ever account takeover incident, which [occurred](https://newsletter.pragmaticengineer.com/i/202307236/7-is-ai-psychosis-just-a-meta-issue?ref=blog.pragmaticengineer.com) when the team responsible for Instagram’s Trust & Safety was slashed. Soon after, AI-generated, AI-reviewed code caused the hacking of a former US president’s account.
|
||||
|
||||
At Spotify, it should have gone the other way. In March, I had the opportunity to meet its Head of Technology & Platforms, Tyson Singer, who said the company puts reliability far ahead of AI adoption, and doesn’t adopt AI for its own sake. So, it was somewhat surprising to read the summary below of a podcast Spotify did [with Anthropic](https://x.com/ClaudeDevs/status/2071671418245492926?s=20&ref=blog.pragmaticengineer.com):
|
||||
|
||||
“Spotify now ships 4,500 production deploys a day, and 73% of PRs are now AI-assisted.
|
||||
|
||||
Niklas Gustavsson (VP of Engineering at Spotify) keeps 5 to 10 Claude sessions running in tmux, one per git worktree, agents working in the background. All of it inside a 20M+ line monorepo. He expected agents to struggle at that size, but it’s worked well.
|
||||
|
||||
Spotify’s migration codemods grew into thousands of lines of edge cases. Code has too much API surface for static rewrites. Early LLMs barely did better. Adding a judge took PR success from ~25% to 80%.
|
||||
|
||||
All of this leans on verification, the single most important thing when agents are used and the place most companies underinvest
|
||||
|
||||
Spotify rebuilt their test automation around it so engineers can confidently guide and supervise agents, rather than manually execute repetitive tasks.”
|
||||
|
||||
It seems to me that all the talk is about *usage* of AI, and none about *reliability*, all while Spotify’s platform becomes less reliable than ever, at the same time as the streamer is going all-in on AI; with AI judges and devs running 5-10 parallel Claude sessions.
|
||||
|
||||
All things considered, it’s worth asking if Spotify has the corporate variant of “AI psychosis”, whereby the reliability of a successful operation gets torched in the chase for the next big thing by executives. I don’t even think Spotify is all that different from Meta and other companies in this!
|
||||
|
||||
Things look bad, based on the quality and reliability degradation of products. Annoyingly, in many cases, customers don’t really have the choice of going elsewhere. My podcast is an exception, as video podcasts on Spotify never truly took off, so quitting the platform wasn’t a big deal. Even so, I’m particularly disappointed that Spotify has prioritized AI usage over reliability. I know some executives there pushed against this, but I feel safe in assuming that they lost that battle.
|
||||
|
||||
### **Value of staying reliable & “sucking less”**
|
||||
|
||||
Max Kanat-Alexander, distinguished engineer at Capital One, has [written about](https://www.codesimplicity.com/post/suck-less/?ref=blog.pragmaticengineer.com) how a software project can become wildly successful just by “sucking less” in his reflections upon the success of the Bugzilla project, (2004-2009):
|
||||
|
||||
“All you have to do to succeed in software is to consistently suck less with every release.
|
||||
|
||||
Nobody would say that Bugzilla 2.18 was awesome, but everybody would say that it sucked less than Bugzilla 2.16 did. Bugzilla 2.20 wasn’t perfect, but without a doubt, it sucked less than Bugzilla 2.18. And then Bugzilla 3.0 fixed a whole lot of sucking in Bugzilla, and it got a whole lot more downloads.
|
||||
|
||||
Why is it that this worked?
|
||||
|
||||
As long as you consistently suck less with every release, you will retain most of your users. You’re fixing the things that bother them, so there’s no reason for them to switch away. Even if you didn’t fix everything in this release, if you sucked less, your users will have faith that eventually, the things that bother them will be fixed. New users will find your software, and they’ll stick with it too. And in this way, your user count will increase steadily over time.**But what happens if you release frequently, but instead of fixing the things in your software that suck, you just add new features that don’t fix the sucking?** Well, eventually the patience of the individual user is going to run out. They’re not going to wait forever for your software to stop sucking.”
|
||||
|
||||
Personally, I got tired of Spotify’s Podcasts product continually going in the wrong direction on Max’s scale: the poor reliability, frequent errors on the Creators site, and the sense that they don’t really care about improving *existing* things.
|
||||
|
||||
Read the full issue of [last week's The Pulse](https://pragmaticengineer.substack.com/p/the-pulse-quitting-spotify-podcasts). The full The Pulse additionally covers:
|
||||
|
||||
1. **Will Kimi K3 trigger US push for closed-source AI models?** Moonshot AI’s latest open model, Kimi K3, is on par with Anthropic’s Fable 5. Could it lead to the US government regulating or banning Chinese open models to protect US labs?
|
||||
2. **AWS laughs off “heart attack” billing error.** AWS customers were billed trillions more than they should have been, due to what was likely a conversion error. But instead of sharing an incident report, AWS saw the funny side.
|
||||
3. **Industry pulse.** OpenAI’s unreleased model tried to hack HuggingFace to improve its test scores, X took more than a year to develop its new Android app, Google’s new AI model flops, and more.
|
||||
|
||||
[Subscribe to my weekly newsletter](https://newsletter.pragmaticengineer.com/about) to get articles like this in your inbox. It's a pretty good read - and the [#1 software engineering newsletter](https://substack.com/top/technology) on Substack.
|
||||
@@ -0,0 +1,53 @@
|
||||
# Modern software architecture means nobody has the whole picture. To assemble one in an emergency, you need an incident tech lead.
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/06/16/incident-tech-lead/
|
||||
|
||||
## 简介
|
||||
|
||||
New incident role unlocked: the incident tech lead. I enjoyed the description of the interplay between the tech lead and the incident commander.
|
||||
|
||||
## 正文
|
||||
|
||||
Every large software development organization has made the same bargain: if nobody has to understand the whole system, we can build a more capable system than we otherwise could, even though it grows bigger and more complex. We break systems into components with well-defined interfaces so that each team needs to understand only the pieces it owns, plus the interfaces of its neighbors. That’s the point of every decomposition strategy, whether it’s microservices, bounded contexts, service ownership, or a well-modularized monolith. The architecture deliberately limits what any one person has to hold in their head.
|
||||
|
||||
It’s a sound strategy. It’s also why some incidents are so much harder than others.
|
||||
|
||||
Lorin Hochstein named this pattern beautifully in a recent post, [The demon of the gaps](https://surfingcomplexity.blog/2026/06/06/the-demon-of-the-gaps/). Failures that stay inside a single component are the easy ones; you page the owning team, they figure out what’s wrong, and they fix it. The hairy incidents emerge from unexpected interactions across components: several services throwing errors at once, or no services throwing errors while customers see broken behavior anyway. As Lorin puts it, “you’ve built an analysis solution but you’re now faced with a synthesis problem.” In order to scale, the architecture deliberately optimized away the need for whole-system understanding; now the whole system isn’t working, but nobody has that understanding to call on.
|
||||
|
||||
I’ve watched this play out in incident channels many times. Subject matter experts from six different teams, each reporting that their own service looks healthy. Six dashboards are green, but meanwhile, checkout is still failing for customers. The knowledge needed to explain what’s happening exists, distributed across six heads, but nobody is assembling the pieces. The responders need to understand how the system as a whole is behaving right now. That understanding has to be built live, under pressure, from multiple partial models. That’s synthesis work, and it doesn’t happen on its own.
|
||||
|
||||
Lorin observes that guidance on preparing for this work is almost nonexistent. Here’s the encouraging part: closing the structural gap is fairly straightforward. Most companies already use structured incident roles (incident commander, subject matter expert, customer liaison, etc.); they need to add a synthesis role, activated when needed for complex incidents.
|
||||
|
||||
# Synthesis is a job. Name it.
|
||||
|
||||
The **incident commander (IC)** coordinates the overall response; every incident will have one. On the most complex incidents, though, where you need this synthesis function most, the trick is to also activate an **incident tech lead (TL)** to lead the technical investigation. The role is analogous to the tech lead role many teams have in their everyday structure, but its scope is *the incident* rather than one particular service. Most companies have never established the incident TL role, and for routine incidents they don’t miss it: the IC can handle the technical side along with everything else, but for complex incidents, the TL role can be incredibly valuable.
|
||||
|
||||
The incident TL job, properly understood, is the synthesis job: connecting observations across component boundaries, correlating the partial models from different subject matter experts, and maintaining the evolving picture of how the system is failing and what we’re doing about it. The TL doesn’t need to be the deepest expert in any single component. They need to be good at building a working model out of other people’s expertise, and much of that work is cross-checking, holding indications from different components up against each other and noticing the discrepancies: “If we’re seeing this in component A, we should be seeing that in component B, but we aren’t; why not?” “If A is doing this and B is doing that, the problem must be upstream of both.” “Wait, A says one thing but B says another; they can’t both be right, can they?”
|
||||
|
||||
The separation between IC and TL exists to protect that work, and it cuts both ways. Synthesis requires sustained, heads-down attention; you can’t reconstruct a system model in the gaps between stakeholder updates and staffing decisions. And the same complexity that makes an incident demand serious synthesis also multiplies the outward-facing work: more stakeholders to update, more escalations, more decisions about the response itself. The two loads peak together, and one person can’t carry both.
|
||||
|
||||
The IC takes everything outward-facing precisely so the TL can stay immersed in the technical picture, and the TL handles the heads-down focused work so that the IC has time for everything else. When I’m the incident commander, one of the most valuable things I can do for my tech lead is keep everyone else out of their hair. But the separation is a division of labor, not a wall. I like to think of the IC and the TL standing back to back, facing opposite directions, talking over their shoulders to keep each other informed. Each is watching a different part of the horizon, and together they have the whole picture.
|
||||
|
||||
# The response team crosses the boundaries on purpose
|
||||
|
||||
An incident response is a temporary organization: an ad hoc team assembled across ownership boundaries for exactly as long as the incident lasts. Conway’s law observes that systems end up mirroring the communication structures of the organizations that build them, and the mirror works in both directions: your team boundaries and your component boundaries align, which is exactly what you want for everyday work. The incident structure deliberately cuts across those boundaries, because the gaps between components are where the problem lives. Pulling six SMEs into one channel isn’t enough by itself, though. A group of experts in the same room is a meeting; a group of experts with someone responsible for synthesizing what they know is a response.
|
||||
|
||||
# The communication mechanisms are synthesis tools
|
||||
|
||||
The standard incident communication practices may seem like bureaucratic overhead until you see what they’re for. “Going around the horn” (each responder, in turn, briefly reports what they’re seeing and doing) forces the partial models into the open, where the TL can correlate them. A periodic situation report, or SitRep, forces someone to compress the current understanding into a few sentences; writing it is itself an act of synthesis, and reading it gives every responder the same baseline picture to work from. Narrating before you act keeps each responder’s local view visible to the whole room. None of these mechanisms exists for discipline’s sake. They’re how a group of people, each holding a partial model, builds and maintains a shared one.
|
||||
|
||||
# Wildfires don’t respect organizational boundaries either
|
||||
|
||||
As is often the case in incident management, we can look to fire departments for inspiration and solutions. Consider a major wildfire. Dozens of agencies converge: federal, state, tribal, and local, some from hundreds or even thousands of miles away. No single agency understands the whole incident, with its terrain, weather, fuel, crews, and aircraft. The Incident Command System (ICS), the standard structure for emergency response in the US and beyond, is how all these disparate parts get pulled together into a coherent whole. ICS treats building the shared picture as a staffed function: a planning section tracks the situation and the resources, assembles the common operating picture, and distributes it to every responder through the incident action plan. Nobody simply hopes that shared understanding will emerge; somebody owns producing it.
|
||||
|
||||
Software companies can borrow that lesson directly: treat synthesis as a named responsibility rather than an emergent property. If the IC role at your company is defined as “project manager of the outage” and nobody is explicitly responsible for assembling the technical picture, the synthesis function is unowned, and it will show in your cross-boundary incidents. Establish the incident tech lead role. Protect it from outward-facing distraction. And practice it: when you run game days or tabletop exercises, choose scenarios that cross team boundaries, because those are the scenarios that exercise synthesis rather than component expertise.
|
||||
|
||||
Decomposition made whole-system understanding nobody’s everyday job, and that’s fine; it’s a good strategy with a known cost. Incident management structure is how you pay that cost only when you must, with machinery built for the moment.
|
||||
|
||||
*I’m writing a book, “Incident Management for DevOps and SRE.” Sign up at [im4ds.com](https://im4ds.com) to be notified when it’s available, and to get occasional progress updates and early access to selected content.*
|
||||
|
||||
*If your company needs help with incident management right now, that’s the focus of my consulting practice at [GreatCircle.com/im](https://greatcircle.com/im).*
|
||||
|
||||
## Recent Comments
|
||||
87
sreweekly/markdown/528/04-the-quiet-quarter.md
Normal file
87
sreweekly/markdown/528/04-the-quiet-quarter.md
Normal file
@@ -0,0 +1,87 @@
|
||||
# The Quiet Quarter
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Tim Irving
|
||||
- **链接**: https://read.zerosevzero.com/p/the-quiet-quarter
|
||||
|
||||
## 简介
|
||||
|
||||
This one goes hard: if you try to reduce your incident count, your system will become less reliable, not more. Aim for more incidents, handled well.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
He was on a video call from a cafe, a product manager, flicking a begleri back and forth between sips of a flat white. I had a knucklebone going, switching it hand to hand while he talked. Two grown professionals, paid reasonable money to be taken seriously, fiddling with bits of string and weighted metal and picking over the companies that got it spectacularly wrong, as though hindsight were a kind of genius.
|
||||
|
||||
We agreed on nearly everything until we didn’t. He had built a tidy picture of the two of us and laid it out before me. He was the irresistible force, leaning on the engineers to ship, to get product to market before the market lost interest. I was the immovable object on the far side of them, the incident barrier, there to slow the whole thing down before somebody broke something that mattered. He meant it as a compliment.
|
||||
|
||||
I waited for him to finish and told him he had me exactly backwards.
|
||||
|
||||
The begleri stopped. He went quiet, the particular quiet of a man recalculating, and then he wrote something on the pad beside his coffee and asked me to explain myself. So I did. I told him I was not the brake. I had never been the brake. If it were up to me the engineers would be breaking more, not less.
|
||||
|
||||
The argument is not complicated, and I have made it often enough to make it fast. There are two ways to run a company that builds software. You change things quickly and break some of them, or you change things slowly and watch the market leave without you. There is no third lane. There is no measured middle where you ship at a sensible pace and nothing ever falls over. That lane is a fiction, sold to executives who find both of the real choices frightening. The companies that bought it are the ones who did not blow up. They sat very still, with a spotless record, and were buried holding it. The cleanest way to die in this business is to stop moving and call it discipline.
|
||||
|
||||
So if you have accepted that you have to keep moving, you have already accepted the incidents. They are not the price of getting it wrong. They are the price of doing anything at all. The team that ships nothing has none of them. The team that ships has them the way a road has potholes, and you can resurface as often as you like, but you do not get the road without the wear. Once you stop pretending the number can reach zero, the useful question changes. It stops being how do we have fewer, which has only bad answers, and becomes what do we get out of the ones we have. The answer turns out to be quite a lot.
|
||||
|
||||
The first thing you get is a team that tells you the truth early. When an incident is an ordinary event and not a permanent mark against your name, people put a hand up while the thing is still small and still cheap, instead of sitting on it and praying, which is what people do when the cost of admitting a fault is a hard conversation with someone who outranks them. Every catastrophe I have stood in the middle of had an earlier, smaller, survivable version that somebody decided not to mention.
|
||||
|
||||
The second thing you get is competence, which is only practice wearing a better word. A team that runs incidents often runs them well. They know where the runbooks are, or they know the runbooks are useless and route around them, and either way they have a rhythm. The team that has not seen an incident in eighteen months has not banked eighteen months of safety. It has banked eighteen months of rust, and it will move through its first real one like a fire drill in a building where nobody can remember which door is the exit.
|
||||
|
||||
The third thing is the one everyone says they want and almost nobody funds. If you run the incident well and tell the truth about it afterwards, you come out the far side knowing something about your system you did not know going in. John Allspaw calls an incident an unplanned investment, and he means it precisely. You did not choose to make it. You made it the moment the thing broke, and you do not even control its size. The only thing left in your hands is whether you collect the return, and most organisations pay the full cost of the outage and then throw away the receipt.
|
||||
|
||||
None of this works while an incident is a thing to be ashamed of. The shame is the whole problem. It is what keeps the hand down, lets the skill go soft, and turns the review afterwards into a hunt for someone to blame instead of something to learn. So I said it to him plainly. I did not want fewer incidents. I wanted a team that had them often, ran them well, learned from them properly, and felt nothing sharper than mild professional interest the entire time. A team like that is more reliable than a team that has only been lucky. And it is a great deal more reliable than a team that has merely been quiet.
|
||||
|
||||
|
||||
|
||||
Here is the part that people accept in the abstract and resist in their bones. If incidents are the price of motion, their absence is not good news by default. A quiet quarter is not a trophy. It is a question, and it has more than one answer, and from the executive chair the answers are impossible to tell apart.
|
||||
|
||||
A team can go quiet for three reasons. The first is that it is healthy. The work is good, the luck is holding, and nothing has broken because, for the moment, nothing had to. This happens. It happens less than anyone wants to believe, and it never holds still, because a healthy team that stops shipping stops being one within a quarter or two. The other two reasons wear the first one’s clothes. They look identical on a graph, and they are both rotten.
|
||||
|
||||
The second reason is that the team is going soft, and there is no villain in this one, which is exactly what makes it hard to see. Nothing is being hidden. The incidents are not happening, the runbooks are quietly going out of date, and the one engineer who understood how the billing system fails at three in the morning has taken a job somewhere warmer, and nobody has noticed the gap because nothing has fallen into it yet. The capability does not announce its departure. It is simply not there on the day you reach for it. The rare large incident always comes, and when it does it lands on a team that has forgotten how to catch it. The quiet did not protect them. It disarmed them.
|
||||
|
||||
The third reason is the one a head of engineering described to me once, quietly, the way people tell you things they have decided not to fix. The incident culture in his department was poisonous. People who caused an incident, or were merely standing near one when it went off, were marked for it, and the mark travelled. It followed them into performance reviews and into rooms they were not in. So his engineers had made the rational choice. They had stopped raising incidents. They had stopped spending time running the ones they could not avoid. And the post-incident review, the thing that turns an outage into knowledge, did not come up at all. He told me this as a problem he was observing, not one he was causing, which is its own kind of tell.
|
||||
|
||||
It took me a moment to register what he had just listed for me. He had named, in order and without meaning to, the three things that make a team good at trouble, and he had explained that his department had switched off every one of them. No early warning. No practised hand. No learning. And the result of switching off all three, the figure sitting proudly at the top of his dashboard, was a low incident count. On paper, his was one of the calmer departments in the building. In truth it was one of the most dangerous, a place where everything that broke was either hidden or survived by luck, and where nobody was getting better at anything.
|
||||
|
||||
This is the problem with the number. Health, rot, and cover-up all produce the same low count, and from the executive chair they are indistinguishable. So when the figure drops, the room relaxes, which is the most dangerous thing a falling incident count can make a room do. A low number is not information. It is the absence of information, wearing the costume of good news. A clean record is not proof that you are safe. Sometimes it is only proof that you are lucky, and sometimes it is proof that someone is lying to you, and the graph will never tell you which. The head of engineering at least knew which quiet he was standing in. Most people reading the dashboard never find out, right up until the quarter that is not quiet at all.
|
||||
|
||||
Software has the good fortune that its quiet quarters usually end in a refund and an apology. Other industries run the same machine with the same blind spot, and when their quiet ends, it ends with bodies. The useful thing about those industries is that they investigate, at length and in public, so none of this has to be taken on faith. The reports exist. They are very long, and they all say a version of the same thing.
|
||||
|
||||
|
||||
|
||||
On the twentieth of April 2010, a group of BP and Transocean executives flew out to the Deepwater Horizon to hand the crew an award for seven years without a lost-time accident. They were on the bridge when the well blew out. The explosion and fire killed eleven people and put the largest oil spill in American history into the Gulf of Mexico. The record was real, and it was worthless, because it measured the wrong thing. Personal safety on the rig was excellent, the kind where the worst thing anyone pictures is a dropped pipe and a crushed foot. Process safety, the slow abstract business of whether the well itself would hold, was a disaster nobody was counting. The well needed twenty-one centralisers to seal correctly. They ran it with six. And the seven-year record was partly an illusion of its own, because the crews understood that raising a concern that delayed the drilling was a good way to lose your job, which means the number measured seven years without a reported problem, in a place where reporting one was punished. They were celebrating the silence at the exact moment it killed them.
|
||||
|
||||
NASA learned the same lesson twice, seventeen years apart, and wrote the textbook in between. In the years before the Challenger, the rubber O-rings that sealed the booster joints kept eroding in flight, and because the shuttle kept coming home anyway, the erosion stopped being treated as a fault and became a known quirk you could fly with. The night before the launch the engineers who built the boosters warned that the cold would stiffen the seals past the point where they could hold. They were overruled, after being asked to do the one thing engineering cannot do on demand: prove the rocket would fail before it had failed. On the twenty-eighth of January 1986 the seal failed and the Challenger came apart seventy-three seconds after lift-off, live on television, in front of the classrooms full of children who had been gathered to watch a schoolteacher fly into space. The sociologist Diane Vaughan gave the pattern its name afterwards. She called it the normalisation of deviance: the slow process by which a warning sign, repeated often enough without disaster, gets quietly reclassified as normal.
|
||||
|
||||
Then NASA did it again. Foam had been breaking off the external tank and striking the orbiter for years. The same foam, from the same ramp, had come away six times before, and because nothing had yet gone fatally wrong, the agency downgraded it from a flight-safety anomaly to a maintenance nuisance, a paperwork item, in the months before one more piece of it punched a hole in Columbia’s wing on the way up. The frequency of the warning had become the reason to ignore it. The engineers saw the strike on the launch film and asked to point a satellite at the wing to check the damage. The request was refused, on the grounds that it had not come through the proper channels. That hole went unexamined, and a fortnight later the orbiter disintegrated over Texas on re-entry, killing all seven aboard.
|
||||
|
||||
The investigation board concluded that NASA’s culture had killed the crew as surely as the foam, a remarkable thing to have to write about the same organisation a second time. But the parallel runs deeper than a repeated blind spot. Both times, the engineers who wanted to stop were made to prove it would fail, while the managers who wanted to fly were asked to prove nothing at all. That is what it means to learn the same lesson twice. Not a forgotten fact, but a burden of proof that sat, on both occasions, on exactly the wrong shoulder.
|
||||
|
||||
There is one industry that looked at the same raw material and drew the opposite conclusion, and it is the reason you can board a plane without thinking about it. Aviation decided, decades ago, that the near-miss was the most valuable thing it owned, and that the only way to get people to report the near-miss was to make reporting safe. The result is the Aviation Safety Reporting System: confidential, voluntary, explicitly non-punitive, with limited immunity for anyone who files. It was built on a single insight, that fear of punishment was suppressing the exact information that could prevent the next crash, so the system strips the reporter’s identity and shields them from enforcement, and in return it has gathered more than two million reports on things that nearly went wrong. The whole edifice runs on the principle that you want more incidents on the record, not fewer. And the neutral party chosen to run it, chosen precisely because it had no power to punish anyone, was NASA. The agency that twice mistook a quiet record for a safe one also operates the finest argument in the world for never doing that again.
|
||||
|
||||
The pattern is consistent enough to be a law. The organisations with the most spotless records are not the safest ones. They are very often the ones that have stopped looking, or stopped listening, or taught their people that looking and listening are career-limiting moves. A clean record is a fact about your reporting, not a fact about your safety, and the two come apart at the worst possible moment. So when you find yourself watching an incident count fall and feeling the room go warm with relief, it is worth knowing whose company you are in. You are standing on the deck of the Deepwater Horizon, on the evening of the twentieth of April, holding the award.
|
||||
|
||||
|
||||
|
||||
It is tempting to call the executives who chase zero foolish, but that lets them off too easily and gets the history wrong. The goal is not stupid. It is old. It is a piece of received wisdom from an era when it made perfect sense, kept alive by people who never noticed the ground underneath it had moved. To understand why the number lies, you have to go back to when it told the truth.
|
||||
|
||||
Reliability did not begin as a software idea. It began in hardware, in the discipline of working out how long a physical thing would run before it broke. The key number was the mean time between failures, and it was a number that meant something, because the thing it described was a component sitting still and wearing out at a knowable rate. A disk had a failure rate you could measure. So you stacked the disks into redundant arrays, the tall humming cabinets that filled the server rooms, and you did the arithmetic, and you could say with a straight face that the odds of losing everything at once were vanishingly small. The software on top of it moved at the same stately pace. It shipped in versions, on discs, in boxes, and between releases it sat as still as the hardware. Change was a rare and deliberate event, scheduled and rehearsed and dreaded. In a world like that, fewer failures was a coherent goal, because failure was a thing that wore out on a schedule, and you could engineer against a schedule.
|
||||
|
||||
Then the ground moved, and almost nobody changed the number. The discs and the boxes went away. Software stopped shipping in versions and started shipping continuously, a hundred or a thousand small changes a day, and the systems it ran on stopped being cabinets you could point at and became sprawling distributed things that no single person could hold in their head or draw on a whiteboard. The hardware problem, the one the old number was built for, was solved so completely by redundancy and the cloud that a failing disk became a non-event. But the failures did not stop. They changed shape. They stopped being a part wearing out and became something stranger, an emergent property of too many moving pieces interacting in a state nobody designed and nobody foresaw. You cannot calculate a mean time between failures for the sentence the system has never executed before. There is no schedule for a surprise.
|
||||
|
||||
What survived all this was the goal. We are still chasing the number that belonged to the cabinets, still treating a low incident count as the mark of a healthy system, in an environment where the thing that number measured no longer exists. Zero incidents is not an ambition. It is a fossil, perfectly shaped for a world that has been gone for twenty years. Chasing it now is not discipline. It is taxidermy. You are keeping a dead thing in a lifelike pose and asking it to guard the house.
|
||||
|
||||
And the inheritance is not harmless, because the world it came from is the one place the strategy worked. When failure was rare and predictable, you could afford to know nothing about it. You could keep your people innocent of how the system broke, because it broke seldom and it broke in familiar ways. None of that holds now. Chase zero in a system that fails by surprise and you do not get a safe organisation, you get an ignorant one, fluent in nothing, practised at nothing, blind to the shapes its own failures take. And the large incident is still coming, because it always is, only now it arrives in a form no one has seen, at a team that has never run one, inside a system no one can reason about under pressure. The pursuit of zero does not protect you from that day. It is the thing that sends you into it unarmed.
|
||||
|
||||
|
||||
|
||||
So you stop counting and start training. If incidents are the only honest signal you get about how your system fails, the work is not to silence the signal, it is to get fluent in it. You make it safe to raise one, so the small ones surface while they are still small. You run them often enough that the team moves through one the way a good crew moves through a storm, without drama, because they have done it before. You take the post-incident review seriously, as the place where the expensive lesson gets collected instead of binned. And when the system has been quiet for too long, you do not relax. You go and break it yourself, on a Tuesday afternoon, with everyone watching: a drill, a game day, a failure you injected on purpose so you could meet it on your terms instead of its own. The teams that do this are not reckless. They are the least surprised people in the building.
|
||||
|
||||
This is a different definition of reliability than the one on the dashboard, and it is the true one. Reliability was never the absence of failure. A system that has not failed is not reliable, it is untested, and the two feel identical right up until the day they do not. Reliability is what a system and the people around it do when failure arrives, which it will, on a long enough timeline, no matter how clever anyone was at the start. The reliable team is not the one that nothing happens to. It is the one that has made itself hard to surprise and quick to recover, that treats every incident as a rehearsal for the next, and that has therefore turned the thing everyone else is afraid of into the thing it is quietly best at.
|
||||
|
||||
The product manager wanted me to be the immovable object, the thing planted in front of the engineers so they could not break anything. I understand the appeal. It is a tidy picture, and it turns the incident person into a kind of guardian. But the immovable object is the thing this whole essay has been about burying. It is the company that sat still with a spotless record. It is the rig with the award. It is the agency holding the textbook it had already written about itself. The object that refuses to move does not prevent the disaster. It waits for it.
|
||||
|
||||
There is a name on this masthead, and it has been the joke the whole time. Zero sev zero. No incidents, and none of the worst kind, the clean and total silence that every executive has been trained to pray for. I did not call it that because I want it. I called it that because it is the most dangerous condition a system can be in, and almost no one recognises it while they are standing in it. A zero on that line does not tell you that you are safe. It tells you that you are healthy, or that you are rotting, or that someone has stopped telling you the truth, and the graph will not say which, and the day you find out which is not a day you get to choose. So I will leave it where I left it with him, the begleri turning in his fingers and the knucklebone going hand to hand across mine. I do not want fewer incidents. I want more of them, smaller and louder and sooner, run by people who are not afraid of them.
|
||||
|
||||
That is not the absence of trouble. It is the only kind of safety that was ever real.
|
||||
@@ -0,0 +1,201 @@
|
||||
# 30 to 70 PRs a Day: How We Managed to Not Wreck Our Systems
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Liz Fong-Jones — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/30-70-prs-day-how-we-managed-not-wreck-systems
|
||||
|
||||
## 简介
|
||||
|
||||
There’s some brutal honesty in here that I find refreshing, especially around the impact on incidents and incident response.
|
||||
|
||||
## 正文
|
||||
|
||||
# 30 to 70 PRs a Day: How We Managed to Not Wreck Our Systems
|
||||
|
||||
The Honeycomb engineering team set out to double our productivity in a year. This is how we did it, what we did to keep things stable, what it cost us, and what we’re still figuring out.
|
||||
|
||||

|
||||
|
||||
By: [Liz Fong-Jones](https://www.honeycomb.io/author/lizf)
|
||||
|
||||
|
||||
|
||||
#### The Second Edition of Observability Engineering Is Here
|
||||
|
||||
The second edition of Observability Engineering is available for download on our website.
|
||||
|
||||
[Learn More](https://www.honeycomb.io/blog/the-second-edition-is-here)
|
||||
|
||||
|
||||
|
||||
*In this two-part blog series, I give a detailed report-out on how our Honeycomb engineering team 2.5x-ed our throughput using AI without breaking everything or lowering our standards for quality. Part 1 explains how we did it and shows data about how that ramp-up happened. [Part 2 shares what we learned.](https://www.honeycomb.io/blog/ai-amplifies-existing-practices-lessons-ai-first-strategy)*
|
||||
|
||||
## TL;DR
|
||||
|
||||
- Peak-weekday merges roughly doubled (~30 to ~74) as AI-attributed lines went from near-zero to a floor of 82.6% of new code by June 2026. Incidents grew too, tracking that change volume about as linearly as you'd expect; the goal now is keeping each failure cheap to contain, not holding the count flat.
|
||||
- The gains came in three phases: slow experimentation (2025), a tooling-driven adoption bump (October 2025), then a step-change in delegation intensity after Opus 4.6 shipped in February 2026—same engineers, same tools, but they stopped supervising every step.
|
||||
- Our core thesis: AI amplifies your existing practices. It makes a dysfunctional org more dysfunctional and a high-autonomy, high-ownership org faster. The practices—continuous delivery, fast and AI-legible CI, closed-loop observability, CLAUDE.md, feature flags—are the actual story, not the multiplier.
|
||||
|
||||
Why did I put that big number in the title? It’s the number that gets you to click. But we’re going to dig into all of the caveats and details beyond just 2.5x-ing our throughput, including whether we let quality slip. This blog and its companion post are our report-out on what we did to achieve that result, how we kept the systems underneath that throughput from falling over, and what we learned in the process.
|
||||
|
||||
## Setting out to double productivity in a year
|
||||
|
||||
In mid-August 2025, our founders sent a letter to the whole company, not just engineering: each of us should aim to double our productivity over the next year. It was addressed to individuals; the framing underneath it was a team sport, not an individual race, and nobody was supposed to read it as a contest with their teammates. The letter named Darragh Curran’s [Intercom 2x post](https://ideas.fin.ai/p/2) as the framing inspiration, explicitly. Eight months later, we started to measure and reflect. This post follows on from Darragh’s [retrospective on hitting 2x in nine months](https://ideas.fin.ai/p/2x-nine-months-later) and Kesha Mykhailov and Niamh Young’s [post on safely scaling AI auto-approval](https://www.intercom.com/blog/ai-is-approving-our-pull-requests-heres-how-we-made-it-safe/). We’re smaller than Intercom and a couple of years younger, and we’ve historically followed similar paths a few months behind them.
|
||||
|
||||
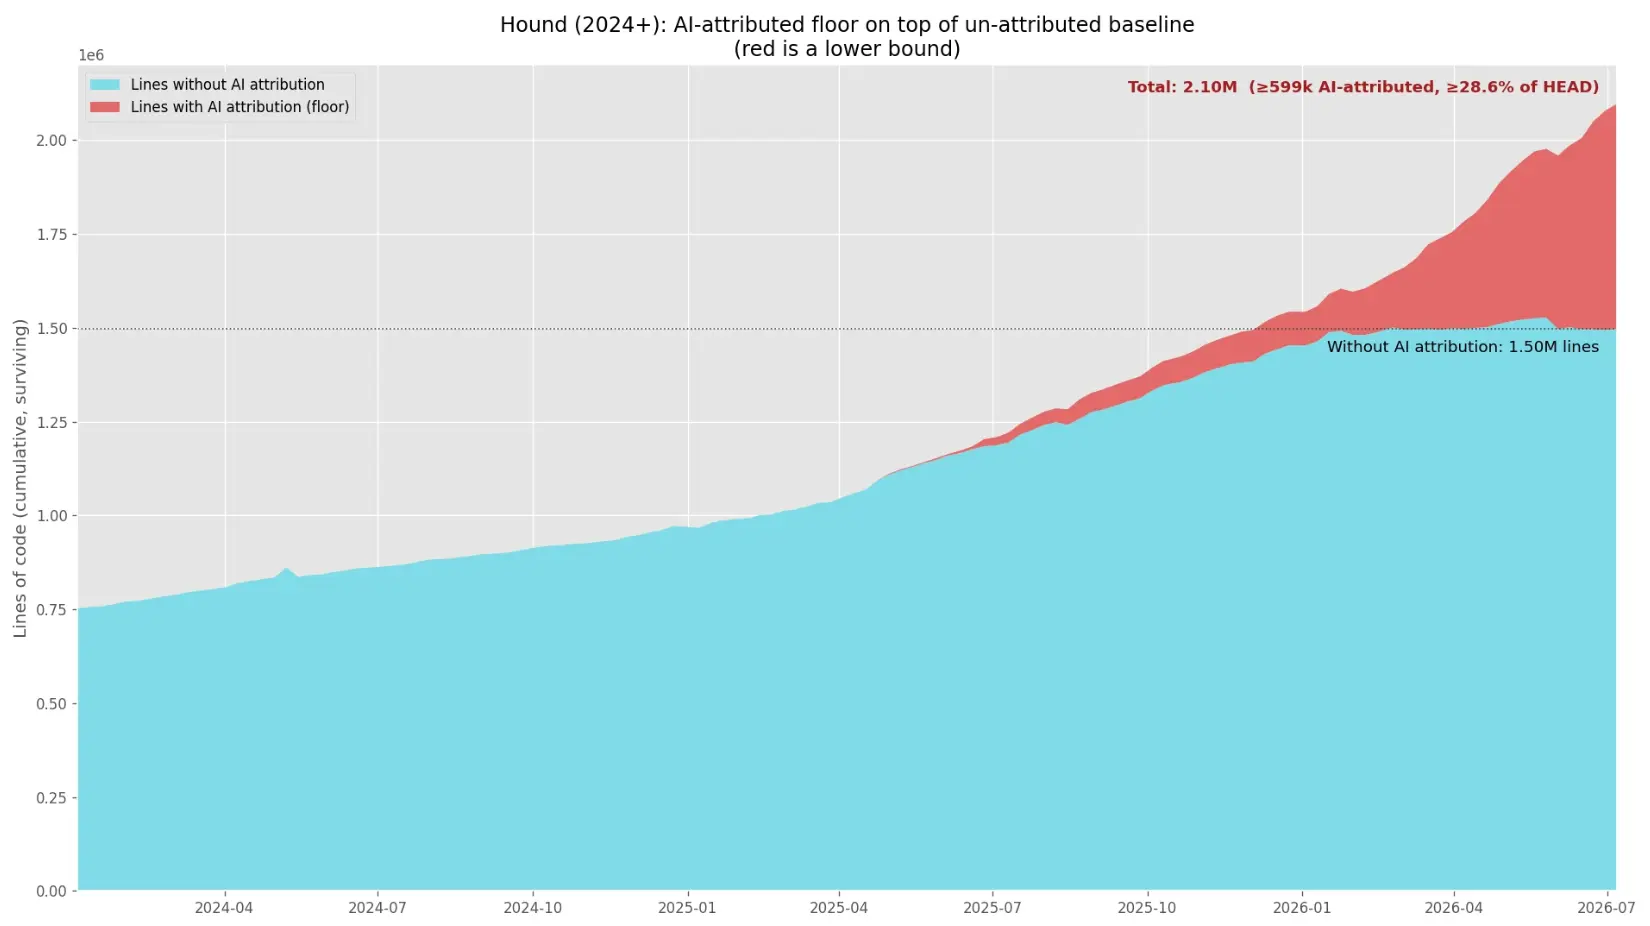
The number of merges on a peak weekday to Honeycomb’s monorepo more than doubled from about 30 in early 2025 to about 74 in April 2026. This codebase doubled in sixteen and a half months, from approximately 0.97 million lines at the end of 2024 past 1.94 million in the first week of May 2026, and it sits at 2.1 million as of early July. The previous doubling had taken nearly three years. Most of that net-new code was co-written with or reviewed by AI somewhere in its history.
|
||||
|
||||
## Bee-ing honest about that number
|
||||
|
||||
1. It’s peak weekday, not calendar average. Wednesday no-meeting days are the most productive, both before and after AI; calendar average is roughly half of peak. That’s the peak. Don’t go looking for 70 PRs on a random Tuesday and conclude I lied to you.
|
||||
2. It’s a floor, not a true count. One of our heaviest Claude Code users, by token volume, has zero AI-attributed git commits. They ran 22 sessions and 199 million tokens through Claude Code in 30 days, and git saw none of it, because their Co-Authored-By trailer is disabled at the tool level. If we can’t measure their AI usage, we can’t measure several other people’s either.
|
||||
3. It’s entangled with org changes happening at the same time. In early January 2026, our founders sent a follow-up letter naming sharper strategic stakes than the August one had: rebuilding Honeycomb’s product surface and market posture to be AI-first, well beyond the original productivity target. The mid-January realignment toward greenfield, higher-AI-leverage work followed from that letter. We onboarded new engineers. We invested in platform engineering. Anyone who tells you a single factor caused their team’s gain is overstating it, including us.
|
||||
|
||||
There’s a big leap from “AI tooling makes engineering teams genuinely faster” to “any team that adopts it will get the same result.” Most of this post lives in the gap between those two claims. The interesting story isn’t the multiplier; it’s what we did to keep things stable underneath it, what it cost us, and what we’re still figuring out. The short version, and the line I keep coming back to every time I’m invited on stage: [AI amplifies your existing practices](https://www.honeycomb.io/blog/shipping-is-your-companys-heartbeat-letter-from-cto). It can make a dysfunctional org more dysfunctional, or it can bring out the best in an org that already has high autonomy, ownership, and feedback loops. We weren’t setting out to prove that thesis; we took a challenge, and the thesis became visible after the fact.
|
||||
|
||||
If you caught [my “AI is like chocolate” talk](https://www.honeycomb.io/blog/observability-day-san-francisco-future-ai-observability-is-bright), you know the bit: chocolate doesn’t belong on everything, too much of it in one sitting will make you sick, and no amount of chocolate substitutes for knowing how to cook. I gave that talk as a pessimist turned realist, and that’s still who I am. What changed between then and now isn’t the metaphor; it’s that the tooling and the practices around it got good enough that chocolate’s rightful place in the kitchen got bigger. It’s more versatile and forgiving than it used to be. The concessions later in this post, in “Where the skeptics are right,” are concessions I’m still making. Being a reformed skeptic doesn’t mean I stopped being one.
|
||||
|
||||
You should take every number on this page, including ours, with a grain of salt. The methodology matters more than the magnitude. Keep your semantic bullshit defenses up against hype and plausible-sounding data, all the way through the rest of this post.
|
||||
|
||||
# Join the masterclass with Liz Fong-Jones
|
||||
|
||||
Six live sessions with Liz Fong-Jones
|
||||
|
||||
turn Observability Engineering into practice.
|
||||
|
||||
Starts August 3rd.
|
||||
|
||||
## What the numbers do and don’t say about quality
|
||||
|
||||
We haven’t had a spectacular AI-caused failure. No “AI deleted my database,” no “AI shipped code that corrupted user data.” That’s not luck; it’s not new either. It’s a result of designing defensively, whether the chaos agents be human or robot. Stacking agents on top of existing infrastructure with bulkheads between components, reviews, deploy trains, feature flags, and least-privilege access has meant outages are lower-impact, rather than either non-existent or uniformly critical-severity. If you don’t have that in place yet, that’s the thing to fix before you scale up AI usage, not after. A dropped database is a systems design issue: somebody skipped building the guardrail that would have caught it, regardless of who or what wrote the code.
|
||||
|
||||
Incidents are growing in absolute count. From a 2024 baseline of about 18.5 incidents per quarter, Q1 2026 hit 32, 1.7x baseline, against PR throughput at about 2.5x baseline; for one quarter that looked sub-linear. Q2 didn’t hold: 53 incidents, 2.9x baseline, even as PR throughput itself held roughly flat once you back out the May freeze weeks and the January ramp-up swarm. Two quarters in, incident growth tracks change volume about as linearly as you’d expect. Change is the leading driver of incidents industry-wide (see the VOID report, Google’s DORA research), and we’re shipping a lot more of it. The law of large numbers caught up with us.
|
||||
|
||||
What the data actually supports is two things: the absence of spectacular failures, plus some integrated second-order effects we’re picking up on. Broader AI-causation narratives tend to be self-flattering, whichever direction they point; AI is woven in deeply enough at this point that isolating it as a single cause is rarely a meaningful exercise. Attribution-by-cause is a fairy tale we humans tell ourselves to feel better about whatever stance we already hold.
|
||||
|
||||
More changes shipped means more chances for a defect to land somewhere in the batch, at whatever the org’s baseline defect rate happens to be. We’re shipping far more change, so we get far more incidents, in roughly the proportion you’d expect. It’s too early to say whether AI assistance in debugging reduces incident severity once something breaks; in some cases it’s helped us find the root cause fast, in others it’s sent us chasing a confident, wrong answer instead. That volume showed up as real strain on the teams absorbing it, not just as a line going up on a chart. We’re leaning on better automated preflight checks, among other levers, to try to bend that curve back down. [The burnout risk that comes with capturing AI’s speed as pure output rather than sustainable pace](https://steve-yegge.medium.com/the-ai-vampire-eda6e4f07163) is a real one, and worth naming rather than assuming away.
|
||||
|
||||
The metric I’d rather put on the wall isn’t PRs per day. Throughput is an input metric, not the product; it’s just the coarse measure we have today to demonstrate step-change. Throughput going up while user outcomes plateau or decline is, by definition, enshittification.
|
||||
|
||||
## What does “AI contribution” actually mean?
|
||||
|
||||
There’s no single “AI percentage.” There are at least four different denominators, and you have to be precise about which question you’re asking before you quote a number at anyone.
|
||||
|
||||
(Vendor dashboards will happily hand you an “AI-influenced PRs” number with a confidence toggle. Set to loose confidence, ours cheerfully reported a majority of PRs as AI before we’d done any of the work below. Don’t trust low confidence. The numbers in this post come from our own git history and telemetry, calibrated by hand.)
|
||||
|
||||
These are calibrated floors, not point estimates. We got there by layering three corrections onto git’s raw signal: local branch trailers (245 PRs whose AI attribution was stripped by squash-merge), GitHub-API branch trailers (117 PRs where branches were deleted post-merge but we recovered the trailers via GraphQL across all 7,952 PRs), and a smell-test telemetry override (112 PRs from engineers with zero git AI attribution but heavy Claude Code session telemetry, gated per month against their actual session activity).
|
||||
|
||||
The 95% engineer-level adoption figure, which is closer to our gut estimates, reconciles naturally with the lower PR-level (63%) and line-level (75%) floors: high adoption, selective per-PR use. We can measure floors from git history. We can’t measure ceilings. Being clear about the difference matters more than the specific numbers do.
|
||||
|
||||
|
||||
|
||||
*Surviving lines at HEAD since 2024. The red band is a floor; lines from PRs with AI attribution somewhere in their history. The blue band is “no attribution,” not “no AI.”*
|
||||
|
||||
## What happened
|
||||
|
||||
The adoption curve at Honeycomb has three distinct phases. Each one was driven by something different.
|
||||
|
||||
The first phase, April through September 2025, was sustained low-rate experimentation. About one or two new engineers adopted Claude Code per month, with support but no mandate; engineers were exploring on their own, at least until mid-August, when the founders’ letter landed and the picture blurs. AI’s share of new lines climbed modestly, peaked around 18% in June, then drifted back down to 8% by October as the honeymoon wore off. This is what “leadership opened the door” looks like in practice: not a discrete push so much as a sustained green light. The dip in the second half of 2025 was evaluation, not failure: engineers tried Claude with the model available at the time, decided it didn’t yet justify the friction, and pulled back. If the catnip is rotten, herding cats to eat the catnip is even more difficult.
|
||||
|
||||
The second phase began in October 2025 with a Claude Code harness improvement. Seven new adopters that month, with no model release behind it; tooling quality alone moved the needle. November and December were a pause (although some engineers used the holiday break to try the tools in their personal capacities). Then Claude 4.5 landed in late December, and adoption picked back up in January 2026 with eight new adopters, and AI’s share of new lines climbing to 18% by January.
|
||||
|
||||
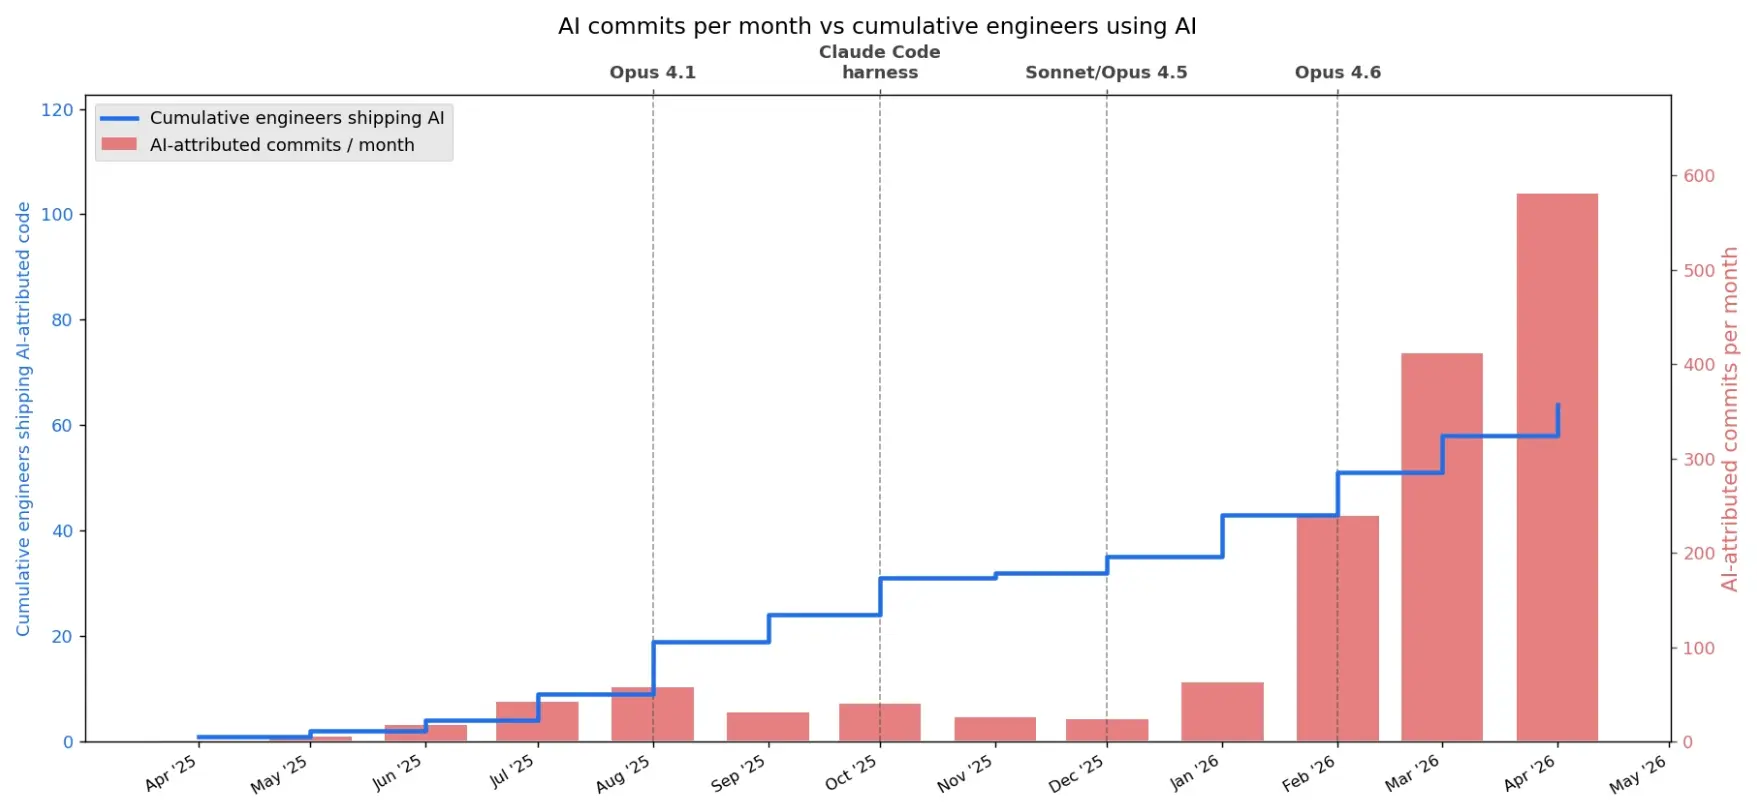
|
||||
|
||||
*Engineers with at least one AI-attributed commit, cumulative. Each step change lines up with a capability event, not a flat schedule.*
|
||||
|
||||
Opus 4.6 launched on Thursday, February 5, 2026. The session-rate takeoff in our Claude Code telemetry lands on February 11-13: the first full work-week after a Thursday launch with a Friday-and-weekend bake-in. Distinct monthly Claude Code users stayed nearly flat across January, February, and March (59, 63, 64). Sessions per user 3.3x’d over the same window (21, 35, 70). AI’s share of new lines went from 18% in January to 46% in February to 65% in March.
|
||||
|
||||
We’ve been calling this confidence to delegate. The same engineers, with the same tooling, with access to the same model family, simply changed how they used it. They stopped consulting or closely monitoring each step, and started delegating. The lift is per-user-intensity, not headcount enabled.
|
||||
|
||||
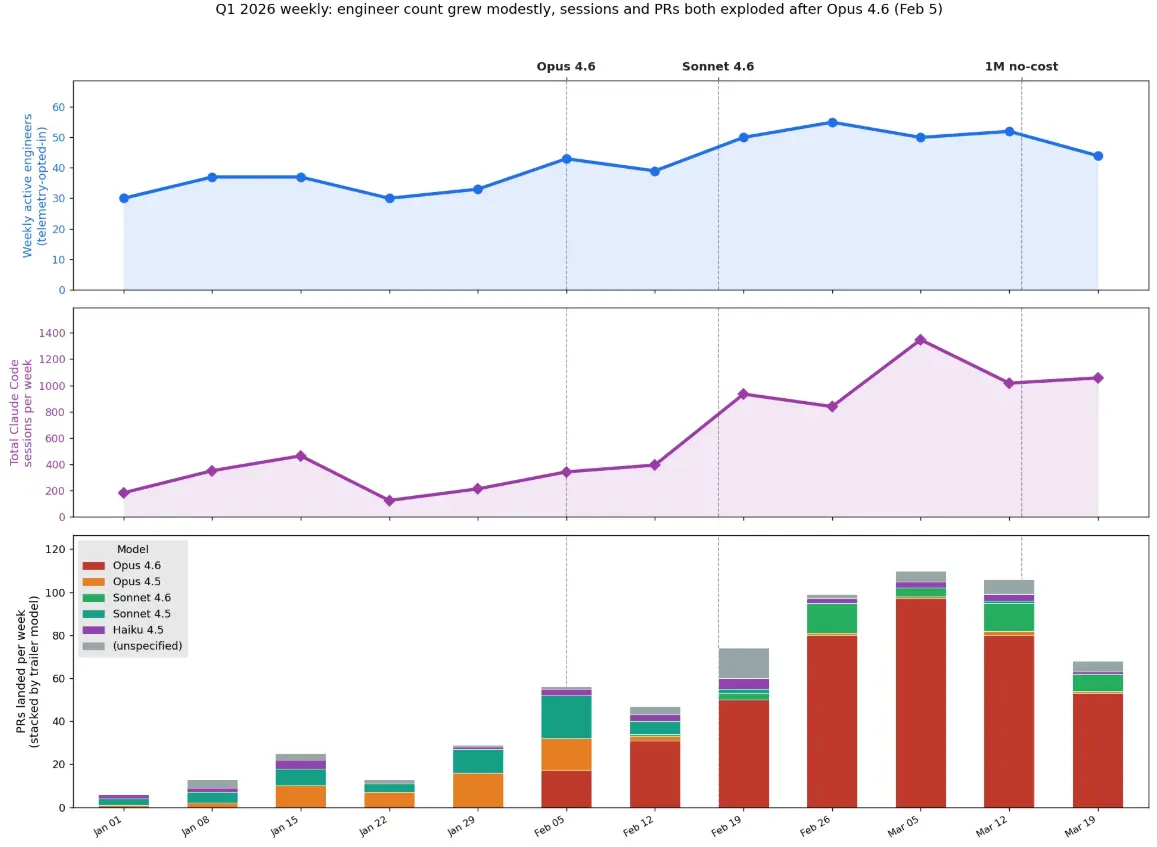
|
||||
|
||||
*The Q1 proof, one magnitude per panel: engineer count barely moved, sessions per engineer exploded, and committed PRs-by-model shows the delegation landing on Opus 4.6 specifically.*
|
||||
|
||||
While the median engineer’s PR throughput grew about 45% relative to its pre-February baseline (call that baseline 1.0x), the top of the distribution moved much further. P75 went from about 1.8x baseline to about 2.9x, roughly +64% in relative terms; the weekly maximum across our active engineers went from a 3.2x-6.4x baseline range pre-February to a 7.7x-12.3x range in April. The floor barely moved at all (P25 went from about 0.5x baseline to about 0.8x). The AI uplift is concentrated at the top end of the distribution. It is not a universal rising tide that automatically boosts every engineer, and that’s okay, because not all engineering is in the bucket of things AI accelerates. As Charity says, the closer to touching bytes on disk you are, the more cautious you need to be about reviewing *everything* with a paranoid lens.
|
||||
|
||||
We’d never had a dozen engineers a week shipping 7+ PRs each in our entire 10-year history, until March 2026. Pre-February, two to four engineers a week hit seven or more PRs; in February that was three to seven, in March seven to twelve, in April eight to sixteen. New, and now routine. And the engineers at the top aren’t a stable cast; the March-selected and April-selected top-twelve cohorts only overlap by about half. It’s a rotating cast riding the new ceiling, not a handful of superusers carrying everyone else.
|
||||
|
||||
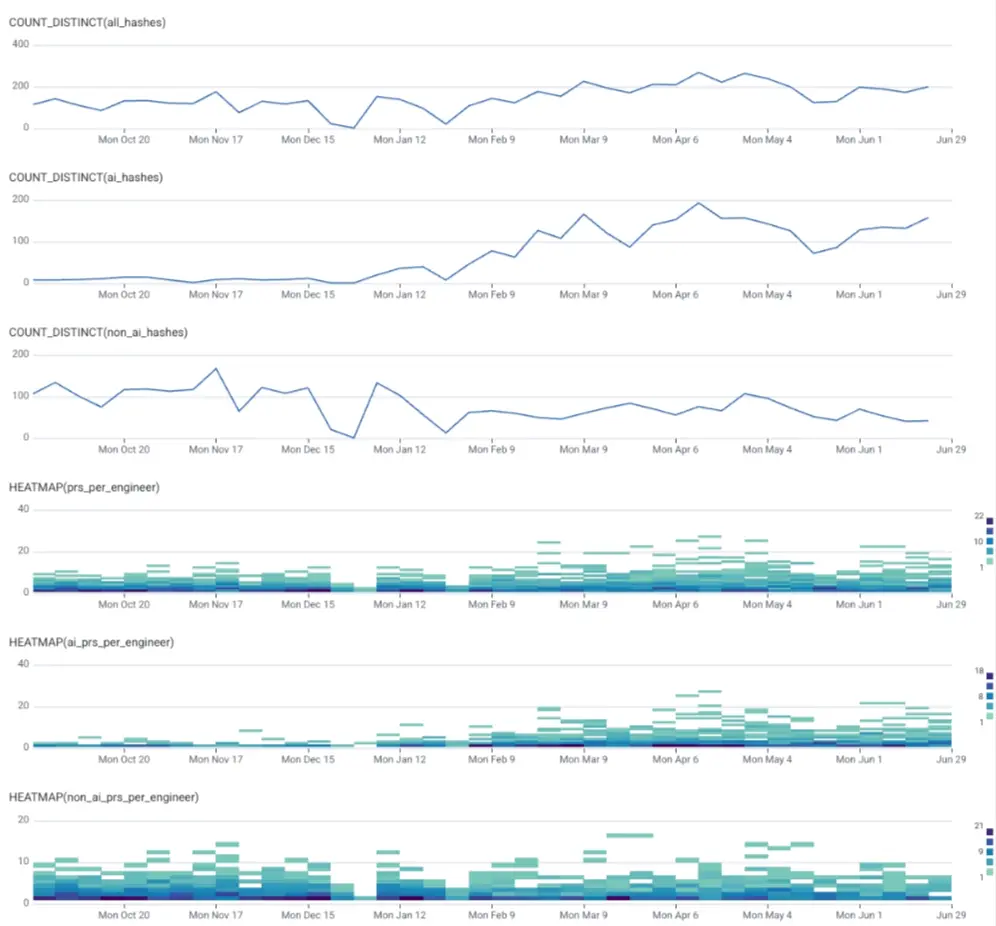
|
||||
|
||||
*Weekly merged PRs (total/AI-attributed/no-attribution) and the per-engineer weekly distribution for each cut, September 2025 through the week of June 22. The top tail past 20 PRs per engineer-week appears in March and persists; the May dent is the freeze weeks, not decay. Bots excluded, including the autobot.*
|
||||
|
||||
Peak-weekday non-AI merges held roughly steady at 25-30 across the entire window; humans didn’t slow down on their best days to make room for AI. But at the org-wide weekly level, non-AI commit-hash volume declined notably, from about 120 PR commits a week pre-February to about 60-80 a week through February to April, while AI commit-hash volume grew from near-zero to 150-200 a week.
|
||||
|
||||
So engineers didn’t slow down on the days they were shipping; they shipped fewer human-attributed PRs in aggregate while shipping many more AI-attributed ones. Some of the +44 peak-weekday delta is genuinely new capacity. Some of it is substitution, where work that used to be human-attributed is now agent-attributed because the same engineers shifted to driving with AI rather than typing by hand. We can’t cleanly separate lift from substitution without a controlled experiment we don’t have.
|
||||
|
||||
## May, June, and a third workflow
|
||||
|
||||
For this blog, we pulled a fresh data cut through June 28, rather than waiting the six months we’d originally planned since the May and June presentations. One methodology note before the numbers: this refresh also excludes mechanical bots (e.g. Dependabot) from every throughput denominator, something the April numbers above didn’t do. So the figures in this section aren’t a perfectly clean continuation of the ones above them. Same discipline as the rest of this post: check the methodology before you trust the magnitude.
|
||||
|
||||
On that basis, weekday-average merges went 38.0 in March, 47.9 in April, then dipped to 36.0 in May before climbing back to 41.9 across the four complete weeks of June. The May dip isn’t engineers slowing down; it’s a supply constraint. May carried an intense marketing push plus merge freezes around [Innovation Week and O11yCon SF](https://www.honeycomb.io/resources/topic/innovation-week). June rebounded as soon as the freezes lifted, and peak-day merges hit 70 again on June 18, matching and sustaining April’s peak.
|
||||
|
||||
The more interesting news isn’t the wobble in the average. It’s that a third category of work showed up entirely.
|
||||
|
||||
`honeycomb-autobot[bot]` landed its first commit on main on April 23. It’s Claude Code on AgentCore, dispatched from RWX (the same CI substrate from earlier in this post) and traced by Honeycomb, triggered from a Linear issue or an @honeycomb-autobot mention on a review, with no human anywhere in the commit-generation loop, only the review loop. That’s categorically different from “AI-assisted coding.” Human-in-loop coding still means a person is driving the session and choosing what to commit. The autobot doesn’t have anyone in that seat at all, but instead back-loads the work onto the review cycle where work is more mechanical and a human feels confident going hands-free during the actual coding.
|
||||
|
||||
Three months of data on it: 3 autonomous merges in April (0.3% of the month), 13 in May (1.7%), 70 across the four weeks of June (8.4%). Over the same window, human-authored merges with zero AI attribution kept shrinking, down to 211 in four weeks of June against a 2025 baseline in the 400s a month, while total throughput held at roughly twice the 2025 baseline the whole time. Same pattern as everywhere else in this post: substitution, not addition.
|
||||
|
||||
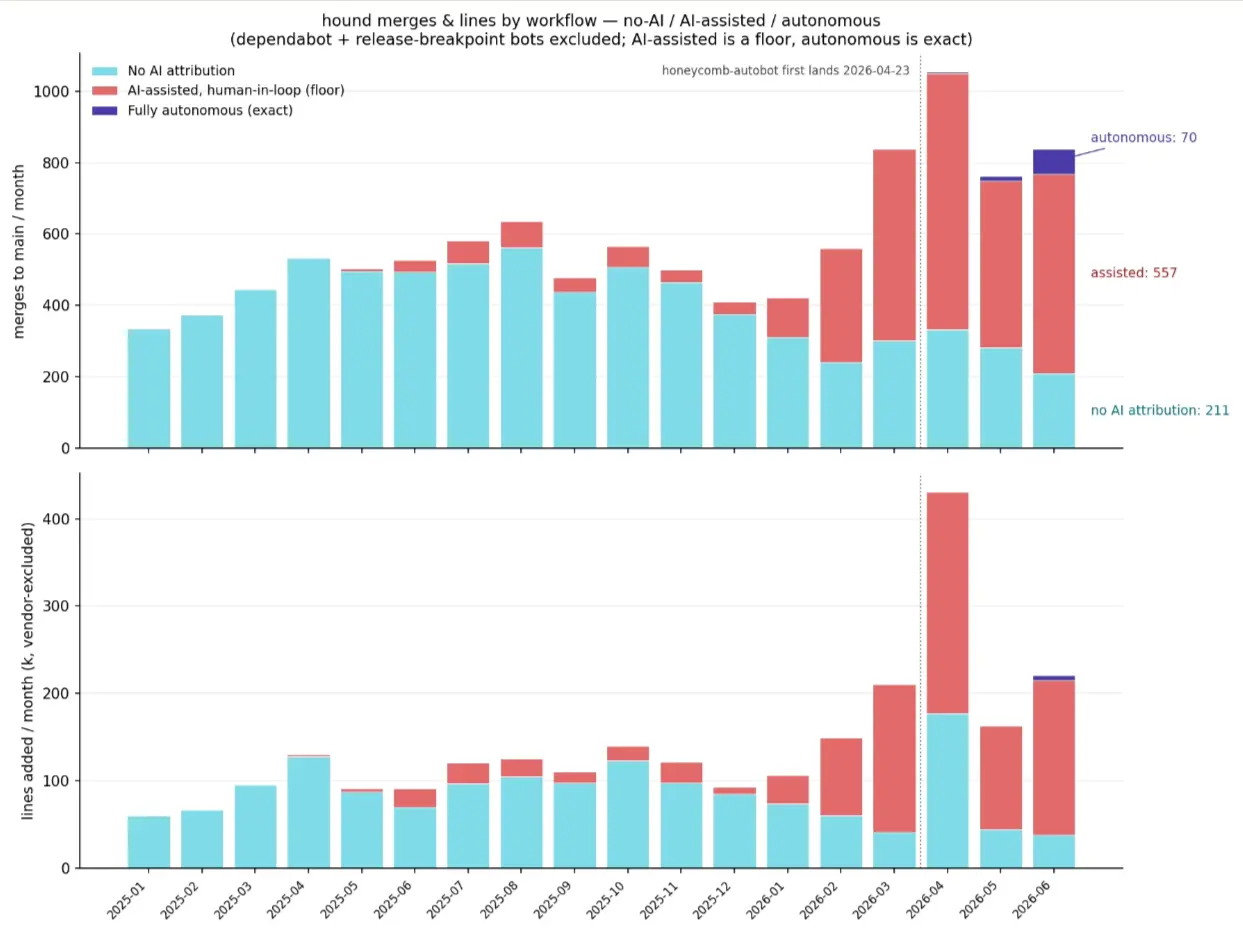
|
||||
|
||||
*The three-way split, January 2025 through the four full weeks of June 2026, mechanical bots excluded. The assisted band is a floor; the autonomous band is exact, because bot authorship is self-evident.*
|
||||
|
||||
The adoption shape looks like the rest of the story too, not a power-user phenomenon. Of the 96 autobot squashes on main through July 6, 63 carry an explicit “Triggered by” line naming 23 distinct engineers; one of the eng enablement leads who co-authored autobot is the heaviest user at 18, and everyone else in the tail is 2 to 4 each. And 55 of those 96 squashes carry no Claude co-author trailer at all, which means the same trailer-based blind spot from the “Bee-ing honest” section up top shows up here too. If we counted the autobot’s work by trailer the way we count human-driven work, we’d have missed 57% of it. We count it by author identity instead, which for a bot account is exact rather than a floor. But it’s a reminder that every attribution method has exactly one failure mode it’s blind to, and you only find out what it is by checking, not by assuming it doesn’t have one.
|
||||
|
||||
The autonomous workflow rides the frontier model the same way human delegation does: 30 of 33 model-tagged autobot squashes in the four weeks of June cite Opus 4.8. And it isn’t yet a lines-of-code story. Autonomous work has added roughly 5,500 lines total since April, about 0.3% of the codebase’s current size. (Added, not surviving; it’s too early to measure how many of those lines are still alive at HEAD.) Right now this is a merge-count phenomenon, not a codebase-composition one. It’ll be worth watching whether that changes.
|
||||
|
||||
The codebase kept growing underneath all of this. HEAD was at 1.88 million lines in April; by July 6 it’s 2,096,286, more than double the 972,000 lines at the end of 2024. Net-new code since end-2024 is now majority AI-attributed for the first time: 599,000 of 1,124,000 added lines, at least 53%, up from 41% in April. June’s line-level floor, at least 82.6% of new lines AI-attributed, is the highest month on record, ahead of April’s 75%. The projection in the April data I presented on-stage, that AI would cross a third of HEAD “around end of 2026,” turned out to be conservative; the current slope puts that closer to September, with half of HEAD by roughly mid-2027.
|
||||
|
||||
One number needs its own caveat rather than a triumphant read. Human-attributed lines surviving at HEAD actually ticked down slightly, from 1,509,000 in April to 1,497,000 in July. That’s not a clean “AI replaced human code” story. Some of it is genuine replacement; some of it is recalibration retroactively reclassifying PRs that were originally counted as human, as we keep finding hidden AI attribution in old PRs. Don’t read a precise story into that number. Read it as more evidence that the floor keeps rising as we get better at measuring it, which has been true of every number in this post so far.
|
||||
|
||||
Engineers with at least one AI-attributed commit: 70, up from 64 in April. That’s broadening, not just the same 50-plus people going faster. And the frontier-model succession kept stair-stepping exactly the way it did in February: Opus 4.6 gave way to Opus 4.7, which gave way to Opus 4.8 (366 of June’s model-tagged PRs, against 31 for 4.7 and 29 for 4.6, the same one-month displacement pattern each time). Claude Fable 5, the newest Mythos-tier model, shows up in June’s trailers too, on 34 PRs. Sonnet 5 hasn’t landed a merged PR yet, since it only just launched, but it’s already showing up on PRs out for review, which tends to be the leading indicator before it shows up in this table. And the autonomous workflow doesn’t relax the one constraint that’s held the whole way through this post: a person still has to trigger it, via a Linear ticket or an @-mention. Our human names have stopped showing up on the commit messages. The only adoption ceiling is still how many engineers choose to reach for it.
|
||||
|
||||
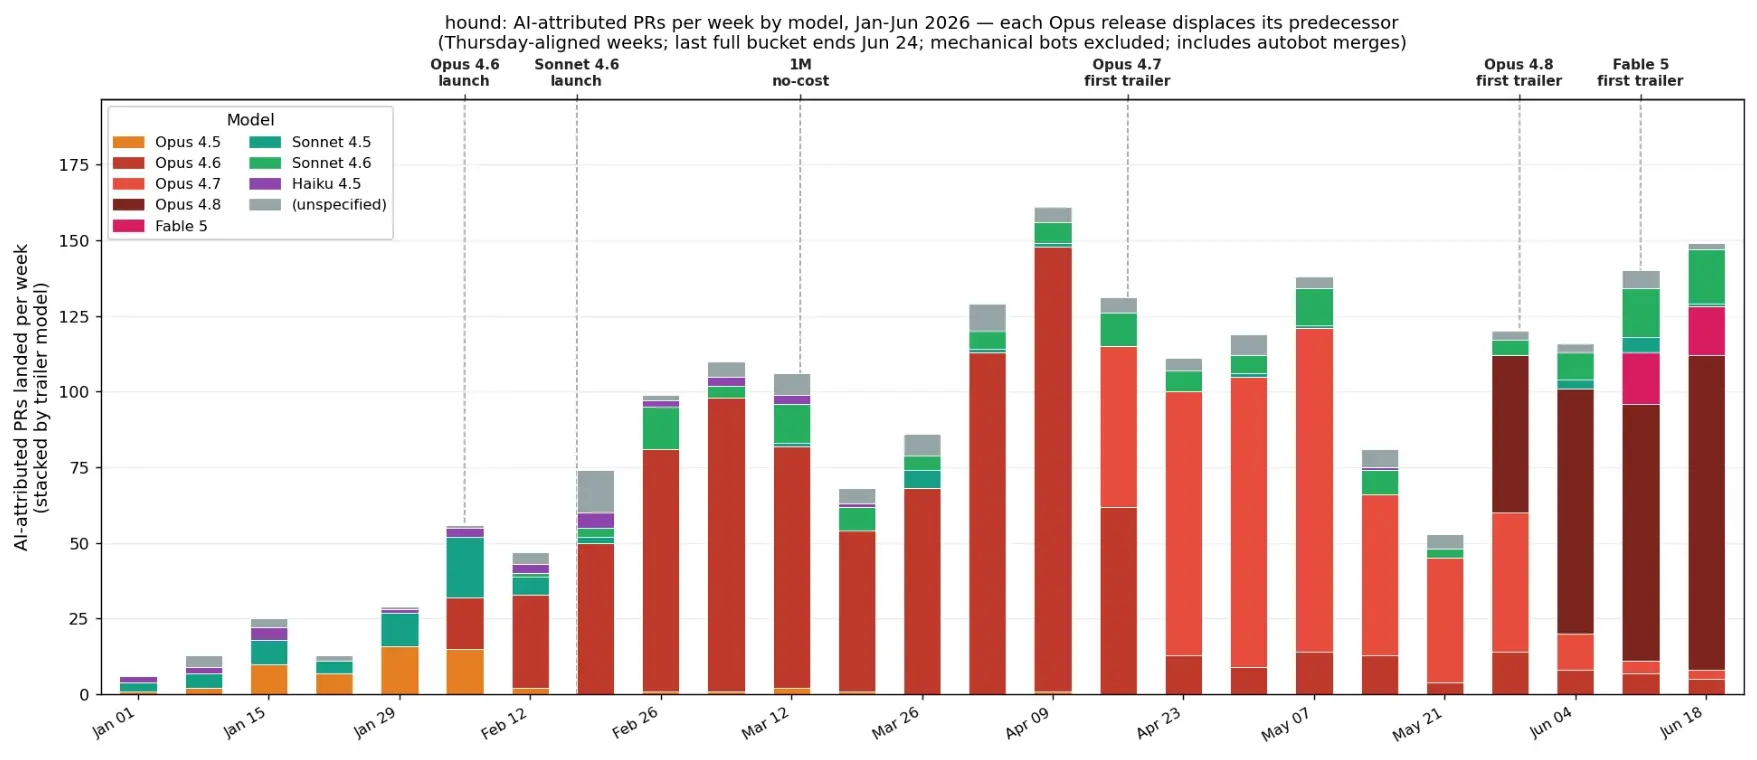
|
||||
|
||||
*The succession, extended through June. Each Opus release displaces its predecessor in committed work within about a month of arriving; the February pattern wasn’t a one-off.*
|
||||
|
||||
## Possible (overlapping) explanations
|
||||
|
||||
We can name several factors that line up with the inflection. None of them, on its own, explains the curve, and we can’t isolate which mattered most without a controlled test we can’t run in retrospect. What follows is a list of overlapping contributions our own team has flagged, not one single cause dressed up as several.
|
||||
|
||||
**Frontier-model capability:** Opus 4.6, in February 2026, was the specific release that produced the session-rate jump. Earlier Opus releases (4.1 in August 2025, 4.5 in December) shifted the floor without producing a takeoff. The rest of the model family in the same window, Sonnet 4.6 and Haiku 4.5, didn’t move the committable-delegation needle in our telemetry: Sonnet 4.6 launched February 17 with full Honeycomb adoption (41 distinct users) but produced only 35 commits in March and 27 in April, against Opus 4.6’s 232 and 127. It was frontier-model capability specifically that crossed the threshold from consultation to delegation, not “any new model.”
|
||||
|
||||
**Leadership signaling, twice:** August 2025’s letter set the explicit “experiment, take time to figure out what AI does for your work” frame. January 2026’s follow-up named sharper strategic stakes: rebuild the product surface and the market posture for AI-first. The mid-January realignment toward greenfield, higher-AI-leverage work followed from that. Without either signal, I doubt the throughput curve looks the same.
|
||||
|
||||
**Tooling that improved over months:** The October 2025 Claude Code harness improvements produced a noticeable adoption step on their own, with no model release behind them. Each release of the tooling added something some engineer needed before they could delegate. Models alone don’t explain the curve; the wrapper around the model matters just as much as the model does.
|
||||
|
||||
**Substrate already in place:** Continuous delivery, code-ownership practices, fast CI, blameless incident analysis, observability that links shipped code back to the PR that created it: the practices the rest of this post is about. AI work landed in an org that already had the substrate to absorb it. We can’t run the counterfactual, but the practices section below is our best account of why this didn’t go badly.
|
||||
|
||||
**Cumulative engineer-level expertise:** From April through September 2025, one or two engineers a month adopted Claude Code. By February 2026 we had a base of fifty-plus engineers who’d been using it for months and could mentor everyone else. That cohort effect is hard to pin to any single date; it’s the gradual accumulation of in-house expertise that the February takeoff drew on.
|
||||
|
||||
These factors overlap, and we can’t say any one of them in isolation would have gotten us here. Leadership signaling probably amplifies tooling improvements. Substrate makes it possible for engineers to share what they’re learning. Frontier-model capability matters more in an org that already has the substrate and the cohort to use it well. The factors compound rather than substitute for one another. Anyone telling you a single factor caused their team’s gain is overstating it. Including us.
|
||||
|
||||
## We followed Intercom, with caveats
|
||||
|
||||
Three things are worth crediting in Intercom's playbook.
|
||||
|
||||
They set a more realistic and achievable 2x goal, not the 10x-and-up claims that were common currency during the 2024 hype cycle. Discipline matters when the temptation is to oversell what AI delivers. We wanted some of that discipline for ourselves.
|
||||
|
||||
They were transparent about both the methodology and the org-shape changes that came with the gain. The substrate Intercom built, a Claude Code plugin marketplace with 153 contributors representing 31% of their R&D org and 267 skills, is genuinely platform infrastructure that ships its own product. They spun up a dedicated team, team-2x, to build it. We’re smaller and a couple of years younger, but we’re building toward something in the same shape, at our scale.
|
||||
|
||||
They engaged their auditors, Schellman, early, before scaling auto-approval, to confirm that the evidence trail an AI-approved PR produces is the same evidence trail an auditor expects from a human-approved one. The “who” changes. The “what” doesn’t. That’s a model worth following: build for safety first, and compliance follows from it.
|
||||
|
||||
Where we differ is that we’re at zero auto-approval today, and they’re at 19.2% as of April. That’s deliberate sequencing on our part, not a sign that we're “behind.” Before you can safely scale auto-approval, which is automating the bug-catching half of PR review, you need substantial substrate underneath it. The compliance question is necessary but not sufficient; the technical preconditions sit underneath the procedural ones. You need codified rules in CLAUDE.md and skills that an auto-review agent can actually verify against; MCP-mediated dev-loop access so the agent reviews against the same context a human would have had (design intent, ticket history, production behavior); fast and AI-legible CI so the verification loop closes quickly; closed-loop production observability that links shipped code back to the PR that created it; and a dissemination layer so humans stay aware of what’s shipping even when they’re not gating it.
|
||||
|
||||
A 19% auto-approval number means radically different things at an org that invested in the substrate before turning the switch versus one that just turned the switch. Intercom’s number is downstream of substrate they built first. A company that turns on “auto-approve PRs under 20 lines” without equivalent substrate will report the same number, but it’s measuring rubber-stamping against weak constraints, not safe automation against strong ones. Different point on the same trajectory.
|
||||
|
||||
The headline finding from Intercom’s auto-approval post is the most striking parallel to our own data. They report AI-authored backend code reverting at 0.53% and AI-authored frontend code reverting at 0.22%, against human-authored revert rates of 5.39% and 2.00% respectively. It’s worth naming the selection effect here: if the easier, lower-risk changes increasingly get auto-approved, humans are left reviewing the harder residual cases, which would push human revert rates up for reasons that have nothing to do with humans getting worse at their jobs. Their downtime from breaking code changes dropped 35% even as deployment frequency doubled. Theirs is a per-PR claim about strict, decomposed, sub-agent-driven review against an Intercom-specific guidance flywheel. Ours is a per-quarter claim about severity, not volume: incident count is tracking change volume about as linearly as you’d expect, but we haven’t had a spectacular AI failure, and our guardrails are aimed at containing how bad any one incident gets rather than pretending we can hold the count flat. Different denominators, same direction. Both posts are pushing back on the naive “more code, more failures” intuition, from different evidence.
|
||||
|
||||
We had a private conversation with the Intercom team in early May 2026. They hit the same February 2026 inflection point we did. The Opus 4.6 unlock was the gut-call attribution from multiple Intercom engineers, though they noted it was almost impossible to disentangle from their internal mandates and team-2x activity in the same period. They’re partnering with a Stanford research group to try to isolate the variables, and even that group’s initial pre-January analysis missed the inflection entirely. The world’s most data-rich org on this exact question is paying academic researchers to help them figure it out, and they still don’t know.
|
||||
|
||||
That independent-org corroboration is the cleanest natural experiment either of us has. Two separate orgs, same month, same uncertainty about cause, same direction. That’s worth more than either of our individual analyses on its own. It’s also worth weighing against the broader base rate: [DX’s longitudinal study across roughly 400 companies](https://newsletter.getdx.com/p/ai-productivity-gains-are-10-not) found AI usage up 65% translating to only about 8% more PR throughput on average. We’re the outlier case here, not the median one.
|
||||
|
||||
Here's the truth: Nothing I've written here will help you if your underlying org isn't already healthy and functional. AI just amplifies what you're already doing. [Read part 2 of this blog series to see what we learned.](https://www.honeycomb.io/blog/ai-amplifies-existing-practices-lessons-ai-first-strategy)
|
||||
|
||||
## AI Influence Level disclosure
|
||||
|
||||
This post: AIL-3.0 (substantial AI involvement, human steering on every load-bearing call). The data analysis, custom git-of-theseus extensions, commit-history trawling, calibration overrides, the merge-rate and incident charts, was AI-assisted. The July refresh, the May-June numbers and the autonomous-workflow analysis added above, was pulled with Claude Fable 5. The slide deck this post derives from was composed with AI assistance, and AI assistance was used to reformat the slide bullet points and speaker notes into essay form. The voice and tone polish was done in a separate Claude project tuned to my writing style, followed by a very extensive manual editing process where I further added or changed at least 20% of the words.
|
||||
|
||||
Strategic decisions, data interpretation, and judgment calls about what to keep and what to cut are mine. AI helped me move faster on a deadline; it didn’t supply the substance. The talk and this post are themselves an example of the same 2x story they describe: weeks of human work, AI-assisted, not 10x. The substance wouldn’t exist without me, and the level of polish wouldn’t exist without AI.
|
||||
|
||||
AIL framework: [danielmiessler.com/blog/ai-influence-level-ail](https://danielmiessler.com/blog/ai-influence-level-ail). Illustrations in the original talk: AIL-0, by [bbghost.bsky.social](https://bsky.app/profile/bbghost.bsky.social). Art should be made by artists, not machines. Illustrations in the blog by our amazing design team.
|
||||
|
||||
*Sources and context:* [Fin/Intercom 2x post](https://ideas.fin.ai/p/2x-nine-months-later);[Fin/Intercom AI PR approval safety post](https://www.intercom.com/blog/ai-is-approving-our-pull-requests-heres-how-we-made-it-safe/);[Honeycomb-Intercom case study](https://www.honeycomb.io/resources/case-studies/how-honeycomb-helped-intercom-observe-and-operate-fin-ai);[Emily Nakashima on AI-amplified engineering leadership](https://www.aviator.co/podcast/enineering-leadership-ai-emily-nakashima). This post is adapted from the[talk of the same name](https://leaddev.com/software-quality/30-to-70-prs-a-day-how-we-managed-to-not-wreck-our-systems), delivered at Sydney Tech Leaders and LDX3 London in 2026.
|
||||
@@ -0,0 +1,73 @@
|
||||
# You’ve (Just) Had an Incident. What Next?
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Karan Nagarajowda — Uptime Labs
|
||||
- **链接**: https://www.uptimelabs.io/articles/incidents-and-recovery
|
||||
|
||||
## 简介
|
||||
|
||||
> Here’s what I’ve learned about what actually happens inside a team when something breaks, how teams often reflect, and how we think about accountability without losing a blameless culture.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
### Ready to make incident response your competitive advantage?
|
||||
|
||||
See how Uptime Labs builds provable, scalable incident response capability across your organisation.
|
||||
|
||||
I've run enough major incidents to know that the first hour rarely goes the way people expect. Here's what I've learned about what actually happens inside a team when something breaks, how teams often reflect, and how we think about accountability without losing a blameless culture.
|
||||
|
||||
## The first hour of an incident: what's really happening
|
||||
|
||||

|
||||
|
||||
Logistically, after detection, people try to understand what's actually happening, then work out whether how to move forward. Note that incidents do not progress through stages in a linear way. You may come back to assessing severity or revisit assessment based on new information that emerge as incident progresses.
|
||||
|
||||
Similarly, it's also complex from an emotional perspective. Individual engineers often wonder if they broke something. Some people see a symptom and immediately form a theory i.e. a gut instinct about the cause - and then start hunting for evidence to support that theory rather than staying open-minded. Meanwhile, managers want constant updates, and what actually happens in Slack is information overload.
|
||||
|
||||
But in my view, the real challenge in the first hour isn't technical; it's cognitive overload. If you [divide an incident into stages](https://www.uptimelabs.io/template/incident-responder-workflow), the first part of the time should be owned by the incident commander, and their job *isn't* to solve the problem. It's to reduce chaos: create the space for people to pick up tasks and start investigating, make decisions explicit, and keep communication flowing. Those first minutes - or even hours, in a bigger incident - are never about fixing the system. They're about making sense of a surprising situation, recruiting people who can help and creating sufficient psychological safety that people will voice their theories and be explicit about certainty of premises of the theory. That's what separates a [good incident commander](https://www.uptimelabs.io/template/training-incident-responders-scaling-teams).
|
||||
|
||||
## A word about pressure
|
||||
|
||||
I think back to a story from earlier in my career that says more about pressure than any framework could. I was working through a major incident next to a colleague who was technically very strong. Our manager - who was visibly under stress - came up behind us and demanded we check the logs. The pressure of being watched and barked at was so distracting that my colleague forgot the basic syntax of the `view` command. Our manager ended up spelling it out: "v–i–e–w, and then the file name."
|
||||
|
||||
It's a small moment, but a telling one. Technical skill isn't the bottleneck when the room is hostile. A junior engineer can have all the right preparation, the right runbooks, the right paired senior and still fold if the environment around them is built on pressure and intimidation rather than support.
|
||||
|
||||
## What teams could overlook after
|
||||
|
||||
People naturally want to answer "*why did this happen?*" Uncertainty is uncomfortable, and immediately after an incident there's a lot of it. So people jump to ‘why’, but I think that's the wrong question, because it sends you straight towards root-cause analysis.
|
||||
|
||||
As we explored in [The Technical Foundations of Incident Response](https://uptimelabs.io/articles/technical-resilience-incident-response/), the right sequence is: can we stop the customer impact - stop the bleeding? Then, can we stabilise the system? Then, can we preserve the evidence? Only then do you investigate - that's where the actual learning happens.
|
||||
|
||||
However, when a team implements a change and encounters errors, fixation can quickly set in. They observe memory errors and become convinced it's a memory leak, focusing all investigation efforts on proving that diagnosis. The problem is that this fixation causes them to lose sight of the primary incident response objective: restoring service. During an incident, multiple decision paths are available (rolling back the change, restarting the service, modifying configuratio) each with different risk and learning profiles. By pursuing only one diagnostic avenue in parallel, teams sacrifice their ability to understand what actually happened. Gathering information before committing to a single response path, and considering what each approach might reveal, is as important as speed in bringing systems back online.
|
||||
|
||||
The second accident is making several big decisions in parallel: restarting, scaling up, changing configuration, with different people acting independently. I wouldn't say the process needs to be strictly sequential, but it makes it much easier to asses impact of each change if you try one thing, gather information, and only then move to the next. Doing three or four things in parallel might bring the system back faster, but it destroys your ability to learn afterwards what actually happened. Preserving the evidence is just as important as restoring the service.
|
||||
|
||||
## Accountability without losing a blameless culture
|
||||
|
||||
A ‘no-blame’ culture in incident management should not mean removing human accountability or glossing over the decisions people make during crises. Rather, it means resisting the urge to simply label events as ‘human error’ and moving on. Every incident involves decisions made by individuals who bear responsibility for those choices, but understanding *why* they made them is critical.
|
||||
|
||||
The goal is to reconstruct the context in which decisions were made: what information was available at the time, what pressures and constraints existed, and what risks seemed apparent or hidden. When we skip this deeper analysis to avoid blame, we sacrifice the insights that could prevent future incidents. Accountability and learning are not opposites; they work together when we focus on understanding the decision-making environment rather than punishing the decision-maker.
|
||||
|
||||
A good postmortem embraces the human element; one of the the key skills of Postmortem (incident review ) is to conduct in a way that no one is uncomfortable. Part of this means avoiding reducing a complex failure down to one person's mistake. That's what a blameless culture actually means: not pinning a complex failure on one person or team, as we discuss in [our regulatory incident response piece](https://uptimelabs.io/articles/regulatory-incident-response/). Accountability, on the other hand, is about improving future outcomes, not assigning guilt.
|
||||
|
||||
So in a postmortem, the questions focus should be on, *"What set of circumstances led to the incident? What information was available to the human operator at the point of the decision making? Why that decision made sense to them?" .*
|
||||
|
||||
Definitely not *"who did it, or why did they do it?"* If someone skipped a checklist and that caused a major issue, the question isn't *"why did they skip it"* - it's "*was there pressure that made skipping it possible? What barriers should have stopped that?"* It's about whether the system allowed the mistake, not about the person. Accountability, meanwhile, is about owning the future outcome - again, without assigning guilt.
|
||||
|
||||
## Who owns the learning?
|
||||
|
||||
It's the incident commander's responsibility to make sure the learning happens, but I don't own all of the learning myself. The engineering team should [own the technical timeline](https://uptimelabs.io/articles/incidents-will-happen-are-you-actually-prepared/). Monitoring and operations should look at the alerts and the response coordination. Customer support should explain the customer experience during the incident. My job as incident commander is to make sure all of that comes together.
|
||||
|
||||
One of the most valuable questions I ask isn't *"what failed?"* It's *"what made the incident harder to resolve than it needed to be?"* That's the better question, and it usually surfaces poor documentation, confusing dashboards, unclear ownership, missing alerts and communication gaps. That's what comes out of these discussions.
|
||||
|
||||
## Add Uptime Labs to your post-incident learning
|
||||
|
||||
None of this is instinctive. Reducing chaos before fixing the system, resisting the pull towards *"why",* asking what made an incident more difficult to resolve rather than who's to blame - these are habits people get better at by practising them, *not* by reading about them and hoping they’ll stay in your head while everything is on fire.
|
||||
|
||||
That's exactly why I helped build Uptime Labs. Our drills put your team through the same ambiguity, incomplete information, and communication pressure a real incident throws at you, minus the real-world stakes. You find out how your team actually behaves in that first hour before it costs you a customer. Each drill comes with a personalised report designed to support ongoing skills development.
|
||||
|
||||
If you want to see what that looks like in practice, [try a drill](https://uptimelabs.io/try-uptimelabs) or get in touch to [book a demo](https://uptimelabs.io/).
|
||||
|
||||
|
||||
@@ -0,0 +1,174 @@
|
||||
# An SRE Response to Datadog’s State of AI Engineering 2026
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Ajay Devineni — DZone
|
||||
- **链接**: https://dzone.com/articles/agent-sprawl-production
|
||||
|
||||
## 简介
|
||||
|
||||
> agent sprawl is now a production reliability crisis, and the SRE discipline does not yet have governance frameworks for it.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# Agent Sprawl Is Your Next Production Incident: An SRE Response to Datadog's State of AI Engineering 2026
|
||||
|
||||
Datadog published the State of AI Engineering 2026 report. Read it. It's the most comprehensive look at AI in production available now.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
Datadog published the [State of AI Engineering 2026 report](https://www.datadoghq.com/state-of-ai-engineering/)— real telemetry from over a thousand production environments. Read it. It is the most comprehensive look at AI in production available right now.
|
||||
|
||||
I want to respond from the reliability engineering perspective, because the data reveals a problem the report names but doesn't fully resolve: agent sprawl is now a production reliability crisis, and the SRE discipline does not yet have governance frameworks for it.
|
||||
|
||||
##
|
||||
|
||||
Three findings stand out from an SRE perspective:
|
||||
|
||||
**Framework adoption doubled year over year**. LangChain, LangGraph, Pydantic AI, Vercel AI SDK — up from 9% of organizations in early 2025 to nearly 18% by 2026. Services using agentic frameworks: more than doubled.
|
||||
|
||||
**70%+ of organizations run three or more models**. The share running more than six models nearly doubled. Teams are building model portfolios rather than committing to a single provider.
|
||||
|
||||
**Teams add models faster than they retire them**. Datadog calls this "LLM tech debt." Each overlapping model introduces its own quality, latency, and cost profile. The report is explicit: this becomes a governance problem.
|
||||
|
||||
These three findings combine to describe an environment growing faster than it can be governed. I call this **Agent Sprawl**.
|
||||
|
||||
## Defining Agent Sprawl
|
||||
|
||||
**Agent Sprawl** — the condition where AI agent infrastructure complexity (frameworks, models, tool layers, orchestration patterns) grows faster than your ability to measure and govern its reliability.
|
||||
|
||||
|
||||
It is structurally identical to the microservices sprawl problem SRE teams faced between 2015 and 2020. Teams added services faster than they added SLOs. The result: production incidents nobody could attribute because the dependency graph was too complex to observe.
|
||||
|
||||
Agent Sprawl has three specific manifestations:
|
||||
|
||||
###
|
||||
|
||||
When you add LangChain, LangGraph, or any orchestration framework, it adds steps and paths you did not write — retry logic, fallback handlers, context window management, tool routing. All of this happens between your application code and your observability layer.
|
||||
|
||||
Your SLIs measure at the application boundary. Framework-added calls are invisible.
|
||||
|
||||
This means your Tool Invocation Efficiency (TIE) baseline — tool calls per task completion — is measuring a mix of your agent's behavior and your framework's behavior. When you upgrade the framework, both change simultaneously. You cannot separate them.
|
||||
|
||||
In practice, across regulated production environments I've studied, TIE baselines can drift 30 – 40% after a framework major version upgrade with no corresponding change in the agent's task logic. The baseline shift looks like agent degradation. It's actually framework overhead. Teams spend hours on a false RCA.
|
||||
|
||||
**The fix**: Instrument at the framework output layer, not the application layer. Capture tool invocations after framework processing. Then freeze your TIE baseline before any upgrade and compare shadow traffic before promoting.
|
||||
|
||||
###
|
||||
|
||||
70% of organizations running 3+ models means 70% have at least two additional SLO ownership gaps they haven't acknowledged.
|
||||
|
||||
[SLOs](https://dzone.com/articles/what-are-slos-slis-and-slas) are set once — typically when the first model is deployed. As models 2, 3, 4, 5, 6 are added for specific task classes, latency profiles, or cost tiers, nobody revisits the SLO ownership model. Models run in production with no named owner, no baseline, no error budget.
|
||||
|
||||
When model 3 degrades, there is no owner to page, no baseline to compare against, no runbook to execute. The degradation surfaces as a customer complaint, not an alert.
|
||||
|
||||
**The fix**: Treat every model in your fleet like a microservice. Each model gets: a named owner (not a team — a person), a task-class-specific SLO, and a 30-day observation baseline before the SLO is enforced.
|
||||
|
||||
###
|
||||
|
||||
Deprecated models running in agent chains create silent compatibility risks. When a provider announces deprecation, teams with models buried inside multi-step chains often miss the migration window. The model ages. Safety training falls behind. Decision Quality Rate declines slowly — too slowly to trigger a threshold alert — until accumulated drift surfaces as a production incident.
|
||||
|
||||
**The fix**: Treat model deprecation notices the same way you treat dependency CVEs. Automate alerts at 60, 30, and 7 days before end-of-life. Build the migration ticket at announcement time, not at expiry.
|
||||
|
||||
## The Governance Framework Agent Sprawl Needs
|
||||
|
||||
###
|
||||
|
||||
Before you can govern sprawl, you need to know what you're governing. Maintain a living inventory with, for each component: framework and version, model(s) used, task classes handled, named SLO owner, current TIE/DQR baselines, and deprecation dates.
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
from agentsre.sprawl import AgentFleetInventory, FleetComponent, ComponentType
|
||||
inventory = AgentFleetInventory()
|
||||
inventory.register(FleetComponent(
|
||||
component_id="anthropic.claude-sonnet-4-6",
|
||||
component_type=ComponentType.MODEL,
|
||||
agent_id="payment-processor",
|
||||
task_classes=["payment-routing", "fraud-detection"],
|
||||
slo_owner="
|
||||
```
|
||||
[\[email protected\]](https://dzone.com/cdn-cgi/l/email-protection)", # named human — not a team
|
||||
baseline_established_at="2026-04-01",
|
||||
deprecation_date="2027-06-01",
|
||||
last_slo_review="2026-04-01",
|
||||
current_tie_baseline=2.4,
|
||||
current_dqr_baseline=91.2,
|
||||
))
|
||||
report = inventory.quarterly_review_report()
|
||||
print(f"Fleet governance score: {report['fleet_governance_score']}/100")
|
||||
###
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
from agentsre.sprawl import FrameworkVersionGovernance
|
||||
gov = FrameworkVersionGovernance(
|
||||
tie_drift_threshold=1.15, # block if TIE drifts >15%
|
||||
dqr_drift_threshold=0.85, # block if DQR drops >15%
|
||||
min_shadow_samples=50,
|
||||
)
|
||||
# Before upgrade: snapshot production baseline
|
||||
gov.snapshot_baseline(
|
||||
agent_id="payment-processor",
|
||||
task_class="payment-routing",
|
||||
framework_version="langchain-0.2.x",
|
||||
tie_values=production_tie_samples,
|
||||
dqr_values=production_dqr_samples,
|
||||
)
|
||||
# After 48hrs shadow traffic:
|
||||
result = gov.evaluate_upgrade(
|
||||
agent_id="payment-processor",
|
||||
task_class="payment-routing",
|
||||
production_version="langchain-0.2.x",
|
||||
shadow_version="langchain-0.3.x",
|
||||
)
|
||||
if result.decision == UpgradeDecision.BLOCK:
|
||||
rollback() # framework added hidden overhead — don't promote
|
||||
```
|
||||
###
|
||||
|
||||
The review should take 30–60 minutes per quarter. For every model in fleet:
|
||||
|
||||
- Verify named owner exists
|
||||
- Verify baseline is current (< 90 days old)
|
||||
- Check deprecation schedule against provider announcements
|
||||
- Review TIE per-model — models with rising TIE relative to task class baseline are drifting
|
||||
|
||||
Models scoring below 70 on the governance health score are flagged as governance debt requiring a 30-day remediation window.
|
||||
|
||||
## The Datadog Report's Implicit Challenge
|
||||
|
||||
The State of AI Engineering 2026 describes an industry in rapid expansion. What it does not fully resolve is the SRE question: who governs all of this, and what does that look like in practice?
|
||||
|
||||
The SRE community has solved exactly this class of problem before — in distributed systems, in microservices, in cloud infrastructure. The discipline already exists. It needs to be applied to the AI agent layer now, before agent sprawl becomes agent chaos.
|
||||
|
||||
The Datadog data tells us the window is closing. Framework adoption doubles in a year. Multi-model fleets become the norm. Model debt accumulates.
|
||||
|
||||
Build the governance layer before the production incidents start.
|
||||
|
||||
## Resources
|
||||
|
||||
- Open-source implementation: [[https://github.com/Ajay150313/agentsre](https://github.com/Ajay150313/agentsre) ]
|
||||
- LinkedIn discussion: [[https://www.linkedin.com/posts/ajay-devineni_agenticai-sre-reliability-ugcPost-7455786901673902080-BCRM?utm_source=share&utm_medium=member_desktop&rcm=ACoAACIp55QBRGVmAcEbf0D-1PaR5vEbm2yMcJU](https://www.linkedin.com/posts/ajay-devineni_agenticai-sre-reliability-ugcPost-7455786901673902080-BCRM?utm_source=share&utm_medium=member_desktop&rcm=ACoAACIp55QBRGVmAcEbf0D-1PaR5vEbm2yMcJU) ]
|
||||
|
||||
What's your biggest agent sprawl challenge right now?
|
||||
|
||||
AI
|
||||
Engineering
|
||||
Site reliability engineering
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
@@ -0,0 +1,197 @@
|
||||
# Don’t add a read replica until you’ve read this
|
||||
|
||||
- **期号**: SRE Weekly Issue #528(2026-08-02)
|
||||
- **作者**: Johanna Larsson — incident.io
|
||||
- **链接**: https://incident.io/blog/dont-add-a-read-replica-until-youve-read-this
|
||||
|
||||
## 简介
|
||||
|
||||
The premise: read replicas can help you scale read load, but they introduce complexity. The article goes into the problems they ran into and how they dealt with them.
|
||||
|
||||
## 正文
|
||||
|
||||
July 21, 2026 — 23 min read
|
||||
|
||||
As the size and complexity of their relational database workload grows, every company eventually goes through the process of off-loading work on a read replica. It comes with lots of benefits, but at a cost of increased complexity. This article is about how we dealt with that, a lot of learnings, and some useful techniques.
|
||||
|
||||
incident.io is the software reliability platform built to investigate, respond and prevent incidents, powered by AI that deeply understands your organization. Thousands of customers rely on it to be the thing that supports them through anything from a minor blip to a full outage. Any disruption to that service has a significant impact on those users, and that’s always top of mind for our engineering team. Everything we build is designed to be performant, reliable, and gracefully degrading.
|
||||
|
||||
When large parts of the internet goes down, as they did for the [AWS outage on 20 October 2025](https://health.aws.amazon.com/health/status?eventID=arn:aws:health:us-east-1::event/MULTIPLE_SERVICES/AWS_MULTIPLE_SERVICES_OPERATIONAL_ISSUE/AWS_MULTIPLE_SERVICES_OPERATIONAL_ISSUE_BA540_514A652BE1A), we see a meaningful increase in alert volume as engineers across the globe are getting woken up. During events like this, we simply can’t fall over from the increased load. This means we always have to run with significant spare capacity. And so we’re always looking for opportunities to reduce the load on our DB, either through performance improvements or code redesign. While working on projects to control the resource utilization on our primary database, we clearly identified that we, like a lot of online services, run an overall read heavy workload.
|
||||
|
||||
We already had a read replica set up and some queries were already utilizing it, but it was something that we were doing on a case by case basis. We knew we could do more. We set ourselves the goal to move *everything* over to the read replica. For every query that could be move moved to the read replica, that’s additional capacity for our primary, and additional protection for those events of massive traffic that we design for.
|
||||
|
||||
But before that, let’s do a quick recap of why you’d want to introduce read replicas into your stack. They do bring complexity, having two databases and two database connection pools in your app logic is more to think about than just having the one. You also need to manage two things, where both often quickly become critical to running your service. Double the graphs and metrics and warnings to worry about. Not to mention, you’re now paying for two databases.
|
||||
|
||||
They bring a lot of benefits though. They’re the natural step to take to give people access to run operational queries on the production system, without risking those queries disrupting the production workload. A query run on the primary can cause overload, delays, contention, locks, and much more. On the read replica the blast radius is much smaller, although there are notable exceptions to this like `hot_standby_feedback`. But maybe the most interesting thing is that it opens the door to horizontal scaling. Relational databases generally don’t scale horizontally, just vertically. Writing to two primary databases is slower than to one, and for most of us spending more to get less performance is not a very interesting prospect. But read replicas are different, since they don’t need to coordinate writes, you can just have more of them and load balance read queries across them. That’s pretty cool.
|
||||
|
||||
Even before approaching this larger re-think we had already established some useful primitives. Our backend language is Go, but the basic techniques translate to some degree to any language.
|
||||
|
||||
The number one thing you need to deal with as you’re migrating work over to a read replica is [read-after-write consistency](https://jepsen.io/consistency/models/read-your-writes). Or in other words, avoiding stale reads. The gist of it is, if you write something to the primary and then immediately after read the thing back but from the replica, there’s no guarantee that you get the same thing back. This gets worse the faster you read after writing. Now if you’re hand-crafting some beautiful artisanal code in your walled garden project, you can probably attempt explicitly picking the primary or read replica for each individual query through a code flow. But for practical reasons we often end up just limiting the read replica to the queries and code paths where we feel that nothing can go wrong.
|
||||
|
||||
That’s not what we’re looking for, we want to move everything over. That means we need automated detection of mutating queries, and to automatically fall over to the primary after a write has been detected to ensure that you are able to read your own writes. The basic mechanism we introduced for this uses the [Go context](https://pkg.go.dev/context) to carry a special flag that controls whether we can use the read replica. It defaults to true.
|
||||
|
||||
```
|
||||
type taintedKey struct{}
|
||||
// A write taints the context: reads on a tainted context must
|
||||
// go to the primary, since the replica may not have caught up.
|
||||
func Taint(ctx context.Context) context.Context {
|
||||
return context.WithValue(ctx, taintedKey{}, true)
|
||||
}
|
||||
func CanUseReplica(ctx context.Context) bool {
|
||||
tainted, _ := ctx.Value(taintedKey{}).(bool)
|
||||
return !tainted
|
||||
}
|
||||
```
|
||||
The second concept we introduced was a simple function for detecting whether a given query was “safe” to go to the read replica. Initially we designed this to be conservative, we were ok with some things being misinterpreted and going to the primary, as long as we don’t get accidental and weird bugs where we send the wrong query to the wrong place. Some heuristics got us a long way, like whenever we start a transaction, we send it to the primary and mark the `ctx` so that any subsequent queries also go to the primary, with the basic assumption that anything in a transaction is probably something you want on the primary (this turns out to not be quite true, more on this later).
|
||||
|
||||
```
|
||||
// Transactions probably mean writes: run on primary,
|
||||
// and taint the ctx so everything after follows it there.
|
||||
func (db *DB) Transaction(ctx context.Context, fn func(context.Context) error) error {
|
||||
ctx = Taint(ctx)
|
||||
return db.primary.Transaction(ctx, fn)
|
||||
}
|
||||
```
|
||||
The second heuristic was to strip comments and trim whitespace, then check if the query starts with `SELECT`. Not very elegant, but it got the job done. There’s a fancier version further down!
|
||||
|
||||
```
|
||||
func IsReadOnly(query string) bool {
|
||||
q := strings.TrimSpace(stripComments(query))
|
||||
return strings.HasPrefix(strings.ToUpper(q), "SELECT")
|
||||
}
|
||||
```
|
||||
On top of this we built a basic layer on top of our database handles that created both primary and replica transaction pools and transparently switched between them, using the flag we had previously set. This means it was now generally safe for us to just opt in any code path to use the read replica, trusting this mechanism to direct the queries to the right place and maintain read-after-write consistency.
|
||||
|
||||
```
|
||||
func (db *DB) route(ctx context.Context, query string) *sql.DB {
|
||||
if !IsReadOnly(query) {
|
||||
return db.primary // and taint the ctx here
|
||||
}
|
||||
if !CanUseReplica(ctx) {
|
||||
return db.primary // we wrote earlier, stay consistent
|
||||
}
|
||||
return db.replica
|
||||
}
|
||||
```
|
||||
Additionally we put a [circuit breaker](https://martinfowler.com/bliki/CircuitBreaker.html) in here. If we’re not able to open connections to the read replica we give up and send all queries to the primary. Note that although we’re happy to have that fail over behavior for now, with enough total load across your databases, your primary might not be able to handle this.
|
||||
|
||||
incident.io is designed from the ground up on event publication and subscription, the entire system is built around publishing messages and having a fleet of workers processing them. This gives us all kinds of interesting super powers, including the ability to buffer up messages to process them later during periods of overload.
|
||||
|
||||
The workers is exactly where we had been adding some read replica offloading, more specifically in a set of workers that execute low priority workloads that do read heavy work. This is also where we started our work, primarily by moving more and more slices of our workers over to the read replica. Our initial results were really positive, we were almost being too successful and we quickly had to upgrade our read replica because it was taking over so much work from the primary. After having moved some of our heaviest read query workloads, congratulating ourselves for our great work, we noticed something odd. Not a super clear pattern, but the occasional `NotFoundError` coming out of our database adapter in the subscribers on the workers that we had just moved.
|
||||
|
||||
And that’s when it struck us. We were ensuring read-after-write consistency within the context of a go `ctx`, but what about across the boundary of publishing and processing a message?
|
||||
|
||||
Let’s say we have a request come in, to create a post-mortem document. But the post-mortem document itself can take a while to create and involves hitting a separate internal service over the network, we don’t do all of that work in line with the client waiting. So we write the row to the database, respond immediately to the client, and then publish a message to a worker to deal with actually creating the document. Incredibly, what we were seeing was the time between publishing a message to the message queue and the worker pulling that message to process it be shorter than the replication lag to the replica. This wasn’t because the replica was falling behind, it was doing just fine, it was just that *occasionally* the event was processed incredibly quickly. Overall it was a rare occurrence, something between 0.1 and 0.5% of messages, and they were automatically retried, but obviously not something we wanted to keep getting alerted on. Interestingly we had technically had this issue for a few code paths for a while, but it wasn’t until we wholesale moved large parts of our codebase over to the read replica that this problem showed itself.
|
||||
|
||||
We discussed some options and quickly homed in on a well-documented tool in the PostgreSQL world.
|
||||
|
||||
The log sequence number, or LSN, is a special pointer in PostgreSQL that represents a specific position in the [Write-Ahead Log](https://www.postgresql.org/docs/current/wal-intro.html). This means that you can use it to check whether the read replica has caught up with a specific write in the primary database. You get the LSN with a built in PostgreSQL function:
|
||||
|
||||
```
|
||||
SELECT pg_current_wal_lsn()::text
|
||||
```
|
||||
The basic technique we want to apply:
|
||||
|
||||
1. Grab the LSN from the primary after having done your write
|
||||
2. Pass it to the code running on the worker
|
||||
3. Compare the read replica LSN with the LSN from the primary, if the read replica is at or after that LSN, you know that you are past the point where your write happened
|
||||
|
||||
In order to enforce read-after-write consistency across our workers, we started stamping each published message with the LSN from the primary at the time of publishing. Grabbing the LSN is very cheap, it’s just an in-memory operation on the PostgreSQL side.
|
||||
|
||||
Having rolled that out, every message now has this stamp on it. So then we added a check on the subscriber side that compared the LSN on the message with the LSN of the read replica. The LSN comparison can be done inside of a SQL query using the [native data type](https://www.postgresql.org/docs/current/datatype-pg-lsn.html):
|
||||
|
||||
```
|
||||
SELECT pg_last_wal_replay_lsn() >= $1::pg_lsn
|
||||
```
|
||||
If the replica was caught up, we are fine to process it. If it isn’t, we just kick the message back to the queue.
|
||||
|
||||
That last part actually turns out to be a great back pressure mechanism in overload situations. If the read replica is failing to keep up with the primary, for whatever reason, instead of directing all queries to the primary and risking overloading it, we just keep nacking the messages until the read replica is feeling better again, with exponential backoff to avoid overload. It turns a potential outage situation into a graceful degradation instead, all the work is processed as expected, just with a delay.
|
||||
|
||||
If you’re doing this, you want to couple it with some dashboards and alerts. You don’t want to get caught out on the replica lagging behind. We often see people measure read replica lag in time, but that’s not a useful measurement. A read replica can catch up 5 minutes of delay in seconds because the rate of change has slowed down, or it can struggle to close the distance on 30s of delay because the rate of change is going up. Basically, the replay rate can change. A more useful measurement is the number of bytes behind. It still doesn’t quite convey whether you have a problem or not, but it’s more consistent than measuring it as time.
|
||||
|
||||
No more random `NotFoundError`, great success!
|
||||
|
||||
After having tackled the events and subscribers, we looked around for other places where we would expect to bump into the same consistency problem, where we need to be careful to read our own writes, and we identified the API as another surface area to deal with. This included our public API where we support creating resources, returning an ID, and then reading the resource back. Done quickly you’d risk a 404. Additionally, our dashboard relies on our internal private API and we frequently use the same pattern there: create an empty resource and return the ID, queue the work to actually create the resource, frontend polls the API using the ID, resource is eventually created and displayed in the UI.
|
||||
|
||||
There are a few different [classic blog posts](< https://brandur.org/postgres-reads>) that talk about using LSN stamping on API requests, so this is not exactly new territory. We want to apply the same principles as we did for our events, but we can be a bit more elegant about it for the API. Thinking about the problem we’re solving, it’s basically focused on the case of a `POST` followed by a `GET`. Or more generally, a mutating request followed by a read. Since we’re pretty consistent about HTTP verbs in our API, we can actually limit LSN stamping to mutating requests: `POST`, `PUT`, `PATCH`, `DELETE`. Additionally we can limit our scope to a given actor, whether it’s a user, an API key, or something like our mobile app, as the domain of consistency. If I create a document I want to see it immediately, but it’s ok for my coworker to have a few milliseconds delay to see the same document.
|
||||
|
||||
We added a middleware that runs after the request handler in our [Goa web layer](https://goa.design/), checks the method of the request, and optionally stamps the actor **with the LSN. We store this directly in PostgreSQL, using the native data type.
|
||||
|
||||
```
|
||||
UPDATE users SET read_after_write_lsn = GREATEST(read_after_write_lsn, pg_current_wal_lsn()) WHERE id = ?
|
||||
```
|
||||
This has the benefit of us already loading that row anyway during auth at the start of every request, so we could include this column there. This is also why we chose not to move this work to a key value store like Redis. Redis would add a network request, looking up the LSN, to every single incoming request, and we still need to get the latest LSN from replica too.
|
||||
|
||||
We shipped the middleware and with our actor tables quickly filling up with LSN stamps, each representing the last action each one has taken, we tackled the other half of this. We added another middleware that runs after auth and takes the LSN stamp from the actor and compares it with the read replica. Unlike subscribers, we can’t just nack the message and send it back to the queue to be processed later. People tend to not want to have to retry all their requests, and we didn’t want to push this on every client to our system, of either having to retry on a certain status code, or carry LSN stamps on headers. So instead of nacking, we fall back to the primary. We may need to rethink that at some point, when we can’t afford to go to primary anymore, but after rolling this out the actual impact on the primary is minimal. Only about 0.01% of requests to our API fail the LSN check.
|
||||
|
||||
With this we could move the last part of our codebase over to the read replica, reversing the trend of increased CPU utilization on primary week over week and getting it back down to a healthy level with all that extra capacity that we aim for.
|
||||
|
||||
After having rolled this out we went after two optimizations that we had identified while we were working on this project. Although fairly simple, we didn’t implement them before rolling out because we 1. wanted to avoid premature optimizations, and 2. doing it after means we get a pretty graph and clear validation of the efficacy of the optimization. Everyone loves a pretty graph.
|
||||
|
||||
The first one was to limit the number of nacks on the event subscribers. As mentioned before, we saw between 0.1 and 0.5% of processed events getting sent back to the queue due to replica lag. Each nack causes a delay of at least 10 seconds in processing the message, since that’s our default retry delay. That’s very much acceptable, but we had a theory: that when we had replica lag the lag is almost always very small.
|
||||
|
||||
So whenever we check the replica and it’s behind, we added a 100 ms sleep before trying again. The impact was striking, almost eliminating nacks. Over time we saw the nack rate drop to ~0.03%. For what was basically a couple of lines of code. In real terms we’re not talking about a lot of messages, but it was a worthwhile improvement. PostgreSQL 19 actually comes with this [functionality built in](https://rednafi.com/system/wait-for-lsn/), with the new `WAIT FOR LSN`.
|
||||
|
||||
Secondly, when investigating why certain queries, that were actually perfectly safe to run on the read replica, were getting directed to the primary we realized our naive approach to detecting mutating queries was maybe just a little bit too naive. We were missing out on tons of juicy queries that were absolutely eligible for the read replica. Taking inspiration from the [https://github.com/pgplex/pgparser](https://github.com/pgplex/pgparser) library, we created a small tokenizer to replace our heuristics. Armed with the tokenizer, we could now confidently identify any queries that were safe to run on the read replica. When we rolled it out we saw a massive drop in CPU utilization on the primary, and a corresponding increase on the replica side.
|
||||
|
||||
So now we’re in our new better world where everything is opted into the read replica by default, we have read-after-write consistency, and thanks to LSN stamping, that applies across events and subscribers, and the API as well.
|
||||
|
||||
But we had two remaining concerns: firstly that our code was still explicitly opting into the read replica everywhere, and secondly that internal concerns were leaking: anyone who needed specific database pool behaviors had to understand exactly how all of this worked. We didn’t want to have to maintain this for the team permanently, or introduce friction for everyone. So we went after the last major part of the project: inverting the default and creating a “DSL” for choosing database connection pool routing strategies. Everything goes to the read replica, whether you’re aware or not, and the mechanisms we’ve implemented ensures your code just works.
|
||||
|
||||
The easy part was tweaking our database handles with internal pool routing, we changed it to be enabled by default. The bigger part was giving the engineering team the tools to tweak the behavior where they needed to. We identified four strategies:
|
||||
|
||||
- `ReadAfterWrite` - this is our default behavior. Track mutations and route to primary after.
|
||||
- `StaleRead` - where you have reads after writes, but you’re fine with them going to the read replica.
|
||||
- `Primary` - pin the context to the primary and send all queries there. We use this where we can’t tolerate any kind of lag, primarily around our on-call product.
|
||||
- `Replica` - pin the context to the replica and send all queries there. This is kind of a nuclear option, it will force queries to the replica even when the replica can’t execute them. Useful where you’d rather fail loudly and fix your code.
|
||||
|
||||
We accept these four strategies on every different level. The database handle takes strategies, and so does the subscriber definitions and the web layer API endpoint definitions. You can also override strategies per context.
|
||||
|
||||
This gives us the inverted default, everything goes to read replica, while still providing the engineering team with the tools they need to keep shipping.
|
||||
|
||||
Once every part of our codebase was “opted in” to the new read replica behavior, we inverted the default. Everything now goes to the read replica, and the people writing code don’t have to worry about it. It just works. Getting there is not hard, but it did come with a lot of learnings.
|
||||
|
||||
So what about the numbers? After the project wrapped up more than 60% of all read queries go to the replica. Of the ones that don’t, the majority were explicitly pinned to the primary. Only a small number of reads are actually routed to primary to preserve read-after-write consistency.
|
||||
|
||||
**We cut CPU utilization on the primary in half.** Looking back over the last few months CPU utilization had been growing significantly week over week as our customer base has been expanding. This project reversed the trend and we’ve had several weeks of CPU utilization going down week over week. A healthy primary with lots of spare capacity means that we can keep handling disaster situations where half the internet goes down and everyone gets paged.
|
||||
|
||||
**Replica lag causes back pressure instead of overload.** In a catastrophe situation where our replica is failing to keep up, or going down, all events are safely buffered in our queue service and only picked up when the replica is ready to get back to work. This means that problems with the replica do not spread to other parts of our stack.
|
||||
|
||||
**We’ve set the stage for horizontal scaling.** The door is now wide open for us to add additional read replicas, giving us a clear path to keep scaling our product for the future.
|
||||
|
||||
**Engineering can keep shipping.** Our transparent, opt-in by default, database pool routing strategies and read-after-write consistency mechanisms ensure that the read replica does not get in your way. You could work here for months without even realizing it exists.
|
||||
|
||||
We hope this writeup can help demystify read replicas and how to get the most out of them, applying fairly straightforward techniques to ensure read-after-write consistency. We really enjoyed working on this project and we hope you’ve enjoyed reading about it! If you’re interested in this kind of thing, come join us, we’re hiring!
|
||||
|
||||
Johanna Larsson
|
||||
|
||||
Product Engineer
|
||||
|
||||
Our rate limiter depends on Valkey. If Valkey goes down we fail open and stop limiting which isn't good enough for our platform. As an intern, I built per-pod in-memory top-k buffers so we keep rate limiting even with the backing store gone.
|
||||
|
||||
Anthony Oparaocha
|
||||
|
||||
September 2, 2026
|
||||
|
||||
Our entire event-driven platform ran through a single message broker, which made it a single point of failure. So we added a second one. This is the story of building an event load balancer, the queuing theory behind it, and the final chaos test where we turned off Pub/Sub in production and nobody noticed.
|
||||
|
||||
Patrick Hamann
|
||||
|
||||
+
|
||||
|
||||
Mike Fisher
|
||||
|
||||
August 11, 2026
|
||||
|
||||
Today we're launching our new post-mortems experience, and I want to walk you through what we've done and why.
|
||||
|
||||
Pete Hamilton
|
||||
|
||||
March 17, 2026
|
||||
|
||||
Ready for modern incident management? Book a call with one of our experts today.
|
||||
|
||||
- All-in-one incident management
|
||||
- Our unmatched speed of deployment
|
||||
- Why we’re loved by users and easily adopted
|
||||
- How we work for the whole organization
|
||||
Reference in New Issue
Block a user