sreweekly: 528 期数据 + 全文抓取(articles/pages + markdown 正文扩充)
This commit is contained in:

@@ -7,3 +7,55 @@
|
||||
## 简介
|
||||
|
||||
Celebrating heroes in incident response can incentivize further heroics. That can prevent the kind of growth that will improve incident response overall.
|
||||
|
||||
## 正文
|
||||
|
||||
It’s 3 a.m. in California, where most of the dev team are still snug in their beds. The auth system has started rejecting valid credentials. Early bird East Coast customers are already trying (and failing) to log in for the day, and thousands of users in Europe have already given up and gone elsewhere. In a couple of hours, the West Coast will be waking up too. A brilliant engineer swoops in and saves the day. She has legendary debugging skills and a deep understanding of the auth system, and she puts together a fix in forty minutes that would have taken anyone else hours to even diagnose. Later that morning, leadership is sending thank-you messages in the all-hands channel. Her VP awards her a small spot bonus, and her manager reminds her to include it in the next performance review cycle.
|
||||
|
||||
What doesn’t usually happen is anyone asking: what if she hadn’t been there? Because that heroic save, for all the heartfelt celebration around it, was actually a near miss from a systemic point of view.
|
||||
|
||||
## Near misses look like successes
|
||||
|
||||
In aviation and other safety-critical fields, it’s widely accepted that a near miss is an unparalleled opportunity to learn and deserves the same investigation as an actual failure. The reasoning is straightforward: a near miss reveals the same systemic vulnerabilities that a failure does. The only difference between a near miss and a disaster is that the outcome happened to be good this time, often because of luck, timing, or the presence of one specific person.
|
||||
|
||||
A heroic incident response is a similar opportunity. The system nearly failed, and would have failed if that one engineer hadn’t been available or hadn’t known exactly what to do. Her skill, expertise, and dedication are worth appreciating. But her unavailability would have meant a much worse outcome, and that’s worth examining too. Too many companies celebrate the save and stop there.
|
||||
|
||||
## The incentive nobody designed
|
||||
|
||||
When a company celebrates a heroic save without examining why the heroics were necessary, it sends a message. The message isn’t intentional, but it’s clear nonetheless: what gets valued is the dramatic rescue, not the boring preparedness work that would have made the rescue unnecessary.
|
||||
|
||||
Over time, that message shapes behavior. The engineer who writes thorough runbook documentation, trains new team members on the auth system, and invests in monitoring improvements doesn’t get the same recognition as the one who swoops in at 3 a.m. and saves the day. Preparedness work is largely invisible in performance reviews. Heroic saves are memorable.
|
||||
|
||||
The result is a perverse incentive loop. Heroics get rewarded, preparedness doesn’t, and the company remains dependent on heroic saves because nobody is investing in the alternative. This isn’t because anyone explicitly decided that preparedness doesn’t matter. It’s because the reward system is quietly rewarding the wrong thing, and nobody has noticed because the heroes keep delivering results. Until they don’t.
|
||||
|
||||
In my experience, this is one of the most common patterns in companies that are struggling with incident management. They have talented, dedicated people who keep delivering heroic results, and because the results keep coming, nobody realizes there’s a growing structural problem underneath.
|
||||
|
||||
## The hero as single point of failure
|
||||
|
||||
The incentive loop creates a second problem. The hero gradually becomes a bottleneck and a single point of failure. When that engineer is on vacation and the next auth system incident hits, the team might spend hours just figuring out what’s going wrong, let alone fixing it. When they eventually leave the company (as they likely will; heroes tend to burn out), the team discovers that critical knowledge walked out the door with them.
|
||||
|
||||
I see this pattern regularly in my consulting work. In a company’s most serious incidents, it keeps turning to the same handful of heroic engineers. Those engineers are talented and committed, and their involvement has genuinely saved the company from significant damage. Everyone involved with incidents knows who they are, and breathes a sigh of relief when they join an incident channel. But the company has never seriously examined what its response capability looks like without them. The term that often comes up to describe these people is “indispensable,” which is really another way of saying that the company’s incident response capability depends on specific individuals’ availability.
|
||||
|
||||
## Why the problem stays hidden
|
||||
|
||||
The most insidious aspect of this pattern is that it’s invisible to leadership for as long as the heroes keep delivering. Companies at the earliest stages of incident management maturity often don’t realize they’re at risk. Leadership sees consistently good outcomes and assumes the company has strong incident response, when what they actually have is strong individuals (and a certain amount of good luck).
|
||||
|
||||
By the time the fragility surfaces, the gap between where the company *thought* it was and where it *actually* was can be startling.
|
||||
|
||||
## Heroic is a growth stage, not a compliment
|
||||
|
||||
When I assess incident management capabilities for my consulting clients, one of the dimensions I evaluate is program maturity: where is this company on the growth path from ad hoc response to reliable organizational capability? The first stage on that path is called “Heroic.” It isn’t meant to be flattering. It means that incident response quality is a property of specific talented individuals rather than a property of the company. When those individuals are available, things go well. When they’re not, things go sideways.
|
||||
|
||||
Every company starts here. The question is whether they invest in growing past it, converting individual capability into organizational capability. That transition is what the rest of the maturity model describes, and it’s the core of what effective incident management programs are designed to do.
|
||||
|
||||
## What to recognize instead
|
||||
|
||||
None of this means companies should stop recognizing heroic contributions when they happen. When someone saves the day at 3 a.m., thank them. But also investigate why the heroics were necessary, and invest in the answers. That’s a form of recognition too: it says the save mattered enough to learn from.
|
||||
|
||||
To move from “Heroic” to higher levels of organizational capability, you need to shift what gets sustained recognition. Recognize the work that makes heroic saves unnecessary: the runbooks, the training, the well-coordinated responses where nobody had to be heroic.
|
||||
|
||||
If an engineer spent much of their quarter writing runbooks, training new responders, and coordinating incident responses, recognize that work: in performance reviews, in public acknowledgment from leadership, in awards and bonuses. If you don’t, you’re telling your organization that the only incident management work worth noticing is the dramatic save.
|
||||
|
||||
The goal is to make effective incident response something the company can do reliably, regardless of who happens to be on call. Heroes are still welcome, and still admired. They just shouldn’t be required.
|
||||
|
||||
## Recent Comments
|
||||
|
||||
@@ -7,3 +7,182 @@
|
||||
## 简介
|
||||
|
||||
What might happen when we quickly adopt LLMs and make sweeping changes in our complex systems?
|
||||
|
||||
## 正文
|
||||
|
||||
## Control and complexity: tension in systems design
|
||||
|
||||
The adoption of LLMs in software development has led countless organizations to rapidly change their practices and structures. Old methods are questioned, replaced, and repurposed as the economics around creating new code get shaken up. Because humans and LLMs aren’t interchangeable, the dynamics in play are also very different. Systems are systems, and so regardless of what is changing, there are known patterns on which we can draw to provide some guidance and warnings.
|
||||
|
||||
Without taking a step back and looking at the mindset behind the design of the system in which you operate, you’re likely to get somewhat incoherent (as in “clashing” and “conflicting,” not as in “nonsensical”) measures and policies. And so in this post I want to discuss how we organize systems by contrasting two families of approaches.
|
||||
|
||||
The first is about analytical decomposition that aims to maintain control over a system, and the other is based on a perspective of complex systems that resist analysis, which tend to focus on figuring out interactions and mechanisms to foster desirable emergent behaviour.
|
||||
|
||||
Comparing these has always been useful to tease apart assumptions and important elements of system design, and it is still relevant now with new types of changes being proposed.
|
||||
|
||||
### The approaches
|
||||
|
||||
#### Analytical Decomposition and Control
|
||||
|
||||
At the core of classic science, engineering, and many forms of management, lies the idea that the whole can be understood from its parts. Decompose a complicated thing enough that you can get a thorough and detailed understanding of every component, and you should be able to know how the ensemble works. This approach, analytical decomposition (also sometimes described as “Cartesian-Newtonian”), has been trustworthy and reliable in countless parts of modern life.
|
||||
|
||||
This ability to divide, analyze, and understand generally extends to understanding causality over time: each action has a reaction, each event has a material cause, and these can be traced and evaluated or tested objectively. It follows that we can turn this around: if we understand an object well enough, then we can predict what it will do when acted upon.
|
||||
|
||||
This is foundational to building machines and processes with any sort of predictability and reliability. You can have a high-level goal and a lot of disjoint parts, break down the problem, assemble components that are well tested and within tolerances, and have a working solution. A corollary is that if every part in the machine plays its role well, then the machine itself ought to work well.
|
||||
|
||||
This requires taming a messy, chaotic world, and controlling parameters such that variability can be bounded. Design with enough tolerances and redundancy, and things should work. If not, we can dive in, take it apart, understand what broke, fix it, and be better for it.
|
||||
|
||||
This approach is everywhere, from signal processing and telecommunications, where lossy information transmission is detected and corrected through redundancy, up to industrial quality control, where [statistical processes can be used to define the acceptable boundaries](https://surfingcomplexity.blog/2024/11/23/ttr-the-out-of-control-metric/) of production.
|
||||
|
||||
It also exists at the human level: in human factors engineering, concepts such as working memory (how many things the typical operator can hold in mind) or ideal observers (a theoretical person who monitors instruments at an optimal frequency against which we define “complacency”) have been constructed for the purpose of making sure that systems in which people participate will keep them acting within desirable parameters.
|
||||
|
||||
It’s also visible at organizational levels. Bureaucratic processes and hierarchies aim to keep alignment top-down such that the whole ensemble works coherently. Mechanisms of discipline and legibility are in play to keep the organization’s evolution under control. At broader scales, organizations often try to control their environment, their market, or the legislative context in which they operate.
|
||||
|
||||
Basically, by deciding how much of a mess is accepted on the inside of a process, we can define a clearer interface on the outside of it for others to interact with. This abstraction creates a simplified but effective way to group a complicated ensemble into a manageable unit.
|
||||
|
||||
Software ends up representing a sort of ideal for this mindset: systems can be written in languages that ensure some level of hard-won determinism. Execution is ideally always the same, there is no wear and tear, what worked yesterday will work tomorrow, everywhere. Policy decisions defined far away from the sharp end can be deterministically enforced at all levels.
|
||||
|
||||
This means systems can be built from components bottom-up, aligning with top-down intent, limiting variability that comes from either machining or human behaviour. The ideal is a highly predictable, controlled, competitive, and reactive system.
|
||||
|
||||
#### Complexity and Emergence
|
||||
|
||||
The problem is that by definition, complex systems resist analytical decomposition.
|
||||
|
||||
There are many competing descriptions of complex systems, some of which are behavioural and some of which are structural. They all boil down to something like “things are so interconnected and have so many states that they become either unrepresentable, unpredictable or uncontrollable.”
|
||||
|
||||
Other key elements are that these systems are dynamic, heavily influenced by their own history, and are also open—they continually change and interact in ways that don’t respect clean boundaries. This creates a tension where many participants have distinct goals, perspectives, representations, and degrees of freedom. By the time you’re done analyzing the system, it’s already something else. Even observing the system changes it in important ways.
|
||||
|
||||
Put another way, if you find yourself surprised by the system’s behaviour, by the time you’ve pinned down what happened, it’s already a different system and your policy changes will be lagging or contributing to more counterintuitive surprises. Complex systems are more influenced than controlled.
|
||||
|
||||
This dynamism leads to strategies that encourage equally dynamic adjustments. Since you can’t make these predictable, interventions will often be small and iterative. Alternatively, if you can’t simplify the elements or interactions you’re trying to control, you can increase the variety of control behaviours in order to make ongoing adjustments better. This tends to mean “put a controller—human or otherwise—that has [enough internal complexity to cancel out the complexity](https://pespmc1.vub.ac.be/REQVAR.html) of the thing it controls.” This, in cybernetics speak, is an attempt at creating more adaptive and dynamic control mechanisms.
|
||||
|
||||
Balance is attained not by keeping things static, but by keeping them in motion.
|
||||
|
||||
The ideal system is self-aware and flexible such that it can endlessly adapt and sustain itself, despite ever-increasing challenges. It's unclear whether the ideal can be reached.
|
||||
|
||||
### How they compose (or fail to do so)
|
||||
|
||||
Systems generally evolve from a constrained definition of the problem and its potential solutions, something that is tractable and effective. As the scope and scale of operations grow more comprehensive, further interventions trying to steer the system provide diminishing returns, and they increasingly produce unintended effects. These are the effects of complex systems showing up as things become tangled.
|
||||
|
||||
The coping mechanism I’ve seen the most often is one of doubling down by doing more analysis, more decomposition, and putting more effort into more flexible automation that covers more cases. This in turn changes the nature of success and failure, by creating sometimes less frequent but bigger incidents instead. This type of composition takes place by substituting what breaks when possible, or sometimes by pure accident. It’s rarely been an orderly process.
|
||||
|
||||
More rarely seen mechanisms seek to find out how much of the analytical and control-centric approaches we can afford to give up, identifying what can’t change at all, and then expanding complexity-aware mechanisms outwards from there. This is far less comfortable because this sort of stance demands that you give up on the idea that you actually are in control—a very unpleasant state of affairs to broadcast for a business.
|
||||
|
||||
There are in fact long-standing debates as to whether larger scale accidents can actually be avoided. For example, Jean-Christophe Le Coze offers [the following categorization](http://dx.doi.org/10.1016/j.ssci.2014.03.015):
|
||||
|
||||

|
||||
|
||||
1. A ‘deterministic’ thread, where the properties of the technological systems themselves (such as tight coupling and complexity) will eventually defeat efforts to prevent accidents.
|
||||
2. An ‘epistemic’ branch that focuses on the idea that organizations will suffer from 'failures of foresight' where weak signals and indicators that accidents are incubating will not be seen or accepted by the structures of power, and worldviews will fail to match new challenges, leading to accidents.
|
||||
3. A ‘self-organizing’ thread that considers systems as adaptive and therefore frames success and failures as consequences emerging from systems' self-organization, through an exploration of problem and solution spaces with their available resources.
|
||||
|
||||
These differing views are not fully incompatible, and authors from one category will frequently borrow from others. Each perspective will however come with a focal point, a thing that is seen as important and worthy of consideration: the structure of control, the historicity of the system, the dynamics of power structures, the adaptive and changing nature of systems, the limited perspectives of participants, concepts around culture, and so on.
|
||||
|
||||
Many contributors to these debates, while stating that accidents are unpredictable or hard to avoid, nevertheless seek explanations that can support making them less likely. They look at the limitations of known approaches, and expand the boundaries of what we should consider, adding new perspectives that can reveal new insights.
|
||||
|
||||
There’s a lot of existing literature across many disciplines to study and get a better grasp on what doesn’t work (and when), and what is contextually useful. The opposition of analytical decomposition for control and complexity for emergence I’m offering here is crude and lacks nuance, but that’s hopefully what makes it an acceptable tool to think about changing systems.
|
||||
|
||||
Oversimplification is what we’re doing here, and knowing what kind of wrong we’re going for is useful. As George Box (1976) said: “Since all models are wrong [we] must be alert to what is importantly wrong.”
|
||||
|
||||
### Contrasting Approaches in Practice
|
||||
|
||||
In a bit of a caricatural manner, the following examples will show relatively stereotypical perspectives to topics relevant to software through both analytical decomposition (with a focus on control) and complexity (with a focus that deliberately limits itself to influence):
|
||||
|
||||
| Topic | Analytical Decomposition / Control | Complexity / Emergence |
|
||||
|---|---|---|
|
||||
| Training and education | Build a well-defined curriculum, best practices for teachers and trainers, and testing mechanisms to ensure predictable performance and uniformity across students. | Create environments that foster exploration, experimentation, and information exchange; provide guidance and support. |
|
||||
| Safety | Prevent undesirable behaviours that lead to failure. Hazards are to be contained or designed out, and deviations from procedures or best practices are seen as a risk. | Foster positive behaviours that lead to success. Find how people bridge gaps in processes, work around obstacles, and recover from problems. |
|
||||
| Correctness | The software does what the specification or API says it should. Tests pass, it is feature-complete, and operates within known boundaries. | Users or customers are able to successfully accomplish their tasks; goals can shift based on their needs. |
|
||||
| Reliability | Uptime is within acceptable range, and is verifiable through SLAs, SLOs, etc. Load testing and thorough verification can prevent outages. | Nines don’t matter if customers aren’t happy. You also won’t know for sure if software works until you hit production. Plan for recovery and coping with surprise. |
|
||||
| Approach to incidents | Runbooks define best practices. Protocols and processes are defined to investigate and triage problems as efficiently as possible. Build for clear information and rapid diagnostics. Investigate what broke so recurrence can be prevented. | Surprises may require improvisation. Who knows what will happen; build capacity to deal with the unknown. Investigations must look into normal work to understand how the system works in the first place. |
|
||||
| Developing features | Understanding the needs of users and the strengths and gaps in current offerings lets you identify what to build and how to build it. | Experiments in the field with potential features that you iterate on is how you best find what features may prove useful. |
|
||||
| Standards and norms | Written unambiguously based on verifiable processes and outcomes to make enforcement tractable, scalable, and clear. | Written in a goal-oriented manner as to support and guide the people who execute the work and who need to adapt rules to their reality. |
|
||||
|
||||
For each category, the attitude taken can drive people to pick drastically different approaches and activities, some of which may or may never overlap—the drive to control costs and errors can hinder the effectiveness or desire to experiment, and beliefs about how complex systems work may oppose all sorts of measures that are typically used to demonstrate accountability.
|
||||
|
||||
I say this table is caricatural because in the real world, lines are often not this clean-cut, nor this superficial. It is possible for a control-centric hierarchy to align managers on goals and delegate authority down to cope with system complexity, and for control to be emphasized based on who people in power trust, for example. Centralized control tends to be most effective on the analytical decomposition side, but there are also approaches that aren’t control-centric that benefit from it.
|
||||
|
||||
In fact, many activities can be used in both approaches, and serve both for distinct people, or even at the same time for any given person:
|
||||
|
||||
| Activity | Analytical Decomposition / Control | Complexity / Emergence |
|
||||
|---|---|---|
|
||||
| Code Review | Find bugs and flaws; track and assign accountability; ensure quality. | Build awareness and provide a space for feedback within and across teams. |
|
||||
| SLO adoption | Organizational tool to ensure all teams manage their reliability adequately. | Prioritization tool whose value comes from having teams discuss and define what is an acceptable level of reliability. |
|
||||
| Refactoring | Pay down technical debt, reduce complexity, improve maintainability and flexibility, normalize used patterns. | Countering entropy, adapting a code base to changing contexts based on new information available or shifting requirements. |
|
||||
| Chaos Engineering | Validating that expected failure cases are properly tolerated or recovered from | Experimentation-driven exercise in which participants form theories about their system’s behaviour in failure scenarios and try to confirm or disconfirm them. |
|
||||
| Using a platform | A shared platform can encourage good architectural patterns and prevent undesirable ones, while abstracting away complexity for teams that build on it. | Platforms provide systems with means of commoditizing shared elements to benefit from economies of scale and specialization, and address organizational bottlenecks through self-serve access. |
|
||||
|
||||
Even if activities in this list *can* serve both analytical decomposition and complexity-aligned approaches, that doesn’t mean that they *will*.
|
||||
|
||||
For example, code review approaches that are control-centric and aim to hammer out any deviation from established norms may be adversarial to the point of causing anxiety or hindering actual feedback. Some implementations may still be able to mix automation and the proper social norms to successfully support both purposes to varying degrees of success.
|
||||
|
||||
My experience has been that for these activities, the underlying position taken truly matters if you want to understand how they play out, and how they sometimes fail to meet someone’s expectations. This underlying position will also matter when it comes to prioritizing one activity against others. If participants or stakeholders do not agree to the higher-level purpose and desired outcome, then there will be a gap in ways these activities are expected to be carried out and how they take place, and in the relative importance they will be given across the system.
|
||||
|
||||
When someone wants to change, supplement, or remove some of these activities, it’s useful to wonder what’s the nature of the change and what’s the perspective it favours.
|
||||
|
||||
### Flipping across approaches
|
||||
|
||||
As a heuristic, when multiple lenses are available, we can either try to find the best one (for some arbitrary criteria), or use a complementary or intersecting approach that uses as many of them as possible. Picking a single lens can lead to seeking implementations that maximize one type of activity contextually—whether control or emergence—whereas a combined approach can seek to make sure chosen activities are able to serve multiple properties, as a sort of tradeoff.
|
||||
|
||||
Sometimes, what you get is not what you intend. An organization that sets up activities for control may find itself relying on practitioners invisibly repurposing them for complexity-aligned contributions. Meanwhile, the organization’s decision-makers exercise less control than they believe, or misattribute benefits to their own acts. They can then lose what they had when altering control mechanisms and incidentally hindering the hidden adaptations.
|
||||
|
||||
Conversely, if activities are set up for emergence but are instead done mechanically as if intended for control, they won’t provide the expected benefits and might look and feel like busy work: the organization then neither controls nor benefits from adaptive effects.
|
||||
|
||||
For broad topics and categories such as reliability or correctness, there are often no clearly defined choices or principles that are written down and that you can use. Organizations however tend to have some general tools that line up on the control-to-emergence spectrum, usually around process design and enforcement mechanisms.
|
||||
|
||||
If you’re faced with behaviour you dislike, let’s say people from other teams modifying sensitive code your team owns unannounced, you can take measures such as having discussions with them reasserting ownership, and mentioning the expected process. You could require a preliminary RFC document or ticket before any change request is submitted. You can rely on code ownership files to prevent any unexpected change from going further without your agreement. You can move that key code to repositories which other teams cannot access.
|
||||
|
||||
All of these are relatively local and play on the direct surrounding structure to modify actions and prevent undesirable acts. These approaches may be tremendously effective with little effort, but can also inadvertently fail to make desirable behaviour likelier.
|
||||
|
||||
Closer to emergence’s perspective, it may be more typical to figure out what drives other teams to send these changes unannounced. What are the constraints and pressures they see that makes their current behaviour reasonable to them? If everyone agrees the process is a good ideal state but it frequently gets ignored, what is perceived as more important than that? Only once this is understood should you then design an intervention. This type of questioning—often informed by patterns such as those highlighted previously by Le Coze—tends to have you pull on a thread that unravels through the whole organization. It can be time consuming and difficult to do without established trust, but it can reshape expectations, and as easily lead to major change as to minor interventions upstream.
|
||||
|
||||
A combined approach would be one where a broad understanding of the situation is obtained by leaning on complexity-aware methods, and is then used to design simple but high-leverage checks and barriers such that minimal control yields high rewards. This relies on the complexity stance to look not just at the system’s structure and purposes, but at how its various components and participants interact. Once the interactions make more sense, then the analytical approach is hopefully more effective.
|
||||
|
||||
A risk here is to find yourself with a system that either feels so intractable, resistant to complexity approaches, or inflexible to cross-cutting interventions that you’re back to purely local defences, except they are late, with more work needed to get to the same place.
|
||||
|
||||
The question then is not which approach is better, but how do we know when the current approach reaches its limits and what do we do then?
|
||||
|
||||
### Pitfalls of uncritical system design
|
||||
|
||||
People change their systems all the time, with or without this knowledge. They’re often successful, but not always, or at least not in the ways they had planned. Knowing what to look for doesn’t mean you’ll get it right, but it increases your odds.
|
||||
|
||||
This might be true in the current LLM-driven shakeups as well. Because the technology is new and design patterns aren’t crystallized yet, a lot of people experiment a bit haphazardly. Many of their ideas have interesting elements or aspects to them that are worth learning from, but glaring omissions from a systems perspective that will still need to be handled.
|
||||
|
||||
It’s almost impossible not to find examples of wide sweeping changes proposed when reading tech opinion pieces, which I’ll avoid linking to here. But they include ideas such as:
|
||||
|
||||
- Replacing code reviews with various types of barriers (tests and automated checks), rarely questioning what emergent roles the practice may have nor how static barriers may qualitatively differ from more adaptive ones.
|
||||
- Splitting software work into high-level specs to be translated to code in a black box with external checks only, without offering explanations around how the specs may cover varying abstraction layers, how the external checks can remain tractable, or how information worth learning should cross these boundaries in each direction.
|
||||
- Asking for everyone to become a sort of manager-of-agents while keeping agents under tight control loops, without asking what you may lose (or at least cause as second-order effects) in this analogy by changing the delegation and control mechanisms wholesale.
|
||||
- Focusing on system-level observable outcomes and letting go of imposing the structure within, trusting that the system will self-organize itself adequately.
|
||||
|
||||
If you design a system with control in mind—the use of barriers (think of the Swiss cheese model), the presence of extensive testing, of processes and procedures guaranteeing best practices—then you should pay as much attention to the mechanisms that will be needed to figure out if control actually works. This means asking questions like:
|
||||
|
||||
- How do we know our observations remain relevant, and that we surface the right signals?
|
||||
- How can we know if our understanding of the system loses accuracy?
|
||||
- What important elements is our analysis leaving out or obscuring when trying to make things legible?
|
||||
- How much variability is tolerated, and are we suppressing necessary types of it?
|
||||
- Are the things we optimize for creating brittleness elsewhere?
|
||||
- Is our control real or illusory? How would we know if that changes?
|
||||
|
||||
Well-regulated systems compensate for disruptions in ways that hide or suppress the signals of accumulating problems, both at technical and cultural levels. These questions aim to figure out whether any thought is given to what hides such behaviours.
|
||||
|
||||
When you design for emergence—think of self-organization, market-like mechanisms, or delegation of decisions to participants with local context—other questions come up:
|
||||
|
||||
- Are local parts of the system working at cross purposes?
|
||||
- Is goal alignment effective? What maintains coherence?
|
||||
- What capabilities or efficiencies are we sacrificing when giving up on legibility?
|
||||
- Can we afford to lose the efficiency of a control-centric system? When might we need it?
|
||||
- How do we differentiate adaptation from drift?
|
||||
- What preserves dissent and carries information from the edges of the system?
|
||||
|
||||
Since complexity-aware approaches tend to resist prescriptive stances, there are often risks of increased inertia or widespread misalignment. Emergent properties will be key to success and failure, but without some careful thinking and influence, things can take on a life of their own.
|
||||
|
||||
Whenever someone pushes for a system design that focuses on analytical decomposition or control, ask how they know they’re doing what’s needed, and the mechanisms by which they adapt. Whenever someone pushes for a design that seems to promise self-regulation and endless flexibility, ask how they’ll maintain coherence and the conditions they rely on for good outcomes. Whenever someone pushes to switch from one to the other, ask what depends on current behaviour and consider what the second-order impacts might be there.
|
||||
|
||||
Tech companies often rush to reinvent themselves around the outsized promises of new technology. Integrating new technology into existing workflows generally demands transforming the workflows. These changes often aim at reducing variability and increasing control, but cross subsystem boundaries in ways that disrupt tangled interactions that were dynamically stable.
|
||||
|
||||
Automation that makes things predictable necessarily removes elements of unpredictability that can be useful to adaptation and evolution. Likewise, trying to make a part of the system more adaptive may necessarily make it less predictable. Both have knock-on effects on the rest of the system.
|
||||
|
||||
Where and how does the system migrate from one mode of operation to the other? Where is control necessary and where is it not? What do we choose to analyze and decompose and what do we treat like an ecosystem instead?
|
||||
|
||||
If we don’t have an answer to these, we also don’t have a good answer to how our systems will avoid failure or meet success. Systems are systems. They will keep acting like systems, and failing like systems.
|
||||
|
||||
@@ -7,3 +7,137 @@
|
||||
## 简介
|
||||
|
||||
> Most teams log, but log badly: wrong severity levels, no trace IDs, inconsistent fields, and logs siloed from traces.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# Structured Logging in Distributed Systems: What Most Teams Get Wrong and How to Fix It
|
||||
|
||||
Most teams log, but log badly: wrong severity levels, no trace IDs, inconsistent fields, and logs siloed from traces. Fix that, and incidents go from hours to minutes.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
Logging is one of the oldest practices in software engineering, yet in distributed systems it remains one of the most poorly implemented. Most teams log, but very few log well. The gap between having logs and having useful logs becomes painfully visible the moment a production incident occurs at 2 AM across a system running dozens of microservices.
|
||||
|
||||
This article focuses on structured logging: what it is, where teams consistently go wrong with it, and the concrete practices that separate log data you can actually act on from log noise that burns engineering hours during incidents. If you are building or operating distributed systems today, structured logging is not optional. It is the foundation on which every other observability signal- traces, metrics, alerts- depends.
|
||||
|
||||
## What Structured Logging Actually Means
|
||||
|
||||
[Structured logging](https://dzone.com/articles/structured-logging-spring-boot-improved-logs) means emitting log entries as machine-readable key-value pairs rather than arbitrary free-text strings. Instead of this:
|
||||
|
||||
Plain Text
|
||||
|
||||
|
||||
|
||||
`[ERROR] 2026-07-10 03:14:22 - Failed to process payment for user 84729, reason: timeout`
|
||||
You emit this:
|
||||
|
||||
JSON
|
||||
|
||||
|
||||
|
||||
```
|
||||
{
|
||||
"timestamp": "2026-07-10T03:14:22Z",
|
||||
"level": "error",
|
||||
"service": "payment-service",
|
||||
"event": "payment_processing_failed",
|
||||
"user_id": 84729,
|
||||
"reason": "timeout",
|
||||
"duration_ms": 3001,
|
||||
"trace_id": "4bf92f3577b34da6a3ce929d0e0e4736",
|
||||
"span_id": "00f067aa0ba902b7"
|
||||
}
|
||||
```
|
||||
The difference sounds cosmetic. It is not. The first format requires regex parsing and string matching to extract meaning. The second is immediately queryable, aggregatable, and, crucially, correlatable with traces and metrics from other services handling the same request.
|
||||
|
||||
## **The Five Mistakes Distributed Systems Teams Make With Logs**
|
||||
|
||||
### **1. Logging Without Context Propagation**
|
||||
|
||||
In a monolith, a single log line tells you where in the codebase an event occurred. In a distributed system, a log line without a correlation identifier tells you almost nothing. If Service A calls Service B which calls Service C, and Service C fails, you need a shared identifier, typically a trace ID, that threads through all three services' logs so you can reconstruct the full request journey.
|
||||
|
||||
The fix is context propagation: passing a trace ID through every request, injecting it into every log entry, and configuring your logging library to include it automatically. In practice, this means integrating your logging setup with OpenTelemetry or a similar tracing framework from day one, not as an afterthought. When your log entries include trace_id and span_id fields, you can jump from a log entry to its full distributed trace in a single query; that capability compresses incident diagnosis from hours to minutes.
|
||||
|
||||
### **2. Inconsistent Field Naming Across Services**
|
||||
|
||||
In a [microservices architecture](https://dzone.com/articles/what-are-microservices-architecture-and-how-do-the) developed by multiple teams, field-naming inconsistencies compound into a real problem at scale. One service logs user_id, another logs userId, a third logs uid. One service logs errors under error, another uses err, another uses exception. When you need to query across services during an incident, this inconsistency forces per-service query variations, slowing everything down.
|
||||
|
||||
Establish and enforce a logging schema across your organization. Define a canonical set of field names for common concepts, user identifiers, request identifiers, error fields, latency fields, and make that schema part of your service standards. Libraries like structlog in Python or logrus/zap in Go make it straightforward to enforce common fields at the logger initialization level, so teams can't easily deviate from the schema accidentally.
|
||||
|
||||
### **3. Logging at Wrong Severity Levels**
|
||||
|
||||
Severity level misuse is endemic. INFO logs that should be DEBUG. Application errors logged as WARN because the developer did not want to trigger alerts. Business logic exceptions logged as ERROR when they are expected and handled. Over time, this degrades the signal value of severity levels to the point where teams stop filtering by level entirely.
|
||||
|
||||
Adopt and document clear severity semantics for your organization:
|
||||
|
||||
- **DEBUG** : information useful only during active development; should not run in production
|
||||
- **INFO** : normal operational events (service started, request received, job completed)
|
||||
- **WARN** : unexpected conditions that are recoverable and do not require immediate action
|
||||
- **ERROR** : failures that require investigation; every ERROR should eventually be investigated or suppressed with documented justification
|
||||
- **FATAL** : unrecoverable failures; service cannot continue
|
||||
|
||||
Treat severity levels as a contract with your future on-call self.
|
||||
|
||||
### **4. Over-Logging Hot Paths**
|
||||
|
||||
High-throughput services that log every incoming request at INFO level generate enormous log volumes that create three problems: storage costs escalate, log search performance degrades, and genuinely important events get buried in noise. A service processing 10,000 requests per second generates over 860 million log lines per day from request logging alone.
|
||||
|
||||
Use sampling for high-frequency, low-severity log events. Most observability platforms and [log monitoring tools](https://middleware.io/blog/log-monitoring-tools/) support log sampling natively; you configure a sampling rate for specific log patterns, keeping representative data without keeping everything. For example, sample 1% of successful payment processing logs but keep 100% of error logs. This dramatically reduces volume while preserving signal fidelity where it matters.
|
||||
|
||||
### **5. Treating Logs as a Standalone Signal**
|
||||
|
||||
Logs become exponentially more powerful when they are correlated with traces and metrics. A spike in error logs is interesting. An error log spike correlated with a latency metric increase correlated with a trace showing a database connection timeout is actionable in seconds. Teams that treat logs as independent from their other observability signals are leaving significant diagnostic capability on the table.
|
||||
|
||||
If you are not already running [OpenTelemetry](https://dzone.com/refcardz/getting-started-with-opentelemetry), start there. It provides a unified SDK for instrumenting logs, traces, and metrics in a way that ensures they carry shared context identifiers. Once your logs carry the same trace IDs as your distributed traces, your observability signals become correlated by default, not by manual investigation.
|
||||
|
||||
#### **A Practical Logging Schema to Start With**
|
||||
|
||||
Here is a minimal structured logging schema that covers the majority of production use cases across distributed services:
|
||||
|
||||
JSON
|
||||
|
||||
|
||||
|
||||
```
|
||||
{
|
||||
"timestamp": "ISO-8601 UTC",
|
||||
"level": "debug|info|warn|error|fatal",
|
||||
"service": "service-name",
|
||||
"version": "1.4.2",
|
||||
"environment": "production",
|
||||
"event": "snake_case_event_name",
|
||||
"message": "Human-readable description",
|
||||
"trace_id": "OpenTelemetry trace ID",
|
||||
"span_id": "OpenTelemetry span ID",
|
||||
"user_id": "optional",
|
||||
"request_id": "optional",
|
||||
"duration_ms": "optional, numeric",
|
||||
"error": {
|
||||
"type": "TimeoutError",
|
||||
"message": "Connection timed out after 3000ms",
|
||||
"stack": "optional, omit in high-volume paths"
|
||||
}
|
||||
}
|
||||
```
|
||||
This schema is opinionated but extensible. Services add domain-specific fields as needed while every entry maintains the common fields that make cross-service correlation possible.
|
||||
|
||||
## **Conclusion**
|
||||
|
||||
Structured logging in distributed systems is not about logging more; it is about logging intentionally. The practices that separate teams who resolve incidents in minutes from teams who spend hours in log archaeology come down to four things: consistent field naming, trace context propagation, disciplined severity usage, and treating logs as a correlated signal rather than an isolated one.
|
||||
|
||||
Get these right, and your logs become a first-class observability asset during incidents. Get them wrong, and you have the worst of both worlds: high storage costs and low diagnostic value. The patterns outlined here are not theoretical; they are the difference between incident response that feels like detective work and incident response that feels like reading a timeline.
|
||||
|
||||
systems
|
||||
Observability
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
|
||||
@@ -9,3 +9,70 @@
|
||||
> If you had to explain to a neighbour why your organisation is so safe, and generally works well, what would you say?
|
||||
|
||||
It’s all about people. I really enjoyed the quote from Charles Billings on principles for automation.
|
||||
|
||||
## 正文
|
||||
|
||||
*This article is a slightly edited reproduction of the [Editorial](https://skybrary.aero/sites/default/files/bookshelf/hs36/HS36-Shorrock-Editorial.pdf) published in HindSight magazine* [issue 36](https://skybrary.aero/articles/hindsight-31) *(Autumn 2024) (all issues available at [SKYbrary](https://www.skybrary.aero/index.php/HindSight_-_EUROCONTROL))*
|
||||
|
||||

|
||||
|
||||
[https://flic.kr/p/2fMsKHp](https://flic.kr/p/2fMsKHp)
|
||||
|
||||
I joined the world of aviation in the late 1990s as a Human Factors analyst in UK air traffic management. I had just completed my master’s degree in work design and ergonomics, following my bachelor’s degree in applied psychology. For the first half of my career, my focus was mostly on micro interactions: breaking down tasks, procedures, and interactions at a granular level – seconds and minutes, button presses and radio transmissions. This work involved incident analysis, critical incident interviewing, human-machine interface evaluation, and simulation observation, all aimed at identifying episodes of what we might call ‘loss of control’. Breakdowns and breakages in countless human-human and human-machine loops preceded interactions that sometimes led to losses of separation, level busts and runway incursions.
|
||||
|
||||
Looking back, I was primarily using applied cognitive psychology and cognitive ergonomics to understand control through loops of internal mental processes – perception, memory, attention, and decision-making – along with interactions, and feedback and from the environment. This is often depicted in diagrams with boxes and arrows illustrating the processing of information.
|
||||
|
||||
In the second half of my career, my work shifted toward the macro level, zooming out to interactions within and between organisations, over months, years, and even decades. I listen carefully to people in various roles about their unique experiences. Here, the loops involve communication, cultures, and changes over time. These loops are inseparable and interdependent, creating formidable complexity in terms of people, technology, processes, structures, and organisations.
|
||||
|
||||
No single frame of understanding suffices; I draw upon many disciplines, especially humanistic and social psychology, systems thinking, complexity science, and the humanities, in my attempts to understand the world. From this perspective, people seek to maintain control collectively through loops of communication and influence that evolve document them.
|
||||
|
||||
Looking at the big picture, what is incredible is not that we sometimes lose control, but that we manage to maintain control at all. (Note that there are various meanings of ‘control’, from hard – making something happen – to soft – managing or influencing a process or situation – and it is worth thinking about what it means for you.) This brings me to a question that I often pose to groups, including senior managers: If you had to explain to a neighbour why your organisation is so safe, and generally works well, what would you say? The responses vary, but in the best-connected environments, different groups – controllers, engineers, managers, safety specialists – recognise and acknowledge each other’s contributions, forming large, interconnected loops. It’s a vital question to ponder, because if you don’t, how do you know what to nurture and extend…or defend in the face of cost cuts?
|
||||
|
||||
“Looking at the big picture, what is incredible is not that we sometimes lose control, but that we manage to maintain control at all.”
|
||||
|
||||
|
||||
I recently posed this question to an audience of CEOs and safety directors at a EUROCONTROL conference in Spain. It was heartening to hear some senior leaders acknowledge in detail how people are their organisations’ greatest assets. They emphasised that people need to be in control and in the loop. I was surprised at the level of resonance with the theme of this issue of HindSight.
|
||||
|
||||
The CEOs’ comments took my mind back to a groundbreaking report by Charles Billings, [Human-Centered Aviation Automation: Principles and Guidelines](https://ntrs.nasa.gov/api/citations/19960016374/downloads/19960016374.pdf), published in 1996 by NASA. Billings was a former flight surgeon and specialist in aviation medicine, who became an influential and distinguished NASA expert in aviation human factors. The principles in his report remain solid to this day, and the first three are so general that they apply regardless of the presence of automation.
|
||||
|
||||
1. The human operator must be in command.
|
||||
2. To command effectively, the human operator must be involved.
|
||||
3. To remain involved, the human operator must be appropriately informed.
|
||||
|
||||
The remaining principles focus on the relationship between human operators and automated systems:
|
||||
|
||||
1. The human operator must be informed about automated systems behaviour.
|
||||
2. Automated systems must be predictable.
|
||||
3. Automated systems must also monitor the human operators.
|
||||
4. Each agent in an intelligent human-machine system must have knowledge of the intent of the other agents.
|
||||
5. Functions should be automated only if there is a good reason for doing so.
|
||||
6. Automation should be designed to be simple to train, to learn, and to operate.
|
||||
|
||||
While these principles remain valid, they primarily address the operator-machine dynamic, or ‘joint cognitive system’. This was the focus of my interest in cognitive psychology and cognitive ergonomics. But the humanistic psychologist and systems thinker in me seeks principles that recognise people as more than operators, with control (or influence) distributed throughout organisations, industries, and societies. To this end, I propose the following nine principles to help ‘see’ the people in control:
|
||||
|
||||
1. **People are whole and complex beings.** We are greater than the sum of our mental, emotional, physical or behavioural ‘parts’, and cannot be fully understood by focusing on tasks, functions, roles, or occupations.
|
||||
2. **People have unique virtues, values, gifts, and passions.** For these to be expressed fully, we need a supportive and nurturing environment that values individuality, diversity, and inclusion.
|
||||
3. **People have goals, and seek meaning, purpose, and creativity.** We often seek these things through relationships, work, and personal pursuits.
|
||||
4. **People naturally strive to learn, grow, and develop.** We tend to flourish in a supportive and enabling environment.
|
||||
5. **People are inherently social beings.** We seek meaningful connections with others to find belonging, identity, support, and shared purpose, and are profoundly influenced by social norms, expectations, and pressures.
|
||||
6. **People’s subjective experience is unique.** Our experience shapes how we interpret and respond to the world around us and affects our wellbeing.
|
||||
7. **People live in unique and dynamic contexts.** These ever-changing contexts – personal, social, organisational, societal, political, environmental, technological, economic, and legal – strongly influence us.
|
||||
8. **People are part of complex adaptive systems.** Our interactions are influenced by a dynamic network of interactions, which are interconnected and interdependent, with outcomes that are often unpredictable.
|
||||
9. **People have some choice, control, and responsibility.** But agency is distributed among many and shaped by the opportunities and constraints of the contexts in which we exist, along with our capabilities and motivation.
|
||||
|
||||
These principles remind us that people are more than operators and need to be considered in the broader context. Although these principles have remained valid over millennia, the contexts and the complex adaptive systems in which we live and work (Principles 7 and 8) have changed dramatically, impacting our choices, control, and responsibilities (Principle 9). I encourage you to consider the principles in the light of any activity or change, inside or outside of an organisation.
|
||||
|
||||
“Things work because people make things work, bridging the gaps in the loops as they arise in order to stay in control.”
|
||||
|
||||
|
||||
Over the last quarter of a century, one observation has become increasingly clear: everything is connected. In a complex industry like aviation, we can rarely discuss ‘local problems’ in isolation. Even the loss of a single individual – who may possess unique expertise – can significantly impact an organisation. This is equally true for the loss of critical resources. For instance, in our conversation in this issue of *HindSight*, Captain James Burnell discussed the effects of losing crew rooms at some airports. I revisited this impact through the lens of the nine principles I have just outlined. When I recently shared this story with another pilot from a different country, he was horrified at the prospect. *“Crew rooms are sacred!”*, he said, *“There would be riots!”* Crew rooms are shared resources that help crews to stay in the loop and maintain control and have even broader benefits for people.
|
||||
|
||||
Going back to my *“If you had to explain to a neighbour…”* question, my answer is that things work because people make things work, bridging the gaps in the loops as they arise in order to stay in control. We do this using our remarkable expertise, creativity and connectivity, and do this sometimes to our personal cost. What is amazing is that things work as well as they do. It’s time that we fully acknowledged the reason for this – us – and respect people as so much more than operators and overseers of machines and processes.
|
||||
|
||||
### Discover more from Humanistic Systems
|
||||
|
||||
Subscribe to get the latest posts sent to your email.
|
||||
|
||||
This one too !!- well done
|
||||
|
||||
T
|
||||
|
||||
@@ -7,3 +7,45 @@
|
||||
## 简介
|
||||
|
||||
Type conversion in aviation involves an experienced pilot training on a new kind of aircraft. This article draws a parallel to transitioning to a new job as an SRE.
|
||||
|
||||
## 正文
|
||||
|
||||
# Type Conversion: What Changes (and What Doesn’t) When You Start a New SRE Job
|
||||
|
||||
Pilots have a specific term for moving from one airplane to another: a *“type conversion”*. Not *“learning to fly”* again — you already know how to fly. It’s the process of taking everything you already know and re-mapping it onto a new machine that does the same job with a different cockpit.
|
||||
|
||||
Starting a new SRE job is the same thing. And thinking about it that way has changed how I plan the first few weeks in a new seat.
|
||||
|
||||
## The principles don’t change
|
||||
|
||||
Aerodynamics doesn’t care what airplane you’re in. Lift, drag, thrust, weight — every single-engine piston airplane you’ll ever fly balances the same four forces the same way. A stall is a stall. A stabilized approach is a stabilized approach. The control surfaces that do the work — ailerons, elevator, rudder — are present on every one of them, even when they’re shaped differently or hung in a different place on the fuselage.
|
||||
|
||||
SRE is the same underneath. Error budgets, blast radius, the instinct to widen the time window before trusting a correlation, the discipline of not doing anything you can’t undo quickly — none of that is specific to a company. You bring all of it with you on day one. The job isn’t *“relearn reliability engineering.”* It’s *“figure out where this particular airplane keeps its flap controls.”*
|
||||
|
||||
## The instruments are always there — the panel layout isn’t
|
||||
|
||||
Every airplane you strap into will show you airspeed, altitude, and engine RPM. That’s not optional; you cannot fly safely without them. What changes is where they are on the panel, and maybe whether you’re reading a needle or a glass display.
|
||||
|
||||
Every production system you’ll ever own is going to show you latency, error rate, and saturation, whatever the org calls its version of the USE or RED method. That information exists somewhere, because you can’t run anything at scale without it. What changes is whether it lives in Datadog or Prometheus/Grafana or a homegrown dashboard nobody’s updated the README for. Whether there is an alert on CPU saturation or queue depth, and whether the number you’re staring at is raw or something three layers of aggregation removed from the truth. The first week on a new system is instrument scan practice: find the gauges, confirm what they actually measure, and figure out which ones lie under load.
|
||||
|
||||
## The controls you already know may work differently
|
||||
|
||||
This is the part that trips people up, because it’s where confidence and competence quietly come apart. You know how flaps work. You’ve used them hundreds of times. But if you learned on electric flaps — a switch, a preset, done — and the new airplane hands you a mechanical Johnson bar you have to feel your way through by position, “I know how flaps work” isn’t enough anymore. Retractable gear instead of fixed. A constant-speed prop with a blue lever to manage instead of one knob that just goes faster or slower. Same job, same physics, genuinely different procedure, and the procedure is exactly where accidents might happen.
|
||||
|
||||
New job, same story. You know how deploys work. You’ve shipped code for years. But if you learned on a fully automated ArgoCD pipeline and the new shop is still doing blessed-branch deploys by hand through a Jenkins job somebody’s afraid to touch, “I know how deploys work” is not the same as knowing how deploys work *here*. Kubernetes instead of a fleet of long-lived VMs. A change-management process with an approval board instead of merge-and-go. The underlying skill transfers. The muscle memory for the specific lever in front of you does not, and that’s the gap that gets people in trouble in the first month — not lack of skill, but skill applied on autopilot to the wrong control.
|
||||
|
||||
## The numbers you have to memorize are airframe-specific
|
||||
|
||||
Every airplane has its own set of V-speeds — best glide, maneuvering speed, gear and flap extension limits — and you memorize them cold for *that* airplane. The number for best glide speed in a 172 will get you killed in a Bonanza. Knowing that V-speeds exist and knowing what they are for this specific one are two completely different kinds of knowledge, and only the second one is useful in an emergency.
|
||||
|
||||
Same with paging thresholds, SLO targets, and escalation policy. You already understand that error budgets exist and that burn-rate alerts are how you catch them early. That’s the concept, and it travels. The actual numbers — what latency triggers a page here, what counts as a SEV1, who gets called at 3 a.m. and in what order — are specific to this system, this traffic pattern, this org’s risk tolerance, and you have to learn them cold before you’re the one holding the controls during an incident. Nobody hands you a card with the new numbers on it before your first on-call shift, any more than they hand a pilot a V-speed card mid-flight. You go find it, in the runbooks and the postmortems and the people who’ve flown this one before you, before you need it.
|
||||
|
||||
## How you actually check out on a new type
|
||||
|
||||
Pilots don’t skip the transition training just because they’re experienced. A thousand hours in one airplane buys you good instincts and bad habits in equal measure when you move to a different one, and the honest pilots know it. The process is always the same shape: study the systems (the POH, the equivalent of the wiki nobody’s updated since the last incident), fly with someone who already knows this airplane before you fly it alone, and treat the first hours as information-gathering.
|
||||
|
||||
I’m about to do this again — new company, new stack, new set of V-speeds to learn — and the plan is the same one I’d give anyone else walking into a new seat: don’t assume the panel is laid out the way your last one was, don’t trust a control until you’ve confirmed what it actually does *here*, and spend the first weeks flying the pattern with an instructor in the right seat before you take it up solo. The principles of flight got you your license. They will not, by themselves, tell you where this airplane keeps its flap controls.
|
||||
|
||||
## Where I land
|
||||
|
||||
The comfort in all of this is that the hard part — the part that took years to build — is the part that transfers completely. You are not starting over. You’re doing a type conversion, not primary training. The four forces still balance the same way; the instruments still tell the truth if you know how to read them; and the checklist still doesn’t fly the plane — the pilot who knows when to deviate from it does. That pilot is still you. You’re just learning where the controls and instruments are.
|
||||
|
||||
@@ -7,3 +7,65 @@
|
||||
## 简介
|
||||
|
||||
Some big names in this Q&A, and they share a couple of delicious morsels.
|
||||
|
||||
## 正文
|
||||
|
||||
# 'My Boss Wants Me to Pick an AI SRE Tool': Q&A at Incident Fest (Adaptive Capacity Labs)
|
||||
|
||||

|
||||
|
||||
### Ready to make incident response your competitive advantage?
|
||||
|
||||
See how Uptime Labs builds provable, scalable incident response capability across your organisation.
|
||||
|
||||
*During* *Incident Fest 2026**, our friends over at Adaptive Capacity Labs, John Allspaw & Beth Adele Long, answered questions about the relationship between AI & humans in our virtual ‘AMA Marquee’. Here are a selection of the questions & answers.*
|
||||
|
||||
## Q: What are the safe and helpful use cases for AI in incident response based on where technology is today? Real-life examples would be very helpful.
|
||||
|
||||
**Beth Adele Long:**
|
||||
|
||||
In terms of safety, I’m a proponent of read-only access during incidents. I was going to say “unless it’s a relatively trivial / low-risk scenario,” but any write access that’s powerful enough to be useful is also likely to be dangerous. And incidents are already confusing enough without having to unwind a bizarre decision that was implemented at AI speed.
|
||||
|
||||
With that safety caveat in mind, in long-running incidents, I can certainly see AI being helpful in the same the way it’s already being used during routine work: as a thought partner to help responders figure out what’s going on and explain current behavior. (J. Paul talked about exactly this [in his talk](https://www.uptimelabs.io/incident-fest-26/main-stage), actually, and his point is ***really*** important. When AI predictions are bad, they degrade performance much more drastically than its good predictions *improve* performance.)
|
||||
|
||||
I would love to see AI tools helping responders better with pattern-matching, but again, how that information is connected and then presented to responders very much matters. I’d also love to see AI supporting incident commanders by helping them make sense of the organization itself — who’s the right SME? Who do we page? Who has been working on the current incident long enough that they’re probably burned out, and I should send them on a humanity break? These are aspects we don’t think about enough but that really matter to effective incident response.
|
||||
|
||||
## Q: My boss wants me to pick an AI SRE tool to introduce into our org. Where do I start?
|
||||
|
||||
**Beth Adele Long:**
|
||||
|
||||
Oh boy, this is a tough one. I would start by getting clear about any contrasts between purported aims and real aims. By which I mean: how much is this a pragmatic request based on specific expectations (“As a leader, I believe AI SRE will help us do X, as measured by Y”) and how much is this actually motivated by something along the lines of “the board / my VP / someone in power says we need to be using AI more, and I need you to make me look good.” The more the latter factor is in play, the less room you’ll have to negotiate based on the actual benefit of the tools. You may just have to pick something and let it play out.
|
||||
|
||||
In either case, I recommend looking at how much an AI SRE tool supports *integration into everyday work*. Are they getting lost in the leftover principle that Stu talked about, promising they’ll do work with no intervention? Or are they *making life easier for your SREs*? The latter claim is easy to test: do a pilot and see what your engineers say. Operational types are notoriously blunt and usually overloaded, so you’ll probably get a fast and honest take whether the tools are helpful or just annoying.
|
||||
|
||||
Finally: good luck. This is a tough time to be evaluating tools that are still very much in flux and figuring out how to provide genuine value.
|
||||
|
||||
## Q: AI has saved a lot of time in the incident review process: sifting through loads of data, nicely constructing the timeline and extracting patterns. It saves a lot of time doing conversations and interviews. I wonder if other folks have seen such time savings.
|
||||
|
||||
**John Allspaw:**
|
||||
|
||||
[The METR study in 2025 on developer productivity](https://arxiv.org/pdf/2507.09089) helped shine some light on how the perception of time savings/spent can be different than the actual amount of time savings/spent.
|
||||
|
||||
(Before testing, developers guessed AI would make them 24% faster. After using it, they *believed* they were 20% faster. Turns out it was actually 19% slower.)
|
||||
|
||||
I’m fascinated by this topic, so I have questions for you as well as others:
|
||||
|
||||
When it sifts through data, what data does it dismiss as unimportant?
|
||||
|
||||
Since all timelines are opinionated (because they’re constructed from raw data in ways that make sense to the author of said timeline), same question: how does the AI choose between events to include and events to dismiss?
|
||||
|
||||
## Q: When using AI in incident response, people frequently say that you have to second guess whether the AI is saying something sensible or not. Isn't that the same with humans?
|
||||
|
||||
**John Allspaw:**
|
||||
|
||||
Evaluating what your colleague has said while you’re both responding to an incident is clearly something happens, yep. Whether or not you’re “second guessing” what they’re asserting depends entirely on your experience with the person in the past, what they’ve said earlier in the response, how they described how they arrived at what they’re saying, etc.
|
||||
|
||||
I’d guess that many people with experience responding to incidents can think of other ways that a human coworker’s contributions might be different than an AI agent’s contributions during an incident…?
|
||||
|
||||
**Beth Adele Long:**
|
||||
|
||||
To expand on John’s remark about “your experience with the person in the past”: with humans we have a deep intuitive sense of *how* to judge someone’s trustworthiness. The engineer who’s been at the company for 5 years and deeply knows this system gets weighted differently than a new hire; the person who’s “often wrong, never in doubt” gets more skepticism than the quiet person who only speaks up when they really know what’s going on. AI usually falls into the “often wrong, never in doubt” bucket! And my experience is that it’s a lot more expensive to evaluate AI’s wall of text in an incident than to guess the trustworthiness of a colleague’s terse assertion. Humans tend to be more efficient at building a shared context as a group (thanks, evolution). So yes, the second guessing is always happening at some level, but *how* that process unfolds is different in important ways.
|
||||
|
||||
*To see the full range of Q&As, you can explore* *Incident Fest here**.*
|
||||
|
||||
|
||||
|
||||
@@ -9,3 +9,153 @@
|
||||
A super-engaging deep-dive.
|
||||
|
||||
> This investigation is a useful reminder: running boring technology in a non-standard way is a risk.
|
||||
|
||||
## 正文
|
||||
|
||||
At the end of last year, our uptime was [pretty shaky](https://tailscale.com/blog/hypergrowth-isnt-always-easy). You can see this trend on [our status page](https://status.tailscale.com/history), and that instability continued into the new year. Many of these outages were caused by a single bug, deep in [SQLite](https://sqlite.org/index.html). It took months of intense forensics to track it down.
|
||||
|
||||
Now we’re in summer, we’re confident that we’ve found the bug, that we understand it—and more importantly, that we’ve fixed it.
|
||||
|
||||
We know our customers expect Tailscale to be a reliable service, and for several months we didn’t live up to that promise. That’s disruptive, and we’re sorry. We’re publishing this blog post to explain what went wrong, how we responded, and how we ultimately helped to uncover a long-standing bug in the heart of the SQLite database.
|
||||
|
||||
## [Tailscale’s database architecture](https://tailscale.com#tailscales-database-architecture)
|
||||
|
||||
While our clients interact with our [control plane](https://tailscale.com/docs/concepts/control-data-planes) as a single public endpoint ([controlplane.tailscale.com](http://controlplane.tailscale.com)), internally, our control plane is split into a series of coordination servers (or “shards”). Each tailnet lives on one internal shard at a time, but can migrate seamlessly from one to another. These shards are an internal implementation detail: you don’t know what shard your tailnet is on, and you never need to.
|
||||
|
||||
Each shard has an SQLite database that holds all the information about the tailnets on that shard. A single Go process exclusively accesses that database, and serves the control plane for those tailnets. This single-writer design is exactly how SQLite is meant to be used.
|
||||
|
||||
We’ve used SQLite as our primary database [since 2022](https://tailscale.com/blog/database-for-2022), and we chose it because it's well-known, reliable, and widely used. SQLite is [“boring technology”](https://mcfunley.com/choose-boring-technology)—in a good way. Many companies use SQLite in much larger deployments without issue, and we expected the same stress-free usage.
|
||||
|
||||
In our current backup pipeline, we take a complete snapshot of the database every few minutes, then upload the entire SQLite file to an S3 bucket. We’d been running this setup without incident since early 2023.
|
||||
|
||||
Fast forward to August last year, when a data pipeline that reads those S3 backups reported an error in one of our databases. We ran SQLite’s `PRAGMA integrity_check` command against the backup, and found it was indeed corrupted. SQLite corruption [is possible](https://www.sqlite.org/howtocorrupt.html), but it’s highly unusual and not something you should encounter in normal operation. We repaired the affected database, and investigated the cause, but to no avail.
|
||||
|
||||
When operating at scale, even rare events can occur with some frequency, so we should have been unsurprised when it happened again—and again, and again, and again. In total, we faced 19 separate instances of database corruption over six months before we finally resolved the underlying bug.
|
||||
|
||||
When you hear the phrase “database corruption”, it’s natural to worry about data loss. Because our control plane only handles configuration data, these databases contain metadata about your tailnet and devices, but never your private encryption keys or network traffic. In the earliest incidents, the recovery process meant a handful of newly added devices or configuration changes didn’t persist, and a small amount of metadata had to be re-entered.
|
||||
|
||||
Whenever corruption occurred, we had to stop the control plane process on the shard while we repaired or restored the database. This was painful for tailnets on that shard, because their entire control plane disappeared during that recovery window. In the early incidents, that downtime was over an hour, but we gradually sped up the recovery process over subsequent incidents.
|
||||
|
||||
Each tailnet is a mesh network, where devices make peer-to-peer WireGuard® connections to each other. When a device joins the tailnet, it has to get a list of other devices from the control plane before it can establish new connections—so if a device came online during the SQLite downtime, it couldn’t connect. While the database was being repaired, devices already online remained connected to each other, but they couldn’t learn about changes to the network. Those tailnets also temporarily lost access to the web-based admin console and the Tailscale API.
|
||||
|
||||
There’s also a broader impact on trust. We post a global incident on [our status page](https://status.tailscale.com/) even when only a small number of tailnets are affected. Many people saw a status page event for an incident that didn’t affect them. Indeed, the majority of shards and tailnets were never involved in a database corruption incident! Nonetheless, repeated downtime erodes trust, whether or not you’re directly affected.
|
||||
|
||||
From the very first instance of corruption, we knew this was a serious threat to our reliability, and we threw a lot of engineering time at the problem—but the fix wasn’t easy.
|
||||
|
||||
## [Trying to find the fault](https://tailscale.com#trying-to-find-the-fault)
|
||||
|
||||
This bug resisted all our initial attempts to find it.
|
||||
|
||||
We looked at recent changes, but there weren’t any that seemed relevant. Nobody had been working on our low-level code that interacts with SQLite, because it had all been written years ago and presented no issues up until that point. We re-reviewed all of that code with a fine-toothed comb to look for previously missed bugs, but we didn’t find anything that would cause the corruption we were seeing.
|
||||
|
||||
We looked for common factors between corruption incidents, but we couldn’t find any. It wasn’t tied to a single shard, or customer, or tailnet feature, or time of day, or load level. We were at a loss for what might be triggering the behaviour.
|
||||
|
||||
This lack of reliable trigger conditions meant we couldn’t reproduce the bug synthetically. Instead, we had to rely on deploying passive, forensic telemetry in our live environment to catch the corruption red-handed. Gathering live diagnostics for a database issue is the last thing we wanted to do, but we had no choice.
|
||||
|
||||
As an additional complication, the corruption didn’t occur on a regular schedule. Sometimes incidents would be hours apart, other times weeks. This made it difficult to predict progress or plan further work, because we were never sure when we’d get our next diagnostic dump. We had a six-week period between October and December when there were no corruption incidents, before they returned as an unwelcome Christmas present.
|
||||
|
||||
Because this wouldn’t be a quick or easy fix, we reached out to the SQLite developers for a [professional support contract](https://sqlite.org/prosupport.html). This was a great decision. It gave us direct access to their deep expertise and experience, and we had many detailed technical conversations about our architecture and our incidents.
|
||||
|
||||
Between Tailscale engineering and the SQLite core developers, we mapped out several theories for what might be causing the corruption—including [broken POSIX locks on close()](https://www.sqlite.org/howtocorrupt.html#_posix_advisory_locks_canceled_by_a_separate_thread_doing_close_), mismanaging memory owned by SQLite, or accidentally using SQLite from multiple threads [while disabling thread safety](https://sqlite.org/compile.html#threadsafe). After every incident, we gathered more data, added more diagnostics, and systematically ruled out these theories. We were gradually converging on the true bug.
|
||||
|
||||
## [The transactions that didn’t bark](https://tailscale.com#the-transactions-that-didnt-bark)
|
||||
|
||||
While we were investigating the root cause, we still had a live platform to run. We took aggressive steps to automate recovery and minimize downtime:
|
||||
|
||||
- Configuring our control plane shards to hard-stop immediately upon encountering corruption
|
||||
- Deploying an automated backup monitor that continuously ran `PRAGMA integrity_check` over our backups
|
||||
- Improving our runbooks and on-call training
|
||||
|
||||
These efforts cut our response time to under an hour—and then we discovered an unexpected clue.
|
||||
|
||||
We wanted a way to restore service that didn’t involve rolling back to the last known-good backup (which would lose a lot of data) or repairing the known-corrupted database (which was potentially risky).
|
||||
|
||||
To do this, we built a transaction logging pipeline. We streamed every SQL statement that modified the database to a separate log file. Because SQLite is [a single-writer database](https://sqlite.org/faq.html#:~:text=only%20one%20process%20can%20be%20making%20changes%20to%20the%20database%20at%20any%20moment%20in%20time) with [serialisable transactions](https://www.sqlite.org/isolation.html), our transaction history was completely linear and deterministic. (This wouldn’t be true in a multi-writer database like Postgres or MySQL.) Replaying those transactions against the latest known-good backup should restore the database to its most recent state, safely bypassing the corruption.
|
||||
|
||||
This pipeline worked, but then it did something even better: it gave us a clue.
|
||||
|
||||
In two incidents, our transaction logs failed to replay cleanly. Upon closer inspection, we discovered that data written and committed by one transaction was inexplicably invisible to later transactions. A write had vanished into thin air without raising an error. That should be impossible!
|
||||
|
||||
## [The writing on the WAL](https://tailscale.com#the-writing-on-the-wal)
|
||||
|
||||
As these incidents were ongoing, the SQLite developers had been developing a new debugging tool. For a while, we’d suspected that the bug was somewhere in the checkpoint process. They were building a new tool to give better visibility into what was happening during checkpoints.
|
||||
|
||||
To understand what this tool found, we need to briefly explain how SQLite checkpoints work.
|
||||
|
||||
A SQLite database is made of a series of “pages”, tiny blocks of information. When you update the database, some of those pages need to be replaced with new pages with the updated information.
|
||||
|
||||
For better performance and greater concurrency, we run SQLite with Write-Ahead Logging, which means new pages aren't written directly to the database file. Instead, they’re written to the "write-ahead log" or "WAL file".
|
||||
|
||||
New pages can't be written to the WAL file indefinitely; at some point they have to be copied back to the main database file. This process is called “checkpointing”.
|
||||
|
||||
In most deployments, SQLite itself decides when to do a checkpoint, and the process is invisible to the end user and developer. In our control plane, we take manual control of the checkpoint process so we can run fast and consistent backups. This non-standard approach seemed suspicious as we steadily eliminated potential causes.
|
||||
|
||||
One clue was that during corruption incidents, our metrics showed that SQLite would report copying more pages from the WAL file than were actually available. If there are 10 pages in the WAL file and 20 pages get copied to the database, something is clearly wrong.
|
||||
|
||||
To understand what was happening during these faulty checkpoints, the SQLite developers created a new debugging tool for the virtual filesystem layer.
|
||||
|
||||
SQLite is split into several layers. The top layer is the parser and code generator, which converts SQL statements into SQLite’s internal data structures. These data structures get passed to the pager, which splits them into the individual pages to be written to disk. Actually writing them to disk is handled by the OS interface, or “virtual filesystem”. Currently SQLite has two mainstream virtual filesystem implementations—Unix and Windows.
|
||||
|
||||
If you're interested in a deeper dive on these internals, I recommend [this lecture by Richard Hipp](https://www.youtube.com/watch?v=ZSKLA81tBis), the primary author of SQLite.
|
||||
|
||||
This approach allows you to replace different layers with different implementations, or wrap an existing layer to get more information. To help diagnose our problem, the SQLite developers created a wrapper around the virtual filesystem that writes additional tracing information and logs about changes to the database. This wrapper is called the `tmstmpvfs` shim, and the source code is available in the [SQLite public repository](https://sqlite.org/src/file/ext/misc/tmstmpvfs.c?proof=394548354).
|
||||
|
||||
We deployed the shim into our live environment, and waited for the next corruption to occur. Fortunately, we didn't have to wait long.
|
||||
|
||||
## [The WAL-Reset bug](https://tailscale.com#the-wal-reset-bug)
|
||||
|
||||
After our next corruption incident, the additional logs from the new `tmstmpvfs` shim allowed the SQLite developers to find and fix the bug: a rare data race in the SQLite source code between a checkpoint and a write transaction.
|
||||
|
||||
In particular, if a write occurs at a specific time during a checkpoint, the checkpointing process gets confused—it thinks some of the pages have been copied from the WAL into the main database file, but they haven’t. Those pages never get written to the database file, and that data is permanently lost. The database file becomes corrupt, because other pages which reference those pages—such as an index—are written to the database.
|
||||
|
||||
The SQLite developers named this the [“WAL-Reset bug”](https://sqlite.org/wal.html#the_wal_reset_bug), and they estimate it was present in SQLite for at least 16 years. It could exist that long because it was rare—so rare, the SQLite developers had to add code to deliberately trigger it in their testing environments. Their fix adds [an additional check to the checkpointing function](https://sqlite.org/src/info/7168988acbec2d8d) which detects when the WAL has been reset by another thread.
|
||||
|
||||
They confirmed that this bug caused all of the baffling behaviour we’d seen. It explained the corruption, the transaction logs that wouldn’t apply cleanly, and the inconsistent checkpoint statistics. They also explained why we were more likely to hit the bug than other SQLite users: we take manual control of the checkpointing process, and we checkpoint very aggressively. Even a bug triggered by a rare condition was bound to hit us eventually.
|
||||
|
||||
This was an exciting moment. After months of confusion and uncertainty, we finally had a plausible theory for why the corruption was occurring, and a fix we could deploy to prevent it.
|
||||
|
||||
The SQLite developers released the fix as [SQLite 3.52.0](https://sqlite.org/changes.html#version_3_52_0), and we prepared to deploy it as soon as it was available.
|
||||
|
||||
## [Fixed, with a false alarm](https://tailscale.com#fixed-with-a-false-alarm)
|
||||
|
||||
We rolled out SQLite 3.52.0 carefully—first to a few canary shards, then, when we saw it running smoothly, we deployed it to the rest of the control plane.
|
||||
|
||||
Our backup monitor promptly turned red, and reported corruption in **13 different databases**. This was extremely alarming, but we followed our recovery procedures to fix all the supposed corruption, and everything was happy. It turned out these databases had not suffered real corruption, but were subject to a second problem in the version of SQLite.
|
||||
|
||||
We shared our errors with the SQLite developers, which uncovered a bug in SQLite related to [stale expression indexes](https://sqlite.org/staleexpridx.html). If you create an index on a computed value, and then the computation changes, the index will contain mismatched values, which gets reported as corruption by `PRAGMA integrity_check`.
|
||||
|
||||
In our case, we were storing some high-precision timestamps as text, converting them to a floating-point number in a VIRTUAL generated column, and the SQLite 3.52.0 release that fixed our data race also made [an optimisation](https://research.swtch.com/fp) that subtly changed the rounding behaviour for text-to-floating-point conversions. Our canary shards didn’t have any timestamps that triggered the changed rounding behaviour, so we missed this in our phased rollout.
|
||||
|
||||
Because this change caused false corruption warnings, the SQLite developers withdrew the 3.52.0 release and instead published 3.51.3, which only contained a fix for the WAL-Reset bug.
|
||||
|
||||
We fixed the issue on our side by reducing the precision of our timestamps to integer seconds; text-to-integer conversions are unambiguous. Meanwhile, the SQLite developers created an automated, [self-healing index feature](https://sqlite.org/staleexpridx.html#selfheal) in 3.53.0, which prevents the stale expression index problem.
|
||||
|
||||
## [Party time!](https://tailscale.com#party-time)
|
||||
|
||||
With the fix rolled out to our entire control plane, we were ready to declare victory, but we were still cautious. An absence of corruption incidents doesn’t mean things are fixed—we’d already had one six-week period of deceptive calm.
|
||||
|
||||
We wanted positive proof that this data race was actively occurring in our production environment. Now that we understood the cause of the bug—a collision between a write transaction and a WAL-reset—we patched our SQLite driver to [log a warning](https://github.com/tailscale/sqlite/commit/070c921dea03f793cbbbd9d39551d0ad26136113#diff-fcff16fa73210758d3a31f4cfa4609ad5b3ca692b66fc7fb7587c08a1ab11048) when these two operations overlap. If the warning fired but the database remained uncorrupted, we’d know the fix had saved us from a potential corruption incident.
|
||||
|
||||
We deployed the warning, and we waited. And we waited. And waited. And waited. As weeks slipped by, we began to wonder why we didn’t see it. Was the warning broken? Was our theory wrong? Was the true bug still lurking in the darkness?
|
||||
|
||||
Then, two months later, the alert we were waiting for finally fired:
|
||||
|
||||
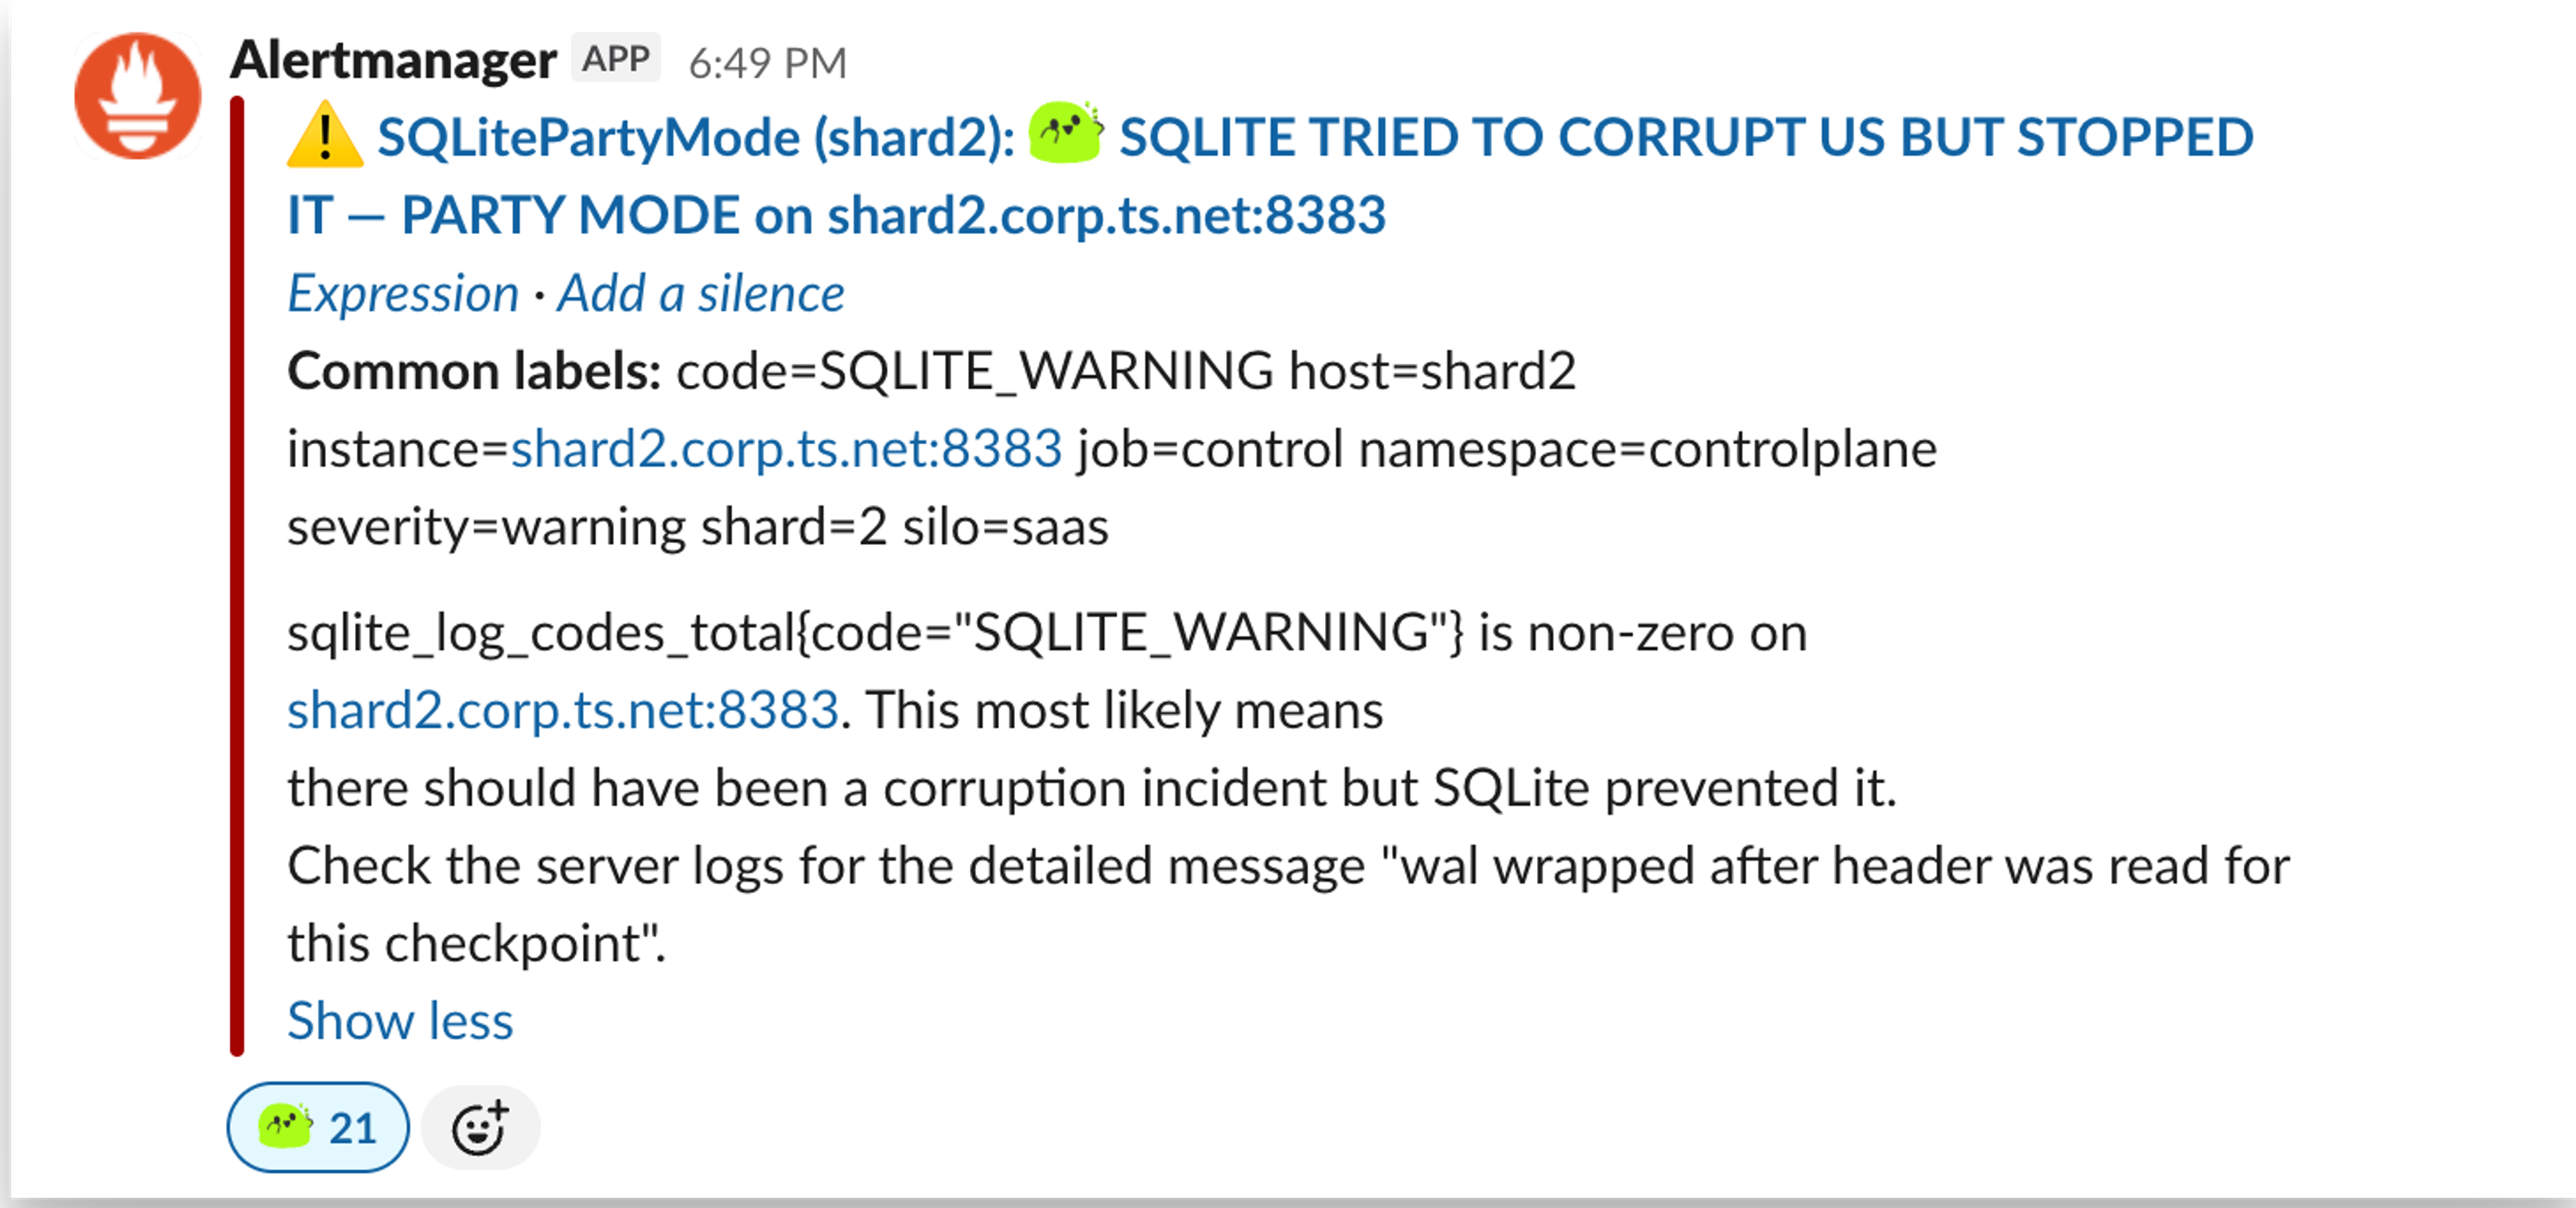
|
||||
|
||||
This alert proved that the precise conditions for the WAL-Reset bug *do* occur in our production environment, which means it was the likely culprit for our six months of shaky uptime.
|
||||
|
||||
Since that weirdly joyous alert fired, we’ve run for another four months without any database incidents, as of this writing. Finally, we could breathe a sigh of relief.
|
||||
|
||||
## [Off the well-trodden path](https://tailscale.com#off-the-well-trodden-path)
|
||||
|
||||
Nobody wanted us to spend six months looking for bugs in SQLite. This was an immensely frustrating experience for both our customers and staff, and we’re all glad to put this instability behind us.
|
||||
|
||||
This investigation is a useful reminder: **running boring technology in a non-standard way is a risk.** The common paths and standard configurations are incredibly well-tested and reliable. Most people use SQLite in a standard configuration and never face this sort of issue. Everything we were doing was a public, documented, supported configuration—but by taking manual control of the checkpointing process and running at our own aggressive pace, we stepped off the well-trodden operational path.
|
||||
|
||||
Resolving these incidents was a massive, cross-functional effort involving dozens of people—including Tailscale's engineering and support teams, and the core maintainers of SQLite. It is to all of their credit that the impact of these incidents was not much worse.
|
||||
|
||||
We know that repeated downtime erodes trust, no matter how many people are affected, and we’re grateful to our customers for their patience and support while we chased this down.
|
||||
|
||||
Frustrating as this period was, we’re left in a stronger position than we were before. The long-standing bug in SQLite has been patched, and we fixed dozens of other incidental issues that we spotted while looking for it. We funded the open-source SQLite VFS shim that helped isolate the race condition almost immediately, and will help track down similar bugs in the future. Finally, we’ve refined our database backup and recovery processes, and live-tested them over a dozen times.
|
||||
|
||||
Hopefully there won’t be another database incident like this—but if there is, we’ll be ready.
|
||||
|
||||
@@ -7,3 +7,134 @@
|
||||
## 简介
|
||||
|
||||
A handy guide on topology constraints in Kubernetes, with a worked example.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
# Optimizing Kubernetes pod deployments for reliability with topology spread constraints
|
||||
|
||||
If you’re like many Kubernetes users, you don’t pay much attention to where or how Kubernetes distributes your pods. As long as they’re running, it doesn’t matter where they get deployed, right? Surely Kubernetes will use some complex algorithm to figure out the most reliable way to distribute your pods across the cluster…right?
|
||||
|
||||
Pod distribution plays a much bigger role in reliability than you might think. Fortunately, it’s easy to control when, where, and how Kubernetes distributes pods. By adding a few lines to your manifest, you can ensure your deployments are zone-redundant and evenly scalable. The feature is called *topology spread constraints*, and in this blog, we’ll explain how it works in full detail.
|
||||
|
||||
|
||||
## Why are topology spread constraints important for reliability?
|
||||
|
||||
[Topology spread constraints](https://kubernetes.io/docs/concepts/scheduling-eviction/topology-spread-constraints/) determine how Kubernetes distributes pods across failure domains, such as regions, zones, and nodes. This helps ensure your workloads are truly distributed not just across the cluster, but across your operating environment. You can set cluster-level constraints as a default, or set constraints for individual workloads.
|
||||
|
||||
|
||||
### How to configure topology spread constraints
|
||||
|
||||
Topology spread constraints are defined using the field spec.topologySpreadConstraints. These can be applied to a pod or to the cluster. Constraints have the following fields:
|
||||
|
||||
- `maxSkew` : the degree to which pods may be unevenly distributed. Its behavior depends on the value of`whenUnsatisfiable` :
|
||||
- If `whenUnsatisfiable: DoNotSchedule` , this determines the maximum difference between the minimum number of pods in the domain vs. the number of matching pods in the target topology. In other words, this is how far off the minimum a domain is allowed to get.
|
||||
- If `whenUnsatisfiable: ScheduleAnyway` , Kubernetes gives a higher precedence to topologies that would help reduce the skew.
|
||||
- If
|
||||
- `minDomains` : the minimum number of eligible domains (e.g. availability zones or regions).
|
||||
- `topologyKey` : the node label used to identify nodes used for this constraint. Any nodes that have this label are grouped into topology domains according to their values. For example, using`topology.kubernetes.io/zone` as a key creates domains based on the availability zones your hosts span.
|
||||
- `whenUnsatisfiable` : how to handle pods that don’t satisfy the spread constraint. By default, it won’t be scheduled (`DoNotSchedule` ). Setting this to`ScheduleAnyway` schedules the pod regardless, prioritizing nodes that minimize the`maxSkew` .
|
||||
- `labelSelector` : the pod label used to find matching pods.
|
||||
- `matchLabelKeys` : a list of pod label keys to use to calculate the spreading skew.
|
||||
- `nodeAffinityPolicy` : determines how to treat each pod’s`nodeAffinity` and`nodeSelector` settings.`Honor` (the default) limits the topology calculation to these nodes, while`Ignore` uses all nodes.
|
||||
- `nodeTaintsPolicy` : determines whether to include node taints in the topology calculation.
|
||||
|
||||
Note that you can define only one `topologySpreadConstraint` for a given `topologyKey` and `whenUnsatisfiable` pair.
|
||||
|
||||
|
||||
## How to add a topology spread constraint to a Kubernetes manifest
|
||||
|
||||
Imagine we have a Kubernetes cluster distributed across three availability zones: us-east-1a, us-east-1b, and us-west-2a. We also have a pod that we want to deploy and replicate for redundancy. We’ll start with the following manifest:
|
||||
|
||||
|
||||
If we deploy four replicas of the pod using a round-robin algorithm, we end up with one node with two pods and two nodes with one pod:
|
||||
|
||||
|
||||
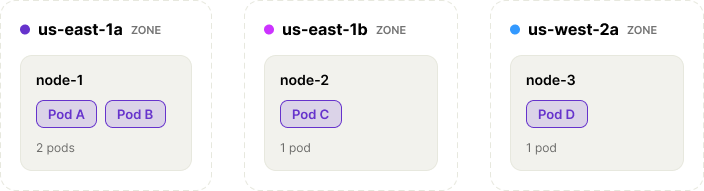
|
||||
|
||||
|
||||
However, the Kubernetes scheduler might deploy two pods to two nodes, leaving one empty; or it might deploy three pods to us-east-1a and one to us-east-1b, which puts us at risk if the us-east region ever goes down. Or, in the worst case, it could deploy all four to one node and create a single point of failure.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
1. Let’s first limit the pod imbalance by setting `maxSkew` to 1. This ensures that no single node has more than one additional replica of the pod than any other node.
|
||||
2. Next, we’ll set the `topologyKey` to`topology.kubernetes.io/zone` , since we want to limit the spread by zone even if our zones span multiple regions.
|
||||
3. We want Kubernetes to run the pod even if it can’t satisfy our topology constraints, so we’ll set `whenUnsatisfiable` to`ScheduleAnyway` .
|
||||
4. We want to match all Nginx pods (in this deployment, anyway), so let’s add a `labelSelector` that matches`app: nginx` .
|
||||
|
||||
Now, our manifest looks like this:
|
||||
|
||||
|
||||
## How to find pods with missing topology spread constraints
|
||||
|
||||
You can use the `kubectl` command-line tool to retrieve a list of pods, then use the `jq` command-line tool to filter pods that don’t have `topologySpreadConstraints` defined. For example:
|
||||
|
||||
|
||||
You can also use Gremlin’s built-in [Detected Risks](https://www.gremlin.com/docs/reliability-management-detected-risks#toc-topology-spread-constraints-absent) feature to automatically scan your Kubernetes pods for missing topology spread constraints.
|
||||
|
||||
Once you’ve added your constraints, re-run this command to ensure your pods don’t appear in the output. If you’re using Gremlin, the “[topology spread constraints absent](https://www.gremlin.com/docs/reliability-management-detected-risks#toc-topology-spread-constraints-absent)” risk status will automatically change from “at-risk” to “mitigated” and your service’s reliability score will increase.
|
||||
|
||||
|
||||
## Combining topology spread constraints, node affinity rules, and taints and tolerations
|
||||
|
||||
As we already saw, topology spread constraints can interact with other Kubernetes features, particularly [node affinity rules](https://kubernetes.io/docs/concepts/scheduling-eviction/assign-pod-node/#affinity-and-anti-affinity) and [taints and tolerations](https://kubernetes.io/docs/concepts/scheduling-eviction/taint-and-toleration/). But there are subtle differences between these.
|
||||
|
||||
Affinity rules define the specific criteria for scheduling a pod on a node. For example, a pod running a large language model (LLM) might have an affinity rule that requires a node with a GPU. This way, you can combine affinity rules and topology spread constraints to limit the domain of nodes available to a pod. Just make sure you set `nodeAffinityPolicy: Honor` (the default).
|
||||
|
||||
Conversely, taints specify where *not* to schedule a pod unless it has a matching toleration. If a node’s GPU crashes due to a driver issue, you don’t want Kubernetes scheduling LLMs onto that node. Instead, you can apply a taint that prevents Kubernetes from scheduling pods on that node, while also migrating running pods onto new nodes. Like affinity rules, these work in tandem with topology spread constraints by limiting the size of the domain, as long as you set `nodeTaintsPolicy: Honor`.
|
||||
|
||||
|
||||
## Other Kubernetes risks to watch out for
|
||||
|
||||
Topology spread constraints are just one piece of a resilient Kubernetes deployment. If you want to know how to protect yourself against other risks like missing liveness probes, unset resource requests, and improperly configured high-availability clusters, check out our comprehensive ebook, "Kubernetes Reliability at Scale."
|
||||
|
||||
In the meantime, if you'd like a free report of your reliability risks in just a few minutes, you can sign up for a free 30-day Gremlin trial, or use Gremlin's [Detected Risks](https://www.gremlin.com/docs/reliability-management-detected-risks#toc-topology-spread-constraints-absent) feature to automatically scan your existing Kubernetes pods for missing topology spread constraints.
|
||||
|
||||
|
||||
**Start your free trial**
|
||||
|
||||
Gremlin's automated reliability platform empowers you to find and fix availability risks before they impact your users. Start finding hidden risks in your systems with a free 30 day trial.
|
||||
|
||||
[sTART YOUR TRIAL](https://www.gremlin.com/trial)
|
||||
|
||||
To learn more about Kubernetes failure modes and how to prevent them at scale, download a copy of our comprehensive ebook
|
||||
|
||||
[Get the Ultimate Guide](https://www.gremlin.com/whitepapers/kubernetes-reliability-at-scale-how-to-improve-uptime-with-resiliency-management?utm_source=cta&utm_medium=webpage&utm_campaign=on_page_cta_kub_rel_at_scale+)
|
||||
|
||||
[Back to top](https://www.gremlin.com#single-article)
|
||||
|
||||
|
||||
## How to troubleshoot unschedulable Pods in Kubernetes
|
||||
|
||||
Kubernetes is built to scale, and with managed Kubernetes services, you can deploy a Pod without having to worry...
|
||||
|
||||

|
||||
|
||||
Kubernetes is built to scale, and with managed Kubernetes services, you can deploy a Pod without having to worry...
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/how-to-fix-kubernetes-unschedulable-pods)
|
||||
|
||||
|
||||
## How to ensure consistent Kubernetes container versions
|
||||
|
||||
One of Kubernetes' killer features is its ability to seamlessly update applications no matter how large your deployment is. Did a developer make a code change, and now you need to update a thousand running containers? Just run kubectl apply -f manifest.yaml and watch as Kubernetes replaces each outdated pod with the new version.
|
||||
|
||||

|
||||
|
||||
One of Kubernetes' killer features is its ability to seamlessly update applications no matter how large your deployment is. Did a developer make a code change, and now you need to update a thousand running containers? Just run kubectl apply -f manifest.yaml and watch as Kubernetes replaces each outdated pod with the new version.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/kubernetes-container-image-version-uniformity)
|
||||
|
||||
|
||||
## Managing slow container starts with Kubernetes readiness probes
|
||||
|
||||
Pods without readiness probes are like engineers without coffee. Learn how readiness probes work, why they’re important, and how to configure them correctly.
|
||||
|
||||

|
||||
|
||||
Pods without readiness probes are like engineers without coffee. Learn how readiness probes work, why they’re important, and how to configure them correctly.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/managing-slow-container-starts-kubernetes-readiness-probes)
|
||||
|
||||
Reference in New Issue
Block a user