sreweekly: 528 期数据 + 全文抓取(articles/pages + markdown 正文扩充)
This commit is contained in:

@@ -7,3 +7,47 @@
|
||||
## 简介
|
||||
|
||||
Need another team to do something fast? Just use this one weird trick: declare an incident! This article explains why the obvious solution (gating incident declaration) isn’t a good idea.
|
||||
|
||||
## 正文
|
||||
|
||||
You see someone declare a Sev-2 and you wonder: wait, why is that even an incident? Nothing is down. Customers aren’t affected. But a manager needed to get their team’s problem to the top of another team’s priority queue, and the incident process was a reliable way to make it happen. That’s not really what the incident process is for, but it worked, so where’s the harm?
|
||||
|
||||
The problem is, once folks see that this works, it starts happening more often. A product manager declares an incident because the incident notification is the fastest way to get leadership attention on a problem that’s been stuck in the backlog for weeks. An account team declares one because they need engineering support for a big demo to a major prospect and the incident process is the easiest way to pull engineers out of their sprint work on short notice. An engineer declares one because it’s easier than navigating the formal exception process for the deployment freeze.
|
||||
|
||||
The harm is cumulative. When a growing fraction of your declared “incidents” aren’t real emergencies, the urgency signal degrades. When a genuine Sev-1 arrives, people respond with less urgency because they’ve been conditioned to expect another workaround. And the incentives compound: folks who game the system get their problems solved faster, which teaches everyone else that gaming is how to get things done. Each individual declaration is an understandable decision by someone who needs to get something done; it’s the aggregate that corrodes the process.
|
||||
|
||||
Every one of these non-emergency declarations still carries the full overhead of a real incident. Responders get pulled off their planned work. Someone drops whatever else they were doing to serve as incident commander. Stakeholders context-switch to follow along. When you’re running enough of these, your teams are spending a meaningful fraction of their time in emergency mode for things that aren’t really emergencies, and all the indirect costs of incidents (disrupted projects, context-switching, recovery time) accumulate just the same.
|
||||
|
||||
There’s an irony here: people are reaching for the incident process *because* it works; they’ve seen that it reliably delivers coordination, prioritization, and urgency on demand.
|
||||
|
||||
## The instinctive response is wrong
|
||||
|
||||
When companies notice this pattern, the instinctive response is often to tighten the declaration criteria. They add gatekeeping: maybe you need manager approval to declare an incident, or there’s a pre-declaration checklist you have to complete first, or someone reviews whether the declaration was “warranted” after the fact. The intent is reasonable. The net effect is corrosive.
|
||||
|
||||
Gatekeeping incident declarations is counterproductive. Every speedbump you build also slows down real incidents. The person who hesitates to declare because they’re not sure the problem is “bad enough” is already a common failure mode in incident response. Adding a formal approval step or a post-hoc review of whether the declaration was justified makes that hesitation worse, not better.
|
||||
|
||||
You also miss what the gaming is telling you: people reaching for the incident process are telling you that your normal processes are falling short. If you only crack down on the gaming, you suppress the symptom without learning anything from it, and the underlying problems persist.
|
||||
|
||||
## Fix the escape routes, not the escaping
|
||||
|
||||
Instead, look at what side effects people are trying to trigger when they declare questionable incidents, and make those capabilities available through other means.
|
||||
|
||||
If the easiest way to bypass the deployment freeze is to declare an incident, create a non-incident exception process for urgent changes. This doesn’t have to be complicated; a lightweight approval from a designated release manager, with a clear escalation path, covers most cases.
|
||||
|
||||
If the easiest way to get your problem moved up another team’s priority queue is to declare an incident, create a prioritization escalation path that doesn’t require an incident. A cross-team triage meeting, an explicit expedite-request mechanism, or even a dedicated Slack channel that the right people actually monitor can absorb most of the pressure. The bar doesn’t have to be as high as “declare an emergency”; it just has to be lower than “wait six weeks for the next planning cycle.”
|
||||
|
||||
If the easiest way to assemble a cross-functional team on short notice is through the incident process, create a lightweight coordination mechanism for non-incident situations. Some companies call these “swarms” or “tiger teams” or “coordination requests.” The name doesn’t matter; what matters is that people have a way to get the collaboration they need without borrowing the incident process to do it.
|
||||
|
||||
Repeatedly gaming the incident process to get resource prioritization or cross-functional coordination isn’t a series of one-off workarounds; it’s a symptom of a systemic problem that needs a systemic response. Google’s SRE organization built formal [Code Yellow and Code Red](https://www.theengineeringmanager.com/growth/code-yellow-code-red/) mechanisms for exactly this: structured ways to rally resources and elevate priority when a problem is serious enough to demand cross-functional attention, but isn’t an incident.
|
||||
|
||||
## The diagnostic question
|
||||
|
||||
Look at your last dozen or so incidents and ask, for each one: was this declared because there was an emergency, or because the incident process was the easier path to something the team needed?
|
||||
|
||||
You don’t need a formal audit. Just ask a few experienced incident commanders and on-call engineers; they already know which ones were real and which ones weren’t. Then talk to the folks who called for the questionable ones (in a blameless, fact-finding way, of course). They’ll tell you exactly what’s missing from the normal processes, if you’re willing to listen.
|
||||
|
||||
People gaming the incident process is just a symptom. The underlying problem is usually that normal processes are too rigid, too slow, or too unresponsive, and the incident process is the path of least resistance. Fix the underlying problem and the gaming stops, because there’s nothing left to game around. Your incident urgency signal recovers, your teams stop burning emergency-mode cycles on non-emergencies, and when a real Sev-1 hits, people respond like it matters.
|
||||
|
||||
And if you’re dealing with this, take a moment to appreciate what it says about your incident process: people are borrowing it because it *works*. The fix isn’t to make it stop working. It’s to make everything else work that well too.
|
||||
|
||||
## Recent Comments
|
||||
|
||||
@@ -7,3 +7,7 @@
|
||||
## 简介
|
||||
|
||||
Ethics are relative, right? This article is full of genuinely useful tips and framings.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
|
||||
@@ -7,3 +7,291 @@
|
||||
## 简介
|
||||
|
||||
Whoa. It’s been quite a few years since my last run-in with an overfull conntrack table, and this is a fun new twist.
|
||||
|
||||
## 正文
|
||||
|
||||
[Knowledge Hub](https://www.adyen.com/knowledge-hub)
|
||||
|
||||
Article
|
||||
|
||||
# Inside Cilium CNI: solving mysterious Kubernetes pod setup timeouts
|
||||
|
||||
A deep dive into how Adyen's Data Platform Engineering team investigated and resolved linear-time scaling bottlenecks in Cilium CNI connection tracking garbage collection to fix mysterious Kubernetes pod setup timeouts on high-resource nodes.
|
||||
|
||||
I was fully aware a year ago that a single configuration line could break the Kubernetes networking stack. But if they told me that leftovers from Kubernetes pods which terminated hours prior could block new ones from starting, I would have thought they were joking.
|
||||
|
||||
In high-performance networking, 35 seconds is a lifetime. This was the latency required to iterate through our connection tracking table of 7 million entries at a maximum speed of 200,000 entries per second. At our 16-million-entry peak, this sequential lookup could take up to 80 seconds, leading to Cilium CNI timeouts preventing new pods from starting on affected nodes.
|
||||
|
||||
We uncovered this linear-time behavior at Adyen by tracing syscalls, inspecting codebases, and analyzing eBPF internals. This investigation revealed how our varied workloads turned the connection tracking table's garbage collection algorithm into a critical bottleneck.
|
||||
|
||||
## Our setup: why we're different
|
||||
|
||||
At Adyen, we run Cilium CNI across all our 100+ Kubernetes clusters. When we switched from Calico to Cilium, we knew we'd face challenges adapting it to our production workloads. Our production big data Kubernetes clusters have a unique usage pattern compared to the other Kubernetes environments within Adyen:
|
||||
|
||||
**Data extraction from HDFS**. Our infrastructure relies on more than 500 datanodes. Trino represents one of our most demanding HDFS workloads, processing analytical queries against data stored on HDFS. Due to the distributed nature of HDFS, each file you download requires a new connection to any of these 500 nodes. Therefore, during peak hours, a single pod can produce approximately 50,000 connections every minute.
|
||||
|
||||
**Pod churn.** Many pods we spawn on the Kubernetes cluster run batch jobs, such as Spark jobs. They stay around for anywhere from a second to a couple of hours.
|
||||
|
||||
**Wide variety of workloads.** Some workloads are very CPU-intensive, like Spark pods executing complex joins and transformations with relatively few network connections. Others are extremely network-intensive, like Trino pods querying thousands of small files on HDFS, each requiring a new connection. This creates a large number of short-lived connections that stress the connection tracking table.
|
||||
|
||||
Furthermore, our machines are more powerful than most Kubernetes cluster machines within Adyen:
|
||||
|
||||
- Machines with 64 physical cores and 512GB of RAM
|
||||
- Machines with 128 physical cores and 2TB of RAM
|
||||
|
||||
At the time, our environment consisted of Kubernetes 1.31.7 and Cilium 1.16.5. We provide these specific versions to help interested readers correlate our findings with the relevant codebases.
|
||||
|
||||
To support our unique workloads, we progressively tuned Cilium by increasing DNS proxy timeouts, expanding the connection tracking table capacity, raising API rate limits, and streamlining "security labels". This configuration allowed us to overcome challenge after challenge, except for one:
|
||||
|
||||
**`Failed to create pod sandbox: rpc error: code = Unknown desc = failed to setup network for sandbox "0fecf4844d3f8f2df218f09d91f9698bb424e2166551952f46fd7638f4757cf2": plugin type="cilium-cni" failed (add): unable to create endpoint: Cilium API client timeout exceeded`**
|
||||
|
||||
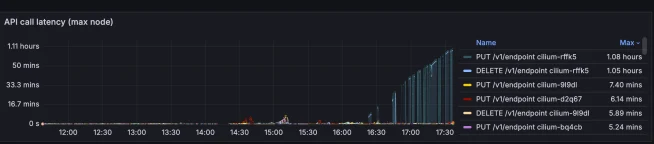
Kubernetes would create a pod, spin up the sandbox, and then attempt to set up the networking with Cilium. This operation would time out. From that point onwards, it also timed out any other pod attempting to spawn on the same node. Furthermore, we noticed that on those affected nodes, the API duration for DELETE /v1/endpoint and PUT /v1/endpoint, the routes responsible for adding and deleting a Cilium endpoint, also increased. You can see this clearly in the image below where the endpoint call latency starts to increase linearly over time from 4:20 pm onwards, indicating that endpoint creation and deletion never finish.
|
||||
|
||||
|
||||
|
||||
It is important to note that these clusters are only used for analytical processing and big data workloads. The issue was identified, analyzed, and fully resolved before any SLO was breached. Furthermore, as our big data environments are isolated from our core transactional flows, this issue never impacted our real-time payment processing pipeline or merchant transactions.
|
||||
|
||||
## The symptom: something's wrong, but what?
|
||||
|
||||
First, we found no related timeouts in the Cilium Agent logs. We enabled debug logging, hoping to find hidden errors. Nothing. The logs gave us the big picture but didn't reveal the bottleneck.
|
||||
|
||||
We did learn some valuable things from debugging the broken nodes:
|
||||
|
||||
- Listing all endpoints on a broken node would time out: cilium endpoint list
|
||||
- Listing the logs of an endpoint worked fine and showed the endpoint was stuck in the regenerating phase: cilium endpoint log <ENDPOINT_ID>
|
||||
- Requesting the endpoint state with kubectl get ciliumendpoint showed it was still regenerating, while the Kubernetes manifest of the endpoint showed a ready status.
|
||||
- Checking the filesystem at /var/run/cilium/state showed endpoint folders with a _next suffix, indicating they didn't complete successfully.
|
||||
|
||||
This validated our suspicion that the issue was in the Cilium agent, not at the kubelet or CNI plugin level. But we still didn't know why.
|
||||
|
||||
## Under the hood: how Cilium sets up networking for a pod
|
||||
|
||||
Before we dive into the debugging journey, it's helpful to understand what happens when a pod spawns and Cilium sets up its networking.
|
||||
|
||||
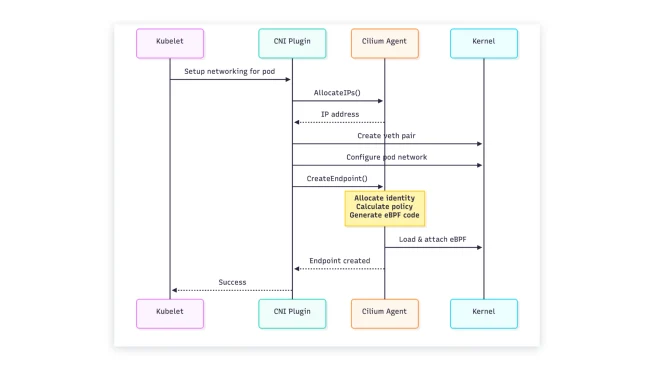
The process starts when Kubernetes assigns a pod to a specific node. The kubelet initiates the pod setup and calls the configured CNI plugin (Cilium, in our case). The Cilium CNI plugin performs several operations:
|
||||
|
||||
1. **Allocates an IP** using IPAM (IP Address Management)
|
||||
2. **Creates a link device** (in our setup, a veth pair. One end in the host namespace, one in the pod)
|
||||
3. **Configures the pod network** by setting the IP address, configuring routes and setting sysctl parameters
|
||||
4. **Creates a Cilium endpoint** via the Cilium agent API
|
||||
5. **Retrieves or allocates a security identity** using pod labels
|
||||
6. **Calculates network policy** for this endpoint
|
||||
7. **Generates, compiles, and injects eBPF****code** into the kernel
|
||||
8. **Returns success** to the kubelet
|
||||
|
||||
The key thing to understand is that when creating a Pod, and thus an endpoint, the CNI plugin calls the Cilium agent, which runs as a DaemonSet on each node. The agent does the heavy lifting: managing eBPF maps, handling connection tracking, applying network policies, and more.
|
||||
|
||||
Here's a simplified view of the flow:
|
||||
|
||||
|
||||
|
||||
A vital part of this process occurs during endpoint creation: Cilium triggers the connection tracking table's garbage collection to verify that the pod's IP is free of residual connections from its previous run. The scrubIPsInConntrackTable function executes this operation, scanning the entire conntrack table to identify and delete relevant entries.
|
||||
|
||||
The consequences of failing garbage collection are significant. Stale entries accumulate without limit, and while our table can accommodate up to 16 million entries, the real bottleneck is the mandatory scan that every new pod requires. This cleaning step is essential to mitigate IP address reuse conflicts, ensuring that a fresh pod doesn't inherit any open connections from a prior one.
|
||||
|
||||
This is where our story really begins.
|
||||
|
||||
*Note:* [Arthur Chiao's excellent deep dive into Cilium's CNI implementation](https://arthurchiao.art/blog/cilium-code-cni-create-network/) *provided much of our understanding of the CNI flow. While Arthur Chiao wrote it a few years ago, the core concepts remain relevant, and it is an invaluable resource for anyone wanting to understand how Cilium works under the hood.*
|
||||
|
||||
## Down the rabbit hole: tracing the root cause
|
||||
|
||||
### What is the agent actually doing?
|
||||
|
||||
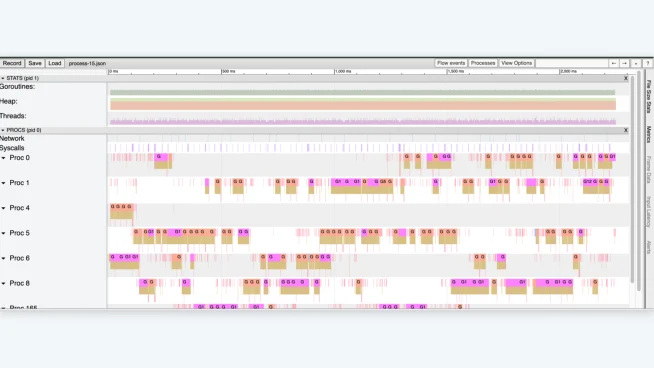
We needed to see what the Cilium agent was doing when it hung. Enter pprof, Go's built-in profiler. We enabled pprof in Cilium's configuration and captured traces from a broken node right after spawning 50 pods.
|
||||
|
||||
The CPU and memory profiles didn't reveal much at first. But when we opened the execution traces, the timeline view showed exactly what each goroutine was doing, and everything became clear.
|
||||
|
||||
|
||||
|
||||
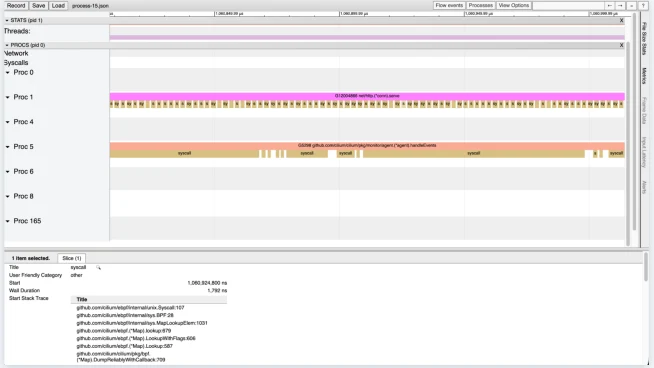
We saw long-running goroutines spending their entire time in syscalls. Zooming in closer revealed the pattern:
|
||||
|
||||
|
||||
|
||||
The agent was making BPF syscalls in a tight loop: nextKey(), lookup(), nextKey(), lookup(), over and over again. The agent uses these syscalls to iterate through an eBPF map:
|
||||
|
||||
1. **nextKey(currentKey)** - Gets the next key in the BPF map after currentKey
|
||||
2. **lookup(key)** - Retrieves the value associated with key
|
||||
|
||||
Let's do some napkin math. We selected a 35-millisecond fragment and counted 14,916 syscall occurrences. That's 426,171 syscalls per second. Since getting each element from an eBPF map takes two syscalls (next + get), we were iterating through roughly 213,000 entries per second.
|
||||
|
||||
As Cilium is a user-space process, accessing or manipulating the map forces a context switch on every syscall. A context switch is the process of the CPU temporarily halting the user-space process (Cilium) to execute code in the kernel (to handle the BPF syscall) and then resuming the user-space process. This involves saving and restoring the entire state of the CPU registers and memory space, which adds significant overhead and is a major source of latency.
|
||||
|
||||
Here's the critical insight: this is a sequential operation. You can't parallelize it because you need the current key to get the next key. Even on our powerful server CPUs, this was the maximum speed we could achieve. And there was one more important detail in the traces: this was happening in the scrubIPsInConntrackTable function, the one that cleans the connection tracking table when creating an endpoint.
|
||||
|
||||
## Why so many syscalls? The connection tracking table
|
||||
|
||||
That's when we remembered something we'd seen in cilium status --verbose:
|
||||
|
||||
```
|
||||
BPF Maps: dynamic sizing: on (ratio: 0.005000)
|
||||
Name Size
|
||||
TCP connection tracking 16777216
|
||||
Non-TCP connection tracking 14232516
|
||||
...
|
||||
```
|
||||
Our TCP connection tracking table had a maximum size of 16 million entries, two times the default of eight million for a machine with 2TB of RAM. We had deliberately configured `**cilium_bpf_map_dynamic_size_ratio: 0.0050`** in our Helm Chart months earlier, fully expecting the connection tracking capacity to scale proportionally with memory across our node types. At the time, this was a planned scaling adjustment to prevent connection tracking exhaustion on our 512GB RAM machines under high-throughput workloads. This configuration worked as intended to support our unique workload evolution, but as our traffic grew, it created a new scaling challenge in how the larger table interacted with the garbage collection auto-scaling algorithm on our high-resource 2TB RAM nodes.
|
||||
|
||||
But how many entries were actually in the table? We listed them with `**cilium bpf ct list global`**. This showed about 7 million entries. But here's what made it interesting: when we checked the timestamp of the *expires* field against the system uptime, we found that the vast majority were already expired, some by several hours. This pointed us directly toward the garbage collection mechanism.
|
||||
|
||||
Now the napkin math gets interesting:
|
||||
|
||||
- Maximum iteration speed: ~200,000 entries per second
|
||||
- Current table size: 7 million entries
|
||||
- Time to walk the current table: 35 seconds
|
||||
- Maximum table size: 16 million entries (at worst)
|
||||
- Time to walk the full table: 80 seconds
|
||||
|
||||
That means every time we created or deleted an endpoint, we would spend as much as 35 seconds iterating through the connection tracking table, and in the worst-case scenario, a maximum of 80 seconds. Keep in mind our CNI timeout constraint is 90 seconds.
|
||||
|
||||
But wait, if the entries were expired, why wasn’t the garbage collector cleaning them up?
|
||||
|
||||
## Why aren't expired entries cleaned up? Garbage collection gone wrong
|
||||
|
||||
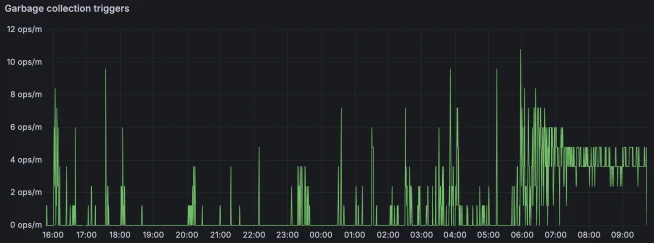
Cilium has garbage collection for the connection tracking table. Looking at the metrics, GC was triggering quite often:
|
||||
|
||||
|
||||
|
||||
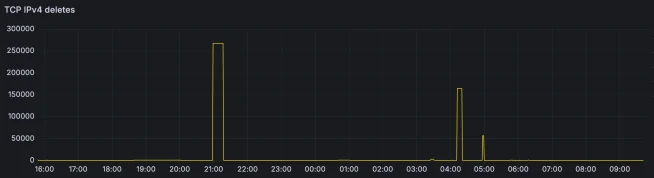
But when we looked at what the garbage collector was actually deleting, we saw a problem:
|
||||
|
||||
|
||||
|
||||
The garbage collector was running frequently but deleting almost nothing most of the time. Only occasionally would it delete significant numbers of entries.
|
||||
|
||||
Digging into the code revealed why. Cilium has two types of GC operations:
|
||||
|
||||
1. **Endpoint-specific cleanup** : When creating or deleting an endpoint, clean entries matching that endpoint's IP
|
||||
2. **Periodic expired entry cleanup** : Runs on an interval to remove all expired entries
|
||||
|
||||
Pod creation and deletion triggered almost all of the frequent GC runs in the metrics (the type 1 endpoint-specific cleanups). The periodic cleanup (type 2), which removes expired entries, was barely running at all.
|
||||
|
||||
Why? Because the GC interval auto-scales based on how much it deletes:
|
||||
|
||||
```
|
||||
// Simplified from Cilium source
|
||||
func GetInterval(interval time.Duration, maxDeleteRatio float64) time.Duration {
|
||||
if maxDeleteRatio > 0.25 {
|
||||
// Deleted > 25% of entries → GC more frequently
|
||||
interval = time.Duration(float64(interval) * (1.0 - maxDeleteRatio))
|
||||
} else if maxDeleteRatio < 0.05 {
|
||||
// Deleted < 5% of entries → GC less frequently
|
||||
interval = time.Duration(float64(interval) * 1.5)
|
||||
}
|
||||
if interval > ConntrackGCMaxLRUInterval {
|
||||
interval = ConntrackGCMaxLRUInterval // 12 hours
|
||||
}
|
||||
return interval
|
||||
}
|
||||
```
|
||||
Here's the problem with a 16-million-entry table:
|
||||
|
||||
- To delete more than 5% (and avoid slowing down), you need to delete 800,000+ entries
|
||||
- To delete more than 25% (and speed up), you need to delete 4+ million entries
|
||||
- Starting interval: 5 minutes
|
||||
- Maximum interval: 12 hours
|
||||
|
||||
Imagine this scenario:
|
||||
|
||||
1. The node initially experiences a low connection volume when it is newly onboarded or runs only light workloads.
|
||||
2. The garbage collector deletes less than 5% of entries during a run, which fails to trigger more frequent cycles.
|
||||
3. The garbage collection interval increases progressively from minutes until it reaches the 12-hour maximum. It would start with 7.5 minutes, increase to 11.25 minutes, then to 16.875 minutes, and so on, until eventually reaching the 12-hour limit.
|
||||
4. Heavy data workloads eventually land on the node and generate a high volume of network traffic.
|
||||
5. New connections fill the tracking table for up to 12 hours before the garbage collector runs again.
|
||||
|
||||
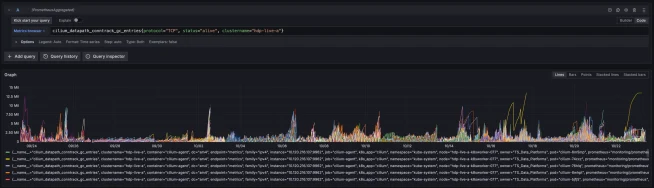
By the time garbage collection eventually executes, the connection tracking table may have already accumulated up to 16 million stale entries. While the GC run might delete enough records to temporarily restore speed, the excessive delay between cycles is inherently problematic. This lag allows the table to accumulate a large number of stale entries again, forcing every pod created during the long interval after the previous GC to endure the significant performance penalty of a sequential scan.
|
||||
|
||||
|
||||
|
||||
## Why does it cascade? Mutex locks, timeouts, and retries
|
||||
|
||||
While a single slow pod spawn is highly inconvenient, the issue escalated significantly when multiple pods tried to spawn simultaneously.
|
||||
|
||||
We captured a goroutine dump from the Cilium agent using gops and analyzed it with a script that groups similar stack traces. The results were revealing:
|
||||
|
||||
```
|
||||
- 57 occurrences:
|
||||
createEndpoint() → WaitForFirstRegeneration() → waiting on RWMutex
|
||||
- 57 occurrences:
|
||||
regenerateBPF() → runPreCompilationSteps() → invoked
|
||||
- 56 occurrences:
|
||||
scrubIPsInConntrackTable() → garbageCollectConntrack() → waiting for Lock
|
||||
```
|
||||
|
||||
There's a **global mutex on the connection tracking table**. When we spawn 50 pods at once:
|
||||
|
||||
- Pod 1 acquires the lock and starts the 80-second table iteration
|
||||
- Pods 2-50 queue up waiting for the lock
|
||||
- Pod 1 finishes after 80 seconds
|
||||
- Pod 2 acquires the lock, starts another 80-second iteration
|
||||
- But Pod 2's timer started 80 seconds ago → timeout at 90 seconds
|
||||
- Pod 2 times out
|
||||
- Pods 3-50 never stand a chance
|
||||
|
||||
Here's where it gets worse. When the CNI times out after 90 seconds:
|
||||
|
||||
- The timeout returns an error to the caller
|
||||
- **But the underlying work doesn't stop** , the agent keeps iterating
|
||||
- The container runtime (containerd) immediately calls DeleteEndpoint()
|
||||
- Delete also needs to walk the conntrack table
|
||||
- Now the system queues up both create and delete operations
|
||||
|
||||
And then Kubernetes retries:
|
||||
|
||||
- The kubelet's *podWorkerLoop* retries after 60-90 seconds (with jitter)
|
||||
- Each retry adds another endpoint creation and deletion request to the queue
|
||||
- The queue grows faster than it drains
|
||||
|
||||
We could see this in the logs. For one pod (cilium-node-breaker-5), we saw:
|
||||
|
||||
- 15:54:30 - Create endpoint (attempt 1)
|
||||
- 15:56:00 - Delete endpoint (timeout)
|
||||
- 15:57:12 - Create endpoint (attempt 2)
|
||||
- 15:59:57 - Create endpoint (attempt 3)
|
||||
- 16:02:39 - Create endpoint (attempt 4)
|
||||
|
||||
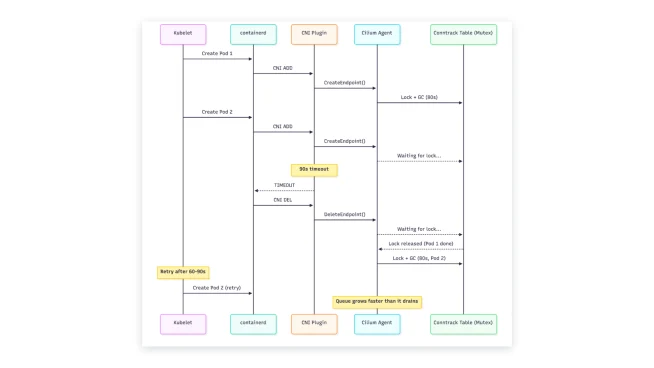
The node enters a contention cycle: new work arrives faster than old work completes, and the queue never drains.
|
||||
|
||||
Here's the full picture:
|
||||
|
||||
|
||||
|
||||
## The fix: one line to rule them all
|
||||
|
||||
After all that investigation, the fix was anticlimactic in its simplicity. We couldn't rely on the auto-scaling GC interval because it would inevitably grow too long on quiet nodes. Hence, we prevented the GC interval from auto-scaling by setting a fixed value:
|
||||
|
||||
`conntrackGCInterval: 60s`
|
||||
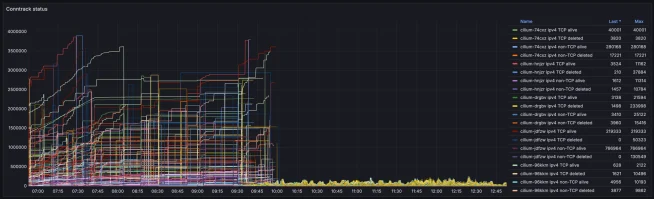
That's it. One configuration line ensures garbage collection runs at least every minute, regardless of how much it deletes. We applied the change at 9:00 am and completed the DaemonSet rollout by 10:00 am. The results speak for themselves:
|
||||
|
||||
|
||||
|
||||
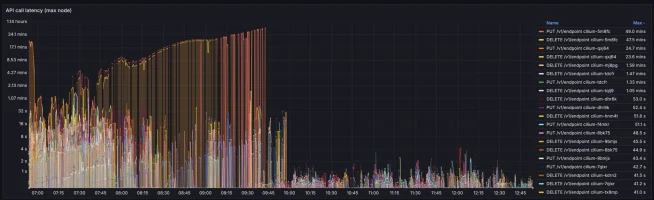
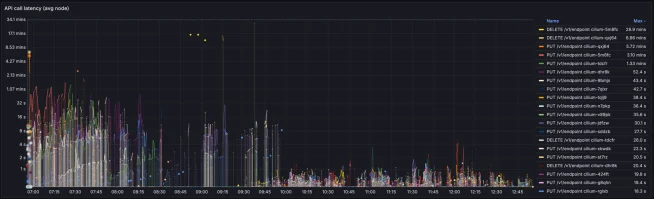
The conntrack table size dropped dramatically and stayed stable. More importantly, the API call durations returned to normal:
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Since the fix, we haven't seen a single instance of the timeout error. Pod spawn times are reliable again.
|
||||
|
||||
## Lessons learned
|
||||
|
||||
**Scaling parameters can have long-tail interactions.** Our proactive tuning of bpf_map_dynamic_size_ratio to support workload scaling on 512GB RAM machines successfully resolved initial capacity limits. However, as our analytical workloads evolved and traffic increased, the larger table size dynamically allocated on our 2TB RAM machines revealed a subtle interaction with the CNI's GC auto-scaling algorithm. These scaling parameters can take months to show their full impact as traffic patterns grow, particularly in environments with adaptive background loops.
|
||||
|
||||
**Observability and full-stack understanding are critical.** While logs showed symptoms, we needed profiling and tracing to reveal the root cause across the entire stack. The container runtime (timeouts, delete behavior), the CNI plugin (timeout values), the Cilium agent (mutex locks, GC logic), and the Linux kernel (eBPF maps, syscall performance) were all relevant to understanding how we got to the pod spawn timeouts. On top of that, adding napkin math with real numbers proved very powerful. Once we had the key numbers, 200k syscalls/sec, 12M table entries and a 90-second timeout, we determined the root cause far before we understood the full chain. Always measure your system's actual performance characteristics, not just theoretical limits.
|
||||
|
||||
**Auto-scaling algorithms need bounds.** Cilium's GC interval auto-scaling makes sense for most deployments: if you're deleting lots of entries, run GC more often; if you're deleting few entries, save CPU by running GC less often. But the algorithm didn't account for varying workloads, where a machine has a low connection volume for a prolonged period, after which, with a single pod introduction, it could get a very high connection volume. Nor did the algorithm account for very large tables where "5% of entries" is an enormous absolute number. The 12-hour maximum interval was too long for our workload. Auto-scaling without careful consideration of edge cases can backfire.
|
||||
|
||||
**Timeouts don't stop work**. When the CNI timed out, we assumed the work would stop. It didn't. The agent kept processing in the background while new requests queued up. This is a common pattern in distributed systems: timeouts protect the caller but don't necessarily cancel the operation. Be explicit about cancellation when needed.
|
||||
|
||||
**Treat conntrack health as a first-class operational metric**. The difference between a healthy cluster and a contention cycle showed up clearly in some metrics we weren't watching:
|
||||
|
||||
- GC duration - cilium_datapath_conntrack_gc_duration_seconds - jumped from 1s to 80s
|
||||
- Table size - cilium_datapath_conntrack_gc_entries - 7M entries, mostly expired
|
||||
|
||||
Proactively alerting on these metrics is something we now recommend for any Cilium deployment with dynamic workloads, alongside setting `**conntrackGCInterval: 60s`**. Don't optimise for CPU savings during quiet periods at the expense of pod spawn timeouts during busy periods.
|
||||
|
||||
## Conclusion
|
||||
|
||||
A single configuration line ultimately resolved the mysterious timeout error that impacted our ability to spawn new pods on our big data platform: conntrackGCInterval: 60s. Our investigation revealed that the root cause of our pod timeouts was Cilium's auto-scaling garbage collection algorithm, allowing the cleanup interval to grow to 12 hours, leading to a massive accumulation of expired entries and a linear-time iteration trap.
|
||||
|
||||
This experience provided major takeaways regarding system resilience and the necessity of a full-stack understanding. We learned that scaling parameters and resource allocations can have long-tail interactions that only surface months later as workloads evolve. Furthermore, we discovered that auto-scaling algorithms require strict bounds to prevent unexpected performance degradation in edge cases, such as the varying connection volumes we see on our high-resource machines. The investigation also highlighted that timeouts often only protect the caller, without stopping the underlying work, potentially triggering a contention cycle of retries that we could only diagnose through deep observability into mutex locks, syscalls, and eBPF internals.
|
||||
|
||||
As we move forward, we must ask ourselves: are the adaptive behaviours in our infrastructure truly protecting us, or are they masking inefficiencies that only appear at peak capacity? By treating conntrack health as a first-class operational metric and prioritising reliability over minor CPU savings, we can build more robust systems. And remember, if you ever see mysterious timeouts in your CNI: sometimes the answer hides in 426,000 syscalls per second.
|
||||
|
||||
@@ -7,3 +7,47 @@
|
||||
## 简介
|
||||
|
||||
> For eight years I ran SRE for a storage system measured in exabytes. The dashboard I checked every morning shrank to seven numbers. Here they are.
|
||||
|
||||
## 正文
|
||||
|
||||
For eight years I ran the SRE team behind a storage system measured in exabytes. Over time, the dashboard I checked every morning shrank to a handful of numbers. These are the seven that told me whether the service was healthy.
|
||||
|
||||
Availability tells you if the system is up. Durability tells you if your data is still there. The two are not the same.
|
||||
|
||||
|
||||
Here’s the short version.
|
||||
|
||||
| KPI | What it measures | How we tracked it |
|
||||
|---|---|---|
|
||||
| Availability | Percent of requests succeeding | 99.99% per region, per service |
|
||||
| Durability | Probability your data survives | 11 nines (10^-11 annual loss) |
|
||||
| TTFB | Time to first byte returned | p50, p95, p99 latency per object size |
|
||||
| Canaries | Synthetic test traffic | Continuous PUT/GET from every region |
|
||||
| Hotspots | Skew across storage nodes | Top-N node load vs cluster median |
|
||||
| IOPS | Operations per second | Read/write IOPS per shard, per disk |
|
||||
| DB Shards | Metadata partition health | Shard CPU, lag, hot-key skew |
|
||||
|
||||
## Availability and durability are the two non-negotiables
|
||||
|
||||
Availability is uptime. Durability is whether the data survives. You can be 100% available and lose data, you can be 100% durable and offline. Customers care about both. We hit 11 nines of durability by writing every object to multiple availability domains with erasure coding, and proved it monthly with a recovery drill.
|
||||
|
||||
## TTFB is what users actually feel
|
||||
|
||||
Aggregate availability hides slow tails. A 99.99% available service with a p99 TTFB of 2 seconds feels broken. Always track latency by object size bucket. A 10 MB read should not share an SLO with a 100 byte HEAD.
|
||||
|
||||
## Canaries are your truth
|
||||
|
||||
Customers don’t tell you when they’re sad. They leave. Canaries are synthetic PUT/GET/LIST traffic running continuously from every region. If a canary fails for 30 seconds, you find out before your customer’s pager goes off.
|
||||
|
||||
## Hotspots and IOPS surface the silent failures
|
||||
|
||||
A storage cluster can be 99.99% available while one node is on fire. Track per-node IOPS and bytes-served, and alert on the top-N nodes diverging from cluster median. Hotspots are the leading indicator of a customer key range overwhelming a shard.
|
||||
|
||||
## DB shards are the part nobody talks about
|
||||
|
||||
Object storage looks stateless, but the metadata layer is a sharded database. One hot shard, one rebalance gone wrong, and your control plane stalls. Watch shard CPU, replication lag, and hot-key skew the same way you watch the data plane.
|
||||
|
||||
The data plane scales. The control plane bites.
|
||||
|
||||
|
||||
Those seven numbers, watched together, told me almost everything I needed to know about whether the service was healthy.
|
||||
|
||||
@@ -7,3 +7,7 @@
|
||||
## 简介
|
||||
|
||||
> Traditional observability monitors execution. LLM observability must monitor behavior.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
|
||||
@@ -7,3 +7,208 @@
|
||||
## 简介
|
||||
|
||||
This one has a lot of great detail on how their approaches to quota management failed and how they iterated.
|
||||
|
||||
## 正文
|
||||
|
||||
# How Uber Conquered Database Overload: The Journey from Static Rate-Limiting to Intelligent Load Management
|
||||
|
||||
# Introduction
|
||||
|
||||
Uber’s thousands of microservices handle traffic for over 170 million monthly active users: riders, Uber Eats users, drivers, and couriers. At the heart of this infrastructure are [Docstore](https://www.uber.com/us/en/blog/schemaless-sql-database/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) and [Schemaless](https://www.uber.com/us/en/blog/schemaless-part-one-mysql-datastore/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f), Uber’s in-house distributed databases built on top of MySQL®. These databases span thousands of clusters, store tens of petabytes of operational data, and serve tens of millions of requests per second with billions of rows read or updated. They back some of the most latency-sensitive and mission-critical workloads, powering every business vertical at Uber: from rides and deliveries to maps, payments, and beyond.
|
||||
|
||||
At this scale, even minor overloads aren’t isolated events, they cascade. A brief spike in one part of the system can ripple outward: downstream services time out, retries pile up, and degradation amplifies into broader failure. In a multitenant environment, it’s also critical to ensure fairness and prevent any tenant from hogging all the resources. With workloads varying in traffic shape, latency profiles, and system impact, building effective overload protection is a uniquely challenging problem.
|
||||
|
||||
The cost of getting overload protection wrong is steep. This blog shares how we built an intelligent load manager that detects overload from multiple signals to keep our databases stable and fair under pressure.
|
||||
|
||||
## Docstore and Schemaless
|
||||
|
||||
Before diving into the load manager that protects Uber’s databases, let’s walk through their architecture.
|
||||
|
||||
While [Docstore](https://www.uber.com/us/en/blog/schemaless-sql-database/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) supports transactions with full CRUD operations and [Schemaless](https://www.uber.com/us/en/blog/schemaless-part-one-mysql-datastore/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) is optimized for append-only workloads, both share a common architectural foundation. It comprises three primary layers: a stateless query engine, a stateful storage engine, and a control plane. For the scope of this blog, we’ll focus on the query and storage engine layers.
|
||||
|
||||
The stateless query engine is responsible for query planning, request routing, sharding, schema management, authorization, request parsing, and validation. It serves as the routing layer: coordinating and validating client requests before handing them off to the storage layer.
|
||||
|
||||
The stateful storage engine handles transaction management, connection pooling, consensus, and replication. Data is sharded across multiple partitions, with each partition consisting of one leader and two followers, coordinated via [Raft](https://www.scs.stanford.edu/~zyedidia/docs/papers/raft.pdf) to ensure strong consistency. Each partition is backed by MySQL nodes with locally attached NVMe SSDs, built to support high-throughput, low-latency workloads at scale.
|
||||
|
||||
## Challenges
|
||||
|
||||
### Quota-Based Rate Limiting in the Query Engine Layer
|
||||
|
||||
Initially, we explored a quota based rate-limiting approach within the stateless query engine layer. The concept was simple: assign each read and write request a capacity unit cost based on bytes processed, grant users fixed quotas, and return a 429 when those quotas were exceeded. Since routing nodes were stateless, we stored quota usage in a central Redis® cache. While conceptually sound, this approach didn’t hold up in production.
|
||||
|
||||
First, it added unnecessary complexity. Every request required a Redis call, introducing a new point of failure and the overhead of an additional network hop.
|
||||
|
||||
Further, for the stateless routing layer to accurately shed requests for an overloaded storage partition, it’d need to maintain realtime health and load information for thousands of partitions across the system. This introduced a lot of tracking overhead, undermining the scalability of the architecture.
|
||||
|
||||
The cost model was also too imprecise. In Docstore and Schemaless, due to the way MySQL handles scanning and filtering, a query that performs a full table scan but returns a single row was assigned the same capacity cost as a query that only reads a single row. This fundamental flaw in our metering meant that lightweight and heavyweight operations were treated the same, making quota enforcement unreliable.
|
||||
|
||||
Finally, quotas were defined statically, resulting in frequent requests from stakeholders to adjust their quotas, making them ineffective in multitenant environments.
|
||||
|
||||
Despite its initial promise, this approach failed. But it gave us a crucial insight: overload management must live as close to the storage nodes as possible. That realization became a cornerstone of the final design in the stateful storage layer.
|
||||
|
||||
### Identifying the Right Signal for Overload
|
||||
|
||||
A core challenge in designing a resilient load manager is choosing a reliable signal for overload. Simple QPS-based rate limiting is too coarse. It fails to account for workload variability, often shedding too late or too early. What can be more effective is concurrency: the number of operations currently in flight. It directly reflects system load, following Little’s Law: *Concurrency = Throughput × Latency*. In stateful systems, it maps closely to resource usage, making it a more dependable indicator.
|
||||
|
||||
### Balancing Resilience and Fairness
|
||||
|
||||
Balancing resilience and fairness is a core challenge in multitenant systems. During system-wide stress, we want to shed traffic by priority, dropping low-priority requests first. But when a single noisy actor hogs resources without triggering global overload, we also need per-tenant rate limiting that works independently of the system load. This dual requirement led us to combine dynamic overload detectors with fairness enforcement mechanisms that operate in parallel.
|
||||
|
||||
## Building the Foundation of a Unified Load Manager
|
||||
|
||||
### Controlled Delay: Smarter Queuing Under Pressure
|
||||
|
||||
The load-shedding journey began with [CoDel](https://queue.acm.org/detail.cfm?id=2209336) (Controlled Delay), a concept borrowed from networking to combat bufferbloat. Instead of shedding based on queue length, CoDel looks at how long requests wait in the queue: favoring responsiveness over volume.
|
||||
|
||||
We implemented separate CoDel queues for each operation type:
|
||||
|
||||
- **Read queue** : for point lookups and light queries
|
||||
- **Write queue** : for insert, update, and upsert operations
|
||||
- **Slow queue** : for long-running and background operations like scans, deletes, or replication
|
||||
|
||||
Each queue was managed independently, giving us better isolation across workloads.
|
||||
|
||||
FIFO queuing wasn’t enough because a pure FIFO queue processes requests in arrival order, which works well when traffic is stable. But under overload, FIFO creates a trap: old requests accumulate, wait too long, and often get abandoned or retried by the client. This results in wasted work. Meanwhile, fresh requests, still relevant and likely to succeed, sit idle at the end of the line.
|
||||
|
||||
CoDel introduces adaptive LIFO to solve this. Figure 5 shows how it works.
|
||||
|
||||
Under normal load, the queue behaves as FIFO. Under pressure, it switches to LIFO, favoring newer requests that still have a chance to succeed. This simple shift improves responsiveness by failing fast, shedding stale work, and giving fresh requests priority.
|
||||
|
||||
### Scorecard Engine
|
||||
|
||||
The Scorecard engine is a rule-based admission control component and a lightweight quota system designed to enforce per-tenant concurrency limits in multitenant environments. While load-shedding protects the system during overload, Scorecard ensures that no single tenant can dominate shared infrastructure, even in normal conditions.
|
||||
|
||||
The configuration is simple and deterministic.
|
||||
|
||||
The primary benefit of the Scorecard lies in incident containment. It helps pinpoint the source of disruption during outages or traffic spikes. It isolates and caps misbehaving tenants without disrupting others, balances stability during normal load with strict limits under stress, and reduces blast radius during overload events by enforcing boundaries quickly and deterministically.
|
||||
|
||||
The Scorecard provides predictable fairness and blast radius control, especially when multiple tenants are competing for shared resources.
|
||||
|
||||
### Regulators
|
||||
|
||||
While Scorecard protects against concurrency-based overuse, it doesn’t cover all the ways a stateful database system can overload. Some forms of skews are subtle. They don’t show up in concurrency saturation, but they can still degrade system performance if left unchecked.
|
||||
|
||||
For example, a low QPS caller can still overload the system by sending large write payloads. Or, traffic skewed to one partition key can overload a single cluster while others sit idle.
|
||||
|
||||
To guard against these skewed behaviors, we introduced plug-in regulators: node-local overload detectors that enforce invariants the system mustn’t violate. They rarely trigger during healthy operation, and that’s by design. At the same time, when users accidentally create hotspots or large data ingestions, regulators kick in to prevent cascading failures.
|
||||
|
||||
We use these regulators:
|
||||
|
||||
- **Write bytes regulator:** Limits concurrent write volume to prevent I/O saturation
|
||||
- **Partition key regulator:** Throttles traffic targeting hot partition keys
|
||||
- **Memory regulator:** Tracks free process memory and throttles when we’re low on memory
|
||||
- **Goroutines regulator:** Tracks total number of goroutines and throttles when it exceeds threshold
|
||||
|
||||
### What Worked Well
|
||||
|
||||
By shedding excess requests, our CoDel queues prevented runaway resource exhaustion, which led to improved stability and a higher success rate for accepted requests. This approach was particularly effective at ensuring that core system functionality remained available during overloads.
|
||||
|
||||
The Scorecard engine successfully isolated misbehaving tenants by enforcing per-tenant concurrency limits. This allowed us to quickly contain disruptions from noisy neighbors without penalizing other users, ensuring that shared resources were used fairly.
|
||||
|
||||
### Limitations
|
||||
|
||||
While this initial setup laid the foundation for overload protection and fairness, it came with a few limitations. First, CoDel treated all requests equally, dropping low-priority and user-facing traffic alike, leading to a bad customer experience and increased on-call load.
|
||||
|
||||
CoDel also relied on fixed queue timeouts and static inflight concurrency limits, which can be a low-fidelity solution for a dynamic system, requiring frequent manual tuning and leading to operational toil.
|
||||
|
||||
The fixed, static wait times in CoDel led to a thundering herd problem. When requests were eventually rejected, they’d all retry at once, triggering repeated cycles of overload and rejection. During these periods, the lack of traffic differentiation meant even high-priority requests were dropped, leading to customer-visible errors and amplifying the blast radius.
|
||||
|
||||
Ultimately, it kept things from breaking, but lacked the nuance and dynamism required for a high-quality user experience. This highlighted the need for dynamic and priority-aware queues.
|
||||
|
||||
## Evolving the Architecture
|
||||
|
||||
### Cinnamon Replaces CoDel
|
||||
|
||||
We observed that many overloads stemmed from low-priority, asynchronous jobs: pipelines, aggregators, and internal garbage collection flows. These shouldn’t have the same survivability as ride requests or real-time pricing queries.
|
||||
|
||||
To address this, we replaced CoDel with [Cinnamon](https://www.uber.com/us/en/blog/cinnamon-using-century-old-tech-to-build-a-mean-load-shedder/), a priority-aware load shedder developed by the Delivery team at Uber. Cinnamon makes smarter shedding decisions by considering request rank, dynamic system state, and the relative importance of workloads.
|
||||
|
||||
Request rank is derived from the priority attached to the request, and if no explicit priority is present, Cinnamon assigns a default based on the calling service. Priority is defined using a tiering model from tier 0 (t0) for the most critical traffic to tier 5 (t5) for the least. While t0 is reserved for a small subset of critical infrastructure services, t1 represents the most important user facing online traffic, the core workloads we aim to protect during overloads. This system allows Cinnamon to shed lower-priority traffic first during overload.
|
||||
|
||||
With request priority awareness in place, we simplified the queue structure to just read and write queues. Long-running and background operations were marked with lower priority instead of having a separate queue.
|
||||
|
||||
Before Cinnamon, the CoDel queue load shedder was priority-agnostic and shedding during overload was indiscriminate.
|
||||
|
||||
After Cinnamon, the queue load shedder was priority-aware and shedding during overload happened in order of priority.
|
||||
|
||||
### Performance and Stability Gains
|
||||
|
||||
We saw performance and stability gains from the Cinnamon-based design. Requests are ranked, allowing Cinnamon to shed low-priority traffic first, protecting user facing flows. During overloads, critical user-facing requests are better protected with minimal impact.
|
||||
|
||||
Cinnamon also adapts queue timeout thresholds using P90 latency metrics, eliminating the need for manual tuning. Moreover, its [Auto Tuner](https://www.uber.com/blog/cinnamon-auto-tuner-adaptive-concurrency-in-the-wild/) dynamically adjusts inflight limits, represented by the available slots in the blue box in Figure 10, to maximize throughput. It does this by continuously monitoring and reacting to realtime latency and error rate signals, ensuring stable and effective load shedding.
|
||||
|
||||
Unlike CoDel’s static approach, which aggressively rejects all requests after a fixed wait time, like 5 milliseconds, Cinnamon’s [PID-based control](https://www.uber.com/us/en/blog/pid-controller-for-cinnamon/) allows the system to absorb pressure without overreacting. It dynamically adjusts queue timeouts and inflight limits based on realtime latency and error signals, shedding only when necessary. This prevents a large class of premature shedding that would otherwise lead to unnecessary rejections, retries, and thundering herd effects. The result is smoother recovery, fewer 429s, and more consistent availability without compromising system health.
|
||||
|
||||
### Areas for Improvement
|
||||
|
||||
Despite the gains from Cinnamon, some key challenges remained, highlighting the need for a unified platform.
|
||||
|
||||
The load manager acted based on the local health of the server, tracking signals like inflight concurrency, write bytes, or memory usage. But in distributed systems, overload isn’t always local. A leader node may need to shed traffic because follower nodes are lagging, even if it’s healthy itself. We call this commit index lag. Traditionally, external components using token-bucket-based rate limiters handled such remote shedding decisions. These were easy to build but proved ineffective at scale, introducing split-brain behaviors and globally suboptimal shedding decisions.
|
||||
|
||||
The initial design was excellent for concurrency-based shedding, but it wasn’t built to be a reusable platform for future overload signals that would inevitably arise from a growing system.
|
||||
|
||||
These insights led us to the final evolution of our system: transforming Cinnamon from a concurrency only shedder into a truly general purpose overload control engine. By consolidating all signals into a single, modular decision-making loop, we achieved holistic and consistent overload management.
|
||||
|
||||
## The Unified Load Shedding Engine
|
||||
|
||||
### Centralizing Overload Decisions
|
||||
|
||||
We enhanced Cinnamon to support pluggable external signals like follower commit lags, enabling the system to make globally informed, priority-aware shedding decisions within the same admission control path. This shift unified local and remote overload logic into a single control loop, closing the gaps that previously caused instability.
|
||||
|
||||
But shedding isn’t always a one-size-fits-all decision and that’s where the load manager architecture shines. Built on a BYOS (Bring Your Own Signal) ethos, it provides a pluggable framework that lets the team embed new overload signals and route them to the right control path. Whether the pressure is systemic or actor-specific, the load manager sheds broadly by priority or precisely by caller, based on the signal.
|
||||
|
||||
### The Payoff: Unified Control, Simplified Load Management
|
||||
|
||||
The shift to a centralized, pluggable architecture made the system more stable and predictable, with real wins.
|
||||
|
||||
Cinnamon sheds excess requests immediately using a PID controller, avoiding the memory and goroutine buildup caused by token bucket limiters. This led to lower tail latencies and a leaner resource usage profile, even under heavy load. We saw:
|
||||
|
||||
- 80% increase in throughput under overload (QPS average of 5,400 versus 3,000)
|
||||
- ~70% reduction in P99 latency (upsert average of 1.0 seconds versus 3.1 seconds)
|
||||
- ~93% fewer goroutines during overload (peak 10,000 versus 150,000)
|
||||
- ~60% lower heap usage (1 GB max versus 5-6 GB spikes)
|
||||
|
||||
|
||||
We also saw smoother, more predictable shedding behavior. Without PID regulation, shedding acts like a hammer: reactive and abrupt. With it, it’s more like a dimmer switch: smooth and stable. The difference is clear when comparing how commit lag stabilizes under a token bucket limiter versus Cinnamon’s PID-based controller.
|
||||
|
||||
## Lessons Learned
|
||||
|
||||
- **Prioritization is paramount.** Effective load-shedding starts with deciding what matters most. Protect critical, user-facing traffic first. Everything else is secondary.
|
||||
- **Fail fast, don’t block.** Rejecting early is almost always better than holding requests in memory until they expire. It reduces wasted work, keeps latencies predictable, prevents OOMs, and makes the system more resilient under stress.
|
||||
- **PID regulation for stable shedding** . Simple, reactive shedding based solely on current error rates often causes instability, overcorrecting too late, and too hard. PID based regulation brings balance by incorporating system history and directional trends, making it a critical tool for smooth, sustained, and resilient overload control.
|
||||
- **Place control close to the source of truth.** The best shedding decisions happen where the state lives. Protection in the layer that has full context, typically the storage layer in stateful systems.
|
||||
- **Embrace dynamism.** Avoid static configurations wherever possible. Your system should be intelligent enough to adapt to different scenarios, based on the context.
|
||||
- **Invest in visibility and monitoring.** Good observability is the foundation for tuning and trust. Track what’s being shed, why it’s being shed, and how each component contributes to system pressure.
|
||||
- **Simplicity over complexity.** This is a meta principle that guides all the other decisions.
|
||||
|
||||
# Conclusion
|
||||
|
||||
Our journey to a resilient load manager was defined by the unique complexities of a large-scale, stateful, and distributed environment. By unifying disparate components into a single decision-making brain and adopting a Bring Your Own Signal model, we gained the flexibility to handle systemic overloads and localized noisy neighbor issues with precision. The result is a load management system that sheds smarter in a priority-aware manner, keeps tail latencies low, and drastically reduces operational toil.
|
||||
|
||||
If you like challenges related to distributed systems, databases, storage, and cache, apply for open positions [here](https://www.uber.com/us/en/careers/list/?query=storage&department=Engineering).
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
A project of this scope is rarely accomplished alone. Our sincere thanks to Rich Porter, Jesper Nielsen, Piyush Patel, and the engineers from the Storage and Delivery teams for their guidance and collaboration throughout this journey. From design reviews to on-call insights, their contributions were instrumental in building a resilient system that now safeguards some of Uber’s most critical infrastructure.
|
||||
|
||||
*Cover Photo Attribution: “[Heavy Traffic Jam in Urban City Center](https://www.pexels.com/photo/heavy-traffic-jam-in-urban-city-center-32487428/)” by [Dapur Melodi](https://www.pexels.com/@dapur-melodi-192125/)*
|
||||
|
||||
*MySQL is a registered trademark of Oracle and/or its affiliates. Other names may be trademarks of their respective owners.*
|
||||
|
||||
*Redis is a trademark of Redis Labs Ltd. Any rights therein are reserved to Redis Labs Ltd. Any use herein is for referential purposes only and does not indicate any sponsorship, endorsement or affiliation between Redis and Uber.*
|
||||
|
||||
Dhyanam Vaidya
|
||||
|
||||
Dhyanam Vaidya is a Software Engineer on Uber’s Storage Platform team. He’s contributed to the design and implementation of many Docstore features. His work focuses on improving the reliability, resilience, and operational efficiency of Uber’s distributed databases at scale.
|
||||
|
||||
Prathamesh Deshpande
|
||||
|
||||
Prathamesh Deshpande is a Staff Engineer on Uber’s Storage Platform team, building database features and distributed storage systems that meet Uber’s global reliability and performance requirements. His work focuses on large-scale data management, distributed database storage systems, and platform reliability.
|
||||
|
||||
Mike Ma
|
||||
|
||||
Mike Ma is a Staff Software Engineer on Uber’s Storage Platform team, where he has contributed to multiple core components of both Schemaless and Docstore. His work focuses on scalability, reliability, performance, and operational excellence across Uber’s large scale distributed databases.
|
||||
|
||||
Chaitanya Yalamanchili
|
||||
|
||||
Chaitanya Yalamanchili is a Sr. Manager and technical lead on Uber’s Storage Platform team. He leads the development of online distributed storage systems with a focus on providing a world-class platform that powers all the critical business functions and lines of business at Uber. The platform serves tens of millions of QPS and stores tens of Petabytes of operational data.
|
||||
|
||||
@@ -7,3 +7,121 @@
|
||||
## 简介
|
||||
|
||||
This article uses Voyager 1, whose engineers just shut down another instrument to conserve its steadily-decaying power, as an extended analogy for graceful degradation.
|
||||
|
||||
## 正文
|
||||
|
||||
### Voyager and the Art of Graceful Degradation
|
||||
|
||||
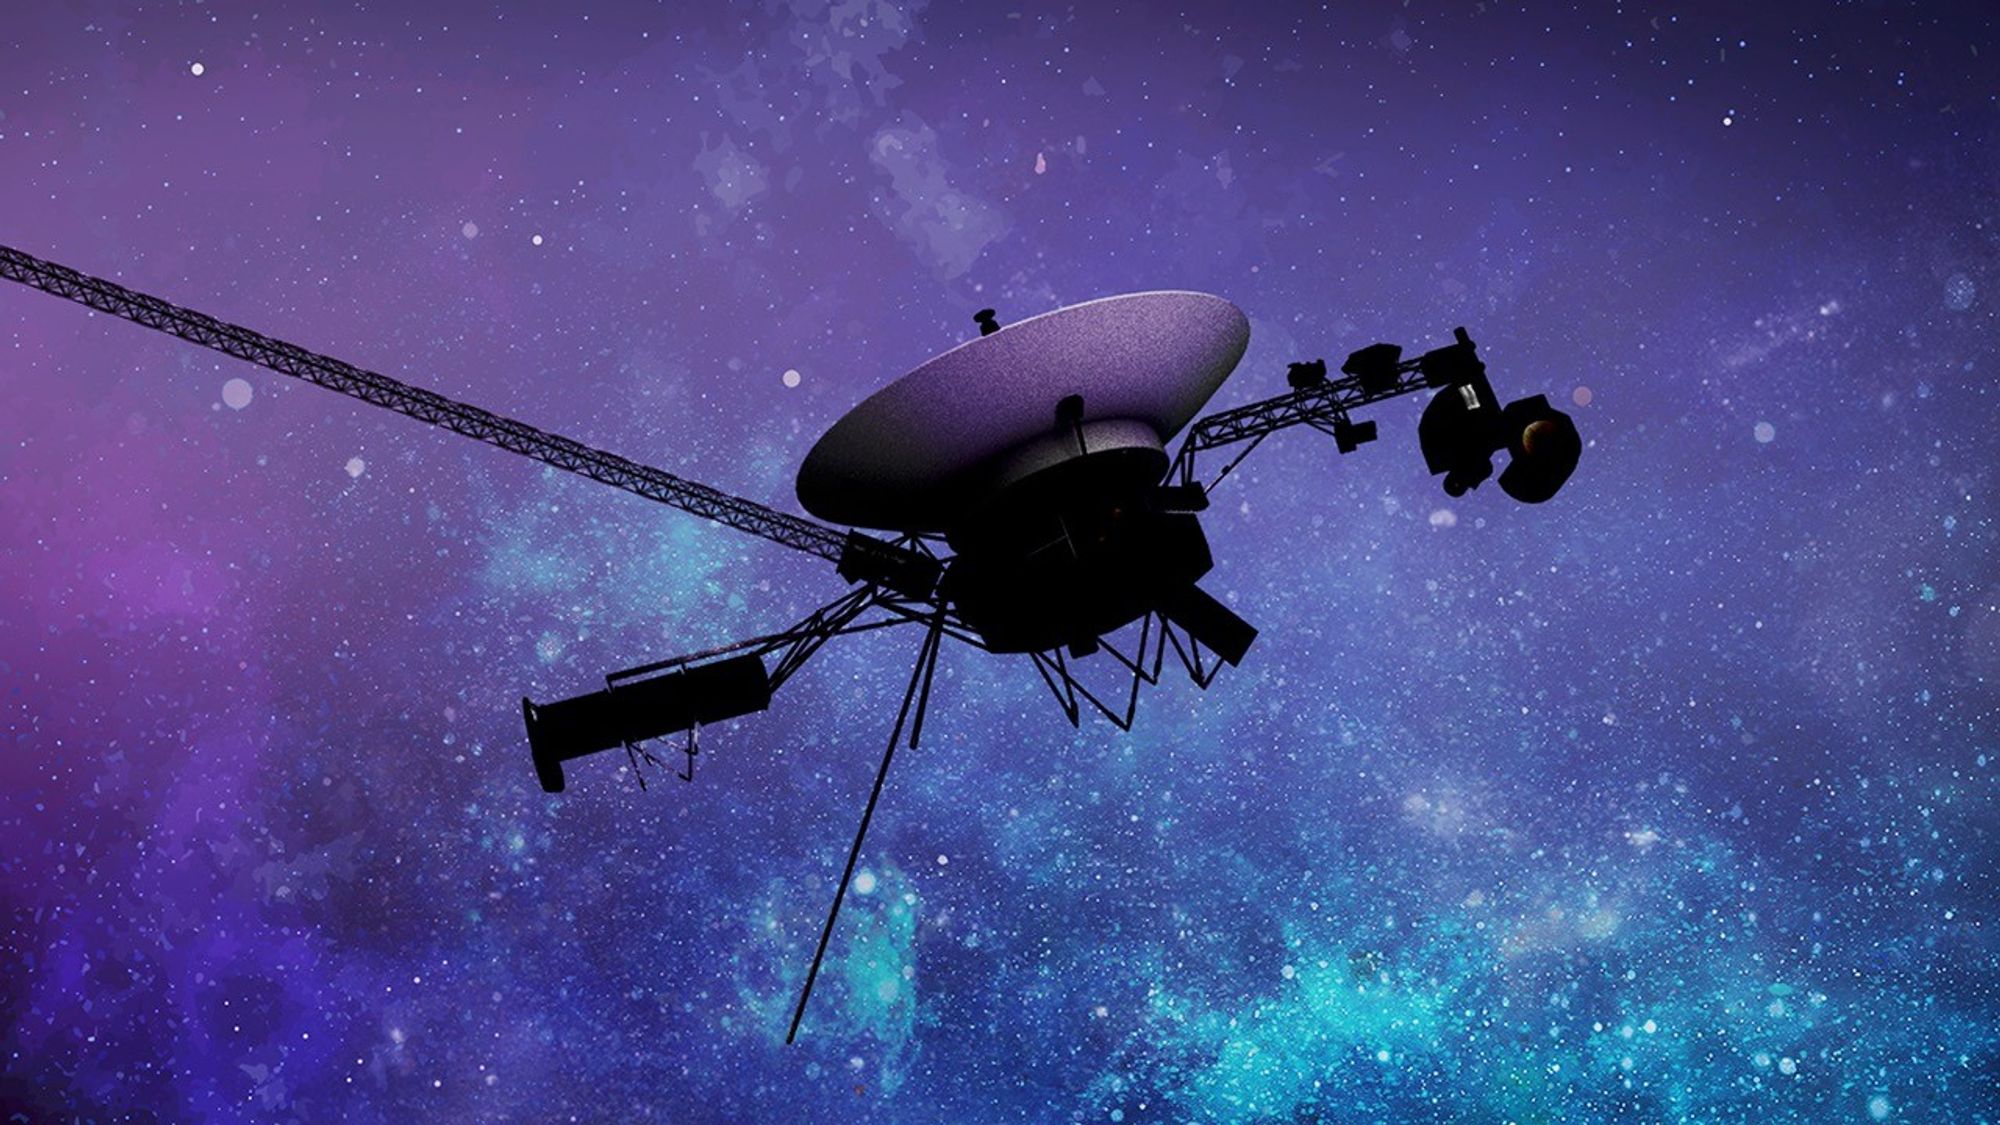
Like a great celestial swan, Voyager 1 is flying `—` swiftly, boldly, albeit a little stiffly in places.
|
||||
|
||||
|  |
|
||||
| [NASA/JPL-Caltech](https://science.nasa.gov/blogs/voyager/2026/04/17/nasa-shuts-off-instrument-on-voyager-1-to-keep-spacecraft-operating/) |
|
||||
|
||||
It moves through interstellar space with enormous momentum, far beyond the planets that once defined its mission, carrying instruments that continue to report from a region no man‑made craft has ever reached. Yet every action it takes is constrained by a finite and steadily diminishing supply of energy, each signal carefully weighed against what it costs to send.
|
||||
|
||||
There is a quiet elegance in that balance.
|
||||
|
||||
Voyager does not insist on doing everything it once did. It does not pursue peak capability when conditions no longer allow it. Instead, it adapts -- releasing some functions so that others can continue, prioritizing what matters most over what is merely possible.
|
||||
|
||||
In engineering, we have a name for systems that behave this way.
|
||||
|
||||
#### We call it **graceful degradation**.
|
||||
|
||||
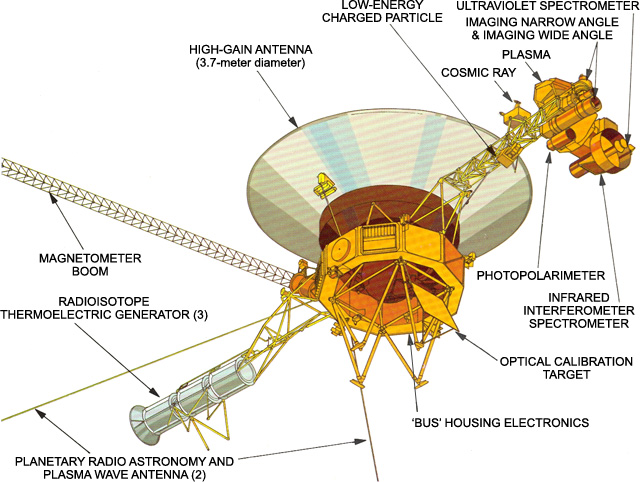
[Low‑Energy Charged Particle (LECP) detector](https://pds-atmospheres.nmsu.edu/data_and_services/atmospheres_data/Voyager/lecp.html)— an instrument that measures ions, electrons, and cosmic rays to map the structure and pressure of the interstellar medium, helping to define the boundary between the solar system and interstellar space— was shut down to conserve power and extend the spacecraft’s operational life.
|
||||
|
||||
Voyager is powered by a radioisotope thermoelectric generator whose output declines as radioactive fuel decays. Every year, available power drops by a few watts. Unlike systems here on Earth, there is no possibility of provisioning more capacity, no redundancy waiting in reserve, and no “scale out” option.
|
||||
|
||||
Seen through a Site Reliability Engineering lens, Voyager’s power margin is its **error budget.** It defines *how much can go wrong* before the mission begins to suffer.
|
||||
|
||||
Early in the mission, that budget was generous. Minor inefficiencies, unexpected behaviors, and non‑optimal configurations could be tolerated. As the decades passed, the margin narrowed. Today, even a modest, unplanned dip of power by a wayward instrument risks triggering Voyager’s undervoltage fault protection — an automated safeguard that will shut components down abruptly to ensure survival.
|
||||
|
||||
In February, a routine roll maneuver caused such a dip. Engineers understood that allowing the spacecraft to cross that line would mean entering a survival mode where system preservation is prioritized over delivering mission value.
|
||||
|
||||
This moment is familiar to anyone who has operated a production system near its limits:
|
||||
|
||||
- CPU saturation turning latency into user-visible slowness
|
||||
- Memory pressure triggering process and container termination
|
||||
- Queues backing up until messages expire undelivered
|
||||
- Storage exhaustion freezing otherwise healthy transactions
|
||||
|
||||
Graceful degradation is about prioritizing your goals and your capabilities, and as you approach a point where you cannot fulfill all your goals, acting *before* you reach that point.
|
||||
|
||||
- Reduce CPU consumption (lower frame rates, remove animations, disable optional features)
|
||||
- Defer low‑priority work (batch reports, replace live data with aggregates)
|
||||
- Prioritize critical traffic and drop nonessential messages
|
||||
- Reject new transactions when storage thresholds are reached to protect core paths
|
||||
|
||||
In Reliability Engineering, as in much of life, we'd rather have brownouts than blackouts.
|
||||
|
||||
While we never want to disappoint users, we'd rather reduce features rather than take outages. We'll degrade experience -in a controlled fashion - rather than lose the service entirely. We shed load in controlled ways instead of letting cascading failures decide the outcome.
|
||||
|
||||
That is exactly what Voyager’s engineers did.
|
||||
|
||||
Years before this moment, scientists and engineers jointly agreed on a shutdown sequence: which instruments would be sacrificed first as power declined, and which capabilities were most critical to preserve. By April 2026, seven of Voyager 1’s ten original science instruments had already been retired. The LECP was simply next on the list — not because it failed, but because its cost‑to‑value ratio was now unfavorable.
|
||||
|
||||
This is the same decision Site Reliability Engineers (SREs) make when:
|
||||
|
||||
- Disabling expensive recommendation pipelines during peak traffic
|
||||
- Serving cached or approximate results instead of fully computed ones
|
||||
- Temporarily turning off background jobs to protect user‑facing latency
|
||||
|
||||
Nothing is broken, *per se*. The system is deliberately choosing to do less so that it can continue to succeed in part rather than fail in total. Graceful degradation is not a weakness; it is a sign of maturity.
|
||||
|
||||
Voyager continues to operate the instruments that provide uniquely valuable data — measuring magnetic fields and plasma waves in interstellar space — while relinquishing others whose contribution, though still useful, no longer justifies their cost.
|
||||
|
||||
Even the LECP shutdown was reversible by design. A small motor that rotates the sensor remains powered, preserving the option of reactivation should future power‑saving measures succeed.
|
||||
|
||||
This is graceful degradation with reversibility in mind. The current state is preserved, while recovery paths maintained and, most importantly, options are left open. Granted, the chances of Voyager suddenly being replenished with fresh plutonium for additional power is exactly 0, but Reliability Engineers here on the ground do plan on overcoming their temporary issues which caused the degradation and using the available options to fully restore services.
|
||||
|
||||
This is why we gate features behind flags instead of deleting code and why we can temporarily change users' capabilities instead of removing them from the system.
|
||||
|
||||
### Balancing Performance, Capacity, and Risk
|
||||
|
||||
Reliability is rarely about maximizing performance. It is about continuously balancing **performance**, **capacity**, and **risk** — especially when capacity is finite and margins are thin.
|
||||
|
||||
Voyager operates permanently at this intersection.
|
||||
|
||||
Performance, in Voyager’s case, is scientific throughput: how many instruments are active, how often measurements are taken, and how much data is returned.
|
||||
|
||||
Capacity is a steadily shrinking power budget that cannot be replenished.
|
||||
|
||||
Risk grows as margins shrink: a sudden undervoltage event could trigger autonomous shutdowns that are difficult, slow, and dangerous to recover from across a 23‑hour communication delay.
|
||||
|
||||
Graceful degradation is how the Voyager team manages this triangle.
|
||||
|
||||
By shutting down the LECP before power levels became critical, the team deliberately traded peak scientific performance for reduced operational risk and preserved capacity for the instruments that matter most.
|
||||
|
||||
|  |
|
||||
| [The status of Voyager's instruments (NASA/JPL-Caltech)](https://science.nasa.gov/mission/voyager/where-are-voyager-1-and-voyager-2-now/#instrument-status) |
|
||||
|
||||
|
||||
**Voyager does less than it once did — but it does so more safely, more predictably, and for longer.**
|
||||
|
||||
This mirrors everyday SRE work:
|
||||
|
||||
- lowering request concurrency to prevent saturation
|
||||
- reducing image quality or refresh rates under load
|
||||
- shrinking feature scope during high-risk windows
|
||||
- renegotiating SLOs instead of pretending nothing has changed
|
||||
|
||||
In each case, performance is intentionally reduced to keep risk within acceptable bounds.
|
||||
|
||||
Because Voyager’s degradation path was defined years in advance, with a healthy system and with management & engineering having time and clarity to make rational trade-offs, the unexpected power dip didn't result in a frantic rush to heroically solve a problem, it triggered a pre-planned process which resulted in a graceful retirement of the instrument chosen ahead of time. No surprises, just good engineering.
|
||||
|
||||
Graceful degradation is a social and organizational capability as much as a technical one. It requires shared understanding across teams, explicit agreement on priorities, and acceptance that loss is inevitable. It's not about preventing failure forever. It is about ensuring that when degradation occurs, it happens on your terms.
|
||||
|
||||
While few of us work on systems like Voyager, there are many commonalities -
|
||||
|
||||
- Our platforms are usually far older than the original business model they were designed to support.
|
||||
- Our architectures often outlast our architects.
|
||||
- Our "temporary" services that we built with “temporary” design decisions have become permanent.
|
||||
|
||||
Our systems survive not by staying perfect, but by letting go gracefully. At least, these are the ones which cause the least stress to their owners and maintainers.
|
||||
|
||||
Voyager is still returning data from interstellar space not because nothing has failed, but because failures have been managed thoughtfully, incrementally, and with humility. Twenty-five billion kilometers from Earth, Voyager continues to demonstrate a lesson every experienced SRE eventually learns:
|
||||
|
||||
The systems that last longest are not the ones that cling to every feature, but the ones that decide, and well in advance, which parts they are willing to give up.
|
||||
|
||||
## Comments
|
||||
|
||||
## Post a Comment
|
||||
|
||||
Reference in New Issue
Block a user