sreweekly: 528 期数据 + 全文抓取(articles/pages + markdown 正文扩充)
This commit is contained in:

@@ -7,3 +7,51 @@
|
||||
## 简介
|
||||
|
||||
What can you do to shorten the time to detect an incident? Some great ideas in here, especially monitoring your company’s main web page for a sudden uptick in traffic.
|
||||
|
||||
## 正文
|
||||
|
||||
Your company has probably invested significantly in what happens after an incident is identified: incident response tooling, trained incident commanders, communication protocols, on-call rotations. That investment matters. But what about the gap between when a problem starts and when anyone on your team knows about it?
|
||||
|
||||
During that gap, customer damage is accumulating. The problem is getting worse, the blast radius is expanding, and nobody on the team is doing anything about it because nobody knows yet.
|
||||
|
||||
You can’t eliminate this gap entirely, but you can shrink it. Four investments make the biggest difference.
|
||||
|
||||
## Broaden your detection surface
|
||||
|
||||
Automated monitoring is the first and best line of defense, but it can only catch the failure modes someone thought to check for. Human detection isn’t a gap you can eliminate; it’s a permanent and valuable part of your detection capability.
|
||||
|
||||
This means your customer support team is part of your detection infrastructure, whether or not you’ve told them so. So is any part of your company that interacts with customers regularly: account execs, customer success managers, even your social media team. They talk to your customers every day and often see concerns emerge before engineering does. And don’t overlook your customers themselves, who won’t limit their reports to your “official” support channels. If all these folks don’t have clear, fast escalation paths to flag potential problems for engineering, you have a detection gap that no amount of monitoring investment will close.
|
||||
|
||||
If your company is a heavy user of its own product, the detection surface extends even further. When I led Slack’s incident management program, literally anyone in the company might notice a problem while using Slack internally. Not every company is in that position (it depends entirely on what the product is), but those who are should take advantage of it. Make sure everyone (all the way down to the part-time security guard covering the front desk on weekends) knows how to report problems they see.
|
||||
|
||||
And watch for indirect signals. One of Slack’s best harbingers of “something is broken, even if we don’t know what yet” was the page-view rate on our public status page. If it started surging upward, we knew that *something* was wrong, even if we weren’t getting any other clear signals yet, and we’d start investigating. It was like smelling a light waft of smoke, well before the smoke detectors and fire alarms go off. If you have a public status page, consider adding its traffic patterns to your monitoring. A sudden spike in visits is a low-cost early warning powered by the collective behavior of your user base.
|
||||
|
||||
## Lower barriers to reporting
|
||||
|
||||
Most of these detection channels depend on someone raising a concern, and that only works if the barrier to doing so is low. At many companies, the only mechanism for raising an alarm is to declare an incident, which triggers a full coordinated response: pages go out, a channel is created, an incident commander is assigned, people drop what they’re doing.
|
||||
|
||||
That’s appropriate when you know you have a real problem. But if the only way to raise a concern is to trigger that entire response, people will hesitate, and rightfully so. Nobody wants to be the person who launched a full incident response over a hunch that turns out to be wrong. So they wait for more evidence, and the detection gap grows.
|
||||
|
||||
Think of it like calling emergency services. When you call 911 (or 999, 000, 112, or whatever your country’s emergency number is), you don’t have to know whether you need an ambulance, a fire engine, a hazmat team, or a bomb squad. You describe what you see, and a trained dispatcher determines how serious the situation is, what sort of response is warranted, and who to send.
|
||||
|
||||
Your incident detection should work the same way: make it easy for anyone to say “I think something might be wrong,” and let someone with training, experience, and context determine what response is warranted. At Slack, introducing a lightweight mechanism for exactly this was one of the most impactful things we did.
|
||||
|
||||
## Continuously right-size your alerting
|
||||
|
||||
It’s tempting to close the detection gap by making your monitoring more aggressive: lower the thresholds, add more alerts, page on anything that twitches. This can backfire badly. Every alert that wakes someone at 3 AM and turns out to be nothing makes it a little more tempting for your on-call engineers to dismiss the next one. Alert fatigue is one of the most insidious threats to detection, precisely because it accumulates gradually. Your alerting system doesn’t fail all at once; it erodes, one false alarm at a time, until the real alerts get lost in the noise.
|
||||
|
||||
The discipline runs in both directions: yes, add monitoring when you discover gaps, but regularly prune alerts that aren’t earning their keep. If a service-owning team can’t get through a review of every alert they received in the past week in a reasonable portion of a weekly ops review meeting, they’re getting too many alerts.
|
||||
|
||||
## Examine the gap
|
||||
|
||||
Another way to shrink the detection gap over time is to examine it after every incident. You’re never going to be able to fully automate detection, but it’s still an ideal worth pursuing. Three questions, asked consistently in every post-incident review, create a steady stream of improvements:
|
||||
|
||||
- How long was the gap between when the problem started and when we detected it?
|
||||
- Could we have detected it sooner?
|
||||
- What monitoring would we need to add, or what threshold would we need to adjust, to catch this kind of problem faster next time?
|
||||
|
||||
## The bottom line
|
||||
|
||||
Investing in detection is investing in the foundation of your entire incident management capability. You can have well-trained incident commanders, practiced responders, and polished communication protocols, but none of it matters until you know there’s a problem.
|
||||
|
||||
## Recent Comments
|
||||
|
||||
@@ -7,3 +7,56 @@
|
||||
## 简介
|
||||
|
||||
What an interesting incident! I recommend reading Azure’s write-up before reading Lorin’s excellent analysis.
|
||||
|
||||
## 正文
|
||||
|
||||
The folks at Microsoft Azure recently wrote up a [post incident review for a networking issue in their West U.S region.](https://azure.status.microsoft/en-us/status/history/?trackingId=ZJV6-SGG) From the included timeline, it looks like the impact was on the order of five hours. It’s a pretty short write-up, but let’s take a look at the contributors.
|
||||
|
||||
On 23 July 2026, a break-fix repair was initiated on an optical device to address a network reliability risk.
|
||||
|
||||
|
||||
The first contributor mentioned in the write-up was work that was done to repair a device in their networking stack. Here I can’t help but think of the first bullet in my [conjecture on why reliable systems fail](https://surfingcomplexity.blog/2017/06/24/a-conjecture-on-why-reliable-systems-fail/). They made a change to the system in order to fix an ongoing problem, and due to a set of circumstances, things got worse rather than better.
|
||||
|
||||
A defect in our blast radius analysis system incorrectly expanded the scope of the repair event to include all optical devices egressing a specific datacenter.
|
||||
|
||||
|
||||
The second contributor mentioned was a (presumably) latent defect in their system. Note the irony of the failure mode here: I suspect this blast radius analysis system usually contributes to reliability, but in this case it hurt reliability by increasing the blast radius.
|
||||
|
||||
The safety validation step, which is designed to confirm that at least one of the two redundant datacenter paths remains available, ran but incorrectly concluded the operation was safe.
|
||||
|
||||
|
||||
The third contributor mentioned was a safety check (good!) that passed even though the action was unsafe (bad!).
|
||||
|
||||
The checks validated each device individually rather than evaluating the aggregate effect of isolating all devices at once, a scenario that was not accounted for because the system was never designed to process a full datacenter’s worth of devices in a single request.
|
||||
|
||||
|
||||
The reason it failed was due to an interaction with the second contributor: the blast radius being all of the optical devices egressing the datacenter. The designers never envisioned that the check would have to handle the sort of scenario that occurred as a result of the blast radius analysis system defect.
|
||||
|
||||
As a result, routes were withdrawn from multiple devices simultaneously, disrupting connectivity between the datacenter and the WAN – therefore impacting traffic entering or leaving the West US region.
|
||||
|
||||
|
||||
It sounds like this change effectively disconnected the West US datacenter from the internet.
|
||||
|
||||
Once the route withdrawals took effect at 14:44 UTC, physical links and routing adjacencies continued to appear healthy, which initially masked the correlation between the break-fix activity and the connectivity disruption
|
||||
|
||||
|
||||
Here we have our fourth contributor: the operators were receiving misleading signals from the system. The links and routes looked healthy, even though connectivity was broken.
|
||||
|
||||
The impact presented as a WAN routing anomaly, as third-party networks could not reach Azure in the region, rather than as a datacenter connectivity failure.
|
||||
|
||||
|
||||
Our fifth contributor is another flavor of misleading signals. The symptoms presented as a routing issue between Azure and third-parties.
|
||||
|
||||
Although all physical work in the region was stopped, our engineers could not correlate to this recent change because the preparation activities in advance of the break-fix did not succeed, so the physical layer and traffic appeared healthy.
|
||||
|
||||
|
||||
This is the sixth contributor mentioned in the writeup. The writing is a little oblique here, but I think what they are saying is that the repair event did not show up in their event log because the repair event didn’t actually complete. It sounds like the preparation activities were the ones that triggered the incident. But, because the repair event didn’t actually happen, the operators looking for events that correlate in time with the onset of the incident didn’t see the triggering event because it didn’t show up in the log of events. That’s my best guess, anyways.
|
||||
|
||||
Our automated recovery and rollback system detected the device failures, and attempted multiple retries to restore the affected devices. However, because that system depended on the same datacenter connectivity that had been disrupted, its automated rollback attempts were unsuccessful.
|
||||
|
||||
|
||||
This is the seventh and final contributor mentioned. Azure has an automated recovery and rollback system (good!), but the failure mode in this case prevented automated rollback from succeeding (bad!).
|
||||
|
||||
As always, I’d love to know more about how the operators identified what the failure mode actually was, and how they traced it back to the optical device repair work.
|
||||
|
||||
## One thought on “Quick thoughts on Azure Regional Outage from July 23, ’26”
|
||||
|
||||
@@ -7,3 +7,142 @@
|
||||
## 简介
|
||||
|
||||
> Distributed databases rarely fail in the clean, isolated ways described by component diagrams. They fail through timing gaps, stale metadata, ambiguous ownership, retry storms, incompatible health decisions, and overlapping maintenance activity.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# Why Distributed Databases Fail at Coordination Boundaries
|
||||
|
||||
Failures in distributed systems emerge at interfaces where independent components exchange timing, ownership, and state information.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
Distributed databases are often evaluated through familiar technical dimensions: replication factor, consistency model, partitioning strategy, throughput, latency, and recovery time. These characteristics matter, but they do not fully explain why systems that appear healthy at the component level still experience severe production failures.
|
||||
|
||||
In many cases, the storage engine is not the weakest part of the architecture. The failure occurs at a coordination boundary.
|
||||
|
||||
A coordination boundary is any point where independently operating components must agree on timing, ownership, ordering, configuration, or state. These boundaries appear between replicas, partitions, control planes, data planes, load balancers, clients, metadata services, and background maintenance processes. Each component may behave correctly according to its local rules while the overall system produces an incorrect or unstable result.
|
||||
|
||||
This is why [distributed database](https://dzone.com/articles/what-is-a-distributed-database) incidents can be difficult to predict. The database may not fail because a server crashes or a disk becomes unavailable. It may fail because two healthy components temporarily disagree about who owns a partition, whether a node is available, or which version of configuration should be applied.
|
||||
|
||||
## Local Correctness Does Not Guarantee System Correctness
|
||||
|
||||
Engineers naturally reason about software components individually. A node accepts requests, writes data, replicates changes, responds to health checks, and reports metrics. If each of those behaviors appears correct, the system is assumed to be healthy.
|
||||
|
||||
Distributed systems challenge that assumption.
|
||||
|
||||
A replica can be healthy but delayed. A coordinator can be available but operating with stale metadata. A load balancer can route traffic correctly according to its current configuration while that configuration no longer reflects the database topology. A client can retry a failed request according to policy while unintentionally amplifying load during a partial outage.
|
||||
|
||||
Each component is locally correct. Their interaction is not.
|
||||
|
||||
Consider a partition ownership transition. One node is being removed, replaced, or scaled down, and another node is taking responsibility for the affected data range. The outgoing node may believe it still owns the partition because it has not received the latest control-plane update. The incoming node may already begin accepting requests because it has received a newer version of the assignment.
|
||||
|
||||
For a brief period, both nodes may behave correctly according to the information available to them. The system, however, has entered an ambiguous ownership state.
|
||||
|
||||
That ambiguity can lead to duplicate processing, inconsistent writes, rejected requests, or unexpected latency. The problem does not exist entirely inside either node. It exists at the boundary where ownership information is exchanged and interpreted.
|
||||
|
||||
## Time Is Often the Hidden Coordination Dependency
|
||||
|
||||
Many distributed database designs avoid relying on perfectly synchronized clocks. Even so, time remains embedded throughout the system.
|
||||
|
||||
Timeouts determine when a request is considered failed. Leases determine how long a node retains authority. Heartbeats influence failure detection. Retry intervals shape traffic behavior. Expiration policies determine when data should disappear. Background processes decide when to compact, replicate, repair, or rebalance information.
|
||||
|
||||
These mechanisms create coordination dependencies even when the architecture does not explicitly describe them that way.
|
||||
|
||||
For example, a client sends a write request and does not receive a response before its timeout. The client cannot immediately know whether the write failed, succeeded, or is still being processed. It retries the request through another route.
|
||||
|
||||
If the database supports idempotent request handling, the retry may be safe. If it does not, the same logical operation may be applied twice. The first server and the client both followed their expected behavior. The uncertainty appeared between them because completion and acknowledgment were separated by a network boundary.
|
||||
|
||||
This is a common distributed systems pattern. A timeout provides information about waiting, not about the final outcome of an operation.
|
||||
|
||||
Cloud architects should therefore treat every timeout as an ambiguity boundary. Timeout behavior must be designed together with idempotency, deduplication, retry limits, load shedding, and observability. Configuring a timeout without defining the system’s response to uncertainty simply moves the failure elsewhere.
|
||||
|
||||
## Metadata Can Become More Critical Than Data
|
||||
|
||||
[Database reliability](https://dzone.com/articles/stop-being-afraid-of-databases) discussions frequently focus on protecting stored records. Replication, backups, checksums, and repair mechanisms are designed to preserve data durability.
|
||||
|
||||
However, the metadata that describes how data should be accessed can be just as important.
|
||||
|
||||
Partition maps, routing tables, node membership, schema versions, configuration states, and feature capabilities determine how requests travel through the system. If this metadata becomes stale or inconsistent, the underlying data may remain fully intact while applications lose the ability to access it reliably.
|
||||
|
||||
This is particularly important in systems that separate the control plane from the data plane. The control plane decides how infrastructure should be configured. The data plane processes live requests using that configuration.
|
||||
|
||||
Separating these responsibilities improves scalability and operational isolation, but it introduces another coordination boundary. Configuration changes must move safely from the control plane to every affected data-plane component. During that transition, the system may contain multiple valid configuration versions at once.
|
||||
|
||||
The engineering question is not merely whether a configuration update can be delivered. It is whether old and new versions can coexist without violating system correctness.
|
||||
|
||||
Safe configuration rollout often requires versioning, backward compatibility, staged activation, and explicit rollback behavior. Without those protections, a harmless-looking control-plane update can produce a data-plane outage even when no database node has failed.
|
||||
|
||||
## Load Balancing Can Amplify Database Instability
|
||||
|
||||
[Load balancing](https://dzone.com/articles/mastering-load-balancers-optimizing-traffic-for-hi) is sometimes treated as an infrastructure layer outside the database itself. In practice, routing behavior directly influences distributed database reliability.
|
||||
|
||||
When a node slows down, a load balancer may reduce traffic to it. That appears beneficial, but the remaining traffic must go somewhere. Healthy nodes receive additional load, their latency increases, and health checks may begin failing. The load balancer then removes more nodes, increasing pressure on the smaller remaining pool.
|
||||
|
||||
This creates a feedback loop.
|
||||
|
||||
The database causes routing changes, and the routing changes make the database less stable. Neither system is necessarily defective. The failure emerges from their interaction.
|
||||
|
||||
Aggressive health checks, short timeout thresholds, synchronized retries, and immediate node removal can turn a minor performance issue into a broad outage. A more resilient design considers the rate of change, not only the current health signal.
|
||||
|
||||
Cloud architects should ask whether routing decisions become less reliable during overload. They should also examine whether the database and load-balancing layers use compatible definitions of health. A node capable of serving read traffic may be temporarily unsuitable for writes. A node completing recovery may be reachable but not ready for production load.
|
||||
|
||||
Binary healthy-or-unhealthy classifications often hide these operational differences.
|
||||
|
||||
## Background Work Creates Coordination Pressure
|
||||
|
||||
Distributed databases perform significant work outside the direct request path. Replication, compaction, repair, rebalancing, expiration, backup, and cleanup processes compete for shared resources.
|
||||
|
||||
These operations are often independently scheduled, which creates additional coordination boundaries. A compaction process may increase disk activity while a rebalance consumes network bandwidth. A repair job may begin during a traffic peak. Expired records may accumulate faster than cleanup processes can remove them.
|
||||
|
||||
Each mechanism may operate within its configured limits, yet their combined effect can overwhelm the system.
|
||||
|
||||
Time-to-live functionality provides a useful example. Expiring a record appears to be a simple data operation, but at scale it affects storage layout, indexing, replication, read behavior, and cleanup scheduling. The system must determine when an item is logically expired, when it should stop appearing in reads, and when its physical storage can be reclaimed.
|
||||
|
||||
Those events may not occur simultaneously.
|
||||
|
||||
If expiration processing is poorly coordinated, large groups of records can become eligible for deletion at the same time, creating bursts of background work. The feature itself works correctly, but the interaction between expiration timing and resource consumption can destabilize the database.
|
||||
|
||||
The broader lesson is that operational features should be evaluated as distributed workflows, not isolated functions.
|
||||
|
||||
## Designing for Boundary Failures
|
||||
|
||||
The most effective way to improve distributed database reliability is to identify coordination boundaries during architecture design.
|
||||
|
||||
For every boundary, engineers should define what information crosses it, how that information is versioned, how long it remains valid, and what happens when delivery is delayed or duplicated. They should also determine whether the receiving component can safely operate with stale information.
|
||||
|
||||
Observability should follow the same structure. Monitoring individual nodes is necessary, but it is not sufficient. Teams need visibility into ownership transitions, metadata propagation delays, retry amplification, routing changes, replication lag, and background-work queues.
|
||||
|
||||
These signals reveal disagreement between components before that disagreement becomes a complete outage.
|
||||
|
||||
Testing must also include transitional states. Steady-state benchmarks show how a system performs when ownership, routing, and configuration are stable. Production failures frequently occur while those conditions are changing.
|
||||
|
||||
Architects should test node replacement, delayed configuration propagation, partial network loss, rolling upgrades, uneven clock behavior, repeated retries, overloaded background workers, and conflicting health signals. These scenarios expose the boundaries where local assumptions stop matching global reality.
|
||||
|
||||
## Reliability Lives Between Components
|
||||
|
||||
Distributed databases rarely fail in the clean, isolated ways described by component diagrams. They fail through timing gaps, stale metadata, ambiguous ownership, retry storms, incompatible health decisions, and overlapping maintenance activity.
|
||||
|
||||
The database node that appears responsible may only be the place where the problem becomes visible.
|
||||
|
||||
For cloud architects and engineers, the practical shift is to stop treating coordination as an implementation detail. Coordination is part of the system’s correctness model.
|
||||
|
||||
Storage engines protect data. Replication protects availability. Load balancing distributes work. Control planes manage change. None of these mechanisms can provide reliability independently.
|
||||
|
||||
Reliability emerges from how they coordinate, especially when information is delayed, incomplete, duplicated, or temporarily inconsistent.
|
||||
|
||||
That is where distributed databases are most likely to fail, and where architects should focus first.
|
||||
|
||||
Database
|
||||
Load balancing (computing)
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
|
||||
@@ -13,3 +13,127 @@ I love this concept of a “political incident”:
|
||||
And ouch, I felt this bit:
|
||||
|
||||
> You have spent forty minutes of the incident on the severity field.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
The hands went up before I finished.
|
||||
|
||||
Not straight away. There was a gap of about four seconds between the sentence and the first one, which is roughly how long it takes to decide you disagree with someone with enough standing that disagreeing carries a cost. Then a second. Then three more, stacked in the participant list, waiting.
|
||||
|
||||
I was on a call with a room full of incident commanders. The subject was political incidents, by which I mean the ones where the severity arrives before the impact assessment does. What I said was this: in a political incident it is easier not to fight it. Take the escalation. Run the room like you didn’t. Pay lip service to the executive right up until the point they leave the bridge.
|
||||
|
||||
I have said less popular things in that forum. I have not said one that produced a quieter four seconds.
|
||||
|
||||
They waited. That is the part worth recording. Nobody interrupted, nobody typed in the chat, and the hands stayed up while I finished a spiel that had another two minutes in it. This is a room of people trained to hold position under pressure and let the commander finish. They applied the training to me.
|
||||
|
||||
Then it came back, and it was not tactics. It was principle. Push back. Hold the line. Defend the process. The severity matrix exists for a reason, and the reason is that somebody has to be willing to say no to a senior person while the phone is ringing.
|
||||
|
||||
What I had not expected was who it came from. Not the new ones.
|
||||
|
||||
They said it the way you say something about a thing being taken from you.
|
||||
|
||||
I thought they had it precisely wrong. I still do.
|
||||
|
||||
|
||||
|
||||
Here is what I had done before I stopped doing it.
|
||||
|
||||
I fought them. Every time. I had the matrix, and the matrix was clear, and I could show you the row and the column and the impact definition that put the thing at a three. This is not difficult work. Anybody can read a table. What I did not understand for a long time is that nobody I was arguing with was reading it, or had ever read it, or had at any point agreed to be bound by it.
|
||||
|
||||
So it goes to the manager. The manager takes it up. It comes back down a different pipe entirely and it arrives mid-incident, from a skip two levels removed, and it is four words long. Just do it, please.
|
||||
|
||||
You are on a bridge with fourteen people and an unhealthy service. You have spent forty minutes of the incident on the severity field. And you are going to lose the forty-first as well, because the answer was always going to be yes, and the only thing your forty minutes bought was a record of you being difficult about it.
|
||||
|
||||
Then the hallway. Days later, no meeting invite, no thread. Someone stops you near the kitchen and says you should just do what is asked. Friendly. Actually friendly, which is the part that stays with you. They are not delivering a reprimand, they are doing you a favour, passing on something said about you in a room you were not in.
|
||||
|
||||
It arrives in myriad channels, that irritation. Never the one you fought in.
|
||||
|
||||
I used to read this as a failure of the framework. It is not that.
|
||||
|
||||
They were never working to our severity matrix. They had a pressing need and an escalation of their own and a matter to deal with, and they had learned that the smaller the number the faster their matter moved. That is not a misunderstanding of the process. That is a correct reading of it.
|
||||
|
||||
It is the cost of running a good incident command practice. When urgency is high, people look for the fastest lever in the building. You built it.
|
||||
|
||||
|
||||
|
||||
I get paged into a bridge already in progress. This happens. What happens less often is that when I arrive there is someone three levels above me on the call, issuing instructions.
|
||||
|
||||
So something has occurred. I do not yet know what.
|
||||
|
||||
I run the intros anyway, because the ritual is load-bearing and because it buys me ninety seconds of looking at people. Commander on the call. Where are we. What is the sitrep. Who has the deployment.
|
||||
|
||||
The engineers answer. They answer correctly, in order, with the right level of detail. And they are sullen in a way I recognise before I can account for it. Not tired. Not stuck. There is a particular flatness that people carry after they have been told off for a decision that was right, and they know it was right, and they have worked out that saying so a second time will cost them more than the first time did.
|
||||
|
||||
I do not ask what happened before I joined. I have the answer.
|
||||
|
||||
So I smile. I take the plan from the team, and I read it back, and I confirm the deployment window and the rollback trigger. Then I turn to the person three levels up and I ask whether there is anything else.
|
||||
|
||||
There is not. Command is visible, the number is correct, the machine is running. They disembark.
|
||||
|
||||
I count four seconds.
|
||||
|
||||
Then I say the actual thing, which is this. The deployment takes three hours. Plan B is staged. The alerts are rigged and they will fire, and until they fire there is nothing here for any of you to do.
|
||||
|
||||
I ask whether we need to be on this call while it runs.
|
||||
|
||||
They look at me like I have taken the floor out. Twenty minutes ago they were reprimanded for running a three as a three, and now the incident commander is standing them down from three hours of watching a number increment on a dashboard nobody is going to act on.
|
||||
|
||||
We push what matters into the channels. We adjourn. Three and a half hours later it resolves.
|
||||
|
||||
The executive is satisfied. The team is intact. Nobody has had a conversation about the severity matrix, because there was nothing to have a conversation about. The severity is a two. It says so in the record.
|
||||
|
||||
I did not run a two. I ran a three with a two written on it, and I sent six people home.
|
||||
|
||||
|
||||
|
||||
Here is what I told the room of incident commanders, and here is where it stops being true.
|
||||
|
||||
I told them the loop closes. Absorb the escalation, run the incident properly, and the correction arrives later, in the review, where everybody has hindsight and nobody has adrenaline. The severity gets named as inflated. The record gets amended. It costs nothing because by then it costs nothing.
|
||||
|
||||
I have sat in a great many of those reviews. I have watched that correction arrive perhaps a handful of times.
|
||||
|
||||
What happens instead is that I read a post-incident review for a severity two and the review is not about a severity two. The impact section does not describe an impact. The timeline has a forty minute gap at the start that nobody explains. The whole document has the shape of a thing written around an object rather than about it.
|
||||
|
||||
So I ask why it was escalated.
|
||||
|
||||
Nobody answers. I ask again, differently. Somebody offers a technical reason that is not a reason. I ask a third time, and this is the part I want on the record, because three times is not a rhetorical device, it is the actual number, and by the third one everybody in the room understands that I am not going to stop.
|
||||
|
||||
Then someone says it. Meekly, or with a flash of irritation at having to be the one. A head of engineering escalated this. An executive did not have a report on time.
|
||||
|
||||
And the room changes. Not to relief. To something closer to embarrassment, the collective adjustment of a group of adults who have all been carefully not saying the same thing and have just found out that everyone else was doing it too.
|
||||
|
||||
Unless you were on the bridge, it is not information. It is folklore. It is passed in hallways and hushed the way you hush a name you do not want to summon, and it never once travels far enough to reach a document.
|
||||
|
||||
That is not a review process failing at its job. A review process that cannot write down who escalated something is telling you what it is for. It is for reviewing engineers.
|
||||
|
||||
The absorption works. I have never doubted the absorption. It was the other half I promised them, the half that closes the loop, that I had less evidence for than I sounded like I did.
|
||||
|
||||
Absorption without correction is not neutral. It is a subsidy. I gave that executive a resolved incident, a satisfied bridge, no friction and no consequence, and a review that could not write down what they had done. The next one arrives sooner. Absorb and correct, or do not absorb.
|
||||
|
||||
|
||||
|
||||
So I ask the room whether we can put it in the review.
|
||||
|
||||
They say yes. They mean it at the time, or they mean it enough. Sometimes it appears. More often the document goes out unchanged, and the cycle starts again some weeks later with different people and the identical shape.
|
||||
|
||||
Smile and nod. Agree in the room, decline in the artefact.
|
||||
|
||||
I know that move. I taught it in a forum once and five hands went up.
|
||||
|
||||
What goes in instead is the actions. There are always actions, because a review without actions is a review that failed, and everybody in the room understands the assignment. So they write them. Deliver the next phase of this project faster. Improve the reliability of the report generation. Owners against each one. Due dates. Engineering time apportioned in a planning session six weeks later by people who were not on the bridge and will never be told why the work exists.
|
||||
|
||||
This is administrative violence. The three hour call was not. A three hour call costs an afternoon. This costs a quarter, and it is the only account of the event that will exist in five years.
|
||||
|
||||
The whole thing is measurable, and the measurement is simple. Ask whether the review can record who escalated it and why. Do not argue for it. Just ask, and then watch what the answer is.
|
||||
|
||||
A review process with an aversion to authority will never work. The answer to that one question tells you exactly how safe the people in that building actually feel. Not the survey. Not the values on the wall. Whether a document can contain the sentence “this was escalated by a head of engineering because a report was late,” and survive.
|
||||
|
||||
I stood in front of a room of commanders and they told me I was giving something away. They said it the way you say a thing is being taken from you.
|
||||
|
||||
They were right that something was being taken. Nobody has come for the severity matrix.
|
||||
|
||||
What gets taken is the record. Every absorbed escalation produces a document that is accurate about the outage and silent about the cause.
|
||||
|
||||
And the incident is a two. The record says so. It will say so forever.
|
||||
|
||||
@@ -7,3 +7,77 @@
|
||||
## 简介
|
||||
|
||||
Where can you safely use LLM agents, versus when you should keep things in human hands? This one has some good criteria to consider.
|
||||
|
||||
## 正文
|
||||
|
||||
**Five key takeaways:**
|
||||
|
||||
1. Automate based on impact and recoverability, not on whether the AI is technically capable of doing the task.
|
||||
2. Alert triage, anomaly detection, incident summaries, capacity forecasting — these are the easy wins. Low risk, high value.
|
||||
3. Production changes, incident command, security response, severity calls — keep a human's name on these. Always.
|
||||
4. Reversibility and blast radius are better questions than "can the AI do this."
|
||||
5. The goal isn't AI replacing engineers. It's AI clearing enough noise that engineers can actually think.
|
||||
|
||||
I've sat through the version of this conversation that sounds like a vendor pitch — AI triages everything, drafts your runbooks, predicts outages before they happen, and nobody gets paged at 2 a.m. anymore. I've also watched the other version happen in real time: an automated remediation script restarts the wrong service, confidently, at 11 p.m., and a 20-minute blip turns into a four-hour outage while everyone tries to figure out why the "fix" made things worse.
|
||||
|
||||
Both of those are real. AI is already inside SRE workflows whether or not anyone signed off on it — the question that actually matters is where it belongs, and where a human still needs to be the one holding the decision.
|
||||
|
||||
None of what follows comes from a whitepaper. It's from watching what breaks when teams move too fast with this stuff, and what quietly gets better when they don't.
|
||||
|
||||
## Reversibility and blast radius
|
||||
|
||||
Here's the mental model I keep coming back to before automating anything: can you undo it, and how bad is it if you're wrong?
|
||||
|
||||
Restarting a pod — reversible, low stakes. Deleting a database backup — not reversible, at all. Scaling a service up is easy to walk back. Silencing an alert for six hours is technically reversible too, except the six hours where something real happened and nobody saw it isn't something you get back.
|
||||
|
||||
Blast radius is the other half of it, and it's not the same thing as severity. A misclassified low-priority alert costs a few wasted minutes. A misrouted sev-1 costs an hour of response time during an active outage, while the right team sits there not knowing they should be paged. And blast radius scales with what the action touches — one service versus a shared piece of infrastructure everything depends on, even when both look equally "minor" on paper.
|
||||
|
||||
Anything with low reversibility and a wide blast radius shouldn't be running on autopilot. Anything reversible and contained is fair game. The stuff in between is where you actually need judgment — specifically, judgment from the people who'll be the ones on call when it goes sideways.
|
||||
|
||||
Notice this framing never asks whether the AI *can* do something. It asks what happens if it's wrong. That's the more useful question, and it's the one most teams skip.
|
||||
|
||||
## Where this actually works well
|
||||
|
||||
**Alert noise.** This is the least controversial win there is. Somewhere between 30 and 60% of production alerts are noise by the time a human sees them — duplicates, transients, things that resolved themselves three minutes ago. AI grouping related alerts, suppressing known-flapping signals, correlating spikes with recent deploys — worst case, something gets mislabeled and a human still catches it. Low blast radius, fully reversible. This is exactly the profile you want.
|
||||
|
||||
One catch: it only works well tuned to your environment, not a generic model. An alert that always fires right before a nightly batch job and clears itself a minute later is trivial to suppress — but only if the model actually knows about your batch schedule. Skip that step and you've just added a second layer of noise on top of the first.
|
||||
|
||||
**First drafts of runbooks and postmortems.** Runbook rot is one of the oldest problems in this field. The doc that was accurate in 2022 is a landmine now — nobody updates it, an incident hits, someone follows it anyway, and step four references a service that got decommissioned eight months ago. AI is genuinely good at pulling together a first draft from past incidents, change logs, whatever documentation exists. Same for postmortems — a draft that someone who actually lived through the incident reviews before it goes out saves real hours.
|
||||
|
||||
**Forecasting and anomaly detection.** This is pattern matching, and models are good at pattern matching. A holiday traffic spike that happens once a year gives engineers almost no reps to build intuition about — but a model trained across several years of that same spike has plenty. The important part: keep this as a recommendation a human acts on, not something that auto-provisions infrastructure on its own. The moment it stops informing a decision and starts making one, the blast radius changes.
|
||||
|
||||
**Narrow, well-understood auto-remediation.** This one comes with real caveats, but it earns its place. A specific service that needs a restart when it hits a known stuck state, a queue that needs draining past a defined threshold — fine, if the failure class is precisely defined, tested, and low-blast-radius by design. And there has to be a circuit breaker. If the fix doesn't work within a set window, it stops and escalates instead of retrying forever on a wrong diagnosis. Automation that keeps trying the same broken fix is worse than doing nothing.
|
||||
|
||||
## Where it doesn't belong
|
||||
|
||||
**Severity calls.** Get this wrong either direction and it costs you. A real sev-1 marked as low pulls in the wrong people at the wrong urgency while an SLA clock runs. A minor issue marked critical drags a response team into something that didn't need them at 3 a.m. AI can surface context and flag patterns worth escalating — but the actual call needs a name attached, someone accountable for it. "The model said it was low severity" doesn't hold up in a postmortem.
|
||||
|
||||
**Production changes without sign-off.** Config changes, scaling decisions, anything touching a database directly, restarts outside that narrow bounded case above — a human authorizes these. AI can prep the change, check it against known-good patterns, even simulate the blast radius. What it shouldn't do is decide the moment is right and pull the trigger itself.
|
||||
|
||||
**Security incidents.** Different risk shape entirely. Miss something real and an active compromise sits there while the system waits for more confirmation. False-positive and you've locked out legitimate engineers mid-response. AI correlating logs to surface signal fast — genuinely useful. Containment and escalation decisions — that needs someone who can weigh legal and business context a model was never trained on.
|
||||
|
||||
**Root cause, as a stated fact.** AI narrowing the search space by correlating deploy timing with metric shifts is useful groundwork. But writing "root cause: X" in a postmortem is a claim that shapes what the org fixes next and what it decides to ignore. Get that wrong because a correlation looked convincing, and the actual bug ships again next quarter.
|
||||
|
||||
**Who to escalate to.** This is context a model just doesn't have — who's already underwater tonight, what else is on fire across the org, whether the responding engineer's confidence is real or performed. Escalation is a trust call as much as a technical one.
|
||||
|
||||
## The thing nobody's measuring
|
||||
|
||||
There's a slower cost that never shows up in a single incident review: engineers stop building intuition when AI absorbs all the routine reps. The edge cases are exactly where judgment matters most — and they're exactly the cases you need practice on the boring stuff to be ready for. A team leaning hard on automation can look great for a long stretch, right up until something shows up that doesn't match anything the model — or the team — has seen before.
|
||||
|
||||
This isn't an argument against automating things. It's an argument for being honest about which reps you're willing to give away.
|
||||
|
||||
## A few practices worth adopting
|
||||
|
||||
- Decide, as a team, which categories of action AI can take alone versus which need a sign-off — decide this before an incident forces the question at 2 a.m.
|
||||
- Keep an actual human accountable for anything irreversible. Not nominally "in the loop" — actually reviewing before it executes.
|
||||
- Build in a circuit breaker for anything automated. If it doesn't work within a defined window, it escalates instead of retrying.
|
||||
- Rotate people through the routine cases sometimes, even when AI could handle it, so the skill doesn't quietly disappear.
|
||||
- Revisit the boundary as systems change. A failure class that was well-understood six months ago might not be anymore after an architecture shift.
|
||||
|
||||
Skip this and you end up with automation debt, eroded skills, and a production system nobody fully understands anymore — which is a worse place to be than where you started.
|
||||
|
||||
## Where this leaves things
|
||||
|
||||
It's not really a question of whether to use AI. It's whether you're using it somewhere judgment genuinely isn't needed, or somewhere it is and you've just decided waiting for a human is too slow.
|
||||
|
||||
One of those is a real force multiplier. The other is a liability with a delay timer on it.
|
||||
|
||||
@@ -7,3 +7,172 @@
|
||||
## 简介
|
||||
|
||||
I learned a lot about Git while reading this one. Speeding up Git clones in CI may not seem important, but it will when you’re trying to roll out a fix during an incident.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
Mike Thompson
|
||||
|
||||
Senior Staff Engineer
|
||||
|
||||

|
||||
|
||||
Daniel Esponda
|
||||
|
||||
Staff Engineer
|
||||
|
||||
If you have ever watched a CI job sit on “Fetching repository …” while nothing seems to happen, you already know the unglamorous truth about continuous integration: Every job begins by getting the code, and getting the code is not free.
|
||||
|
||||
At Datadog, CI fetches code millions of times a week across thousands of repositories. Our largest repositories are monorepos with years of history and hundreds of thousands of files. At that scale, `git clone` stops being a footnote and becomes a large contributor to CI run times.
|
||||
|
||||
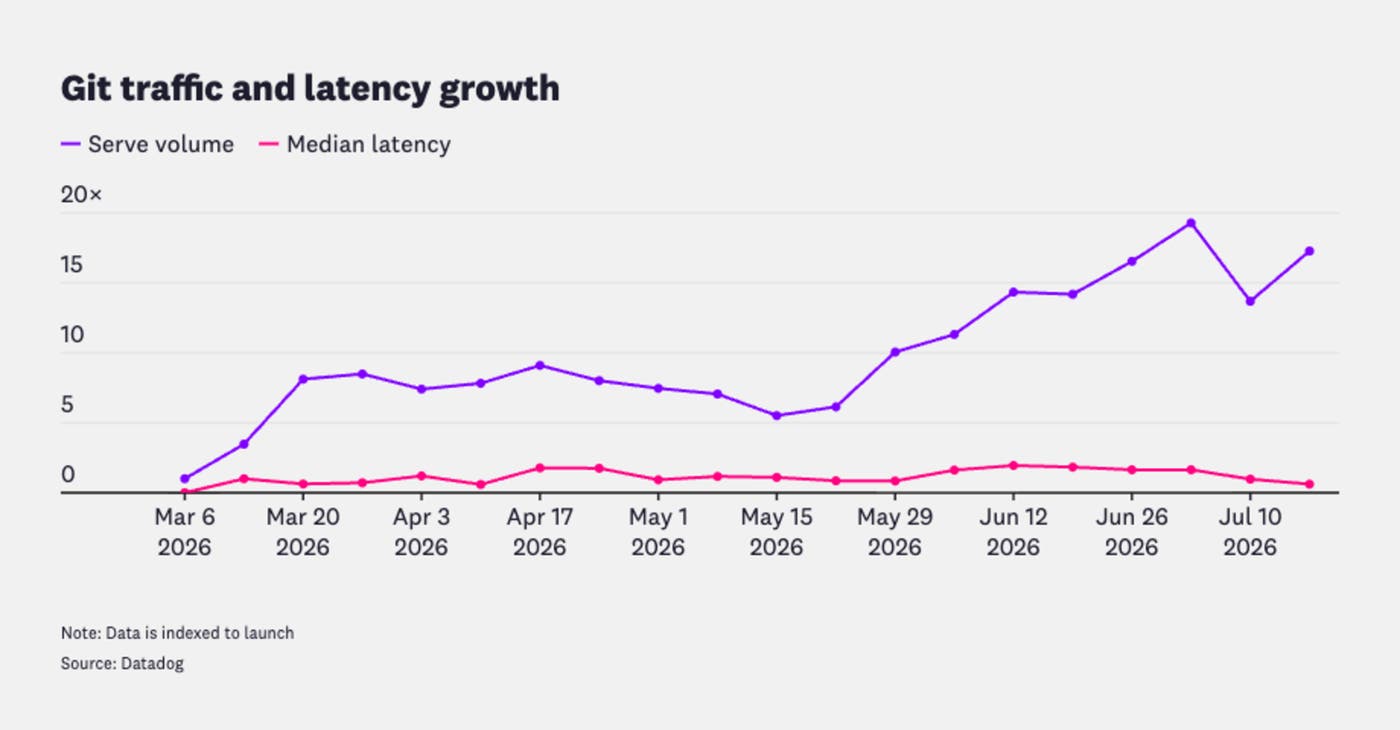
This is the story of **gitretriever**, the Git mirror we built to serve code to CI at Datadog scale. In its first 4 months, gitretriever served more than a billion Git requests and hundreds of terabytes of code. Today gitretriever handles more than 100 million requests each week. Despite the 20× traffic growth since launch, median latency has remained around 40 ms, while fetch-serving CPU on our previous Git backend has dropped by three to four times.
|
||||
|
||||
## [Serving Git to CI, and why it gets hard](https://www.datadoghq.com#serving-git-to-ci-and-why-it-gets-hard)
|
||||
|
||||
Datadog has a unique CI setup: GitHub serves as the authoritative code repository, while almost all of our internal CI workloads run on a self-hosted GitLab installation. CI fetches from GitLab’s Gitaly, fronted by Praefect (Gitaly Cluster’s routing and replication manager) and kept in sync with GitHub by an internal service (aptly named “codesync”). This hybrid architecture has carried us through more than a decade of growth.
|
||||
|
||||
But CI load does not grow smoothly. The expanding use of AI coding agents has driven an order-of-magnitude increase in Git traffic, with agents hitting Git far harder and more often than even our most active contributors ever could. That traffic comes on top of the continually growing load from internal deployment, auditing, and security services. As that growth accelerated, the pressure hit hardest where our code is densest: our large monorepos. Operational load increased, CI run times grew, and multi-hour long CI outages became more frequent. It was clear we needed a more sustainable solution.
|
||||
|
||||
## [Why the usual fixes don’t scale](https://www.datadoghq.com#why-the-usual-fixes-dont-scale)
|
||||
|
||||
We tried adding capacity, we tried increasing instance size, we tried placing different repositories on dedicated backends, and we tried optimizing build pipelines. Things would improve for a week or two, but then our CI infrastructure would inevitably end up degraded or outright down. So why didn’t any of the usual approaches work?
|
||||
|
||||
A single fetch from a large monorepo can consume several seconds of server CPU. At peak, hundreds of jobs perform fetches at the same moment and land on the same handful of nodes. Adding capacity did little to reduce per-node CPU usage. In some cases, adding more nodes made the problem worse.
|
||||
|
||||
Before committing to a new architecture, we had to figure out why none of our previous attempts at fixing the problem had worked:
|
||||
|
||||
- **Scale the backend or add nodes** : In our replicated setup, every write had to be copied to every replica. Adding a node increased replication overhead instead of relieving it.
|
||||
- **Put a content delivery network (CDN) or caching proxy in front** : The expensive part of a fetch isn’t a static byte range you can cache at the edge. It’s computation that’s specific to each client’s request.
|
||||
- **Clone on demand from GitHub** : That simply moves the thundering herd upstream, where we run into server-side rate limits.
|
||||
|
||||
The common thread was that we had been scaling the wrong axis. Read traffic scales with the number of CI jobs, but in our replicated architecture, write costs scale with the number of replicas. Every time we added replicas to handle more reads, we also increased replication overhead, and more CPU time went to maintaining the system instead of serving fetches.
|
||||
|
||||
To understand why serving those fetches consumed so much CPU in the first place, it helps to look at what happens during a Git fetch.
|
||||
|
||||
## [Why a Git fetch is expensive](https://www.datadoghq.com#why-a-git-fetch-is-expensive)
|
||||
|
||||
To understand why our design works, it helps to understand how Git stores data and where a `git fetch` spends its time.
|
||||
|
||||
### [Git data types](https://www.datadoghq.com#git-data-types)
|
||||
|
||||
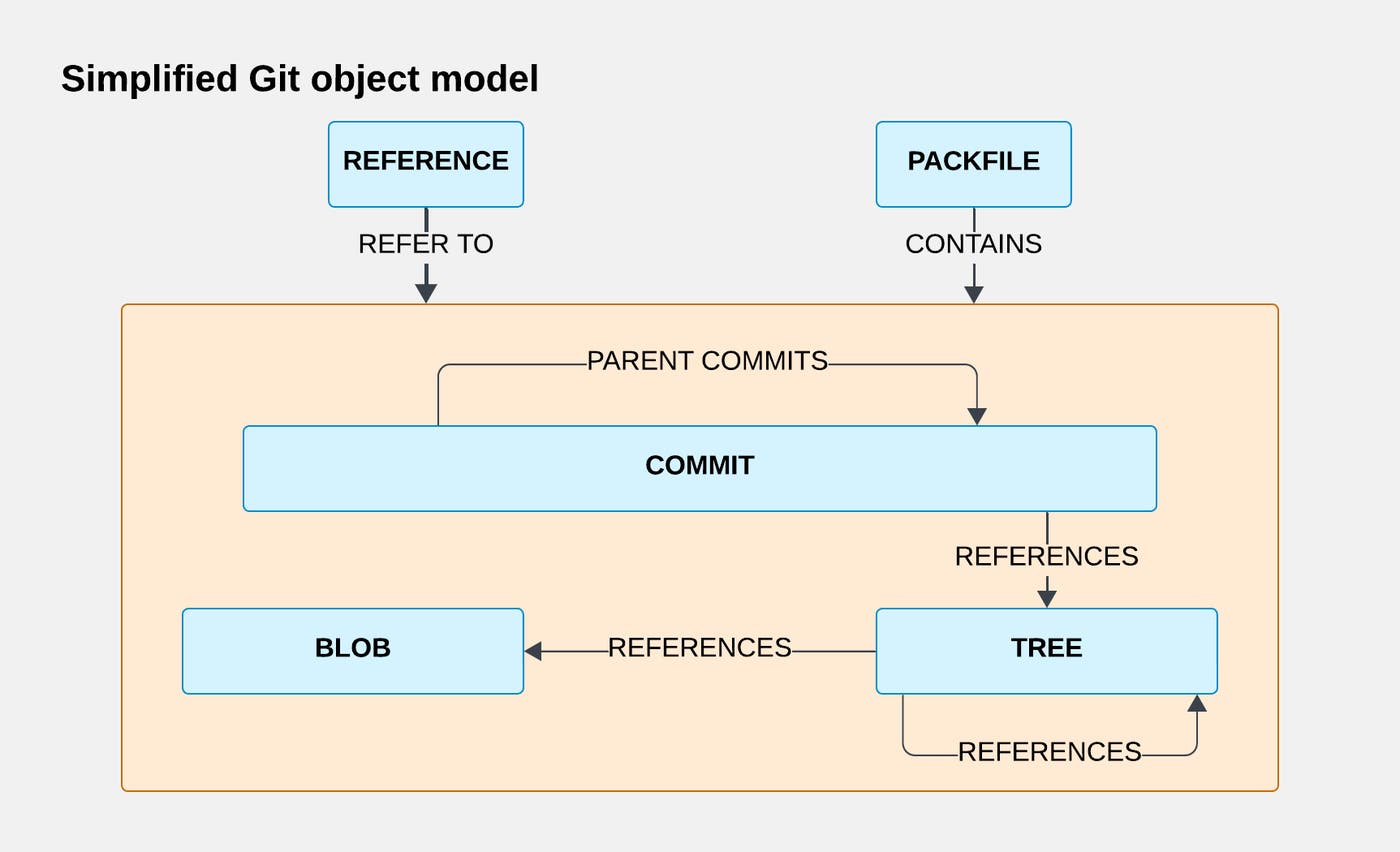
Git’s object database is primarily built around immutable objects. For the purposes of this post, we’ll focus on three:
|
||||
|
||||
- **Blobs** , which store file contents
|
||||
- **Trees** , which describe directory entries (for example, folders and blobs)
|
||||
- **Commits** , which store metadata, a commit message, a reference to a tree, and references to parent commits
|
||||
|
||||
Each object is identified by a hash of its type, size, and contents. SHA-1 remains the default object format, although Git also supports SHA-256 repositories.
|
||||
|
||||
Finally, there are **references**, which are mutable names stored separately from objects. For example, `refs/heads/main` identifies the commit at the tip of the `main` branch.
|
||||
|
||||
Objects may be stored on disk individually as **loose objects** or grouped into **packfiles**. Within a packfile, an object may be stored in full or as a delta against another object (known as **delta** **compression**), which allows Git to efficiently store the complete history of changes to files within a repository. Packfiles are immutable to allow for safe concurrent reads.
|
||||
|
||||
|
||||
|
||||
Write operations (for example, `git push`) may introduce new packfiles. A background maintenance process periodically consolidates loose objects and smaller packfiles into new packfiles. Unreachable objects (for example, deleted files) are eventually removed after a certain threshold by being omitted during packfile consolidation.
|
||||
|
||||
### [Git protocol v2](https://www.datadoghq.com#git-protocol-v2)
|
||||
|
||||
Now that we understand Git’s data types, we can briefly look at how the current (v2) Git protocol works.
|
||||
|
||||
The Git client uses the `ls-refs` command to learn the current object IDs of references it cares about (for example, all branches). The client and server then begin a multi-round negotiation to determine which objects the server needs to send to the client. You can read more about this negotiation process in the [Git protocol v2 documentation](https://git-scm.com/docs/gitprotocol-v2).
|
||||
|
||||
Once the client and server have determined which objects to send, the server creates a packfile containing those objects and sends it to the client.
|
||||
|
||||
Constructing the response packfile can be CPU and I/O-intensive. The server locates objects within packfiles by using an index that Git maintains for each packfile. Some objects can be copied as is into the response packfile, while others must be decompressed and recompressed using delta compression. Under a sufficiently large number of concurrent fetches, this packfile construction work can saturate server CPU and storage capacity.
|
||||
|
||||
Client behavior, such as requesting weeks’ worth of changes to a large monorepo, can make this more expensive in both CPU and I/O operations. Git attempts to reduce this cost with reachability bitmaps, sparse traversal, multi-pack indexes, and pack reuse. We tried all of these options, but client behavior and the rate at which our monorepos changed still concentrated CPU load on a small number of servers.
|
||||
|
||||
The final step of a fetch or pull from a Git server is for the client to read the received packfile and update its local index of available objects. This requires only a small amount of client-side CPU.
|
||||
|
||||
## [Our approach: Many independent mirrors, kept fresh](https://www.datadoghq.com#our-approach-many-independent-mirrors-kept-fresh)
|
||||
|
||||
If the problem is CPU concentrated on a few contended nodes, the solution is to stop concentrating it.
|
||||
|
||||
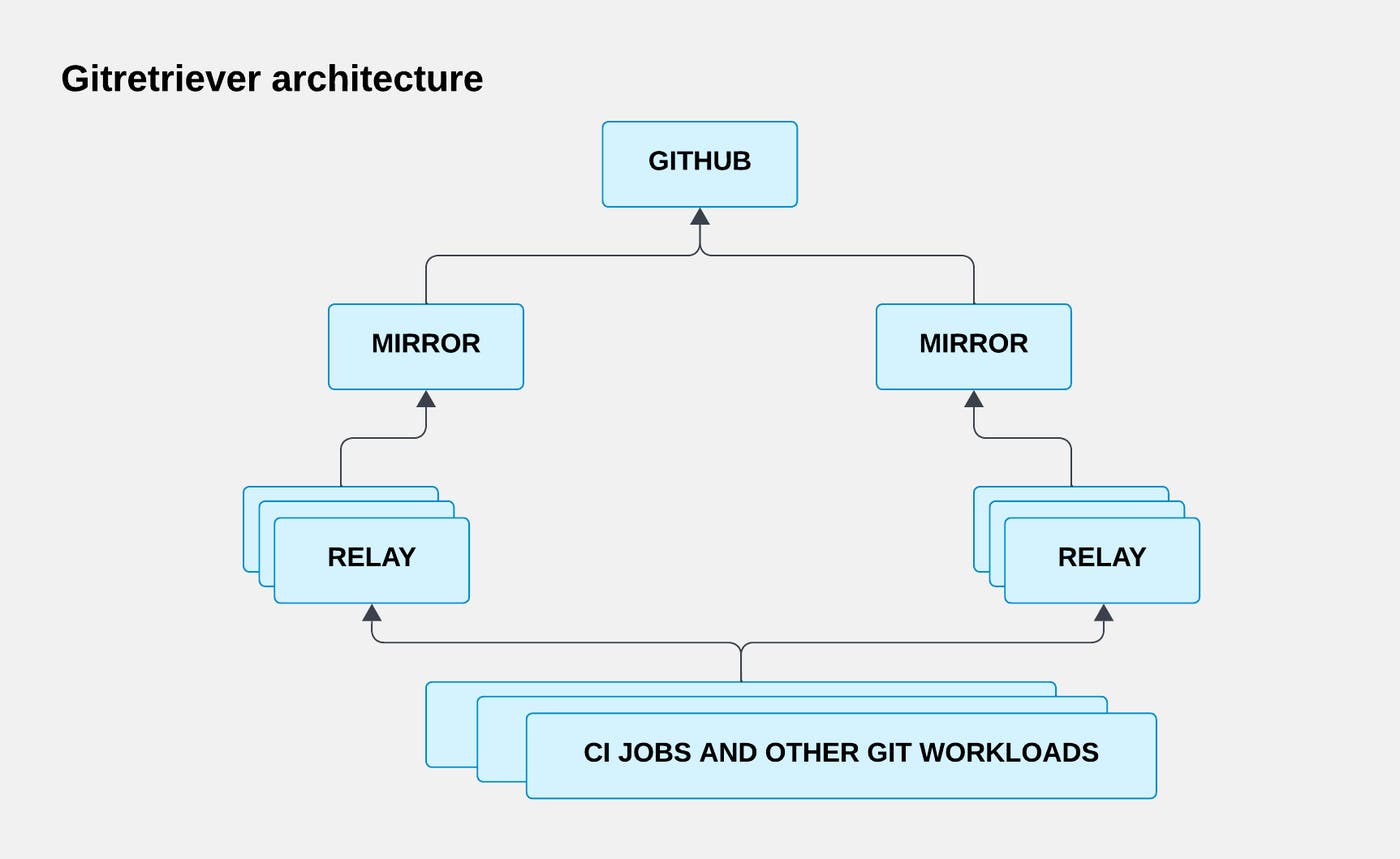
Gitretriever runs independent pods, each of which maintains a fresh local copy of the repositories it serves without waiting for every node to reach consistency. Each pod serves its local copy directly, with no consensus and no multi-writer replication between peers. Gitretriever pods have two roles, as shown in the following diagram:
|
||||
|
||||
- **Mirrors** stay in sync with GitHub. We deliberately keep this fleet small because its job is to be a good GitHub client: a handful of well-behaved pollers rather than thousands of them.
|
||||
- **Relays** fan out reads to CI jobs. This fleet is larger and autoscaled based on CPU and network load, allowing us to provision enough read capacity to meet demand without turning that growth into additional load on GitHub.
|
||||
|
||||
|
||||
|
||||
## [**Staying fresh and reducing CPU usage**](https://www.datadoghq.com#staying-fresh-and-reducing-cpu-usage)
|
||||
|
||||
**Staying fresh and reducing CPU usage**
|
||||
|
||||
The architecture works only if every mirror and relay stays close to the latest changes without recreating the CPU bottlenecks we were trying to eliminate. We designed gitretriever around three principles that keep repositories fresh while minimizing repeated work.
|
||||
|
||||
### [Distribute Git pulls across branches](https://www.datadoghq.com#distribute-git-pulls-across-branches)
|
||||
|
||||
Gitretriever mirrors continually poll the upstream in a tight loop for changes. Gitretriever performs a parallel fetch for each reference it detects as changed since the previous synchronization loop iteration. No single request concentrates an expensive delta compression job on GitHub, and each small pack requires far less indexing CPU than one monolithic monorepo pack. Staying close to the tip of each branch also means that, in any given synchronization loop iteration, only a small number of branches have changed, reducing the number of packfiles we need to fetch.
|
||||
|
||||
### [Spend the sync work once, then reuse it](https://www.datadoghq.com#spend-the-sync-work-once-then-reuse-it)
|
||||
|
||||
For the busiest repositories, one mirror cannot serve every client, so changes fan out to a fleet of relays. Relays can connect to mirrors or to other relays. Each relay splits its upstream connection into two channels:
|
||||
|
||||
- **A signaling gRPC stream** : Announces that a pack is ready, propagates reference updates, and communicates mirror and relay topology changes
|
||||
- **A plain HTTP endpoint** : Serves the pack bytes themselves
|
||||
|
||||
Because Git objects are content-addressed, a relay installs the packfile it receives from its upstream mirror or relay without regenerating, re-indexing, or re-verifying it. It drops the packfile and its index into place, trusting the objects inside by the hashes that identify them. The work of pulling and indexing from GitHub happens once on the mirror, and every relay reuses that work instead of fetching again. As a result, the relay fleet can grow without adding load on GitHub while remaining within single-digit milliseconds of the tip.
|
||||
|
||||
### [Never build the same pack twice](https://www.datadoghq.com#never-build-the-same-pack-twice)
|
||||
|
||||
Gitretriever is both a Git client and a Git server. The current implementation uses Git’s default backend storage format: packfiles, reference tables, reachability bitmaps, and multi-pack indexes. That means gitretriever has to make serving other Git clients (such as CI jobs) as efficient as possible.
|
||||
|
||||
A fresh push to a busy branch sets off a thundering herd of identical fetches. Gitretriever implements a **pack cache**, allowing it to reuse previously assembled packfiles for identical client requests. About half of all pack-building fetches are served directly from the cache, skipping the delta compression calculation on mirrors and relays entirely. Cache misses are still served locally by the mirrors and relays, so even a cache miss never becomes a trip to GitHub.
|
||||
|
||||
Underneath these are smaller refinements, including a readiness check that understands Git state and keeps a pod out of rotation until its pack count is healthy, along with background repacking that keeps the packfile count under control while the pod continues serving. But the theme never changes: Take the CPU that used to pile up in one place and either spread it out or stop repeating it.
|
||||
|
||||
Future iterations of gitretriever will build on the relay replication protocol to keep an always-up-to-date copy of our large repositories directly on CI nodes, allowing jobs to skip the initial `git clone` altogether.
|
||||
|
||||
## [The bigger surprise: Many use cases don’t need a clone](https://www.datadoghq.com#the-bigger-surprise-many-use-cases-dont-need-a-clone)
|
||||
|
||||
Once every repository had a fresh mirror, something in the traffic caught our eye: Most non-CI workloads don’t need a full repository clone. They wanted a single file at a commit, the SHA a branch pointed to, the list of files that changed, or the merge base of two refs. Cloning an entire repository to answer one of those questions was enormous overkill, yet our internal services, developer tools, and AI agents were doing it constantly.
|
||||
|
||||
So we added a small, read-only HTTP API for exactly those queries. Resolving a ref or reading a file takes single-digit to tens of milliseconds. By comparison, a shallow clone of a large monorepo takes on the order of 75 seconds and keeps a CPU core busy for most of that time. Moving these use cases to the API reduces latency and removes load from the entire system.
|
||||
|
||||
The non-CI workloads changed how we think about gitretriever. It’s less a faster Git server and more the query layer for Git across our engineering systems.
|
||||
|
||||
This is the direction the platform is heading. As workflows become more automated and more AI agents ask questions about code, the cheapest and fastest answer is often another API rather than handing out a repository clone.
|
||||
|
||||
## [Rolling out gitretriever safely](https://www.datadoghq.com#rolling-out-gitretriever-safely)
|
||||
|
||||
Rolling out gitretriever required careful planning. Our CI infrastructure is used by every engineer at Datadog, so one wrong move could bring engineering to a halt. We used feature flags and built in automatic fallback to the old backend into our CI jobs, so if a mirror became unreachable or a fetch failed, the job fell back to the previous path. The worst-case outcome was no worse than before. We then migrated one repository group at a time, starting with the largest monorepo, while watching the old backend’s CPU graph.
|
||||
|
||||
When that first monorepo cut over, we saw an immediate step decrease in CPU usage. That confirmed our understanding of the problem: Gitretriever was absorbing the heaviest, most CPU-dense fetches first. Those were the same ones that had been degrading developer experience and driving outages.
|
||||
|
||||
The metrics matched our expectations:
|
||||
|
||||
- **Synchronization time dropped from several seconds to a few hundred milliseconds** , making continuous, coordination-free mirroring possible.
|
||||
- To date, gitretriever has served **more than a billion Git requests and hundreds of terabytes of data** across roughly**5,500 repositories** , and now handles**more than 100 million requests each week** .
|
||||
- **Traffic grew about 20× in 4 months while median serve latency remained around 40 ms** (Figure 3). The system became an order of magnitude busier without getting materially slower.
|
||||
- The result we care about most: Moving CI fetch traffic to gitretriever **reduced the old backend’s fetch-serving CPU by three to four times, even as overall CI activity kept climbing** (Figure 4). Its memory footprint dropped in step, which later let us right-size that backend down. The old backend still handles some use cases that gitretriever**doesn’t** yet support (e.g., rendering the GitLab UI), so we**don’t** claim we replaced it (yet). But the fetch-path load it had been drowning under is gone.
|
||||
|
||||
|
||||
|
||||
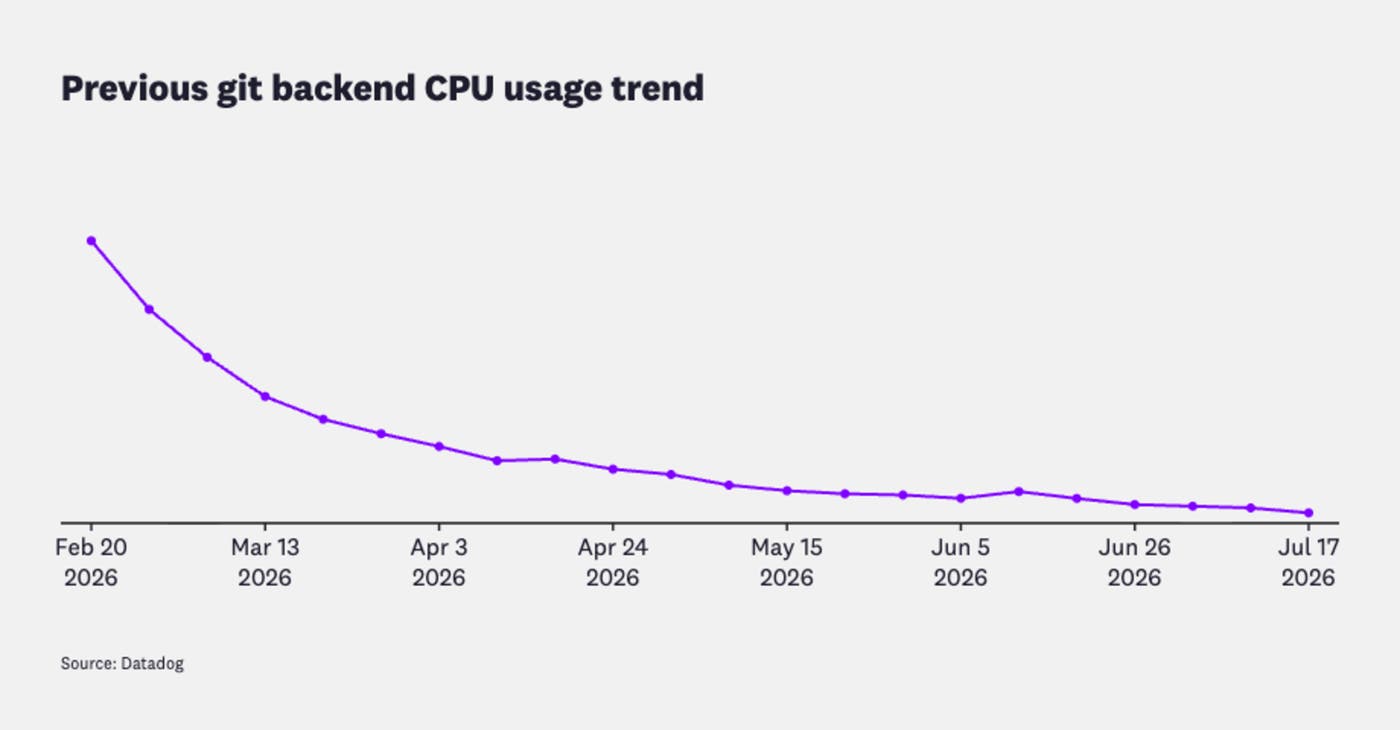
|
||||
|
||||
## [How we built it: Two engineers, Claude Code, and design doc in nearly every folder](https://www.datadoghq.com#how-we-built-it-two-engineers-claude-code-and-design-doc-in-nearly-every-folder)
|
||||
|
||||
We chose to use Claude Code on this project to accelerate development and to explore how far AI could responsibly assist with building production infrastructure. What made an AI collaborator trustworthy on a system this central wasn’t the model; it was the discipline around how we used it.
|
||||
|
||||
We planned before we wrote code, designing each change and iterating on the design through several rounds before committing a line of code. We validated every change with integration tests backed by real metrics and logs, not just unit tests, so the bar for “done” was observed behavior rather than a green checkmark. To keep both the AI and ourselves aligned across a dozen packages, we maintained a living design document in nearly every directory, describing its architecture, data flow, concurrency model, and configuration, and updating it alongside the code.
|
||||
|
||||
Those documents ended up serving two purposes. During development, they kept AI-generated changes aligned with the architecture. When ownership of the service transitioned to the team that now maintains it, the same documents became the handoff.
|
||||
|
||||
The lesson we would pass on is that the design documents became the interface between the engineers, the AI, and the next team. Ultimately, the quality of your tests and telemetry data sets the ceiling on how far you can trust an AI collaborator.
|
||||
|
||||
## [What’s next](https://www.datadoghq.com#whats-next)
|
||||
|
||||
Gitretriever is not finished. We’re expanding the query API so more workloads can skip cloning entirely, allowing us to fully decommission our old Git backend. We’re also continuing the rollout across the rest of our repositories and building for a future where automated and agent-driven workflows ask even more of Git.
|
||||
|
||||
A few ideas we’ll carry into whatever comes next:
|
||||
|
||||
- **Make it disposable so you do not have to make it durable.** Some of the hardest parts became much simpler once we made them rebuildable instead of authoritative.
|
||||
- **Content addressing lets you trust data by name.** That’s what makes coordination-free replication safe.
|
||||
- **The fastest fetch is the one that transfers nothing** , whether that’s a fast-path ref update or an API call that answers the real question without a clone.
|
||||
|
||||
More than any single optimization, gitretriever reflects how we approach engineering at Datadog: Push a good system as far as it will go, then, when the scale curve demands it, design the next generation from a better understanding of the problem, validate it against real telemetry data, and write down what you learned so the next team can build on it.
|
||||
|
||||
If this sounds like your kind of problem, we would love to work with you. Take a look at our [open roles](https://careers.datadoghq.com/all-jobs/?s=Infrastructure&child_department_Engineering%5B0%5D=Backend).
|
||||
|
||||
@@ -7,3 +7,7 @@
|
||||
## 简介
|
||||
|
||||
Switching from their custom-written autoscaler to the new off-the-shelf option made sense, but it wasn’t a simple drop-in replacement.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
|
||||
@@ -7,3 +7,89 @@
|
||||
## 简介
|
||||
|
||||
Can we replace human code review with LLM-based reviews? This article lays out what an LLM can’t replicate, and I’d argue that these are the pieces that matter most for reliability.
|
||||
|
||||
## 正文
|
||||
|
||||
The abstract for article “[The End of Code Review: Coding Agents Supersede Human Inspection](https://arxiv.org/abs/2606.13175)” paints this picture for the reader…
|
||||
|
||||
**Abstract** – Code review has been the primary quality gate in software development since Fagan formalised code inspection in 1976. For five decades, having a human examine and comment on a colleague’s changes before merge has been a cornerstone practice at organisations of every size. Coding agents are large language model (LLM)-based autonomous systems capable of reading, writing, testing, and repairing software. We argue that coding agents have crossed a threshold of capability at which traditional human code review is no longer a necessary component of a software quality pipeline. Our argument rests on two claims: every stated goal of code review can be served by agents at lower cost and higher throughput; the naive integration in which agents write code and humans remain the mandatory reviewers is a dead end because it neither provides meaningful assurance nor scales with AI-assisted throughput.
|
||||
|
||||
|
||||
The article is structured well and quite straightforward for engineers who aren’t used to reading research articles very often. However, I do think the argument critically depends on a problematic framing: ***the substitution myth***.
|
||||
|
||||
The author decomposes peer code review into four stated functions: defect detection, style enforcement, knowledge transfer, and awareness. It argues an agent can perform each one. The conclusion, of course, is that if an agent can execute each of those functions, then the agent has the capability to replace a human reviewer.
|
||||
|
||||
I think this overlooks some important aspects of peer code review that *cannot* be reduced to a function:
|
||||
|
||||
**A peer reviewer’s confusion**
|
||||
|
||||
When an experienced engineer reads a diff and says “I don’t understand this.”, their confusion *is* the finding. It means the code is either too complex, the abstraction is wrong, or the intent is not clear. An LLM will always ‘understand’ the code in the sense of being able to *process* it. It can’t give you the signal of legitimate human incomprehension. The article treats comprehensibility as something that is more about style than anything else. It’s not. It’s an emergent property and it shows up in the interaction between a person attempting to understand the artifact and the artifact itself.
|
||||
|
||||
**Qualified skepticism about whether the change is even necessary**
|
||||
|
||||
Questioning the existence of a change, like:
|
||||
|
||||
“Should this actually be *two* PRs?”
|
||||
|
||||
|
||||
or
|
||||
|
||||
“This solves the symptom, not the problem”
|
||||
|
||||
|
||||
These are questions about intent, scope, and appropriateness of the change. All of that comes *before* whether the code is “correct.” The article’s framing assumes that a) the code change being reviewed is necessary, and b) the main purpose of the review is verification.
|
||||
|
||||
But anybody who has ever had contact with production understands that code review is *often the last* (or sometimes only) moment when someone can be expected to challenge whether the change is even necessary.
|
||||
|
||||
**The ability to see what is *not* there**
|
||||
|
||||
A human reviewer can notice that an API contract has changed but the error handling didn’t. They can notice what is *missing*. In other words: being able to recognize what is *expected* to be present, but isn’t. The article doesn’t acknowledge this at all, which is particularly interesting, given that [absence blindness](https://absencebench.github.io/) is exactly the class of failure that LLMs tend to be quite poor at.
|
||||
|
||||
The agent reviews what is there; engineers with expertise can easily notice what’s missing.
|
||||
|
||||
*Who* wrote the code influences the scrutiny of the review
|
||||
|
||||
Peer code reviewers have a sort of *calibrated attention* that comes from past experience with the code’s author, who is often a colleague. For example: a less-tenured engineer’s first commit to, say, a payments module will likely get different attention than a veteran and ‘grey beard’ engineer’s routine refactoring.
|
||||
|
||||
Reviewers typically match the situation’s who, what, when, and where to their own experience of where risk lies.
|
||||
|
||||
The article seems to treat all diffs as equivalent inputs.
|
||||
|
||||
**Code review is bidirectional and constructive**
|
||||
|
||||
It seems to me that paper reduces knowledge transfer down to just information delivery; the agent simply ‘generates explanations.’ But discussion in a code review is a *joint* *cognitive activity*. The peer reviewer learns about the author’s approach, the author learns via the reviewers’ questions, and the result is a shared understanding that neither party had prior to the discussion.
|
||||
|
||||
This is **coactive** work, not simply a transmission. An agent’s summary isn’t a substitute for a conversation that changes both participants’ mental models.
|
||||
|
||||
**Operational context that lives outside repos**
|
||||
|
||||
“We just had an incident in this service last Tuesday.”
|
||||
|
||||
“The team that owns this downstream consumer is about to deprecate that interface.”
|
||||
|
||||
“Legal told us not to log this field anymore.”
|
||||
|
||||
|
||||
Human reviewers possess so much more contextual knowledge than they’re aware of, even though they can recognize connections in the wild. People understand the current state of the organization, recent events, and informal agreements that aren’t captured in tests, docs or version control, and they can recognize how these may influence the code under review. This happens so often that it’s all but invisible.
|
||||
|
||||
The article assumes the codebase *is* the complete context. It never is.
|
||||
|
||||
**Accountability for the code isn’t just a beuraucratic formality**
|
||||
|
||||
The article treats human responsibility as a compliance artifact, a “named human” for legal or other rule-related purposes. But being aware that you are personally responsible for approving a change shapes how you review it. It is the “skin in the game.” An agent that “signs off” on a pull request bears no consequences and certainly has no incentive structure that fuels an earnest evaluation. While the paper does include ethics concerns in its discussion section, it ends up redirecting it to “requirements engineering and post-deployment monitoring” which seems to me as hand-waving way of kicking the can down the road.
|
||||
|
||||
The most fundamental issue I have with the article is that it assumes code review is a first and foremost a **detection** process: you find defects, style violations, security issues, etc., and the assumption is that detecting these faster and cheaper is universally better.
|
||||
|
||||
But code review is also a *coordination* process, a *sensemaking* process, and a *governance* process.
|
||||
|
||||
The ***substitution myth*** often plays out in this same way:
|
||||
|
||||
1. First, decompose the human contribution of work into measurable functions.
|
||||
2. Show that the machine can replicate this human contribution into measurable functions of its own.
|
||||
3. Declare the human redundant.
|
||||
|
||||
This approach often falls apart at the same point: the human contribution that mattered most was the *integration* across functions. People’s ability to adapt to unplanned circumstances and contexts and serve the social accountability expected.
|
||||
|
||||
This ability to adapt in those situations aren’t accounted for in the original decomposition step #1, above.
|
||||
|
||||
I don’t think they were accounted for in the original article, either.
|
||||
|
||||
Reference in New Issue
Block a user