diff --git a/sreweekly/articles/536/01-omnipresent-availability-risks-in-cloud-software.html b/sreweekly/articles/536/01-omnipresent-availability-risks-in-cloud-software.html new file mode 100644 index 00000000..c276176f --- /dev/null +++ b/sreweekly/articles/536/01-omnipresent-availability-risks-in-cloud-software.html @@ -0,0 +1,1253 @@ + + + + + + + +Omnipresent availability risks in cloud software – Surfing Complexity + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+ + +
+ +
+ + + + +
+
+ +
+
+ + + +
+
+

Omnipresent availability risks in cloud software

+ +
+ +

I’m using this post to gather together some common threads I’ve noticed after reading write-ups of major cloud software incidents. By cloud software, I’m referring to software-as-a-service (do people even say that anymore? in the cloud. This doesn’t just apply to cloud providers, although it does apply to them as well.

+ + + +

Here’s an outline of the topics in this post:

+ + + +
    +
  • problem areas +
      +
    • saturation +
        +
      • example: databases
      • +
      +
    • + + + +
    • networking (traffic routing failure) +
        +
      • example: DNS
      • +
      +
    • + + + +
    • security (deny valid access) +
        +
      • example: SSL certificates
      • +
      +
    • +
    +
  • + + + +
  • essential non-standard changes +
      +
    • mitigating an operational issue
    • + + + +
    • migration
    • +
    +
  • + + + +
  • essential increase in essential complexity +
      +
    • reliability subsystem
    • + + + +
    • migration
    • +
    +
  • +
+ + + +

I think of all of these as omnipresent availability risks: I think these are fundamentally unavoidable, and will be contributing to software incidents until the end of time; or, at the very least, until the end of my own career in software.

+ + + +

There are three general areas that most major incidents seem to fall into: saturation, networking, and security. So, let’s start with those.

+ + + +

Saturation

+ + + +

Saturation is probably the topic I talk about most frequently, both on this blog and elsewhere (e.g.,: the saturation post I wrote for the Resilience in Software Foundation and my saturation talk at the Software Should Work conference). The system becomes saturated when it reaches a limit. That’s a pretty generic description, but there are many limits!

+ + + +

Databases

+ + + +

Many major incidents involve some system component becoming saturated in one form or another. I personally worry about database saturation the most. That’s because it’s difficult to recover from an overloaded production database. In addition, because database systems are such complex beasts, it can be quite difficult to even determine what the specific performance issue actually is. This is why having in-house database operational expertise is critical.

+ + + +

Saturation is an omnipresent risk because the finite nature of resources is a hard constraint in the world that we live in. Eventually, some resource in your system is going to run out.

+ + + +

Example: GitHub Incident, Aug 26, 2026

+ + + +

Networking

+ + + +

While I prattle on endlessly about saturation, not every major incident involves saturation. You can encounter scenarios where all of your internal subsystems are reporting healthy, but from your customer’s point of view, your site is down: they can’t use it. One way this can happen is if your users can’t even reach your site, and that’s where the networking problem area comes in.

+ + + +

A networking problem can lead to packets being misrouted. These requests might be black-holed (i.e., silently dropped), or they might be incorrectly routed to a service that doesn’t have the capacity to respond to all of these requests, in which case you’ve got both a network routing issue and a saturation issue.

+ + + +
A visual depiction of an actual black hole. Image source: NASA
+ + + +

DNS

+ + + +

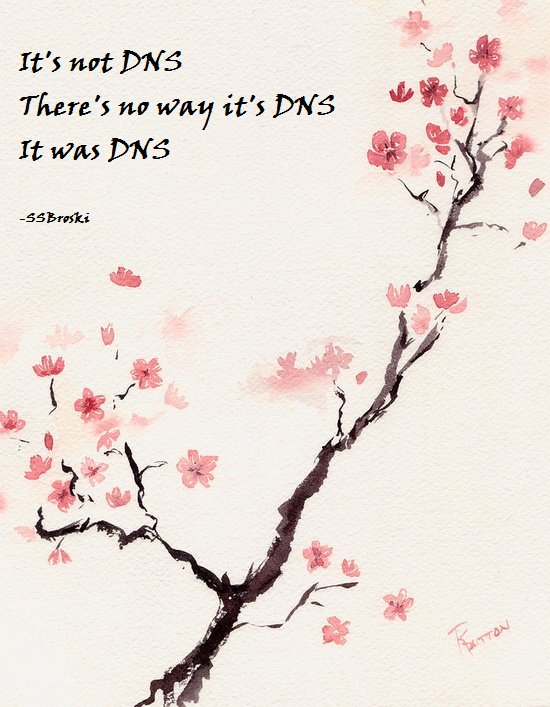
DNS issues are an example of this kind of network-related failure mode. There’s no way those packets are going to make it to their destination if the client can’t even determine which IP address to send them to. And when DNS breaks, that’s what happens.

+ + + +

I bring DNS up because it’s bitten folks enough times that there’s a famous haiku:

+ + + +
+ + + +

More generally, networking is an omnipresent risk because cloud software is inherently distributed, so networking is always a critical service. Now, I don’t work in networking, but from the outside, networking just feels like a dangerous domain to do operational stuff in. The blast radius of a networking issue can be very large. And, because network behavior is inherently distributed, reasoning about the behavior of operational changes is just inherently difficult. Honestly, that’s probably why I don’t work in networking.

+ + + +

And, so, I predict we’ll continue to see networking issues contribute to large-scale incidents.

+ + + +

Example: Buildkite incident, Aug 25, 2026

+ + + +

Security

+ + + +

There’s a fundamental tradeoff between availability and security: availability is about ensuring that the good people can access the system. Security is about ensuring that the bad people cannot access the system. This means that there’s always a risk that a security system designed to prevent bad actors from accessing the system can lead to good actors also being blocked. Consider this scenario: there’s an internal security subsystem that goes unhealthy (possibly due to saturation). Is your policy to fail closed or fail open in the event that this subsystem is erroring? Answering that requires making an availability-security tradeoff.

+ + + +

SSL certificate expiration

+ + + +

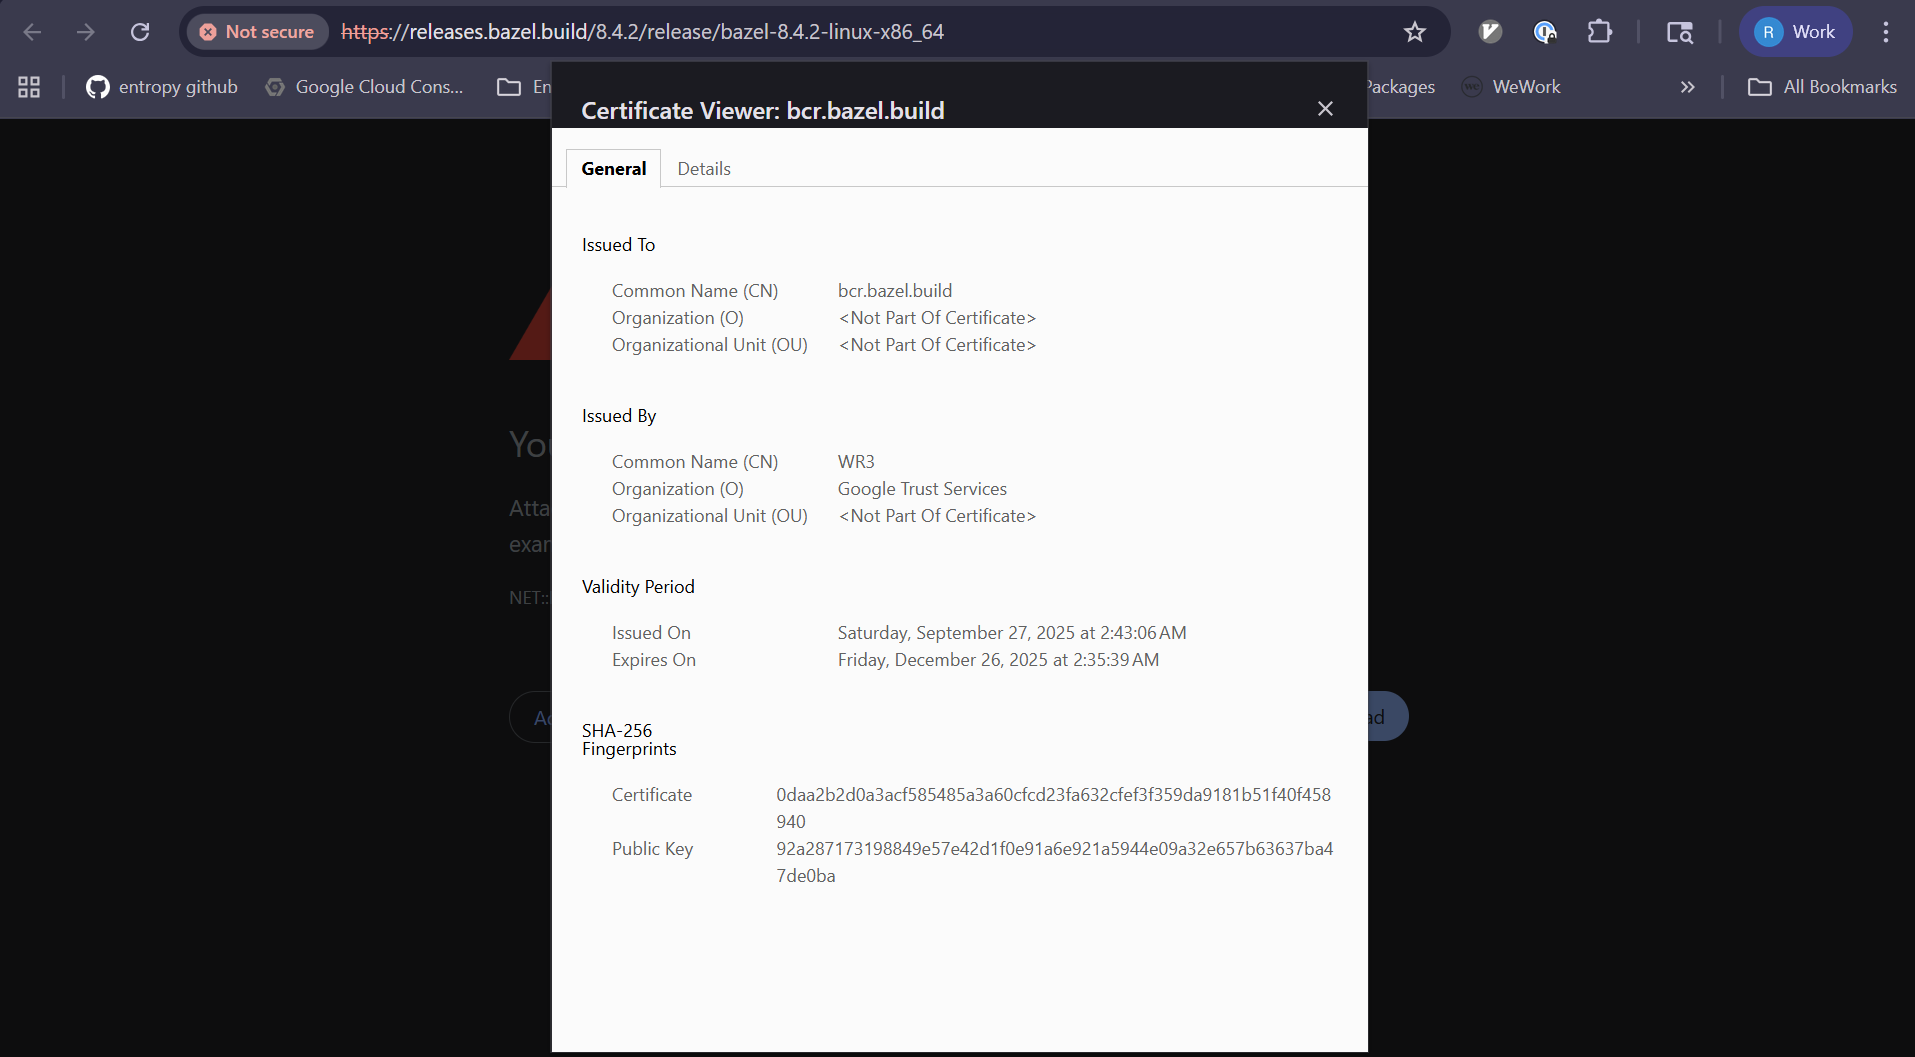
Another example of this failure mode, which keeps biting our industry again and again, is SSL certificate expiration. Here you have the behavior of a security system that is preventing legitimate access because the cert wasn’t renewed.

+ + + +
Bazel expired certificate
Even the mighty Google encounters SSL certificate expirations. This is from the Bazel incident
+ + + +

And so, my claim is availability incidents that involve security subsystems will continue to be a thing forever.

+ + + +

Example: Bazel incident, Sep 27, 2025

+ + + +

Essential uncommon changes

+ + + +

Your system is constantly undergoing change. Heck, if you stopped making changes, the system would eventually stop working properly. Now, there are some changes that your org does very frequently. Hopefully, you’re deploying often, flipping feature flags a lot, and so on. But there are other changes that your org has less experience with, because they happen much less often. That means that there hasn’t been as much investment in tooling to support these sorts of changes, and it means that the people making these changes don’t have the same level of expertise as they do with the more common changes. That makes these sorts of changes more dangerous: less mature tooling and less experienced humans.

+ + + +

Mitigating an operational issue

+ + + +

A few years ago, I wrote a post titled a conjecture on why reliable systems fail where I speculated on two common contributors to major incidents. One of those contributors was a manual intervention that was intended to mitigate a minor incident. Now, it may be that you frequently have to do manual interventions to mitigate system issues, in which case you’ll have a lot of experience with those sorts of interventions. But you’ll also be more motivated to put in the engineering effort to automate away those sorts of common issues.

+ + + +

It’s exactly the uncommon issues that require a human operator to intervene to mitigate that are dangerous, because they are uncommon. But they’re essential: there’s a problem in the system, and you need to fix it! But because all practitioner actions are gambles, the manual mitigation carries risk that you could make the problem even worse. And, eventually, this will happen to you.

+ + + +

Example: Azure Regional Outage, Jul 23, 2026

+ + + +

Migration

+ + + +

If you’re at a tech company, unless it’s a start-up, you’ll be dealing with migrations, as old tech gets replaced by newer tech that is better suited to the problems that your org is currently facing. While migrations as a general category are extremely common, each migration is itself a snowflake. This means that the specific details of the migration work is an uncommon change. The work of migration involves making a kind of change to your system that you haven’t made before.

+ + + +

To make things worse, one of the dangers of migration is that, as you go along, you start to build confidence that your changes are safe, but there are actually hidden dangers lurking in the system for the next migration. The confidence in the safety of the work exceeds the actual safety. I mean, you made n-1 changes as part of the migration, and none of those changes had negative consequences. It’s natural to assume that the same outcome will occur with the nth change.

+ + + +

Example: Rogers Network outage, Jul 8, 2022

+ + + +

Essential increase in essential complexity

+ + + +

The late American computer scientist Fred Brooks wrote a famous software engineering essay titled No Silver Bullet where he drew a distinction between accidental complexity and essential complexity. The general idea was that there was some amount of complexity in a software system that didn’t need to be there (accidental complexity) and some amount that was just inherent to the nature of the problem space and solution space and so could not be removed (essential complexity).

+ + + +

Reliability subsystem

+ + + +

We’ve developed multiple techniques to improve the reliability of software systems, including retries, concurrency limiting, autoscaling, automated failover, circuit breakers, health checks, canaries, outlier detection, the list goes on and on. There’s one thing that all of these techniques have in common: they increase the complexity of the overall system! And they do this because they have to increase complexity in order to do their job. This is a consequence of Ashby’s Law, which states that if you want to build a control system that handles more scenarios, you have to increase the complexity of the controller itself.

+ + + +

This means that reliability subsystems result in a complexity trade-off. On the one hand, our system can now automatically recover from failure modes that previously required manual intervention. On the other hand, as we all know, increase in complexity is itself dangerous because it can introduce entirely new failure modes that weren’t there before.

+ + + +

Going back to my conjecture blog post, the second contributor I posited was: unexpected behavior of a subsystem whose primary purpose was to improve reliability. And this is exactly why. Adding reliability subsystems improves the robustness of our system, but it adds essential complexity to our system, which can lead to novel incidents.

+ + + +

Example: OpenAI incident, Dec 11, 2024

+ + + +

Migration

+ + + +

Like all engineers, I’m a big fan of giving the answer “it depends” if somebody asks me a question about whether they should do X or Y. However, if someone came up to me and said, “Lorin, I’m preparing to do a migration at my company, and I’m trying to decide whether to do a big-bang migration or an incremental one”, then I would almost certainly say, “For the love of God, please do an incremental migration!”. Sometimes big-bang migrations are unavoidable, but when given a choice, I’m going to go for the incremental migration as the safer option.

+ + + +

However, when you do an incremental migration, it means that you need to simultaneously support the old system and the new system at the same time while you’re doing the migration. This means that even if the new system yields a net decrease in overall complexity over the old system, while the migration is happening, you’re going to see an increase in system complexity. And that means that you’ll see incidents arise as a byproduct of this increased complexity.

+ + + +

Example: Cloudflare incident, Jul 14, 2025

+ + + +

Incidents are inevitable, so you’d better be ready

+ + + +

To reiterate, I think all of the risks mentioned here are omnipresent: they are fundamental to the nature of cloud software. I don’t think that any of these risks can be eliminated. That’s why I believe so strongly in the value of getting better at incident response. Because, if you prepare, you can get better at dealing with problems that arise as a result of these risks.

+
+ + + + +
+ + + + +
+ + + + +
+

Leave a comment

+ + +
+ + + +

+

+ +
+ + +
+
+ + + +
+ + +
+
+ + + + + + + + + +
+
+
+
+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + diff --git a/sreweekly/articles/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.html b/sreweekly/articles/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.html new file mode 100644 index 00000000..022b6b33 --- /dev/null +++ b/sreweekly/articles/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.html @@ -0,0 +1,498 @@ + Master Background Jobs With Smarter Queue Architecture and Reliability - Techgenyz
+September 18, 2026
+8:30 AM IST
+ +
+ +
+ +
+ +
+ +

Disclaimer: We may earn a commission if you make any purchase by clicking our links. Please see our detailed guide here.

Follow us on:
+ +

Master Background Jobs With Smarter Queue Architecture and Reliability

+Background jobs

Highlights

  • Background jobs move slow or resource-heavy tasks away from the main request-response cycle, improving application speed and reliability.
  • Queue-based systems use producers, queues, and workers to process tasks independently from the main application.
  • Idempotency is essential because distributed systems can execute the same job more than once.
  • Retry strategies with exponential backoff, jitter, and dead-letter queues help manage failed jobs safely.

+Table of Contents

+

Every backend application, at some point, has a task that takes too long to run inside the request-response cycle. Sending a welcome email, generating a PDF report, resizing an uploaded image, reconciling a payment, syncing data to a third-party service, these operations are too slow to block the user on, too important to drop if they fail, and too variable in duration to handle predictably inside a web server process that is optimized for fast, stateless responses.

Background jobs solve several critical problems in modern systems. By moving expensive operations into the background, applications respond almost instantly, creating smoother and faster user experiences. Heavy workloads can overwhelm web servers if handled synchronously, since background workers distribute these workloads more efficiently across multiple machines or containers. As traffic grows, developers can simply add more workers instead of scaling the entire application. If a worker fails, the job can be retried automatically.

Understanding how background job systems work (and, more importantly, how they fail) is a core backend engineering skill in 2026. The concepts are not complex, but the implementation gaps that produce double-charged payments, silently dropped emails, and unrecoverable job failures are almost always traceable to the same small set of design decisions made without a complete picture of how queue-based systems behave under real conditions.

The Core Architecture: Producers, Queues, and Workers

The core idea behind background task processing is to decouple the initiation of a task from its execution. This is achieved through a message broker acting as a queue, where tasks are published by the main application and consumed by workers. A queue is a data structure that holds tasks awaiting execution, since tasks are typically added by the main application process and picked up by worker processes. Workers operate independently from the main application, allowing for parallel processing and preventing blocking. A scheduler is a component responsible for executing tasks at predefined times or intervals.

ai-assisted coding tools, SQL injection
Image Source: freepik

The request lifecycle in a background-job-enabled system looks like this: a user action triggers a web request, the web server validates the request, records the intent, and pushes a job description into the queue, then returns a response to the user immediately. A separate worker process, running independently of the web server, pulls the job from the queue, executes the actual work, and records the result. The user receives their response in milliseconds.

This architecture produces three important properties. The web server’s response time is decoupled from the duration of the background work, a job that takes three minutes does not make the user wait three minutes. The work is durable: even if the server that received the original request restarts, the job description persists in the queue and will be processed by a worker. And the system scales horizontally: when job volume increases, additional worker processes can be added without touching the web server layer.

In-process jobs, calling asynchronous logic from the API server using setImmediate, setTimeout, or internal promise chains, are the simplest approach to write but fragile in practice. When the server restarts, all in-flight jobs are lost with no record of what was pending. This is the failure mode that catches early-stage teams: the application appears to handle background work correctly in development and under normal conditions, but any process restart during a deployment, crash, or scale-down event silently drops every job that was queued in memory at that moment.

Common Use Cases and Why Each One Demands Background Processing

The use cases that belong in background job queues are consistent across application types, and the reason each one belongs there is specific to the properties of that work.

  • Email and notification delivery is the most universal background job. Sending email via an external SMTP service or API introduces network latency, rate limits, and occasional delivery failures that are unpredictable and outside the application’s control. A transactional email that fails because the email provider’s API was momentarily slow should be retried; it should not cause the user’s action to fail or make them wait. Queuing email delivery decouples the user action from the delivery outcome and enables automatic retry when the provider is briefly unavailable.
  • Report generation is the clearest case for background processing from a user experience perspective. A report that aggregates twelve months of data, joins multiple tables, and formats the result as a PDF may take thirty seconds or three minutes depending on data volume. No user should wait at an HTTP connection while that computation runs. The correct pattern is: the user requests the report, the server queues the generation job and returns a job ID, the user’s client polls a status endpoint or waits for a push notification, and the completed report is made available for download when the worker finishes.

The Asynchronous Request-Reply pattern: the caller receives a URL or resource identifier when it submits the job and polls that endpoint for status. Alternatively, the background task can publish an event when it completes, and the caller subscribes to those events, an approach suitable for cloud-native event routing through services like AWS EventBridge or Azure Event Grid.

  • Media processing (image resizing, video transcoding, thumbnail generation, PDF creation, format conversion) involves CPU-intensive or storage-intensive operations that are poorly suited to web server processes. Image processing and file generation are classic worker tasks. Resizing uploads, generating thumbnails, converting formats, creating PDFs, and extracting metadata all benefit from asynchronous processing. The user can upload a file and receive an immediate response while the worker performs the transformation in the background, improving user experience and isolating heavy storage or CPU operations from the API.
Market Research For Startups
Image credit: Freepik
  • Payment and financial reconciliation requires background processing with the strongest reliability guarantees of any use case.Payment-related tasks often belong in workers with strong safeguards. Capturing a payment, reconciling a transaction, generating an invoice or polling for settlement, because payment systems are sensitive to duplicates and partial failure, these jobs must be idempotent and carefully logged. A queue helps manage retries, but business logic must still prevent double charging or repeated side effects.

At-Least-Once Delivery and Why Idempotency Is Non-Negotiable

The property of queue-based systems that most confuses engineers unfamiliar with distributed systems is delivery guarantee. Most message queues, including Redis-backed systems, AWS SQS in its standard mode, and RabbitMQ, guarantee at-least-once delivery, meaning a message will be delivered to a consumer at least once, but may be delivered more than once under specific failure conditions (a worker crashes after processing a job but before acknowledging it, the acknowledgment packet is lost, the broker times out and redelivers).

Every distributed system runs on at-least-once delivery. Idempotency is the only safe response. The practical engineering approach is not to chase exactly-once at the broker level but to make consumers idempotent, so a duplicate delivery changes nothing. Systems like Temporal achieve exactly-once execution of orchestration logic by building on top of an at-least-once substrate.

An idempotent job is one where running it twice produces the same outcome as running it once. For email jobs, this means checking whether the email has already been sent using a database record or an idempotency key, before sending it, and returning successfully without sending again if it has. For payment capture jobs, this means passing the payment provider an idempotency key that deduplicate the charge on their end even if the request is retried. For report generation jobs, this means checking whether a report for the same parameters already exists before starting computation.

The idempotency key pattern, generating a unique, stable identifier for a job at enqueue time and passing it through to every operation the job performs, is the implementation pattern that makes at-least-once delivery safe in practice. The key is generated once from the job parameters and stored alongside the job; if the job runs again, every operation that checks the key finds the existing result and returns it without performing the side effect again.

Retry Logic: Exponential Backoff, Jitter, and Dead-Letter Queues

A job that fails needs a retry strategy, and the retry strategy is what determines whether a transient failure (a momentarily unavailable dependency) is handled gracefully or cascades into a sustained problem that overwhelms the dependency it is retrying against.

Exponential backoff is the standard retry timing strategy: the first retry happens after a short interval, the second after a longer interval, the third after a longer interval still, with each retry waiting exponentially longer than the previous one. This prevents a flood of simultaneous retries from hammering a recovering service. Jitter, adding a small random offset to each retry delay, prevents the thundering herd problem where many jobs that failed at the same time retry at the same time, producing the same overload condition that caused the failure.

Collaboration Platforms
Representational image based on an official image | Techgenyz

Dead-letter queues are the diagnostic instrument that makes retry systems observable. When a job exhausts its retry limit without succeeding, it moves to the dead-letter queue. The dead-letter queue is where operations should watch, as every job there represents a failure that requires investigation, whether a bug in the job logic, a permanent dependency failure, or data that the job cannot process. A dead-letter queue that is not monitored is not meaningfully better than silent job dropping, for the jobs accumulate unseen and the underlying failure is never diagnosed.

The Transactional Outbox: Guaranteeing a Job Is Enqueued When Its Data Is Committed

One of the subtler reliability gaps in background job systems is the window between writing data to the database and enqueuing the corresponding job. If an application writes a user record and then enqueues a welcome email job, but crashes between the write and the enqueue, the user exists in the database but never receives their welcome email. If the application enqueues the job first and then writes the user record, but crashes between the enqueue and the write, the job runs against data that does not yet exist.

The transactional outbox pattern solves this: the job description is written to an outbox table in the same database transaction as the data change, guaranteeing that either both succeed or neither does. A separate process reads the outbox table and publishes the messages to the queue, exactly when the data is committed, not before and not after. This pattern eliminates the consistency gap that exists between database writes and queue publishes in applications that treat them as separate operations.

Selecting the Right Queue for the Workload

BullMQ plus managed Redis remains a practical stack for Node.js teams operating their own infrastructure; lightweight enough for small teams but feature-rich enough for retries, delayed execution, concurrency, and observability, with a dashboard for job visibility. For AWS-native teams, SQS provides queue primitives with worker services on ECS, Lambda, or Kubernetes, with EventBridge for routing and Step Functions for complex workflows. For teams on Google Cloud, Cloud Tasks with Cloud Run workers fits event-driven, HTTP-dispatch models.

Celery with Redis or RabbitMQ as the broker remains the standard choice for Python teams; mature, well-documented, and compatible with every Python web framework. Sidekiq is the standard for Ruby on Rails teams, offering high performance backed by Redis. For Java and JVM-based teams, Spring Batch and Quartz Scheduler handle the enterprise job scheduling use case.

Long-running workflows and observability matter more than queue purity. Trigger.dev, Inngest, Hatchet, and Upstash Workflow deserve evaluation before building custom orchestration layers; they provide durable execution, step-level retry logic, and built-in observability for complex multi-step jobs that a basic queue does not handle well. The selection criterion that matters most is not which tool has the most features but which one the team can operate reliably and which one makes the jobs observable enough to diagnose failures when they occur.

Observability: The Layer That Background Jobs Most Commonly Lack

Background jobs are hard to observe precisely because they are asynchronous: the request that enqueued a job is long gone by the time the work runs. The job may hop through several queues before completing, and without deliberate instrumentation, a failed job is invisible until a user notices the missing email or the undelivered report.

Windows 11 Beta Preview
Representational image: Techgenyz

The minimum viable observability setup for a background job system includes: a queue dashboard that shows pending job count, processing rate, and error rate per job type; structured log output from workers that includes the job ID, job type, attempt number, duration, and outcome for every execution; alerts on dead-letter queue depth that fire when jobs begin accumulating without being processed; and queue depth monitoring that fires when the backlog grows beyond the threshold at which workers can clear it within a defined time window.

Each of these is achievable with standard tooling (BullMQ’s built-in dashboard, structured JSON logging in worker processes, and monitoring platform alerts), and together they close the visibility gap that makes background job failures hard to diagnose in systems that were instrumented as an afterthought.

What to Watch Next

The direction of background job systems in 2026 is toward durable execution frameworks that move beyond simple queues to provide step-level retry, human approval gates, and observable multi-step workflows. The use case driving this evolution is AI agent pipelines: long-running, multi-step operations that combine LLM calls, tool invocations, and data operations in sequences that may run for minutes or hours and require reliable state persistence across every step.

For backend teams building or improving their background job infrastructure today, the practical starting point is unchanged from what it has been for years: use a queue-backed architecture with an independent worker process, make every job idempotent, implement exponential backoff with jitter, watch the dead-letter queue, and add observability before the first production incident makes its absence visible. The tools have matured, the patterns are well-established, and the teams that get this right find that their backend systems become more reliable and more debuggable at the same time, which is the outcome that good background job architecture reliably delivers.

Recommended
More from this topic
+ + + + + + \ No newline at end of file diff --git a/sreweekly/articles/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.html b/sreweekly/articles/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.html new file mode 100644 index 00000000..eb284d30 --- /dev/null +++ b/sreweekly/articles/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.html @@ -0,0 +1,93 @@ + + + + + + + + Reddit + + + + +
+ +
+ + + + \ No newline at end of file diff --git a/sreweekly/articles/536/05-quick-thoughts-on-github-actions-aug-26-incident.html b/sreweekly/articles/536/05-quick-thoughts-on-github-actions-aug-26-incident.html new file mode 100644 index 00000000..5104cee9 --- /dev/null +++ b/sreweekly/articles/536/05-quick-thoughts-on-github-actions-aug-26-incident.html @@ -0,0 +1,966 @@ + + + + + + + +Quick thoughts on GitHub Actions Aug 26 incident – Surfing Complexity + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+ + +
+ +
+ + + + +
+
+ +
+
+ + + +
+
+

Quick thoughts on GitHub Actions Aug 26 incident

+ +
+ +

Last week, GitHub Actions experienced another incident. As is typical of a GitHub public writeup, it was published very soon after the incident, but there also aren’t isn’t a lot of detail. But let’s see what we info we can glean from it.

+ + + +

Database saturation

+ + + +

The first thing I noticed is that this incident is, once again, a saturation-related failure mode. Specifically, it was a database that was saturated due to write traffic.

+ + + +
+

This impact was triggered by saturation of writes to the database primary used by the service processing triggers for Actions workflows.

+
+ + + +

As I mentioned in my last blog post, database-related saturation issues are particularly pernicious, because they can be very difficult to recover from.

+ + + +

Multiple contributors, but not much detail

+ + + +

The write-up mentions seven separate factors that contributed to the incident.

+ + + +
    +
  • Growing peak daily load (this increased the writes to the database)
  • + + + +
  • An upstream issue in GitHub’s event processing infrastructure (?), which further increased the load
  • + + + +
  • Failing over from primary to replica did not lead to full recovery (?)
  • + + + +
  • Existing throttles were set ~10% too high, so they provided insufficient overload protection
  • + + + +
  • some jobs remained stuck in queued/waiting state after recovery (?)
  • + + + +
  • another issue that left some jobs left in a waiting-for-runner state after recovery
  • + + + +
  • a bug that left that some runs showing as queued even though they had already failed
  • +
+ + + +

I annotated contributors with (?) where I felt the report really didn’t provide any details at all. The mention of the upstream issue references a different GitHub incident, but there are no details on that other incident page at all. It does say “A detailed root cause analysis will be shared as soon as it is available”, so perhaps we’ll get more details on this other issue in the next few days.

+ + + +

What I’m most curious about, though, is what happened with the database failover. All we get in the write-up is this one line:

+ + + +
+

The primary was failed over, but the system did not fully recover.

+
+ + + +

What happened here??? Did the newly promoted primary get overwhelmed the same way that the previous one did? Did something else go wrong? I wish there they went into a lot more detail on the particular failure mode.

+ + + +

Slowly nursing an overloaded database back to health

+ + + +

On the plus side, the report does have some details on how they were able to mitigate. They throttled traffic to the database until it recovered, and then ramped the traffic back up slowly enough so that they didn’t knock it over again. Here’s the actual text:

+ + + +
+

At 15:45 UTC, throttling combined with service restarts recovered the service’s core health. Those throttles were gradually raised between 15:54 and 17:22 to restore full webhook processing for Actions runs. This ramp was deliberately slow to ensure we did not re-overwhelm the system given our original throttling was now known to be incorrectly set. The queue of webhook events was fully burned down at 17:40 UTC.

+
+ + + +

Two things I want to note about this. First of all, this sort of recovery approach is something you are going to need to do some day when your own database gets overloaded (and, believe me, it’s going to happen). If you’re prepared for this, you’ll have access to a throttle knob that the responders can manually control so they can cut the traffic and then increase it. It’s not something you want to have to build during an incident.

+ + + +

The second thing to note is that throttling means that you are deliberately cutting off access to the database for your users in order to bring it back up. This means that you will be temporarily increasing user pain in order to recover the system. This sucks, but it’s a decision you sometimes have to make during an incident: that you actually have to deliberately make the system behave worse from the user’s perspective in order to get it back into a healthy state. Now, if you have the ability of doing QoS-style throttling where you can selectively block the less important requests, then you might be able to reduce the amount of pain. But, once again, that’s something you need to have built into your system in advance.

+ + + +

Irony: fix was already in-flight when the incident struck

+ + + +

This line in the write-up broke my heart a little (emphasis mine):

+ + + +
+

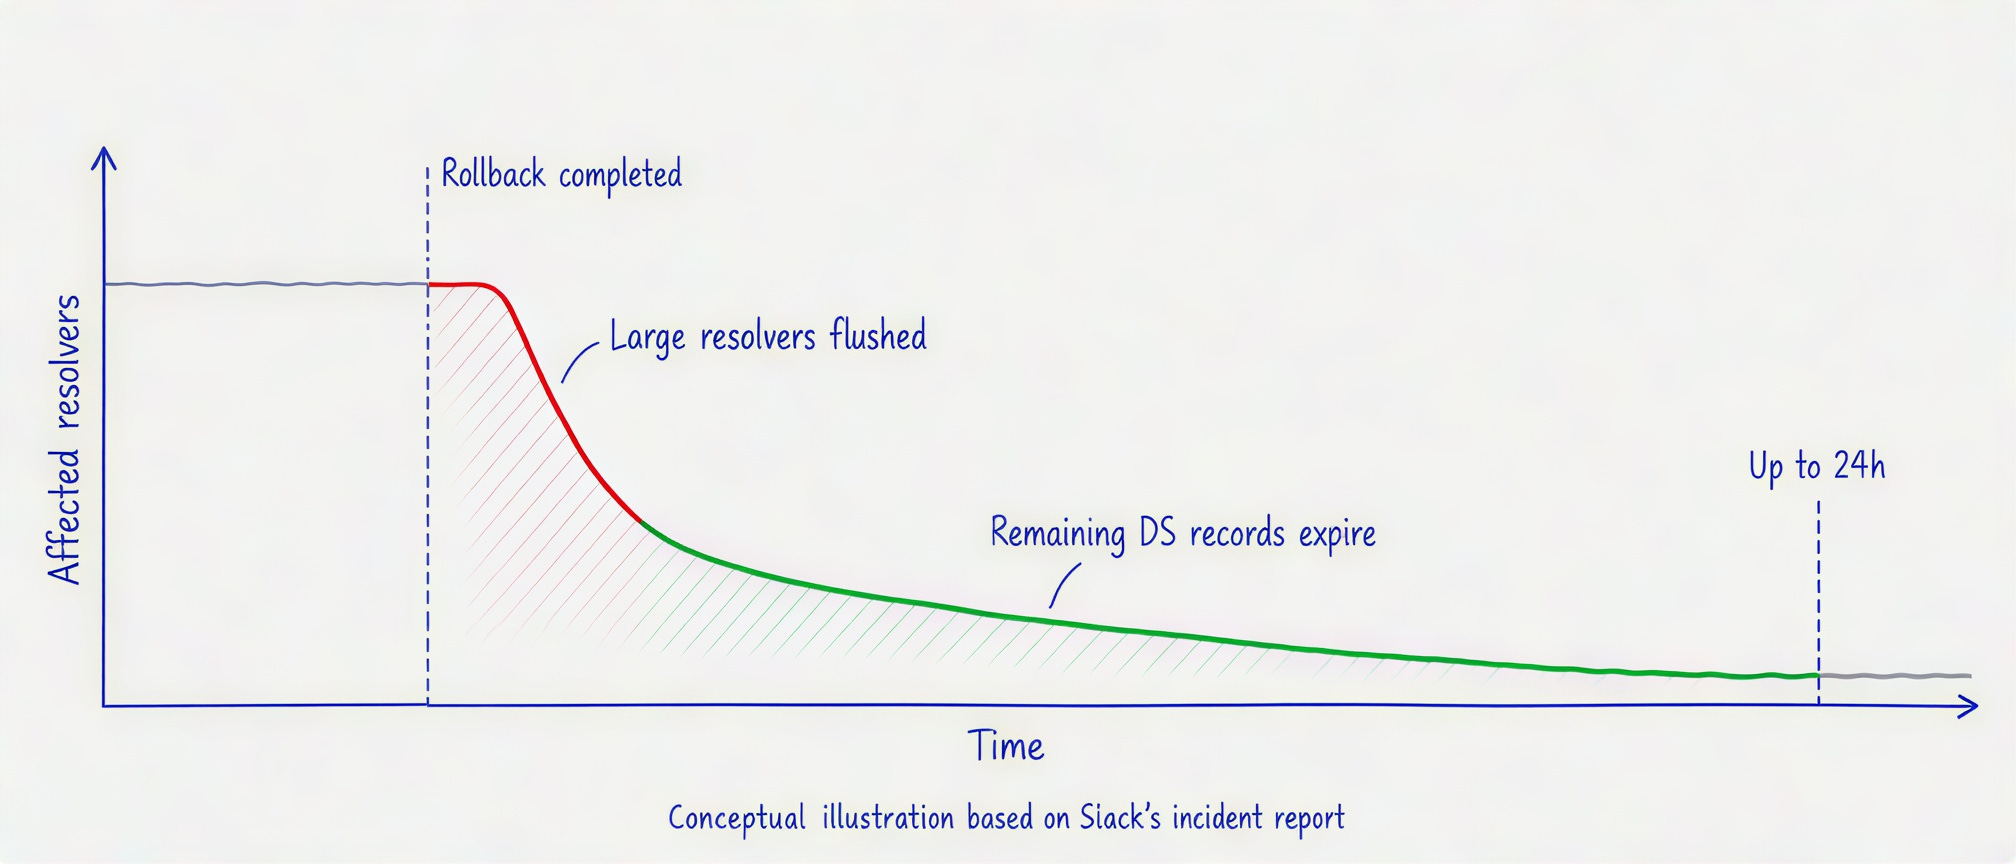
Several changes to improve the general scalability of this part of Actions were already complete and deploying to production. Rollout of those changes will be complete within the next 24 hours.

+
+ + + +

They were already working on reducing the likelihood of an incident like this, but it bit them before they could finish rolling out the improvements. That’s really just bad luck.

+ + + +

Another GitHub incident, another limit hit

+ + + +

Finally, we continue to see GitHub hitting one limit after another as they experience continued growth. There are just so many different limits within a system like this. I won’t be surprised if I’m soon reading up on yet another saturation-related GitHub incident.

+
+ + + + +
+ + + + +
+ + +

+ One thought on “Quick thoughts on GitHub Actions Aug 26 incident”

+ + +
    +
  1. + +
  2. +
+ + + + +
+

Leave a comment

+ + +
+ + + +

+

+ +
+ + +
+
+ + + +
+ + +
+
+ + + + + + + + + +
+
+
+
+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + diff --git a/sreweekly/articles/536/06-your-agent-is-not-production-ready-until-it-can-recover.html b/sreweekly/articles/536/06-your-agent-is-not-production-ready-until-it-can-recover.html new file mode 100644 index 00000000..b323eff8 --- /dev/null +++ b/sreweekly/articles/536/06-your-agent-is-not-production-ready-until-it-can-recover.html @@ -0,0 +1,918 @@ + + + + + + + + + Your agent is not production-ready until it can recover - Arpio + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + Skip to main content
+
+ + +
+ + + +
+
+ + +
+ + +
+ + +
+ +
+ +
+ +

When an agent becomes the front door to your support organization, it stops being an experiment. It is production infrastructure with a customer-facing SLA, and it fails in ways your existing runbooks have never seen.

+

Most teams get the build right. They ship the agent, wire up retrieval, add guardrails, and watch the traces. Then someone asks what happens if the region hosting it goes away, and the room gets quiet. The answer is usually a mix of “we have Terraform” and “we would rebuild it,” which is not a recovery plan with a number attached to it.

+

We are going to walk you through a fictitious, but realistic scenario with Digitata. Digitata is a B2C service provider and they want to jump on the agentic wave by adding a virtual customer service agent that is powered by Amazon Bedrock. 

+

When you think of building an agentic application, you need to consider resilience for the agent equal to the data and infrastructure. To put this in context, we’ll walk through a fictional case with the Digitata customer service agent.

+

The Digitata customer service agent

+

Meet Digitata, an enterprise B2C company with an active customer service team.  Many of the customer service requests are product questions. In order to free time for human agents, Digitata has built an agentic interface for customers to address these queries. The agent will replace the first tier of the ticket queue, and greatly improve resolution time.

+


+
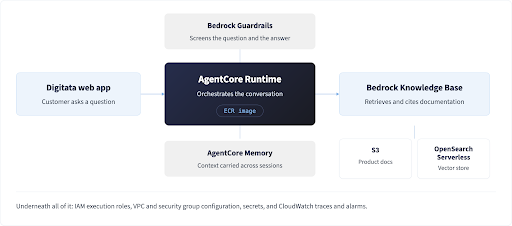
Digitata built their agentic application using Bedrock AgentCore along with other supporting Bedrock services, it’s been tested in development and QA environments, and we are now ready to ship it to production.

+

+

How the components relate:

+


+ + + + + + + + + + + + + + + + + + + + + + + +
AgentCore RuntimeHosts the agent itself. The orchestration code ships as a container image in Amazon ECR, and the runtime executes it under a scoped execution role.
Bedrock Knowledge BaseGrounds answers in Digitata’s product documentation. Docs land in an S3 data source; the resulting embeddings live in an OpenSearch Serverless vector collection, and answers cite the source page.
Bedrock GuardrailsKeeps the agent inside its job. Denied topics stop it answering general questions, and content filters screen what comes back before a customer sees it.
AgentCore MemoryCarries context across sessions, so a customer who returns tomorrow does not restate their account, their plan, and the problem they were already halfway through.
Supporting AWS resourcesIAM execution roles, VPC and security group configuration, secrets, and the CloudWatch alarms and traces that make the whole thing observable.
+

The production readiness checklist

+

With their agent built in a sandbox with all of the needed Amazon Bedrock resources, the next step for the Digitata team was getting it to production.  This process entails much more than a demo. The Digitata team created a production-ready checklist that the agents must pass to meet production-readiness:

+

Behavior and Quality

+
    +
  • Guardrail policies pinned to a published version, with adversarial prompts running in CI
  • +
  • Scope and refusal evals gating every deploy
  • +
  • A golden set of documentation questions re-run after each ingestion
  • +
+

Operations

+
    +
  • Alarms on failed ingestion, guardrail intervention rate, tool errors, and model throttling
  • +
  • Per-session traces, plus sampled human review of real conversations
  • +
  • Per-session token ceilings and a monthly budget alarm
  • +
+

Disaster Recovery (1-hour RTO)

+
    +
  • RTO and RPO agreed with the business and written down
  • +
  • Every component in scope: runtime image, agent configuration, guardrails, knowledge base, vector index, memory, roles, network
  • +
  • Recovery points in a separate account that production credentials cannot reach or delete
  • +
  • A drill on a schedule that produces a working agent answering real questions
  • +
+

Building the DR plan by hand

+

When they got to the final requirement of the production-ready checklist, Digitata hit a roadblock: they hadn’t incorporated their Amazon Bedrock services into their DR plan. “It is all in Terraform” is a good starting position, but an incomplete one. Terraform recreates resources; it does not carry the data inside them, and several of these components hold state that has no export button. Their first instinct was to build the disaster recovery plan by hand.

+

Digitata began to outline their recovery component by component:

+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
ComponentWhat recovery requires
Runtime container imageThe image sits in one region’s ECR registry. A runtime in the recovery region cannot pull it. You need cross-region replication and a guarantee that the exact tag production was running is present, not just the latest build.
Agent configurationModel selection, system prompt, tool and MCP wiring, and session settings live in the control plane. Anything a developer changed in the console and never backported to code does not exist in your recovery environment.
GuardrailsGuardrails are regional, versioned resources referenced by ID. Recreate them in the recovery region and the IDs differ, so every reference has to be resolved at deploy time rather than hardcoded.
Knowledge base & S3 sourceS3 replication handles the documents. The knowledge base resource, its embedding model configuration, and its data source binding all have to be recreated and re-associated.
OpenSearch Serverless vectorsVectors do not travel with the S3 bucket. Either you re-ingest the whole corpus in the recovery region, which takes as long as it takes and is usually the long pole in your RTO, or you run and pay for a second continuously synced collection.
AgentCore MemoryMemory is the accumulated value of every customer conversation, and there is no bucket you can point a nightly job at. Getting it out means building and owning a streaming pipeline.
IAM, network, secretsRole ARNs, VPC IDs, subnet IDs, and secret ARNs are account and region specific. Every one has to be parameterized, and a single hardcoded ARN fails the deploy at the worst possible moment.
+

Building the recovery path yourself

+

Digitata has a strong infrastructure and operations team; and they weren’t about to take any shortcuts on an initiative that was client-facing. The identified five workstreams to deliver a tested one-hour recovery.

+
    +
  1. Refactor the IaC to be account and region agnostic. Every account ID, region, ARN, and resource name becomes a variable. Provider aliases, separate state, and a second set of tfvars. Then the harder part: keeping the recovery configuration honest as the application changes weekly.
  2. +
  3. Build a memory backup pipeline. Stream memory events to Kinesis, and replicate them to a copy of the memory in the recovery environment. This is a new production data pipeline, with its own monitoring, its own failure modes, and its own on-call surface.
  4. +
  5. Replicate the documentation and the image. S3 cross-region replication for the knowledge base data source, ECR replication rules for the runtime image, and a decision on the vector store: pay to keep a warm collection synced, or accept a re-ingestion window inside your RTO.
  6. +
  7. Write and script the recovery runbook. Ordering matters: knowledge base before agent, guardrail version resolved before the runtime starts, memory reloaded before traffic arrives. The parts that cannot be automated become manual steps, and manual steps are where an hour turns into an afternoon.
  8. +
  9. Test it, repeatedly. An untested recovery plan is a hypothesis. Each drill means standing up the environment, validating that the agent answers grounded questions with memory intact, and tearing it down without disturbing production.
  10. +
+

Digitata realized that the initial build is finite work, but the ongoing cost erodes plans: every new tool the agent gains, every guardrail policy change, every VPC adjustment has to land in the recovery configuration too, or your tested plan quietly stops matching production. When the disaster recovery process doesn’t match, Digitata’s ability to respond to an outage event would be broken.

+

Ransomware Protection

+

Digitata’s team is ready for an outage. They built up their DR plan that accounts for changes to the agents and they are ready in case there are any disruptions to the underlying resources that support not only their agent, but also their cloud application.  However, there is one aspect of recovery that they missed: a cyber attack.

+

Being cyber resilient is similar to disaster resilience, but there is some nuance. Replication is designed to propagate changes faithfully, which means it propagates corrupted container images or deleted memories just as faithfully.

+

Recovering from a cyber event needs something replication cannot give you: historical recovery points an attacker with production credentials cannot reach, held in an isolated account, plus somewhere clean to validate that the threat is gone before anything serves traffic again.

+

While considering Cyber resilience, Digitata realized they had a big challenge keeping up with the pace of change with their new agents while meeting the resilience requirements set forth by the risk and compliance team.

+

The same result, in minutes

+

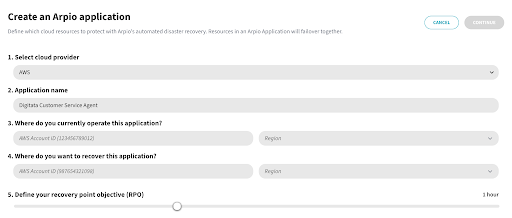
Digitata turned to Arpio because only Arpio protects Amazon Bedrock, including AgentCore runtimes and memory, knowledge bases, and guardrails, alongside the rest of the AWS resources the application depends on. There is no pipeline to build and no recovery configuration to maintain in parallel with production. With Arpio, resilience can be set up in four steps.

+

Step 1 — Point Arpio at the source environment

+

Connect the production account and the recovery account, then scan. Arpio inventories what is running, including the agent runtime, its guardrails, its knowledge base and vector store, and its memory.

+

Step 2 — Let dependency detection build the protection scope
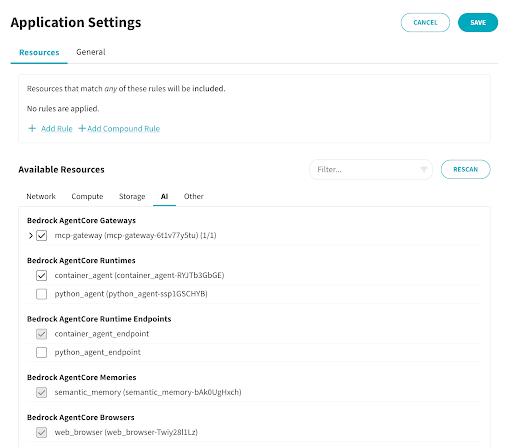
+

Select the application and Arpio follows its dependencies outward: the ECR image the runtime pulls, the S3 data source behind the knowledge base, the IAM roles, the network.

+

Step 3 — Continuous, isolated recovery points
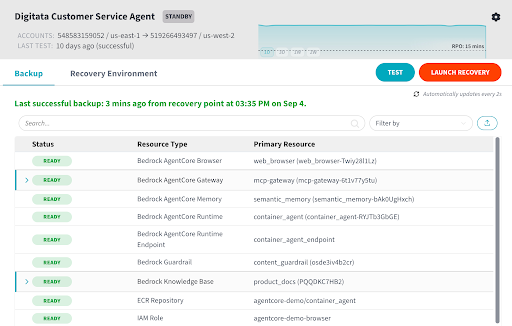
+

Arpio syncs the whole scope into the recovery account on a schedule, supporting a 15-minute RPO for this application. Recovery points are held outside production’s reach, so a compromise of the production account does not take the backups with it.

+

Step 4 — Test on demand, then recover in one click
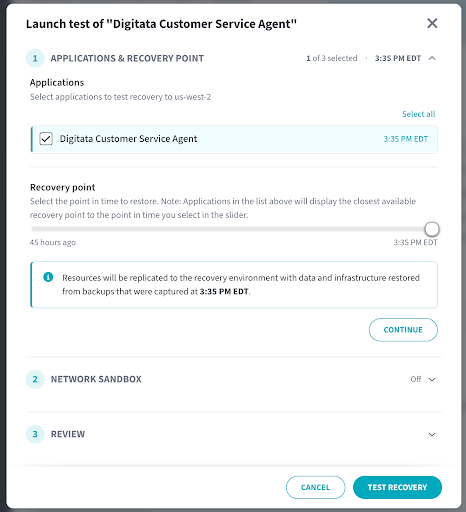
+

Run a test into an isolated sandbox whenever you want, without touching production, and confirm the agent answers grounded questions with its memory intact. When it counts, the same automation runs for real: an RTO of 15 minutes for this application, well inside the one-hour target.

+

Digitata’s Result

+

After a side-by-side comparison, Digitata’s I&O team realized that providing a resilient agentic application added a lot of unforeseen scope to ensure it was ready to meet the compliance and risk teams’ resilience requirements. They chose Arpio because the platform not only understood their full AWS environment, but also understood their agents as well.  This ensures that their application can remain resilient in the face of outages, disasters, and even a cyber attack.

+


+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
Built by handWith Arpio
Time to first protectionWeeks of platform work across five workstreamsMinutes, in the console
Agent memoryA streaming pipeline you build, run, and monitorCovered in scope
Vector storeRe-ingest during the outage, or pay for a warm second collectionRecovered with the application
Keeping up with changeManual, every time the application changesRescanned continuously
TestingA scheduled project with production riskOn demand, isolated from production
RansomwareReplication propagates the damageHistorical points in an isolated account
+


+

See it against your own agent

+

Bring the architecture you are about to ship and we will scan it, show you the dependencies, and run a recovery test with you.

+

Request a Demo »

+
+
+ +
+ +
+
+ + + + + +
+ +
+ + +
+
+ +
+ +
+ +
+ + + + + +
+
+ + + +
+ + +
+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + \ No newline at end of file diff --git a/sreweekly/articles/536/07-rollback-does-not-erase-distributed-memory.html b/sreweekly/articles/536/07-rollback-does-not-erase-distributed-memory.html new file mode 100644 index 00000000..7c9fd217 --- /dev/null +++ b/sreweekly/articles/536/07-rollback-does-not-erase-distributed-memory.html @@ -0,0 +1,342 @@ + + + + + + + + + + + + Rollback Does Not Erase Distributed Memory + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+

Discussion about this post

User's avatar

No posts

Ready for more?

    +
    + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + diff --git a/sreweekly/articles/536/08-the-architecture-of-neki.html b/sreweekly/articles/536/08-the-architecture-of-neki.html new file mode 100644 index 00000000..42725c20 --- /dev/null +++ b/sreweekly/articles/536/08-the-architecture-of-neki.html @@ -0,0 +1,192 @@ +The architecture of Neki — PlanetScale
    Neki, sharded Postgres, is now available. Get started
    Navigation

    Blog|Engineering|Neki

    The architecture of Neki

    Harshit Gangal |

    Meet Neki: sharding for Postgres. Neki allows applications to connect to massive, sharded databases over a single connection string. This post takes apart the architecture from the bottom up, one piece at a time, starting with what's underneath all of it.

    Real Postgres

    Neki is built as a sharding and scaling solution for real Postgres. It's not a fork, nor a wire-compatible reimplementation, nor a MySQL sharding idea wearing a Postgres label. Neki uses ordinary PostgreSQL instances that store rows in Postgres data pages using MVCC, carry out transactions, and work as you would expect with psql and other Postgres drivers. Neki builds around those instances to let you shard them, scale them, and manage them as one database.

    Let's take a look:

    PostgresManager

    Using vanilla Postgres means Neki needs a way to run and manage each instance. That includes starting and stopping Postgres, owning its data directory, and configuring replication so a new instance can join a shard. PostgresManager handles this coordination, running as the first process in the Postgres container and managing the postgres process directly.

    Sidecar

    Postgres uses a separate backend process for each connection and limits how many can be open at once. Neki’s Sidecar sits in front of each instance and pools connections, letting many client connections share fewer Postgres backends.

    The Router, which is the component that accepts external client connections, communicates with the Postgres nodes via these Sidecars.

    It also reports each Postgres instance's health and whether it is a primary or replica, so the rest of the cluster knows whether it can receive write queries.

    The pool doesn't treat every connection the same way. The length of time a connection is checked out for use varies depending on what it's being used for. A multi-statement transaction holds on to its connection until commit or rollback. A session-scoped advisory lock needs a connection of its own, because the lock has to outlive whatever transaction is open at the time and can't share that connection. Everything else checks a connection out and hands it back the moment the statement finishes.

    The Sidecar knows which of the three to use because the Router sends the necessary information with the query: autocommit, an open transaction, or a session that has to stay on one backend.

    Shards

    Each Postgres instance gets its own Sidecar and PostgresManager pair. Real deployments need more than one instance: a primary and its replicas. Neki calls that group a shard, the unit it splits data across. It's always advised to run a shard with a primary and 2+ replicas for high availability, as well as for additional read query capacity.

    A shard is considered one Postgres cluster. Its replicas are physical copies of the primary, so they share a catalog and the same object identifiers.

    Object Identifiers (OIDs) are how Postgres tracks objects internally, rather than by name. A client reads a column’s type OID off the wire to interpret its bytes and may cache that OID for later re-use. A custom type therefore needs to carry the same OID no matter which shard answers the query. Independent shards can assign that type different OIDs, so Neki designates one shard in the entire Neki cluster as the authoritative shard. This shard is the source of truth for translating custom type OIDs in responses from other shards to match. It ensures OIDs are consistent across the many shards of the Neki cluster.

    The authoritative shard's Sidecar also watches for schema changes and reports them to the Routers. This keeps the Routers' view of the schema current when a table is renamed or a column is dropped.

    Admin

    In a distributed system, instances can fail independently while the rest of the system lives on. Neki is no different. A primary or replica can go down at any moment while its fellow instances on the shard are healthy. The Admin's job is to detect failures, promote a replica, and maintain each shard’s durability policy.

    It health-checks every Sidecar, tracks replication lag for each replica, and decides when a shard needs a new primary. When a primary goes down, it coordinates an emergency failover, promoting a replica to take its place. It can also coordinate a planned switchover, which are needed for intentional node resizes and version upgrades. In both situations, Admin uses pg_rewind to bring diverged instances onto the new primary’s timeline, copying only the data that changed since the timelines diverged.

    Each shard has a durability policy that determines when a commit is acknowledged:

    • Async: The primary acknowledges the commit without waiting for a replica.
    • Sync: The primary waits for a replica to confirm the commit, protecting against the loss of a single node.
    • Cross-zone sync: The primary waits for confirmation from a replica in another availability zone, protecting against the loss of the primary’s zone.

    Postgres enforces whichever one is configured, using its own synchronous replication machinery. The Admin keeps that configuration correct as replicas join or leave shards, or a failover moves the primary to a different zone.

    Much of Admin’s work, however, doesn’t involve changing the primary. It repoints replicas to the correct replication source and corrects roles when Postgres and the topology disagree.

    Operator

    Neki’s components need to be deployed, updated, and replaced when their machines fail. Neki is built Kubernetes-first, and the Operator manages this full lifecycle.

    The Operator models a cluster as a hierarchy. A cluster owns routers and shards, and each shard owns the pods running its Postgres instances and Sidecars. When the Neki cluster configuration changes, the Operator works out which pods need to be created, updated, or removed.

    How it replaces an instance depends on whether that instance is still running. For a live instance, the Operator builds a replacement and confirms it has caught up before deleting the old one. If a node fails and loses its ephemeral storage, the Operator rebuilds the lost instance from scratch once its safety checks pass.

    Admin and the Router handle the database side of those disruptions. Admin coordinates a switchover for planned primary replacements or a failover when a primary goes down. The Router can buffer queries that are safe to retry while a healthy primary becomes available.

    Router

    We've talked a lot about how the Neki cluster operates and handles failure internally. What we've yet to dive into is how applications use the thing!

    The Router is the entry point for clients connecting to a Neki cluster, presenting a single Postgres wire-protocol endpoint to connect to a (potentially) massive sharded database. Applications use Postgres drivers to send SQL and open transactions without managing connections to individual shards.

    Authentication and role checks are done as if it were the Postgres instance itself, and the protocol's own extended-query flow and prepared-statement lifecycle are all built into the Router.

    Once a query arrives, the Router runs a Postgres-compatible parser against the authoritative shard's catalog, plans it against the current sharding layout, and sends it to whichever Sidecar needs to run it over gRPC.

    Not every query can run on a single shard. A join may need data from several shards or an aggregate may need to read from all of them. The Router coordinates that work as a distributed query.

    Whenever possible, it leaves the work to the Postgres instances. If both sides of a join are on the same shard, the Router sends the join to that shard. When a join needs to run across shards, the Router executes it itself, choosing between nested-loop, hash, and merge joins based on cost estimations.

    Note

    Read more about Routers, parsing, and sharded query planning in our other blog, The lifecycle of a sharded Postgres query.

    Earlier, we covered how Admin promotes a new primary during a switchover or failover. If that happens, the Router can buffer queries, giving the Admin time to complete the handover. For queries that can safely be retried after failing against a primary, the Router buffers the query and waits, for a fixed time, for a healthy primary. Once a healthy primary is available, the Router releases queued queries gradually.

    Data Topology

    Router, Sidecars, and Admin all need a consistent picture of which shards exist, what key ranges they own, and which tables are sharded at all. If the Router's copy is wrong, a query can land on the wrong shard. This is all specified with a Data Topology, and etcd holds the single, authoritative copy of it. When the Data Topology changes, the Router, Sidecars, and Admin pick up the updated configuration without a restart or manual synchronization.

    The Data Topology defines shard groups, named sets of physical shards, each owning a range of routing keys. Each table belongs to a shard group. Shard indexes specify the columns or expressions and the strategy used to turn row values into routing keys. Those keys determine which shard receives each row.

    Replicator

    As a database grows, its layout may need to change. Tables need to be imported, shards need to be split, and schemas need to change all while applications keep using the database.

    Neki's Replicator handles the data movement behind all such operations. It runs as a separate process colocated with a shard's Sidecar and Postgres. It is responsible for copying existing rows to new destinations, and also keeping the data current by decoding changes from a Postgres logical replication stream and applying them as SQL.

    Three workflows use the Replicator:

    • MoveTables relocates a set of tables, including imports from an external Postgres instance
    • Reshard redistributes data across shard key ranges, allowing a shard to be split when it outgrows its capacity
    • OnlineDDL changes a table's schema by building a shadow table alongside the original and keeping it current through the same change-data-capture pipeline MoveTables and Reshard use to relocate rows. A final rename swaps the new table into place. This supports changes such as repartitioning a table, alongside changes that would otherwise require a blocking operation.

    Once the data has been copied and the destination is caught up, the workflow switches from the original tables or shards to their replacements. This is the cutover. The Router uses the same buffering mechanism that handles primary changes for this step. It buffers queries during that switch and releases them afterward.

    Together, these components let Neki scale Postgres horizontally while presenting a single database to applications.

    Get started

    Neki is in Platform Preview right now.

    Start a Neki cluster today: build on it from scratch, or import an existing Postgres database.

    \ No newline at end of file diff --git a/sreweekly/articles/536/index.json b/sreweekly/articles/536/index.json new file mode 100644 index 00000000..7dbfef0d --- /dev/null +++ b/sreweekly/articles/536/index.json @@ -0,0 +1,50 @@ +[ + { + "idx": 1, + "url": "https://surfingcomplexity.blog/2026/08/29/omnipresent-availability-risks-in-cloud-software/", + "ok": true, + "error": null + }, + { + "idx": 2, + "url": "https://itnext.io/how-we-built-real-time-stock-pricing-at-mofid-brokerage-031015ce1301", + "ok": false, + "error": "HTTP 403" + }, + { + "idx": 3, + "url": "https://techgenyz.com/background-jobs-backend-architecture/", + "ok": true, + "error": null + }, + { + "idx": 4, + "url": "https://www.reddit.com/r/sre/comments/1wguk7p/can_automated_root_cause_analysis_reliably/", + "ok": false, + "error": "trafilatura returned empty" + }, + { + "idx": 5, + "url": "https://surfingcomplexity.blog/2026/08/29/quick-thoughts-on-github-actions-aug-26-incident/", + "ok": true, + "error": null + }, + { + "idx": 6, + "url": "https://arpio.io/https-arpio-io-your-agent-is-not-prodution-ready-until-it-can-recover/", + "ok": true, + "error": null + }, + { + "idx": 7, + "url": "https://storiesfromtheedge.substack.com/p/rollback-does-not-erase-distributed", + "ok": true, + "error": null + }, + { + "idx": 8, + "url": "https://planetscale.com/blog/the-architecture-of-neki", + "ok": true, + "error": null + } +] \ No newline at end of file diff --git a/sreweekly/html/536-2026-09-28.html b/sreweekly/html/536-2026-09-28.html new file mode 100644 index 00000000..89962693 --- /dev/null +++ b/sreweekly/html/536-2026-09-28.html @@ -0,0 +1,96 @@ +

    View on sreweekly.com

    + +
    +

    A message from our sponsor, Planetscale:

    +

    PlanetScale is headed to SREcon26 in Dublin this October. Swing by our booth to grab some merch, catch a live demo, and chat with the team behind the world’s fastest databases. We can’t wait to see you there.

    +

    → If you’re not at SREcon but still want to learn how PlanetScale can reliably scale your databases, get in touch.

    +
    + + +
    +
    + +
    +

    Common threads seen across incident write-ups from many companies.

    +

      Lorin Hochstein

    +
    +
    + + + +
    + +
    +
    +

    How we built a production architecture handling 1,900+ messages per second and tens of thousands of concurrent connections with Kafka, Redis Pub/Sub, .NET Channels, and SSE.

    +
    +

      Mohsen Rajabi — ITNEXT

    +
    +
    + + + +
    + +
    +

    This is a thorough tour of the design decisions that separate a background job system that works in development from one that survives production.

    +

      Shreshtha Saha — Techgenyz

    +
    +
    + + + +
    + +
    +

    This question kicked off a great comment section:

    +
    +

    Has anyone gotten an automated RCA setup to actually nail root cause without a person doing the final synthesis, or is that still mostly aspirational marketing from vendors?

    +
    +

      u/Acrobatic_Refuse8100 and many others — reddit

    +
    +
    + + + +
    + +
    +

    Do you have a way to slow down traffic to your database during an incident? This one has a great explanation of why you need one.

    +

      Lorin Hochstein

    +
    +
    + + + +
    + +
    +

    Through a fictitious case study, this article shows how to go about building a reliable service with an agentic component.

    +

    FYI the last ~quarter or so is a sales pitch, but the preceding majority of the article isn’t.

    +

      Arpio

    +
    +
    + + + +
    + +
    +

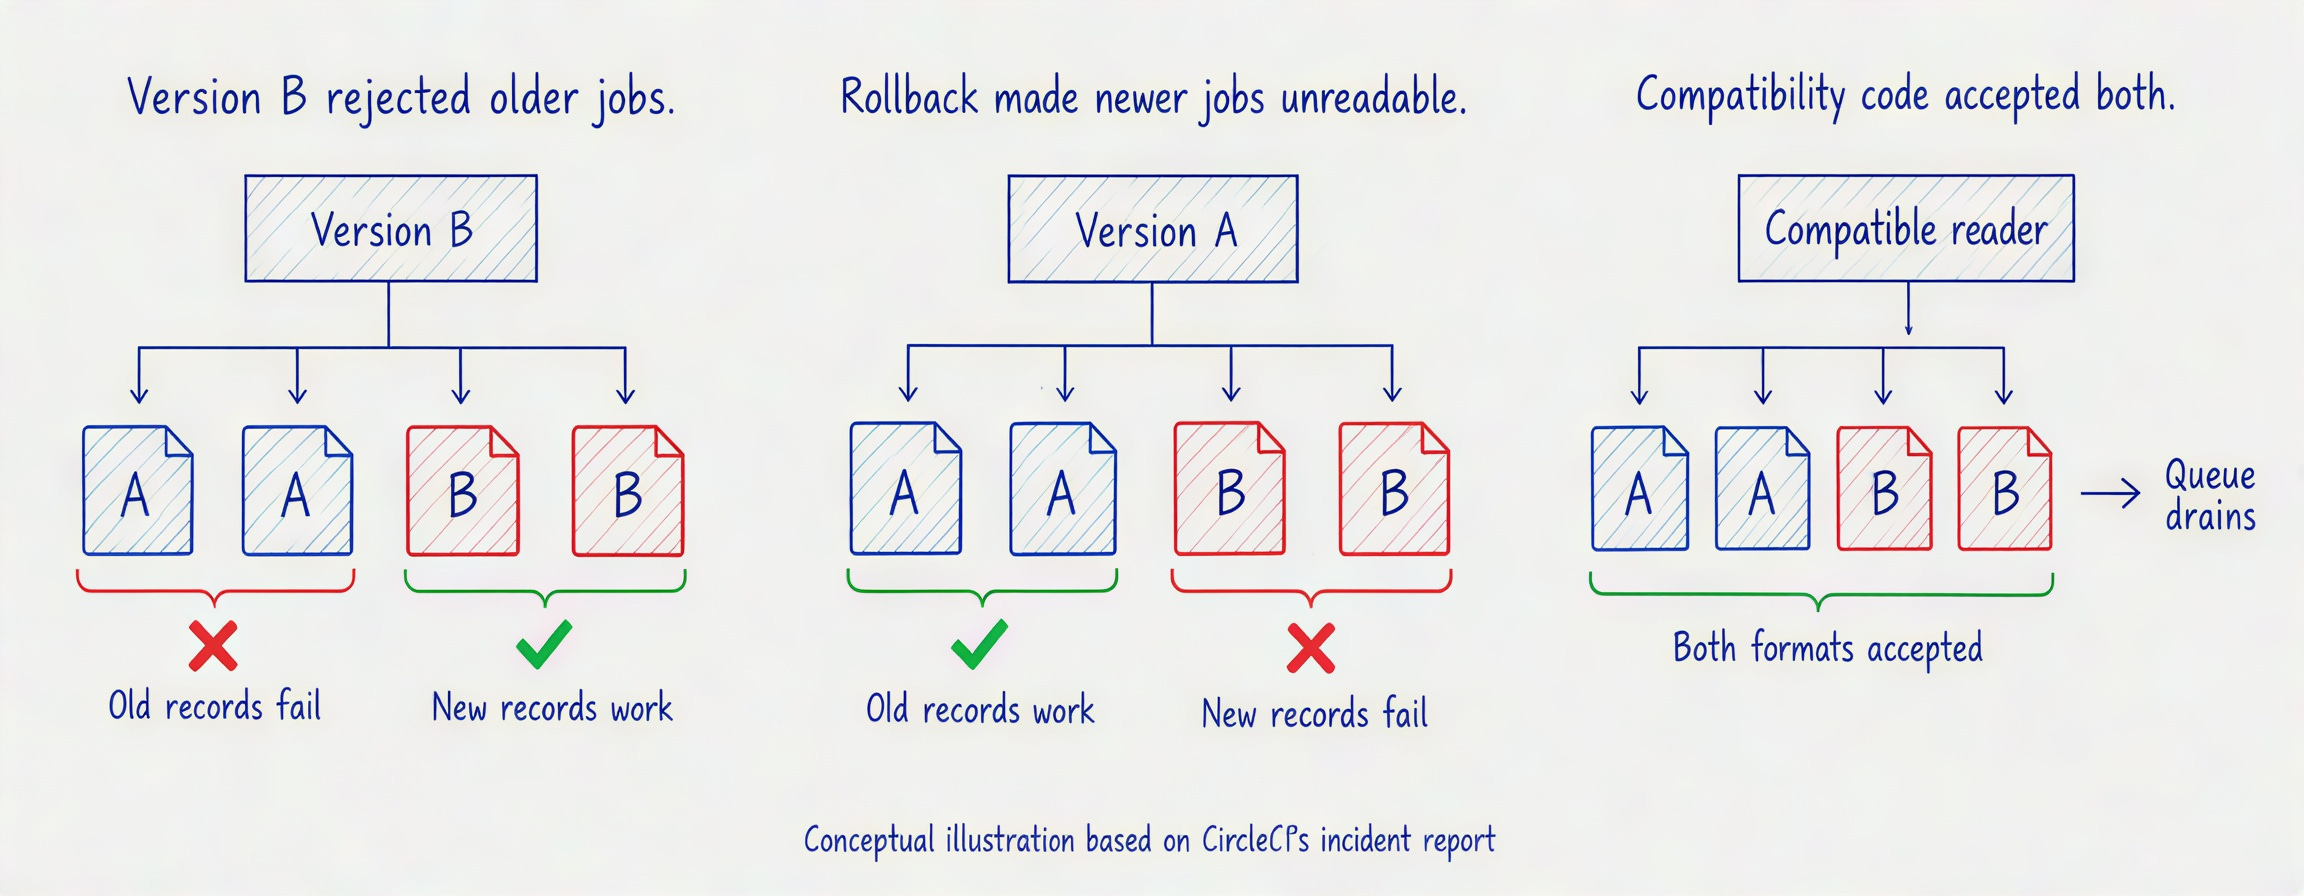
    Rollback sounds great in theory, but it doesn’t always work. The CircleCI example really hits hard.

    +

    This reminds me of a classic article from the now-defunct company Skyliner, You Can’t Have a Rollback Button.

    +

      Balu Kambala

    +
    +
    + + + +
    + +
    +

    Yes, this is a walkthrough of a vendor’s product, but the architecture is genuinely interesting and it reads like an engineering explainer rather than a sales pitch. I especially liked the wrinkle where one shard has to be designated authoritative so that custom type OIDs stay consistent across the whole cluster.

    +

      Harshit Gangal — PlanetScale

    +

      This article is published by this issue’s sponsor, but their sponsorship did not influence its inclusion in the newsletter.

    +
    +
    +
    \ No newline at end of file diff --git a/sreweekly/manifest.json b/sreweekly/manifest.json index 504a517d..75b4c030 100644 --- a/sreweekly/manifest.json +++ b/sreweekly/manifest.json @@ -1,6 +1,6 @@ { "feed": "https://sreweekly.com/feed/", - "last_scanned": "2026-09-22T06:00:19", + "last_scanned": "2026-09-29T06:00:19", "issues": { "532": { "id": "532", @@ -8013,6 +8013,20 @@ "extracted": false, "article_count": 0, "markdown_dir": null + }, + "536": { + "id": "536", + "title": "SRE Weekly Issue #536", + "url": "https://sreweekly.com/sre-weekly-issue-536/", + "pub_date": "2026-09-28", + "html_file": "html/536-2026-09-28.html", + "fetched_at": "2026-09-29T06:00:19", + "extracted": true, + "article_count": 8, + "markdown_dir": "markdown/536", + "extracted_at": "2026-09-29T06:00:40", + "articles_fetched": 6, + "articles_failed": 2 } } } \ No newline at end of file diff --git a/sreweekly/markdown/536/01-omnipresent-availability-risks-in-cloud-software.md b/sreweekly/markdown/536/01-omnipresent-availability-risks-in-cloud-software.md new file mode 100644 index 00000000..3c76581a --- /dev/null +++ b/sreweekly/markdown/536/01-omnipresent-availability-risks-in-cloud-software.md @@ -0,0 +1,130 @@ +# Omnipresent availability risks in cloud software + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Lorin Hochstein +- **链接**: https://surfingcomplexity.blog/2026/08/29/omnipresent-availability-risks-in-cloud-software/ + +## 简介 + +Common threads seen across incident write-ups from many companies. + +## 正文 + +I’m using this post to gather together some common threads I’ve noticed after reading write-ups of major cloud software incidents. By *cloud software*, I’m referring to software-as-a-service (do people even say that anymore? in the cloud. This doesn’t just apply to cloud providers, although it does apply to them as well. + +Here’s an outline of the topics in this post: + +- problem areas + - saturation + - example: databases + - networking (traffic routing failure) + - example: DNS + - security (deny valid access) + - example: SSL certificates +- saturation +- essential non-standard changes + - mitigating an operational issue + - migration +- essential increase in essential complexity + - reliability subsystem + - migration + +I think of all of these as *omnipresent availability risks*: I think these are fundamentally unavoidable, and will be contributing to software incidents until the end of time; or, at the very least, until the end of my own career in software. + +There are three general areas that most major incidents seem to fall into: saturation, networking, and security. So, let’s start with those. + +## Saturation + +*Saturation* is probably the topic I talk about most frequently, both [on this blog](https://surfingcomplexity.blog/?s=saturation) and elsewhere (e.g.,: the [saturation post](https://resilienceinsoftware.org/news/11475336) I wrote for the Resilience in Software Foundation and my [saturation talk](https://youtu.be/PHYCRubnmSM) at the Software Should Work conference). The system becomes *saturated* when it reaches a limit. That’s a pretty generic description, but there are many limits! + +### Databases + +Many major incidents involve some system component becoming saturated in one form or another. I personally worry about database saturation the most. That’s because it’s difficult to recover from an overloaded production database. In addition, because database systems are such complex beasts, it can be quite difficult to even determine what the specific performance issue actually is. This is why having in-house database operational expertise is critical. + +Saturation is an omnipresent risk because the finite nature of resources is a hard constraint in the world that we live in. Eventually, some resource in your system is going to run out. + +Example: [GitHub Incident, Aug 26, 2026](https://www.githubstatus.com/incidents/y1t7p9fzrlj2) + +## Networking + +While I prattle on endlessly about saturation, not every major incident involves saturation. You can encounter scenarios where all of your internal subsystems are reporting healthy, but from your customer’s point of view, your site is down: they can’t use it. One way this can happen is if your users can’t even reach your site, and that’s where the networking problem area comes in. + +A networking problem can lead to packets being misrouted. These requests might be *black-holed* (i.e., silently dropped), or they might be incorrectly routed to a service that doesn’t have the capacity to respond to all of these requests, in which case you’ve got both a network routing issue and a saturation issue. + +![](https://surfingcomplexity.blog/wp-content/uploads/2026/08/image-3.png?w=1024) + +[NASA](https://science.nasa.gov/resource/black-hole/) + +### DNS + +DNS issues are an example of this kind of network-related failure mode. There’s no way those packets are going to make it to their destination if the client can’t even determine which IP address to send them to. And when DNS breaks, that’s what happens. + +I bring DNS up because it’s bitten folks enough times that there’s a famous haiku: + +![](https://surfingcomplexity.blog/wp-content/uploads/2026/08/image-1.png?w=550) + +More generally, networking is an omnipresent risk because cloud software is inherently distributed, so networking is always a critical service. Now, I don’t work in networking, but from the outside, networking just feels like a dangerous domain to do operational stuff in. The blast radius of a networking issue can be very large. And, because network behavior is inherently distributed, reasoning about the behavior of operational changes is just inherently difficult. Honestly, that’s probably why I don’t work in networking. + +And, so, I predict we’ll continue to see networking issues contribute to large-scale incidents. + +Example: [Buildkite incident, Aug 25, 2026](https://www.buildkitestatus.com/incidents/tm6746k61p73) + +## Security + +There’s a fundamental tradeoff between availability and security: availability is about ensuring that the good people can access the system. Security is about ensuring that the bad people cannot access the system. This means that there’s always a risk that a security system designed to prevent bad actors from accessing the system can lead to good actors also being blocked. Consider this scenario: there’s an internal security subsystem that goes unhealthy (possibly due to saturation). Is your policy to fail closed or fail open in the event that this subsystem is erroring? Answering that requires making an availability-security tradeoff. + +### SSL certificate expiration + +Another example of this failure mode, which keeps biting our industry again and again, is SSL certificate expiration. Here you have the behavior of a security system that is preventing legitimate access because the cert wasn’t renewed. + +![Bazel expired certificate](https://surfingcomplexity.blog/wp-content/uploads/2025/12/image-4.png?w=1024) + +And so, my claim is availability incidents that involve security subsystems will continue to be a thing forever. + +Example: [Bazel incident, Sep 27, 2025](https://surfingcomplexity.blog/2025/12/27/the-dangers-of-ssl-certificates/) + +## Essential uncommon changes + +Your system is constantly undergoing change. Heck, if you stopped making changes, the system would eventually stop working properly. Now, there are some changes that your org does very frequently. Hopefully, you’re deploying often, flipping feature flags a lot, and so on. But there are other changes that your org has less experience with, because they happen much less often. That means that there hasn’t been as much investment in tooling to support these sorts of changes, and it means that the people making these changes don’t have the same level of expertise as they do with the more common changes. That makes these sorts of changes more dangerous: less mature tooling and less experienced humans. + +### Mitigating an operational issue + +A few years ago, I wrote a post titled [a conjecture on why reliable systems fail](https://surfingcomplexity.blog/2017/06/24/a-conjecture-on-why-reliable-systems-fail/) where I speculated on two common contributors to major incidents. One of those contributors was ***a manual intervention that was intended to mitigate a minor incident***. Now, it may be that you frequently have to do manual interventions to mitigate system issues, in which case you’ll have a lot of experience with those sorts of interventions. But you’ll also be more motivated to put in the engineering effort to automate away those sorts of common issues. + +It’s exactly the *uncommon* issues that require a human operator to intervene to mitigate that are dangerous, because they are uncommon. But they’re essential: there’s a problem in the system, and you need to fix it! But because [all practitioner actions are gambles](https://www.adaptivecapacitylabs.com/HowComplexSystemsFail.pdf), the manual mitigation carries risk that you could make the problem even worse. And, eventually, this will happen to you. + +Example: [Azure Regional Outage, Jul 23, 2026](https://surfingcomplexity.blog/2026/08/16/quick-thoughts-on-azure-regional-outage-from-july-23-26/) + +### Migration + +If you’re at a tech company, unless it’s a start-up, you’ll be dealing with migrations, as old tech gets replaced by newer tech that is better suited to the problems that your org is currently facing. While migrations as a general category are extremely common, each migration is itself a snowflake. This means that the specific details of the migration work is an *uncommon change*. The work of migration involves making a kind of change to your system that you haven’t made before. + +To make things worse, one of the dangers of migration is that, as you go along, you start to build confidence that your changes are safe, but there are actually hidden dangers lurking in the system for the next migration. The confidence in the safety of the work exceeds the actual safety. I mean, you made n-1 changes as part of the migration, and none of those changes had negative consequences. It’s natural to assume that the same outcome will occur with the *nth* change. + +Example: [Rogers Network outage, Jul 8, 2022](https://surfingcomplexity.blog/2024/07/06/quick-takes-on-rogers-network-outage-executive-summary/) + +## Essential increase in essential complexity + +The late American computer scientist Fred Brooks wrote a famous software engineering essay titled *[No Silver Bullet](https://worrydream.com/refs/Brooks_1986_-_No_Silver_Bullet.pdf)* where he drew a distinction between *accidental complexity* and *essential complexity.* The general idea was that there was some amount of complexity in a software system that didn’t need to be there (accidental complexity) and some amount that was just inherent to the nature of the problem space and solution space and so could not be removed (essential complexity). + +### Reliability subsystem + +We’ve developed multiple techniques to improve the reliability of software systems, including retries, concurrency limiting, autoscaling, automated failover, circuit breakers, health checks, canaries, outlier detection, the list goes on and on. There’s one thing that all of these techniques have in common: they increase the complexity of the overall system! And they do this because they have to increase complexity in order to do their job. This is a consequence of [Ashby’s Law](https://surfingcomplexity.blog/2026/01/31/ashby-taught-us-we-have-to-fight-fire-with-fire/), which states that if you want to build a control system that handles more scenarios, you have to increase the complexity of the controller itself. + +This means that reliability subsystems result in a complexity trade-off. On the one hand, our system can now automatically recover from failure modes that previously required manual intervention. On the other hand, as we all know, increase in complexity is itself dangerous because it can introduce entirely new failure modes that weren’t there before. + +Going back to my *conjecture* blog post, the second contributor I posited was: ***unexpected behavior of a subsystem whose primary purpose was to improve reliability***. And this is exactly why. Adding reliability subsystems improves the *robustness* of our system, but it adds essential complexity to our system, which can lead to novel incidents. + +Example: [OpenAI incident, Dec 11, 2024](https://surfingcomplexity.blog/2024/12/14/quick-takes-on-the-recent-openai-public-incident-write-up/) + +### Migration + +Like all engineers, I’m a big fan of giving the answer “it depends” if somebody asks me a question about whether they should do X or Y. However, if someone came up to me and said, “Lorin, I’m preparing to do a migration at my company, and I’m trying to decide whether to do a big-bang migration or an incremental one”, then I would almost certainly say, “For the love of God, please do an incremental migration!”. Sometimes big-bang migrations are unavoidable, but when given a choice, I’m going to go for the incremental migration as the safer option. + +However, when you do an incremental migration, it means that you need to simultaneously support the old system and the new system at the same time while you’re doing the migration. This means that even if the new system yields a net decrease in overall complexity over the old system, while the migration is happening, you’re going to see an *increase* in system complexity. And that means that you’ll see incidents arise as a byproduct of this increased complexity. + +Example: [Cloudflare incident, Jul 14, 2025](https://surfingcomplexity.blog/2025/07/21/cloudflare-and-the-infinite-sadness-of-migrations/) + +## Incidents are inevitable, so you’d better be ready + +To reiterate, I think all of the risks mentioned here are *omnipresent*: they are fundamental to the nature of cloud software. I don’t think that any of these risks can be eliminated. That’s why I believe so strongly in the value of getting better at incident response. Because, if you prepare, you can get better at dealing with problems that arise as a result of these risks. diff --git a/sreweekly/markdown/536/02-how-we-built-a-real-time-stock-pricing-system-at-scale.md b/sreweekly/markdown/536/02-how-we-built-a-real-time-stock-pricing-system-at-scale.md new file mode 100644 index 00000000..0b7de6c3 --- /dev/null +++ b/sreweekly/markdown/536/02-how-we-built-a-real-time-stock-pricing-system-at-scale.md @@ -0,0 +1,13 @@ +# How We Built a Real-Time Stock Pricing System at Scale + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Mohsen Rajabi — ITNEXT +- **链接**: https://itnext.io/how-we-built-real-time-stock-pricing-at-mofid-brokerage-031015ce1301 + +## 简介 + +> How we built a production architecture handling 1,900+ messages per second and tens of thousands of concurrent connections with Kafka, Redis Pub/Sub, .NET Channels, and SSE. + +## 正文 + +> ⚠️ 抓取失败:HTTP 403 diff --git a/sreweekly/markdown/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.md b/sreweekly/markdown/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.md new file mode 100644 index 00000000..45694a65 --- /dev/null +++ b/sreweekly/markdown/536/03-master-background-jobs-with-smarter-queue-architecture-and-reliability.md @@ -0,0 +1,104 @@ +# Master Background Jobs With Smarter Queue Architecture and Reliability + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Shreshtha Saha — Techgenyz +- **链接**: https://techgenyz.com/background-jobs-backend-architecture/ + +## 简介 + +This is a thorough tour of the design decisions that separate a background job system that works in development from one that survives production. + +## 正文 + +## Highlights + +- Background jobs move slow or resource-heavy tasks away from the main request-response cycle, improving application speed and reliability. +- Queue-based systems use producers, queues, and workers to process tasks independently from the main application. +- Idempotency is essential because distributed systems can execute the same job more than once. +- Retry strategies with exponential backoff, jitter, and dead-letter queues help manage failed jobs safely. + +#### Table of Contents + +Every backend application, at some point, has a task that takes too long to run inside the request-response cycle. Sending a welcome email, generating a PDF report, resizing an uploaded image, reconciling a payment, syncing data to a third-party service, these operations are too slow to block the user on, too important to drop if they fail, and too variable in duration to handle predictably inside a web server process that is optimized for [fast, stateless responses](https://learn.microsoft.com/en-us/azure/architecture/best-practices/background-jobs). + +Background jobs solve several critical problems in modern systems. By moving expensive operations into the background, applications respond almost instantly, creating smoother and faster user experiences. Heavy workloads can overwhelm web servers if handled synchronously, since background workers distribute these workloads more efficiently across multiple machines or containers. As traffic grows, developers can simply add more workers instead of scaling the entire application. If a worker fails, the job can be retried automatically. + +Understanding how background job systems work (and, more importantly, how they fail) is a core [backend engineering skill](https://techgenyz.com/chatgpt-linux-app/) in 2026. The concepts are not complex, but the implementation gaps that produce double-charged payments, silently dropped emails, and unrecoverable job failures are almost always traceable to the same small set of design decisions made without a complete picture of how queue-based systems behave under real conditions. + +## The Core Architecture: Producers, Queues, and Workers + +The core idea behind background task processing is to decouple the initiation of a task from its execution. This is achieved through a message broker acting as a queue, where tasks are published by the main application and consumed by workers. A queue is a data structure that holds tasks awaiting execution, since tasks are typically added by the main application process and picked up by worker processes. Workers operate independently from the main application, allowing for parallel processing and preventing blocking. A scheduler is a component responsible for executing tasks at predefined times or intervals. + +![coding ai-assisted coding tools, SQL injection](https://techgenyz.com/wp-content/uploads/2026/01/coding-1024x576.webp) + +The request lifecycle in a background-job-enabled system looks like this: a user action triggers a web request, the web server validates the request, records the intent, and pushes a job description into the queue, then returns a response to the user immediately. A separate worker process, running independently of the web server, pulls the job from the queue, executes the actual work, and records the result. The user receives their response in milliseconds. + +This architecture produces three important properties. The web server’s response time is decoupled from the duration of the background work, a job that takes three minutes does not make the user wait three minutes. The work is durable: even if the server that received the original request restarts, the job description persists in the queue and will be processed by a worker. And the system scales horizontally: when job volume increases, additional worker processes can be added without touching the web server layer. + +In-process jobs, calling asynchronous logic from the API server using setImmediate, setTimeout, or internal promise chains, are the simplest approach to write but fragile in practice. When the server restarts, all in-flight jobs are lost with no record of what was pending. This is the failure mode that catches early-stage teams: the application appears to handle background work correctly in development and under normal conditions, but any process restart during a [deployment](https://techgenyz.com/chatgpt-linux-app/), crash, or scale-down event silently drops every job that was queued in memory at that moment. + +## Common Use Cases and Why Each One Demands Background Processing + +The use cases that belong in background job queues are consistent across application types, and the reason each one belongs there is specific to the properties of that work. + +- **Email and notification delivery** is the most universal background job. Sending email via an external SMTP service or API introduces network latency, rate limits, and occasional delivery failures that are unpredictable and outside the application’s control. A transactional email that fails because the email provider’s API was momentarily slow should be retried; it should not cause the user’s action to fail or make them wait. Queuing email delivery decouples the user action from the delivery outcome and enables automatic retry when the provider is briefly unavailable. + +- **Report generation** is the clearest case for background processing from a user experience perspective. A report that aggregates twelve months of data, joins multiple tables, and formats the result as a PDF may take thirty seconds or three minutes depending on data volume. No user should wait at an HTTP connection while that computation runs. The correct pattern is: the user requests the report, the server queues the generation job and returns a job ID, the user’s client polls a status endpoint or waits for a push notification, and the completed report is made available for download when the worker finishes. + +The Asynchronous Request-Reply pattern: the caller receives a URL or resource identifier when it submits the job and polls that endpoint for status. Alternatively, the background task can publish an event when it completes, and the caller subscribes to those events, an approach suitable for cloud-native event routing through services like AWS EventBridge or Azure Event Grid. + +- **Media processing** (image resizing, video transcoding, thumbnail generation, PDF creation, format conversion) involves CPU-intensive or storage-intensive operations that are poorly suited to web server processes. Image processing and file generation are classic worker tasks. Resizing uploads, generating thumbnails, converting formats, creating PDFs, and extracting metadata all benefit from asynchronous processing. The user can upload a file and receive an immediate response while the worker performs the transformation in the background, improving user experience and isolating heavy storage or CPU operations from the API. + +![market research for startups Market Research For Startups](https://techgenyz.com/wp-content/uploads/2024/03/market-research-for-startups-1024x576.jpg) + +- **Payment and financial reconciliation** requires background processing with the strongest reliability guarantees of any use case.Payment-related tasks often belong in workers with strong safeguards. Capturing a payment, reconciling a transaction, generating an invoice or polling for settlement, because payment systems are sensitive to duplicates and partial failure, these jobs must be idempotent and carefully logged. A queue helps manage retries, but business logic must still prevent double charging or repeated side effects. + +## At-Least-Once Delivery and Why Idempotency Is Non-Negotiable + +The property of queue-based systems that most confuses engineers unfamiliar with distributed systems is delivery guarantee. Most message queues, including Redis-backed systems, AWS SQS in its standard mode, and RabbitMQ, guarantee at-least-once delivery, meaning a message will be delivered to a consumer at least once, but may be delivered more than once under specific failure conditions (a worker crashes after processing a job but before acknowledging it, the acknowledgment packet is lost, the broker times out and redelivers). + +Every distributed system runs on at-least-once delivery. Idempotency is the only safe response. The practical engineering approach is not to chase exactly-once at the broker level but to make consumers idempotent, so a duplicate delivery changes nothing. Systems like Temporal achieve exactly-once execution of orchestration logic by building on top of an at-least-once substrate. + +An idempotent job is one where running it twice produces the same outcome as running it once. For email jobs, this means checking whether the email has already been sent using a database record or an idempotency key, before sending it, and returning successfully without sending again if it has. For payment capture jobs, this means passing the payment provider an idempotency key that deduplicate the charge on their end even if the request is retried. For report generation jobs, this means checking whether a report for the same parameters already exists before starting computation. + +The idempotency key pattern, generating a unique, stable identifier for a job at enqueue time and passing it through to every operation the job performs, is the implementation pattern that makes at-least-once delivery safe in practice. The key is generated once from the job parameters and stored alongside the job; if the job runs again, every operation that checks the key finds the existing result and returns it without performing the side effect again. + +## Retry Logic: Exponential Backoff, Jitter, and Dead-Letter Queues + +A job that fails needs a retry strategy, and the retry strategy is what determines whether a transient failure (a momentarily unavailable dependency) is handled gracefully or cascades into a sustained problem that overwhelms the dependency it is retrying against. + +Exponential backoff is the standard retry timing strategy: the first retry happens after a short interval, the second after a longer interval, the third after a longer interval still, with each retry waiting exponentially longer than the previous one. This prevents a flood of simultaneous retries from hammering a recovering service. Jitter, adding a small random offset to each retry delay, prevents the thundering herd problem where many jobs that failed at the same time retry at the same time, producing the same overload condition that caused the failure. + +![Organization Collaboration Platforms](https://techgenyz.com/wp-content/uploads/2026/09/Organization-1024x576.webp) + +Dead-letter queues are the diagnostic instrument that makes retry systems observable. When a job exhausts its retry limit without succeeding, it moves to the dead-letter queue. The dead-letter queue is where operations should watch, as every job there represents a failure that requires investigation, whether a bug in the job logic, a permanent dependency failure, or data that the job cannot process. A dead-letter queue that is not monitored is not meaningfully better than silent job dropping, for the jobs accumulate unseen and the underlying failure is never diagnosed. + +## The Transactional Outbox: Guaranteeing a Job Is Enqueued When Its Data Is Committed + +One of the subtler reliability gaps in background job systems is the window between writing data to the database and enqueuing the corresponding job. If an application writes a user record and then enqueues a welcome email job, but crashes between the write and the enqueue, the user exists in the database but never receives their welcome email. If the application enqueues the job first and then writes the user record, but crashes between the enqueue and the write, the job runs against data that does not yet exist. + +The transactional outbox pattern solves this: the job description is written to an outbox table in the same [database transaction](https://techgenyz.com/x-money-savings-metal-card-6-percent-apy/) as the data change, guaranteeing that either both succeed or neither does. A separate process reads the outbox table and publishes the messages to the queue, exactly when the data is committed, not before and not after. This pattern eliminates the consistency gap that exists between database writes and queue publishes in applications that treat them as separate operations. + +## Selecting the Right Queue for the Workload + +BullMQ plus managed Redis remains a practical stack for Node.js teams operating their own infrastructure; lightweight enough for small teams but feature-rich enough for retries, delayed execution, concurrency, and observability, with a dashboard for job visibility. For AWS-native teams, SQS provides queue primitives with worker services on ECS, Lambda, or Kubernetes, with EventBridge for routing and Step Functions for complex workflows. For teams on Google Cloud, Cloud Tasks with Cloud Run workers fits event-driven, HTTP-dispatch models. + +Celery with Redis or RabbitMQ as the broker remains the standard choice for Python teams; mature, well-documented, and compatible with every Python web framework. Sidekiq is the standard for Ruby on Rails teams, offering high performance backed by Redis. For Java and JVM-based teams, Spring Batch and Quartz Scheduler handle the enterprise job scheduling use case. + +Long-running workflows and observability matter more than queue purity. Trigger.dev, Inngest, Hatchet, and Upstash Workflow deserve evaluation before building custom orchestration layers; they provide durable execution, step-level retry logic, and built-in observability for complex multi-step jobs that a basic queue does not handle well. The selection criterion that matters most is not which tool has the most features but which one the team can operate reliably and which one makes the jobs observable enough to diagnose failures when they occur. + +## Observability: The Layer That Background Jobs Most Commonly Lack + +Background jobs are hard to observe precisely because they are asynchronous: the request that enqueued a job is long gone by the time the work runs. The job may hop through several queues before completing, and without deliberate instrumentation, a failed job is invisible until a user notices the missing email or the undelivered report. + +![windows 11 beta preview Windows 11 Beta Preview](https://techgenyz.com/wp-content/uploads/2023/12/windows-11-beta-preview-1024x576.jpg) + +The minimum viable observability setup for a background job system includes: a queue dashboard that shows pending job count, processing rate, and error rate per job type; structured log output from workers that includes the job ID, job type, attempt number, duration, and outcome for every execution; alerts on dead-letter queue depth that fire when jobs begin accumulating without being processed; and queue depth monitoring that fires when the backlog grows beyond the threshold at which workers can clear it within a defined time window. + +Each of these is achievable with standard tooling (BullMQ’s built-in dashboard, structured JSON logging in worker processes, and monitoring platform alerts), and together they close the visibility gap that makes background job failures hard to diagnose in systems that were instrumented as an afterthought. + +## What to Watch Next + +The direction of background job systems in 2026 is toward durable execution frameworks that move beyond simple queues to provide step-level retry, human approval gates, and observable multi-step workflows. The use case driving this evolution is AI agent pipelines: long-running, multi-step operations that combine LLM calls, tool invocations, and data operations in sequences that may run for minutes or hours and require reliable state persistence across every step. + +For backend teams building or improving their background job infrastructure today, the practical starting point is unchanged from what it has been for years: use a queue-backed architecture with an independent worker process, make every job idempotent, implement exponential backoff with jitter, watch the dead-letter queue, and add observability before the first production incident makes its absence visible. The tools have matured, the patterns are well-established, and the teams that get this right find that their backend systems become more reliable and more debuggable at the same time, which is the outcome that good background job architecture reliably delivers. diff --git a/sreweekly/markdown/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.md b/sreweekly/markdown/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.md new file mode 100644 index 00000000..e09d4077 --- /dev/null +++ b/sreweekly/markdown/536/04-r-sre-can-automated-root-cause-analysis-reliably-identify-production-i.md @@ -0,0 +1,15 @@ +# r/sre: Can automated root cause analysis reliably identify production issues? + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: u/Acrobatic_Refuse8100 and many others — reddit +- **链接**: https://www.reddit.com/r/sre/comments/1wguk7p/can_automated_root_cause_analysis_reliably/ + +## 简介 + +This question kicked off a great comment section: + +> Has anyone gotten an automated RCA setup to actually nail root cause without a person doing the final synthesis, or is that still mostly aspirational marketing from vendors? + +## 正文 + +> ⚠️ 抓取失败:trafilatura returned empty diff --git a/sreweekly/markdown/536/05-quick-thoughts-on-github-actions-aug-26-incident.md b/sreweekly/markdown/536/05-quick-thoughts-on-github-actions-aug-26-incident.md new file mode 100644 index 00000000..4eccfe10 --- /dev/null +++ b/sreweekly/markdown/536/05-quick-thoughts-on-github-actions-aug-26-incident.md @@ -0,0 +1,69 @@ +# Quick thoughts on GitHub Actions Aug 26 incident + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Lorin Hochstein +- **链接**: https://surfingcomplexity.blog/2026/08/29/quick-thoughts-on-github-actions-aug-26-incident/ + +## 简介 + +Do you have a way to slow down traffic to your database during an incident? This one has a great explanation of why you need one. + +## 正文 + +Last week, [GitHub Actions experienced another incident](https://www.githubstatus.com/incidents/y1t7p9fzrlj2). As is typical of a GitHub public writeup, it was published very soon after the incident, but there also aren’t isn’t a lot of detail. But let’s see what we info we can glean from it. + +## Database saturation + +The first thing I noticed is that this incident is, once again, a saturation-related failure mode. Specifically, it was a database that was saturated due to write traffic. + +This impact was triggered by saturation of writes to the database primary used by the service processing triggers for Actions workflows. + + +As I mentioned in [my last blog post](https://surfingcomplexity.blog/2026/08/29/omnipresent-availability-risks-in-cloud-software/), database-related saturation issues are particularly pernicious, because they can be very difficult to recover from. + +## Multiple contributors, but not much detail + +The write-up mentions seven separate factors that contributed to the incident. + +- Growing peak daily load (this increased the writes to the database) +- An upstream issue in GitHub’s event processing infrastructure (?), which further increased the load +- Failing over from primary to replica did not lead to full recovery (?) +- Existing throttles were set ~10% too high, so they provided insufficient overload protection +- some jobs remained stuck in queued/waiting state after recovery (?) +- another issue that left some jobs left in a waiting-for-runner state after recovery +- a bug that left that some runs showing as queued even though they had already failed + +I annotated contributors with (?) where I felt the report really didn’t provide any details at all. The mention of the upstream issue references [a different GitHub incident](https://www.githubstatus.com/incidents/hcbtzksccj2f), but there are no details on that other incident page at all. It does say “A detailed root cause analysis will be shared as soon as it is available”, so perhaps we’ll get more details on this other issue in the next few days. + +What I’m most curious about, though, is what happened with the database failover. All we get in the write-up is this one line: + +*The primary was failed over, but the system did not fully recover.* + + +What happened here??? Did the newly promoted primary get overwhelmed the same way that the previous one did? Did something else go wrong? I wish there they went into a lot more detail on the particular failure mode. + +## Slowly nursing an overloaded database back to health + +On the plus side, the report does have some details on how they were able to mitigate. They throttled traffic to the database until it recovered, and then ramped the traffic back up slowly enough so that they didn’t knock it over again. Here’s the actual text: + +At 15:45 UTC, throttling combined with service restarts recovered the service’s core health. Those throttles were gradually raised between 15:54 and 17:22 to restore full webhook processing for Actions runs. This ramp was deliberately slow to ensure we did not re-overwhelm the system given our original throttling was now known to be incorrectly set. The queue of webhook events was fully burned down at 17:40 UTC. + + +Two things I want to note about this. First of all, this sort of recovery approach is something you are going to need to do some day when your own database gets overloaded (and, believe me, it’s going to happen). If you’re prepared for this, you’ll have access to a throttle knob that the responders can manually control so they can cut the traffic and then increase it. It’s not something you want to have to build during an incident. + +The second thing to note is that throttling means that you are deliberately cutting off access to the database for your users in order to bring it back up. This means that you will be temporarily increasing user pain in order to recover the system. This sucks, but it’s a decision you sometimes have to make during an incident: that you actually have to deliberately make the system behave *worse* from the user’s perspective in order to get it back into a healthy state. Now, if you have the ability of doing QoS-style throttling where you can selectively block the less important requests, then you might be able to reduce the amount of pain. But, once again, that’s something you need to have built into your system in advance. + +## Irony: fix was already in-flight when the incident struck + +This line in the write-up broke my heart a little (emphasis mine): + +Several changes to improve the general scalability of this part of Actions **were already complete and deploying to production**. Rollout of those changes will be complete within the next 24 hours. + + +They were already working on reducing the likelihood of an incident like this, but it bit them before they could finish rolling out the improvements. That’s really just bad luck. + +## Another GitHub incident, another limit hit + +Finally, we continue to see GitHub hitting one limit after another as they experience continued growth. There are just so many different limits within a system like this. I won’t be surprised if I’m soon reading up on yet another saturation-related GitHub incident. + +## One thought on “Quick thoughts on GitHub Actions Aug 26 incident” diff --git a/sreweekly/markdown/536/06-your-agent-is-not-production-ready-until-it-can-recover.md b/sreweekly/markdown/536/06-your-agent-is-not-production-ready-until-it-can-recover.md new file mode 100644 index 00000000..12d5a731 --- /dev/null +++ b/sreweekly/markdown/536/06-your-agent-is-not-production-ready-until-it-can-recover.md @@ -0,0 +1,146 @@ +# Your agent is not production-ready until it can recover + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Arpio +- **链接**: https://arpio.io/https-arpio-io-your-agent-is-not-prodution-ready-until-it-can-recover/ + +## 简介 + +Through a fictitious case study, this article shows how to go about building a reliable service with an agentic component. + +FYI the last ~quarter or so is a sales pitch, but the preceding majority of the article isn’t. + +## 正文 + +*When an agent becomes the front door to your support organization, it stops being an experiment. It is production infrastructure with a customer-facing SLA, and it fails in ways your existing runbooks have never seen.* + +Most teams get the build right. They ship the agent, wire up retrieval, add guardrails, and watch the traces. Then someone asks what happens if the region hosting it goes away, and the room gets quiet. The answer is usually a mix of “we have Terraform” and “we would rebuild it,” which is not a recovery plan with a number attached to it. + +We are going to walk you through a fictitious, but realistic scenario with Digitata. Digitata is a B2C service provider and they want to jump on the agentic wave by adding a virtual customer service agent that is powered by Amazon Bedrock. + +When you think of building an agentic application, you need to consider resilience for the agent equal to the data and infrastructure. To put this in context, we’ll walk through a fictional case with the Digitata customer service agent. + +## **The Digitata customer service agent** + +Meet Digitata, an enterprise B2C company with an active customer service team. Many of the customer service requests are product questions. In order to free time for human agents, Digitata has built an agentic interface for customers to address these queries. The agent will replace the first tier of the ticket queue, and greatly improve resolution time. + + +Digitata built their agentic application using Bedrock AgentCore along with other supporting Bedrock services, it’s been tested in development and QA environments, and we are now ready to ship it to production. + +![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-1.png) + + +#### **How the components relate:** + + +| **AgentCore Runtime** | Hosts the agent itself. The orchestration code ships as a container image in Amazon ECR, and the runtime executes it under a scoped execution role. | +| **Bedrock Knowledge Base** | Grounds answers in Digitata’s product documentation. Docs land in an S3 data source; the resulting embeddings live in an OpenSearch Serverless vector collection, and answers cite the source page. | +| **Bedrock Guardrails** | Keeps the agent inside its job. Denied topics stop it answering general questions, and content filters screen what comes back before a customer sees it. | +| **AgentCore Memory** | Carries context across sessions, so a customer who returns tomorrow does not restate their account, their plan, and the problem they were already halfway through. | +| **Supporting AWS resources** | IAM execution roles, VPC and security group configuration, secrets, and the CloudWatch alarms and traces that make the whole thing observable. | + +## **The production readiness checklist** + +With their agent built in a sandbox with all of the needed Amazon Bedrock resources, the next step for the Digitata team was getting it to production. This process entails much more than a demo. The Digitata team created a production-ready checklist that the agents must pass to meet production-readiness: + +**Behavior and Quality** + +- Guardrail policies pinned to a published version, with adversarial prompts running in CI +- Scope and refusal evals gating every deploy +- A golden set of documentation questions re-run after each ingestion + +**Operations** + +- Alarms on failed ingestion, guardrail intervention rate, tool errors, and model throttling +- Per-session traces, plus sampled human review of real conversations +- Per-session token ceilings and a monthly budget alarm + +**Disaster Recovery (1-hour RTO)** + +- RTO and RPO agreed with the business and written down +- Every component in scope: runtime image, agent configuration, guardrails, knowledge base, vector index, memory, roles, network +- Recovery points in a separate account that production credentials cannot reach or delete +- A drill on a schedule that produces a working agent answering real questions + +## **Building the DR plan by hand** + +When they got to the final requirement of the production-ready checklist, Digitata hit a roadblock: they hadn’t incorporated their Amazon Bedrock services into their DR plan. “It is all in Terraform” is a good starting position, but an incomplete one. Terraform recreates resources; it does not carry the data inside them, and several of these components hold state that has no export button. Their first instinct was to build the disaster recovery plan by hand. + +Digitata began to outline their recovery component by component: + +| **Component** | **What recovery requires** | +| **Runtime container image** | The image sits in one region’s ECR registry. A runtime in the recovery region cannot pull it. You need cross-region replication and a guarantee that the exact tag production was running is present, not just the latest build. | +| **Agent configuration** | Model selection, system prompt, tool and MCP wiring, and session settings live in the control plane. Anything a developer changed in the console and never backported to code does not exist in your recovery environment. | +| **Guardrails** | Guardrails are regional, versioned resources referenced by ID. Recreate them in the recovery region and the IDs differ, so every reference has to be resolved at deploy time rather than hardcoded. | +| **Knowledge base & S3 source** | S3 replication handles the documents. The knowledge base resource, its embedding model configuration, and its data source binding all have to be recreated and re-associated. | +| **OpenSearch Serverless vectors** | Vectors do not travel with the S3 bucket. Either you re-ingest the whole corpus in the recovery region, which takes as long as it takes and is usually the long pole in your RTO, or you run and pay for a second continuously synced collection. | +| **AgentCore Memory** | Memory is the accumulated value of every customer conversation, and there is no bucket you can point a nightly job at. Getting it out means building and owning a streaming pipeline. | +| **IAM, network, secrets** | Role ARNs, VPC IDs, subnet IDs, and secret ARNs are account and region specific. Every one has to be parameterized, and a single hardcoded ARN fails the deploy at the worst possible moment. | + +## **Building the recovery path yourself** + +Digitata has a strong infrastructure and operations team; and they weren’t about to take any shortcuts on an initiative that was client-facing. The identified five workstreams to deliver a tested one-hour recovery. + +1. **Refactor the IaC to be account and region agnostic.** Every account ID, region, ARN, and resource name becomes a variable. Provider aliases, separate state, and a second set of tfvars. Then the harder part: keeping the recovery configuration honest as the application changes weekly. +2. **Build a memory backup pipeline.** Stream memory events to Kinesis, and replicate them to a copy of the memory in the recovery environment. This is a new production data pipeline, with its own monitoring, its own failure modes, and its own on-call surface. +3. **Replicate the documentation and the image.** S3 cross-region replication for the knowledge base data source, ECR replication rules for the runtime image, and a decision on the vector store: pay to keep a warm collection synced, or accept a re-ingestion window inside your RTO. +4. **Write and script the recovery runbook.** Ordering matters: knowledge base before agent, guardrail version resolved before the runtime starts, memory reloaded before traffic arrives. The parts that cannot be automated become manual steps, and manual steps are where an hour turns into an afternoon. +5. **Test it, repeatedly.** An untested recovery plan is a hypothesis. Each drill means standing up the environment, validating that the agent answers grounded questions with memory intact, and tearing it down without disturbing production. + +Digitata realized that the initial build is finite work, but the ongoing cost erodes plans: every new tool the agent gains, every guardrail policy change, every VPC adjustment has to land in the recovery configuration too, or your tested plan quietly stops matching production. When the disaster recovery process doesn’t match, Digitata’s ability to respond to an outage event would be broken. + +## **Ransomware Protection** + +Digitata’s team is ready for an outage. They built up their DR plan that accounts for changes to the agents and they are ready in case there are any disruptions to the underlying resources that support not only their agent, but also their cloud application. However, there is one aspect of recovery that they missed: a cyber attack. + +Being cyber resilient is similar to disaster resilience, but there is some nuance. Replication is designed to propagate changes faithfully, which means it propagates corrupted container images or deleted memories just as faithfully. + +Recovering from a cyber event needs something replication cannot give you: historical recovery points an attacker with production credentials cannot reach, held in an isolated account, plus somewhere clean to validate that the threat is gone before anything serves traffic again. + +While considering Cyber resilience, Digitata realized they had a big challenge keeping up with the pace of change with their new agents while meeting the resilience requirements set forth by the risk and compliance team. + +## **The same result, in minutes** + +Digitata turned to Arpio because only Arpio protects Amazon Bedrock, including AgentCore runtimes and memory, knowledge bases, and guardrails, alongside the rest of the AWS resources the application depends on. There is no pipeline to build and no recovery configuration to maintain in parallel with production. With Arpio, resilience can be set up in four steps. + +### **Step 1 — Point Arpio at the source environment** + +Connect the production account and the recovery account, then scan. Arpio inventories what is running, including the agent runtime, its guardrails, its knowledge base and vector store, and its memory. + +### **![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-2.webp)Step 2 — Let dependency detection build the protection scope** + +![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-2.webp) Step 2 — Let dependency detection build the protection scope + +Select the application and Arpio follows its dependencies outward: the ECR image the runtime pulls, the S3 data source behind the knowledge base, the IAM roles, the network. + +### **![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-3.png)Step 3 — Continuous, isolated recovery points** + +![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-3.png) Step 3 — Continuous, isolated recovery points + +Arpio syncs the whole scope into the recovery account on a schedule, supporting a 15-minute RPO for this application. Recovery points are held outside production’s reach, so a compromise of the production account does not take the backups with it. + +### **![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-4.png)Step 4 — Test on demand, then recover in one click** + +![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-4.png) Step 4 — Test on demand, then recover in one click + +Run a test into an isolated sandbox whenever you want, without touching production, and confirm the agent answers grounded questions with its memory intact. When it counts, the same automation runs for real: an RTO of 15 minutes for this application, well inside the one-hour target. + +## **![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-5.png)Digitata’s Result** + +![](https://arpio.io/wp-content/uploads/2026/09/AgentCore-Tech-Blog-5.png) Digitata’s Result + +After a side-by-side comparison, Digitata’s I&O team realized that providing a resilient agentic application added a lot of unforeseen scope to ensure it was ready to meet the compliance and risk teams’ resilience requirements. They chose Arpio because the platform not only understood their full AWS environment, but also understood their agents as well. This ensures that their application can remain resilient in the face of outages, disasters, and even a cyber attack. + + +| | **Built by hand** | **With Arpio** | +| **Time to first protection** | Weeks of platform work across five workstreams | Minutes, in the console | +| **Agent memory** | A streaming pipeline you build, run, and monitor | Covered in scope | +| **Vector store** | Re-ingest during the outage, or pay for a warm second collection | Recovered with the application | +| **Keeping up with change** | Manual, every time the application changes | Rescanned continuously | +| **Testing** | A scheduled project with production risk | On demand, isolated from production | +| **Ransomware** | Replication propagates the damage | Historical points in an isolated account | + + +## **See it against your own agent** + +Bring the architecture you are about to ship and we will scan it, show you the dependencies, and run a recovery test with you. diff --git a/sreweekly/markdown/536/07-rollback-does-not-erase-distributed-memory.md b/sreweekly/markdown/536/07-rollback-does-not-erase-distributed-memory.md new file mode 100644 index 00000000..74a46da3 --- /dev/null +++ b/sreweekly/markdown/536/07-rollback-does-not-erase-distributed-memory.md @@ -0,0 +1,95 @@ +# Rollback Does Not Erase Distributed Memory + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Balu Kambala +- **链接**: https://storiesfromtheedge.substack.com/p/rollback-does-not-erase-distributed + +## 简介 + +Rollback sounds great in theory, but it doesn’t always work. The CircleCI example really hits hard. + +This reminds me of a classic article from the now-defunct company Skyliner, You Can’t Have a Rollback Button. + +## 正文 + +The rollback finished successfully. The deployment dashboard showed 100% of nodes running the previous build. The service confirmed the old configuration was active. + +Yet customers were still seeing failures. + +In a distributed system, rolling back code can create a false sense of safety. Reverting the change does not revert every component that has already observed the change. Recursive DNS resolvers and other caches may retain the new state until their TTLs expire. A database may contain records written in a format the previous application cannot read. Queues may still hold work created under the failed version. + +Your servers are running version A, but they are running inside an environment mutated by version B.*A rollback changes what the source of truth says now. However, it does not erase what the rest of the system has already learned.* + +This is why distributed recovery is rarely a single event. Some customers recover immediately. Others recover when caches expire, connections restart, queues drain, or incompatible data is repaired. + +So after a rollback, the important question is not only "Is the old version running?" but also "Which parts of the system still retain state from the new version?" + +**The Takeaway:** Deploying Version 40 over Version 41 changes the code, but not the environment Version 41 mutated. Recovery begins only when the distributed memory such as DNS caches, client pools, and databases is cleared or reconciled. + +Slack’s DNSSEC rollout demonstrates what happens when that memory lives in infrastructure you do not own. + +## The Slack DNSSEC rollback + +During its [DNSSEC rollout](https://slack.engineering/what-happened-during-slacks-dnssec-rollout) for [slack.com](http://slack.com) Slack observed some DNS resolvers returning unexpected NODATA responses. The team decided to roll back. + +DNSSEC depends on records stored in two places. The ‘.com’ parent zone publishes a DS record telling resolvers that `slack.com` must provide cryptographic proof. Slack’s authoritative zone publishes the matching DNSKEY and RRSIG records. + +Slack removed the DS record from ‘.com’ through its registrar and later disabled signing on its authoritative servers. + +The authoritative configuration looked old again. The resolver caches did not. + +Some recursive resolvers had cached the DS record for up to 24 hours. They still expected signed answers from Slack. When the signing material disappeared, validation failed and those resolvers returned SERVFAIL. + +**The rollback made the system worse.** Slack had changed the authoritative state, but it could not force resolver caches to forget the DS record. + +Slack asked major public DNS providers to flush their caches. Large providers recovered quickly. Other resolvers continued failing until their cached DS records expired. + +As shown below, the rollback completed quickly. Recovery followed a long tail as resolver caches expired on different schedules. + +![](https://substackcdn.com/image/fetch/$s_!gHJA!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F123af348-cb0e-435b-8896-8403d4e1dc1a_2016x864.png) + +Slack’s retained state would eventually disappear as resolver caches expired. Database state is harder: records written by the new version may remain indefinitely. + +## **The database does not roll back with the code** + +CircleCI encountered the [incident](https://discuss.circleci.com/t/incident-report-november-8-2021-jobs-stuck-in-a-not-running-state/41890) in November 2021. A deployment changed the type of a field in its job-distribution database. The new version could not process older jobs, so CircleCI rolled it back. The old version then could not process jobs written during the deployment. + +The database now contained two representations, but neither application version understood both. + +Engineers recovered by deploying a compatibility change that ignored the field, then draining the accumulated queues. + +The sequence below shows why neither application version was a safe recovery point. Version B rejected older records, version A rejected records written by version B, and recovery required code that could handle both formats. + +![](https://substackcdn.com/image/fetch/$s_!8N05!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F21c2703a-5490-4d00-897e-feda88a0fdd7_2304x896.png) + +CircleCI had rolled back the code, but recovery required a compatibility build. Once a new version has written a new representation, the old binary may no longer be a safe recovery target. + +## **Rollback is not recovery** + +A dashboard can truthfully report that version 41 was replaced by version 40. That does not mean the system is behaving as version 40 did before the deployment. + +During an incident, I separate three stages: + +1. **The source was rolled back.** The central configuration returned to the old version. + +2. **Components applied the rollback.** Systems using that configuration fetched and applied the old version. + +3. **The system recovered.** Data and actions created by the new version were made compatible, reversed, or repaired. + +Teams often prove the first stage and assume the third. Slack and CircleCI both completed the first stage before reaching the third. Sometimes the safest way to close that gap is to move forward. + +## **Why roll-forward can be safer** + +These incidents show that rollback is not always enough for recovery. Once the new version writes incompatible data or publishes state that other systems cache, returning to the old version can create another failure. + +CircleCI recovered by deploying a compatibility build that ignored the changed field. This allowed it to process jobs written by both versions. For Slack, a safer recovery would have kept the signing material available until cached DS records expired. + +The recovery decision should depend on the state already present in the system, not on how easy it is to run the rollback command. The delay between rollback and actual recovery often appears as a long tail in the error graph. + +## **Reading the recovery curve** + +Slack and CircleCI produced different recovery curves. Slack showed a sharp initial recovery followed by a long tail. CircleCI showed little change after rollback; recovery began only after a compatibility fix and continued as the queue drained. + +The curve cannot prove the cause, but it narrows the search. This is what I mean by incident geometry. A sharp recovery may point to a centralized fix. A long tail may indicate components recovering on independent clocks. Little or no improvement after rollback may indicate durable state that requires repair or reconciliation. + +I’ll go deeper into incident geometry—how user-impact shapes can lead us to architectural findings—in my talk, [The Geometry of Incidents: What User-Impact Shapes Reveal About Platform Architecture](https://www.wearedevelopers.com/events/world-congress-2026-north-america/sessions/1722-the-geometry-of), at WeAreDevelopers World Congress North America. If you’re attending, please stop by. I’d be glad to continue the discussion in person. diff --git a/sreweekly/markdown/536/08-the-architecture-of-neki.md b/sreweekly/markdown/536/08-the-architecture-of-neki.md new file mode 100644 index 00000000..6c0bb947 --- /dev/null +++ b/sreweekly/markdown/536/08-the-architecture-of-neki.md @@ -0,0 +1,119 @@ +# The architecture of Neki + +- **期号**: SRE Weekly Issue #536(2026-09-28) +- **作者**: Harshit Gangal — PlanetScaleThis article is published by this issue’s sponsor, but their sponsorship did not influence its inclusion in the newsletter. +- **链接**: https://planetscale.com/blog/the-architecture-of-neki + +## 简介 + +Yes, this is a walkthrough of a vendor’s product, but the architecture is genuinely interesting and it reads like an engineering explainer rather than a sales pitch. I especially liked the wrinkle where one shard has to be designated authoritative so that custom type OIDs stay consistent across the whole cluster. + +## 正文 + +Meet Neki: sharding for Postgres. Neki allows applications to connect to massive, sharded databases over a single connection string. This post takes apart the architecture from the bottom up, one piece at a time, starting with what's underneath all of it. + +## [Real Postgres](https://planetscale.com#real-postgres) + +Neki is built as a sharding and scaling solution for real Postgres. It's not a fork, nor a wire-compatible reimplementation, nor a MySQL sharding idea wearing a Postgres label. Neki uses ordinary PostgreSQL instances that store rows in Postgres data pages using MVCC, carry out transactions, and work as you would expect with `psql` and other Postgres drivers. Neki builds around those instances to let you shard them, scale them, and manage them as one database. + +Let's take a look: + +## [PostgresManager](https://planetscale.com#postgresmanager) + +Using vanilla Postgres means Neki needs a way to run and manage each instance. That includes starting and stopping Postgres, owning its data directory, and configuring replication so a new instance can join a shard. **PostgresManager** handles this coordination, running as the first process in the Postgres container and managing the `postgres` process directly. + +## [Sidecar](https://planetscale.com#sidecar) + +Postgres uses a separate backend process for each connection and limits how many can be open at once. Neki’s **Sidecar** sits in front of each instance and pools connections, letting many client connections share fewer Postgres backends. + +The Router, which is the component that accepts external client connections, communicates with the Postgres nodes via these Sidecars. + +It also reports each Postgres instance's health and whether it is a primary or replica, so the rest of the cluster knows whether it can receive write queries. + +The pool doesn't treat every connection the same way. The length of time a connection is checked out for use varies depending on what it's being used for. A multi-statement transaction holds on to its connection until `commit` or `rollback`. A session-scoped advisory lock needs a connection of its own, because the lock has to outlive whatever transaction is open at the time and can't share that connection. Everything else checks a connection out and hands it back the moment the statement finishes. + +The Sidecar knows which of the three to use because the Router sends the necessary information with the query: autocommit, an open transaction, or a session that has to stay on one backend. + +## [Shards](https://planetscale.com#shards) + +Each Postgres instance gets its own Sidecar and PostgresManager pair. Real deployments need more than one instance: a primary and its replicas. Neki calls that group a **shard**, the unit it splits data across. It's always advised to run a shard with a primary and 2+ replicas for high availability, as well as for additional read query capacity. + +A shard is considered one Postgres cluster. Its replicas are physical copies of the primary, so they share a catalog and the same object identifiers. + +Object Identifiers (OIDs) are how Postgres tracks objects internally, rather than by name. A client reads a column’s type OID off the wire to interpret its bytes and may cache that OID for later re-use. A custom type therefore needs to carry the same OID no matter which shard answers the query. Independent shards can assign that type different OIDs, so Neki designates one shard in the entire Neki cluster as the **authoritative shard**. This shard is the source of truth for translating custom type OIDs in responses from other shards to match. It ensures OIDs are consistent across the many shards of the Neki cluster. + +The authoritative shard's Sidecar also watches for schema changes and reports them to the Routers. This keeps the Routers' view of the schema current when a table is renamed or a column is dropped. + +## [Admin](https://planetscale.com#admin) + +In a distributed system, instances can fail independently while the rest of the system lives on. Neki is no different. A primary or replica can go down at any moment while its fellow instances on the shard are healthy. The **Admin**'s job is to detect failures, promote a replica, and maintain each shard’s durability policy. + +It health-checks every Sidecar, tracks replication lag for each replica, and decides when a shard needs a new primary. When a primary goes down, it coordinates an emergency failover, promoting a replica to take its place. It can also coordinate a planned switchover, which are needed for intentional node resizes and version upgrades. In both situations, Admin uses `pg_rewind` to bring diverged instances onto the new primary’s timeline, copying only the data that changed since the timelines diverged. + +Each shard has a durability policy that determines when a commit is acknowledged: + +- **Async:** The primary acknowledges the commit without waiting for a replica. +- **Sync:** The primary waits for a replica to confirm the commit, protecting against the loss of a single node. +- **Cross-zone sync:** The primary waits for confirmation from a replica in another availability zone, protecting against the loss of the primary’s zone. + +Postgres enforces whichever one is configured, using its own synchronous replication machinery. The Admin keeps that configuration correct as replicas join or leave shards, or a failover moves the primary to a different zone. + +Much of Admin’s work, however, doesn’t involve changing the primary. It repoints replicas to the correct replication source and corrects roles when Postgres and the topology disagree. + +## [Operator](https://planetscale.com#operator) + +Neki’s components need to be deployed, updated, and replaced when their machines fail. Neki is built Kubernetes-first, and the **Operator** manages this full lifecycle. + +The Operator models a cluster as a hierarchy. A cluster owns routers and shards, and each shard owns the pods running its Postgres instances and Sidecars. When the Neki cluster configuration changes, the Operator works out which pods need to be created, updated, or removed. + +How it replaces an instance depends on whether that instance is still running. For a live instance, the Operator builds a replacement and confirms it has caught up before deleting the old one. If a node fails and loses its ephemeral storage, the Operator rebuilds the lost instance from scratch once its safety checks pass. + +Admin and the Router handle the database side of those disruptions. Admin coordinates a switchover for planned primary replacements or a failover when a primary goes down. The Router can buffer queries that are safe to retry while a healthy primary becomes available. + +## [Router](https://planetscale.com#router) + +We've talked a lot about how the Neki cluster operates and handles failure internally. What we've yet to dive into is how applications use the thing! + +The **Router** is the entry point for clients connecting to a Neki cluster, presenting a single Postgres wire-protocol endpoint to connect to a (potentially) massive sharded database. Applications use Postgres drivers to send SQL and open transactions without managing connections to individual shards. + +Authentication and role checks are done as if it were the Postgres instance itself, and the protocol's own extended-query flow and prepared-statement lifecycle are all built into the Router. + +Once a query arrives, the Router runs a Postgres-compatible parser against the authoritative shard's catalog, plans it against the current sharding layout, and sends it to whichever Sidecar needs to run it over gRPC. + +Not every query can run on a single shard. A join may need data from several shards or an aggregate may need to read from all of them. The **Router** coordinates that work as a [distributed query](https://planetscale.com/blog/what-is-a-neki-router). + +Whenever possible, it leaves the work to the Postgres instances. If both sides of a join are on the same shard, the Router sends the join to that shard. When a join needs to run across shards, the Router executes it itself, choosing between nested-loop, hash, and merge joins based on cost estimations. + +Note + +Read more about Routers, parsing, and sharded query planning in our other blog, [The lifecycle of a sharded Postgres query](https://planetscale.com/blog/the-lifecycle-of-a-sharded-postgres-query). + +Earlier, we covered how Admin promotes a new primary during a switchover or failover. If that happens, the Router can buffer queries, giving the Admin time to complete the handover. For queries that can safely be retried after failing against a primary, the Router buffers the query and waits, for a fixed time, for a healthy primary. Once a healthy primary is available, the Router releases queued queries gradually. + +## [Data Topology](https://planetscale.com#data-topology) + +Router, Sidecars, and Admin all need a consistent picture of which shards exist, what key ranges they own, and which tables are sharded at all. If the Router's copy is wrong, a query can land on the wrong shard. This is all specified with a [Data Topology](https://planetscale.com/blog/what-is-a-data-topology), and **etcd** holds the single, authoritative copy of it. When the Data Topology changes, the Router, Sidecars, and Admin pick up the updated configuration without a restart or manual synchronization. + +The Data Topology defines **shard groups**, named sets of physical shards, each owning a range of routing keys. Each table belongs to a shard group. **Shard indexes** specify the columns or expressions and the strategy used to turn row values into routing keys. Those keys determine which shard receives each row. + +## [Replicator](https://planetscale.com#replicator) + +As a database grows, its layout may need to change. Tables need to be imported, shards need to be split, and schemas need to change all while applications keep using the database. + +Neki's **Replicator** handles the data movement behind all such operations. It runs as a separate process colocated with a shard's Sidecar and Postgres. It is responsible for copying existing rows to new destinations, and also keeping the data current by decoding changes from a Postgres logical replication stream and applying them as SQL. + +Three workflows use the Replicator: + +- **MoveTables** relocates a set of tables, including imports from an external Postgres instance +- **Reshard** redistributes data across shard key ranges, allowing a shard to be split when it outgrows its capacity +- **OnlineDDL** changes a table's schema by building a shadow table alongside the original and keeping it current through the same change-data-capture pipeline MoveTables and Reshard use to relocate rows. A final rename swaps the new table into place. This supports changes such as repartitioning a table, alongside changes that would otherwise require a blocking operation. + +Once the data has been copied and the destination is caught up, the workflow switches from the original tables or shards to their replacements. This is the cutover. The Router uses the same buffering mechanism that handles primary changes for this step. It buffers queries during that switch and releases them afterward. + +Together, these components let Neki scale Postgres horizontally while presenting a single database to applications. + +## [Get started](https://planetscale.com#get-started) + +Neki is in Platform Preview right now. + +Start a [Neki](https://app.planetscale.com/new) cluster today: build on it from scratch, or import an existing Postgres database.