feat(sreweekly): 新增第 534 期 8 篇文章导入并更新 manifest
This commit is contained in:

File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because it is too large
Load Diff
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
50
sreweekly/articles/534/index.json
Normal file
50
sreweekly/articles/534/index.json
Normal file
@@ -0,0 +1,50 @@
|
||||
[
|
||||
{
|
||||
"idx": 1,
|
||||
"url": "https://www.sylvainkalache.com/blog/ai-handles-incidents-engineers-lose-touch-with-their-systems",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 2,
|
||||
"url": "https://surfingcomplexity.blog/2026/08/18/tough-days-at-github-a-continuing-series/",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 3,
|
||||
"url": "https://greatcircle.com/blog/2026/08/18/how-senior-leaders-disrupt-incidents-by-showing-up/",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 4,
|
||||
"url": "https://bluetriangle.com/blog/empowering-retail-excellence-how-lowes-sre-team-is-driving-reliability-through-hyper-automation-and-unified-platforms",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 5,
|
||||
"url": "https://hackernoon.com/before-you-automate-a-decision-define-its-blast-radius",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 6,
|
||||
"url": "https://www.gremlin.com/blog/managing-kubernetes-node-drains-with-pod-disruption-budgets",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 7,
|
||||
"url": "https://www.checklyhq.com/blog/agentic-rewrite-nodejs-to-go",
|
||||
"ok": true,
|
||||
"error": null
|
||||
},
|
||||
{
|
||||
"idx": 8,
|
||||
"url": "https://www.uptimelabs.io/articles/supporting-new-responders",
|
||||
"ok": true,
|
||||
"error": null
|
||||
}
|
||||
]
|
||||
@@ -7996,9 +7996,12 @@
|
||||
"pub_date": "2026-09-14",
|
||||
"html_file": "html/534-2026-09-14.html",
|
||||
"fetched_at": "2026-09-14T19:02:12",
|
||||
"extracted": false,
|
||||
"article_count": 0,
|
||||
"markdown_dir": null
|
||||
"extracted": true,
|
||||
"article_count": 8,
|
||||
"markdown_dir": "markdown/534",
|
||||
"extracted_at": "2026-09-25T13:18:58",
|
||||
"articles_fetched": 8,
|
||||
"articles_failed": 0
|
||||
},
|
||||
"535": {
|
||||
"id": "535",
|
||||
|
||||
@@ -0,0 +1,91 @@
|
||||
# AI handles incidents, engineers lose touch with their systems
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Sylvain Kalache
|
||||
- **链接**: https://www.sylvainkalache.com/blog/ai-handles-incidents-engineers-lose-touch-with-their-systems
|
||||
|
||||
## 简介
|
||||
|
||||
> The better these tools become at resolving routine incidents, the less practice human responders will get. And when an ambiguous, high-severity incident comes in that automation cannot solve, responding engineers will be in trouble.
|
||||
|
||||
I love the concept of comprehension debt described in this article.
|
||||
|
||||
## 正文
|
||||
|
||||
[Back to the blog](https://www.sylvainkalache.com/blog)
|
||||
|
||||
# AI handles incidents, engineers lose touch with their systems
|
||||
|
||||
[Discussed on Hacker News418 points](https://news.ycombinator.com/item?id=49574167)
|
||||
|
||||
When I was an SRE at LinkedIn, back in 2012, I designed a system that could heal itself and learn from previous incidents. AI capabilities were nowhere near what we have today, and that remained a prototype, but this is now a reality.
|
||||
|
||||
These tools do it all: inspect alerts, form hypotheses, query telemetry, correlate recent deployments, and even implement the fix themselves. As much as I love to see it, I have a major concern: we are losing touch with our systems.
|
||||
|
||||
The better these tools become at resolving routine incidents, the less practice human responders will get. And when an ambiguous, high-severity incident comes in that automation cannot solve, responding engineers will be in trouble.
|
||||
|
||||
## [Automation leaves humans with the hardest incidents](https://www.sylvainkalache.com#automation-leaves-humans-with-the-hardest-incidents)
|
||||
|
||||
These AI-assisted incident response tools, more commonly called “AI SREs” – [a term I don’t particularly like](https://rootly.com/blog/borrowed-gravity-words-worth-changing) – are fantastic in many ways. They feel especially magical when they handle a routine incident at night and you don’t have to wake up for a capacity issue.
|
||||
|
||||
The problem is that routine incidents are also how responders “safely” develop an intuition for how their systems behave and fail. When AI runs into a hard, never-seen-before incident it cannot solve, engineers will have to take over with less practice than they would have had before.
|
||||
|
||||
Human-factors researcher Lisanne Bainbridge described this paradox in her famous 1983 paper, The Ironies of Automation. She explained that automation reduces operators’ opportunities to practice routine work while leaving them responsible for new and abnormal situations. She argues that, therefore, operators need to be more skilled and receive even more training than before automation.
|
||||
|
||||
In the years to come, I predict that the average MTTR for most incidents will go down – thanks to AI-assisted incident response – but that the resolution time will shoot up for complex incidents because incident responders lost touch with their system and are struggling to investigate.
|
||||
|
||||
## [Aviation trains pilots for rare failures](https://www.sylvainkalache.com#aviation-trains-pilots-for-rare-failures)
|
||||
|
||||
We can look at the aviation industry for inspiration.
|
||||
|
||||
Plane automation handles much of the flying, but pilots remain responsible for situations that automation cannot manage: engine failures, unreliable instruments, rejected takeoffs, stalls, and other abnormal conditions.
|
||||
|
||||
These events are extremely rare. Modern turbine engines, for example, experience fewer than one in-flight shutdown per 100,000 engine flight hours. In other words, that is rare enough that a commercial pilot may complete an entire career without experiencing one outside a simulator.
|
||||
|
||||
But when a failure occurs, pilots must react quickly and correctly. For example, on [TransAsia Airways Flight 235](https://en.wikipedia.org/wiki/TransAsia_Airways_Flight_235), the right engine’s propeller autofeathered shortly after takeoff. And while the aircraft was designed to continue flying on its left engine, the crew misidentified the problem. The aircraft stalled and crashed only 117 seconds after the first warning.
|
||||
|
||||
Airline pilots regularly return to simulators to rehearse rare emergencies. Under US FAA rules, captains must complete recurrent training or a proficiency check every six months, including scenarios such as an engine failure during takeoff.
|
||||
|
||||
While most software incidents do not threaten lives, that is no reason not to perfect our craft. Turns out the technology that created the issue can also help close it.
|
||||
|
||||
## [The software industry needs incident simulators](https://www.sylvainkalache.com#the-software-industry-needs-incident-simulators)
|
||||
|
||||
At [Rootly](https://rootly.com), an incident management company where I work, we partnered with [Uptime Labs](https://www.uptimelabs.io) to apply this idea through realistic incident simulations. Engineers take the incident commander’s seat during a simulated e-commerce outage, using observability tools while coordinating with LLM-powered stakeholders in Slack.
|
||||
|
||||
The result feels real. You have to investigate what’s going wrong while keeping the response organized and dealing with the CEO and customer support. You get to practice the skills that matter during an incident: making sense of incomplete information, communicating clearly, coordinating people, and actually running the response.
|
||||
|
||||
## [AI can also help preserve these skills](https://www.sylvainkalache.com#ai-can-also-help-preserve-these-skills)
|
||||
|
||||
But what about using AI as a trainer? Responders can ask an agent to explain the steps it took, the signals it examined, and the evidence behind its diagnosis.
|
||||
|
||||
But explanation and observation are not substitutes for practice. You might pick up a few things from watching Serena Williams play, but you only learn tennis by getting on the court, and incident response is no different.
|
||||
|
||||
I spent more than half a decade of my career building a software engineering school around progressive education: learning by doing. It was in-person, but we had no teachers; students worked on projects instead of listening to lectures. When Dropbox told me graduates it hired were still too inexperienced at troubleshooting, I created projects that gave students broken infrastructure and required them to diagnose and repair it. For most hands-on skills, I believe hands-on education beats passive instruction by a lot.
|
||||
|
||||
## [Incident simulation should become part of on-call readiness](https://www.sylvainkalache.com#incident-simulation-should-become-part-of-on-call-readiness)
|
||||
|
||||
As LLMs do more of our work, engineering teams risk accumulating comprehension debt: a growing gap between how their systems work and how well responders understand them.
|
||||
|
||||
Engineers should regularly interact with the system they watch over, handle unfamiliar failures, practice working under pressure, and rehearse the coordination and communication required during a SEV0. Tabletop exercises and chaos engineering are nothing new, but practice has become even more important in the LLM era.
|
||||
|
||||
Researcher Bainbridge recommended giving operators regular hands-on control and using simulation to prevent their skills from decaying. That’s the irony of automation, the more successful it becomes, the less prepared humans may be for the moment it fails.
|
||||
|
||||
|
||||
|
||||
## [Sylvain Kalache](https://www.sylvainkalache.com/my-story)
|
||||
|
||||
AI Labs lead and DevRel at Rootly. Former LinkedIn SRE and co-founder of Holberton School.
|
||||
|
||||
## Related writing
|
||||
|
||||
[blogCan Claude fix itself? From no to maybe](https://www.sylvainkalache.com/blog/can-claude-fix-itself)
|
||||
|
||||
|
||||
|
||||
[blogAI Writes the Code, But Humans Can't Review It All. Now What?](https://www.sylvainkalache.com/blog/ai-writes-the-code-but-humans-cant-review-it-all)
|
||||
|
||||
|
||||
|
||||
[articleLLMs Broke the SRE Runbook. Now What?](https://www.sylvainkalache.com/content/llms-broke-the-sre-runbook-now-what)
|
||||
|
||||
|
||||
@@ -0,0 +1,113 @@
|
||||
# Tough days at GitHub, a continuing series
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2026/08/18/tough-days-at-github-a-continuing-series/
|
||||
|
||||
## 简介
|
||||
|
||||
Another excellent write-up by my favorite writer of incident write-up write-ups. I especially like that last section.
|
||||
|
||||
Lorin also wrote more the next day.
|
||||
|
||||
## 正文
|
||||
|
||||
It wasn’t even [a week ago](https://surfingcomplexity.blog/2026/08/13/github-has-another-tough-day/) when I wrote about a major GitHub incident. Yesterday, they had another big incident, which lasted almost eight hours. There’s a [public write-up](https://www.githubstatus.com/incidents/zkxwbgr0cnmx) already posted, which is surprisingly quick. While I’m personally [very impatient](https://www.githubstatus.com/incidents/zkxwbgr0cnmx) to read these, I also know that it takes time to collect and synthesize the information you need to do a good job with them. I wish they had posted this as a *preliminary write-up* and then done a more detailed write-up in a couple of weeks. That being said, let’s look at the write-up!
|
||||
|
||||
## Saturation strikes yet again
|
||||
|
||||
The immediate cause of the failure was network saturation on load balancers in Central US due to a new peak in traffic.
|
||||
|
||||
|
||||
The failure mode is yet another example of saturation, a topic I’ve written about [again and again](https://surfingcomplexity.blog/?s=saturation) on this blog. Heck, I even gave a [talk on saturation](https://surfingcomplexity.blog/2026/07/30/my-talk-from-the-software-should-work-conference/) a month ago.
|
||||
|
||||
Here’s the full paragraph on the failure mode:
|
||||
|
||||
The immediate cause of the failure was network saturation on load balancers in Central US due to a new peak in traffic. Originally this was caused by an Istio sidecar pod reaching its concurrency limits and failing to auto scale correctly because of a misconfigured policy that watched host service but not sidecar limits. One failure cascaded to more and eventually four HAProxy nodes exhausted their flow limits, degrading the gateway auth path and causing widespread authentication latency and failures. The problem was worsened by optimistic retry logic which overloaded internal load balancers.
|
||||
|
||||
|
||||
Based on this, it sounds like the failure cascade looked like:
|
||||
|
||||
*increase in external traffic → istio sidecars saturate (concurrency limits) → HAProxy nodes saturate (flow limits) → authentication requests fail*
|
||||
|
||||
An increase in load on the system saturated one of the components (istio sidecar), and that propagated to another component (HAProxy), whose saturation broke the auth flow.
|
||||
|
||||
I wish they had included an architectural diagram here, that showed the relationship between the load balancers, the service that whose Istio sidecar pod saturated, the gateway, and the services that handle auth requests. Also, the wording gives the impression that only a single sidecar pod that saturated (*an Istio sidecar pod*), which would be surprising, but I’m also not confident that this is what the authors intended.
|
||||
|
||||
## Diagnostic details: missing in action
|
||||
|
||||
The write-up doesn’t talk about the diagnostic work of the incident responders at all, which is a shame. I can’t tell from this write-up how difficult it was for them to figure out what was happening. There were auth failures, but it doesn’t sound like there was an increase in auth traffic per se, nor was the problem caused by recent changes to the auth system, which is where I would think to look first.
|
||||
|
||||
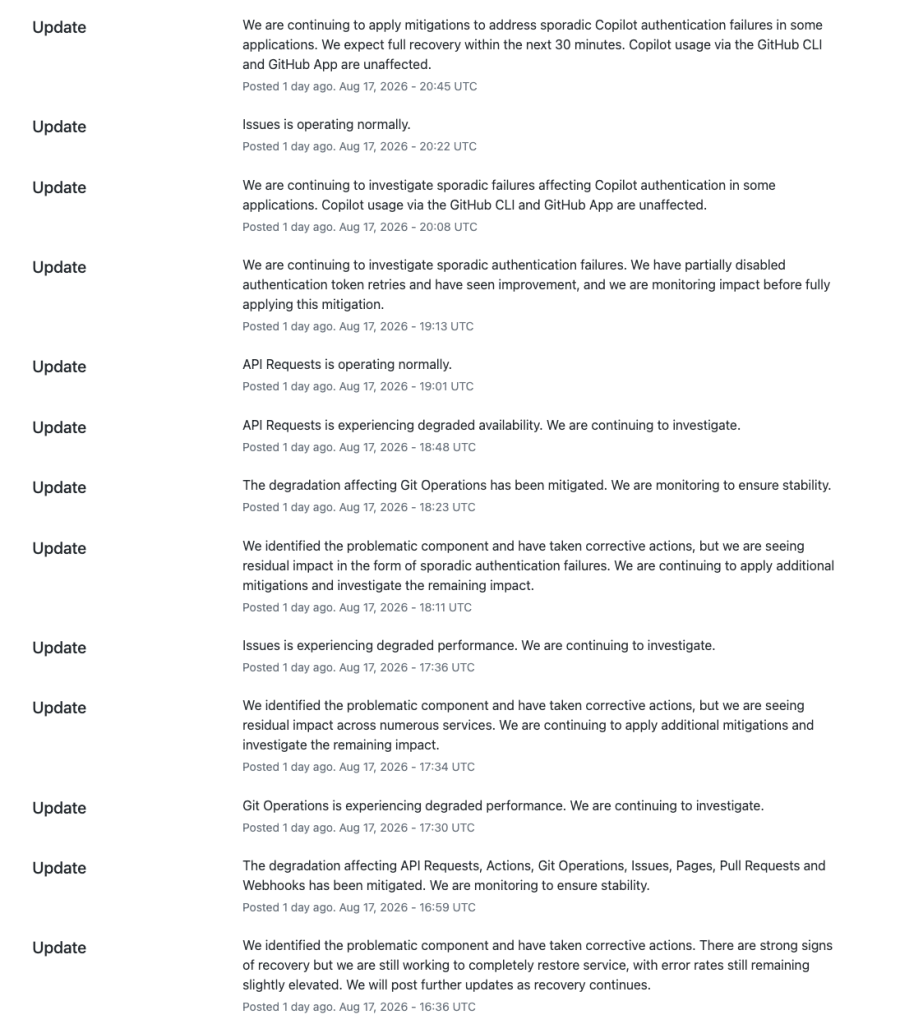
As somebody who was watching the updates to the status page as the incident was happening, I was struck by how they updates alternated between “we have identified the problem” and “we are experiencing issues:
|
||||
|
||||
|
||||
|
||||
I can imagine how frustrating it must have been for the responders to think they had found and fixed the problem, only to continue to see impact.
|
||||
|
||||
## Retries made things worse
|
||||
|
||||
Retries are one of the tools in our toolbox to improve availability. And, usually, retries do improve availability! But retry logic also adds complexity to a system, and adding complexity to a system can introduce new failure modes. In this incident, retries hurt rather than helped, by increasing the load on an overloaded system.
|
||||
|
||||
The problem was worsened by optimistic retry logic which overloaded internal load balancers.
|
||||
|
||||
…
|
||||
|
||||
Residual Copilot authentication failures continued because client retry behavior amplified load: a failed token operation could generate many extra requests and enter a retry loop.
|
||||
|
||||
|
||||
This is a great example of [unexpected behavior of a subsystem *whose primary purpose was to improve reliability*](https://surfingcomplexity.blog/2017/06/24/a-conjecture-on-why-reliable-systems-fail/) from my conjecture on why reliable systems fail.
|
||||
|
||||
## The Copilot Token Service sees 10X traffic
|
||||
|
||||
Note that there were two independent retry behaviors mentioned in the previous section:
|
||||
|
||||
1. optimistic retry logic against the load balancers
|
||||
2. client retry logic against the Copilot Token Service
|
||||
|
||||
It turns out that the client retry logic was due to a previously undiscovered bug in Visual Studio Code(!), which led to one particular service (Copilot Token Service) taking longer to recover:
|
||||
|
||||
Delayed replies to a single internal endpoint triggered a latent retry bug in VS Code that amplified traffic by approximately 10x and caused delayed recovery for the Copilot Token Service.
|
||||
|
||||
…
|
||||
|
||||
Residual Copilot authentication failures continued because client retry behavior amplified load: a failed token operation could generate many extra requests and enter a retry loop. Copilot Token Service traffic increased from a normal 7–9K RPS to 70–100K RPS.
|
||||
|
||||
|
||||
There’s no way you’re pushing out a VS Code bugfix to mitigate an incident! You’ve got to mitigate that on the server side, which is what the responders did, which brings us to the next section.
|
||||
|
||||
## Mitigating the incident: multiple strategies
|
||||
|
||||
While the write-up doesn’t discuss diagnostic work, it does mention multiple mitigations that the responders undertook during the incident:
|
||||
|
||||
- shifting traffic from the Central US region to the Northern Virginia region
|
||||
- paused HAProxy on the four saturated nodes
|
||||
- changed gateway retry logic (via PR)
|
||||
- blocked inbound Copilot Token Service token requests at the load balancer (returned 403s)
|
||||
- gradually ramping up blocked traffic
|
||||
|
||||
As responders, we are always limited in our ability to intervene based on the tools that we have at our immediate disposal. It’s incredibly useful to be able to do things like selectively block traffic, or dynamically change or even disable a reliability-related subsystem. Think about how difficult it would be to block specific types of requests during an incident in your organization, and to ramp that traffic back up slowly after the system recovers. Note how the responders had to use a pull request to change the behavior of the gateway retry logic. I wonder if the failure mode made this more difficult to carry out, but the write-up doesn’t say.
|
||||
|
||||
## “Never again” means never preparing for a novel incident
|
||||
|
||||
The writeup ends, as most writeups do, with some action items intended to prevent recurrence.
|
||||
|
||||
To prevent recurrence, our follow-up actions include:
|
||||
|
||||
|
||||
- Correcting autoscaling policies to account for service-mesh sidecar concurrency and capacity.
|
||||
- Auditing Istio request, concurrency, and scaling limits across affected services.
|
||||
- Reviewing retry limits and backoff behavior across gateways and clients.
|
||||
- Addressing the VS Code retry behavior that amplified Copilot token traffic.
|
||||
- Improving load-balancer capacity monitoring and regional failover safeguards.
|
||||
|
||||
My eternal lament is that people spend too much of their focus on preventing the last incident from recurring. It’s not that I’m opposed to preventative work. It’s that I also want us to spend time on getting better at dealing with novel incidents. Engineering cycles are a finite resource, and every cycle spent on prevention is a cycle not spent on improving our ability to respond effectively to new incidents. And I promise you, you are going to face novel incidents in the future.
|
||||
|
||||
After all, I don’t think GitHub customers who experienced this outage take much solace in knowing that it was a different failure mode from the [previous incident](https://www.githubstatus.com/incidents/qcvjkzcs7j74).
|
||||
|
||||
Hi Lorin,
|
||||
|
||||
Thanks so much for this thoughtful piece.
|
||||
|
||||
I was wondering if you could say a little more about the response itself. Were there aspects of the response that you think could have been more efficient, and if so, what could the responders have done differently? I think that would help provide the missing link and flesh out your main argument.
|
||||
|
||||
There isn’t enough detail from the public writeup for me to have any sense as to what the response was like. This is the kind of information you can only get internally.
|
||||
@@ -0,0 +1,75 @@
|
||||
# How senior leaders disrupt incidents just by showing up
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/08/18/how-senior-leaders-disrupt-incidents-by-showing-up/
|
||||
|
||||
## 简介
|
||||
|
||||
> A VP’s question […] lands with the weight of the org chart behind it, and everyone in the channel feels it.
|
||||
|
||||
I especially liked the sections toward the end on how to mitigate a leader’s impact.
|
||||
|
||||
## 正文
|
||||
|
||||
A vice president joins an incident channel and posts a single, reasonable question: “What’s the customer impact?” Every responder in the channel pauses. The person investigating the network layer stops to check whether they should be the one to answer. The engineer who was about to try a promising mitigation hesitates, wondering if the VP’s question implies a different priority. The incident commander (IC) now has to decide whether to answer the VP or redirect them, and either way, the response has lost momentum.
|
||||
|
||||
There’s nothing wrong with the question itself. If a fellow engineer had asked it, nobody would have blinked. The problem is who asked it and where. A VP’s question in the main incident channel doesn’t land the way a peer’s question does. It lands with the weight of the org chart behind it, and everyone in the channel feels it. If the VP had sent the same question privately to the IC, or to an executive liaison, it would have been answered without disrupting anyone. Instead, it went to the room.
|
||||
|
||||
This is a familiar problem in incident management, and VPs are the usual example, but they’re not the only ones who cause it. Anyone who carries organizational weight can have the same effect: directors, senior architects, the principal engineer who designed the system that’s currently on fire. The dynamics are the same; only the job title changes.
|
||||
|
||||
## The aircraft carrier in the harbor
|
||||
|
||||
A useful way to think about this is to picture an aircraft carrier entering a harbor. The carrier isn’t doing anything wrong. It’s not speeding or behaving recklessly. But it’s enormous, and everything else in the harbor has to adjust: smaller vessels change course, dock operations pause, harbor traffic rearranges itself around the carrier’s presence. The disruption isn’t caused by anything the carrier does. It’s caused by what the carrier is.
|
||||
|
||||
Senior leaders have the same effect in incident channels. When a VP joins and posts a message, responders notice. People stop what they’re doing to read it. Some start formulating answers, even if the question wasn’t directed at them. Others worry about what the VP’s presence means: Is the response not going well enough? Are we in trouble? Should I be doing something different?
|
||||
|
||||
None of this is the VP’s intent. They just wanted to understand what was happening. But the effect is real, and it’s disruptive in ways that senior leaders often don’t recognize, because they can’t see the disruption they’re causing from where they sit.
|
||||
|
||||
## The disruption you can’t see
|
||||
|
||||
This is what separates the presence problem from the more obvious forms of executive disruption. The conventional advice focuses on the visible behaviors: a VP overriding the IC’s decisions, an executive asking rapid-fire questions that pull responders off their tasks, someone senior giving orders that conflict with the tech lead’s plan. Those are real problems, and they deserve attention. But they’re fixable with straightforward norms: address questions to the IC privately, don’t give orders in the main channel, defer visibly to the incident leadership.
|
||||
|
||||
The presence problem is harder, because it persists even when the senior leader does everything right. A VP who joins the channel and says nothing still changes the room. Their presence *will* be noticed, even if Slack doesn’t helpfully snitch on them with a “so-and-so has joined the channel” message to the channel. The presence of someone senior often introduces a layer of self-consciousness that slows things down, even when that person’s intent is purely to observe.
|
||||
|
||||
The *really* tricky cases are the senior leaders who are also genuine technical contributors. At one company, I worked with two senior executives who’d been there since its earliest days. Both were talented engineers who often made real technical contributions during incidents. They weren’t barging in to ask uninformed questions; they were explaining old code and spelunking through logs and spotting things that less experienced responders would have missed.
|
||||
|
||||
Their contributions as subject matter experts were unquestionably valuable. But every time they showed up in an incident channel, many responders (especially newer hires who hadn’t worked side-by-side with them for years) reacted to their titles, not their expertise. The disruption was so tied to their identity that I remember half-seriously considering whether I should tell them to set their Slack display names to secret identities (“Hal Jordan” and “Diana Prince”?), so they could contribute as “just engineers” without anyone knowing The Boss was in the room.
|
||||
|
||||
We never actually did it, but the fact that “give them secret identities” was the best solution anyone could think of tells you something about the nature of the problem. It wasn’t what they were doing; it was who they were.
|
||||
|
||||
And it’s not limited to people with management titles. When I was at Slack, I was an individual contributor with no direct reports, but I led the incident management program and had trained most of the responders and nearly all of the incident commanders. If I joined an incident channel and started asking questions or making suggestions, some would react to my presence the same way they would to a wandering VP. I had to be very intentional about how I showed up, and I probably wasn’t always as careful as I should have been.
|
||||
|
||||
The test isn’t your title; it’s whether your presence changes the room.
|
||||
|
||||
## What senior leaders can do
|
||||
|
||||
The solution isn’t to exclude senior leaders from incidents entirely. Some, like the executives in the story above, are genuine technical contributors whose expertise makes the response better. Others have legitimate information needs: they may need to brief the board, reassure a key customer, or make business decisions that depend on when service will be restored. Both cases deserve to be handled well, but they need different approaches.
|
||||
|
||||
The first question to ask yourself is, do you really need to be visible there at all? Your expertise may be valuable, but so is a response that isn’t reacting to your mere presence. If the answer is yes, be deliberate about how you enter: explicitly state your role (“I’m here as an SME on the payments system; Alex is still the IC”), remind people to take their direction from the incident leadership rather than from you, and consider setting your display name to reinforce it (both Slack and Zoom let you do this). And once you’re in the channel, be disciplined about staying in your stated role. An executive who joins as a subject matter expert but starts asking strategic questions has reintroduced the problem through the back door.
|
||||
|
||||
On the other hand, if you just need to stay informed and make business decisions, your goal should be to do that in a way that doesn’t visibly put you in the incident channel.
|
||||
|
||||
**Get your information from the sitreps.** A well-run incident produces periodic situation reports (sitreps) that are designed to answer exactly the questions senior leaders have: what’s happening, what’s the impact, what’s the plan, and when’s the next update. If the sitreps aren’t meeting your needs, that’s something to work with the team on between incidents, not by visibly disrupting the current incident.
|
||||
|
||||
**If you must communicate with the response, go to the IC privately.** Send a private message. Don’t post in the main channel, even to “just ask a quick question.” There’s no such thing as a quick question from a senior leader during an incident.
|
||||
|
||||
**Consider establishing an executive liaison role.** On larger incidents, one senior leader can serve as the conduit between the response and the rest of the leadership team. The liaison works directly with the IC, passing information along to the other leaders and representing their concerns, so that nobody else on the leadership team needs to enter the incident channel. This is one of the most effective structural solutions to the presence problem.
|
||||
|
||||
**Run interference, in coordination with the IC.** One of the highest-value things a senior leader can do during a major incident is handle the organizational demands that would otherwise land on the IC: the sales team asking what to tell a customer, the legal team needing clarification, the product team wondering whether to delay a launch. But this only works when it’s coordinated with the IC, not freelanced. A quick conversation (“I’m going to handle incoming questions from sales and legal so they don’t land on you; I’ll use the latest sitrep as my source”) keeps the IC informed and avoids the risk of a senior leader making commitments that contradict what the response team is communicating.
|
||||
|
||||
## What ICs can do
|
||||
|
||||
Even in companies with good norms, senior leaders will sometimes show up in the incident channel. The IC needs to be prepared for that.
|
||||
|
||||
When a director drops a question into the channel, intercept it before responders start trying to answer. A simple “Thanks, I’ll follow up with you on that directly” takes the question out of the channel and signals to responders that they should stay focused on their assigned tasks. This is the IC acting as a shield, absorbing the disruption so the responders don’t have to.
|
||||
|
||||
Proactive communication also helps. If you write clear sitreps that include a timestamp and an expected time for the next update, readers can judge how fresh or stale the information is without having to ask. And if you consistently meet the update cadence you’ve committed to, that builds confidence over time that the updates will keep coming.
|
||||
|
||||
When senior leaders can trust that the IC will keep them informed as the response progresses, they’re less likely to come hunting for information themselves. It takes time, over several incidents, to build that trust, but it’s one of the most valuable investments an IC can make.
|
||||
|
||||
## Awareness is the first step
|
||||
|
||||
The hardest part of this problem is that the person causing the disruption almost never sees it. From the bridge of the aircraft carrier, the harbor looks fine. It’s the smaller vessels that changed course. That’s why this isn’t just a behavior problem to be solved with a list of don’ts. It’s an awareness problem. The companies that handle this well aren’t the ones with the most rules about executive behavior during incidents. They’re the ones where senior leaders have internalized a simple idea: during an incident, the most helpful thing you can do might be to stay out of the way, while the most disruptive thing you can do is show up with the best of intentions.
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,212 @@
|
||||
# How Lowe’s SRE Team is Driving Reliability Through Hyper Automation and Unified Platforms
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Raghuprasanth Ravichandran, Joe Praveena A, and Pavan Palagiri
|
||||
- **链接**: https://bluetriangle.com/blog/empowering-retail-excellence-how-lowes-sre-team-is-driving-reliability-through-hyper-automation-and-unified-platforms
|
||||
|
||||
## 简介
|
||||
|
||||
Lowe’s has an intensive (and intense) SRE practice that provides client teams with a framework of tools to ensure reliability.
|
||||
|
||||
## 正文
|
||||
|
||||
[Back to Resource Hub](https://bluetriangle.com/blog)
|
||||
|
||||
# How Lowe's SRE Team is Driving Reliability Through Hyper Automation and Unified Platforms
|
||||
|
||||
|
||||
|
||||
Online retail moves fast—so keeping systems reliable and running smoothly is more important than ever to provide a frictionless user experience.
|
||||
|
||||
At Lowe's, our Site Reliability Engineering (SRE) team has embraced the philosophy of hyper-automation to meet these demands. By integrating innovative tools and solutions, we've streamlined our processes, reduced manual effort, and enhanced our ability to respond swiftly to incidents.
|
||||
|
||||
This approach significantly contributes to Lowe's Total Home Strategy, ensuring we protect and improve the customer experience at every touchpoint. If you're interested in learning exactly how we did it (and you can too), then keep reading to explore the transformative impact of our SRE initiatives, such as leveraging automation to drive excellence in system reliability and operational performance.
|
||||
|
||||
### **Unifying SRE Practices Through Hyper Automation**
|
||||
|
||||
#### #1 Digital Resiliency Hub (DRH): Central Command for SRE Excellence
|
||||
|
||||
In our journey to optimize operational efficiency, we identified the need for a unified platform to streamline Site Reliability Engineering (SRE) tools and resources.
|
||||
|
||||
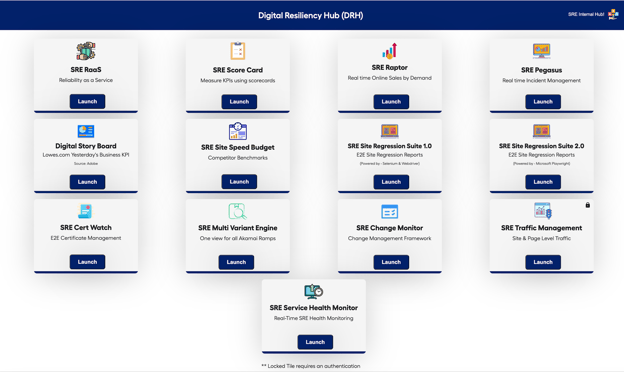
The Digital Resiliency Hub (DRH) is our answer to this need, offering a centralized portal that integrates all SRE products, reducing manual effort and cognitive load. DRH ensures that SRE, business teams, and leadership have quick access to essential tools, fostering a culture of hyper-automation and efficiency.
|
||||
|
||||
|
||||
|
||||
|
||||
*Shown Above: Snapshot of Digital Resiliency Hub (DRH).*
|
||||
|
||||
#### **#2 Comprehensive Reliability with SRE Scorecard**
|
||||
|
||||
Maintaining a unified and comprehensive view of performance and reliability across all product teams is crucial for ensuring the smooth operation of our online selling channels.
|
||||
|
||||
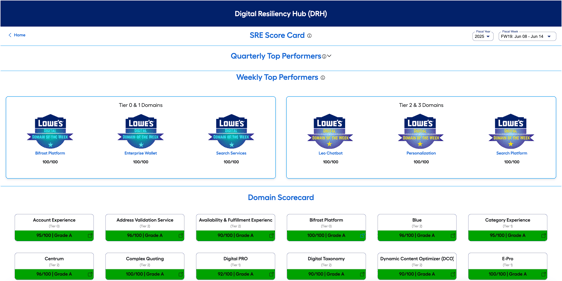
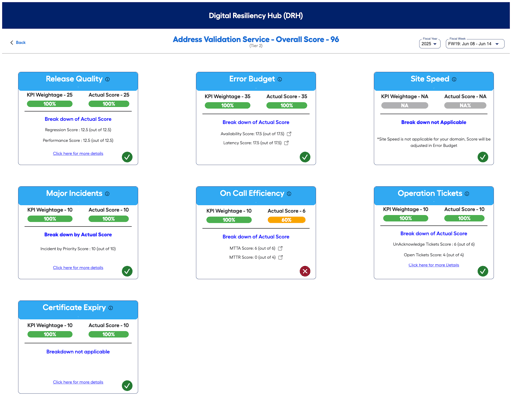
The SRE Scorecard was developed to meet this need, providing an automated tool that tracks and evaluates critical metrics across 40+ domain teams, all of which contribute to our online retail platform's success.
|
||||
|
||||
|
||||
|
||||
|
||||
*Shown Above: Snapshot of SRE Score.*
|
||||
|
||||
##### **Key Features:**
|
||||
|
||||
**1. Real-Time Data Integration:** The SRE Scorecard taps into real-time data from all products within the Digital Resiliency Hub (DRH).
|
||||
|
||||
By consolidating this information, the scorecard offers a holistic view of our system's health, tracking key performance indicators (KPIs) such as release quality, error budgets (covering availability and latency), site speed deviations (both week-over-week and against competitor benchmarks), major incident trends, certificate expiry management, on-call efficiency, and operations ticket resolution.
|
||||
|
||||
**2. Automated Governance:** This tool is an automatic governance mechanism for the 40+ domain teams that stitch together our online selling channels.
|
||||
|
||||
The SRE Scorecard keeps a tight tab on critical areas like release quality and error budgets, ensuring that domains adhere to the highest standards of reliability.
|
||||
|
||||
**3. Scoring and Grading System:** The scorecard assigns grades (A, B, C, D) to each domain based on their performance:
|
||||
|
||||
- **A (Gold Standard):** Represents the highest level of compliance and performance. Continuous adherence to this standard is expected, with regular audits conducted to ensure sustained excellence. Significant deviations may trigger a detailed review.
|
||||
- **B:** Domains can continue releasing features but must promptly address any compliance gaps. Failure to improve consistently may lead to a temporary freeze on new feature releases until compliance is restored.
|
||||
- **C:** Domains face a temporary restriction on releasing features. A detailed analysis of compliance gaps is required, along with a clear plan to achieve at least a 'B' grade. The release freeze is lifted only upon satisfactory improvement.
|
||||
- **D:** Domains are prohibited from releasing features until immediate compliance gaps are rectified. A comprehensive action plan to maintain at least a 'B' grade is mandatory. Continuous non-compliance could result in an extended feature freeze.
|
||||
|
||||
**4. Incentivized Performance:** The SRE Scorecard incentivizes domains to perform better by recognizing those who consistently achieve high grades in quarterly town halls and other forums. This recognition encourages continuous improvement and adherence to the highest standards of operational excellence.
|
||||
|
||||
|
||||
|
||||
|
||||
*Shown Above: Snapshot of SRE Score.*
|
||||
|
||||
#### **#3 Enhancing Performance with SRE Site Speed Budget**
|
||||
|
||||
In the fast-paced environment of online retail, maintaining optimal site speed across various funnels is crucial for delivering a frictionless user experience. But manually tracking performance? That was slow, tedious, and often inaccurate.
|
||||
|
||||
To address this, SREs have developed the Site Speed Budget framework in partnership with Blue Triangle, the business-outcomes platform that quantifies the cost of friction in your digital experience so you can fix what matters most.
|
||||
|
||||

|
||||
|
||||
|
||||
*Shown Above: Screenshot from the Blue Triangle platform using sample data for demonstration purposes only. Not affiliated with or based on data from Lowe’s.*
|
||||
|
||||
This data is critical in benchmarking performance against competitors and setting annual and monthly targets for Core Web Vitals (CWV). By utilizing these insights, the framework continuously monitors key metrics such as Largest Contentful Paint (LCP), Cumulative Layout Shift (CLS), and Interaction to Next Paint (INP), ensuring sustained performance improvements and an enhanced customer experience.
|
||||
|
||||
##### **Key Features:**
|
||||
|
||||
**1. Automated Performance Monitoring:** The tool automates the tracking of site speed, eliminating the need for manual processes and reducing the risk of errors.
|
||||
|
||||
**2. Industry Standard Benchmarking:** By comparing our site's performance with our competitors, we ensure that we remain at the forefront of the industry, providing a competitive edge. Competitor models have been provided by the Blue Triangle Team.
|
||||
|
||||
**3. Annual and Monthly Target Setting:** The tool allows for setting annual performance targets, which are then broken down into more manageable monthly goals. This structure ensures continuous assessment and improvement.
|
||||
|
||||
**4. Week Over Week Performance Tracking**: To ensure that product release cycles do not inadvertently affect site speed, the tool tracks performance week over week. This allows for the swift identification of any issues introduced by new releases, ensuring they are promptly addressed.
|
||||
|
||||
**5. Swift Identification and Resolution of Issues:** With the ability to monitor performance continuously, the tool enables rapid identification of any issues that arise, allowing for quick corrective action to maintain optimal site speed.
|
||||
|
||||
#### **#4 SRE Incident Management Framework**
|
||||
|
||||
Online retail demands impeccable site reliability, but our previous incident management system was fragmented, leading to delayed responses and poor communication.
|
||||
|
||||
The SRE Incident Management Framework addresses these issues by centralizing incident reporting and resolution. This platform provides a comprehensive view of incidents, enabling quicker, more informed decision-making and continuous improvement, enhancing our ability to maintain site reliability and customer trust.
|
||||
|
||||
|
||||
|
||||
|
||||
##### **Key Features:**
|
||||
|
||||
**1. Theater Tile View**: Visualize the entire fiscal year's health with a theater tile view highlighting the days with incidents versus those without. This overview helps quickly assess overall site stability.
|
||||
|
||||
**2. Site Availability Metrics**: Track site availability year-to-date (FYTD), ensuring we maintain the highest levels of uptime.
|
||||
|
||||
**3. MTTD & MTTRs**: Monitor Mean Time to Detect, Mean Time to Recover, and Mean Time to Resolve, allowing for a detailed analysis of our response efficiency. **4. Incident Trend Analysis**: Evaluate incident trends by severity, enabling focused efforts on areas needing the most attention. **5. Root Cause & Product Impact**: Access detailed insights on the root cause themes, responsible products, and impacted products, helping drive continuous improvement. **6. Real-Time Incident Updates**: Receive real-time updates with snapshots of the site experience during incidents, providing a clear understanding of the impact on the customer journey. **7. Embedded Postmortem Links**: Easily access postmortems through embedded links, streamlining the process of reviewing and learning from past incidents.
|
||||
|
||||
This comprehensive incident management approach not only ensures a more reliable site but also fosters a culture of continuous improvement, ultimately enhancing customer trust and satisfaction.
|
||||
|
||||
#### **#5 Proactive Stability with SRE Cert Watch**
|
||||
|
||||
In the complex landscape of online retail, ensuring the continuous validity of certificates across various systems is vital to maintaining site stability and security.
|
||||
|
||||
Previously, managing certificate expiries was a significant challenge due to fragmented reporting. SRE Cert Watch addresses these challenges by consolidating expiry data from various sources, providing comprehensive visibility, and enabling proactive management.
|
||||
|
||||
##### **Key Features:**
|
||||
|
||||
**1. Comprehensive Certificate Mapping**: SRE Cert Watch meticulously maps certificates related to External/Internal/Third-party DNS, Applications, and Databases. This mapping is not generic but is intricately tied to each domain in the purchase path of the site. This level of detail ensures that any potential certificate expiry can be pinpointed to its exact impact on the purchase path flow, allowing for targeted and efficient resolution.
|
||||
|
||||
**2. Proactive Alerting System**: The tool includes an advanced alerting capability that automatically triggers alerts to the SRE team and other concerned teams when a certificate's expiry date is approaching—specifically within 30 days. This proactive approach ensures that teams have ample time to address any potential issues before they can impact the site's functionality or security.
|
||||
|
||||
**3. Consolidated Reporting**: By bringing together data from various sources, SRE Cert Watch eliminates the fragmentation that previously hindered effective certificate management. The tool provides a unified view of all certificates across the site, simplifying the tracking process and ensuring no certificates are overlooked.
|
||||
|
||||
**4. Impact Analysis**: With its detailed mapping to the purchase path, SRE Cert Watch allows teams to quickly assess the potential impact of a certificate expiry on critical site functions. This capability is crucial for maintaining a seamless and secure user experience, particularly during high-traffic periods.
|
||||
|
||||
### Driving the Future of Digital Retail Through Innovation and Automation
|
||||
|
||||
At Lowe's, our commitment to site reliability and operational excellence is driven by a culture of continuous innovation and automation. Through our hyper-automation initiatives, we've established a resilient and efficient SRE framework that enhances system reliability, improves incident response, and optimizes performance.
|
||||
|
||||
|
||||
|
||||
|
||||
'From the Digital Resiliency Hub to the SRE Scorecard and Incident Management Framework, every tool and strategy we've implemented ensures a seamless customer experience and aligns with our Total Home Strategy.
|
||||
|
||||
A key aspect of our performance optimization efforts is the Site Speed Budget framework, developed in collaboration with Blue Triangle. By leveraging Blue Triangle's competitor benchmarking model, we can continuously track, analyze, and enhance site speed, ensuring our online retail platforms remain agile and responsive. This partnership provides us with data-driven insights that guide our performance goals, allowing us to stay ahead of the competition while delivering a frictionless shopping experience.
|
||||
|
||||
As we continue refining our SRE practices, our focus remains on driving proactive solutions that empower both our internal teams and our customers. Through strategic partnerships, advanced automation, and a relentless pursuit of operational excellence, we are shaping the future of digital retail—one innovation at a time.
|
||||
|
||||
Blog Authors:
|
||||
|
||||
- Raghuprasanth Ravichandran, Senior Engineering Manager, Site Reliability Engineering—Lowe’s Companies, INC
|
||||
- Joe Praveena A, Senior Engineering Manager, Site Reliability Engineering—Lowe’s India
|
||||
- Pavan Palagiri, Lead Software Engineer, Site Reliability Engineering—Lowe’s Companies, INC
|
||||
|
||||
Leadership Credit:
|
||||
|
||||
- Deepankar Singh, Senior Director, Site Reliability Engineering—Lowe’s India
|
||||
- Shyam Palani , Director, Site Reliability Engineering—Lowe’s Companies, INC
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[Web Performance
|
||||
|
||||
|
||||
The Friction Point Isn't the Finish Line Anymore
|
||||
|
||||
|
||||
The gap between "we found it" and "we fixed it" is where the revenue leaks out now. That](https://bluetriangle.com/blog/the-friction-point-isnt-the-finish-line-anymore)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[Marketing Analytics
|
||||
|
||||
|
||||
How AI Can Make Your KPIs Look Worse — And Why That Might Mean You're Winning
|
||||
|
||||
|
||||
We dropped a new episode of The Frictionless Experience, and it might change how you read](https://bluetriangle.com/blog/how-ai-can-make-your-kpis-look-worse-and-why-that-might-mean-youre-winning)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[Digital experience optimization
|
||||
|
||||
|
||||
Cupid & Easter Bunnies Leave Sluggish Experiences
|
||||
|
||||
|
||||
TL;DR: That Beautiful Seasonal Campaign Image Is Costing You More Than You Think. A](https://bluetriangle.com/blog/cupid-easter-bunnies-leave-sluggish-experiences)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,491 @@
|
||||
# Before You Automate a Decision, Define Its Blast Radius
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Sai Sandeep Koneti — HackerNoon
|
||||
- **链接**: https://hackernoon.com/before-you-automate-a-decision-define-its-blast-radius
|
||||
|
||||
## 简介
|
||||
|
||||
How far will the impact of an incorrect automated decision spread? Will it get integrated into the system and influence later decisions?
|
||||
|
||||
## 正文
|
||||
|
||||
Over the years, working with enterprise data, analytics, reporting, and production systems has made me increasingly cautious about one particular statement: “The system worked exactly as designed.”
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Sometimes, that is reassuring. Other times, it is the beginning of a much more complicated problem. A pipeline can finish successfully, a report can refresh on time, a rule can execute exactly as written, and an API can return the expected response. Every technical indicator may look healthy, yet the resulting business decision can still be wrong.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
When that happens, the first question is usually obvious: what went wrong? But I have found that another question matters just as much: how far did the mistake travel before somebody noticed?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That is what I think of as the blast radius of an automated decision.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The concept is already familiar in infrastructure and reliability engineering. When a service fails, we do not care only that it failed. We want to understand what else was affected, how many users experienced the impact, how quickly we detected the problem, and whether we could isolate it before it spread further.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Automated decisions deserve the same treatment. Before allowing a system to make or execute a decision automatically, we should understand what happens when that decision is wrong.
|
||||
|
||||
## A correct system can still produce a bad outcome.
|
||||
|
||||
Teams naturally focus on accuracy, latency, availability, and data quality. Those measurements matter, but none of them tells us much about the consequence of a mistake.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Consider a relatively ordinary enterprise workflow in which incoming support cases are automatically prioritized. If one case is incorrectly ranked, the immediate impact may be limited to a delayed response. That is a problem, but it is still relatively contained.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Now, imagine that the priority classification becomes an input to several other processes. Priority determines routing. Routing determines escalation. Escalation determines which team is notified. The classification is also written back into another system, where it appears in reporting and eventually becomes an input to another automated workflow.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
At that point, the original mistake is no longer just an incorrect classification.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
It has effectively become data.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Once a bad decision becomes trusted data, other systems begin building on it. Each downstream process extends the original error, often without knowing anything about the assumptions that produced it.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
This is why I think discussions about automated decision-making need to move beyond whether a system can make a decision accurately. We also need to understand what the organization has allowed that decision to influence.
|
||||
|
||||
## Accuracy tells you how often. Blast radius tells you how bad.
|
||||
|
||||
Suppose a system is 99.9 percent accurate and processes one million decisions. That still leaves roughly one thousand incorrect outcomes.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The accuracy number tells us how frequently the system may be wrong, but it does not tell us whether those thousand errors should concern us. That depends on what happens after each mistake.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
If the errors are isolated, immediately visible, inexpensive to correct, and unable to trigger anything downstream, the operational risk may be manageable. If the same errors alter other records, trigger workflows, influence reporting, or remain unnoticed for days, the same accuracy rate starts to look very different.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A highly accurate system can still create significant risk when a single wrong output has broad consequences.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That is why I do not think of blast radius as another model metric. It is a property of the system surrounding the decision.
|
||||
|
||||
## Four dimensions of decision blast radius.
|
||||
|
||||
I have found it useful to think about blast radius through four practical dimensions: scope, detection, reversibility, and concentration.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
This is not meant to be a complicated scoring model. The value is in forcing a team to look past whether the automated component technically works and toward what happens after it produces an answer.
|
||||
|
||||
### Scope: How much can one decision touch?
|
||||
|
||||
The first question is about reach. If one automated decision is wrong, how many records, users, workflows, or systems can it influence?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
In enterprise environments, dependencies have a habit of growing over time. A status may begin as something used by one application. Later, another process reads it. A report groups customers using that same status. A dashboard uses the report. Someone exports the information, and eventually another process begins treating the value as authoritative.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
This pattern is familiar to anyone who has spent time around analytics platforms. A metric may start as a calculation needed for one report and gradually become reused across dashboards, exports, operational processes, and management decisions. Nothing necessarily breaks during that evolution. The dependency simply becomes larger than the original design anticipated.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Automated decisions can develop the same kind of sprawl. What appears isolated during implementation may eventually become an upstream dependency for processes the original team never considered.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That is why I would want to know not only what a decision directly changes, but also who or what trusts that output afterward.
|
||||
|
||||
### Detection: How long can we be wrong without knowing it?
|
||||
|
||||
Some failures are easy to detect. A service goes down, a query times out, a refresh fails, or users immediately start reporting a problem. Those incidents can be disruptive, but at least the system is telling us something is wrong.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The failures that concern me more are the quiet ones.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The job succeeds. The workflow runs. The dashboard refreshes. No alert fires.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The number is simply wrong. A threshold is outdated. An upstream definition has changed. A calculation that is technically correct is now operating against the wrong business assumption.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
These problems can survive in production because traditional monitoring has nothing obvious to report. From an infrastructure perspective, the system is healthy. From a decision perspective, it may not be.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That is why detection should be part of the decision design itself.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
If an automated process begins producing incorrect outcomes today, what mechanism will expose the problem tomorrow? Are we checking the distribution of outcomes? Are we comparing unusual changes against historical behavior? Is someone reviewing exceptions? Can we trace an unexpected result back through the data and logic that produced it?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
If the answer is simply that somebody will eventually notice, the true blast radius is probably larger than the architecture suggests.
|
||||
|
||||
### Reversibility: What does undo actually mean?
|
||||
|
||||
Engineering teams value rollback because it gives us a recovery path. When a deployment causes a problem, we can often restore the previous version and stabilize the environment.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Decisions are harder to reverse because their effects frequently extend beyond the system that made them.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
An incorrect recommendation that nobody has acted on is easy to correct. Once that recommendation triggers a workflow, changes records, sends notifications, or causes another person or system to make a second decision, rollback becomes much more complicated.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Reversibility therefore is not simply yes or no.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Some actions can be undone in seconds. Others can be technically reversed but require hours of cleanup across several systems. Still others can be corrected in the database while their real-world consequences remain.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The harder an action is to reverse, the more carefully I would think about the amount of authority the system receives before execution.
|
||||
|
||||
### Concentration: Where do the failures accumulate?
|
||||
|
||||
Aggregate performance can also hide where the impact is concentrated.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
An automated routing rule may work well overall but consistently perform poorly for one product category. A forecasting process may behave normally across most regions while producing unreliable results in one market. A classification system may show excellent average performance even though one relatively small segment accounts for a large share of the errors.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Looking only at averages makes these patterns easy to miss.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A system can appear healthy overall while the same workloads, regions, products, or customer segments absorb most of its mistakes.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
For that reason, I would not stop at asking, “What is our error rate?”
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
I would also want to know where those errors are occurring.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The answer may tell a very different story.
|
||||
|
||||
## The decision belongs in the architecture
|
||||
|
||||
One thing that stands out to me in many system designs is how well we document technical components while leaving the actual decision relatively implicit.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Architecture diagrams show databases, services, pipelines, APIs, queues, reports, and integrations. They describe how information moves from one component to another. Yet the business decision the entire system is intended to support can disappear somewhere between the boxes.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
If a system exists to make or influence an important decision, I think that decision should be treated as part of the architecture itself.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The design should make clear what the decision can affect, which systems consume its output, how incorrect outcomes will be detected, how execution can be constrained, and what happens when the system encounters a situation it should not handle automatically.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
This does not necessarily require another large governance process. In many cases, simply asking these questions during design exposes dependencies that an accuracy score will never reveal.
|
||||
|
||||
## Expand autonomy only as fast as you can contain failure
|
||||
|
||||
Production engineering has already taught us an important lesson: we do not need to discover every problem at full scale.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Important changes are often introduced gradually. Exposure is limited, behavior is observed, and only then is the change expanded.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Automated decisions should work the same way.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
If a system is going to start taking an action that previously required human judgment, there is little reason to begin with every customer, every transaction, every region, and every scenario at once. The first production scope could be limited to one workflow, one business unit, a low-impact category of decisions, or a small percentage of transactions.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The specific boundary matters less than the principle: the initial blast radius should be intentional.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
During that period, the team should observe more than whether the automated component technically succeeds. Was the underlying data current? Did the business definition still mean what everyone thought it meant? Did the rule behave correctly around edge cases? Did downstream systems interpret the result correctly? Could an unusual outcome be explained without pulling several teams into a long investigation?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Those questions tell us whether the whole decision chain works.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
They also help determine how much autonomy the system has earned.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Some decisions may eventually be appropriate for full automation. Others may work better as recommendations. Some may require approval before execution, while others may be automated only inside clearly defined limits.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
I think of those not as stages of technological maturity but as levels of operational trust.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A system earns more authority when we understand its behavior, can detect when it is wrong, can contain the consequences, and have a practical way to recover.
|
||||
|
||||
## Every automated decision needs an exit.
|
||||
|
||||
Before putting an automated decision into production, I would also want a clear answer to one practical question: how do we turn off the decision authority without taking down everything around it?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That does not necessarily mean shutting down the application.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A well-designed system may be able to return to recommendation-only mode, temporarily require human approval, reduce transaction limits, exclude a problematic scenario, revert a rule or threshold, or stop using one questionable data source while the rest of the platform continues operating.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
These controls sound obvious during an incident. They are much easier to overlook during development, when most attention is focused on getting the capability launched.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
But an incident is the worst possible time to discover that the only available kill switch is shutting down the entire system.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Containment needs to be designed before it is needed.
|
||||
|
||||
## The real system is bigger than the model.
|
||||
|
||||
This is also why I find it difficult to treat automated decision-making purely as a model problem.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The model, if there is one, is only one component in a longer chain.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
In an enterprise environment, that chain may look something like:
|
||||
|
||||
source data → transformation → business definition → context → decision logic → recommendation → workflow → action
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A failure anywhere along that path can alter the outcome. The source data may be technically valid but incomplete. A semantic definition may have changed. A threshold may no longer reflect the business. A downstream workflow may interpret an otherwise correct result incorrectly.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Sometimes there is no model involved at all.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
A rule, a stale definition, or a seemingly minor field can create exactly the same downstream consequences.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The reliability of the final outcome therefore depends on the entire decision chain, not simply the component producing the recommendation.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
I have written before about tracing a decision backward to the data that created it. Blast radius is the same problem viewed in the opposite direction.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Lineage tells you where the decision came from. Blast radius tells you where the decision goes.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
You need both if you want to understand how an automated system actually behaves in production.
|
||||
|
||||
## The question I would put in every design review.
|
||||
|
||||
If I had to reduce the entire idea to one question, it would be:
|
||||
|
||||
If this decision is wrong, what happens next?
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Answering that question forces the conversation beyond whether a system can automate something or whether its accuracy looks impressive. It makes us examine who consumes the result, what gets triggered downstream, how long a mistake can survive, whether the impact can be contained, and what it will take to undo the action after it has propagated.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
That is the blast radius of an automated decision.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Defining it before automation does not eliminate failures. Production systems will eventually encounter incorrect data, misunderstood assumptions, edge cases, changing business rules, and outcomes that do not behave the way we expected.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The systems I tend to trust most are not the ones designed around the assumption that they will always be right.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
They are the ones designed so that when they are wrong, the mistake has a clear boundary and somewhere to stop.
|
||||
@@ -0,0 +1,171 @@
|
||||
# Managing Kubernetes node drains with Pod Disruption Budgets
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Andre Newman — Gremlin
|
||||
- **链接**: https://www.gremlin.com/blog/managing-kubernetes-node-drains-with-pod-disruption-budgets
|
||||
|
||||
## 简介
|
||||
|
||||
A great primer on how pod disruption budgets work and why they’re critical for reliability.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
# Managing Kubernetes node drains with Pod Disruption Budgets
|
||||
|
||||
Kubernetes normally excels at preserving uptime during maintenance tasks, but it’s not always perfect. Even something as benign as consolidating nodes after a traffic spike could take your application offline if not done carefully. This is where PodDisruptionBudgets (PDBs) come in.
|
||||
|
||||
In this blog, we’ll explain why PDBs are important, what the risks are of not implementing them, and how you can find out which of your own deployments are missing PDB definitions.
|
||||
|
||||
|
||||
## What is a pod disruption?
|
||||
|
||||
A [disruption](https://kubernetes.io/docs/concepts/workloads/pods/disruptions/) is any event that interrupts a pod’s ability to run. Hardware failures, out-of-memory evictions, and cloud provider outages might come to mind: these are *involuntary* disruptions, which you have little to no control over. But if a pod goes down because someone or something took deliberate action, that’s a *voluntary* disruption. Voluntary disruptions include:
|
||||
|
||||
- Draining nodes for replacement, upgrading, or downscaling.
|
||||
- The cluster autoscaler consolidating workloads onto fewer nodes.
|
||||
- Migrating pods to make room for other pods that need a resource on the node.
|
||||
|
||||
A common misconception is that PDBs govern rolling updates to Deployments or StatefulSets. Pods removed during a rolling update count against a PDB, but the Deployment and StatefulSet controllers aren’t limited by PDBs. PDBs work through Kubernetes’ [eviction API](https://kubernetes.io/docs/concepts/scheduling-eviction/), while these controllers delete pods directly. The same applies to [Horizontal Pod Autoscalers](https://www.gremlin.com/community/tutorials/validating-horizontal-pod-autoscaling-on-eks-with-gremlin) (HPAs).
|
||||
|
||||
|
||||
## What is a pod disruption budget, and why is it important for reliability?
|
||||
|
||||
A PDB restricts the number of pods that can be unavailable simultaneously for a given deployment during a voluntary disruption.
|
||||
|
||||
Kubernetes has no way of knowing which of your pods are load-bearing. If you ask it to drain a node, it will evict *everything* on the node. If your pod replicas happen to be spread evenly across the cluster, this isn’t a problem. But if your replicas happen to be consolidated on a single node, you can lose the entire service. PDBs help catch scenarios like these and prevent evictions from proceeding until your pods can migrate to other nodes.
|
||||
|
||||
For example, imagine we’re hosting a web application in an Nginx pod with four replicas for redundancy:
|
||||
|
||||
|
||||
We want to ensure that we always have at least three replicas in order to meet our latency service level objective (SLO), so we’ll create a PDB:
|
||||
|
||||
|
||||
Let’s break down each of these fields:
|
||||
|
||||
- `maxUnavailable` caps the number of pods that can be unavailable during a voluntary disruption. Alternatively, you can use`minAvailable` to set the minimum number of pods that must be available. Both properties also accept percentages in the form of strings (e.g.`maxUnavailable: "50%"` ).
|
||||
- `selector` determines which pods the PDB will apply to. An empty selector matches every pod in the namespace, so scope this carefully.
|
||||
- `unhealthyPodEvictionPolicy` determines when Kubernetes considers unhealthy pods for eviction.`IfHealthyBudget` (the default) only allows an eviction if`currentHealthy` is at or above`desiredHealthy` . The other option,`AlwaysAllow` , permits it regardless.
|
||||
|
||||
After applying the PDB, you can validate it by running `kubectl get pdb nginx-pdb`:
|
||||
|
||||
|
||||
### Validating your pod disruption budget
|
||||
|
||||
Imagine our deployment is running on a four-node cluster. Since we didn’t use [topology spread constraints](https://www.gremlin.com/blog/optimizing-kubernetes-pod-deployments-for-reliability-with-topology-spread-constraints) to control where and how our pods should be distributed, the Kubernetes scheduler placed three of them on the same node.
|
||||
|
||||
|
||||
For details about the PDB, run `kubectl get pdb nginx-pdb -o yaml`:
|
||||
|
||||
|
||||
Under status:
|
||||
|
||||
- `conditions` maps out changes in the PDB’s state.
|
||||
- `currentHealthy` is the number of healthy pods matching the selector.
|
||||
- `desiredHealthy` is the minimum desired number of healthy pods.
|
||||
- `disruptionsAllowed` is the number of pods that can be disrupted while still satisfying this PDB. Since`currentHealthy` and`desiredHealthy` are the same number, this leaves room for zero disruptions.
|
||||
- `expectedPods` is the number of pods matched by the PDB’s selector.
|
||||
|
||||
If we drain the node without a PDB, we’d lose 3/4 of our deployment. But since we defined `maxUnavailable: 2`, the PDB will evict one pod and stall on the second while Kubernetes deploys replicas onto another node. `currentHealthy` drops to 3, `disruptionsAllowed` drops to 0, and the node drain waits for the replacements to become Ready before continuing.
|
||||
|
||||
|
||||
After the new replica becomes available, the PDB allows the eviction to proceed.
|
||||
|
||||
|
||||
## How do you decide the parameters for a PDB?
|
||||
|
||||
Creating a PDB only takes a few lines; the hard part is choosing the right number of unavailable pods. What’s the smallest replica count that your service can run at while still doing its job? It comes down to three factors: **capacity**, **service level objective (SLO) tolerance**, and **operational throughput**.
|
||||
|
||||
Start with capacity. What’s the minimum number of replicas needed to serve your baseline traffic? That becomes your floor. If your normal traffic could be served by two pods, two is your floor. The exception is services that require a certain number of replicas for quorum, like distributed databases and message queues. For those, keep the floor at or above quorum size, and remember that node count isn’t the whole story: for example, a Kafka cluster with three surviving brokers can still refuse writes if a partition drops below its minimum in-sync replicas.
|
||||
|
||||
Next, consider your service level objectives (SLOs). If dropping your floor pushes p99 latency past your SLO, the floor is too low. Keep in mind that `desiredHealthy` guarantees nothing about the remaining pods: they can still crash, get out-of-memory (OOM) killed, or go offline due to a failed node. A PDB only constrains voluntary disruptions. Involuntary disruptions stack on top of whatever the budget already permits.
|
||||
|
||||
Last is operational throughput, which is the cost side of the tradeoff. A narrow budget means longer maintenance cycles, since Kubernetes will need to migrate the same number of pods in fewer batches. For example, draining four pods off a node with `maxUnavailable: 2` only requires two eviction cycles (two pods per cycle), but `maxUnavailable: 1` doubles this to four cycles (one pod per cycle). On large clusters with slow containers, this can be the difference between several minutes and several hours.
|
||||
|
||||
|
||||
### How to test that your PDB holds
|
||||
|
||||
Choosing a value for a PDB is one thing, and verifying that it works as expected is another. The question isn’t whether the mechanism works (that’s the job of the Kubernetes developers), but **whether your service can reliably survive a voluntary disruption**.
|
||||
|
||||
Start by scaling your deployment to the `desiredHealthy` target, then [perform a load test](https://www.gremlin.com/blog/how-reliability-testing-and-load-testing-are-complementary) to replicate peak traffic. If you can maintain your SLOs at that level, then your budget is acceptable. You can also use Gremlin’s [blackhole experiment](https://www.gremlin.com/docs/fault-injection/experiments/blackhole) to make pods unreachable, simulating reduced capacity so you can test without modifying your cluster.
|
||||
|
||||
|
||||
### Common hurdles when creating PDBs
|
||||
|
||||
There are some unexpected “gotchas” when creating PDBs.
|
||||
|
||||
**Never allow `disruptionsAllowed` to equal 0 in steady state**. If `minAvailable` equals your replica count, or `maxUnavailable` is zero, the budget permits nothing. Node drains hang, cluster upgrades stall, and the cluster autoscaler stops consolidating. The failure is silent until the next maintenance window, or an admin checks manually.
|
||||
|
||||
**Both `minAvailable` and `maxUnavailable` round up when using percentages**. Rounding up a maximum makes it more permissive, not less. For example, `maxUnavailable: "30%"` on four replicas allows two evictions rather than one. Calculate the integer equivalent for your minimum, steady, and peak replica counts before committing to a percentage.
|
||||
|
||||
**Don’t use PDBs for single-replica deployments**. A `minAvailable: 1` or `maxUnavailable: 0` budget on one replica pins `disruptionsAllowed` to zero. Expect a missing PDB audit to flag every single-replica deployment. The solution, rather than using a PDB, is to add more replicas.
|
||||
|
||||
**Broken pods can block a drain**. With the default `IfHealthyBudget` policy, a pod that is `Running` but not `Ready` can only be evicted while `currentHealthy` is at or above `desiredHealthy`. Once the budget is spent, a pod in [CrashLoopBackOff](https://www.gremlin.com/blog/how-to-fix-kubernetes-crashloopbackoff) can block the drain indefinitely. Setting `unhealthyPodEvictionPolicy: AlwaysAllow` lets Kubernetes evict these blocking pods. This is best used for stateless services, as stateful services may need the time to catch up on tasks such as replication.
|
||||
|
||||
**Scope your PDB selector to one service**. The broader your selector, the harder it is to calculate your budget. Remember that an empty selector covers every pod in the namespace. Create separate PDBs for each service, even if their rules are identical.
|
||||
|
||||
|
||||
## How do you find deployments with missing PDBs?
|
||||
|
||||
PDBs bind by label selector, so there’s no direct way to identify pods without them. Instead, you can work backwards by collecting every PDB selector in the namespace, then listing pods that match none of them:
|
||||
|
||||
|
||||
There are two things to note with this script:
|
||||
|
||||
1. It only evaluates `matchLabels` selectors, not`matchExpressions` . Any PDB using`matchExpressions` gets skipped and its pods will show as uncovered.
|
||||
2. It lists pods rather than workloads, so each replica appears separately alongside Job and DaemonSet pods.
|
||||
|
||||
Once you’ve applied your PDBs, re-run this script to confirm your pods no longer appear in the output.
|
||||
|
||||
Manually running this script is fine for starting out, but running this per namespace or per service doesn’t scale. Gremlin includes a Detected Risk that automatically scans your cluster for deployments without a PDB. Gremlin surfaces this risk, along with [many other reliability risks](https://www.gremlin.com/technologies/detected-risks), in one report so you can see exactly which services are exposed.
|
||||
|
||||
|
||||
## Other Kubernetes risks to watch for
|
||||
|
||||
PDBs are just one part of a resilient Kubernetes deployment. Pods that are [unevenly distributed](https://www.gremlin.com/blog/optimizing-kubernetes-pod-deployments-for-reliability-with-topology-spread-constraints), [slow to start](https://www.gremlin.com/blog/managing-slow-container-starts-kubernetes-readiness-probes), or [missing resource requests](https://www.gremlin.com/blog/how-to-set-cpu-requests-kubernetes-pods) carry more hidden risks. To learn how to protect against these, check out our comprehensive ebook, [Kubernetes Reliability at Scale](https://www.gremlin.com/whitepapers/kubernetes-reliability-at-scale-how-to-improve-uptime-with-resiliency-management).
|
||||
|
||||
In the meantime, if you'd like a free report of your reliability risks in just a few minutes, you can sign up for a [free 30-day Gremlin trial](https://www.gremlin.com/trial), or use Gremlin's [Detected Risks](https://www.gremlin.com/technologies/detected-risks) feature to automatically scan your existing Kubernetes deployments for missing pod disruption budgets.
|
||||
|
||||
#### K8s Reliability at Scale
|
||||
|
||||
To learn more about Kubernetes failure modes and how to prevent them at scale, download a copy of our comprehensive ebook
|
||||
|
||||
[Get the Ultimate Guide](https://www.gremlin.com/whitepapers/kubernetes-reliability-at-scale-how-to-improve-uptime-with-resiliency-management?utm_source=cta&utm_medium=webpage&utm_campaign=on_page_cta_kub_rel_at_scale+)
|
||||
|
||||
|
||||
|
||||
[Back to top](https://www.gremlin.com#single-article)
|
||||
|
||||
|
||||
## Optimizing Kubernetes pod deployments for reliability with topology spread constraints
|
||||
|
||||
Topology spread constraints control how Kubernetes replicates pods across failure domains, like zones and regions. Learn how they work in this blog post.
|
||||
|
||||
|
||||
|
||||
Topology spread constraints let you determine how Kubernetes spreads pod replicas across failure domains, such as availability zones and regions. This blog explains how they work, how to configure them, and how to scan for missing constraints.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/optimizing-kubernetes-pod-deployments-for-reliability-with-topology-spread-constraints)
|
||||
|
||||
|
||||
## Managing slow container starts with Kubernetes readiness probes
|
||||
|
||||
Pods without readiness probes are like engineers without coffee. Learn how readiness probes work, why they’re important, and how to configure them correctly.
|
||||
|
||||
|
||||
|
||||
Pods without readiness probes are like engineers without coffee. Learn how readiness probes work, why they’re important, and how to configure them correctly.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/managing-slow-container-starts-kubernetes-readiness-probes)
|
||||
|
||||
|
||||
## How to ensure your Kubernetes Pods have enough CPU
|
||||
|
||||
How much CPU should you reserve for your Pod containers? Read this blog to learn how Gremlin can detect underprovisioned or missing CPU requests in your Kubernetes clusters.
|
||||
|
||||
|
||||
|
||||
A common risk is deploying Pods without setting a CPU request. While it may seem like a low-impact, low-severity issue, not using CPU requests can have a big impact, including preventing your Pod from running. In this blog, we explain why missing CPU requests is a risk, how you can detect it using Gremlin, and how you can address it.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/how-to-set-cpu-requests-kubernetes-pods)
|
||||
@@ -0,0 +1,162 @@
|
||||
# Rewriting a Node.js Service in Go With AI Agents
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Edvinas Janusevicius — Checkly
|
||||
- **链接**: https://www.checklyhq.com/blog/agentic-rewrite-nodejs-to-go
|
||||
|
||||
## 简介
|
||||
|
||||
They took a systematic approach using test-driven development. I enjoyed not only learning what went well, but where they ran into trouble.
|
||||
|
||||
## 正文
|
||||
|
||||
Our Results Daemon processes about 92 million messages a day. We recently rewrote it from Node.js to Go, and we let Claude Code write it.
|
||||
|
||||
We wanted to know whether we could trust an agentic rewrite for a critical, high-throughput production service rather than a prototype. It shipped with zero incidents, a 70% reduction in running pods, and a lighter database load. Go's stronger type system also proved a better fit for agents than JavaScript, adding protection against regressions and letting us ship faster and with more confidence.
|
||||
|
||||
What made it work was the test harness we built before the agent wrote a line. Here's how we designed it, and the principles you can reuse on your own legacy services.
|
||||
|
||||
## [The problem](https://www.checklyhq.com#the-problem)
|
||||
|
||||
Checkly is a monitoring platform that runs synthetic checks, automated scripts that emulate real users, and uptime checks that confirm a system component is operational. A runner component executes all of these and produces a result that has to be processed, stored, and alerted on.
|
||||
|
||||
Since we introduced uptime checks, and with the company's overall growth, the volume of checks run on our platform has doubled over the last year. Some components started degrading under that load. The most notable one was Results Daemon, a Node.js component written in vanilla JavaScript.
|
||||
|
||||
Results Daemon is a background worker. It consumes results from our runner, writes them to databases, determines the check outcome, issues alerts, and schedules retries as needed. It also publishes WebSocket updates to our CLI and UI. In total, **this component processes approximately 92,000,000 messages every day**, around 40,000,000 of them check results and the rest WebSocket publishes.
|
||||
|
||||
At that scale, it was becoming a bottleneck. It paged our on-call engineers more often, and limited type safety made every change harder to land safely. So we decided to rewrite Results Daemon in Go using agentic engineering.
|
||||
|
||||
## [Designing a test harness](https://www.checklyhq.com#designing-a-test-harness)
|
||||
|
||||
We built the harness before we started the rewrite. If an agent is going to write the code, something other than a human reviewer has to define what correct means.
|
||||
|
||||
We built it on these design principles:
|
||||
|
||||
- The harness tests the component as a black box. There is zero coupling between the code or language of the system under test and the harness itself.
|
||||
- Every test case provides an input and expects a deterministic output, with all outputs recorded in "golden files." These are generated against the legacy system and later used by the rewrite to assert byte-to-byte parity.
|
||||
- Non-deterministic fields, such as UUIDs or timestamps generated during the test itself, are written as `<uuid>` or`<timestamp>` and are still type-checked, to minimize the risk of differences in behavior slipping through.
|
||||
- Surrounding components (databases, queues, caches, other services) are categorized as boundaries. These are managed strictly by the harness, and the system under test is only pointed at them using environment variables.
|
||||
- Boundaries use real instances of the service in testing. If data is written to PostgreSQL, the harness uses a real PostgreSQL container rather than an emulated one.
|
||||
- For simpler boundaries such as SQS queues, we built our own emulator instead of using ElasticMQ or LocalStack. We found it more performant and simpler, both in our tests and in our assertions.
|
||||
- A set of "oracle" classes fetches the test output and asserts whether the test failed. For example, `PostgresOracle.expectResultToMatchSnapshot(testId)` fetches the relevant output and asserts its byte-level accuracy against the established golden file.
|
||||
|
||||
Three technical choices carried the harness:
|
||||
|
||||
- **Playwright** , a testing framework built for reliability, with strong tooling for network interception and parallel test execution. Our own synthetic monitoring offering is built on Playwright, so we already knew it well, and its black-box model fit what we were doing here.
|
||||
- **Docker Compose** , the simplest way to start and tear down containers for our boundaries, both locally and in CI.
|
||||
- **Toxiproxy** , a TCP proxy that emulates network conditions and let us test how the system behaves when surrounding infrastructure fails.
|
||||
|
||||

|
||||
|
||||
## [Building test cases](https://www.checklyhq.com#building-test-cases)
|
||||
|
||||
With the architecture settled, the next step was building actual test cases. Results Daemon's outputs depend on two things:
|
||||
|
||||
1. The check result, the data object representing the outcome of a check execution. It holds the outcome state of the check run (Failed | Degraded | Success) and other metadata.
|
||||
2. The check configuration at the time the result was received: retry rules for rescheduling, alert rules for notifications, and so on.
|
||||
|
||||
From there it followed quickly that behavior coverage depends directly on the diversity of the inputs. A harness that covers every combination of check result and configuration covers every possible code path, with zero coupling to the implementation. That gave us our first principle:
|
||||
|
||||
- The quality of the harness depends on the quality of the inputs you can provide. The more diverse and realistic the inputs, the greater the coverage of code paths and behaviors. In our case, the number of outcomes is represented by `(accountConfigs × groupConfigs × checkConfigs × resultOutcomes)` .
|
||||
|
||||
We generated those inputs from our internal data lake. We extracted all account, group, and check configurations along with every result outcome from the last 24 hours, which is the longest interval we schedule checks at. We loaded all of it into a ClickHouse instance, and each dataset was "collapsed" into a unique set of configurations and outcomes, each tagged with its number of occurrences. We then used that data to seed realistic scenarios and pin them to business rules. For example, `a re-dispatch takes its runtime from the account when the job pins none`.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
After generating the test cases, we used code coverage reports to estimate how effective the harness was, targeting between 90% and 100%. We also fed those reports back to the agent to review, identify gaps, and propose test cases for anything missed. We expected some gaps to remain, but with all relevant files sufficiently covered and every scoped feature included, we considered the harness ready for a test run.
|
||||
|
||||
- Code coverage is a great metric to track as you start out with your initial set of test cases, since high code coverage means the core behaviors are covered. However, it does measure direct system actual behavior and is therefore likely to miss edge cases.
|
||||
|
||||
We also built a separate suite of tests that caught failure modes when infrastructure failures occur, e.g., PostgreSQL going down, using Toxiproxy. These were focused on how behavior changes and what data is lost when a piece of infrastructure goes down.
|
||||
|
||||
## [The agentic rewrite](https://www.checklyhq.com#the-agentic-rewrite)
|
||||
|
||||
A prerequisite for this approach was an earlier migration to a monorepo running on [Tilt](https://tilt.dev/), which lets us spin up the whole platform end to end in a local development environment.
|
||||
|
||||
We dispatched an instance of Claude Code, using [Fable](https://www.anthropic.com/claude/fable), and gave it one instruction: "build a Go service that consumes data from input queues, processes the messages, and writes the outputs to downstream applications such as databases, caches, and other queues," with the legacy implementation available as a reference. The main acceptance criterion was that the test harness passed against the new implementation.
|
||||
|
||||
The agent ran overnight and produced a deployable service of about 13,000 lines of application code, architecturally mirroring the legacy implementation. **It also kept token usage within the daily limits of a $200 subscription.**
|
||||
|
||||
We ran an earlier attempt with the same instructions using [Opus](https://www.anthropic.com/claude/opus). That implementation did not meet our bar and was discarded.
|
||||
|
||||

|
||||
|
||||
After reviewing the implementation, we deployed the application to every environment except production, using an internal account to push results so we could get feedback quickly. The review also surfaced anti-patterns we wanted gone and improvements we wanted in:
|
||||
|
||||
- Removing configuration generated at runtime. The legacy application derived its configuration from partial values provided via environment variables. That has been a pain point in the past when debugging and making configuration changes, especially under pressure during incidents.
|
||||
- Improving end-to-end observability. The legacy service had high-level observability, but given the increase in throughput, there was clear room to do better.
|
||||
|
||||
We implemented both with human supervision, which gave us two more principles:
|
||||
|
||||
- Human intervention is sometimes required, especially to find and fix anti-patterns an agent inherited from the legacy application or introduced itself. For us this meant removing all configuration derivations and making static environment variables the only way the application is configured, plus improving observability. That improved the system's operability and simplified the code in both the rewrite and the harness.
|
||||
- Take the rewrite as an opportunity to improve things. In our case that meant expanding end-to-end observability. At this message volume, recording low-level metrics such as database connection utilization, CPU, memory, and timings of individual code execution steps was a necessary addition for long-term operational excellence.
|
||||
|
||||
With those in place, the next step was production.
|
||||
|
||||
## [First deployment: what we got wrong](https://www.checklyhq.com#first-deployment-what-we-got-wrong)
|
||||
|
||||
Before deploying, we had to decide how to migrate customers. The simplest approach was to spin up separate infrastructure (queues) and patch the consumers to push data to the new queue for accounts with a specific feature flag enabled.
|
||||
|
||||

|
||||
|
||||
Once the infrastructure was ready, we deployed the Go application across all environments and migrated internal accounts. We ran into issues almost immediately, mainly retries failing.
|
||||
|
||||
The root cause was a critical gap in the harness: our local environment's surrounding infrastructure did not match production. The harness modeled a simplified local queue topology instead of the real one. Locally, retries were routed to 3 queues based on check type alone. In production, routing also depends on factors like priority and hosting type, for a total of 18 possible queues per region. Because the harness assumed the local topology, the agent built its retry logic around it, and the gap made its way into the new application.
|
||||
|
||||
We made that mistake during design. The initial boundary classification was too high-level and assumed production behavior that proved wrong.
|
||||
|
||||
We updated the harness to align with production, removed all code branches that only ran in the local environment, and followed up with a human-supervised refactor of the retry module. A day later, the daemon was processing results for our internal accounts, around 3% of total platform load.
|
||||
|
||||
The retry-queue gap left us with three principles for the harness going forward:
|
||||
|
||||
- The harness environment must align with production as closely as possible.
|
||||
- Every boundary must be established down to its lowest unit. Every single queue, every DB table, accounted for.
|
||||
- Every assumption about the surrounding infrastructure must be written down and verified, not inferred.
|
||||
|
||||
## [Rolling out to customers](https://www.checklyhq.com#rolling-out-to-customers)
|
||||
|
||||
The migration strategy was deliberately boring. Before migrating any customer, the new daemon had already been through the harness and a full rollout across our own internal accounts on real production traffic. On top of that, we migrated customer accounts in stages to reduce blast radius, so each cohort benefited from what we learned on the previous one:
|
||||
|
||||
1. Free accounts, on a trial period or hobbyists.
|
||||
2. Paid accounts, on a monthly subscription.
|
||||
3. Enterprise accounts, with signed enterprise deals.
|
||||
|
||||
Migrating a cohort meant flipping a feature flag, which instantly switched their traffic from the legacy daemon to the new one. After each flip, we monitored for 24 to 48 hours to confirm no results were dropped, failure rates across the platform stayed consistent, and no support escalations pointed back to the daemon before moving on.
|
||||
|
||||
During this period, both daemons were processing real traffic, which meant both had to stay in sync. A change in one needed to land in the other. To enforce that without slowing anyone down, we updated CI to run the harness against both the legacy application and the new daemon, blocking any pull request that failed for either.
|
||||
|
||||
When customers found or flagged bugs, we used a simple TDD loop to fix them: reproduce the gap in the harness first, then fix the underlying issue. That let us close an issue in about an hour, including CI and deployment time.
|
||||
|
||||
The issues we hit were minor, and nearly all of them were edge cases the harness hadn't covered. Beyond those, none of our customers noticed they had been migrated.
|
||||
|
||||

|
||||
|
||||
After a week of migrating customers, monitoring dashboards, and fixing small bugs, the migration was complete, and we decommissioned the legacy workload.
|
||||
|
||||
## [Results](https://www.checklyhq.com#results)
|
||||
|
||||
### [Better database performance](https://www.checklyhq.com#better-database-performance)
|
||||
|
||||
- The tooling we chose to talk to the database, [sqlc](https://sqlc.dev/) , produced more performant queries.
|
||||
- Row locking dropped because Go's concurrency model executes operations inside transactions faster.
|
||||
- Together, that gave us **60% fewer total average active sessions (AAS) on our database and a roughly 15% reduction in database CPU** .
|
||||
|
||||
### [Improved efficiency and operability](https://www.checklyhq.com#improved-efficiency-and-operability)
|
||||
|
||||
- The new daemon freed up around 15 vCPU and 45GB of memory, as the new application needed far fewer pods to support the workload.
|
||||
- The additional observability built into the new application helps with triaging during any alerts or incidents and enables us to make informed decisions when refactoring the code.
|
||||
|
||||
### [Improved developer experience](https://www.checklyhq.com#improved-developer-experience)
|
||||
|
||||
- Go's type system works much better with agents and adds another layer of protection against regressions.
|
||||
- The test harness guarantees consistent behavior before any rollout. That confidence shows up as faster feature and bug-fix shipping, more frequent deployments, and fewer alerts for our on-call engineers.
|
||||
|
||||
With a harness that validates behavior at this level of rigor, **we can now ship agent-written code faster than before**, trusting the harness to catch regressions instead of relying on manual review alone.
|
||||
|
||||
## [Summary](https://www.checklyhq.com#summary)
|
||||
|
||||
Rewriting legacy applications is never easy, even with agents doing the heavy lifting. We got there by designing and building a strict test harness first, then letting the agent work inside it. Rigorous testing, strict boundary definition, and knowing when to step in as a human are what made this work, and those principles will hold up as the tooling keeps changing.
|
||||
|
||||
If you want to see the testing philosophy behind this in a product rather than a blog post, it is the same one behind Checkly: [Monitoring as Code](https://www.checklyhq.com/product/monitoring-as-code/), real Playwright scripts running against production, and results you can trust enough to act on. [Start monitoring for free](https://www.checklyhq.com/), or read the [docs](https://www.checklyhq.com/docs/) to see how it fits your stack.
|
||||
@@ -0,0 +1,78 @@
|
||||
# Supporting Your Team’s New Responders
|
||||
|
||||
- **期号**: SRE Weekly Issue #534(2026-09-14)
|
||||
- **作者**: Karan Nagarajagowda — Uptime Labs
|
||||
- **链接**: https://www.uptimelabs.io/articles/supporting-new-responders
|
||||
|
||||
## 简介
|
||||
|
||||
Great advice if you’re training early-career engineers on incident response. This advice reminds me of some of the techniques that folks used with me when I was starting out.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
### Ready to make incident response your competitive advantage?
|
||||
|
||||
See how Uptime Labs builds provable, scalable incident response capability across your organisation.
|
||||
|
||||
*Bringing new people into on-call can be daunting: for them (obviously), but also for you. Karan Nagarajagowda shares what works when supporting junior engineers through their first high-severity incidents and why your leadership in those moments matters.*
|
||||
|
||||
|
||||
When a junior engineer joins their first high-severity incident, there's a particular kind of nerves that comes with it. They're newer to the system than everyone else in the room. Senior engineers are firing context at each other in shorthand. And they're trying to work out whether they're meant to help, observe or quietly disappear, as the seconds are trickling away.
|
||||
|
||||
Your job as a leader or senior engineer is to coordinate, so they can contribute and communicate. You know that you’ll have nailed it if they leave the incident non-traumatically, feeling like they grew their skills & confidence.
|
||||
|
||||
|
||||
## 1. Assign clear, explicit instructions
|
||||
|
||||
Be specific in what you ask your junior or newer engineers to do, e.g. *"Can you check the metrics and validate them?" "Can you check the logs and correlate with when the issue started?" "Can you do the timeline check and document it?"*
|
||||
|
||||
These types of crisp asks turn a nervous junior into a contributing teammate. Vague instructions like *"help us debug this"* tend to produce paralysis. Explicit, scoped tasks produce results, increasing confidence with every one completed.
|
||||
|
||||
This type of communication removes ambiguity, allowing closer alignment of [mental models](https://www.uptimelabs.io/articles/mental-models-all-the-way-down). The result should therefore yield better results. Recall an important [David D. Woods & John Allspaw](https://cacm.acm.org/practice/revealing-the-critical-role-of-human-performance-in-software/) quote:
|
||||
|
||||
*"Without the cognitive work that people engage in with each other, all software systems eventually fail."*
|
||||
|
||||
|
||||
## 2. Pair with a senior engineer
|
||||
|
||||
Wherever you can, pair a junior engineer with a senior one during an incident to build psychological safety quickly. The senior engineer is there to backstop technical decisions and model how to behave under pressure, and the junior engineer gets to ask the questions they might not want to ask in front of the whole room.
|
||||
|
||||
It's also how new patterns spread. Watching how a senior engineer reads a metric, frames an update, or decides when to escalate is worth more than any post-incident review.
|
||||
|
||||
|
||||
## 3. Embrace blamelessness and demand it from the team
|
||||
|
||||
This one is non-negotiable. The moment a junior engineer fears embarrassment, they stop contributing. And you lose the very observations that often crack the case open.
|
||||
|
||||
Blameless culture isn't a slogan; it's an operating condition for fast incident response. If your new staff are worried about being publicly corrected for guessing wrong, they will stop saying what they actually see, and you'll lose visibility into the problem space right when you need it most.
|
||||
|
||||
As the leader in the room, your tone sets this: it's okay for them to be wrong. It's okay for them to say "I don't know." It's okay for them to flag something that turns out to be unrelated. The cost of staying quiet is almost always higher than the cost of imperfect input.
|
||||
|
||||
[Cat Hicks](https://www.linkedin.com/posts/drcathicks_if-youre-a-high-performing-person-doing-activity-7478149380361965568-mQhH?utm_source=share&utm_medium=member_desktop&rcm=ACoAAAPVTVYBV-MFODC2aB0sCwwEeBjOqW2SyyM) wrote about this relationship between perceived performance and organisational framing about a month ago:
|
||||
|
||||
*‘When a developer struggles, the organization frames its question as something like this: is this person missing skills? Or a team misses its targets, so it asks...who do we need to move out? A project fails....well who owns that and didn't work hard enough?*
|
||||
|
||||
*In my experience, the technical teams that move forward rapidly right now aren't asking "do we have the right people?" but rather "have we built conditions where people can show us what they can do? Where people can be their best selves?"*
|
||||
|
||||
|
||||
## 4. Use the runbook as a springboard to encourage problem-solving
|
||||
|
||||
A good runbook can for sure be helpful for new on-call staff in an incident. Yet it can be a double-edged sword. It can create brittleness, reduce an incident responder to a mere command executor and take away problem-solving. Or it can give the practitioner access to clues from past incidents. Recall Dwight Eisenhower’s famous quote: *"In preparing for battle, I have always found that plans are useless, but planning is indispensable."* Overall, the runbook can note how similar incidents were resolved in the past and explain why a certain sequence of steps worked. Therefore, incident leaders can encourage responders to draw inspiration from the runbook while doing their own problem-solving.
|
||||
|
||||
|
||||
## 5. Practise before it counts
|
||||
|
||||
Mock incidents (or [incident simulations](https://www.uptimelabs.io/)) are the most reliable way to build incident reflexes without the real-world stakes. I run my drills to intentionally include ambiguity, incomplete information, and communication pressure: exactly the things that make a real incident feel disorienting.
|
||||
|
||||
The goal isn't to memorise a runbook. It's to help your team discover what *they* tend to do under pressure (freeze, over-talk, dive too deep, miss the comms), so they can adjust before it matters. Back in the day, the only way to do this was to go through a lot of painful incidents. Now, you can get the same palm-sweating experience, minus the actual downtime.
|
||||
|
||||
|
||||
## Being clear about your role
|
||||
|
||||
When a junior engineer or new on-call staff member walks into their first real incident, the culture they find will shape everything that follows. You can give them all the tools in the world: runbooks, a paired senior, an explicit task. But if you enter into that incident room armed with pressure and blame, they'll feel it and shut down.
|
||||
|
||||
Your coordination and communication skills in early incidents matter and influence their ongoing success. Let’s end on this, by author [Jon Gordon](https://www.google.co.uk/books/edition/The_Carpenter/S5M6AwAAQBAJ?hl=en&gbpv=1&printsec=frontcover): ‘You are not a true success unless you are helping others be successful’.
|
||||
|
||||
|
||||
Reference in New Issue
Block a user