SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,33 @@
|
||||
# Safety Moment – The Power of Local Rational…it is big!
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: http://preaccidentpodcast.podbean.com/e/safety-moment-the-power-of-local-rationalit-is-big/
|
||||
|
||||
## 简介
|
||||
|
||||
Local Rationale: the reasoning and context behind a decision that an operator made. Here’s Todd Conklin reminding us to find out what was really going on when the benefit of hindsight makes a decision seem irrational.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
Jan 3, 2018
|
||||
|
||||
# Safety Moment - The Power of Local Rational...it is big!
|
||||
|
||||
What was the worker thinking when the worker triggered the condtions that led to the failure?
|
||||
|
||||
Everybody does what they do for some reason.
|
||||
|
||||
Here is our chance to discuss this - again.
|
||||
|
||||
Listen and see what you think.
|
||||
|
||||
Best Safety Podcast, Safety Program, Safety Storytelling, Investigations, Human Performance, Safety Differently, Operational Excellence, Resilience Engineering, Safety and Resilience Incentives
|
||||
|
||||
Give this a listen.
|
||||
|
||||
Thanks for listening and tell your friends. See you on a ski lift some place.
|
||||
|
||||
No comments yet. Be the first to say something!
|
||||
@@ -0,0 +1,217 @@
|
||||
# Building a Distributed Log from Scratch, Part 2: Data Replication
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: https://bravenewgeek.com/building-a-distributed-log-from-scratch-part-2-data-replication/
|
||||
|
||||
## 简介
|
||||
|
||||
In part two of the series I linked to last week, Tyler Treat introduces data replication strategies including replicating data to all replicas before returning or just a quorum.
|
||||
|
||||
## 正文
|
||||
|
||||
In [part one](https://bravenewgeek.com/building-a-distributed-log-from-scratch-part-1-storage-mechanics/) of this series we introduced the idea of a message log, touched on why it’s useful, and discussed the storage mechanics behind it. In part two, we discuss data replication.
|
||||
|
||||
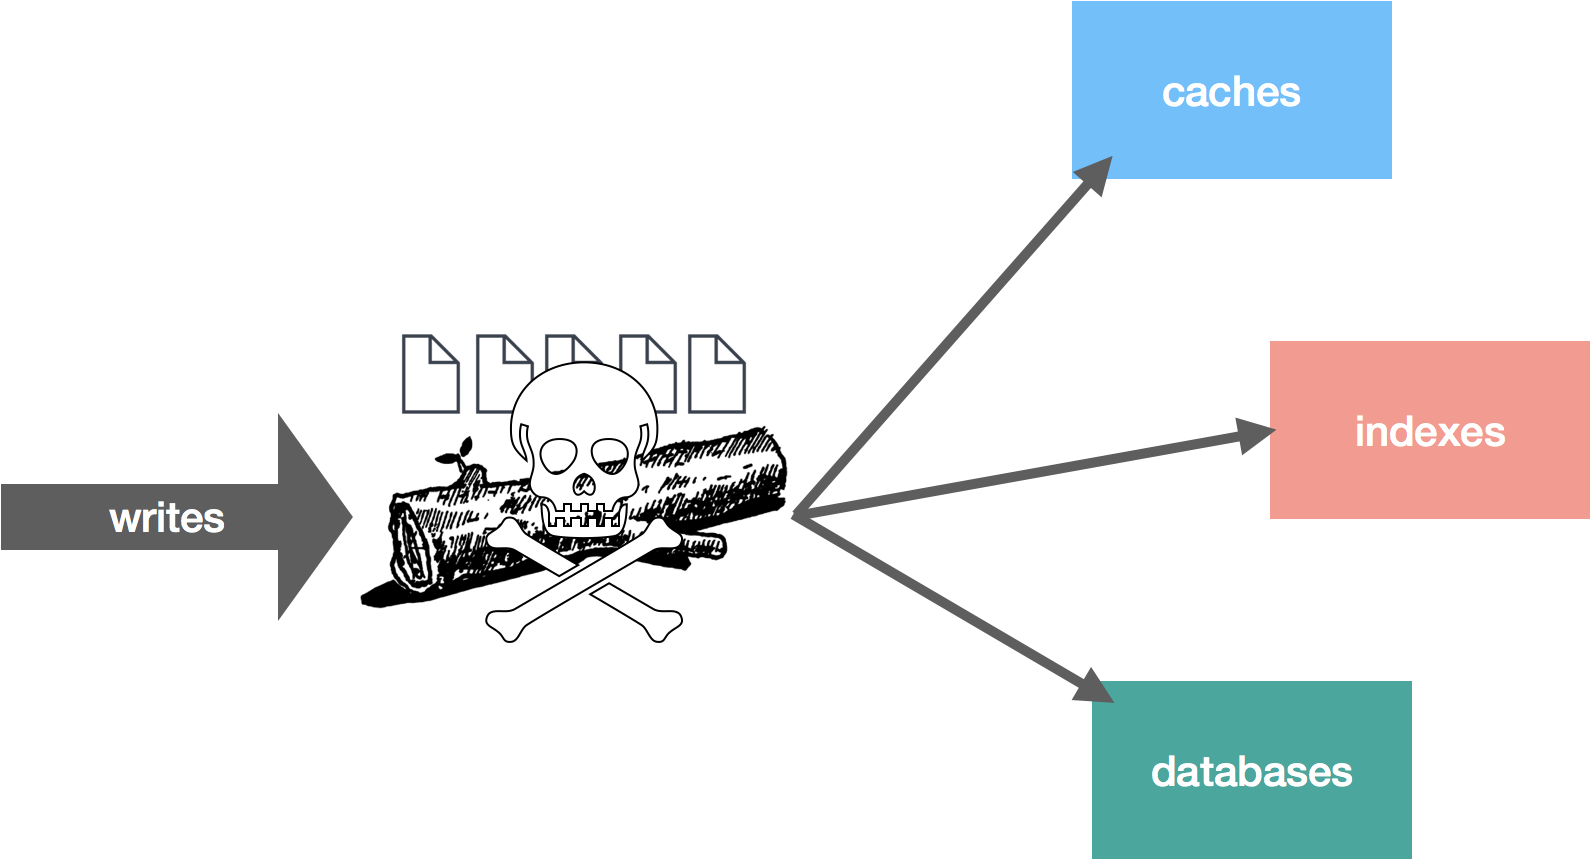
We have our log. We know how to write data to it and read it back as well as how data is persisted. The caveat to this is, although we have a durable log, it’s a single point of failure (SPOF). If the machine where the log data is stored dies, we’re SOL. Recall that one of our three priorities with this system is high availability, so the question is how do we achieve high availability and fault tolerance?
|
||||
|
||||
|
||||
|
||||
|
||||
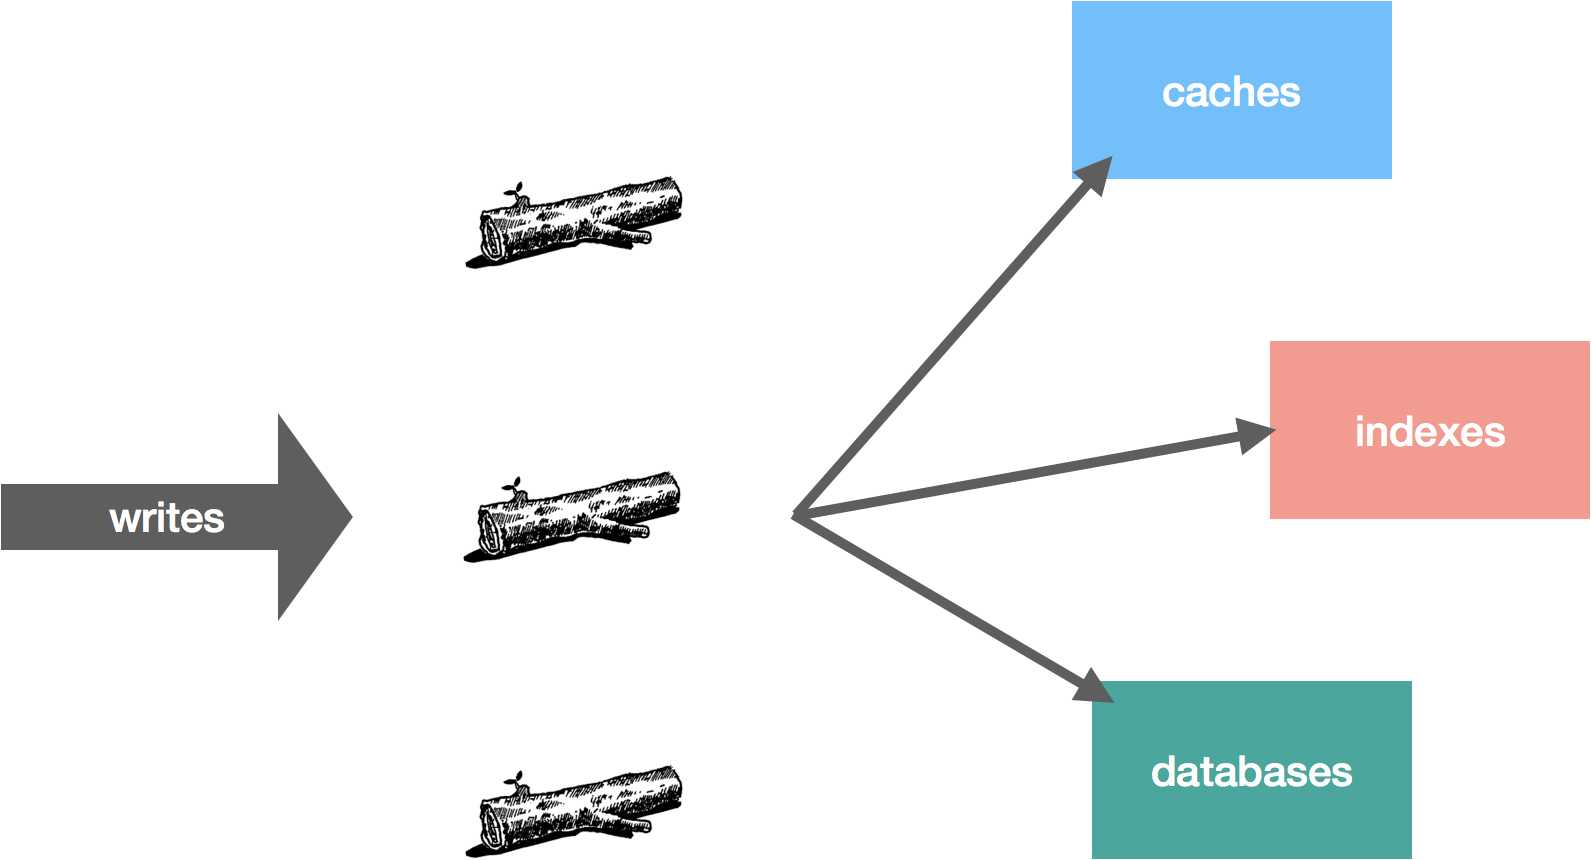
With high availability, we’re specifically talking about ensuring continuity of reads and writes. A server failing shouldn’t preclude either of these, or at least unavailability should be kept to an absolute minimum and without the need for operator intervention. Ensuring this continuity should be fairly obvious: we eliminate the SPOF. To do that, we replicate the data. Replication can also be a means for increasing scalability, but for now we’re only looking at this through the lens of high availability.
|
||||
|
||||
|
||||
|
||||
|
||||
There are a number of ways we can go about replicating the log data. Broadly speaking, we can group the techniques into two different categories: gossip/multicast protocols and consensus protocols. The former includes things like epidemic broadcast trees, bimodal multicast, SWIM, HyParView, and NeEM. These tend to be eventually consistent and/or stochastic. The latter, which I’ve described in more detail [here](https://bravenewgeek.com/understanding-consensus/), includes 2PC/3PC, Paxos, Raft, Zab, and chain replication. These tend to favor strong consistency over availability.
|
||||
|
||||
So there are a lot of ways we can replicate data, but some of these solutions are better suited than others to this particular problem. Since ordering is an important property of a log, consistency becomes important for a *replicated* log. If we read from one replica and then read from another, it’s important those views of the log don’t conflict with each other. This more or less rules out the stochastic and eventually consistent options, leaving us with consensus-based replication.
|
||||
|
||||
There are essentially two components to consensus-based replication schemes: 1) designate a leader who is responsible for sequencing writes and 2) replicate the writes to the rest of the cluster.
|
||||
|
||||
Designating a leader can be as simple as a configuration setting, but the purpose of replication is fault tolerance. If our configured leader crashes, we’re no longer able to accept writes. This means we need the leader to be dynamic. It turns out leader election is a well-understood problem, so we’ll get to this in a bit.
|
||||
|
||||
Once a leader is established, it needs to replicate the data to followers. In general, this can be done by either waiting for all replicas or waiting for only a quorum (majority) of replicas. There are pros and cons to both approaches.
|
||||
|
||||
**Pros**
|
||||
|
||||
**Cons**
|
||||
|
||||
**All Replicas**
|
||||
|
||||
Tolerates *f* failures with *f+1* replicas
|
||||
|
||||
Latency pegged to slowest replica
|
||||
|
||||
**Quorum**
|
||||
|
||||
Hides delay from a slow replica
|
||||
|
||||
Tolerates *f* failures with *2f+1* replicas
|
||||
|
||||
Waiting on all replicas means we can make progress as long as at least one replica is available. With quorum, tolerating the same amount of failures requires more replicas because we need a majority to make progress. The trade-off is that the quorum hides any delays from a slow replica. Kafka is an example of a system which uses all replicas (with some conditions on this which we will see later), and NATS Streaming is one that uses a quorum. Let’s take a look at both in more detail.
|
||||
|
||||
### Replication in Kafka[#](https://bravenewgeek.com#replication-in-kafka)
|
||||
|
||||
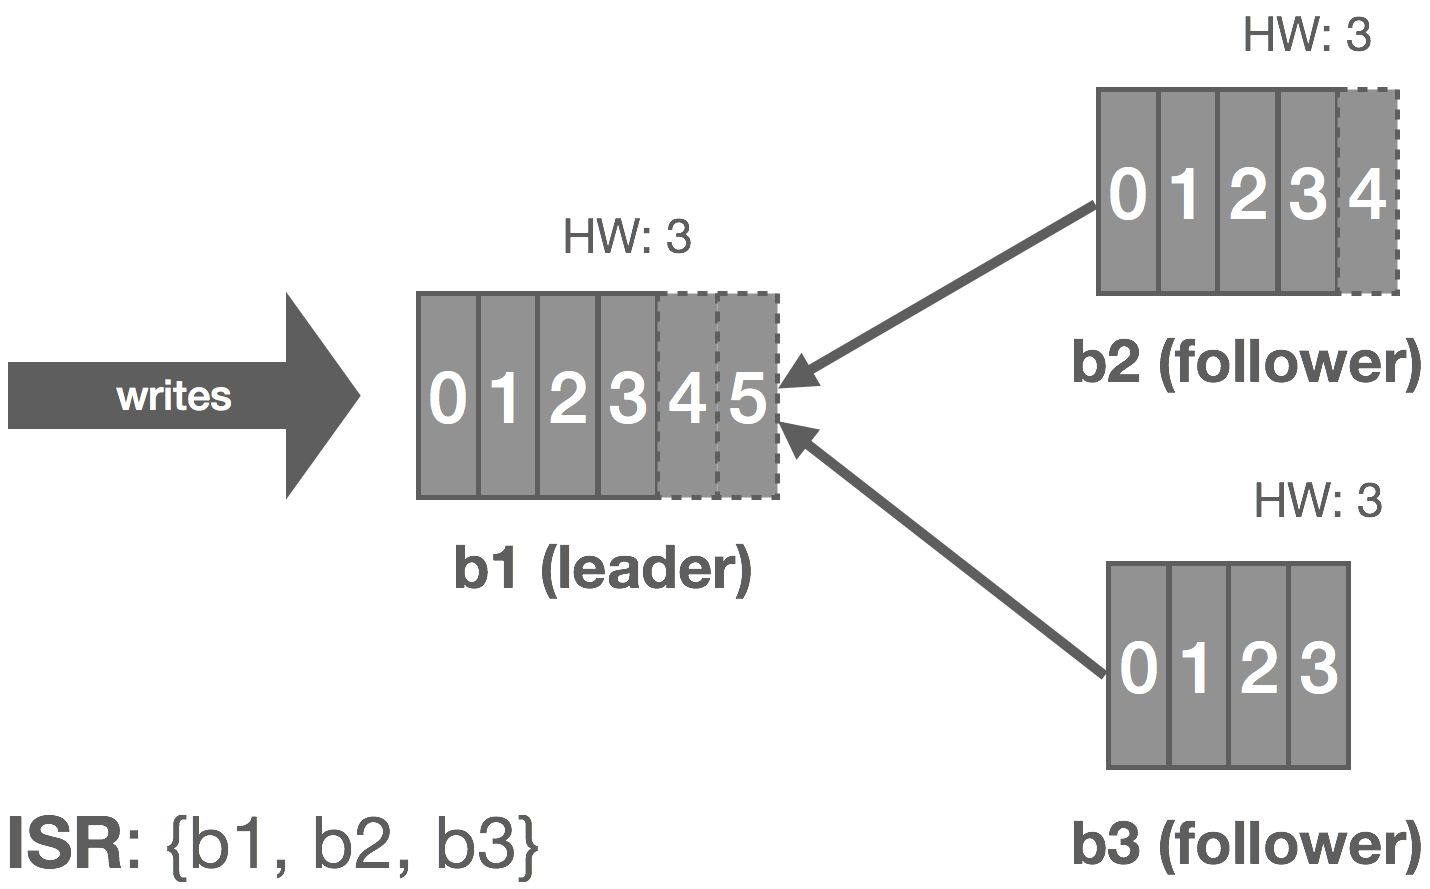
In Kafka, a leader is selected (we’ll touch on this in a moment). This leader maintains an in-sync replica set (ISR) consisting of all the replicas which are fully caught up with the leader. This is every replica, by definition, at the beginning. All reads and writes go through the leader. The leader writes messages to a write-ahead log (WAL). Messages written to the WAL are considered uncommitted or “dirty” initially. The leader only commits a message once all replicas in the ISR have written it to their own WAL. The leader also maintains a high-water mark (HW) which is the last committed message in the WAL. This gets piggybacked on the replica fetch responses from which replicas periodically checkpoint to disk for recovery purposes. The piggybacked HW then allows replicas to know when to commit.
|
||||
|
||||
Only committed messages are exposed to consumers. However, producers can configure how they want to receive acknowledgements on writes. It can wait until the message is committed on the leader (and thus replicated to the ISR), wait for the message to only be written (but not committed) to the leader’s WAL, or not wait at all. This all depends on what trade-offs the producer wants to make between latency and durability.
|
||||
|
||||
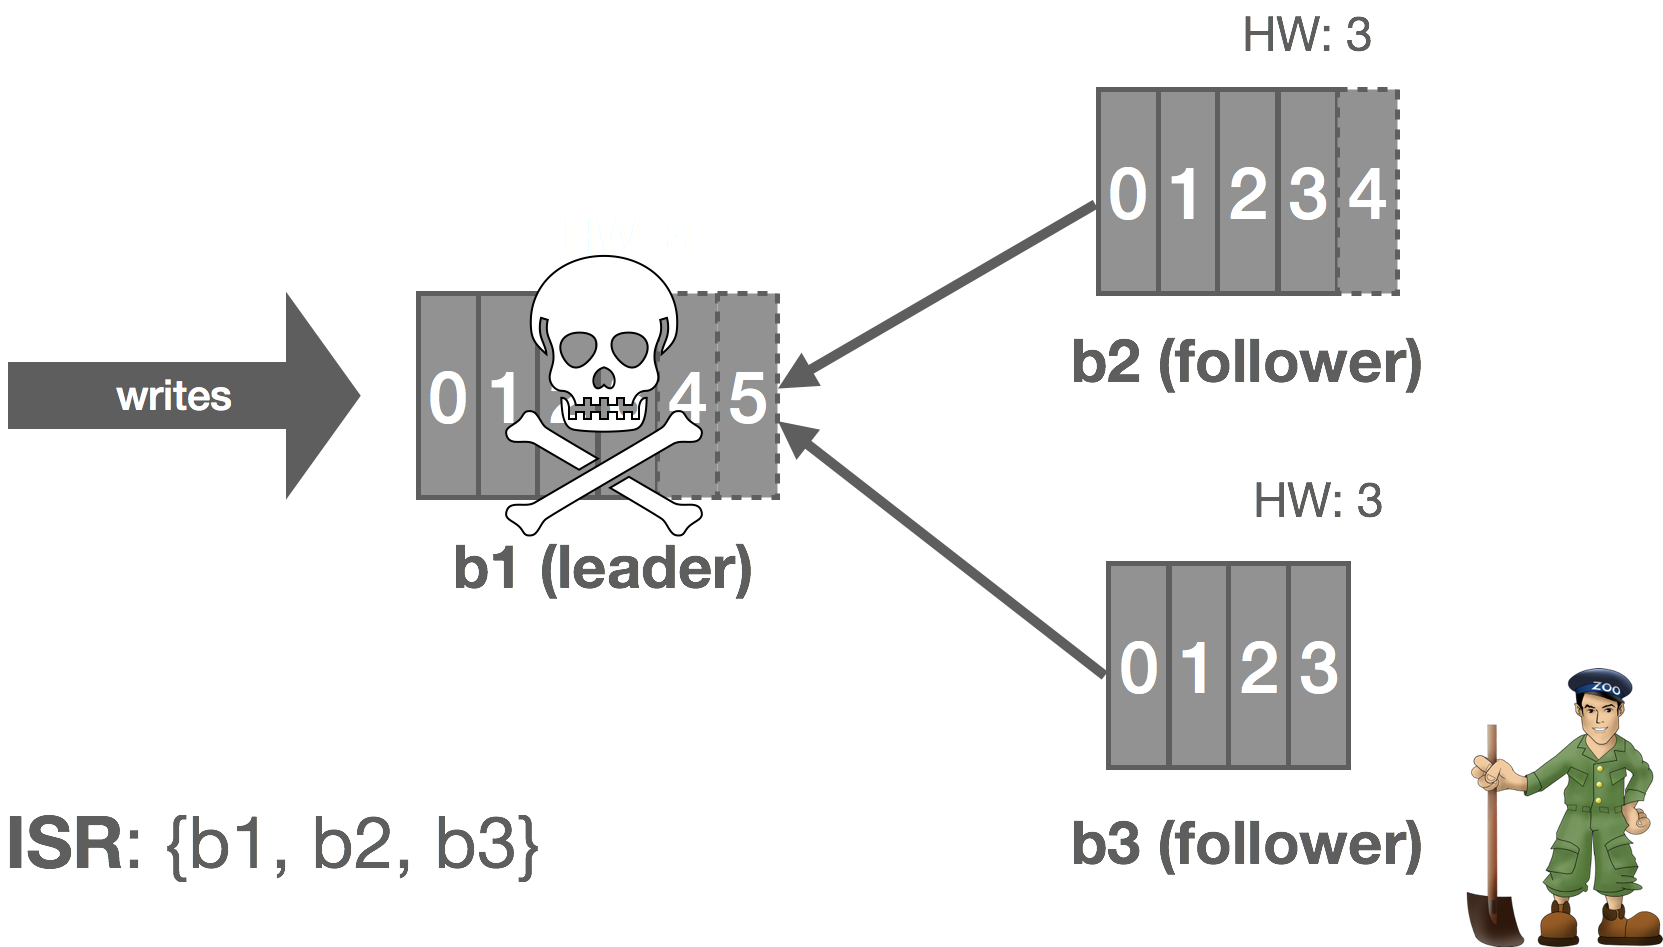
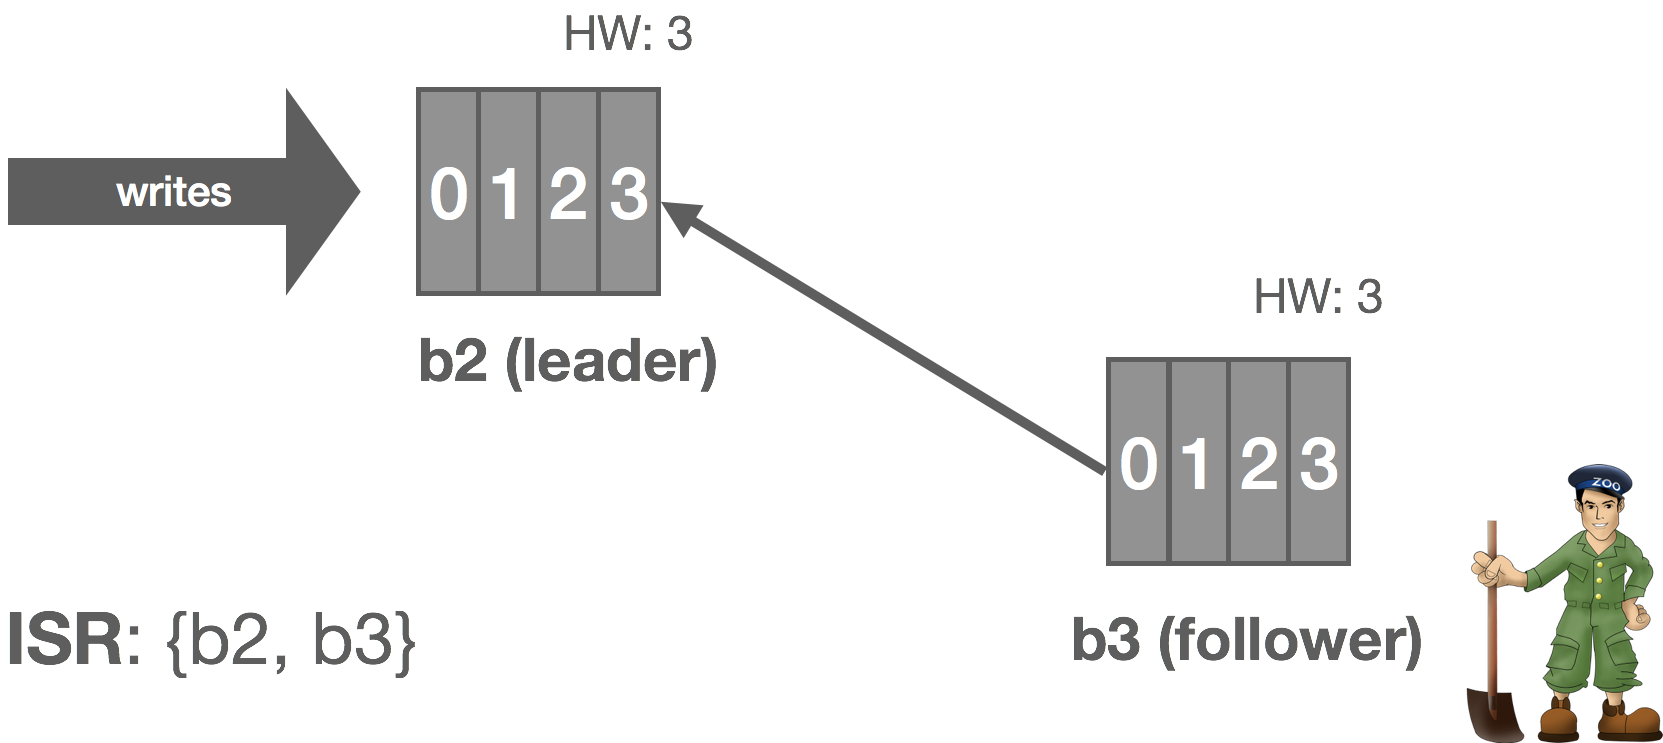
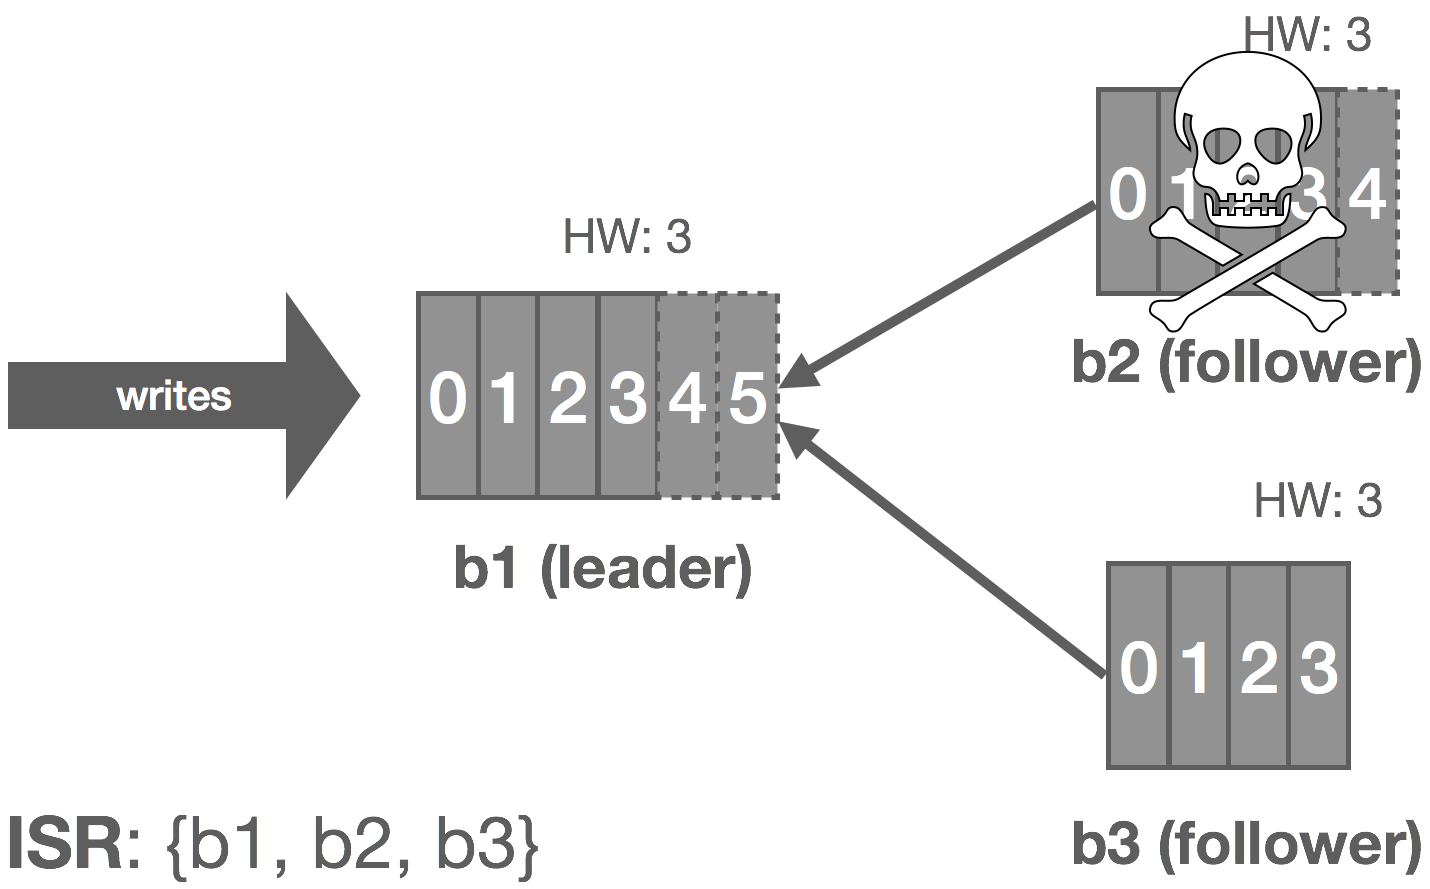
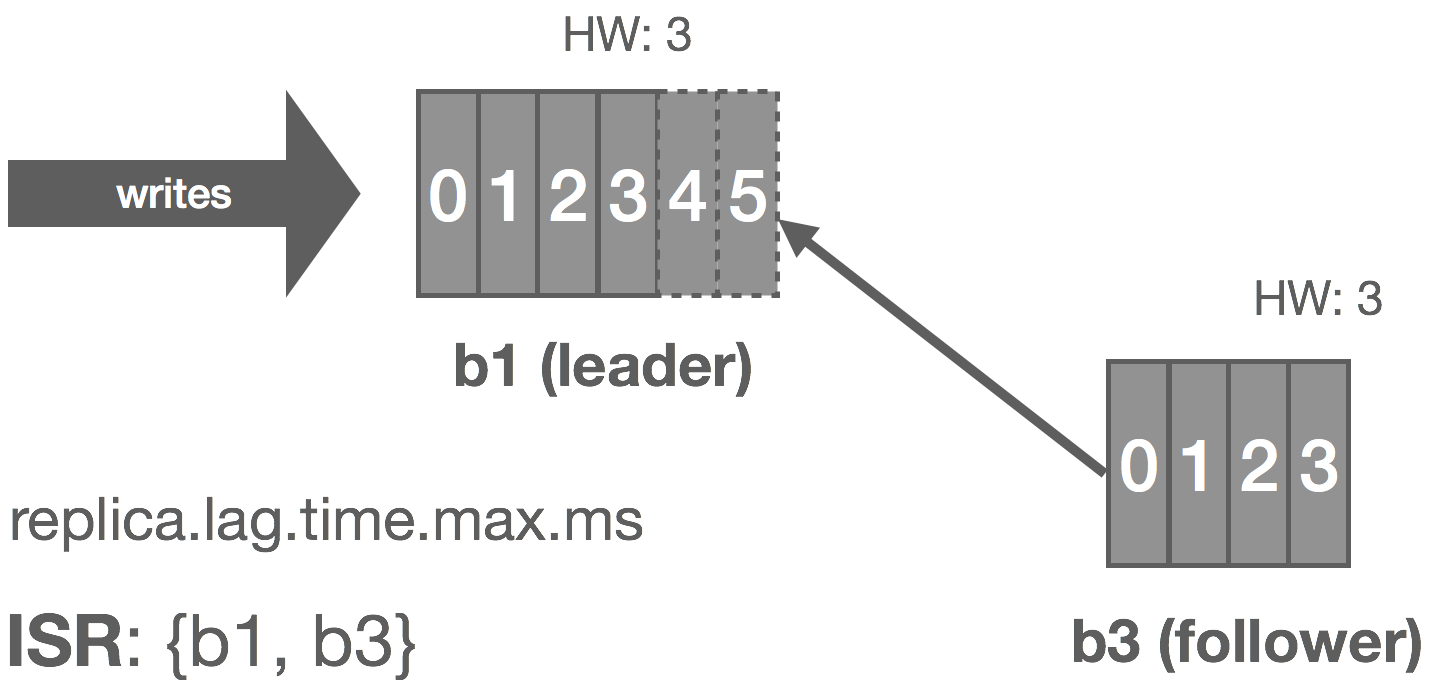
The graphic below shows how this replication process works for a cluster of three brokers: *b1*, *b2*, and *b3*. Followers are effectively special consumers of the leader’s log.
|
||||
|
||||
|
||||
|
||||
|
||||
Now let’s look at a few failure modes and how Kafka handles them.
|
||||
|
||||
#### Leader Fails[#](https://bravenewgeek.com#leader-fails)
|
||||
|
||||
Kafka relies on [Apache ZooKeeper](https://zookeeper.apache.org/) for certain cluster coordination tasks, such as leader election, though this is not actually how the log leader is elected. A Kafka cluster has a single controller broker whose election is handled by ZooKeeper. This controller is responsible for performing administrative tasks on the cluster. One of these tasks is selecting a new log leader (actually *partition* leader, but this will be described later in the series) from the ISR when the current leader dies. ZooKeeper is also used to detect these broker failures and signal them to the controller.
|
||||
|
||||
|
||||
|
||||
|
||||
Thus, when the leader crashes, the cluster controller is notified by ZooKeeper and it selects a new leader from the ISR and announces this to the followers. This gives us automatic failover of the leader. All committed messages up to the HW are preserved and uncommitted messages may be lost during the failover. In this case, *b1* fails and *b2* steps up as leader.
|
||||
|
||||
|
||||
|
||||
|
||||
#### Follower Fails[#](https://bravenewgeek.com#follower-fails)
|
||||
|
||||
The leader tracks information on how “caught up” each replica is. Before Kafka 0.9, this included both how many messages a replica was behind, *replica.lag.max.messages*, and the amount of time since the replica last fetched messages from the leader, *replica.lag.time.max.ms*. Since 0.9, *replica.lag.max.messages* was removed and *replica.lag.time.max.ms* now refers to both the time since the last fetch request *and* the amount of time since the replica last caught up.
|
||||
|
||||
|
||||
|
||||
|
||||
Thus, when a follower fails (or stops fetching messages for whatever reason), the leader will detect this based on *replica.lag.time.max.ms*. After that time expires, the leader will consider the replica out of sync and remove it from the ISR. In this scenario, the cluster enters an “under-replicated” state since the ISR has shrunk. Specifically, *b2* fails and is removed from the ISR.
|
||||
|
||||
|
||||
|
||||
|
||||
#### Follower Temporarily Partitioned[#](https://bravenewgeek.com#follower-temporarily-partitioned)
|
||||
|
||||
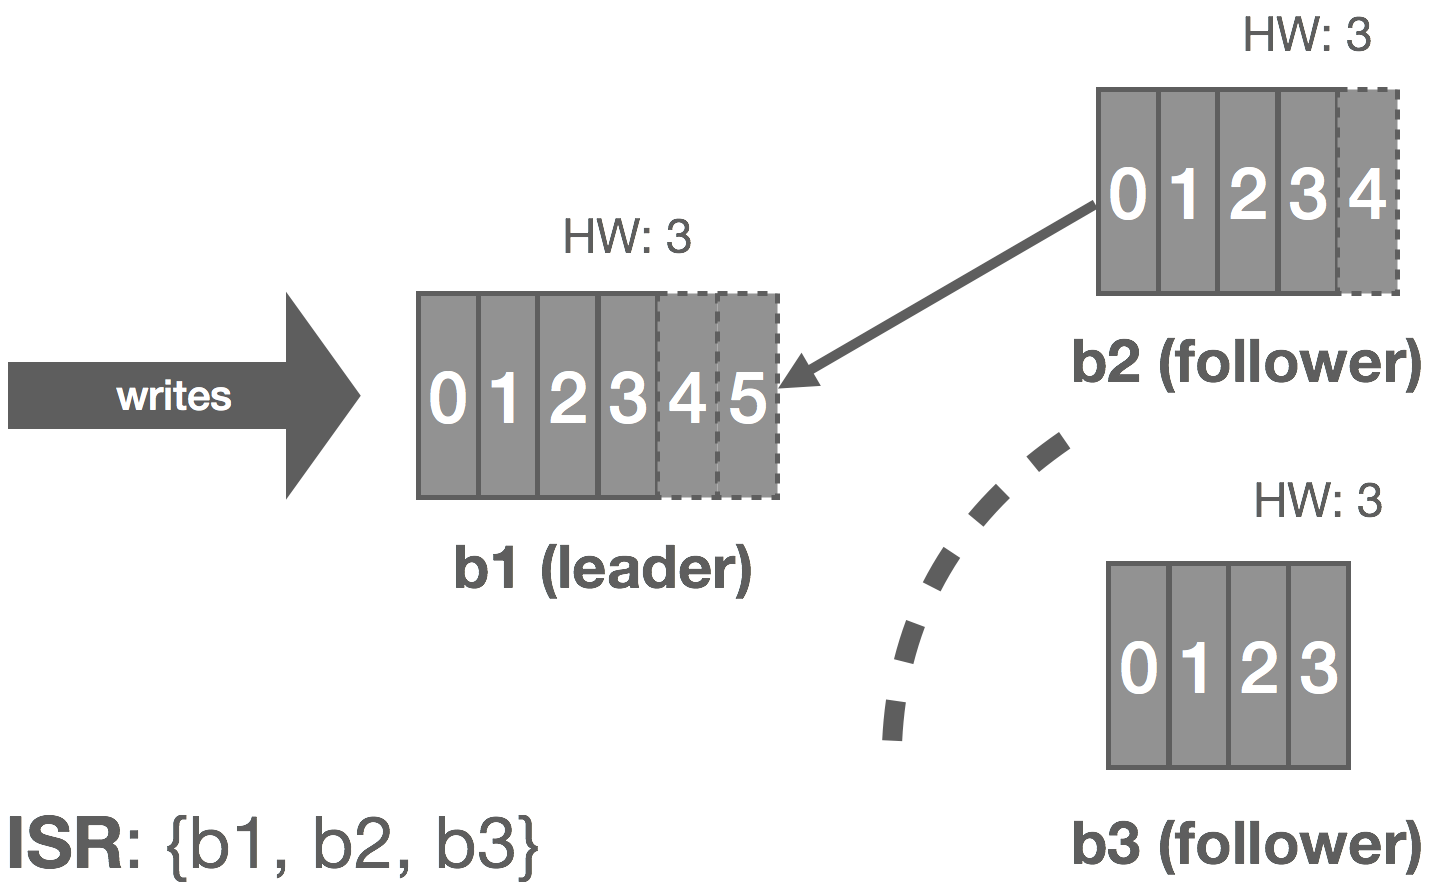
The case of a follower being temporarily partitioned, e.g. due to a transient network failure, is handled in a similar fashion to the follower itself failing. These two failure modes can really be combined since the latter is just the former with an arbitrarily long partition, i.e. it’s the difference between crash-stop and crash-recovery models.
|
||||
|
||||
|
||||
|
||||
|
||||
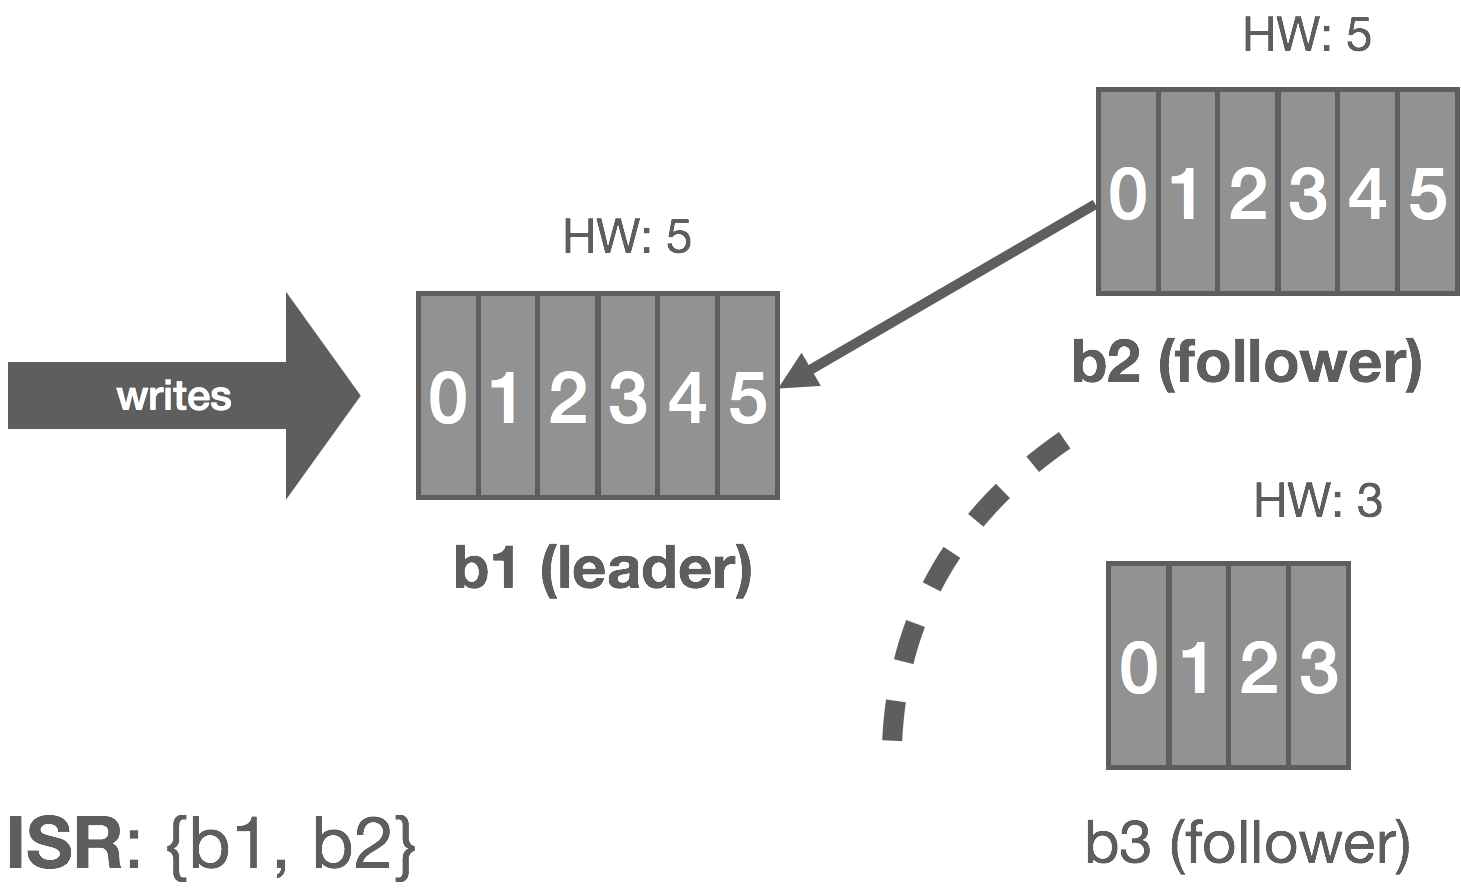
In this case, *b3* is partitioned from the leader. As before, *replica.lag.time.max.ms* acts as our failure detector and causes *b3* to be removed from the ISR. We enter an under-replicated state and the remaining two brokers continue committing messages 4 and 5. Accordingly, the HW is updated to 5 on these brokers.
|
||||
|
||||
|
||||
|
||||
|
||||
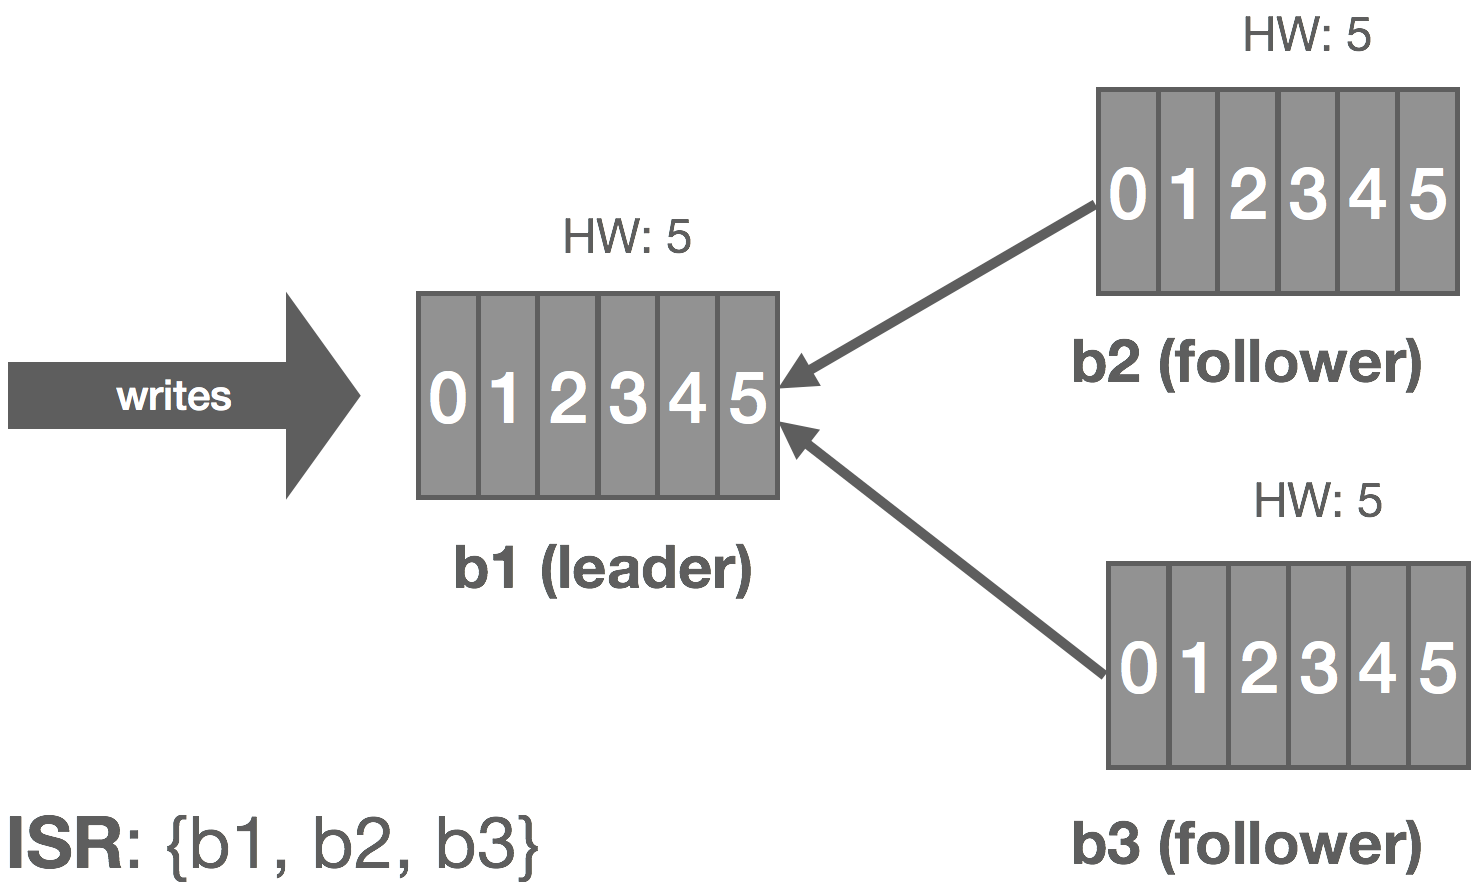
When the partition heals, *b3* continues reading from the leader and catching up. Once it is fully caught up with the leader, it’s added back into the ISR and the cluster resumes its fully replicated state.
|
||||
|
||||
|
||||
|
||||
|
||||
We can generalize this to the crash-recovery model. For example, instead of a network partition, the follower could crash and be restarted later. When the failed replica is restarted, it recovers the HW from disk and truncates its log up to the HW. This preserves the invariant that messages after the HW are not guaranteed to be committed. At this point, it can begin catching up from the leader and will end up with a log consistent with the leader’s once fully caught up.
|
||||
|
||||
### Replication in NATS Streaming[#](https://bravenewgeek.com#replication-in-nats-streaming)
|
||||
|
||||
NATS Streaming relies on the [Raft consensus algorithm](https://raft.github.io/) for leader election and data replication. This sometimes comes as a surprise to some as Raft is largely seen as a protocol for replicated state machines. We’ll try to understand why Raft was chosen for this particular problem in the following sections. We won’t dive deep into Raft itself beyond what is needed for the purposes of this discussion.
|
||||
|
||||
While a log is a state machine, it’s a very simple one: a series of appends. Raft is frequently used as the replication mechanism for key-value stores which have a clearer notion of “state machine.” For example, with a key-value store, we have *set* and *delete* operations. If we set *foo = bar* and then later set *foo = baz*, the state gets rolled up. That is, we don’t necessarily care about the provenance of the key, only its current state.
|
||||
|
||||
However, NATS Streaming differs from Kafka in a number of key ways. One of these differences is that NATS Streaming attempts to provide a sort of unified API for streaming and queueing semantics not too dissimilar from [Apache Pulsar](https://pulsar.apache.org/). This means, while it has a notion of a log, it also has subscriptions on that log. Unlike Kafka, NATS Streaming tracks these subscriptions and metadata associated with them, such as where a client is in the log. These have definite “state machines” affiliated with them, like creating and deleting subscriptions, positions in the log, clients joining or leaving queue groups, and message-redelivery information.
|
||||
|
||||
Currently, NATS Streaming uses multiple Raft groups for replication. There is a single metadata Raft group used for replicating client state and there is a separate Raft group per topic which replicates messages and subscriptions.
|
||||
|
||||
Raft solves both the problems of leader election and data replication in a single protocol. The [Secret Lives of Data](http://thesecretlivesofdata.com/raft/) provides an excellent interactive illustration of how this works. As you step through that illustration, you’ll notice that the algorithm is actually quite similar to the Kafka replication protocol we walked through earlier. This is because although Raft is used to implement replicated state machines, it actually is a replicated WAL, which is exactly what Kafka is. One benefit of using Raft is we no longer have the need for ZooKeeper or some other coordination service.
|
||||
|
||||
Raft handles electing a leader. Heartbeats are used to maintain leadership. Writes flow through the leader to the followers. The leader appends writes to its WAL and they are subsequently piggybacked onto the heartbeats which get sent to the followers using *AppendEntries* messages. At this point, the followers append the write to their own WALs, assuming they don’t detect a gap, and send a response back to the leader. The leader commits the write once it receives a successful response from a quorum of followers.
|
||||
|
||||
Similar to Kafka, each replica in Raft maintains a high-water mark of sorts called the *commit index*, which is the index of the highest log entry known to be committed. This is piggybacked on the *AppendEntries* messages which the followers use to know when to commit entries in their WALs. If a follower detects that it missed an entry (i.e. there was a gap in the log), it rejects the *AppendEntries* and informs the leader to rewind the replication. The [Raft paper](https://raft.github.io/raft.pdf) details how it ensures correctness, even in the face of many failure modes such as the ones described earlier.
|
||||
|
||||
Conceptually, there are two logs: the Raft log and the NATS Streaming message log. The Raft log handles replicating messages and, once committed, they are appended to the NATS Streaming log. If it seems like there’s some redundancy here, that’s because there is, which we’ll get to soon. However, keep in mind we’re not just replicating the message log, but also the state machines associated with the log and any clients.
|
||||
|
||||
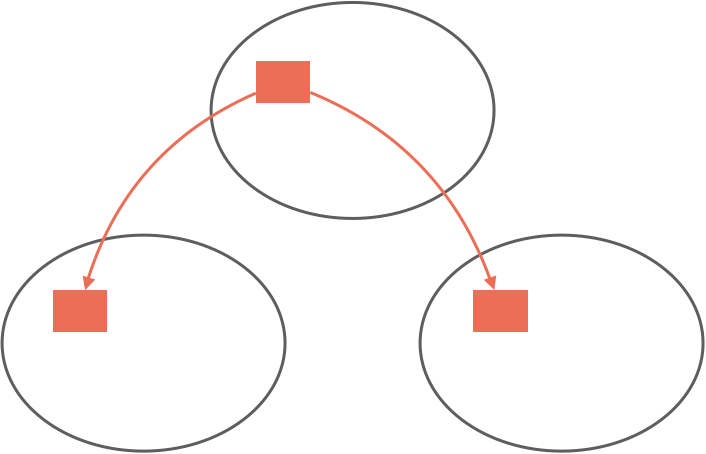
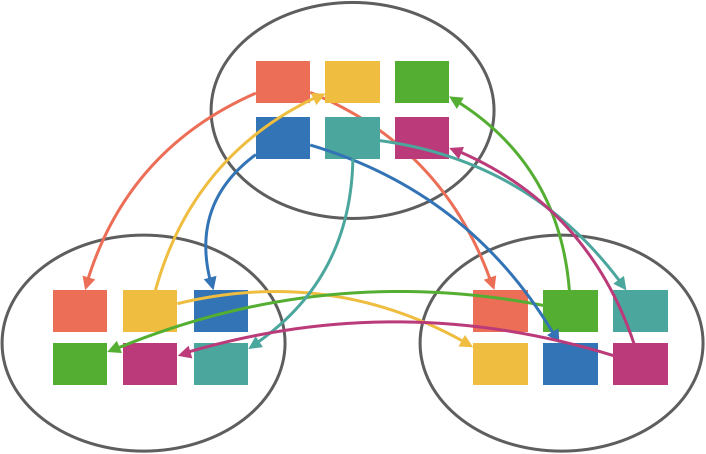
There are a few challenges with this replication technique, two of which we will talk about. The first is scaling Raft. With a single topic, there is one Raft group, which means one node is elected leader and it heartbeats messages to followers.
|
||||
|
||||
|
||||
|
||||
|
||||
As the number of topics increases, so do the number of Raft groups, each with their own leaders and heartbeats. Unless we constrain the Raft group participants or the number of topics, this creates an explosion of network traffic between nodes.
|
||||
|
||||
|
||||
|
||||
|
||||
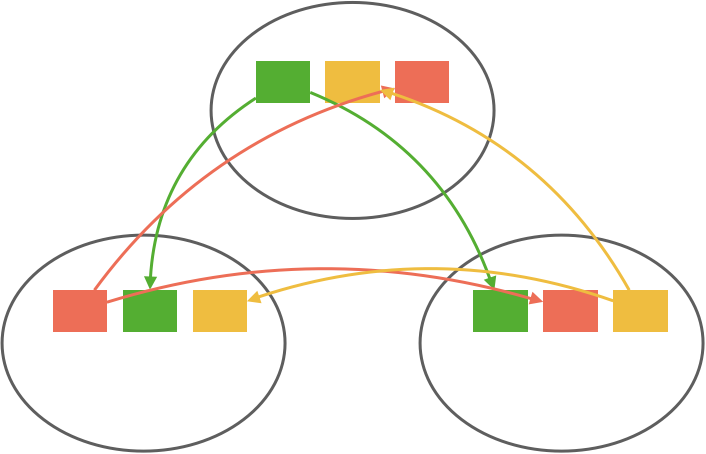
There are a couple ways we can go about addressing this. One option is to run a fixed number of Raft groups and use a consistent hash to map a topic to a group. This can work well if we know roughly the number of topics beforehand since we can size the number of Raft groups accordingly. If you expect only 10 topics, running 10 Raft groups is probably reasonable. But if you expect 10,000 topics, you probably don’t want 10,000 Raft groups. If hashing is consistent, it would be feasible to dynamically add or remove Raft groups at runtime, but it would still require repartitioning a portion of topics which can be complicated.
|
||||
|
||||
|
||||
|
||||
|
||||
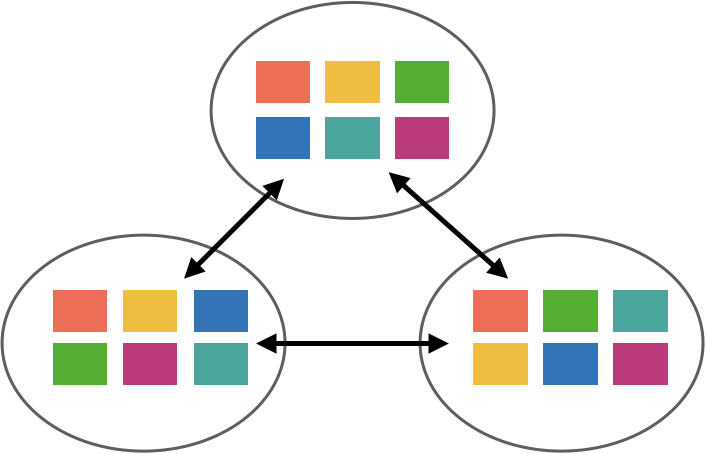
Another option is to run an entire node’s worth of topics as a single group using a layer on top of Raft. This is what CockroachDB does to scale Raft in proportion to the number of key ranges using a layer on top of Raft they call [MultiRaft](https://www.cockroachlabs.com/blog/scaling-raft/). This requires some cooperation from the Raft implementation, so it’s a bit more involved than the partitioning technique but eschews the repartitioning problem and redundant heartbeating.
|
||||
|
||||
|
||||
|
||||
|
||||
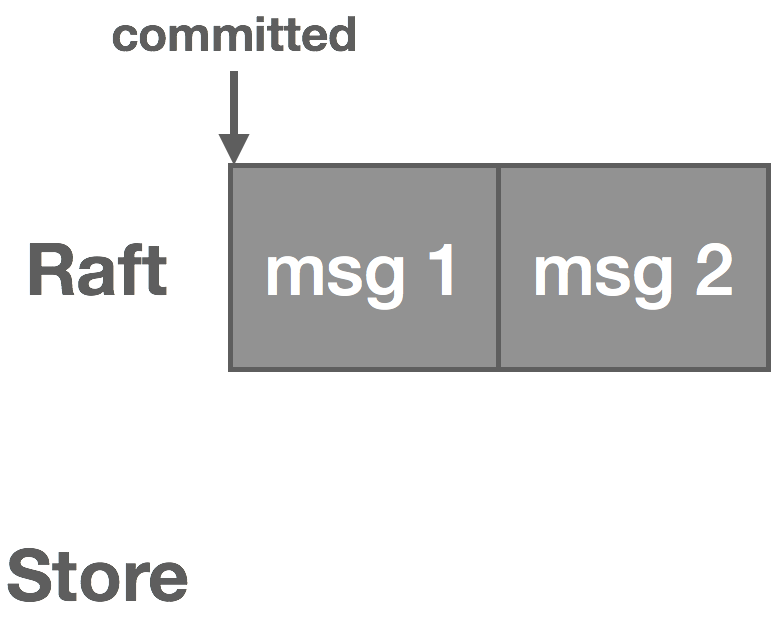
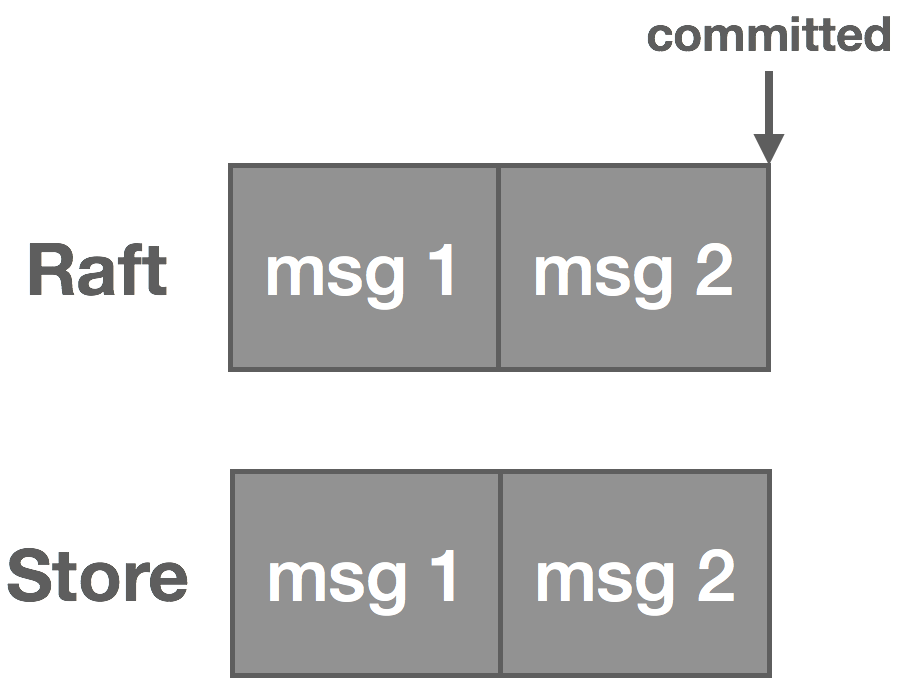
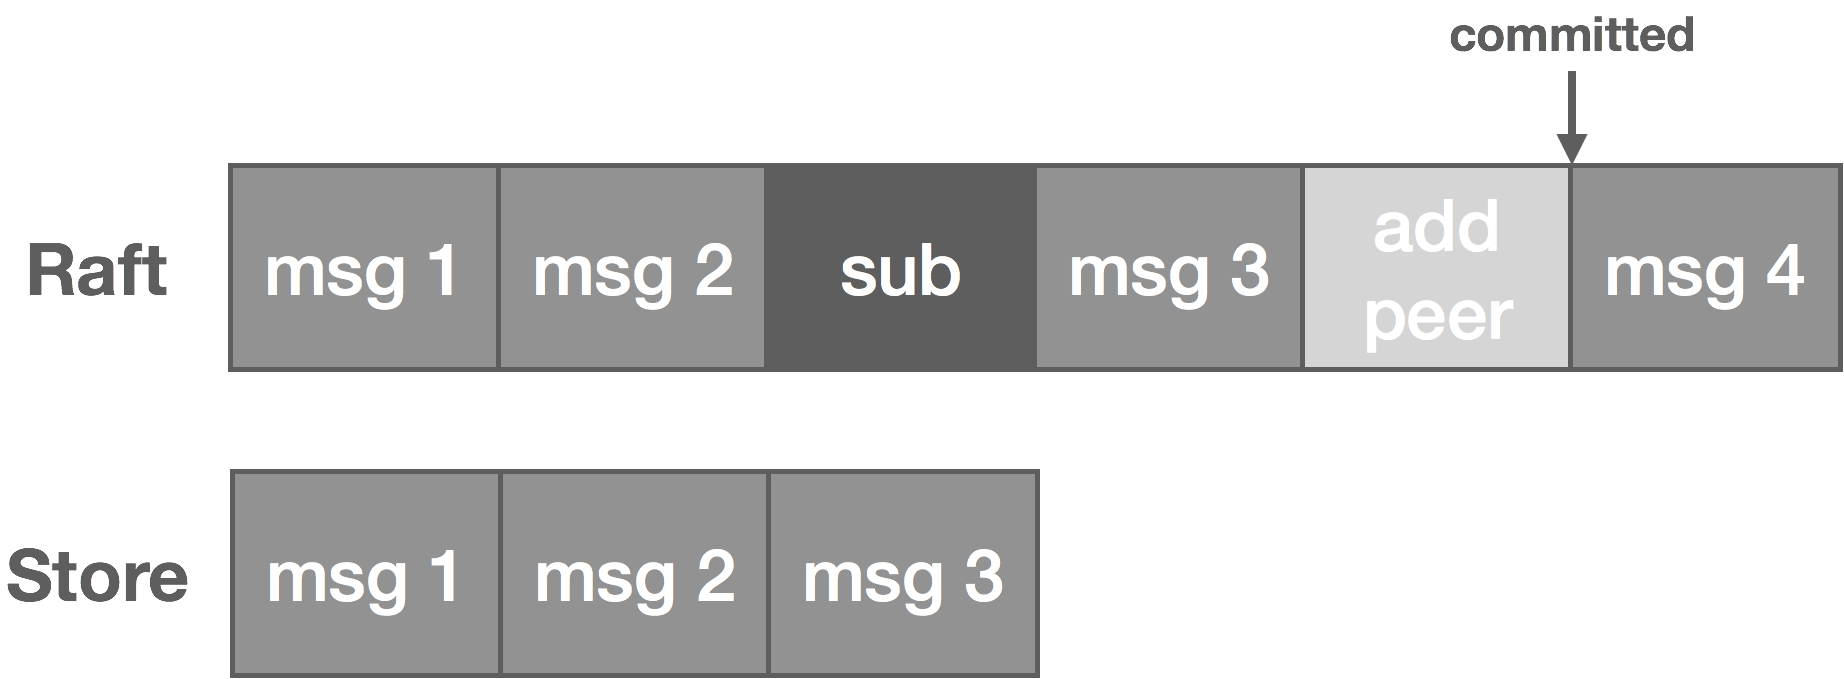
The second challenge with using Raft for this problem is the issue of “dual writes.” As mentioned before, there are really two logs: the Raft log and the NATS Streaming message log, which we’ll call the “store.” When a message is published, the leader writes it to its Raft log and it goes through the Raft replication process.
|
||||
|
||||
|
||||
|
||||
|
||||
Once the message is committed in Raft, it’s written to the NATS Streaming log and the message is now visible to consumers.
|
||||
|
||||
|
||||
|
||||
|
||||
Note, however, that not only messages are written to the Raft log. We also have subscriptions and cluster topology changes, for instance. These other items are not written to the NATS Streaming log but handled in other ways on commit. That said, messages tend to occur in much greater volume than these other entries.
|
||||
|
||||
|
||||
|
||||
|
||||
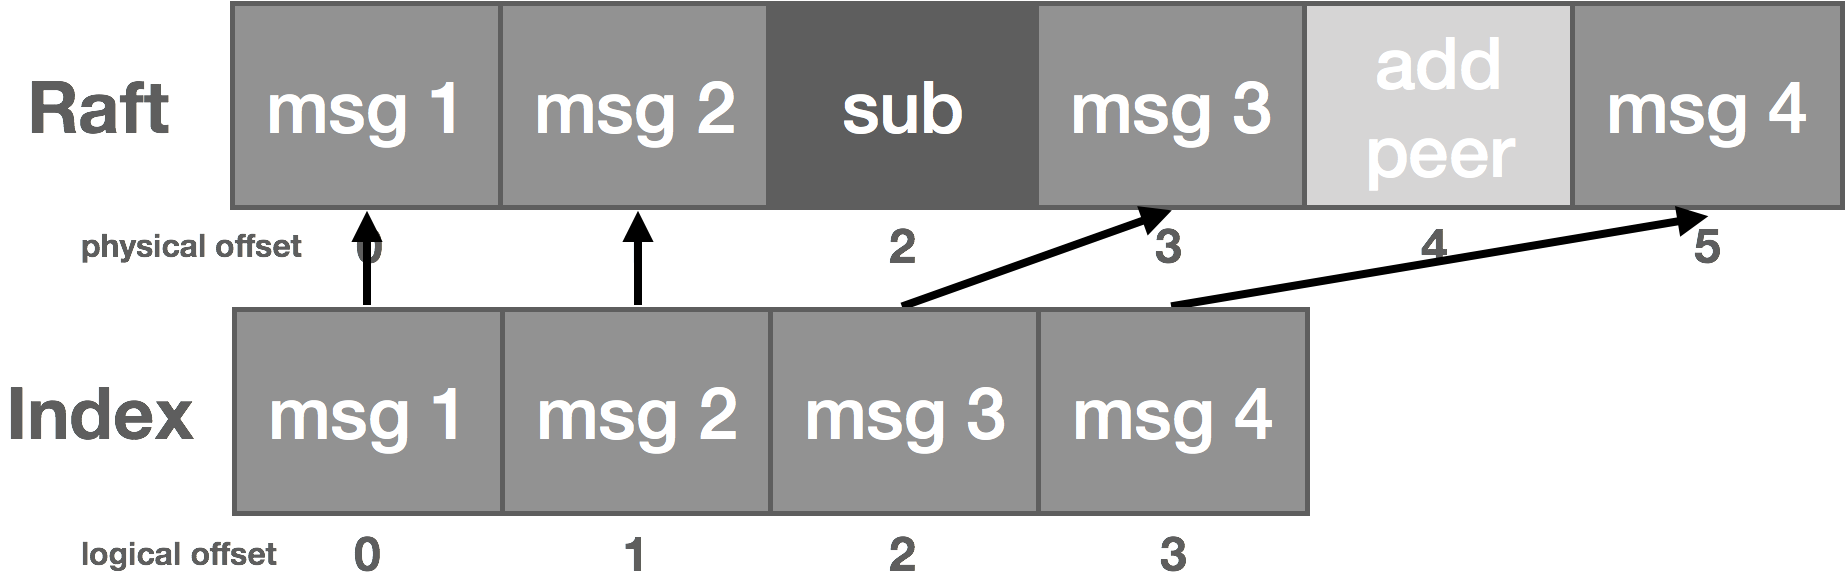
Messages end up getting stored redundantly, once in the Raft log and once in the NATS Streaming log. We can address this problem if we think about our logs a bit differently. If you recall from [part one](https://bravenewgeek.com/building-a-distributed-log-from-scratch-part-1-storage-mechanics/), our log storage consists of two parts: the log segment and the log index. The segment stores the actual log data, and the index stores a mapping from log offset to position in the segment.
|
||||
|
||||
Along these lines, we can think of the Raft log index as a “physical offset” and the NATS Streaming log index as a “logical offset.” Instead of maintaining two logs, we treat the Raft log as our message write-ahead log and treat the NATS Streaming log as an index into that WAL. Particularly, messages are written to the Raft log as usual. Once committed, we write an index entry for the message offset that points back into the log. As before, we use the index to do lookups into the log and can then read sequentially from the log itself.
|
||||
|
||||
|
||||
|
||||
|
||||
### Remaining Questions[#](https://bravenewgeek.com#remaining-questions)
|
||||
|
||||
We’ve answered the questions of how to ensure continuity of reads and writes, how to replicate data, and how to ensure replicas are consistent. The remaining two questions pertaining to replication are how do we keep things fast and how do we ensure data is durable?
|
||||
|
||||
There are several things we can do with respect to performance. The first is we can configure publisher acks depending on our application’s requirements. Specifically, we have three options. The first is the broker acks on commit. This is slow but safe as it guarantees the data is replicated. The second is the broker acks on appending to its local log. This is fast but unsafe since it doesn’t wait on any replica roundtrips but, by that very fact, means that the data is not replicated. If the leader crashes, the message could be lost. Lastly, the publisher can just not wait for an ack at all. This is the fastest but least safe option for obvious reasons. Tuning this all depends on what requirements and trade-offs make sense for your application.
|
||||
|
||||
The second thing we do is don’t explicitly *fsync* writes on the broker and instead rely on replication for durability. Both Kafka and NATS Streaming (when clustered) do this. With *fsync* enabled (in Kafka, this is configured with *flush.messages* and/or *flush.ms* and in NATS Streaming, with *file_sync*), every message that gets published results in a sync to disk. This ends up being very expensive. The thought here is if we are replicating to enough nodes, the replication itself is sufficient for HA of data since the likelihood of more than a quorum of nodes failing is low, especially if we are using rack-aware clustering. Note that data is still periodically flushed in the background by the kernel.
|
||||
|
||||
Batching aggressively is also a key part of ensuring good performance. Kafka supports end-to-end batching from the producer all the way to the consumer. NATS Streaming does not currently support batching at the API level, but it uses aggressive batching when replicating and persisting messages. In my experience, this makes about an order-of-magnitude improvement in throughput.
|
||||
|
||||
Finally, as already discussed earlier in the series, keeping disk access sequential and maximizing zero-copy reads makes a big difference as well.
|
||||
|
||||
There are a few things worth noting with respect to durability. Quorum is what guarantees durability of data. This comes “for free” with Raft due to the nature of that protocol. In Kafka, we need to do a bit of configuring to ensure this. Namely, we need to configure *min.insync.replicas* on the broker and *acks* on the producer. The former controls the minimum number of replicas that must acknowledge a write for it to be considered successful when a producer sets *acks* to “all.” The latter controls the number of acknowledgments the producer requires the leader to have received before considering a request complete. For example, with a topic that has a replication factor of three, *min.insync.replicas* needs to be set to two and *acks* set to “all.” This will, in effect, require a quorum of two replicas to process writes.
|
||||
|
||||
Another caveat with Kafka is unclean leader elections. That is, if all replicas become unavailable, there are two options: choose the first replica to come back to life (not necessarily in the ISR) and elect this replica as leader (which could result in data loss) or wait for a replica in the ISR to come back to life and elect it as leader (which could result in prolonged unavailability). Initially, Kafka favored availability by default by choosing the first strategy. If you preferred consistency, you needed to set *unclean.leader.election.enable* to *false*. However, as of 0.11, *unclean.leader.election.enable* now defaults to this.
|
||||
|
||||
Fundamentally, durability and consistency are at odds with availability. If there is no quorum, then no reads or writes can be accepted and the cluster is unavailable. This is the crux of the [CAP theorem](https://bravenewgeek.com/cap-and-the-illusion-of-choice/).
|
||||
|
||||
In [part three](https://bravenewgeek.com/building-a-distributed-log-from-scratch-part-3-scaling-message-delivery/) of this series, we will discuss scaling message delivery in the distributed log.
|
||||
|
||||
## Comments
|
||||
|
||||
Comments are from this blog's WordPress era and are preserved read-only.
|
||||
|
||||
Brilliant article.
|
||||
|
||||
Great article Tyler. Two clarifications I have.
|
||||
|
||||
First, you first stated that NATS Streaming currently uses one Raft Group per topic, but then mentioned the problem with this (explosion of network traffic). Is the plan to adopt the MultiRaft approach the Cockroach Labs folks developed?
|
||||
|
||||
Second, in the diagram of the message log being an index of the logical offset which points to the Raft log physical offset, I am assuming this implies the physical message (bytes) are stored only in the Raft log? What is the cost of dereferencing the message while reading the message log? I am making the assumption messages are currently read sequentially from the log files and this approach introduces a new indirection.
|
||||
|
||||
Yes, the MVP currently does not address the Raft scalability problem. These are some potential solutions but not yet implemented. This goes for the dual writes in the Raft log. However, with this approach, reads would still be sequential from the log (as they are now). These will be two big areas for improvement following an initial release.
|
||||
|
||||
Hi, are you trying to actually build a distributed log in this serials of blog post?
|
||||
|
||||
“By default, Kafka favors availability by choosing the second strategy.” — you meant the *first* strategy here — picking a replica not necessarily in the ISR set? But actually, since 0.11, unclean.leader.election.enable defaults to false, so please update that paragraph :)
|
||||
|
||||
Nice catch, thanks.
|
||||
|
||||
Regarding these 2 sections of text
|
||||
|
||||
> The thought here is if we are replicating to enough nodes, the replication itself is sufficient for HA of data since the likelihood of more than a quorum of nodes failing is low, especially if we are using rack-aware clustering. …
|
||||
|
||||
AND
|
||||
|
||||
> Another caveat with Kafka is unclean leader elections. That is, if all replicas become unavailable, there are two options: …
|
||||
|
||||
Why is it that we’re worried about all replicas becoming unavailable in Kafka for leader elections, but not as much from the replication/durability perspective?
|
||||
@@ -0,0 +1,29 @@
|
||||
# Developing a Hospital Emergency Incident Command System (HEICS)
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: https://www.everbridge.com/developing-hospital-emergency-incident-command-system-heics/
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s something I wasn’t aware of: hospitals have their own version of the ICS.
|
||||
|
||||
## 正文
|
||||
|
||||
A hospital emergency incident command system (HEICS) is a team of people, trained to respond to an incident — anything from an epidemic threat to a mass casualty incident can trigger the activation of HICS. This is a general overview of the HEICS system and how you can adapt it to your facility.
|
||||
|
||||
### What is HEICS?
|
||||
|
||||
HEICS was developed in the 1980s as a foundation response to emergency events in and around hospitals. From there, HICS (hospital incident command system) was developed by the California Emergency Medical Services Authority to include emergency and non-emergency situations. The HICS plan is used around the U.S. and internationally as a way to prepare for emergency and non-emergency situations. We recommend downloading the [HICS guidebook](https://emsa.ca.gov/wp-content/uploads/sites/71/2017/09/HICS_Guidebook_2014_11.pdf).
|
||||
|
||||
### Who Should be Part of HEICS?
|
||||
|
||||
|
||||
|
||||
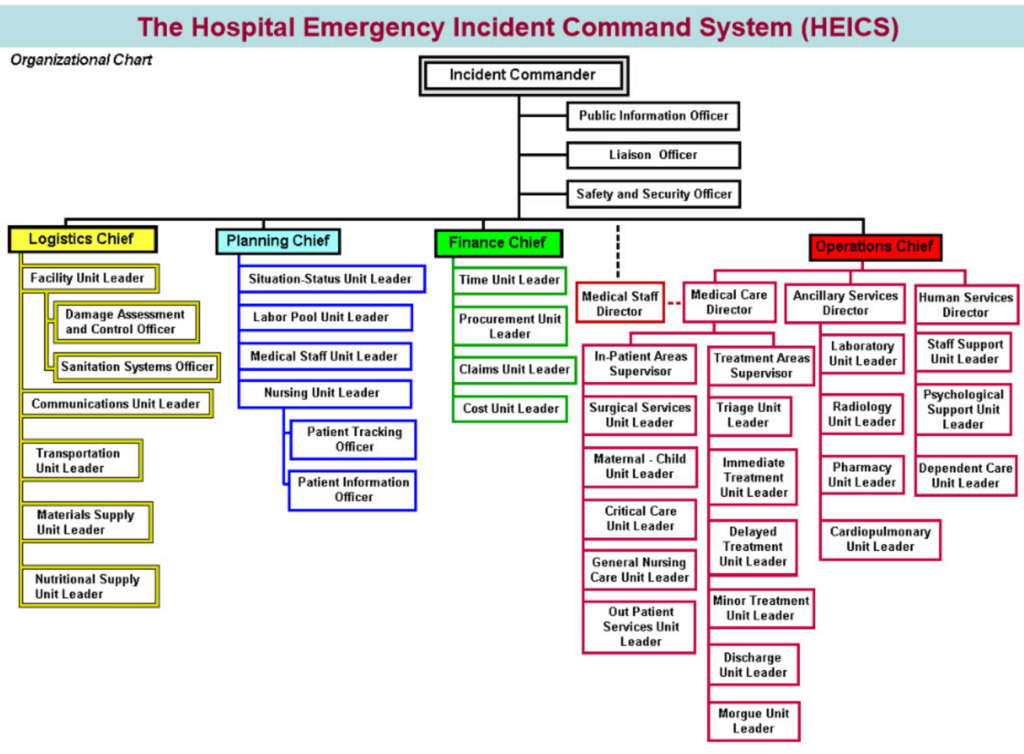
One of the most important decisions you’ll make when you develop your HEICS team is who should be at the table. You’ll need representatives from various departments in the hospital. Once an incident commander has been named — usually someone with formal emergency preparedness experience — you’ll need to build out the rest of the team. People to consider are a public information officer, a liaison officer, a safety and security officer, logistics chief, planning chief, finance chief and an operations chief. You’ll need to gauge how many people you need and what roles they will fulfill based on the size of the hospital and the type of services your facility provides. In a smaller hospital, one person might adopt more than one role. Below is a chart to give you an idea of possible team members, based on a large-sized hospital.
|
||||
|
||||
Image credit: PH2.1
|
||||
|
||||
### Practice Drills
|
||||
|
||||
A big part of emergency preparedness are active and tabletop drills. Active drills are when you participate with your local community to a large-scale drill such as an active shooter situation, or a natural disaster like a hurricane or earthquake. Participants will act as if a real incident is occurring and walk through the steps with local community officials to prepare for a real event. A tabletop drill is when the key stakeholders sit down together and walk through the steps of the drill around a table, it’s much smaller in scale, but no less important — tabletop drills can show flaws in planning and give participants the opportunity to revise documentation and execution. We recommend checking out our page on healthcare tabletop drills to get more information. After you have a drill, participants should do a review of the procedures to see if anything can be improved. While you need a complete set of documents to meet the [CMS Emergency Preparedness](https://www.everbridge.com/cms-emergency-preparedness/) Guidelines, you should think of your plan as a living document, which will regularly be revised and improved.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Google Cloud Platform Blog: Consequences of SLO violations
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: http://feedproxy.google.com/~r/ClPlBl/~3/PDN4c3Fd0mI/consequences-of-SLO-violations-CRE-life-lessons.html
|
||||
|
||||
## 简介
|
||||
|
||||
> In this blogpost, we discuss why you should create a policy on how SREs and devs respond to SLO violations, and provide some ideas for the structure and components of that policy.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,59 @@
|
||||
# This Is What it Takes to Measure the Internet
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: https://www.pcmag.com/news/357855/this-is-what-it-takes-to-measure-the-internet
|
||||
|
||||
## 简介
|
||||
|
||||
Now this is neat. This research team pings basically the entire internet all the time and can track outages across the globe. They can see things like Egypt shutting down Internet access for all of its citizens and the effects of hurricanes.
|
||||
|
||||
## 正文
|
||||
|
||||
Every 11 minutes, [Dr. John Heidemann's](https://www.isi.edu/people/johnh/RESEARCH/index.html) team "pings" 4 million networks to ascertain if they are live, looking for patterns and outliers. If a nation-state shuts down their country's web access (as [Egypt did in 2011](https://www.pcmag.com/archive/egypt-restores-internet-access-260076)) or a hurricane hits, taking out major utilities and communication networks, Professor Heidemann will know what's going on.
|
||||
|
||||
PCMag visited him at the [Analysis of Network Traffic](https://ant.isi.edu/index.html) (ANT) Lab within the [USC Information Sciences Institute](https://www.isi.edu/) (ISI), where they do both traffic and topology. Founded in 1972, ISI played a crucial role in the development of the early internet; it was one of the earliest nodes on ARPANET and the organization that created the DNS system. Today, ISI's 350 researchers undertake research for many federal agencies (including DARPA, Homeland Security, and the Air Force Office of Scientific Research), as well as partner with companies like Lockheed Martin, Raytheon, and Northrop Grumman.
|
||||
|
||||
"Here in the networks division, we develop network protocols and address issues of cyber security, denial of service attacks, mapping, and data analytics to make the internet more secure," Dr. Heidemann told PCMag.
|
||||
|
||||
Dr. Heidemann started in network simulation in the late 90s, and his work led to the first "internet Censuses" in 2003.
|
||||
|
||||
"We wanted to see if we could 'measure the internet'," he told PCMag. "We had noticed these anomalies, while realizing the simple act of pinging could be used to detect when networks fail. And this became important for a bunch of things: telecoms policy, networks and, as IoT comes online, embedded devices. Now we can see to the edge of the public internet—to the routers—but not into your house."
|
||||
|
||||
In case you're not familiar with the term, pinging has been around since the early internet as way to verify if a computer is online, sending a packet of data ("ping") to an internet address and waiting for a response (sometimes referred to as a "pong"). But why did Professor Heidemann choose 11 minutes, and not 10, as the sweep interval to obtain data?
|
||||
|
||||
"Because we don't want to be aligned with human behavior," he explained. "For example, if your computer is scheduled to come on at the top of the hour for two minutes, we didn't want to just hit it at the same time. Having said that, we often analyze the date by hour, so things go back and forth."
|
||||
|
||||
If you want to see Dr. Heidemann's work in action, ANT recently went live with a [world visualization map](https://ant.isi.edu/outage/world).
|
||||
|
||||
"We take all the data we get every 11 minutes from 4 million networks and put it into a grid," Dr. Heidemann said. "So you can see the scale of outages when they occur. For example, the size of the circle is how many networks are down in that area and the color is the percentage of all the networks in that area are down—red being 100 percent—which is what we track during disasters."
|
||||
|
||||
In his office, he then manipulated the map to return to the day Hurricane Irma hit Florida. As the storm intensified, circles around the Florida Keys turned white (50 percent network fail).
|
||||
|
||||
"The neat thing about Irma is we saw the hurricane hit, people lose power temporarily and then they get back on," said Dr. Heidemann. "Which tells us a lot about the [resilience of the power grid and internet](https://www.nytimes.com/2017/09/18/us/harvey-irma-internet.html?_r=0) networks in that area. Of course it was a different story with Puerto Rico and Hurricane Maria. In fact their networks were down for so long that, eventually, when [we] kept re-running the data analysis, suddenly the region 'disappeared' because after pinging the networks and getting no response for over a week, we interpreted that as gone away instead of temporarily down."
|
||||
|
||||
The world visualization map was built using [OpenLayers](https://openlayers.org/), mapping software, with custom code on top for the base data collection, analysis and algorithm development.
|
||||
|
||||
### Recommended by Our Editors
|
||||
|
||||
"We're working really hard now to deploy real-time data," said Professor Heidemann. "The processing is currently done in batch, usually quarterly, unless there's an event, like a natural disaster, where we pull it and do the analysis immediately."
|
||||
|
||||
Up next, the ANT Lab will take its census and outage data to work on prediction and root cause analysis. For example, "when a hurricane hits X area, what's the likely outcome to Y servers, length of time they'll be affected, cost analysis to affected businesses and communities and so on."
|
||||
|
||||
"My big goal in 2018 is two things," said Dr. Heidemann. "I want to reach out to 'real people' because we're at the point, when we have real-time data, and the visualization data you've seen, when a network goes down, you should be able to visit—from another computer, obviously—and get more information. That's the citizen-facing side.
|
||||
|
||||
"On the science side there's a ton of work to be done on these years of data. We now have to work out where are the weak parts of the internet? How can we identify the dependencies? How can we improve them? We now have a vast data set—80 billion data points. There's knowledge embedded in there and it will take a lot of work, but we'll get there."
|
||||
|
||||
Although the ANT lab is working towards concurrent data displays, there are times when, as Dr. Heidemann, explained, you don't want to share it too widely.
|
||||
|
||||
"Most of this work has been supported by the Department of Homeland Security, which has a vested interest in a secure homeland. Other agencies want to support this work to get insights into long-term resilience of our communications networks. However, in some of my security work, particularly in denial of service attacks, we don't want to report it publicly so quickly that the attackers are using our work as evidence of a 'good attack.' Luckily hurricanes aren't adversarial in nature, so I don't see any reason why we don't want to make this information available quickly, as soon as we have it ready."
|
||||
|
||||
|
||||
|
||||
## About Our Expert
|
||||
|
||||

|
||||
|
||||
S. C. Stuart is an award-winning digital strategist and technology commentator for ELLE China, Esquire Latino, Singularity Hub, and PCMag, covering: artificial intelligence; augmented, virtual, and mixed reality; DARPA; NASA; US Army Cyber Command; sci-fi in Hollywood (including interviews with Spike Jonze and Ridley Scott); and robotics (real-life encounters with over 27 robots and counting).
|
||||
|
||||
[Read Full Bio](https://www.pcmag.com/authors/sc-stuart)
|
||||
@@ -0,0 +1,114 @@
|
||||
# How Log Analysis Can Bring Front-End Engineers on Call
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: https://thenewstack.io/log-analysis-can-bring-frontend-engineers-call/
|
||||
|
||||
## 简介
|
||||
|
||||
This is a summary of a couple of talks from Influx Days. I especially like the bit about Baron Schwartz’s talk on the pitfalls of anomaly detection.
|
||||
|
||||
## 正文
|
||||
|
||||
Red Hat AI 3.5 tackles the GPU queue that can stall AI pilots
|
||||
|
||||
|
||||
|
||||
Join our community of software engineering leaders and aspirational developers. Always
|
||||
stay in-the-know by getting the most important news and exclusive content delivered
|
||||
fresh to your inbox to learn more about at-scale software development.
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
It seems that you've previously unsubscribed from our newsletter
|
||||
in the past. Click the button below to open the re-subscribe form
|
||||
in a new tab. When you're done, simply close that tab and continue
|
||||
with this form to complete your subscription.
|
||||
|
||||
|
||||
|
||||
|
||||
The New Stack does not sell your information or share it with
|
||||
unaffiliated third parties. By continuing, you agree to our
|
||||
|
||||
|
||||
[Terms of Use](https://thenewstack.io/terms-of-use/)and[Privacy Policy](https://thenewstack.io/privacy-policy/).
|
||||
Welcome and thank you for joining The New Stack community!
|
||||
|
||||
|
||||
|
||||
Please answer a few simple questions to help us deliver the news and resources you are interested in.
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
Great to meet you!
|
||||
|
||||
|
||||
|
||||
Tell us a bit about your job so we can cover the topics you find most relevant.
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
REQUIRED
|
||||
|
||||
|
||||
|
||||
Welcome!
|
||||
|
||||
|
||||
|
||||
We’re so glad you’re here. You can expect all the best TNS content to arrive Monday through Friday to keep you on top of the news and at the top of your game.
|
||||
|
||||
What’s next?
|
||||
|
||||
|
||||
|
||||
Check your inbox for a confirmation email where you can adjust your preferences and even join additional groups.
|
||||
|
||||
Follow TNS on your favorite social media networks.
|
||||
|
||||
Become a [TNS follower on LinkedIn](https://www.linkedin.com/company/the-new-stack).
|
||||
|
||||
|
||||
Check out [the latest featured and trending stories](https://thenewstack.io/) while you wait for your
|
||||
first TNS newsletter.
|
||||
@@ -0,0 +1,51 @@
|
||||
# Speculative Execution Exploit Performance Impacts – Describing the performance impacts to security patches for CVE-2017-5754 CVE-2017-5753 and CVE-2017-5715
|
||||
|
||||
- **期号**: SRE Weekly Issue #104(2018-01-07)
|
||||
- **作者**: —
|
||||
- **链接**: https://access.redhat.com/articles/3307751
|
||||
|
||||
## 简介
|
||||
|
||||
Meltdown is especially scary because the fix has the potential to significantly impact performance.
|
||||
|
||||
## 正文
|
||||
|
||||
# Speculative Execution Exploit Performance Impacts - Describing the performance impacts to security patches for CVE-2017-5754 CVE-2017-5753 and CVE-2017-5715
|
||||
|
||||
#### Summary:
|
||||
|
||||
This is the 2nd version of the Performance Considerations with results from testing updated kernels for Red Hat Enterprise Linux 7 and 6, based on "Retpoline" optimizations recently accepted upstream.
|
||||
|
||||
[Kernel Side-Channel Attacks - CVE-2017-5754 CVE-2017-5753 CVE-2017-5715](https://access.redhat.com/security/vulnerabilities/speculativeexecution)
|
||||
|
||||
|
||||
The recent speculative execution CVEs address three potential attacks across a wide variety of architectures and hardware platforms, each requiring slightly different fixes. In many cases, these fixes also require microcode updates from the hardware vendors. Red Hat has delivered updated Red Hat Enterprise Linux kernels that focus on securing customer deployments. The nature of these vulnerabilities and their fixes introduces the possibility of reduced performance on patched systems. The performance impact depends on the hardware and the applications in place. We are actively working with our technology partners to reduce or eliminate these performance impacts as quickly as possible.
|
||||
|
||||
#### Details:
|
||||
|
||||
The Red Hat Performance Engineering team characterized application workloads to help guide partners and customers on the potential impact of the fixes supplied to correct CVE-2017-5754, CVE-2017-5753, and CVE-2017-5715, including "Retpoline" kernels to secure pre-Skylake class machines to mitigate part of the Spectre vulnerability for `ibrs`. These machines still need OEM microcode to mitigate `ibpb` part of Spectre, which has little to no impact on performance. The performance impact of these patches still has considerable variations based on workload under test and the hardware configuration. Measurements are reported based on Industry Standard Benchmarks (ISB) representing a set of workloads that most closely mirror common customer deployments.
|
||||
|
||||
Red Hat has tested complete solutions, including updated kernels and updated microcode, on variants of the following modern high volume Intel systems: Haswell / Broadwell (not including Skylake in this report). In each instance, there is performance impact caused by the additional overhead required for security hardening in user-to kernel and kernel-to-user transitions. The impact varies with workload and hardware implementation and configuration. As is typical with performance, the impact that we measured ranged in Jan 2018 was between **1-20%** and has now improved to be within **1-8%** for the ISB set of application workloads tested.
|
||||
|
||||
In order to provide more detail, Red Hat’s performance team is sharing performance results measured on RHEL7, (with similar behavior on RHEL6/5), for a wide variety of benchmarks based on performance impact:
|
||||
|
||||
-
|
||||
**Measurable: previously 8-19% - updated w/ retpoline to be 4-8% -** Highly cached random memory, with buffered I/O, OLTP database workloads, HPC (High Performance Computing) scale-out environments using MPI and benchmarks with high kernel-to-user space transitions were measured to be impacted the most. Examples include OLTP Workloads (tpc), sysbench, pgbench.
|
||||
-
|
||||
**Modest: previously 3-7% - updated w/ retpoline to be 2-5% -** Database analytics, Decision Support System (DSS), and Java VMs were measured to be impacted less than the “Measurable” category. These applications may have a significant sequential disk or network traffic, but kernel/device drivers are able to aggregate requests to moderate level of kernel-to-user transitions. Examples include SPECjbb2005, Queries/Hour and overall analytic timing (sec).
|
||||
-
|
||||
**Small: previously 2-5% - updated w/ retpoline to be 1-2% -** Computation loads like HPC (High Performance Computing) in scale-up using OpenMP, CPU-intensive workloads that spend little time in the kernel were measured to have a very small performance penalty. Examples include Linpack NxN on x86 and SPECcpu2006.
|
||||
-
|
||||
**Minimal:** Linux accelerator technologies that generally bypass the kernel in favor of user direct access were measured to have the least performance impact with less than 1% overhead measured. Examples tested include DPDK (VsPERF at 64 byte) and OpenOnload (STAC-N), Mellanox RDMA. Userspace accesses to VDSO, like gettimeofday (64-bit) were not impacted.
|
||||
-
|
||||
**NOTE:** Because microbenchmarks like netperf/uperf, iozone, and fio are designed to stress a specific hardware component or operation, their results may not be generally representative of customer workload. Some microbenchmarks have shown a larger performance impacts.
|
||||
|
||||
Because containers are implemented as generic Linux processes, applications deployed in containers incur the same performance impact as those deployed on bare metal. We expect the impact on applications deployed in virtual guests to be higher than bare metal because of the increased frequency of user-to-kernel transitions.
|
||||
|
||||
The actual performance impact that customers see may vary considerably based on the nature of their workload, hardware/devices, and system constraints such as whether the workloads are CPU bound or memory bound. If an application is running on a system that has consumed the full capacity of memory and CPU, the overhead of this fix may max out the configuration, resulting in more significant performance degradation. Consequently, the only deterministic way to characterize the impact is to run your workloads in your environment.
|
||||
|
||||
Red Hat Enterprise Linux settings for these patches default to maximum security. Recognizing, however, that customers' needs vary, these patches may be enabled or disabled at boot time or at runtime. As a diagnostic approach, some customers may want to measure results on the patched kernel in configurations with and without the CVE patches enabled. In order to facilitate this, the kernel team has added dynamic tunables to enable/disable most of the CVE microcode/security patches through debugfs tunables as described below.
|
||||
|
||||
Red Hat continues to look for ways to minimize the performance impact of these security mitigations in future versions of Red Hat Enterprise Linux. We fully expect that hardware vendors will prevent these vulnerabilities in new implementations of silicon/microcode. Meanwhile, Red Hat continues to focus on improving customer application performance by better characterizing relevant workloads and isolating factors that affect performance. As always, our experts will be available for consultation about the specifics of your applications and environments.
|
||||
|
||||
## Comments
|
||||
Reference in New Issue
Block a user