SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,15 @@
|
||||
# Per-IP rate limiting with iptables
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://making.pusher.com/per-ip-rate-limiting-with-iptables/
|
||||
|
||||
## 简介
|
||||
|
||||
Pusher had a problem: their service was being bombarded by connections from rogue clients, and they needed to enforce limits. This article is highly polished, with beautiful diagrams and well-constructed explanations.
|
||||
|
||||
> This is the story of how we quelled the biggest threat to our service uptime for several years.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
226
sreweekly/markdown/109/02-structured-logging-and-your-team.md
Normal file
226
sreweekly/markdown/109/02-structured-logging-and-your-team.md
Normal file
@@ -0,0 +1,226 @@
|
||||
# Structured Logging and Your Team
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://honeycomb.io/blog/
|
||||
|
||||
## 简介
|
||||
|
||||
Structured logging can bring a lot of uniformity to your infrastructure, as lovingly explained in this article. Snyk explains how that uniformity allows for a standardized troubleshooting methodology that helps them get to the bottom of most problems in minutes.
|
||||
|
||||
> Instead of focusing on the individual intricacies of each part of our system, we train on the common tools to be used for almost every kind of problem.
|
||||
|
||||
## 正文
|
||||
|
||||
[Blog](https://honeycomb.io/blog)
|
||||
|
||||
# Honeycomb Blog
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AI Norms & Values, Part 3 of 3: Things We Hold True
|
||||
|
||||
The final part of Honeycomb's AI Norms & Values series: the principles the company holds true about AI as a tool, ownership of work, and rising standards; how it actually uses AI day to day; usage patterns for respecting each other's time; and where it stands on AI's ethical externalities like energy use, IP, bias, and wages.
|
||||
|
||||
## Featured
|
||||
|
||||

|
||||
|
||||
[AI Norms & Values, Part 2 of 3: AI for Honeycomb Engineering](https://honeycomb.io/blog/ai-norms-values-part-2-ai-honeycomb-engineering)
|
||||
|
||||

|
||||
|
||||
[Fin's CTO on Building Great Engineering Organizations in the AI Era](https://honeycomb.io/blog/fin-cto-building-great-engineering-organizations-ai-era)
|
||||
|
||||

|
||||
|
||||
[AI Norms & Values, Part 1 of 3: How We Do Business at Honeycomb](https://honeycomb.io/blog/ai-norms-values-part-1-how-we-do-business-at-honeycomb)
|
||||
|
||||

|
||||
|
||||
[What Comes After Observability?](https://honeycomb.io/blog/what-comes-after-observability)
|
||||
|
||||
## Explore Blog
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
|
||||
### AI Norms & Values, Part 3 of 3: Things We Hold True
|
||||
|
||||
The final part of Honeycomb's AI Norms & Values series: the principles the company holds true about AI as a tool, ownership of work, and rising standards; how it actually uses AI day to day; usage patterns for respecting each other's time; and where it stands on AI's ethical externalities like energy use, IP, bias, and wages.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Wide Events vs. Three Pillars: AI Observability Costs
|
||||
|
||||
AI agents make telemetry costs harder to predict. This post compares the three pillars against the wide event model, and explains why wide events keep AI observability costs predictable without sacrificing the context engineers need.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
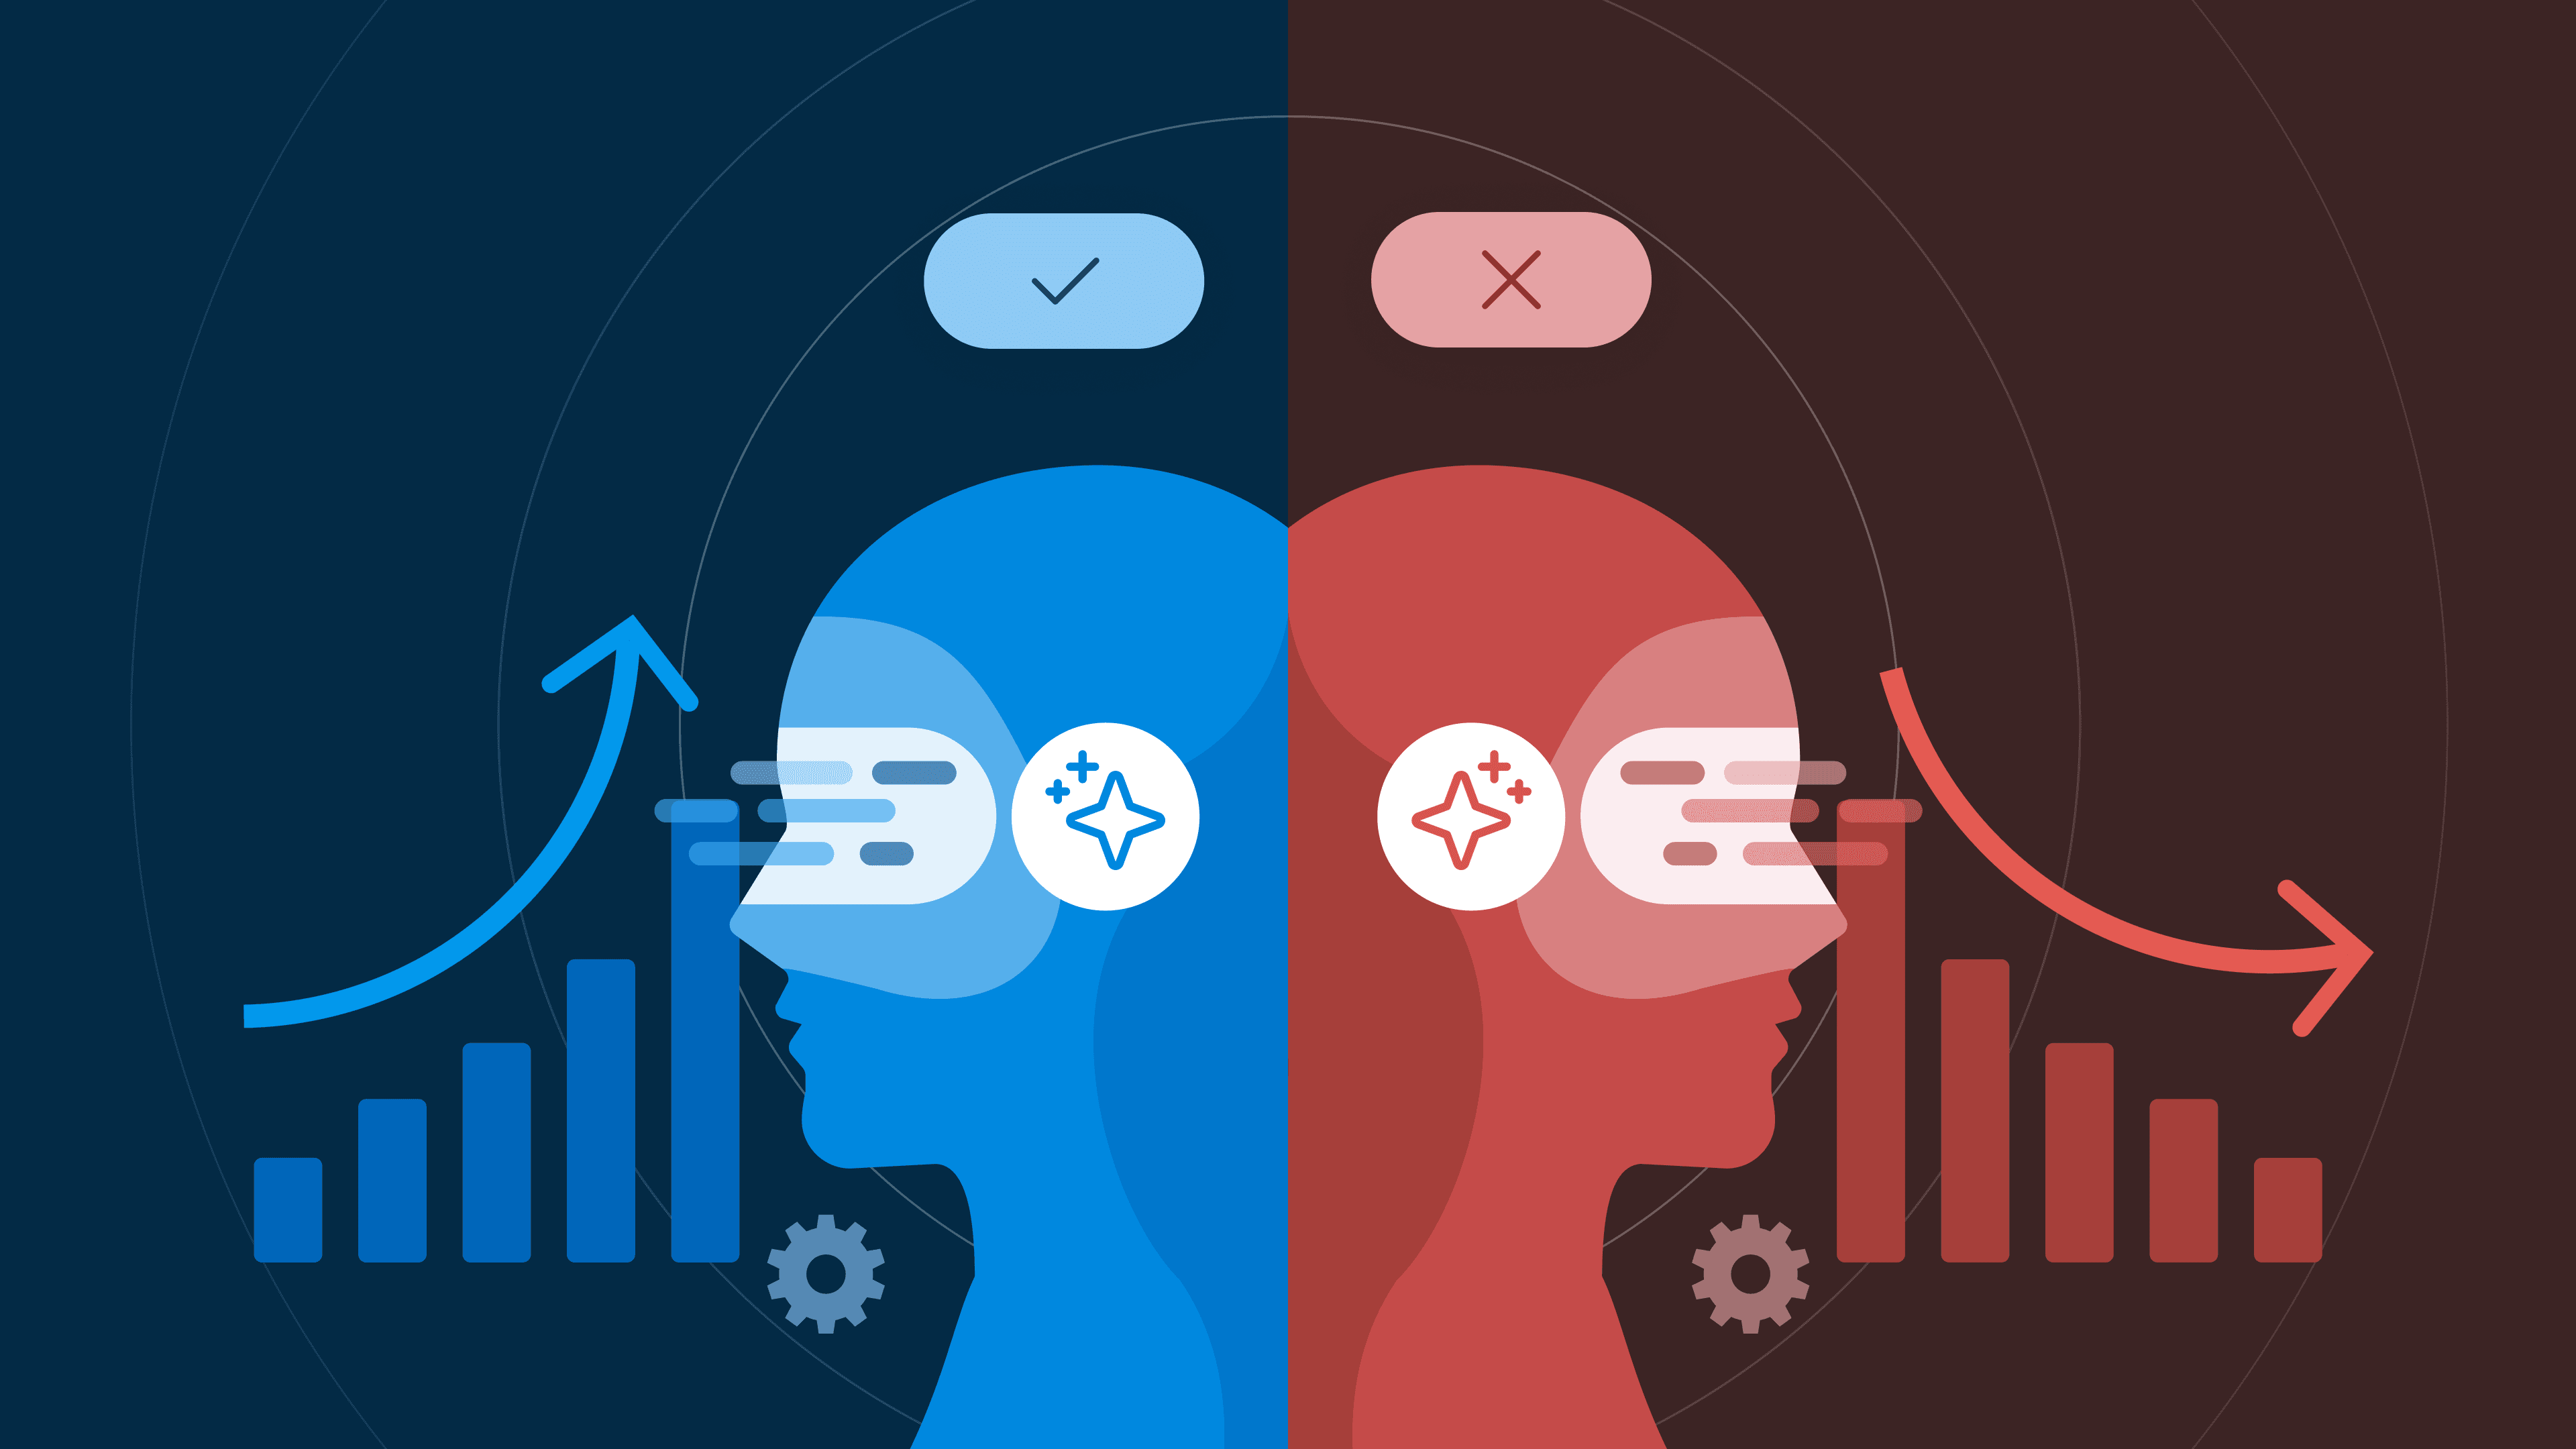
### Relational Query Superpowers
|
||||
|
||||
See how Honeycomb's relational query keywords—root, parent, child, any, any2, any3, and none—let you pull attributes from anywhere in a single trace into one query, walked through with a real checkout-error investigation.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AI Norms & Values, Part 2 of 3: AI for Honeycomb Engineering
|
||||
|
||||
Charity Majors shares a note from Emily Nakashima, SVP of Engineering, on why Honeycomb's engineering org is going all in on AI, the north star it's aiming for, and an honest FAQ about what that means day to day.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Bringing the Most Advanced Sampling to the OpenTelemetry Collector
|
||||
|
||||
Honeycomb is donating its adaptive tail sampling processor, built on years of Refinery experience, to the OpenTelemetry Collector. See how adaptive sampling, trace fingerprinting, and sample rate attribution work, and how to try it today with the Honeycomb Collector Distribution.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Fin's CTO on Building Great Engineering Organizations in the AI Era
|
||||
|
||||
Fin (formerly Intercom) CTO Darragh Curran set a public goal to double engineering productivity—and nearly tripled it. In the first episode of Leading With Observability, he talks with Charity Majors about AI-driven PR review, hands-on leadership through the transition, and why observability is the trust mechanism that makes it all work.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### 7 Best Datadog Alternatives for AI and Agent Observability
|
||||
|
||||
Comparing Datadog alternatives for AI and agent observability? See how Honeycomb, New Relic, Dynatrace, Grafana Cloud, Phoenix, Langfuse, and SigNoz stack up on cost, investigation, and OpenTelemetry support.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AI Norms & Values, Part 1 of 3: How We Do Business at Honeycomb
|
||||
|
||||
It's been a year since Honeycomb issued its AI mandate. Charity reflects on what that produced, why AI isn't special (it just amplifies what's already there), and shares the first of three new documents on Honeycomb's AI norms and values: how we do business.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### How I Support Humans in the AI Era
|
||||
|
||||
A remote engineering manager on why she didn't write a new AI policy for her team. Instead, she created space: for connection, for collaboration, and for discussion.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AI Model Drift: How to Keep Models Reliable
|
||||
|
||||
Learn what AI model drift is, why it happens, and how production teams detect changes in model quality, inputs, prompts, and behavior.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Introducing AI BubbleUp
|
||||
|
||||
Every BubbleUp query now surfaces significant correlations based on relevance, not just statistical analysis. Available today to all Honeycomb customers who have enabled Honeycomb Intelligence.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AMA Recap: More Answers From the Observability Engineering Authors
|
||||
|
||||
We couldn't get through every question during our live AMA with the authors of Observability Engineering, so Charity, Liz, George, and Austin stuck around to answer more on AI, telemetry, and what still needs a human in the loop.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Spend More Time Talking to Humans
|
||||
|
||||
LLMs have reshaped the day-to-day work of software engineering, leaving senior engineers exhausted by context-switching and junior engineers unsure how to grow. The fix isn’t a better prompt — it’s spending more time talking to humans: reducing context churn, pairing across seniority levels, and communicating more across teams.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Honeycomb Named a Visionary in the 2026 Gartner® Magic Quadrant™ for Observability Platforms
|
||||
|
||||
For the third consecutive year, Honeycomb has been named a Visionary in the Gartner® Magic Quadrant™ for Observability Platforms. The recognition reflects Honeycomb's vision for fast, flexible, high-cardinality querying, agent-era observability with Agent Timeline and Canvas, and predictable event-based pricing at trillions of events.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Embracing the Code Review Bottleneck
|
||||
|
||||
Faced with an endless stream of AI-generated code reviews, our team made the counterintuitive choice to lean into the bottleneck rather than reduce it. Surprisingly, velocity held up, knowledge sharing improved, and we developed a collective system ownership that stuck.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### What Comes After Observability?
|
||||
|
||||
A year ago, I predicted ways in which AI was about to fundamentally change observability as we knew it. Here's what we've seen happen since—both at Honeycomb and with our customers—and what we're building for the future.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### 30 to 70 PRs a Day: How We Managed to Not Wreck Our Systems
|
||||
|
||||
The Honeycomb engineering team set out to double our productivity in a year. This is how we did it, what we did to keep things stable, what it cost us, and what we’re still figuring out.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### AI Amplifies Your Existing Practices: Lessons from Our Shift to an AI-First Strategy
|
||||
|
||||
As the Honeycomb engineering team worked to double our productivity, we learned a lot. The most important takeaway? Nothing anyone tells you about AI will land if your starting substrate is unhealthy.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Transforming How We Run Kafka at Honeycomb
|
||||
|
||||
We just completed a large-scale, multi-month Kafka migration project. We couldn't have done it without learning from past mistakes, prioritizing rollback safety, and building shared knowledge across the team through repeated migration practice.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
### Shipping Is Your Company's Heartbeat: A Letter from a CTO
|
||||
|
||||
In an open letter to engineering leaders everywhere, Fin CTO Darragh Curran explains that AI isn't a magic wand but rather an amplifier—of the good and the bad—of your engineering practices. And engineering rigor is more important than ever.
|
||||
@@ -0,0 +1,97 @@
|
||||
# Your Feature Flag Management Needs to Include Retirement
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://rollout.io/blog/feature-flag-retirement/
|
||||
|
||||
## 简介
|
||||
|
||||
Feature flags are awesome! But there’s a downside: adding lots of conditional handling to your code can significantly increase code complexity, which can in turn decrease maintainability and increase risk.
|
||||
|
||||
## 正文
|
||||
|
||||
*The following is a guest post written by Dave Farinelli.*
|
||||
|
||||
*Updated July 2, 2025*
|
||||
|
||||
Feature flag deployment is gaining popularity as a way to provide safer and more effective deployments for teams looking to streamline their deployment pipeline. [Feature flags](https://www.cloudbees.com/blog/ultimate-feature-flag-guide) simplify the process of making more frequent deployments by allowing granular control of the functionality deployed based on the environment.
|
||||
|
||||
## What Is a Feature Flag Lifecycle?
|
||||
|
||||
A feature flag lifecycle refers to the stages a feature toggle goes through—creation, testing, deployment, activation, and retirement. Properly managing this lifecycle is key to minimizing technical debt and ensuring safe rollouts.
|
||||
|
||||
As a refresher, a [feature flag](https://rollout.io/use-case/manage-scale-jenkins) (also called a *feature toggle*) modifies software functionality without requiring a redeployment, effectively allowing for dynamic and easy configuration of software. Some of the perks of being able to do this include:
|
||||
|
||||
- **Experimentation:** The ability to turn on certain features for a subset of users to determine the reception of new features.
|
||||
- **Safer deployments:** The ability to turn off the effects of a deployment quickly, in case a rollback of functionality is required.
|
||||
|
||||
However, by nature, feature flags introduce complexity into a software development lifecycle and have inherent risks for teams not managing said complexity appropriately. The main culprit of this comes in the flag debt, or an overabundance of feature flags, which causes cognitive overload, which in turn translates into further [technical debt](<https://en.wikipedia.org/wiki/Technical_debt#:~:text=Technical%20debt%20(also%20known%20as,approach%20that%20would%20take%20longer.>) and increased risk in further deployments.
|
||||
|
||||
In this article, I’ll go over the general [lifecycle of a feature flag](https://rollout.io/blog/feature-flag-lifecycling), from creation to retirement, to help with managing feature flag complexity and allow your team to get the full benefit of [using feature flags](https://rollout.io/blog/using-feature-flags-across-cicd).
|
||||
|
||||
## Step 1: Creating Feature Flags for Safe and Scalable Deployments
|
||||
|
||||
The first step when considering new functionality is to determine the type of feature flag that will be created alongside the deployment. There are a number of general categories when considering the creation of a feature flag:
|
||||
|
||||
- **Release toggle:** Useful for teams using continuous delivery. Release toggles essentially keep new functionality hidden in deployments while allowing for changes to be committed to the main branch. These toggles typically are kept off until functionality is ready for release.
|
||||
- **Experiment toggle:** Allows for turning on and off completed functionality specific to environments. This is useful when using[A/B testing](https://rollout.io/blog/ab-testing-feature-flags) or[Canary releases](https://rollout.io/blog/using-canary-releases-and-early-life-support-improve-production-releases) . For example, in a load-balanced system, you may choose to use two workflows and randomly assign users to each, then collect data from their experiences and determine the best way forward.
|
||||
- **Ops toggle:** Serves as a “circuit breaker” of functionality to accommodate for potential infrastructure issues. For example, if an external service has unplanned downtime, this might be a long-lasting feature flag that gracefully deactivates functionality in your software.
|
||||
- **Permissioning toggle:** Allows for turning functionality on and off based on a particular subset of users. Unlike Experiment toggles, Permissioning toggles are based on a specific set of users and are usually meant to be long-lasting.
|
||||
|
||||
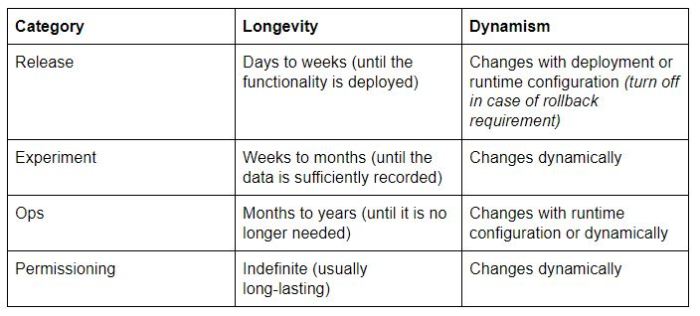
When considering a feature flag, the most important thing is to think about the following traits:
|
||||
|
||||
- The longevity of the feature flag and how long it is expected to be in use.
|
||||
- The dynamism (or ease of configuration) of the feature flag, alongside which the team needs to be able to invoke changing of the feature flag.
|
||||
|
||||
Plotting that on a table, it breaks down to the following:
|
||||
|
||||
|
||||
|
||||
Using the information above will help with being able to determine how a feature flag will be used when deployed into production. For instance, general functionality that will stay static when deployed will be a Release flag, whereas functionality to “short-circuit” features will be an Ops feature flag, changing the overall implementation.
|
||||
|
||||
Once the feature flag is created, the next step is getting it into place—which leads us to the next section of deployment.
|
||||
|
||||
## Step 2: Deploying Feature Flags Across Environments
|
||||
|
||||
After the creation of the feature flag, the next step is getting the feature flag into upstream environments as quickly as possible. By getting the feature flag in place, you’re able to control the environment dynamically, even with the functionality being incomplete.
|
||||
|
||||
No matter what type of flag is in place, getting the flag set up in all upstream environments is key, as it allows for using the feature flag functionality for the granular control it provides. Remember that the feature flag and the functionality do not need to be bundled together. For example, if there is functionality in place that may take weeks to get to a working state, you would be well-served to spread out the complexity of the deployment by deploying the feature flag as soon as possible.
|
||||
|
||||
|
||||
|
||||
Once the flag is in place, the next step is using it!
|
||||
|
||||
## Step 3: Activating Feature Flags in Production
|
||||
|
||||
The third step in the implementation of a feature flag is activating functionality in the production environment. This is where feature flags shine—now, instead of having a deployment and hoping everything works well, you just turn things on when you’re ready to start using said functionality.
|
||||
|
||||
In step one, creation, we talked about the dynamism of flags and the capability of turning them on and off. Especially for Ops and Permissioning flags, it’s important to be able to quickly change their state with ease. A tool like [CloudBees Feature Management](https://rollout.io/capabilities/feature-management) can provide an easy way to set flags to be easily changeable, while providing a dashboard to manage them easily.
|
||||
|
||||
Finally, let’s address different scenarios when thinking about different testing strategies:
|
||||
|
||||
1. One in which a team uses a standard testing environment (for example, development → staging → production).
|
||||
2. Another in which a team uses minimal environments and uses continuous delivery into a single production environment while performing [testing in production](https://rollout.io/blog/why-and-how-testing-in-production) .
|
||||
|
||||
For a team with multiple environments for testing, this allows for [setting feature flags](https://rollout.io/blog/feature-flag-best-practices) based on the environment, allowing for using feature flag functionality across different environments. For instance, a deployment could deploy to both staging and production environments, then clone production data into the staging environment. Setting the feature flags in the staging environment to test new functionality can ensure functionality with real-time data.
|
||||
|
||||
Because feature flags are useful, many of them will reach a point where they are no longer required. Once that’s the case, we’ll move on to the final step of the feature flag lifecycle.
|
||||
|
||||
## Step 4: Retiring Feature Flags to Reduce Technical Debt
|
||||
|
||||
The final (and very important!) step in the use of a feature flag is the retirement of it, effectively merging it into the standard codebase. I touched on this a bit in the introduction but want to reiterate here the importance of the lifespan of feature flags, and the importance of pruning them after their use is no longer required.
|
||||
|
||||
With the use case of feature flags being a way to configure environments, it will cause issues when there are too many ways to configure an environment. Each feature flag provides an opportunity for misconfiguration, and having too many in place causes a lot of cognitive load for those running configuration, which eventually causes issues down the road.
|
||||
|
||||
The solution to this? Make a process in which feature flags are regularly retired and removed from the codebase. This will result in deployments that just remove feature flags and cause certain features to become standard in the codebase. For something like Release flags, this will usually be done quickly after a successful release. Experimental flags will be retired after successful data is collected, and Ops and Permissioning flags may end up sticking around in the long term.
|
||||
|
||||
|
||||
|
||||
## Managing the Feature Flag Lifecycle from Start to Finish
|
||||
|
||||
Hopefully, this guide helps with putting the [feature flag lifecycle](https://rollout.io/blog/feature-flag-retirement) in perspective, giving you the means to understand how to use them with your software solutions.
|
||||
|
||||
You may be thinking, how do I get started with all of this? It’s common to be in a situation where developing an in-house solution for flag lifecycle management is just not a feasible option for your team. A lot of the time used in determining the right solution represents time taken away from developing features for your customers, and without the knowledge of what you may need in a [feature flag management](https://rollout.io/blog/using-feature-flags-across-cicd) solution, you may end up missing important details. More commonly, what happens in these scenarios is that, fueled by good intentions, a solution is started, but is never actually able to solve for having a commercial feature flag management solution.
|
||||
|
||||
There are plenty of solutions that allow for quick integration of a feature flag-based deployment model for your codebase, including [CloudBees Feature Management](https://rollout.io/capabilities/feature-management) product. This will help you get started quickly with using feature flags, without having to add more work in rolling out your own solution, especially if you’re starting from scratch.
|
||||
|
||||
*Dave Farinelli* *is a senior software engineer with over eight years of experience. His specialty is in providing enterprise-level solutions for healthcare and insurance clients. Dave holds a B.S. in computer engineering from Kettering University in Flint, Michigan.*
|
||||
22
sreweekly/markdown/109/04-charity-majors-on-twitter.md
Normal file
22
sreweekly/markdown/109/04-charity-majors-on-twitter.md
Normal file
@@ -0,0 +1,22 @@
|
||||
# Charity Majors on Twitter
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://twitter.com/mipsytipsy/status/957761131216449536
|
||||
|
||||
## 简介
|
||||
|
||||
Following up on her appearance in the New York Times last week, Charity Majors posted this excellent Twitter thread about the importance of vendor relationship management and generating business value, as any kind of engineer. I’d argue especially as an SRE.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
this thread reminds me that I have had a couple of vendor-related thoughts spinning around in my head.
|
||||
the first is: we are all selling something. if you are employed as an engineer, you are selling something too.
|
||||
|
||||
This post is from an account you blocked.
|
||||
|
||||
[11:43 PM · Jan 28, 2018](https://twitter.com/mipsytipsy/status/957761131216449536)
|
||||
|
||||
[San Francisco, CA](https://twitter.com/places/5a110d312052166f)
|
||||
@@ -0,0 +1,13 @@
|
||||
# Google Cloud Platform Blog: Applying the Escalation Policy
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: http://feedproxy.google.com/~r/ClPlBl/~3/X9sgkf7XSWk/applying-the-escalation-policy-CRE-life-lessons.html
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s the latest in Google’s CRE Life Lessons series. Previously, they explained how to build an Escalation Policy, and in this article, they analyze how it would be applied to several fictitious scenarios.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,123 @@
|
||||
# Dynamometer: Scale Testing HDFS on Minimal Hardware with Maximum Fidelity
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://engineering.linkedin.com/blog/2018/02/dynamometer--scale-testing-hdfs-on-minimal-hardware-with-maximum
|
||||
|
||||
## 简介
|
||||
|
||||
LinkedIn needed a way to test their HDFS cluster against real-world traffic patterns. The existing solutions didn’t meet their needs (for reasons they explain toward the end), so they created Dynamometer.
|
||||
|
||||
## 正文
|
||||
|
||||
# Dynamometer: Scale Testing HDFS on Minimal Hardware with Maximum Fidelity
|
||||
|
||||
*Co-authors: [Erik Krogen](https://www.linkedin.com/in/xkrogen/) and [Min Shen](https://www.linkedin.com/in/min-shen/)*
|
||||
|
||||
In March 2015, LinkedIn’s Big Data Platform team experienced a crisis. As the team was preparing to head home for the day, signs of trouble began trickling in: our internal users were reporting that their applications were stalling or timing out. Job queues were backing up, and SLAs would be missed. A bit of investigation indicated that operations performed against our primary [HDFS](http://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/HdfsUserGuide.html) cluster were taking up to two orders of magnitude longer than normal, or timing out completely. This came soon after expanding the cluster by 500 machines, specifically to help provide more capacity to our internal users. Inadvertently, rather than providing an improved user experience as intended, we made our service nearly unusable. By the time the issue was detected, it was non-trivial to remove the new machines, as they had already accumulated a significant amount of data that would need to be copied off before they could be removed from service. Instead, we worked quickly to solve the specific issue causing the performance regression (described in further detail below), and subsequently began to make plans for how to protect ourselves from similar mishaps in the future.
|
||||
|
||||
We realized that sometimes applying changes from the [Apache Hadoop](http://hadoop.apache.org/) open source community, even from official releases, can be risky because performance and scale testing are not part of the standard release process. While this is surprising given that scalability is a core tenet of the design of HDFS, it starts to make sense when you consider the following factors:
|
||||
|
||||
- Scale testing is expensive—the only way to ensure that something will run on a multi-thousand node cluster is to run it on a cluster with thousands of nodes.
|
||||
|
||||
- HDFS is maintained by a distributed developer community, and many developers do not have access to large clusters.
|
||||
- Developers are aware that Apache community releases (as opposed to distributions like [CDH](https://www.cloudera.com/products/open-source/apache-hadoop/key-cdh-components.html) and[HDP](https://hortonworks.com/products/data-platforms/hdp/) ) are not typically run in production.
|
||||
|
||||
Even beyond potential performance regressions in Hadoop code, simple configuration changes in our environment can sometimes have unforeseen consequences, which blow out of proportion at our scale. We recognized the need to do performance testing in our own environment, but faced the difficulty that many issues are impossible to detect without running a cluster that is similar in size to what we use in production. Unfortunately, clusters of that scale are expensive, and we don’t have a spare one lying around that we can use for testing purposes; even if we did, generating sufficient and realistic load would also present a challenge. Many organizations deploying new software at scale go through a process in which changes are tested on successively larger installations, but this requires a lot of hardware, and users on the clusters become unwitting test subjects. We thought that there must be a better way, and to this end, we designed and built [Dynamometer](https://github.com/linkedin/dynamometer), a framework that allows us to realistically emulate the performance characteristics of an HDFS cluster with thousands of nodes using less than 5% of the hardware needed in production. The name is a reference to a [chassis dynamometer](https://en.wikipedia.org/wiki/Chassis_dynamometer), a tool used for performance measurement and testing of vehicles in which a moving road is simulated using a fixed roller.
|
||||
|
||||
In the interest of making Hadoop as robust and scalable as possible for everyone, we are [open sourcing Dynamometer](https://github.com/linkedin/dynamometer) today. Feedback and contributions are greatly appreciated! Please continue reading to learn more about the story of its conception and implementation.
|
||||
|
||||
## Background
|
||||
|
||||
LinkedIn is a data-driven company with over 530 million members. We have both an enormous amount of data to store, and thousands of data scientists, engineers, and business analysts who need to access and analyze this data. Our primary data analytics needs are met by the Apache Hadoop ecosystem (including related technologies, such as [Apache Hive](https://hive.apache.org/) and [Apache Spark](https://spark.apache.org/)), which is used for a variety of mission-critical tasks that range from reporting to feature experimentation to machine learning. LinkedIn’s Hadoop users are constantly developing new applications and workflows, meaning we have a consistent need to expand our clusters. Over the span of only a few years, the size of LinkedIn’s primary Hadoop clusters grew from hundreds to several thousands of nodes, and we now run hundreds of thousands of applications per day. Even at our current scale, we still see compute and storage capacity requirements roughly doubling each year. This means that we have to constantly look for ways to ensure that Hadoop will scale with us, and ensure that changes we make will not have a negative impact on the performance or scalability of our clusters, as they did in the incident described above.
|
||||
|
||||
## Identifying HDFS scalability bottlenecks
|
||||
|
||||
To gain a proper understanding of how to evaluate the scalability of HDFS under varying conditions, we have to first identify the limiting factor of its performance. HDFS is a large and complex system; isolating a single limiting factor allows us to concentrate our efforts in a much more efficient manner than blindly testing the system as a whole.
|
||||
|
||||
*Some examples of HDFS interactions. The NameNode is a centralized bottleneck for all requests requiring metadata, including reading/writing a file, renaming a file, and listing a directory. Note that most client processes are colocated on the same machines as the DataNode processes.*
|
||||
|
||||
The [architecture of HDFS](http://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/HdfsDesign.html) is such that as a cluster grows, the NameNode is the primary bottleneck to scaling, due to a number of factors:
|
||||
|
||||
- While data is distributed across all DataNodes, all metadata is tracked by a single NameNode. This process is additionally responsible for managing all DataNodes and facilitating all client interactions (excluding the transfer of actual data bytes).
|
||||
- As the cluster grows, there is more metadata to keep track of, such as files, directories, and information about each DataNode.
|
||||
- The way Hadoop [colocates compute and storage resources](https://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/HdfsDesign.html#aMoving_Computation_is_Cheaper_than_Moving_Data) means that each DataNode server is also used for executing users’ logic. As more DataNodes are added, the cluster’s compute capacity also expands, and our busy users happily consume these extra resources; thus, as the cluster grows, there are more requests submitted to the NameNode.
|
||||
- The load on a DataNode is mostly affected by the data blocks it stores locally, and we can always add more nodes to spread the load further, so they typically do not block the cluster’s performance.
|
||||
|
||||
As a result, our efforts to ensure that performance and scalability remain high are centered around the NameNode.
|
||||
|
||||
## The NameNode performance crisis
|
||||
|
||||
*Larger clusters submit more operations, and in the presence of the discussed performance regression, larger clusters also require a longer time to complete each operation. This combination results in a superlinear performance impact.*
|
||||
|
||||
In the process of investigating our original incident, we found that the performance regression was brought on by a seemingly innocuous change that had slipped into several upstream releases. The goal of the [original change](https://issues.apache.org/jira/browse/HDFS-5837) (discovered and [fixed a few months later](https://issues.apache.org/jira/browse/HDFS-6599)) was to fix a bug in how load was calculated when choosing DataNodes to replicate blocks onto. It seemed fairly benign, with only about two dozen lines of non-test code changes, but it turned out that it also significantly increased the time it took the NameNode to add a new block to a file. Increasing the duration of this operation is particularly bad because every access to the file namespace occurs under a single read-write lock, so an increase in block addition time is an increase in the time that all other operations are blocked. The increase in block allocation time is proportional to the size of the cluster, so its impact becomes more severe as clusters are expanded. Larger clusters also have a more intense workload and thus more block allocations, further amplifying the effects of this regression. As shown above, the compounding effects of increased operation rate and increased operation runtime mean that adding nodes can have a superlinear effect on overall NameNode load; similarly, some operations’ runtimes are affected by the number of blocks or files in the system, making aggregate scaling effects difficult to predict in advance. This was a prime example of a scaling issue that was difficult for us to predict or to notice on our smaller testing clusters, but which we should have been able to catch prior to deployment.
|
||||
|
||||
## The requirements for our solution
|
||||
|
||||
As discussed above, we reduced our HDFS scaling problem to a problem of NameNode scalability. We identified three key factors which affect its performance:
|
||||
|
||||
- Number of DataNodes in the cluster;
|
||||
- Number and structure of objects managed (files/directories and blocks);
|
||||
- Client workload: request volume and the characteristics of those requests.
|
||||
|
||||
We needed a solution which would allow us to control all three parameters to match our real systems. To address the first point, we developed a way to run multiple DataNode processes per physical machine, and to easily adjust both how many machines are used and how many DataNode processes are run on each machine. The second point, in isolation, would be fairly trivial: start a NameNode and fill it with objects that do not contain any data. However, achieving a similar client workload significantly complicates this step, as explained below.
|
||||
|
||||
The last point is particularly tricky. The nature of requests can have huge performance implications on the system. Write requests are obviously more expensive than read requests; however, even within a single request type, there can be significant performance variations. For example, performing a listing operation against a very large directory can be thousands of times more expensive than performing a listing operation against a single-item directory, and this has significant implications for garbage collection efficiency and optimal tuning. To capture these effects, we set out with a requirement that our testing should be able to simulate exactly the same workload that our production clusters experience. This dictates that we not only execute the same commands, but that those commands are executed against the same namespace, hence the trivial solution to our second point is not sufficient.
|
||||
|
||||
Building off of these factors, and adding in a few additional requirements, we came up with the following list of goals:
|
||||
|
||||
- The simulated HDFS cluster should have a configurable number of DataNodes and a file namespace which is identical to our production cluster.
|
||||
- We should be able to replay the same workload that our production cluster experienced against this simulated cluster. To plan for even larger configurations, we should be able to induce heavier workloads, for example by playing back a production workload at an increased rate.
|
||||
- It should be easy to operate. Ideally, every prospective change would be run through Dynamometer to validate if it improves or degrades the performance of the NameNode.
|
||||
- The coupling between Dynamometer and the implementation of HDFS should be loose enough that we can easily test multiple versions of HDFS using a single version of Dynamometer and a single underlying host cluster.
|
||||
|
||||
## The architecture
|
||||
|
||||
To meet the aforementioned requirements, we implemented Dynamometer as an application on top of [YARN](https://hadoop.apache.org/docs/current/hadoop-yarn/hadoop-yarn-site/YARN.html), the cluster scheduler in Hadoop. We rely on YARN heavily at LinkedIn for other Hadoop-based processing, so this was a natural choice that allowed us to leverage our existing infrastructure. YARN allows us to easily scale Dynamometer by adjusting the amount of resources requested, and helps to decouple the simulated HDFS cluster from the underlying host cluster.
|
||||
|
||||
There are three main components to the Dynamometer setup:
|
||||
|
||||
1. Infrastructure is the simulated HDFS cluster.
|
||||
2. Workload simulates HDFS clients to generate load on the simulated NameNode.
|
||||
3. The driver coordinates the two other components.
|
||||
|
||||
The logic encapsulated in the driver enables a user to perform a full test execution of Dynamometer with a [single command](https://github.com/linkedin/dynamometer/blob/master/README.md#integrated-workload-launch), making it possible to do things like sweeping over different parameters to find optimal configurations.
|
||||
|
||||
The infrastructure application is written as a native YARN application in which a single NameNode and numerous DataNodes are launched and wired together to create a fully simulated HDFS cluster. To meet our requirements, we need a cluster which contains, from the NameNode’s perspective, the same information as our production cluster. To achieve this, we first collect the [FsImage file](https://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/HdfsDesign.html#The_Persistence_of_File_System_Metadata) (containing all file system metadata) from a production NameNode and place this onto the host HDFS cluster; our simulated NameNode can use it as-is. To avoid having to copy an entire cluster’s worth of blocks, we leverage the fact that the actual data stored in blocks is irrelevant to the NameNode, which is only aware of the block metadata. We first parse the FsImage using a modified version of Hadoop’s [Offline Image Viewer](https://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/HdfsImageViewer.html) and extract the metadata for each block, then partition this information onto the nodes which will run the simulated DataNodes. We use [SimulatedFSDataset](https://github.com/apache/hadoop/blob/trunk/hadoop-hdfs-project/hadoop-hdfs/src/test/java/org/apache/hadoop/hdfs/server/datanode/SimulatedFSDataset.java) to bypass the DataNode storage layer and store only the block metadata, loaded from the information extracted in the previous step. This scheme allows us to pack many simulated DataNodes onto each physical node, as the size of the metadata is many orders of magnitude smaller than the data itself.
|
||||
|
||||
*The driver launches two applications onto the host YARN cluster. Simulated clients and DataNodes are spread across the cluster and may be colocated.*
|
||||
|
||||
To make a stress testing job that matches our requirement to replay the same workload as was experienced in production, we must first have a way to collect the information about the production workload. The NameNode has facilities to record every request which it services; the resulting command log is known as the [audit log](https://effectivemachines.com/2017/03/08/unofficial-history-of-the-hdfs-audit-log/). A heavily-loaded NameNode services tens of thousands of operations per second; to induce such a load, we need numerous clients to submit requests. In an effort to ensure that each request has the same effect and performance implications as its original submission, we want to ensure that related requests (for example, a directory creation followed by a listing of that directory) are performed in such a way as to preserve their original ordering. To achieve this while distributing the replay across multiple nodes, we partition the audit log based on source IP address, with the assumption that requests which originated from the same host have more tightly coupled causal relationships than those which originated from different hosts. In the interest of simplicity, the stress testing job is written as a map-only MapReduce job, in which each mapper consumes a partitioned audit log file and replays the commands contained within against the simulated NameNode. During execution we collect statistics about the replay, such as latency for different types of requests.
|
||||
|
||||
## Dynamometer in practice
|
||||
|
||||
LinkedIn is all about data-driven decision making, so it is important to us to have the metrics to back up key changes we make to our Hadoop clusters. Dynamometer has become a standard tool to evaluate new features, giving us hard data about performance impact under production scale and real workloads. We plan to integrate Dynamometer into our testing pipeline, allowing us to quickly catch performance regressions as they are introduced into the codebase. In addition to using Dynamometer to estimate the limits of NameNode performance, we have used Dynamometer to develop actionable plans in a number of areas; we will discuss a few of them here.
|
||||
|
||||
When upgrading our HDFS clusters from Hadoop 2.3 to 2.6, we first used Dynamometer to predict how the new version of NameNode would react to our workload. We found that a change to the storage format of the FsImage file introduced by [HDFS-5698](https://issues.apache.org/jira/browse/HDFS-5698) resulted in a large increase in the memory footprint of the NameNode. Being aware of this in advance allowed us to properly adjust our JVM heap size and GC tuning parameters, potentially avoiding a disaster upon upgrading.
|
||||
|
||||
The entire file namespace stored by the NameNode is protected by a single read-write lock, the [FSNamesystemLock](https://github.com/apache/hadoop/blob/trunk/hadoop-hdfs-project/hadoop-hdfs/src/main/java/org/apache/hadoop/hdfs/server/namenode/FSNamesystemLock.java). This can be a bottleneck for the request volume the NameNode can handle, as all write operations become serialized, and even read operations may become blocked, since the lock is placed into [fair mode](https://docs.oracle.com/javase/7/docs/api/java/util/concurrent/locks/ReentrantReadWriteLock.html) by default (opposite of the Java default). This means that approximate arrival order is used for scheduling which threads can acquire the lock, as opposed to non-fair mode, which prioritizes readers to grab the lock in an effort to increase concurrency. The increased concurrency on non-fair mode comes at the cost of possible starvation of writers, which [can become blocked by a stream of readers](https://docs.oracle.com/javase/7/docs/api/java/util/concurrent/locks/ReentrantReadWriteLock.html).
|
||||
|
||||
The impact of the difference between fairness modes is dependent on the ordering of requests—for example, a burst of only reads followed by a burst of only writes would be unaffected by the locking mode, whereas the lock mode can have a strong influence on a workload which has closely interleaved operation types. This workload-dependent performance impact makes the audit trace replay capabilities of Dynamometer highly appropriate for this analysis. Using Dynamometer, we were able to verify that our write latencies would not be negatively affected by non-fair locking, and would actually improve due to an overall increase in the throughput of the NameNode. Below you can see a graph of the average time a request spent in the NameNode’s queue waiting to be serviced before and after we deployed unfair locking on a production cluster, as well as a prediction of the same using Dynamometer:
|
||||
|
||||
*The average request wait time shown as a function of load, as predicted on Dynamometer and observed in production.*
|
||||
|
||||
We have also experimented with using the [G1 garbage collector](https://docs.oracle.com/javase/9/gctuning/garbage-first-garbage-collector.htm) (G1GC) for our NameNode instead of the Concurrent Mark Sweep collector. While we can gather an idea of which tuning parameters to employ from an understanding of how the NameNode uses its heap memory, ultimately achieving a finely-tuned system requires a number of iterations of changing garbage collection tuning parameters and seeing how the system reacts. Dynamometer enabled us to become aware of a number of unexpected issues that, without tuning, would have resulted in disastrous consequences upon enabling G1GC on a production NameNode. It also enabled us to very finely tune each parameter because of the ease with which we were able to run tests with varying configuration values.
|
||||
|
||||
Finally, our team recently pushed out the [2.7.4 release of Hadoop](http://mail-archives.apache.org/mod_mbox/hadoop-general/201708.mbox/%3CCAKtuutF5XWZJqbLvXQOpFq_us8_XwmhTv_9K%2BznmuAL4okS1DA%40mail.gmail.com%3E). It is imperative that performance remains stable across maintenance releases, so we had to build a high level of confidence in the quality of the release. To this end, we used Dynamometer to verify a lack of noticeable performance regressions to the NameNode, even at our scale.
|
||||
|
||||
The similarities between a production environment and that of Dynamometer allow for accurate testing, and combined with the ease of running Dynamometer with various configurations and binaries, provide us with a very powerful experimentation methodology.
|
||||
|
||||
## Related work
|
||||
|
||||
A number of tools for measuring HDFS and NameNode performance have been developed in the past. Though all are useful, we found that they did not quite satisfy our requirements.
|
||||
|
||||
- [NNThroughputBenchmark](https://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-common/Benchmarking.html#NNThroughputBenchmark) is a utility for measuring NameNode performance on a single node; however, it does away with a few aspects that we find to be important, such as DataNodes and the RPC handling layer. It is meant to “reveal the upper bound of pure NameNode performance” rather than to set realistic real-world expectations.
|
||||
- [TestDFSIO](https://github.com/apache/hadoop/blob/trunk/hadoop-mapreduce-project/hadoop-mapreduce-client/hadoop-mapreduce-client-jobclient/src/test/java/org/apache/hadoop/fs/TestDFSIO.java) is a useful distributed benchmark but focuses on overall data I/O, utilizing DataNodes. We wanted to focus on NameNode performance specifically, since we found that the metadata operation throughput is our scale-limiting factor.
|
||||
- [Synthetic Load Generator](https://hadoop.apache.org/docs/current/hadoop-project-dist/hadoop-hdfs/SLGUserGuide.html) is a useful workload generator similar in form to that which we built for Dynamometer, but it generates its own synthetic workload based on input parameters that decide, for example, the percentage of read requests and write requests. One of our requirements was to have an identically matched workload, so this did not quite match our use case.
|
||||
- [S-Live](https://issues.apache.org/jira/browse/HDFS-708) is similar to TestDFSIO and the Synthetic Load Generator. It tests an entire cluster rather than focusing on the NameNode, and also works off a distribution of operations to perform rather than attempting to match a production workload.
|
||||
|
||||
## Acknowledgements
|
||||
|
||||
Dynamometer is the result of the combined efforts of many people. We would like to thank [Carl Steinbach](https://www.linkedin.com/in/carlsteinbach/) for originally proposing this project along with several elements of the design; [Adam Whitlock](https://www.linkedin.com/in/alloydwhitlock/), [Subbu Subramaniam](https://www.linkedin.com/in/subbusubramaniam/), and [Mark Wagner](https://www.linkedin.com/in/wagnermark/), who worked on the initial proof-of-concept; [Vinitha Gankidi](https://www.linkedin.com/in/vinitha-reddy-gankidi-63090b23/), who converted Dynamometer into a YARN application; and [Zhe Zhang](https://www.linkedin.com/in/zhezhang-zhz/), who helped us make the final push to get the system to where it is today. Lastly, big shout outs go to our team manager [Suja Viswesan](https://www.linkedin.com/in/sujaviswesan/) and to the members of LinkedIn’s Grid SRE team, who have supported our efforts throughout.
|
||||
|
||||
Related articles
|
||||
@@ -0,0 +1,13 @@
|
||||
# Humanize Your Digital Operations
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://www.pagerduty.com/blog/operations-health/
|
||||
|
||||
## 简介
|
||||
|
||||
PagerDuty released a report this week entitled, “The State of IT Work-Life Balance”, which contains the results of their recent survey. This article is an overview, along with some related tidbits about alert fatigue.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
13
sreweekly/markdown/109/08-schrodinger-s-outage.md
Normal file
13
sreweekly/markdown/109/08-schrodinger-s-outage.md
Normal file
@@ -0,0 +1,13 @@
|
||||
# Schrodinger’s Outage
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://www.xaprb.com/blog/schrodingers-outage/
|
||||
|
||||
## 简介
|
||||
|
||||
Through an anecdote, Baron Schwartz cautions against the use of counter-factuals (“you should have…”) in analyzing the decisions leading up to an outage.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,96 @@
|
||||
# 8 Things to Monitor During a Software Deployment
|
||||
|
||||
- **期号**: SRE Weekly Issue #109(2018-02-11)
|
||||
- **作者**: —
|
||||
- **链接**: https://stackify.com/monitor-software-deployment/
|
||||
|
||||
## 简介
|
||||
|
||||
What it says on the tin. This article would make for a great checklist for deploys.
|
||||
|
||||
## 正文
|
||||
|
||||
Retrace will reach End of Life on March 31, 2027. [Click here to learn more.](https://docs.stackify.com/docs/stackify-end-of-life-customer-letter)
|
||||
|
||||
|
||||
|
||||
| February 2, 2018
|
||||
|
||||
As software developers, our ultimate goal is to get our hard work deployed to production. Thanks to [agile development](https://stackify.com/agile-methodology/), [DevOps](https://stackify.com/what-is-devops/), and continuous [deployment tools](https://stackify.com/software-deployment-tools/), that process is quicker than ever! It is important to remember that a software deployment is more of a process and not a single event. As part of that process, you need to be monitoring your production servers and applications to ensure that everything is still running smoothly.
|
||||
|
||||
In this article we are going to discuss **8 critical items you should monitor** during your software deployments.
|
||||
|
||||
Application errors are the first line of defense when it comes to identify application problems. It is really important that developers collect all of their errors across all of their servers to monitor them. They are especially critical during a deployment to quickly spot new application problems.
|
||||
|
||||
During a deployment they can also create a great deal of noise. As part of a deployment, it is common for applications to be restarted in mid-stream. This can cause a lot of transient errors like SQL connection issues, thread abort exceptions, and a wide array of other problems.
|
||||
|
||||
**Tip:** It is important to know what your standard application error rates are before the deployment, so you have an idea whether you are seeing an uptick in errors after the deployment or the error rate is normal.
|
||||
|
||||
**Tip:** Look for new application errors that you have never seen before. Odds are, there is a new null reference exception, SQL timeout, or some other error that will surface with the new deployment. Find it quickly and get ready to hot fix it.
|
||||
|
||||
Note: It is important to monitor your application for HTTP 4xx and 5xx errors along with exceptions being logged by your code itself.
|
||||
|
||||
How much traffic does your application get and what are normal page load times? These are key metrics that you should be monitoring before and after a deployment. If you suddenly get a lot more or less traffic, something could be really wrong.
|
||||
|
||||
A big dip in traffic could mean that users are getting errors and can’t further navigate to additional pages within your application. This would reduce the overall volume of traffic to your site.
|
||||
|
||||
Sometimes this problem can also manifest itself in the application you didn’t even deploy. For example, if your application uses a microservices architecture or makes a lot of internal HTTP web service calls, a new deployment could dramatically change the downstream traffic to your other applications. Keep an eye on their traffic levels to make sure nothing has change dramatically.
|
||||
|
||||
Monitoring the apdex score or customer satisfaction score for your application is a great way to keep the pulse on how well your application is performing. Stackify Retrace automatically tracks this as a customer satisfaction score.
|
||||
|
||||
This score is based on how many web requests were fast, sluggish, slow, and failed. It is a simple math formula that helps you understand the overall performance of your software. Tracking it is a great industry best practice.
|
||||
|
||||
At Stackify, our goal is for our score to be 99%. It is a metric that we monitor constantly. During a deployment you can expect your score to dip slightly. Just after a deployment you should check your score to make sure that it comes back to a normal level.
|
||||
|
||||
Even when deploying to the cloud, CPU usage and overall server load still matters. Sometimes a slight code change can cause huge differences in CPU usage and overall performance. This is especially true in applications that auto-scale across a lot of servers. A few code tweaks here and there can reduce the overall number of servers that you need.
|
||||
|
||||
It is important to keep an eye on the # of servers needed to run your application and the overall CPU usage on your servers.
|
||||
|
||||
If your application uses a SQL database, probably each deployment is going to include some changes to how your SQL database is used, including new SQL queries, changes to existing ones, etc.
|
||||
|
||||
You should always track which SQL queries are used the most and which use the most resources within your database server. A slight change to a SQL query could cause a major bottleneck in your performance!
|
||||
|
||||
Today’s applications use a wide variety of application dependencies. Including SQL & NoSQL databases, caching, queues, storage, HTTP web services, and much more. It is important to keep an eye on the performance of all of these dependencies. These include popular services like Redis, Elasticsearch, MongoDB, etc.
|
||||
|
||||
A slight code change to how your application access something like Redis or an HTTP web service could dramatically change the performance of your code in production. You want to keep an eye out before and after a deployment to see if any major changes have occurred.
|
||||
|
||||
One of the keys to a successful software deployment is communication. At Stackify, we rely heavily on Slack as the central hub of all communication within our company. This includes doing deployments.
|
||||
|
||||
We have a #deployments Slack channel that anyone can monitor to know exactly what is going on before, during, and after a deployment. We also utilize automated Slack alerts via Bamboo which we use for doing deployments.
|
||||
|
||||
As we know, doing a deployment isn’t just the single push of a button. When we do deployments at Stackify, we have to first push SQL change scripts to over 1,000 databases. We also have to deploy up to 10 different web and background service applications that run our infrastructure. This is quite a process that takes time.
|
||||
|
||||
Communicating the progress over our Slack channels helps everyone keep in sync. Anyone who wants to monitor the progress can follow along.
|
||||
|
||||
After you have pushed out new code, it is always a good idea to do some final regression testing. This could be via automated synthetic tests or by doing some quick tests of your own. Even if I have awesome application monitoring setup with a tool like Retrace, I always feel better knowing I have logged in myself and clicked around on a few critical pages within my application.
|
||||
|
||||
Many organizations also have entire processes around doing release validation and regression testing. They will re-run many of the tests they run in QA. It is also common to re-test bugs that were supposed to be fixed in the release before communicating to customers that the fixes have been deployed.
|
||||
|
||||
If you have automated tests, monitoring them definitely applies to this article. Even if you don’t, be sure to monitor Slack to make sure that all the final regression and validation tests pass. That is your signal to have a beer and celebrate another successful software deployment!
|
||||
|
||||
Software deployments are the end result of our hard work. They can also be stressful due to the risk of potentially deploying bad code. It is important to monitor your software at all times with solutions like [Retrace](https://stackify.com/retrace/). This helps you quickly identify when new problems arise or key metrics around error rates, performance, and others are abnormal.
|
||||
|
||||
Stackify's APM tools are used by thousands of .NET, Java, PHP, Node.js, Python, & Ruby developers all over the world.
|
||||
|
||||
Explore Retrace's product features to learn more.
|
||||
|
||||
-
|
||||
|
||||
[App Performance Management](https://stackify.com/retrace-application-performance-management/)
|
||||
|
||||
-
|
||||
|
||||
[Code Profiling](https://stackify.com/retrace-code-profiling/)
|
||||
|
||||
-
|
||||
|
||||
[Error Tracking](https://stackify.com/retrace-error-monitoring/)
|
||||
|
||||
-
|
||||
|
||||
[Centralized Logging](https://stackify.com/retrace-log-management/)
|
||||
|
||||
-
|
||||
|
||||
[App & Server Metrics](https://stackify.com/retrace-app-monitoring/)
|
||||
|
||||
Reference in New Issue
Block a user