SRE weekly 所有文章
This commit is contained in:

209
sreweekly/markdown/208/01-anatomy-of-cascading-failure.md
Normal file
209
sreweekly/markdown/208/01-anatomy-of-cascading-failure.md
Normal file
@@ -0,0 +1,209 @@
|
||||
# Anatomy of Cascading Failure
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Laura Nolan — Slack
|
||||
- **链接**: https://www.infoq.com/articles/anatomy-cascading-failure/
|
||||
|
||||
## 简介
|
||||
|
||||
There’s so much in this article:how to recognize when your system may be susceptible to cascading failurehow to prevent ithow to deal with it when it happens (and how hard that can be)
|
||||
|
||||
## 正文
|
||||
|
||||
### Key Takeaways
|
||||
|
||||
- Cascading failures are failures that involve some kind of feedback mechanism. In distributed software systems they generally involve a feedback loop where some event causes either a reduction in capacity, an increase in latency, or a spike of errors; then the response of the other components of the system makes the original problem worse.
|
||||
- It’s often very difficult to scale out of a cascading failure by adding more capacity to your service: new healthy instances get hit with excess load instantly and become saturated, so you can’t get to a point where you have enough serving capacity to handle the load.
|
||||
- Sometimes, the only fix is to take your entire service down in order to recover, and then reintroduce load.
|
||||
- The potential for cascading failures is inherent in many, if not most, distributed systems. If you haven’t seen one in your system yet, it doesn’t mean you’re immune; you may just be operating comfortably within your system’s limits. There’s no guarantee that will be true tomorrow, or next week.
|
||||
|
||||
## What is a Cascading Failure?
|
||||
|
||||
Cascading failures are failures that involve some kind of feedback mechanism—in other words, vicious cycles in action.
|
||||
|
||||
|
||||
|
||||
The outage that [took down Amazon DynamoDB in US-East-1 on September 20, 2015](https://aws.amazon.com/message/5467D2/) for over four hours is a classic example of a cascading failure. There were two subsystems involved: storage servers and a metadata service. Storage servers request their data partition assignments from the metadata service, which is replicated across data centers. At the time the incident occurred, the average time to retrieve partition assignments had risen significantly, because of the introduction of a new index type (Global Secondary Indexes or GSIs), but the capacity of the metadata service hadn’t been increased, nor had the configured deadlines for the data-partition assignment request operation. Any request that didn’t succeed within that deadline was considered to have failed, and the client would retry.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 1: Services involved in September 2015 DynamoDB outage**
|
||||
|
||||
The incident was triggered by a transient network problem, which caused some of the storage servers to not receive their partition assignments.
|
||||
|
||||
Those storage servers removed themselves from service, and they also continued to retry their requests for partition assignments. The metadata servers became overwhelmed with load from these requests and were therefore slower to respond, which caused more requests sent to them to timeout and be retried. These retries increased the load on the service further. The metadata service was so badly overloaded that operators had to firewall the it off from the storage servers in order to add extra capacity. This meant effectively taking the entire DynamoDB service offline in US-East-1.
|
||||
|
||||
## Why are Cascading Failures So Bad?
|
||||
|
||||
The biggest issue with cascading failures is that they can take down your entire system, toppling instances of your service one by one, until your entire load-balanced service is unhealthy.
|
||||
|
||||
The second problem is they’re an exceptionally hard type of failure from which to recover. They normally start with some small perturbation — like a transient network issue, a small spike in load, or the failure of a few instances. Instead of recovering to a normal state over time, the system gets into a worse state. A system in cascading failure won’t self-heal; it’ll only be restored through human intervention.
|
||||
|
||||
The third problem is that if the right conditions exist in your system, cascading failures can strike with no warning. Unfortunately, the basic preconditions for cascading failures are difficult to avoid: it’s simply failover. If failure of a component can cause retries, or cause load to shift to other parts of your system, then the basic conditions for cascading failure are there. But all is not lost: there are patterns we can apply that help us defend our systems against cascading failures.
|
||||
|
||||
## Feedback Cycles: How Cascading Failures Take Down Our Systems
|
||||
|
||||
Cascading failures in distributed software systems generally involve a feedback loop where some event causes either a reduction in capacity, an increase in latency, or a spike of errors; then the response of the other components of the system makes the original problem worse.
|
||||
|
||||
The Causal Loop Diagram (CLD) is a good tool to understand these incidents. Below is a CLD for the DynamoDB incident from earlier.
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 2: Causal Loop Diagram for September 2015 DynamoDB outage**
|
||||
|
||||
*CLDs are a tool from System Dynamics, an approach to modelling complex systems invented by Jay Forrester at MIT. Each arrow shows how two quantities in the system interact. A ‘+’ beside the arrow means that an increase in the first quantity will tend to increase the second quantity, and a ‘-’ means there is an inverse relationship. So, it follows that increasing the capacity of the service, i.e. the number of instances serving it, will reduce the load per instance. Adding a new type of index, or retries from failing requests will tend to increase it.*
|
||||
|
||||
Where we have a cycle in the diagram, as we do here, we can look at the signs and see if the cycle is balanced, a mixture of ‘+’ and ‘-’. Here, we have all ‘+’ signs in the cycle, meaning that it’s not balanced. In System Dynamics, this is called a "reinforcing cycle" (hence the ‘R’ in the centre with the arrow around it).
|
||||
|
||||
Having a reinforcing cycle in your system doesn’t mean it’ll constantly be in overload. If capacity is sufficient to meet demand, it will work fine. However, it does mean that in the right circumstances — a reduction in capacity, a spike in load, or anything else that that pushes latency or timeouts above a critical threshold — a cascading failure might occur, such as happened to DynamoDB.
|
||||
|
||||
A key realisation — a very similar cycle exists for most replicated services with clients that retry on failure. This is a very, very common pattern. Later in this article we will examine some patterns that help prevent this cycle turning into a cascading failure scenario.
|
||||
|
||||
Let’s look at another example of a cascading failure: [Parsely’s Kafkapocalyspe](https://blog.parse.ly/post/1738/kafkapocalypse/). The systems involved here are different, but the pattern is similar. Due to a launch, Parsely had increased the load on their systems, including their Kafka cluster. Unbeknownst to them, they were close to the network limits on the EC2 nodes on which they were running their Kafka brokers. At some point, one broker hit its network limit, and became unavailable. Load increased on other brokers, as clients failed over, and very quickly all the brokers were down.
|
||||
|
||||
As with the earlier AWS scenario, we see from the Parsely outage how quickly a system can go from being stable and predictable to a very nonlinear and dysfunctional state once a limit is breached, and how recovery doesn’t happen until operators intervene.
|
||||
|
||||
## Recovering From Cascading Failure
|
||||
|
||||
It’s often very difficult to scale out of a cascading failure by adding more capacity to your service: new healthy instances get hit with excess load instantly and become saturated, so you can’t get to a point where you have enough serving capacity to handle the load.
|
||||
|
||||
Many load-balancing systems use a health check to send requests only to healthy instances, though you might need to turn that behavior off during an incident to avoid focusing all the load on brand-new instances as they are brought up. The same is true of any kind of orchestration or management service that kills instances of your servers that fail health checks (such as [kubernetes liveness probes](https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/)); they will remove overloaded instances, contributing to the capacity problem.
|
||||
|
||||
Sometimes, the only fix is to take your entire service down in order to recover, and then reintroduce load. We saw this in the DynamoDB outage. [Spotify had an outage in 2013](https://labs.spotify.com/2013/06/04/incident-management-at-spotify/) where they also had to take the impacted service offline to recover. This is especially likely where the overloaded service doesn’t impose any limit on the number of queued or current requests.
|
||||
|
||||
## Six Cascading Failure Antipatterns
|
||||
|
||||
### Antipattern 1: Accepting unbounded numbers of incoming requests
|
||||
|
||||
Anyone who’s done much benchmarking has probably noticed that individual instances of a service generally hit a peak in throughput; then, if load increases further, you see a drop in throughput and an increase in latency. This change happens because some of the work in any service is not parallelizable (there’s a good explanation of the maths in [Baron Schwartz's talk 'Approaching the Unacceptable Workload Boundary'](https://www.usenix.org/conference/srecon18americas/presentation/schwartz)). In a state of cascading failure, individual service instances can end up with so many queued requests, or so many concurrent threads trying to execute, that the service can become totally unresponsive and may not recover without intervention (generally, a restart). Duo experienced conditions like this during an [outage in 2018](https://status.duo.com/incidents/4w07bmvnt359): *"We determined that limiting was ineffective because of the way our application queues requests while waiting for a database connection. In this case, these queued requests had built up in such a way that the database could not recover as it tried to process this large backlog of requests, even after traffic subsided and the limits were in place."*
|
||||
|
||||
This is why setting a limit on the load on each instance of your service is so important. [Loadshedding](https://www.usenix.org/conference/srecon17europe/program/presentation/cruz) at a load-balancer works, but you should set limits in your service as well, for defense in depth. The mechanisms to implement a limit on concurrent requests vary, depending on the programming language and server framework you’re using, but might be as simple as a semaphore. Netflix’s [concurrency-limits](https://github.com/Netflix/concurrency-limits) tool is a Java-based example.
|
||||
|
||||
Failing requests early when a server is heavily loaded is actually also good for clients. It’s better to get a fast failure and retry to a different instance of the service, or serve an error or a degraded experience, than wait until the request deadline is up (or indefinitely, if there’s no request deadline set). Allowing this to happen can lead to slowness that spreads through an entire microservice architecture, and it can sometimes be tricky to find the service that is the underlying cause, when every service has ground to a halt.
|
||||
|
||||
### Antipattern 2: Dangerous client retry behaviour
|
||||
|
||||
We don’t always have control over client behaviour, but if you do control your clients, moderating client request patterns can be a very useful tool. At the most basic level, clients should limit the number of times they retry a failed request within a short period of time. In a system where clients retry too many times in a tight loop, any minor spike of errors can cause a flood of retried requests, effectively DOSing the service. Square experienced this in [March 2017](https://medium.com/square-corner-blog/incident-summary-2017-03-16-2f65be39297) when their Redis instance became unavailable because of a code path that would retry a transaction up to 500 times. Here is sample Golang code for that simple retry loop:
|
||||
|
||||
```
|
||||
```
|
||||
```
|
||||
const MAX_RETRIES = 500
|
||||
for i := 0; i < MAX_RETRIES; i++ {
|
||||
_, err := doServerRequest()
|
||||
if err == nil {
|
||||
break
|
||||
}
|
||||
}
|
||||
```
|
||||
When Square’s engineers rolled out a fix to reduce the number of retries, the feedback loop immediately ended and their service began serving normally.
|
||||
|
||||
Clients should use an exponentially increasing backoff between retry attempts. It’s also good practice to add a little random noise, or jitter, to the backoff time. This ‘smears’ a wave of retries out over time, so a service that’s temporarily glitching for a few milliseconds doesn’t get hit with twice its normal load when all clients simultaneously retry. The number of retries and how long to wait is application specific. User-facing requests should fail fast or return a degraded result of some kind, whereas batch or asynchronous processing can wait much longer.
|
||||
|
||||
Here is sample Golang code for a retry loop with exponential backoff and jitter:
|
||||
|
||||
```
|
||||
```
|
||||
```
|
||||
const MAX_RETRIES = 5
|
||||
const JITTER_RANGE_MSEC = 200
|
||||
steps_msec := []int{100, 500, 1000, 5000, 15000}
|
||||
rand.Seed(time.Now().UTC().UnixNano())
|
||||
for i := 0; i < MAX_RETRIES; i++ {
|
||||
_, err := doServerRequest()
|
||||
if err == nil {
|
||||
break
|
||||
}
|
||||
time.Sleep(time.Duration(steps_msec[i] + rand.Intn(JITTER_RANGE_MSEC)) *
|
||||
time.Millisecond)
|
||||
}
|
||||
```
|
||||
Modern best practice goes a step beyond exponential backoff and jitter. The [Circuit Breaker](https://www.martinfowler.com/bliki/CircuitBreaker.html) application design pattern wraps calls to an external service and tracks success and failure of those calls over time. A sequence of failed calls will ‘trip’ the circuit breaker, meaning that no more calls will be made to the failing external service, and clients attempting to make such calls will immediately get an error. Periodically, the circuit breaker will probe the external service by allowing one call through. If the probe request succeeds, the circuit breaker will reset and again start making calls to the external service.
|
||||
|
||||
Circuit breakers are powerful because they can share state across all requests from a client to the same backend, whereas exponential backoff is specific to a single request. Circuit breakers reduce the load on a struggling backend service more than any other approach. Here’s a [circuit breaker implementation](https://github.com/matttproud/golang_circuitbreaker) for Golang. Netflix’s Hystrix includes a [Java circuit breaker](https://github.com/Netflix/Hystrix/wiki/How-it-Works#CircuitBreaker).
|
||||
|
||||
### Antipattern 3: Crashing on bad input — the ‘Query of Death’
|
||||
|
||||
This ‘query of death’ is any request to your system that can cause it to crash. A client may send a query of death, crash one instance of your service, and keep retrying, bringing further instances down. The reduction in capacity can then potentially bring your entire service down as the remaining instances get overloaded from the normal workload.
|
||||
|
||||
This kind of scenario can be the result of an attack on your service, but it may not be malicious, just bad luck. This is why it’s a best practice to never exit or crash on unexpected inputs; a program should exit unexpectedly only if internal state seems to be incorrect and it would be unsafe to continue serving.
|
||||
|
||||
Fuzz testing is an automated testing practice that can help detect programs that crash on malformed inputs. Fuzz testing is especially important for any service that is exposed to untrusted inputs, which means anything outside your organisation.
|
||||
|
||||
### Antipattern 4: Proximity-based failover and the domino effect
|
||||
|
||||
What do your systems do if an entire data center or availability zone goes down? If the answer is ‘fail over to the next nearest one’ then your systems have the potential for a cascading failure.
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 3: Map of data center locations**
|
||||
|
||||
If you lost one of your US East Coast data centers in a topology, like the one shown above, then the other data center in that region would get roughly twice the load as soon as users failed over. If the remaining US East Coast data center couldn’t manage the load and also failed, then the load would likely go primarily to US West Coast data centers (it’s cheaper than sending traffic to Europe, usually). If those failed, then your remaining locations would likely go down next: like dominos. Your failover plan, which is intended to improve your system’s reliability, has brought your entire service down.
|
||||
|
||||
Geographically balanced systems like this need to do one of two things: either make sure that load fails over in a way that doesn’t overload the remaining data centers, or else maintain a lot of capacity everywhere.
|
||||
|
||||
Systems that are based on IP Anycast (like most DNS services and many CDNs) generally overprovision, specifically because anycast, which serves a single IP from many points on the Internet, gives you no way to control inbound traffic.
|
||||
|
||||
This level of overprovisioning for failure can be very expensive. For many systems, using a way to direct load to data centers that have capacity available makes more sense. This is often done using DNS load balancing (for example [NS1’s intelligent traffic distribution](https://ns1.com/blog/using-load-shedding-for-intelligent-traffic-distribution-1)).
|
||||
|
||||
### Antipattern 5: Work prompted by failure
|
||||
|
||||
Sometimes, our services do work when a failure occurs. Consider a hypothetical distributed data store system that splits our data into blocks. We want a minimum number of replicas of each block, and we regularly check that we have the right number of copies. If we don’t, then we start making new copies. Here’s a pseudo-code snippet:
|
||||
|
||||
```
|
||||
```
|
||||
```
|
||||
replicaChecker()
|
||||
while true {
|
||||
for each block in filesystem.GetAllBlocks() {
|
||||
if block.replicasHeartbeatedOK() < minReplicas {
|
||||
block.StartCopyNewReplica()
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 4: Replication of data blocks after a failure.**
|
||||
|
||||
This approach will probably work fine if we lose one block, or one server of many. But what if we lose a substantial proportion of the servers? An entire rack? The serving capacity of the system will be reduced, and the remaining servers are going to be busy re-replicating data. We haven’t put any limits on how much replication we’re going to do at a time. Here’s a Causal Loop Diagram showing the feedback loop.
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 5: Causal loop diagram showing the feedback loop in the system**
|
||||
|
||||
The usual way around this is to delay replication (because failure is often transient), and limit the number of in-flight replication processes with something like the [token bucket](https://en.wikipedia.org/wiki/Token_bucket) algorithm. The Causal Loop Diagram below shows how this changes the system: we still have a feedback loop, but there’s now an inner balanced loop that prevents the feedback cycle from running away.
|
||||
|
||||

|
||||
|
||||
|
||||
**Figure 6: Causal loop diagram showing rate limit on replication**
|
||||
|
||||
### Antipattern 6: Long startup times
|
||||
|
||||
Sometimes, services are designed to do a lot of work on startup—perhaps by reading and caching a lot of data. This pattern is best avoided, for two reasons. First, it makes any form of autoscaling hard:by the time you’ve detected an increase in load and started up your slow-to-start-up service, you may be in trouble. Second, if instances of your service fail for some reason (out of memory, or a query of death causes them to crash) it will take you a long time to get back to your usual serving capacity. Both of these conditions can easily lead to overload on your service.
|
||||
|
||||
## Reducing Cascading Failure Risks
|
||||
|
||||
The potential for cascading failures is inherent in many, if not most, distributed systems. If you haven’t seen one in your system yet, it doesn’t mean you’re immune; you may just be operating comfortably within your system’s limits. There’s no guarantee that will be true tomorrow, or next week.
|
||||
|
||||
We’ve listed a number of antipatterns to avoid if you want to reduce the risk of experiencing a cascading failure. No service can withstand an arbitrary spike of load. Nobody wants their service to serve errors, but sometimes it’s the lesser evil, when the alternative is to see your entire service grind to a standstill trying to deal with every incoming request.
|
||||
|
||||
## Further Reading
|
||||
|
||||
- '[Addressing Cascading Failures](https://landing.google.com/sre/sre-book/chapters/addressing-cascading-failures/) ,' by Mike Ulrich, in*Site Reliability Engineering: How Google runs Production Systems* .
|
||||
- 'Stability Patterns' chapter in *Release It!* by Michael T Nygard.
|
||||
- '[Handling Overload](https://landing.google.com/sre/sre-book/chapters/handling-overload/) ' chapter by Alejandro Forero Cuervo in*Site Reliability Engineering: How Google runs Production Systems* .
|
||||
|
||||
## About the Author
|
||||
|
||||
**Laura Nolan** is a Senior Staff Engineer at Slack Technologies in Dublin. Her background is in Site Reliability Engineering, software engineering, distributed systems, and computer science. She wrote the 'Managing Critical State' chapter in the O'Reilly 'Site Reliability Engineering' book, as well as contributing to the more recent 'Seeking SRE'. She is a member of the USENIX SREcon steering committee.
|
||||
@@ -0,0 +1,35 @@
|
||||
# Catchpoint’s SRE Survey 2020 Is Here
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Peter Murray — Catchpoint
|
||||
- **链接**: https://blog.catchpoint.com/2020/01/30/catchpoints-sre-survey-2020-is-here/
|
||||
|
||||
## 简介
|
||||
|
||||
It’s time for this year’s SRE Survey. Don’t forget that with each completed survey, Catchpoint donates $5 to charity.
|
||||
|
||||
> This growing demand [for SREs] is not without growing pains as a skills gap problem has emerged due to the fact that SRE training requires a hands-on, interactive learning environment.
|
||||
|
||||
## 正文
|
||||
|
||||
### SRE Report: AI optimism and the economics of effort
|
||||
|
||||
February 10, 2026
|
||||
|
||||
February 10, 2026
|
||||
|
||||
Thank you! Your submission has been received!
|
||||
|
||||
Oops! Something went wrong while submitting the form.
|
||||
|
||||
Showing 0 out of 0 posts
|
||||
|
||||
January 22, 2026
|
||||
|
||||
December 17, 2025
|
||||
|
||||
December 2, 2025
|
||||
|
||||
No results found
|
||||
|
||||
Please try different keywords
|
||||
@@ -0,0 +1,15 @@
|
||||
# Resilience Roundup – Above the Line, Below the Line
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Thai Wood (summary)Dr. Richard Cook (original article)
|
||||
- **链接**: https://resilienceroundup.com/issues/68/
|
||||
|
||||
## 简介
|
||||
|
||||
Both the summary and the original article are well worth reading. This stood out to me:
|
||||
|
||||
> As much as we may think of incidents as taking place in all those technical parts of the system below the line, incidents actually take place above it
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,590 @@
|
||||
# The Jellyfish-Inspired Database Under AWS Block Storage
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Timothy Prickett Morgan — The Next Platform
|
||||
- **链接**: https://www.nextplatform.com/2020/02/18/the-jellyfish-inspired-database-under-aws-block-storage/
|
||||
|
||||
## 简介
|
||||
|
||||
The EBS control plane data store resembles a “jellyfish” (actually a Physalia, a.k.a. Portuguese man-of-war).
|
||||
|
||||
## 正文
|
||||
|
||||
## Broadcom Rides Rocketing Trend For Custom AI Accelerators
|
||||
|
||||
September 10, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Nvidia Expands Its Open Source AI Presence With $12.9 Billion Hugging Face Buy
|
||||
|
||||
September 3, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Optics Still Driving Marvell’s AI Business More Than Custom Chips
|
||||
|
||||
September 2, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## VMware Intros Private AI Cloud, AI Factory As Workloads Shift To On-Prem
|
||||
|
||||
September 1, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## In The Long Run, Nvidia NVSwitch Is The InfiniBand Of Scale Up AI Networks
|
||||
|
||||
August 31, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[COMPUTE](https://www.nextplatform.com/compute/2026/08/27/peeling-apart-that-supposed-120-billion-chip-deal-google-inked-with-marvell/5292984)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Peeling Apart That Supposed $120 Billion Chip Deal Google Inked With Marvell
|
||||
|
||||
August 27, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## IBM Pushes System Design To Reach Ultra-Cold Temperatures For Quantum
|
||||
|
||||
August 19, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Cerebras Overclocks WSE-3 Waferscale Engine To Boost Inference Oomph In “Nexus” CS-4
|
||||
|
||||
August 19, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
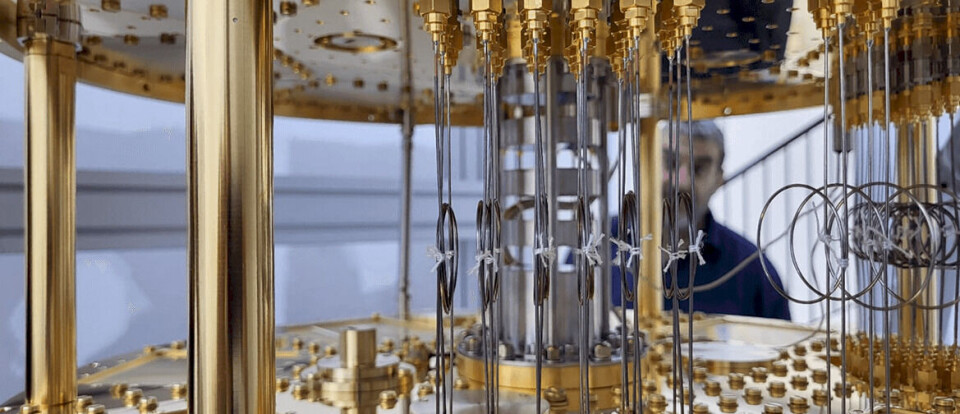
||||
|
||||
|
||||
## Quantum Startup Qarakal Takes Lessons From Classical Systems With Pangaea Architecture
|
||||
|
||||
August 18, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[CONNECT](https://www.nextplatform.com/connect/2026/08/17/cisco-can-finally-sell-lots-of-supercomputers-and-their-networks/5288804)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Cisco Can Finally Sell Lots Of Supercomputers And Their Networks
|
||||
|
||||
August 17, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[CLOUD](https://www.nextplatform.com/cloud/2026/08/14/the-neoclouds-build-cash-hoards-faster-than-revenues/5288040)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## The Neoclouds Build Cash Hoards Faster Than Revenues
|
||||
|
||||
August 14, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[AI](https://www.nextplatform.com/ai/2026/08/13/the-war-between-open-source-open-weight-and-closed-ai-models/5287504)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## The War Between Open Source, Open Weight, And Closed AI Models
|
||||
|
||||
August 13, 2026
|
||||
|
||||
|
||||
|
||||
[COMPUTE](https://www.nextplatform.com/compute/2026/08/13/the-genai-boom-will-lift-supermicro-but-it-will-lift-others-too/5287161)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## The GenAI Boom Will Lift Supermicro, But It Will Lift Others, Too
|
||||
|
||||
August 13, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Nvidia Drives Bang For The Buck With New GenAI Model And Router
|
||||
|
||||
August 11, 2026
|
||||
|
||||
|
||||
|
||||
[connect](https://www.nextplatform.com/connect/2026/08/10/as-ai-networks-scale-in-three-directions-so-does-arista/5285500)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## As AI Networks Scale In Three Directions, So Does Arista
|
||||
|
||||
August 10, 2026
|
||||
|
||||
|
||||
|
||||
[ai](https://www.nextplatform.com/cloud/2026/08/06/google-builds-a-new-gemini-model-team-as-ai-investments-accelerate/5284258)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Google Builds A New Gemini Model Team As AI Investments Accelerate
|
||||
|
||||
August 6, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[CLOUD](https://www.nextplatform.com/cloud/2026/08/04/why-shouldnt-amazon-spinoff-aws-and-annapurna-labs/5282586)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Why Shouldn’t Amazon Spinoff AWS And Annapurna Labs?
|
||||
|
||||
August 4, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[COMPUTE](https://www.nextplatform.com/compute/2026/07/31/ibm-three-demonstrations-prove-quantum-advantage-has-been-reached/5282091)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## IBM: Three Demonstrations Prove Quantum Advantage Has Been Reached
|
||||
|
||||
August 1, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[CLOUD](https://www.nextplatform.com/cloud/2026/07/31/ai-dominates-the-microsoft-conversation-but-not-the-companys-business/5281992)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## AI Dominates The Microsoft Conversation, But Not The Company’s Business
|
||||
|
||||
July 31, 2026
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
[COMPUTE](https://www.nextplatform.com/compute/2026/07/30/just-how-rosy-are-those-ai-infrastructure-spending-forecasts/5281473)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Just How Rosy Are Those AI Infrastructure Spending Forecasts?
|
||||
|
||||
July 31, 2026
|
||||
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
# The Problem with Microservices: ‘Deep Systems’
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Ben Sigelman — LightStep
|
||||
- **链接**: https://www.enterpriseai.news/2020/02/18/how-developers-can-overcome-the-microservices-deep-systems-problem/
|
||||
|
||||
## 简介
|
||||
|
||||
Ideal: each team manages their microservice(s) in isolation.
|
||||
|
||||
Reality: microservices interact in unexpected ways and a broader system emerges that has remarkable similarities to running a monolith.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,92 @@
|
||||
# SRE for single-tiered software applications
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: Eric Harvieux — Google
|
||||
- **链接**: https://cloud.google.com/blog/products/management-tools/sre-for-single-tiered-software-applications/
|
||||
|
||||
## 简介
|
||||
|
||||
This one discusses how to handle SRE for a monolith, and some examples of what often goes wrong.
|
||||
|
||||
## 正文
|
||||
|
||||
# Making your monolith more reliable
|
||||
|
||||
##### Eric Harvieux
|
||||
|
||||
SRE Systems Engineer
|
||||
|
||||
In cloud operations, we often hear about the benefits of microservices over monolithic architecture. Indeed, microservices help manage hardware being abstracted away and push developers towards resilient, distributed designs. However, many enterprises still have monolithic architectures which they need to maintain.
|
||||
|
||||
For this post, we’ll use [Wikipedia’s definition of a monolith](https://en.wikipedia.org/wiki/Monolithic_application): “A single-tiered software application in which the user interface and data access code are combined into a single program from a single platform.”
|
||||
|
||||
When and why to choose monolithic architecture is usually a matter of what works best for each business. Whatever the reason for using monolithic services, you still have to support them. They do, however, bring their own reliability and scaling challenges, and that’s what we’ll tackle in this post. At Google, we use site reliability engineering (SRE) principles to ensure that systems run smoothly, and these principles apply to monoliths as well as microservices.
|
||||
|
||||
### Common problems with monoliths
|
||||
|
||||
We’ve noticed some common problems that arise in the course of operating monoliths. Particularly, as monoliths grow (either scaling with increased usage, or growing more complex as they take on more functionality), there are several issues we commonly have to address:
|
||||
|
||||
- **Code base complexity** : Monoliths contain a broad range of functionality, meaning they often have a large amount of code and dependencies, as well as hard-to-follow code paths, including RPC calls that are not load-balanced. (These RPCs call to themselves or call between different instances of a binary if the data is sharded.)
|
||||
- **Release process difficulty** : Frequently, monoliths consist of code submitted by contributors across many different teams. With more cooks in the kitchen and more code being cooked up every release cycle, the chances of failure increase. A release could fail QA or fail to deploy into production. These services often have difficulty reaching a mature state of automation where we can safely and continuously deploy to production, because the services require human decision-making to promote them into production. This puts additional burden on the monolith owners to detect and resolve bugs, and slows overall velocity.
|
||||
- **Capacity** : Monolithic servers typically serve various types of requests, and that variation means that in order to complete the requests, differences in compute resources—CPU, memory, storage I/O, and so on—are required. For example, an RDBMS-backed server might handle view-only requests that read from the database and are reasonably cacheable, but may also serve RPCs that write to the database, which must be committed before returning to the user. The impact on CPU and memory consumption can vary greatly between these two. Let’s say you load-test and determine your deployment handles 100 queries per second (qps) of your typical traffic. What happens if usage or features change, resulting in a higher number of expensive write queries? It’s easy to introduce these changes—they happen organically when your users decide to do something different, and can threaten to overwhelm your system. If you don’t check your capacity regularly, you can end up being underprovisioned gradually over time.
|
||||
- **Operational difficulty** : With so much functionality in one monolithic system, the ability to respond to operational incidents becomes more consequential. Business-critical code shares a failure domain with low-priority code and features. Our Google SRE guidelines require changes to our services to be[safe to roll back](https://landing.google.com/sre/sre-book/chapters/release-engineering/) . In a monolith with many stakeholders, we need to coordinate more carefully than with microservices, since the rollback may revert changes unrelated to the outage, slow development velocity, and potentially cause other issues.
|
||||
|
||||
How does an SRE address the issues commonly found in monoliths? The rest of this post discusses some best practices, but these can be distilled down to a single idea: Treat your monolith as a platform. Doing so helps address the operational challenges inherent in this type of design. We’ll describe this monolith-as-a-platform concept to illustrate how you can build and maintain reliable monoliths in the cloud.
|
||||
|
||||
### Monolith as a platform
|
||||
|
||||
A software platform is essentially a piece of software that provides an environment for other software to run. Taking this platform approach toward how you operate your monolith does a couple of things. First, it establishes responsibility for the service. The platform itself should have clear owners who define policy and ensure that the underlying functionality is available for the various use cases. Second, it helps frame decisions about how to deploy and run code in a way that balances reliability with development velocity.
|
||||
|
||||
Having all the monolith code contributors share operational responsibility sets individuals against each other as they try to launch their particular changes. Instead of sharing operational responsibility, however, the goal should be to have a knowledgeable arbiter who ensures that the health of the monolith is represented when designing changes, and also during production incidents.
|
||||
|
||||
### Scaling your platform
|
||||
|
||||
Monoliths that are run well converge on some common best practices. This is not meant to be a complete list and is in no particular order. We recommend considering these solutions individually to see if they might improve monolith reliability in your organization:
|
||||
|
||||
- **Plug-in architecture** : One way to manifest the platform mindset is to structure your code to be modular, in a way that supports the service’s functional requirements. Differentiate between core code needed by most/all features and dedicated feature code. The platform owners can be gatekeepers for changes to core code, while feature owners can change their code without owner oversight. Isolate different code paths so you can still build and run a working binary with some chosen features disabled.
|
||||
|
||||
- **Policies for new code and backends** : Platform owners should be clear with the requirements for adding new functionality to the monolith. For example, to be resilient to outages in downstream dependencies, you may set a latency requirement stating that new back-end calls are required to time out within a reasonable time span (milliseconds or seconds), and are only retried a limited number of times before returning an error. This prevents a serving thread from getting stuck, waiting indefinitely on an RPC call to a backend, and possibly exhausting CPU or memory.
|
||||
Similarly, you might require developers to load test their changes before committing or enabling a new feature in production, to ensure there are no performance or resource requirement regressions. You may want to restrict new endpoints from being added without your operation team’s knowledge.
|
||||
|
||||
- **Bucket your SLOs** : For a monolith serving many different types of requests, there’s a tendency to define a new SLI and SLO for each request. As the number of SLOs increases, however, it gets more confusing to track and harder to assess the impact of error budget burn for one SLO vs. all the others. To overcome this issue, try bucketing requests based on the similarity of the code path and performance characteristics. For example, we can often bucket latency for most “read” requests into one group (usually lower latency), and create a separate SLO bucket for “write” requests (usually higher latency). The idea is to create groupings that indicate when your users are suffering from reliability issues.
|
||||
Which team owns a particular SLO or deciding whether an SLO is even needed for each feature are important considerations. While you want your on-call engineer to respond to business-critical outages, it’s fine to decide that some parts of the service are lower-priority or best-effort, as long as they don’t threaten the overall stability of the platform.
|
||||
- **Set up traffic filtering** : Make sure you have the ability to filter traffic by various characteristics, using a web application firewall (WAF) or similar method. If one RPC method experiences a[Query of Death](https://landing.google.com/sre/sre-book/chapters/addressing-cascading-failures/) (QoD), you can temporarily block similar queries, thereby mitigating the situation and giving you time to fix the issue.
|
||||
- **Use feature flags** : As described in the[SRE book](https://landing.google.com/sre/sre-book/chapters/reliable-product-launches/) , giving specific features a knob to disable all or some percentage of traffic is a powerful tool for incident response. If a particular feature threatens the stability of the whole system, you can throttle it down or turn it off, and continue serving all your other traffic safely.
|
||||
- **Flavors of monoliths** : This last practice is important, but should be carefully considered, depending on your situation. Once you have feature flags, it’s possible to run different pools of the same binary, with each pool configured to handle different types of requests. This helps tremendously when a reliability issue requires you to re-architect your service, which may take some time to develop. Within Google, we once ran different pools of the same web server binary to serve web search and image search traffic separately, because performance profiles were so different. It was challenging to support them in a single deployment but they all shared the same code, and each pool only handled its own type of request.
|
||||
There are downsides to this mode of operation, so it’s important to approach this thoughtfully. Separating services this way may tempt engineers to fork services, in spite of the large amount of shared code, and running separate deployments increases operational and cognitive load. Therefore, instead of indefinitely running different pools of the same binary, we suggest setting a limited timeframe for running the different pools, giving you time to fix the underlying reliability issue that caused the split in the first place. Then, once the issue is resolved, merge serving back to one deployment.
|
||||
|
||||
Regardless of where your code sits on the monolith-microservice spectrum, your service’s reliability and users’ experience are what ultimately matters. At Google, we’ve learned—sometimes the hard way—from the challenges that various design patterns bring. In spite of these challenges, we continue to serve our users 24/7 by calling to mind [SRE principles](https://landing.google.com/sre/), and putting these principles into practice.
|
||||
|
||||
##### Related articles
|
||||
|
||||
[Infrastructure Modernization](https://cloud.google.com/blog/products/infrastructure-modernization/ai-powered-quick-assessments-in-migration-center)
|
||||
|
||||
### New AI-powered quick assessments in Migration Center turbocharge modernization
|
||||
|
||||
By Jeff Welsch • 2-minute read
|
||||
|
||||
|
||||
|
||||
[Databases](https://cloud.google.com/blog/products/databases/deep-dive-on-new-ai-powered-database-agents)
|
||||
|
||||
### Introducing Database Operations Agents: The future of autonomous database management
|
||||
|
||||
By Niranjan Shivprasad • 6-minute read
|
||||
|
||||
|
||||
|
||||
[Management Tools](https://cloud.google.com/blog/products/management-tools/cloud-monitoring-adds-long-lookback-alert-policies-for-promql)
|
||||
|
||||
### Anomaly detection using dynamic thresholds and two-year-long alerts in Cloud Monitoring
|
||||
|
||||
By Lee Yanco • 6-minute read
|
||||
|
||||

|
||||
|
||||
[Management Tools](https://cloud.google.com/blog/products/management-tools/alert-with-sql-in-cloud-monitoring-observability-analytics)
|
||||
|
||||
### From query to action: Introducing SQL alerting in Cloud Monitoring Observability Analytics
|
||||
|
||||
By Joy Wang • 4-minute read
|
||||
|
||||

|
||||
@@ -0,0 +1,13 @@
|
||||
# Trying to sneak in a sketchy .so over the weekend
|
||||
|
||||
- **期号**: SRE Weekly Issue #208(2020-02-23)
|
||||
- **作者**: rachelbythebay
|
||||
- **链接**: https://rachelbythebay.com/w/2020/02/09/horizonta/
|
||||
|
||||
## 简介
|
||||
|
||||
The author blocked an unexpected Sunday deploy of untested code, and it turned out to be a good thing they did.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:URLError: _ssl.c:1015: The handshake operation timed out
|
||||
Reference in New Issue
Block a user