SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,42 @@
|
||||
# Prevent application and network instability by serving stale content
|
||||
|
||||
- **期号**: SRE Weekly Issue #223(2020-06-14)
|
||||
- **作者**: Patrick HamannFull disclosure: Fastly is my employer.
|
||||
- **链接**: https://www.fastly.com/blog/prevent-application-network-instability-serve-stale-content
|
||||
|
||||
## 简介
|
||||
|
||||
I’ve used this technique in the past with a single-page app and a highly-cacheable API, to ensure stability even when the backend goes down.
|
||||
|
||||
## 正文
|
||||
|
||||
# [CMCDv2: Leveling Up Your Video Streaming Telemetry](https://www.fastly.com/blog/cmcdv2-leveling-up-your-video-streaming-telemetry)
|
||||
|
||||
Elevate your video streaming telemetry with CMCDv2. Discover how Request, Response, and Event modes offer deeper, full-stack insights into viewer performance.
|
||||
|
||||
|
||||
|
||||
## Staying Secure
|
||||
|
||||
### All blog posts
|
||||
|
||||
- [CMCDv2: Leveling Up Your Video Streaming Telemetry](https://www.fastly.com/blog/cmcdv2-leveling-up-your-video-streaming-telemetry)Elevate your video streaming telemetry with CMCDv2. Discover how Request, Response, and Event modes offer deeper, full-stack insights into viewer performance. 
|
||||
- [Accelerate Migrations: Introducing Direct Fetch for Fastly Object Storage](https://www.fastly.com/blog/accelerate-migrations-introducing-direct-fetch-fastly-object-storage)Accelerate your data migrations with Fastly's new Direct Fetch API for Object Storage. Transfer from S3-compatible sources directly, bypassing client limits. 
|
||||
- [CVE-2026-82329: JFrog Artifactory Authentication Bypass Exploitation Activity](https://www.fastly.com/blog/cve-2026-82329-jfrog-artifactory-authentication-bypass-exploitation-activity)Attacks targeting JFrog Artifactory (CVE-2026-82329) exploded in 72 hours. Fastly threat intelligence breaks down the mass scanning surge—and how our virtual patch protects you today. 
|
||||
- [Building Fastly Log Analytics Tools: An Open-Source Approach to Deeper Insights](https://www.fastly.com/blog/building-fastly-log-analytics-tools-open-source-approach-deeper-insights)Gain deeper insights with Fastly Log Analytics. Build an open-source, self-hosted dashboard to own your data, reduce vendor costs, and troubleshoot instantly. 
|
||||
- [Building for the Model Hardware Standard](https://www.fastly.com/blog/building-for-the-model-hardware-standard)Anthropic’s Model Hardware Standard (MHS) lets AI agents operate physical equipment. Here’s how we’re prototyping secure edge MCP support for it. 
|
||||
- [Preserving Analytics Attribution During Bot Challenges: A Fastly VCL & NGWAF Deep Dive](https://www.fastly.com/blog/preserving-analytics-attribution-bot-challenges-fastly-vcl-ngwaf-deep-dive)Learn how to preserve Google Analytics attribution during bot challenges. Discover how to use Fastly's NGWAF and VCL to maintain data accuracy while securing your site. 
|
||||
- [Instantly AI-Agent-Ready with WebMCP on Demand](https://www.fastly.com/blog/instantly-ai-agent-ready-webmcp-on-demand)Ensure your website is AI-agent-ready with WebMCP on Demand. See how Fastly uses edge computing to intelligently annotate web forms for reliable agent interaction. 
|
||||
- [Why SaaS and PaaS Infrastructure Leaders Are Facing 22% More Unwanted Bots](https://www.fastly.com/blog/saas-and-paas-infrastructure-leaders-are-facing-more-unwanted-bots)Bot traffic is hammering SaaS & PaaS platforms. Watch Fastly’s on-demand webcast to learn how to adaptively mitigate bot risks, protect your origin, and maintain platform uptime. 
|
||||
- [Inside Fastly’s 2026 Internship Program: Projects, Impact & Culture](https://www.fastly.com/blog/inside-fastlys-2026-internship-program-projects-impact-and-culture)Go behind the scenes of Fastly’s 2026 Internship Program. See how our intern cohort tackled real-world engineering projects and made a lasting impact. 
|
||||
- [Level Up Your Security with Fastly API Enforcement](https://www.fastly.com/blog/level-up-security-fastly-api-enforcement)Take control of your API landscape with Fastly API Security. Discover, monitor, and enforce schema compliance at the edge to stop threats and secure your apps. 
|
||||
- [MCP at the Edge: What Changes When MCP Runs Securely in Every POP](https://www.fastly.com/blog/mcp-at-the-edge)Stop wasting 500ms per AI tool call. See how Fastly Compute scales stateless MCP servers worldwide for instant, secure, sub-millisecond agent execution. 
|
||||
- [The Invisible Stadium](https://www.fastly.com/blog/the-invisible-stadium)See how AI, edge routing, and expert teams manage massive traffic spikes during the World Cup, ensuring a seamless, high-performance viewing experience.
|
||||
- [Terraform Your Fastly Config in a few Commands](https://www.fastly.com/blog/terraform-your-fastly-config-in-a-few-commands)Import your complete Fastly setup into Terraform in minutes. No rewrites, no downtime, just your existing infrastructure, now as code. 
|
||||
- [Online Sports’ Shadow Audience](https://www.fastly.com/blog/online-sports-shadow-audience)Piracy, bots, and AI-driven attacks shadowed the 2026 World Cup. Here's what the traffic data reveals — and what it means for infrastructure. 
|
||||
- [Beyond the Bot Block: How Fastly and Experian Are Turning AI Agent Traffic into Revenue](https://www.fastly.com/blog/beyond-bot-block-fastly-experian-turning-ai-agent-traffic-into-revenue)Discover how Fastly and Experian Agent Trust enable secure agentic commerce. Learn how to verify, authorize, and monetize AI agent traffic at the edge. 
|
||||
- [AI Content Provenance is Gaining Momentum: Get C2PA Support Now with Image Optimizer](https://www.fastly.com/blog/ai-content-provenance-c2pa-support-with-image-optimizer)Ensure compliance with new AI transparency laws. Fastly Image Optimizer now supports C2PA, preserving critical provenance metadata through your delivery pipeline.
|
||||
- [What is CVE-2026-66066? Protecting Your Rails App from Active Storage RCE](https://www.fastly.com/blog/what-is-cve-2026-66066-protecting-rails-app-active-storage-rce)Learn about CVE-2026-66066: An arbitrary file read vulnerability in Rails Active Storage. Understand the risks and protect your environment with our virtual patch.
|
||||
- [What Modern Fintechs Actually Need from Their Security Stack](https://www.fastly.com/blog/what-modern-fintechs-actually-need-from-their-security-stack)Ditch fragmented tools and manual tuning. See how high-performing fintechs use edge security to protect payments, APIs, and user trust.
|
||||
- [Teaching Coding Agents to Check Their VCL with Fastly Fiddle](https://www.fastly.com/blog/teaching-coding-agents-to-check-their-vcl-with-fastly-fiddle)Learn how to use Fastly Fiddle to test and verify VCL on real infrastructure. This sandbox tool helps both developers and coding agents debug edge configurations.
|
||||
- [Automated Payments at the Edge with x402 and Fastly Compute](https://www.fastly.com/blog/automated-payments-at-the-edge-with-x402-and-fastly-compute)Protect APIs and agentic traffic at the edge. Explore a practical guide to enforcing x402 HTTP payment challenges using Fastly Compute and testnet stablecoins.
|
||||
@@ -0,0 +1,210 @@
|
||||
# The Impending Doom of Expiring Root CAs and Legacy Clients
|
||||
|
||||
- **期号**: SRE Weekly Issue #223(2020-06-14)
|
||||
- **作者**: Scott Helme
|
||||
- **链接**: https://scotthelme.co.uk/impending-doom-root-ca-expiring-legacy-clients/
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s a deep dive into how your CA’s certificate can affect your application’s reliability — at least in the eyes of your customers.
|
||||
|
||||
## 正文
|
||||
|
||||
Regular readers will know that I'm very active in the CA / PKI space and even deliver a [2-day advanced training course](https://www.feistyduck.com/training/the-best-ssl-and-tls-training-in-the-world?utm_source=scotthelme.co.uk) on the topic. Over the last year or so I've been watching as a potentially big problem has been rolling in over the horizon and just the other day I saw the first signs of the storm hitting the shore.
|
||||
|
||||
#### Terminology
|
||||
|
||||
Just before we dig in I want to clear up some terminology so we're all on the same page. A CA is a Certificate Authority, the organisations that issue certificates so you can have HTTPS on your website. I speak a lot about [Let's Encrypt](https://letsencrypt.org/?utm_source=scotthelme.co.uk) who are one of the biggest CAs out there but you may also recognise names like Comodo, Sectigo, DigiCert et al. The PKI, or Public Key Infrastructure, is used to authenticate users and devices online. Today I'm going to be talking about a subset of that which we call the Internet PKI, which refers to the collection of public CAs used to issue certificates to websites so we can authenticate them in the browser.
|
||||
|
||||
#### How CAs Work
|
||||
|
||||
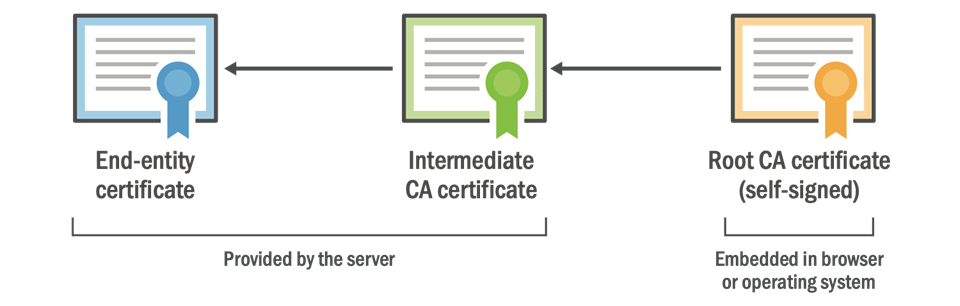
So that the browser can authenticate a website, it must be presented with a valid certificate chain by the server it's connecting to. A typical chain would look something like this, but note that there can be more than 1 intermediate certificate in a chain. The minimum number of certificates you can expect to see in a valid chain is 3.
|
||||
|
||||
|
||||
|
||||
The Root CA Certificate is the heart of a CA and is quite literally embedded in your OS or your browser of choice, it's physically present on your device. The Root CA issues the Intermediate CA, which in-turn issues the End-Entity Certificate (also known as the leaf certificate or server certificate) to your website. The Leaf and Intermediate certificates are delivered to the client from the server, and the client already has the Root certificate, so with this collection of certificates the chain can be built and the identity of the website authenticated. That is an *incredibly* brief overview of how this works and for more details you should seriously check out our [Training Course](https://www.feistyduck.com/training/the-best-ssl-and-tls-training-in-the-world?utm_source=scotthelme.co.uk) on the subject, but for now that should be enough to get us going.
|
||||
|
||||
#### So what's the problem?
|
||||
|
||||
The problem is something that we all deal with on a regular basis without too much issue: Certificates have an expiry date and need replacing. I recently wrote about the new lifetime limit of 1 year that will be imposed in [September 2020](https://scotthelme.co.uk/certificate-lifetime-capped-to-1-year-from-sep-2020/?utm_source=scotthelme.co.uk) which means we will all have to replace our Server Certificates every 12 months at least. That limit only applies to Server Certificates though, the certificates that we obtain to install on our website, it does not apply to CA Certificates.
|
||||
|
||||
CA Certificates are governed by a different set of rules to our certificates and as such they have different lifetime restrictions. It's very common to see Intermediate Certificates with a lifetime of 5 years and Root Certificates with a lifetime of 25 years! This means that Intermediate Certificates expire on a somewhat regular schedule but this generally isn't a problem. Because the intermediate is delivered by the website it's fairly dynamic and as the website is renewing their certificate on a regular schedule, changing out the intermediate isn't really much of an extra burden. It can be changed quite easily alongside the Server Certificate, unlike the Root CA Certificate.
|
||||
|
||||
As I said a moment ago, the Root CA is embedded into the client device itself, usually in the OS but also possibly in the browser or other software. Changing the Root CA isn't something the website can control, it's something that requires an update to be installed on the client, either an OS update or software update. I wonder what our track record of keeping OS/software updated is in the wider world?...
|
||||
|
||||
#### Legacy CAs
|
||||
|
||||
Some CAs have now been around for a very long time, we're talking 20-25 years! That also just so happens to mean that some of the original Root CAs out there are also coming towards the end of their natural life, their time is almost up. For most of us this won't be a problem at all because CAs have created new root certificates and those have been distributed across the World in OS and browser updates for years. For some of us though, those who haven't installed OS or browser updates for years, well there's kind of a problem...
|
||||
|
||||
This problem was perfectly demonstrated recently, at May 30 10:48:38 2020 GMT to be exact. That exact time was then the [AddTrust External CA Root](https://crt.sh/?id=1&ref=scotthelme.co.uk) expired and brought with it the first signs of trouble that I've been expecting for some time.
|
||||
|
||||
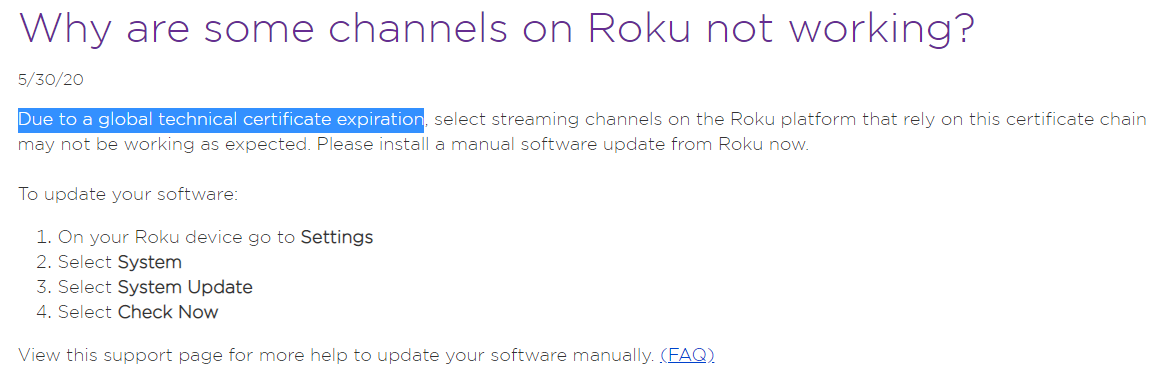
Roku, who are a pretty popular streaming device, had an [incident](https://support.roku.com/en-gb/article/360049417393?utm_source=scotthelme.co.uk).
|
||||
|
||||
|
||||
|
||||
Stripe, the payment processor, also had [issues](https://twitter.com/stripestatus/status/1266764992520441856?utm_source=scotthelme.co.uk).
|
||||
|
||||
As of 10:48 UTC, webhook delivery is failing for some users. We’re investigating and will post updates here.
|
||||
|
||||
— Stripe Status (@stripestatus)[May 30, 2020](https://twitter.com/stripestatus/status/1266764992520441856?ref_src=twsrc%5Etfw&ref=scotthelme.co.uk)
|
||||
|
||||
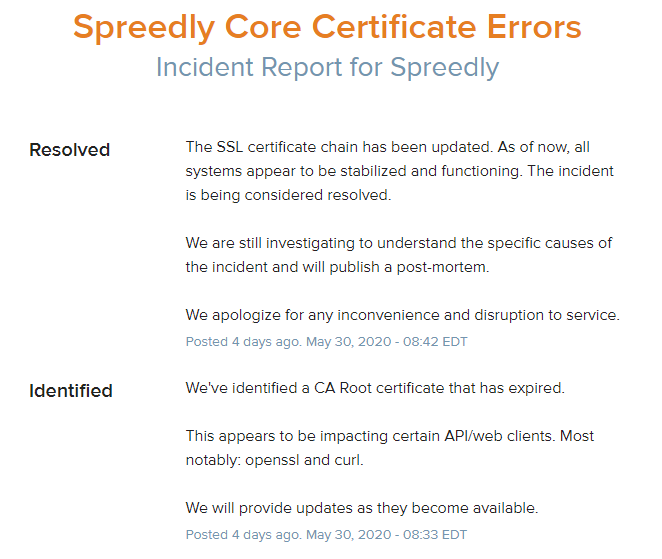
Spreedly, another big payment processor, also had an [incident](https://status.spreedly.com/incidents/h39zkpygxcpk?utm_source=scotthelme.co.uk).
|
||||
|
||||
|
||||
|
||||
There is a whole load of stuff that broke because of this Root CA expiring and Andy Ayer has a good list tracking quite a few more [here](https://twitter.com/__agwa/timelines/1266777818811322368?utm_source=scotthelme.co.uk). The point is, the affected clients only have the old (now expired) AddTrust Root CA Certificate installed and because they've not been updated they haven't received the new version that replaces it. Without that new version, things simply don't work and Server Certificates that should be valid, that are valid, will rightly be seen as invalid and rejected by the client.
|
||||
|
||||
#### A Long Time Coming
|
||||
|
||||
This particular issue does not come as a surprise to many that operate in this specific area, I've been talking about this impending problem for probably 2 years in our [TLS training course](https://www.feistyduck.com/training/the-best-ssl-and-tls-training-in-the-world?utm_source=scotthelme.co.uk), but for many, this will come as a surprise, proven by all of the incidents I linked to above.
|
||||
|
||||
|
||||
|
||||
Another good example is the upcoming Root CA transition that's Let's Encrypt will be performing. I wrote about this back in [April 2019](https://scotthelme.co.uk/lets-encrypt-to-transition-to-isrg-root/?utm_source=scotthelme.co.uk) when Let's Encrypt were planning to transition from their Identrust cross-signed chain to their own ISRG Root chain in July 2019, but it didn't happen...
|
||||
|
||||
***Update, May 20 2019***
|
||||
|
||||
*Due to concerns about insufficient ISRG root propagation on Android devices we have decided to move the date on which we will start serving a chain to our own root from July 8, 2019, to July 8, 2020.*
|
||||
|
||||
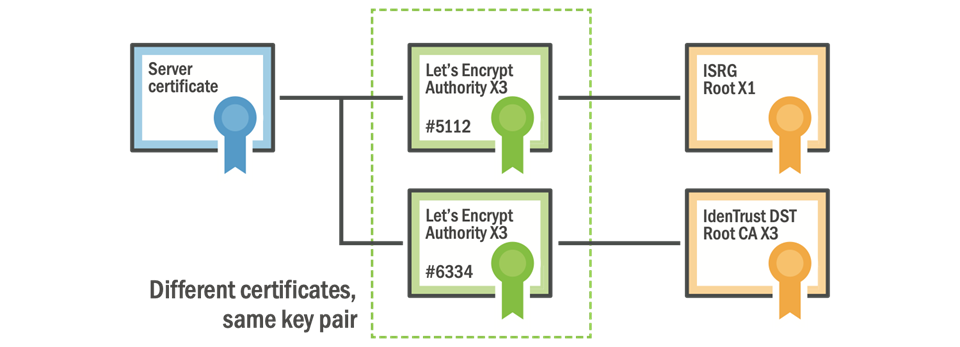
Let's Encrypt had to push back the transition because of an issue we call root propagation, or more specifically, a lack of root propagation, where a Root CA is not widely distributed onto all clients out there. Let's Encrypt are currently using a cross-signed intermediate and chain down to the IdenTrust DST Root CA X3 certificate. That root certificate expires on 30th Sep 2021 and was issued way back in Sep 2000, so it's widely distributed, or propagated, as most devices have done an update in the last 20 years and as a result they have the IdenTrust Root Certificate installed. That said, Let's Encrypt need to move away from it before it expires and the plan was to migrate to their Root CA, the ISRG Root X1.
|
||||
|
||||
|
||||
|
||||
The ISRG Root was issued on 4th Jun 2015 and began the approval process to become a CA, a process it completed [6th Aug 2018](https://letsencrypt.org/2018/08/06/trusted-by-all-major-root-programs.html?utm_source=scotthelme.co.uk). At that point the Root CA will be available to all clients via an OS or software update, all they need to do is install the update. "All they need to do"...
|
||||
|
||||
Here is the core of the problem. The new Let's Encrypt Root CA was created in 2015 and fully approved for distribution in 2018. Now, ~2 years later, if a device has not been updated since Aug 2018, how does it know about this new Root CA? The answer: it doesn't. This is why Let's Encrypt delayed their switch to their own ISRG Root CA and are still serving the intermediate that chains down to the IdenTrust root, but that solution will only last until the expiry of the IdenTrust Root. They bought themselves some time, but not much. To test if your current client has the ISRG Root X1 installed, try and load this test site: [https://valid-isrgrootx1.letsencrypt.org/](https://valid-isrgrootx1.letsencrypt.org/?utm_source=scotthelme.co.uk)
|
||||
|
||||
If you can connect without warnings then it probably means you're OK, but just because it does connect it doesn't mean you're definitely OK. I'm not going to go into the complexities of chain building and the client doing what it wants, or the possibility you're behind a device terminating TLS on a corporate network, because there are a heap of other things to consider here that require hundreds more words. All I can say is that you're probably OK and if you want to spend hours talking about this, well, I have a training course for that!
|
||||
|
||||
#### This is not Let's Encrypt specific
|
||||
|
||||
Not by a long shot, and that's the problem. We're coming to a point in time now where there are lots of CA Root Certificates expiring in the next few years simply because it's been 20+ years since the encrypted Web really started up and that's the lifetime of a Root CA certificate. This will catch some organisations off guard in a big way, as we've already seen, but there are also some organisations that have seen the problem on the horizon and are taking whatever steps they can to resolve it.
|
||||
|
||||
With the TLS Training I deliver and various bits of consultancy work I do, I've worked with some organisations that have already actually hit this problem and worked through a solution where they can. There's only one organisation I'm fortunate enough to have been given permission to talk about and that's the BBC, our national broadcaster here in the UK. They had a really interesting problem because they do a lot of online streaming to a lot of different devices. Now, mobile apps and browsers aren't *generally* too much of a problem, but Smart TVs, well, they're a whole different game.
|
||||
|
||||
|
||||
|
||||
I'm sure many of you here know that Smart TVs aren't often as 'smart' as we'd like. Generally speaking the only time my TV gets an update now it's to *remove* a feature, not add one... But this lack of updates does present another rather interesting problem. A Smart TV is basically a cut-down Linux computer, a computer that does TLS comms, that has a Root CA store and that has the exact same problems I've just talked through. The clock is ticking on the Root Certificates installed on the TV and with no updates, they never get replaced...
|
||||
|
||||
|
||||
|
||||
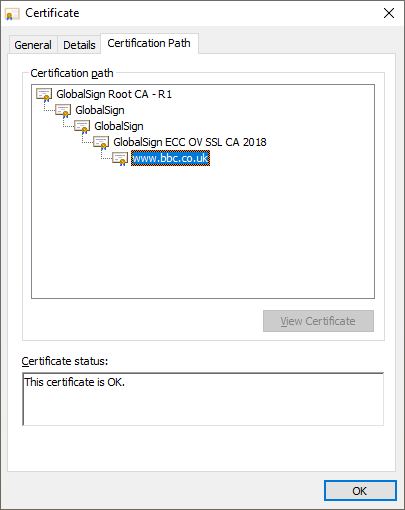
A very awesome friend of mine, [Neil Craig](https://twitter.com/tdp_org?utm_source=scotthelme.co.uk), is Lead Technical Architect at the BBC and he got me some specific details of an incident over there and allowed me to share it with you. On a recent server certificate update they got a new certificate issued by the GlobalSign [R5 Root](https://valid.r5.roots.globalsign.com/?utm_source=scotthelme.co.uk), the root is valid from 13th Nov 2012 to 19th Jan 2038. The problem was, some TVs are so out of date that they don't have that R5 Root CA installed on them that was issued in 2012! This means that those TVs will reject certificates that chain to that Root CA and as a result, the streaming app stops working on the TV! Here we are in 2019/2020 with a problem that an 8 year old Root CA still hasn't managed to make its way onto a significant portion of 'Smart' TVs. The BBC were smart though and there was a workaround they could deploy which meant serving additional intermediate certificates that chain down to a different GlobalSign Root CA. The GlobalSign [R3 Root](https://valid.r3.roots.globalsign.com/?utm_source=scotthelme.co.uk) is valid 18th Mar 2009 to 18th Mar 2029 and the [R1 Root](https://valid.r1.roots.globalsign.com/?utm_source=scotthelme.co.uk) is valid 1st Sep 1998 to 28th Jan 2028. With the R1 Root going back so far, and there being an alternate trust path available to build to it, the BBC was able to fix the problem and those outdated TVs were fixed because they had the old R1 Root installed. Here's a trimmed output from `openssl s_client -connect www.bbc.co.uk:443 -showcerts` and what that looks like in Chrome on Windows at present. They use the same workaround on their `www` so it's easier for us to inspect the chain there than it is on the iPlayer API endpoints.
|
||||
|
||||
```
|
||||
Certificate chain
|
||||
0 s:C = GB, ST = London, L = London, O = British Broadcasting Corporation, CN = www.bbc.co.uk
|
||||
i:C = BE, O = GlobalSign nv-sa, CN = GlobalSign ECC OV SSL CA 2018
|
||||
1 s:C = BE, O = GlobalSign nv-sa, CN = GlobalSign ECC OV SSL CA 2018
|
||||
i:OU = GlobalSign ECC Root CA - R5, O = GlobalSign, CN = GlobalSign
|
||||
2 s:OU = GlobalSign ECC Root CA - R5, O = GlobalSign, CN = GlobalSign
|
||||
i:OU = GlobalSign Root CA - R3, O = GlobalSign, CN = GlobalSign
|
||||
3 s:OU = GlobalSign Root CA - R3, O = GlobalSign, CN = GlobalSign
|
||||
i:C = BE, O = GlobalSign nv-sa, OU = Root CA, CN = GlobalSign Root CA
|
||||
```
|
||||
|
||||
|
||||
What we can see here is the `www.bbc.co.uk` certificate issued by the `GlobalSign ECC OV SSL CA 2018` intermediate. That Intermediate has an Authority Key ID of `3de629489bea07ca21444a26de6eded283d09f59` which means it can chain to any one of following three certificates:
|
||||
|
||||
[GlobalSign ECC Root CA - R5](https://censys.io/certificates/179fbc148a3dd00fd24ea13458cc43bfa7f59c8182d783a513f6ebec100c8924?utm_source=scotthelme.co.uk) (Root) Validity 13 Nov 2012 to 19 Jan 2038
|
||||
|
||||
[GlobalSign ECC Root CA - R5](https://censys.io/certificates/f349954e8fb6d44011bcb789d97d9a2cb2032bd5f0b598d1fb8a099f5848d523?utm_source=scotthelme.co.uk) (Intermediate) Validity 19 Jun 2019 to 28 Jan 2028
|
||||
|
||||
[GlobalSign ECC Root CA - R5](https://censys.io/certificates/3f319b2afed4a0f75127be59925550d0428e68763a09e273eb6a9ff8d18dbb5b?utm_source=scotthelme.co.uk) (Intermediate) Validity 21 Nov 2018 to 18 Mar 2029
|
||||
|
||||
The problem here is the first one in the list, the R5 Root. This is the newer one issued in 2012 that the older Smart TVs did not have installed, so the BBC couldn't just return the `www.bbc.co.uk` and `GlobalSign ECC OV SSL CA 2018` certificates, they had to provide more intermediates so the client can build an alternate chain. By providing the 3rd certificate in the above list, the R5 Intermediate, the client can build a chain 'around' the R5 Root that is missing, so the chain continues. That R5 Intermediate certificate has an Authority Key ID of `8ff04b7fa82e4524ae4d50fa639a8bdee2dd1bbc` meaning it could chain to one of the following three certificates:
|
||||
|
||||
[GlobalSign Root CA - R3](https://censys.io/certificates/cbb522d7b7f127ad6a0113865bdf1cd4102e7d0759af635a7cf4720dc963c53b?utm_source=scotthelme.co.uk) (Root) Validity 18 Mar 2009 to 18 Mar 2029
|
||||
|
||||
[GlobalSign Root CA - R3](https://censys.io/certificates/c94fedda4e8608908580bc7f87b434e03bb262e42f64c63820a8f50fb17c1cec?utm_source=scotthelme.co.uk) (Intermediate) Validity 18 Mar 2009 to 28 Jan 2028
|
||||
|
||||
[GlobalSign Root CA - R3](https://censys.io/certificates/445eec78bc61215044a0379656aa2d5db5e42f76cb70b8d14c2077aa943d4ebb?utm_source=scotthelme.co.uk) (Intermediate) Validity 19 Sep 2018 to 28 Jan 2028
|
||||
|
||||
At this point the BBC could end the chain and serve the `www.bbc.co.uk` , `GlobalSign ECC OV SSL CA 2018` and `GlobalSign Root CA - R5` (Intermediate) to the client for it to anchor on the [`GlobalSign Root CA - R3`](https://censys.io/certificates/cbb522d7b7f127ad6a0113865bdf1cd4102e7d0759af635a7cf4720dc963c53b?utm_source=scotthelme.co.uk) (Root) but again, with an issue date of 2009 and a few years for approval and distribution, that might still not solve the problem as the R3 Root might not be present. So, in goes another intermediate to work around that! Again they served the 3rd certificate in the list above, the `GlobalSign Root CA - R3` (Intermediate), which has an Authority Key ID of `607b661a450d97ca89502f7d04cd34a8fffcfd4b`. That means it could chain to one of the following two certificates:
|
||||
|
||||
[GlobalSign Root CA](https://censys.io/certificates/ebd41040e4bb3ec742c9e381d31ef2a41a48b6685c96e7cef3c1df6cd4331c99?utm_source=scotthelme.co.uk) (Root) Validity 01 Sep 1998 to 28 Jan 2028
|
||||
|
||||
[GlobalSign Root CA](https://censys.io/certificates/a8cc00deef9e19f74cceae192b86fe2e3d1a01391bbb01dd62a0438dd07501a7?utm_source=scotthelme.co.uk) (Intermediate) Validity 20 Feb 2014 to 15 Dec 2021
|
||||
|
||||
Now we're *finally* getting somewhere. That first certificate has a Friendly Name of `GlobalSign Root CA - R1` and is a Root CA that is old enough to be installed on ancient devices that haven't been updated in years and the 'Smart' TVs can successfully build a chain to anchor on. This means instead of serving a 'normal' chain of:
|
||||
|
||||
```
|
||||
www.bbc.co.uk (Leaf)
|
||||
GlobalSign ECC OV SSL CA 2018 (Intermediate)
|
||||
```
|
||||
The BBC instead have to serve a chain of:
|
||||
|
||||
```
|
||||
www.bbc.co.uk (Leaf)
|
||||
GlobalSign ECC OV SSL CA 2018 (Intermediate)
|
||||
GlobalSign Root CA - R5 (Intermediate)
|
||||
GlobalSign Root CA - R3 (Intermediate)
|
||||
```
|
||||
Note: when I started this blog I had no idea how deep down the rabbit hole we were going to end up, but here we are. Anyway, onward!
|
||||
|
||||
At best, all the BBC have done here is delay the problem until 2028 when the R1 Root expires. At that point, they could shorten the chain and try to anchor on the R3 Root instead, which expires in 2029, and hope that Smart TVs have updated enough to have that Root CA installed by the time we get there...
|
||||
|
||||
The BBC could also look at switching to another CA with a Root CA that has a slightly longer expiry, maybe 2030 or 2031, but it's the same problem over and over again. The solution here, the real solution, is that the client needs to be updated. Smart TV manufacturers might release updates for a couple of years, but we're talking a decade or more if you want to resolve this particular problem. I've quite comfortably had a TV for 10 years and I'm sure as hell not contributing a heap of e-waste just to update the Root CAs installed on my television!!
|
||||
|
||||
#### This affects all devices
|
||||
|
||||
If you have a device that's connected to the Internet or has the word 'Smart' somewhere in the marketing material then this Root CA expiry problem is probably a consideration, there's no way to avoid it. If the device is not updated then the Root CA store will become stale over time and eventually, the problem will surface. How soon it will be a problem, and how big of a problem it will be, will depend on when the Root CA store was last updated, but just because a device was built in 2018, it doesn't mean the software wasn't already 6+ years out of date either.
|
||||
|
||||
With all the problems that the BBC have had they now require these things to be taken into consideration if Smart TV manufacturers want to get the BBC seal of approval for the iPlayer on the box. Microsoft have also taken steps to remedy this problem in Windows and your OS can now get Root CA Store updates when it needs them. Going forwards, it does look like this problem is starting to be solved for the future, but it isn't being solved for the past and the present.
|
||||
|
||||
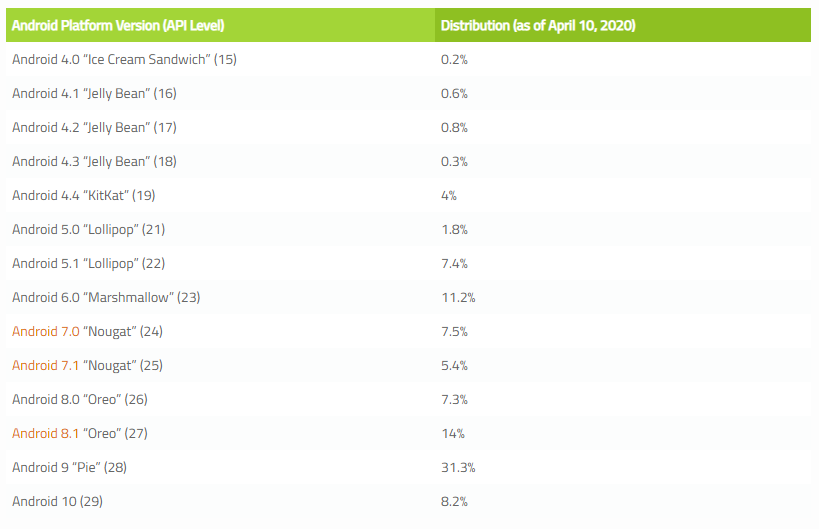
Going back earlier in the thread I mentioned that the Let's Encrypt root transition was delayed, their reason was a lack of root propagation and they specifically called out Android devices. I did some digging and found [data](https://www.xda-developers.com/android-version-distribution-statistics-android-studio/?utm_source=scotthelme.co.uk) on what the Android ecosystem looks like in terms of installed OS versions.
|
||||
|
||||
|
||||
|
||||
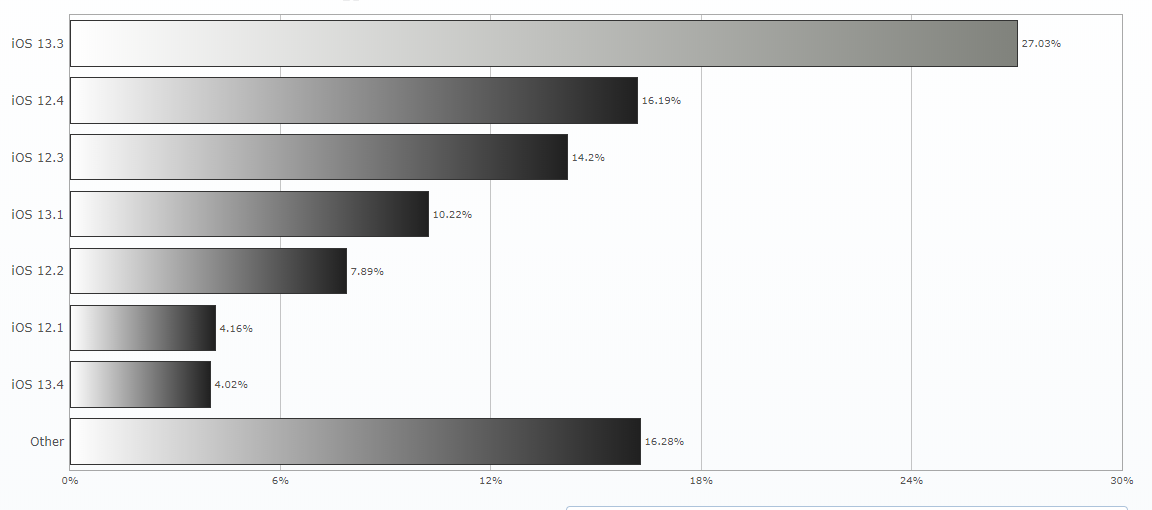
This shows there is a *significant* portion of devices that are either lagging seriously behind on updates or simply aren't being updated either by the vendor or by the user (hint: it's the vendor). If we take a look at similar [data](https://gs.statcounter.com/ios-version-market-share/mobile-tablet/worldwide/?utm_source=scotthelme.co.uk#monthly-201905-202005-bar) for iOS, it's a very different story.
|
||||
|
||||
|
||||
|
||||
I wouldn't be too concerned about this problem if I was an iOS user (I am) but it looks like Android users might have some concerns in the not too distant future!
|
||||
|
||||
#### No modern CAs for you
|
||||
|
||||
Changing the intermediates you serve to chain back to an old Root CA to keep devices alive is one thing, and even switching CA to choose a CA with the longest lived 'legacy' root is another, but this also means you can't use a modern CA if you want to. Let me quote something that Neil said to me:
|
||||
|
||||
we literally can't use a CA like LE [Let's Encrypt] with TVs because it's in very few root stores
|
||||
|
||||
An enormous media and streaming platform can't use a wicked-awesome, fully automated and free CA because the devices that connect to their service aren't modern enough. Yep, that's right, your cutting edge 50" 4K Smart TV isn't modern enough. Sounds crazy, right? But that's the problem!
|
||||
|
||||
If you operate a service, or want to build one, that will have legacy client considerations, you can't just go out and hit up the coolest, newest and free CA, you need to be careful about your choice. You need to know which platform your clients are on, which version of their trust store they're using and when they were last updated, all in the hope you can figure out which root certificates are in there and which CA to use to issue your certificates. It sounds easy, but it can be a real pain to figure out. Some vendors like Apple provide data on the contents of their current Root Store, like [iOS 13 here](https://support.apple.com/en-us/HT210770?utm_source=scotthelme.co.uk), and you can go back some time but it's not straightforward or easy. Cloudflare have [cfssl_trust](https://github.com/cloudflare/cfssl_trust?utm_source=scotthelme.co.uk) which can get you back to ~2017 and covers various platforms but that could easily not be far enough back for your needs either. In truth, is this is a concern for you then you have a little bit of work to do to figure this out, there's no easy way. Given the prominence of legacy 'stuff' on the Internet, I think we'd better get to fixing this sooner rather than later.
|
||||
|
||||
#### Detecting the issue
|
||||
|
||||
Knowing if you have an issue like this could be quite useful indeed and there was a surprising story about how to detect the problem. Of course you can have an advanced and intimate knowledge of all of your clients and their Root Stores, which is difficult, or you can use NEL. I wrote an introductory blog post about [Network Error Logging](https://scotthelme.co.uk/introducing-the-reporting-api-nel-other-major-changes-to-report-uri/?utm_source=scotthelme.co.uk) and followed that up with a [Network Error Logging: Deep Dive](https://scotthelme.co.uk/network-error-logging-deep-dive/?utm_source=scotthelme.co.uk) too. The TLDR; for this blog though is that you can have a client send you feedback when they have connectivity issues to your site, including issues caused by certificates. Here's is a very small subset of the errors a client can report.
|
||||
|
||||
```
|
||||
tls.version_or_cipher_mismatch
|
||||
The TLS connection was aborted due to version or cipher mismatch
|
||||
tls.bad_client_auth_cert
|
||||
The TLS connection was aborted due to invalid client certificate
|
||||
tls.cert.name_invalid
|
||||
The TLS connection was aborted due to invalid name
|
||||
tls.cert.date_invalid
|
||||
The TLS connection was aborted due to invalid certificate date
|
||||
tls.cert.authority_invalid
|
||||
The TLS connection was aborted due to invalid issuing authority
|
||||
tls.cert.invalid
|
||||
The TLS connection was aborted due to invalid certificate
|
||||
tls.cert.revoked
|
||||
The TLS connection was aborted due to revoked server certificate
|
||||
tls.cert.pinned_key_not_in_cert_chain
|
||||
The TLS connection was aborted due to a key pinning error
|
||||
tls.protocol.error
|
||||
The TLS connection was aborted due to a TLS protocol error
|
||||
tls.failed
|
||||
The TLS connection failed due to reasons not covered by previous errors
|
||||
```
|
||||
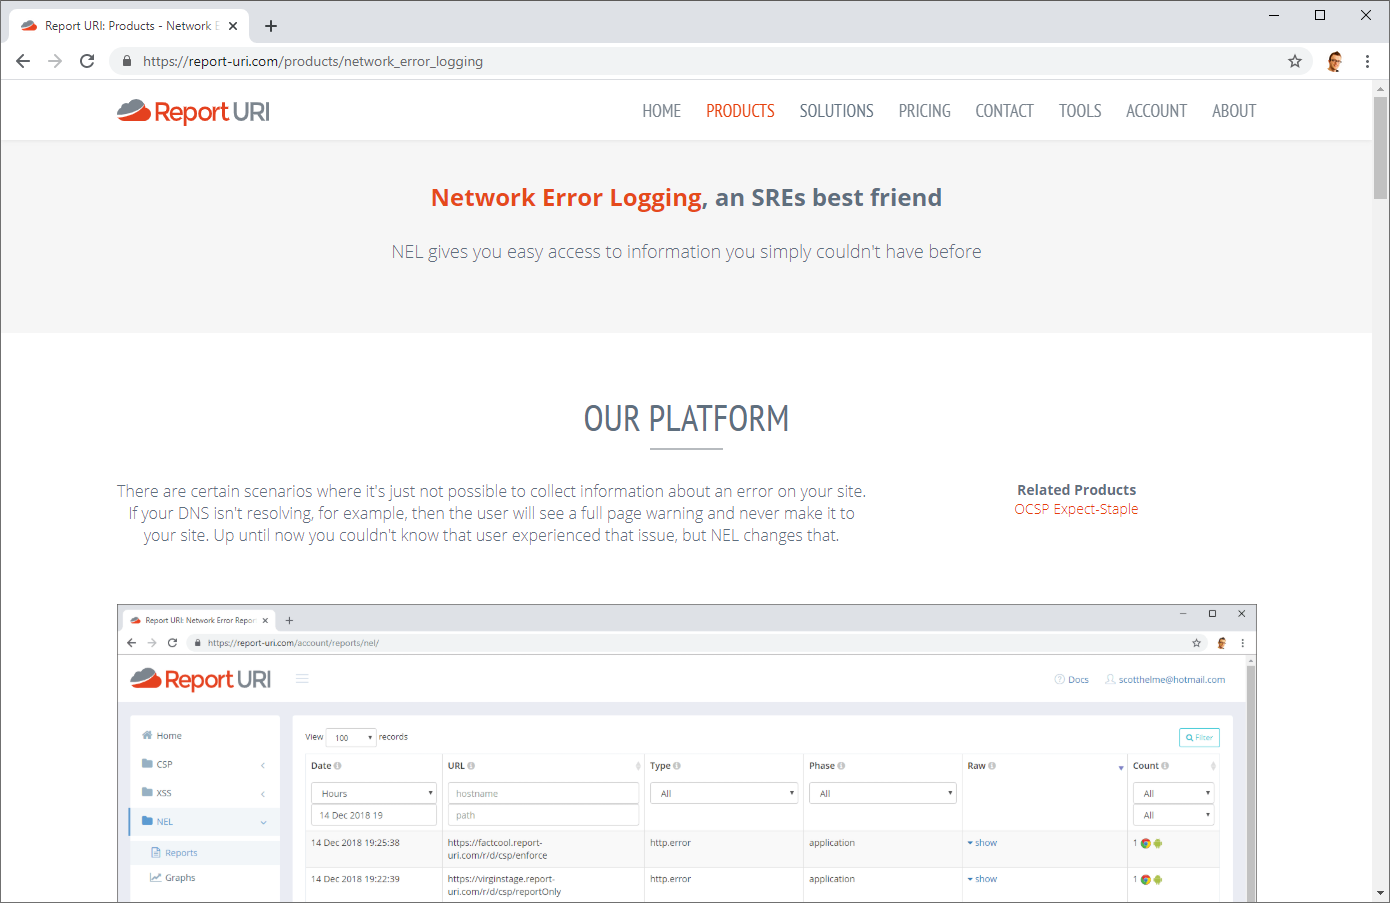
The error of interest there of course is the `tls.cert.authority_invalid` error and when the client starts to report those, you can quickly take steps to investigate. It may seem surprising that we're talking about NEL, which is a very modern feature, and talking about legacy clients that don't have updates installed at the same time. The scenario here though turned out to be old Android devices running modern version of Chrome browser which got us to the scenario of an outdated OS and Root Store but a modern client that supported NEL reports! If you don't currently use NEL you should check out my blogs linked above and our support for NEL Reports over at [Report URI](https://report-uri.com/products/network_error_logging?utm_source=scotthelme.co.uk).
|
||||
|
||||
|
||||
|
||||
#### The Solution
|
||||
|
||||
Updates. One way or another there needs to be an update somewhere. If you're building devices or software that depend on the Internet PKI for secure comms then you're going to have to consider the impact that not updating a Root Store will have on your product or service. If you run a service with legacy clients you need to consider how your choice of CA can affect them.
|
||||
|
||||
The cynic in me tells me that TV manufacturers might not care that streaming services stop working because the solution is to buy a new TV, but planned obsolescence isn't a new idea and there's probably no hidden agenda here according to [Hanlon's Razor](https://en.wikipedia.org/wiki/Hanlon%27s_razor?utm_source=scotthelme.co.uk) (or [Occam's Razor](https://en.wikipedia.org/wiki/Occam%27s_razor?utm_source=scotthelme.co.uk) if you prefer a more gentle message).
|
||||
|
||||
If you're bundling a library or building on an OS, you need to consider how you're going to update the Root Store in the years to come. You don't need to release a software update with new features, simply replacing the Root Store with the latest version might give a device years more useful life or prevent your service being negatively impacted when the next Root CA expiry comes around. The recent AddTrust Root CA expiry showed us that some big organisations did not see this coming and weren't prepared, but this is the first such incident of its kind, certainly not the last.
|
||||
@@ -0,0 +1,13 @@
|
||||
# [Coinbase] Incident Post Mortem: June 1, 2020
|
||||
|
||||
- **期号**: SRE Weekly Issue #223(2020-06-14)
|
||||
- **作者**: Michael de Hoog — Coinbase
|
||||
- **链接**: https://blog.coinbase.com/incident-post-mortem-june-1-2020-1cff2e51fa64
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s Coinbase’s followup from their outage last week.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
94
sreweekly/markdown/223/04-who-s-afraid-of-serializability.md
Normal file
94
sreweekly/markdown/223/04-who-s-afraid-of-serializability.md
Normal file
@@ -0,0 +1,94 @@
|
||||
# Who’s afraid of serializability?
|
||||
|
||||
- **期号**: SRE Weekly Issue #223(2020-06-14)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2020/06/13/whos-afraid-of-serializability/
|
||||
|
||||
## 简介
|
||||
|
||||
> Kyle Kingsbury recently did an analysis of PostgreSQL 12.3 and found that under certain conditions it violated guarantees it makes about transactions, including violations of the serializability transaction isolation level.I thought it would be fun to use one of his counterexamples to illustrate what serializable means.
|
||||
|
||||
## 正文
|
||||
|
||||
Kyle Kingsbury’s *Jepsen* recently did [an analysis of PostgreSQL
|
||||
12.3](http://jepsen.io/analyses/postgresql-12.3) and found that under certain
|
||||
conditions it violated guarantees it makes about transactions, including
|
||||
violations of the [serializability](https://jepsen.io/consistency/models/serializable) transaction
|
||||
isolation level.
|
||||
|
||||
I thought it would be fun to use one of his counterexamples to illustrate what serializable means.
|
||||
|
||||
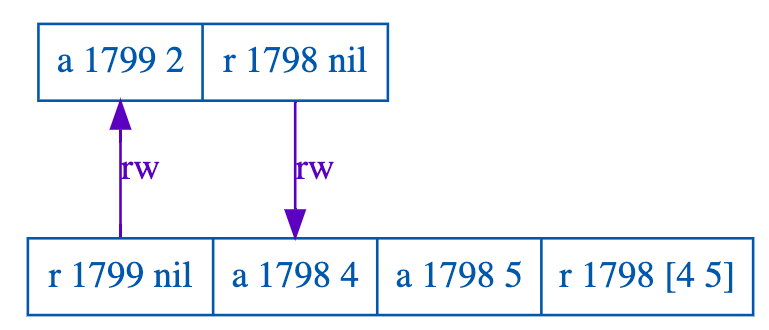
Here’s one of the counterexamples that Jepsen’s tool, [Elle](https://github.com/jepsen-io/elle), found:
|
||||
|
||||
|
||||
|
||||
In this counterexample, there are two list objects, here named 1799 and 1798, which I’m going to call *x* and *y*. The examples use two list operations, append (denoted "a") and read (denoted "r").
|
||||
|
||||
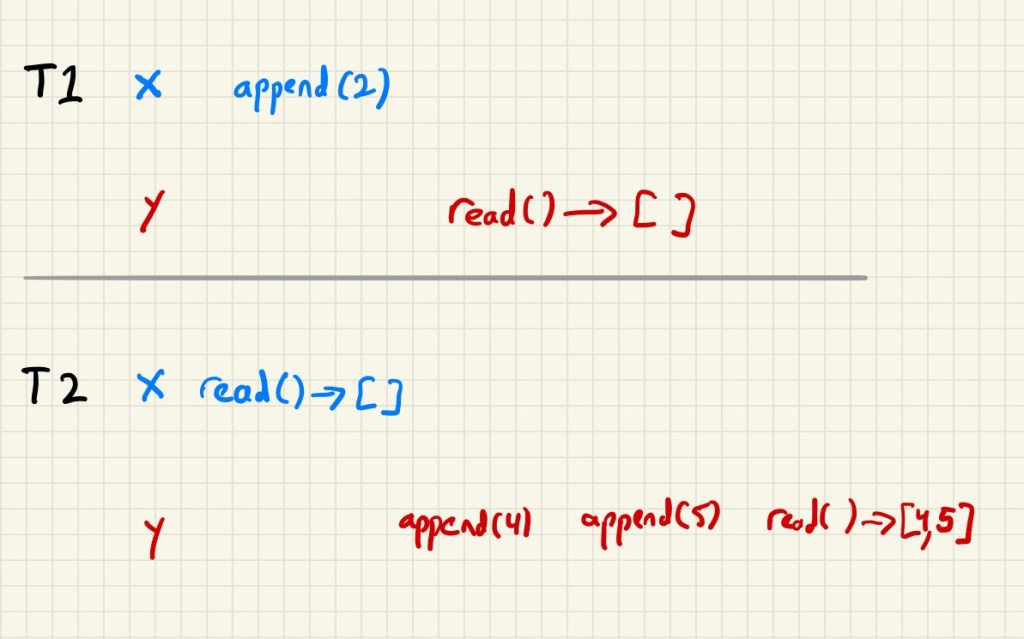
Here’s my redrawing of the example. I’ve drawn all operations against *x* in blue and against *y* in red. Note that I’m using empty list (`[]`) instead of *nil*.
|
||||
|
||||
|
||||
|
||||
There are two transactions, which I’ve denoted T1 and T2, and each one involves operations on two list objects, denoted *x* and *y*. The lists are initially empty.
|
||||
|
||||
For transactions that use the *serializability* isolation model, all of the operations in all of the
|
||||
transactions have to be consistent with some sequential ordering of the transactions. In this particular
|
||||
example, that means that all of the operations have to make sense assuming either:
|
||||
|
||||
- all of the operations in T1 happened before all of the operations in T2
|
||||
- all of the operations in T2 happened before all of the operations in T1
|
||||
|
||||
# Assume order: T1, T2
|
||||
|
||||
If we assume T1 happened before T2, then the operations for *x* are:
|
||||
|
||||
```
|
||||
x = []
|
||||
T1: x.append(2)
|
||||
T2: x.read() → []
|
||||
```
|
||||
This history violates the contract of a list: we’ve appended an element to a list but then read an empty list. It’s as if the append didn’t happen!
|
||||
|
||||
# Assume order: T2, T1
|
||||
|
||||
If we assume T2 happened before T1, then the operations for *y* are:
|
||||
|
||||
```
|
||||
y = []
|
||||
T2: y.append(4)
|
||||
y.append(5)
|
||||
y.read() → [4, 5]
|
||||
T1: y.read() → []
|
||||
```
|
||||
This history violates the contract of a list as well: we read `[4, 5]` and then `[ ]`: it’s as if the values disappeared!
|
||||
|
||||
Kingsbury indicates that this pair of transactions are illegal by annotating the operations with arrows that show required orderings. The "rw" arrow means that the read operation that happened in the tail must be ordered before the write operation at the head of the arrow. If the arrows form a cycle, then the example violates serializability: there’s no possible ordering that can satisfy all of the arrows.
|
||||
|
||||
# Serializability, linearizability, locality
|
||||
|
||||
This example is a good illustration of how serializability differs from [linearizability](https://jepsen.io/consistency/models/linearizable).
|
||||
Lineraizability is a consistency model that also requires that operations must be consistent with sequential ordering.
|
||||
However, linearizability is only about individual objects, where transactions refer to collections of objects.
|
||||
|
||||
(Linearizability also requires that if operation *A* happens before operation
|
||||
*B* in time, then operation *A* must take effect before operation *B*, and
|
||||
serializability doesn’t require that, but let’s put that aside for now).
|
||||
|
||||
This counterexample above is a *linearizable* history: we can order the operations such that they are consistent with the contracts of x and y. Here’s an example of a valid history, which is called a *linearization*:
|
||||
|
||||
```
|
||||
x = []
|
||||
y = []
|
||||
x.read() → []
|
||||
x.append(2)
|
||||
y.read() → []
|
||||
y.append(4)
|
||||
y.append(5)
|
||||
y.read() → [4, 5]
|
||||
```
|
||||
Note how the operations between the two transactions are interleaved. This is forbidden by transactional isolation, but the definition of linearizability does not take into account transactions.
|
||||
|
||||
This example demonstrates how it’s possible to have histories that are linearizable but not serializable.
|
||||
|
||||
We say that lineariazibility is a *local* property where serializability is not: by the definition of linearizability, we can identify if a history is linearizable by looking at the histories of the individual objects (x, y). However, we can’t do that for serializability.
|
||||
|
||||
## One thought on “Who’s afraid of serializability?”
|
||||
@@ -0,0 +1,137 @@
|
||||
# Achieving FMEA goals faster with Chaos Engineering
|
||||
|
||||
- **期号**: SRE Weekly Issue #223(2020-06-14)
|
||||
- **作者**: Matthew Helmke
|
||||
- **链接**: https://www.gremlin.com//blog/achieving-fmea-goals-faster-with-chaos-engineering/
|
||||
|
||||
## 简介
|
||||
|
||||
> Failure mode and effects analysis (FMEA) is a decades-old method for identifying all possible failures in a design, a manufacturing or assembly process, or a product or service.
|
||||
|
||||
If you’ve been tasked with applying FMEA in your SRE work, this article will get you started.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
# Achieving FMEA goals faster with Chaos Engineering
|
||||
|
||||
Failure mode and effects analysis ([FMEA](https://asq.org/quality-resources/fmea)) is a decades-old method for identifying all possible failures in a design, a manufacturing or assembly process, or a product or service. In the last few years it has [begun to be used](https://www.slideshare.net/AnnMarieNeufelder/an-introduction-to-software-failure-modes-effects-analysis-sfmea) by companies looking to make their computer systems better. While FMEA is not officially an ISO standard procedure like [ISO 31000 Risk Management](https://www.iso.org/iso-31000-risk-management.html), there are [ISO implementations](https://www.iso.org/obp/ui/#iso:std:iso:12132:ed-2:v1:en) specific to certain applications. Instead, it is broader and able to be applied to a wide range of needs.
|
||||
|
||||
DevOps and the move from corporate-owned datacenters to the cloud, combined with the rise of microservices, have created systems that are more flexible and cost-efficient. But that comes with greater complexity and the risk of unknown single points of failure. Our new applications and production environments are too large and complex to adequately or accurately reproduce in testing and staging environments.
|
||||
|
||||
The goal of Chaos Engineering is to create more reliable and resilient systems by injecting small, controlled failures into large scale computer systems. Only by properly testing a system can we truly know where its weaknesses lie. We think we know our system’s capacity and how it will respond to known actions, but we aren’t certain because we haven’t yet found a way to test our assumptions. In addition, we can only fix problems by finding them. When we have a good sense of what *can* go wrong, disaster recovery times are shortened and the criticality of incidents is reduced.
|
||||
|
||||
This seems like a match made in heaven. Using FMEA and Chaos Engineering in tandem for failure detection and failure analysis will help achieve the ultimate goals of both more quickly and with greater assurance that the desired results have been achieved. Whether using root cause analysis to find initial causes of failures or instead expecting those failures going forward and creating automated failover and initial incident response schemes, our systems benefit from a careful examination and testing.
|
||||
|
||||
## What is FMEA?
|
||||
|
||||
FMEA was started in the 1940s by the U.S. military as a step-by-step approach for identifying all possible failures in a design, in a manufacturing process, in a product or service, or an assembly process. This is important because by anticipating the potential small failures, you can adjust processes and systems to prevent the cascading consequences of failures. This is just as true in software applications.
|
||||
|
||||
As a process analysis tool, FMEA can be used at any stage from design through the process, product, or service’s lifecycle. It is typically implemented after quality function deployment ([QFD](https://asq.org/quality-resources/qfd-quality-function-deployment)) is performed. QFD measures customer satisfaction and analyzes their needs. In software, this is similar to the requirements gathering process that precedes writing the first line of code. Only by knowing what customers want and need can we produce something suitable and delightful. If you are coming from a DMAIC world, FMEA occurs during the Analysis phase of the process.
|
||||
|
||||
[DMAIC](https://en.wikipedia.org/wiki/DMAIC) is a data-driven strategy used to improve processes created as part of the [Six Sigma](https://en.wikipedia.org/wiki/Six_Sigma) set of tools and techniques. It is sometimes used by itself to drive improvements.
|
||||
|
||||
It stands for:
|
||||
|
||||
- Define the problem
|
||||
- Measure performance
|
||||
- Analyze the process
|
||||
- Improve process performance
|
||||
- Control the improved process
|
||||
|
||||
FMEA is typically used while a process, product, or service is being:
|
||||
|
||||
- Created
|
||||
- Applied for the first time
|
||||
- Modified or improved
|
||||
- Run in production
|
||||
|
||||
The approach is also useful while developing control plans for quality assurance or quality control and when analyzing failures that have happened to prevent their recurrence. Organizations using FMEA may also apply it periodically throughout the life cycle, for the purposes of continual improvement or an undocumented change was introduced that caused a regression or new failure. In this case, the application may be scheduled on a periodic basis or may be randomly applied.
|
||||
|
||||
No one can control world events; the scope is just too large, which is one of the reasons disaster recovery plans and failure mitigation was created. Similarly, in the world of today’s complex systems, we don’t always control all the moving parts. In today’s cloud computing environments, we don’t control the infrastructure, so changes can happen that we have no control over or way to anticipate. What we can do is apply some very similar steps to enhance our understanding of our systems and mitigate potential failures.
|
||||
|
||||
FMEA is a complex process with implementation details that vary according to organizational goals and industry standards. From a high level, it involves assembling a team of people who analyze and determine the scope of the FMEA. From there, flowcharts and forms are created to capture every detail as clearly as possible. Then, every part of the system is analyzed carefully to find potential modes of failure, possible root causes, and probable customer impacts. While the complex process was designed for other uses, any software application will benefit from us taking time to consider and find potential failures and considering customer impacts. We can only prevent what we anticipate.
|
||||
|
||||
Once the failure modes are discovered, described, and documented, FMEA requires the analysis of three things:
|
||||
|
||||
- Severity - using an S rating, this denotes the potential impact of a failure, from insignificant to catastrophic
|
||||
- Occurrence - using an O rating, this denotes the probability that the failure will occur, from extremely unlikely to inevitable
|
||||
- Detection - using a D rating, this denotes how well the process controls put in place can detect a cause or a failure mode after they occur but before a customer is affected
|
||||
|
||||
When the team assigns a severity rating to each failure mode, this is similar to the SEV-1 or SEV-4 style ratings that are used for software incidents. The occurrence rating is similar to categorizing the results of a Chaos Engineering test to prioritize system enhancements; there’s more on that in the next section.
|
||||
|
||||
After the severity and occurrence ratings are calculated, process controls are identified and written covering the tests, procedures, or mechanisms that we will put in place to keep the failures from reaching the customer. Notice that we aren’t assuming the ability to prevent all failures, but instead expect there to be failures that are impossible to keep from happening. What we are trying to do is prevent customer impact.
|
||||
|
||||
Site reliability engineers (SRE) do something similar when we write runbooks (sometimes called playbooks) documenting procedures and information to help make human-required assistance in an emergent situation more efficient and effective.
|
||||
|
||||
Finally, the FMEA group determines how to detect failures as early as possible and give a set of recommended actions. An SRE will agree that good system monitoring and observability enables early failure detection in today’s computer systems and applications.
|
||||
|
||||
## How does Chaos Engineering support FMEA goals?
|
||||
|
||||
This methodical and scientific approach of FMEA is useful, but not perfectly possible with our constantly-changing computing architectures today, at least not in the sense of documenting every piece of the architecture and how it interacts with other parts of the system. When load balancers spin up or take down resources according to system load, it is impossible to know second by second what some of our systems look like. We can approximate, but any drawing we attempt will be imprecise at any given moment.
|
||||
|
||||
However, most FMEA goals do not actually require that level of exactness. What the goals require is finding failure modes and doing something about them. In fact, FMEA itself is a bit fuzzy because it is anticipating failure modes, not documenting actual experience (although some analyses may start from past failure events). We can choose to be comfortable with the inexactness of prediction while searching for potential problems and solving them in advance.
|
||||
|
||||
What Chaos Engineering does is use an intentional, planned process through which we inject harm into a system to learn how it responds and ultimately, to find and fix problems and find defects before they happen in a way that impacts customers. Before starting any attacks on your systems, you should fully think out and develop the experiments you want to run. Sounds familiar, doesn’t it?
|
||||
|
||||
Chaos Engineering doesn’t create chaos; it acknowledges the chaos that already exists in our massive deployments and constantly-changing systems and was created to reign in the potential customer impacts of that chaos. A component or service failure should not be able to bring down the whole system. We can’t anticipate all of them, but that doesn’t mean we shouldn't try to find the ones we can anticipate.
|
||||
|
||||
When creating a chaos experiment we:
|
||||
|
||||
1. Start with a *hypothesis* stating the question that we’re trying to answer, and what you think the result will be. For example, if your experiment is to learn what happens to one of your bank’s ATMs when network latency increases beyond a set level, your hypothesis might state that you expect the machine to store a local record of the incident, prevent customer account balance errors, and signal maintenance as soon as connectivity improves.
|
||||
2. Define your *blast radius* . The blast radius includes any and all components affected by this test. A smaller blast radius will limit the potential damage done by the test. We strongly recommend you start with the smallest blast radius possible. Once you are more comfortable running chaos experiments, you can increase the blast radius to include more components.
|
||||
3. You should also define your *magnitude* , which is how large or impactful the attack is. For example, a low-magnitude experiment might be to test application responsiveness after increasing CPU usage by 5%. A high-magnitude experiment might be to increase usage by 90%, as this will have a far greater impact on performance. As with the blast radius, start with low magnitude experiments and scale up over time.
|
||||
4. *Monitor* your infrastructure. Determine which metrics will help you reach a conclusion about your hypothesis, take measurements before you test to establish a baseline, and record those metrics throughout the course of the test so that you can watch for changes, both expected and unexpected.
|
||||
5. *Run the experiment* . You can use Gremlin to run experiments on your infrastructure in a simple, safe, and secure way. We also want to define*abort conditions* , which are the conditions where we should stop the test to avoid unintentional damage. With Gremlin, we can actively monitor our experiments and immediately stop them at any time.
|
||||
6. Form a *conclusion* from your results. Does it confirm or refute your hypothesis? Use the results you collect to modify your infrastructure, then design new experiments around these improvements.
|
||||
|
||||
Repeating this process over time will help us harden our applications and processes against failure. Use this process to discover failure modes or confirm suspected ones, learn their impact on the rest of the system, discover mean time to detect ([MTTD](https://www.gremlin.com/oreilly-reducing-mttd-for-high-severity-incidents/)) when a failure occurs and learn whether the system auto-heals with designed failover schemes and mitigation techniques. MTTD is very similar to FMEA’s *Detection*.
|
||||
|
||||
Likewise, you can use Chaos Engineering to help you calculate both *Severity* and *Occurrence*. Here are some examples. If you perform a blackhole attack against a single DB and discover that it shuts down the entire application, the *Severity* is high. If instead you are performing a simple CPU attack, which reproduces a common event, that would be considered a high-*Occurrence* event when compared to something rare like a full region evacuation. Carefully designed chaos experiments can help you detect new entries into these categories and determine the proper ratings to assign to each that you find, accelerating the overall process.
|
||||
|
||||
Frequently, organizations begin their Chaos Engineering journey using [GameDays](https://www.gremlin.com/community/tutorials/how-to-run-a-gameday/), which are days with a couple of hours set aside for a team to run one or more chaos experiments and then focus on the technical outcomes. Risk assessment goals can be set in advance and then tested alongside other of the system’s capabilities with everyone on the software development team participating with real-time monitoring and implementation.
|
||||
|
||||
The Chaos Engineering goal of finding failure modes more safely, easier, and faster aligns perfectly with FMEA goals. In fact, although they developed in different times for different purposes, site reliability engineering looks like an implementation of FMEA to the world of distributed systems and large-scale software applications.
|
||||
|
||||
Once failure scenarios are discovered, the information gathered is used to set improvement goals as the results of chaos experiments inform how reliability work is prioritized or scheduled. Serious issues that are detected are given the highest priority. Implementing Chaos Engineering into our operation helps us achieve our goals of continuous improvement and reliable systems. We can eliminate or reduce outages as we build resiliency into our systems.
|
||||
|
||||
## Chaos Engineering helps you achieve your FMEA goals more quickly
|
||||
|
||||
Both SRE and FMEA have one major goal: prevent anything that affects the customer negatively. FMEA uses risk priority numbers (RPN) when assessing risk. RPNs are calculated using an equation involving severity, occurrence/likelihood, and detection. In SRE, we use service-level objectives (SLO) with associated error budgets to set targets for reliability that are measurable and actionable.
|
||||
|
||||
Whether in the physical world of manufacturing or the virtual world of computing, we all have expectations and agreements that we must meet and we all have defined ways to measure success. Reliability and customer satisfaction are the goals.
|
||||
|
||||
Applying FMEA goals to today’s enterprise software systems is possible, but accelerated using Chaos Engineering. SREs have discovered that Chaos Engineering helps them meet and exceed their service level agreements, it can also help organizations with regulations or mandates to use FMEA meet or exceed similar expectations by discovering potential failure modes the only way possible in today’s distributed architectures.
|
||||
|
||||
#### Start your free trial
|
||||
|
||||
Gremlin's automated reliability platform empowers you to find and fix availability risks before they impact your users. Start finding hidden risks in your systems with a free 30 day trial.
|
||||
|
||||
[START YOUR TRIAL](https://www.gremlin.com/trial)
|
||||
|
||||

|
||||
|
||||
[Back to top](https://www.gremlin.com#single-article)
|
||||
|
||||
|
||||
## What is Failure Flags? Build testable, reliable software—without touching infrastructure
|
||||
|
||||
Failure Flags make it possible to test your software’s failure modes without compromising that software or its security, and without outsized efforts to build specialized testing environments.
|
||||
|
||||
|
||||
|
||||
Building provably reliable systems means building testable systems. Testing for failure conditions is the only way to...
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/gremlin-failure-flags-test-software)
|
||||
|
||||
|
||||
## Introducing Custom Reliability Test Suites, Scoring and Dashboards
|
||||
|
||||
Discover how to create custom reliability test suites, scoring, and dashboards in Gremlin. Define your own reliability standards, measure reliability proactively with custom scoring, and identify organization-wide reliability risks with executive dashboards. Improve your system's reliability and meet IT governance requirements with Gremlin.
|
||||
|
||||
|
||||
|
||||
Last year, we released Reliability Management, a combination of pre-built reliability tests and scoring to give you a consistent way to define, test, and measure progress toward reliability standards across your organization.
|
||||
|
||||
[Read more](https://www.gremlin.com/blog/introducing-custom-reliability-test-suites-and-scoring)
|
||||
Reference in New Issue
Block a user