SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,94 @@
|
||||
# [Increment: Reliability] Interview: Dr. David D. Woods
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Ipsita Agarwal — Increment
|
||||
- **链接**: https://increment.com/reliability/resilience-engineering-david-woods/
|
||||
|
||||
## 简介
|
||||
|
||||
People throw around “resiliency” quite often when they mean “reliability” or “high availability”. Dr. Woods sets the record straight.
|
||||
|
||||
## 正文
|
||||
|
||||
Technological systems, like society, are becoming ever more complex—with interdependencies that are difficult to trace, operating in environments that inevitably find their edges. Resilience engineering posits that to be dynamic, systems must be able to extend their capabilities gracefully and adapt their capacities when needed.
|
||||
|
||||
We sat down with Dr. David D. Woods, who helped found resilience engineering in the early 2000s in response to several NASA accidents, including the Space Shuttle Columbia disaster, for which he was an advising investigator. For 40 years Dr. Woods has worked to improve the safety of complex, high-risk systems in fields such as aviation, nuclear power, and critical care medicine. In this conversation, he explains the concepts behind resilience engineering through the lens of the COVID-19 pandemic and other real-world crises, and how we can build systems that can perform even under stress and surprise.
|
||||
|
||||
*This interview has been edited and condensed for length and clarity.*
|
||||
|
||||
**Increment:** **What’s the difference between reliability and resilience as it relates to complex systems? In my experience, these terms get confused easily and often.**
|
||||
|
||||
**Dr. David D. Woods:** Reliability is a record from the past—we can pull out different facets of how we’ve performed in the past and say we’re getting better on this criterion or that. The problem is that [reliability] makes the assumption that the future will be just like the past. That assumption doesn’t hold because there are two facts about this universe that are unavoidable: There are finite resources and things change.
|
||||
|
||||
|
||||
Finite resources and change mean that the future will not be like the past. You need to be poised to adapt, and [you can’t do that] by just trying to invest in reliability. You have to think about robustness and resilience. Robustness then becomes: Can you make the system not just more optimal or productive but able to withstand known risks? If you understand a threat, how do you make the system robust so it will continue to work—or work in a gracefully degrading mode—in the face of that threat?
|
||||
|
||||
|
||||
Now we’re getting to what really is at the heart of resilience, and that’s extensibility. How do you extend performance when an event challenges the way you usually work, challenges your boundaries? Events will arise which stress your system. Those events will find the edges in your plans for normal operation and in your contingency plans, [so] you need to find ways to stretch at those edges. Resilience as extensibility is the opposite of brittle reliability.
|
||||
|
||||
|
||||
We build sources for extensibility to be able to extend performance when we *don’t* understand what the challenge is. We rely on a lot of cognitive, human, and collaborative mechanisms. NASA Mission Control practiced anomalies on space shuttles for the Apollo era all the time. In space, surprise is normal. [They weren’t practicing a] specific failure. They were practicing how to have extensive resilience in the face of an event they hadn’t [anticipated]. They were practicing teamwork.
|
||||
|
||||
|
||||
**System failures can arise from a combination of smaller component failures or the environment being complex and unpredictable. And yet there’s this persistent idea that we have to become better at predicting, modeling, and potentially excusing failure if the chances of that failure happening are very low. How do you make the case for true surprises?**
|
||||
|
||||
The first way to approach surprise is from a reliability and robustness point of view, [in which surprise is] about the way consequences and frequency combine. If it’s low frequency [and the consequences are low], it doesn’t matter. If the consequences are high and it’s low frequency, then we need to do something. For example, [the nuclear power industry] was worried about this in the ’70s given public concern about radiation. [Nuclear accidents] are estimated to be very low-frequency events, but because they can be so catastrophic, you’re going to make a big effort to be prepared to handle them.
|
||||
|
||||
|
||||
It’s a frequency-consequence combination. Everybody assumes that frequency just declines, that we have a normal distribution and the tail is small. But it turns out, in statistics, [we] look at what’s called heavy-tail distributions. We often underestimate what looked like low-frequency events. They’re actually much higher frequency than you think because the tails are heavy.
|
||||
|
||||
|
||||
An example is Hurricane Harvey in Houston, Texas, a couple of years ago. That was the third year in a row that Houston had a “one-in-500–year” flood event. If you say [what we’re expecting] is a one-in-100–year flood event and you’re looking at a specific geographic location, the frequency data might [suggest that]. But now take space and time averaging. In the continental U.S. this year, how many one-in-100–year flood events will happen? There will be multiple one-in-100–year flood events this year, and that number is increasing. So you have to better prepare.
|
||||
|
||||
|
||||
We screw frequency up because we get trapped in linear simplifications, and we miss trends of change in the world. And that is not remotely good enough.
|
||||
|
||||
|
||||
The science underlying resilience says there’s a different kind of surprise, and that’s the dominant form we care about: model surprise. In other words, because of finite resources and change, you’re adapting to the world and trying to get a better match between your capabilities and the world you’re in. The possibility for the mismatch to grow, or to move around, is fundamental. You can think of this as an envelope: [Your system is] successful within that envelope, but it has boundaries. The boundaries move. They’re not static.
|
||||
|
||||
|
||||
Model surprise will happen because the world keeps changing. So, very simply stated, viability [of a system] in the long run requires extensibility. The world will throw challenges that find the edges in your current system. If you can’t extend performance at the edges, you’ll end up with a brittle collapse.
|
||||
|
||||
|
||||
**Can we look at an example that demonstrates brittle reliability versus graceful extensibility in the way the COVID-19 pandemic was handled?**
|
||||
|
||||
We saw a classic form of resilient performance extensibility in the early stage [of the pandemic]. With the novelty of the disease, there was a lot of uncertainty about the proper kind of care: Do you put [patients] on ventilators quickly or delay [doing so] even though their oxygen saturation is low? The guidelines before COVID suggested that you respond aggressively to low oxygen saturation in the blood. But [health care workers] had to learn that that could be an over-response. An ad hoc, informal communication network rapidly emerged among physicians trying to develop and understand how to best treat patients. These physicians had a readiness to revise and a readiness to respond.
|
||||
|
||||
|
||||
For an example of brittleness, in [early spring 2020] the CDC was struggling with the novelty [of the disease] and trying to integrate information and send guidance to hospital systems about how to deal with [it]. But what happened? The CDC was sending updated guidance to hospitals multiple times a day. The problem that hospital systems had was how to keep up with these changing recommendations.
|
||||
|
||||
|
||||
[Government jurisdictions and hospital systems] just weren’t set up as dynamic organizations, whereas an emergency room in a hospital is set up to be very dynamic. Viability requires extensibility. And extensibility has to be built before you’re in the challenge or change situation. Generating this capability during the change is much more difficult than if you generate it in advance.
|
||||
|
||||
|
||||
**Extensibility is a dynamic capability: We have to be able to design a system in such a way that it can adapt in advance of a crunch by anticipating that crunch. How does anticipation work? What’s the distinction between anticipation and modeling for brittle reliable systems and contingency planning?**
|
||||
|
||||
Anticipation turns out to be critical. The classic result is anticipating a bottleneck or crunch, so you act now in order to generate the resources or response capability before the bottleneck hits you. This originally came from studies on how people adapt to high workload, like anesthesiologists who did dynamic stuff in an operating room. They were highly sensitive [to change]. The [absolute] probability of a crunch happening might be low, but they picked up signs that the probability had gotten higher.
|
||||
|
||||
|
||||
People [tend to] discount evidence that challenges their model. Their model is being surprised by events in the world, but instead of being ready to revise, they discount the evidence. It’s [about] how sensitive you are to the emerging information that things don’t fit your model. If you’re waiting for definitive evidence that some new problem has arisen, the problem will be much bigger before you act.
|
||||
|
||||
|
||||
Instead, the people who were good [at adapting] were sensitive. They were picking up early evidence that things might be different, so they monitored new channels. They interacted with other people to pick up what information they had. They changed their effort. Anticipation is very tightly connected to a readiness to revise.
|
||||
|
||||
|
||||
**You’ve previously written that every unit in a system, at whatever scale, has to have non-zero graceful extensibility. What do you mean by that?**
|
||||
|
||||
If you have zero extensibility you’re maximally brittle. A unit can’t have enough [graceful extensibility] by itself.
|
||||
|
||||
|
||||
To use a hospital example, in no unit—a clinician or clinician team—can we have enough ICU capability. No unit by itself can have sufficient graceful extensibility given the possibility for model surprise. And the reason is the same: finite resources and change. This is why an emergency room has the capability to adapt to patient crises, but only so much. At some point in a mass-casualty event it needs help from the rest of the hospital system in order to handle all the patients. It needs more personnel, it needs to expand the space it takes [up], it needs to facilitate interactions with the diagnostic centers in the hospital. So you have to have other interdependent units, and they have to be ready to adapt to help the unit at risk of getting crunched.
|
||||
|
||||
|
||||
As I start to run out of the capacity to act as the situation continues to deteriorate, I need help from somebody who’s in the neighborhood, so to speak. The neighboring units parallel or above, sometimes even below in a network or a hierarchy, need to recognize I’m at risk of saturation and do something to help me.
|
||||
|
||||
|
||||
You can see the breakdown of [extensibility] in the pandemic response. Early in the pandemic, some governors and states got slammed. They were quickly trying to get the public to cooperate with restrictions because they were afraid of overloading their hospitals. They got better cooperation because everyone [realized] we don’t want to have our hospitals look like Italy or New York. Then, once hospitals were able to adapt or it didn’t get that bad for certain jurisdictions, everybody went, “See, we don’t want to do this anymore, it’s not that bad,” and cooperation with activity restrictions dropped off.
|
||||
|
||||
|
||||
That’s an example of what we call reciprocity. Without reciprocity, you can’t get that second layer of, “I have some graceful extensibility, but as I start to run out of capability, I need other parties to help me.”
|
||||
|
||||
|
||||
**What would you say to someone who reads this interview and says, “Alright, I understand the concept of resilience. I understand that my system has to have graceful extensibility. Where do I start?”**
|
||||
|
||||
That’s contingent on the engineering system and the role they’re dealing with. The pursuit of efficiency—faster, better, cheaper—inadvertently undermines the sources of resilient performance. So the general advice is [to adopt] pragmatic but different engineering [practices]. It’s the balance between seeking optimality in the short run and building and investing in graceful extensibility [in the long run]. Those have to be balanced—they interact, they’re interdependent, and you need both.
|
||||
@@ -0,0 +1,94 @@
|
||||
# [Increment: Reliability] The process: Implementing Yelp’s failover strategy
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Mathieu Frappier, Dorothy Jung, and Qui Nguyen — Increment
|
||||
- **链接**: https://increment.com/reliability/yelp-traffic-failover-strategy/
|
||||
|
||||
## 简介
|
||||
|
||||
A key part of their strategy is to keep their service running at 50% capacity or less, allowing them to lose a datacenter without overloading the remaining datacenter.
|
||||
|
||||
## 正文
|
||||
|
||||
On the surface, the process is straightforward: Site reliability engineers at Yelp sometimes shift traffic to prevent user-facing errors. Under the hood, however, it involves a complex choreography between production systems, infrastructure teams, and hundreds of developers and their services. This is the story of how Yelp’s production engineering and compute infrastructure teams implemented a failover strategy by finding a balance between reliability, performance, and cost efficiency.
|
||||
|
||||
## What’s a traffic failover?
|
||||
|
||||
Yelp serves requests out of two regional AWS data centers located on both U.S. coasts. Read-only requests, which constitute the bulk of user traffic, are sent to the nearest data center, with additional logic to ensure the load is evenly distributed between both regions. Sometimes, one region becomes unhealthy due to a bad infrastructure configuration, an impaired critical data store, or, on rare occasions, an AWS issue. When any of these happen, we could be serving users HTTP 500 errors and need to act quickly.
|
||||
|
||||
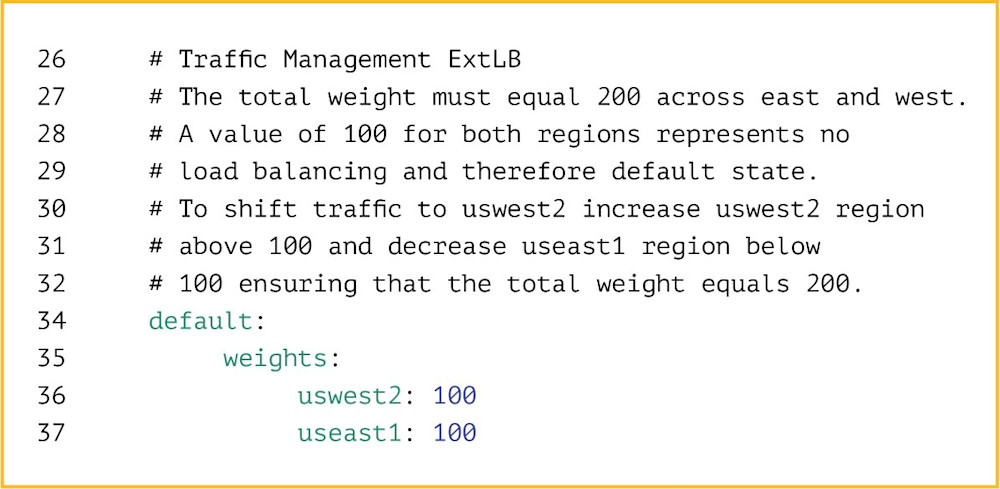
To mitigate such outages, one tool at Yelp’s disposal is the failover: the ability to quickly shift traffic from the unhealthy region to the healthy one. A partial traffic shift alleviates pressure on impaired systems and allows them to recover. The shift can also be total: a full failover. All we need to do to shift traffic is update a Git-controlled YAML file. But even during an emergency, merging and pushing the change requires approvals, typically from the secondary on-call production engineer, a manager, or an engineer involved in the ongoing incident.
|
||||
|
||||
|
||||
|
||||
*An extract from the traffic management configuration file*
|
||||
|
||||
On-call engineers at Yelp regularly practice partial and full failovers to ensure our infrastructure can handle the sudden change in load and our teams remain comfortable executing the procedure. While the failover itself is a simple config change, situations that require full failovers are often stressful and unpredictable. The primary on-call engineer needs to be familiar with the process to avoid additional strain.
|
||||
|
||||
## When failovers fail
|
||||
|
||||
Major shifts in traffic patterns can overwhelm the healthy region that’s now serving global traffic. In Yelp’s early days, we “melted” a healthy region on numerous occasions by sending too much traffic to one region too quickly. Most of our services and clusters of machines can scale up in minutes, assuming all systems are working as they should, but these are crucial minutes we can’t spare. Our response needs to be instant.
|
||||
|
||||
Furthermore, in a constantly evolving infrastructure, adding capacity to production can be complicated—a recent change in low-level configuration could slow or even prevent us from getting new, healthy machines. This can quickly devolve into a worst-case scenario where we’re unable to scale up the healthy region and end up serving HTTP 500 errors to users.
|
||||
|
||||
## Keeping double capacity
|
||||
|
||||
A good way to prevent meltdowns is to keep extra compute capacity around at all times.
|
||||
|
||||
One way to do this is to have more machines available. By doubling the number of running machines, we always have the compute capacity we need to handle failovers. This also means we don’t need to add machines in an emergency, which removes one step in the failover process and, more importantly, reduces dependency on the compute infrastructure team if something goes wrong provisioning these instances.
|
||||
|
||||
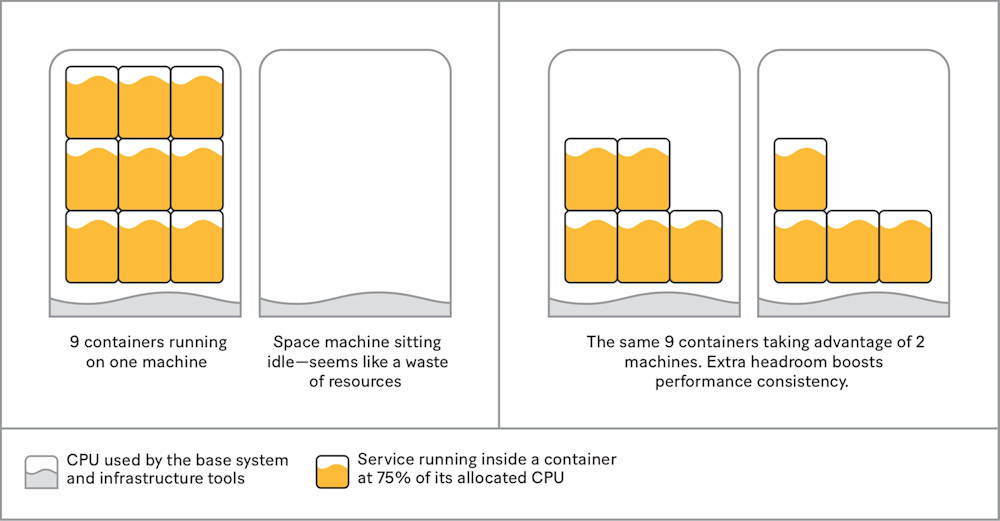
However, keeping idle machines around just in case of a failover can seem like a waste of resources, so we put them to work by distributing the containers we need among all available machines. This way, each machine has just 50 percent of its resources allocated to services in normal situations, allowing it to absorb load spikes and maintain more consistent performance—and it costs the same.
|
||||
|
||||
|
||||
|
||||
*Spreading containers evenly across multiple machines gives services more headroom.*
|
||||
|
||||
With enough machines to handle failover conditions, we’ve gained reliability (spreading containers on multiple hosts means a single host failure will impact fewer services) and improved performance consistency. However, we still need to address the critical minutes it takes to schedule more copies of our services during an emergency failover. We need traffic shifts to happen in seconds, not minutes, to minimize the number of 500s we may be serving.
|
||||
|
||||
## Always be ready to shift traffic
|
||||
|
||||
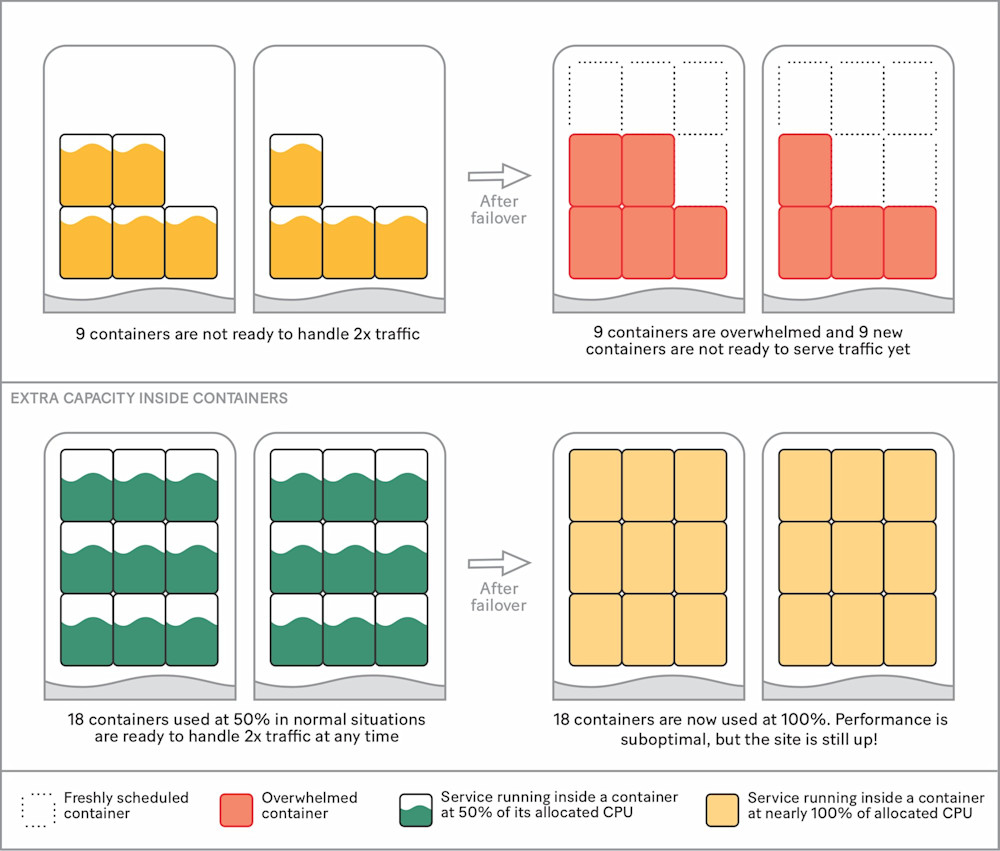
Precious time can be wasted during failovers as we wait for additional containers to be scheduled to handle the new load, download their Docker image, and warm up their workers before finally being able to serve traffic. To shave off those extra minutes, we decided to keep the extra capacity inside the containers as part of the normal service configuration, ensuring we don’t need to add any more during failover. While this may seem like a benign detail, it’s the key to our reliability strategy, since it allows us to always be ready for failover.
|
||||
|
||||
|
||||
|
||||
|
||||
Having additional containers in use has a few key advantages:
|
||||
|
||||
- We can guarantee high performance consistency to users by keeping free resources on all machines. These resources are already reserved by the services.
|
||||
- We already have enough containers to handle a sudden 2x traffic increase.
|
||||
- We’ve cut down our dependency on the compute infrastructure’s ability to schedule containers at a critical time.
|
||||
|
||||
In order for this strategy to work, however, containers must be correctly sized and ask for the right amount of resources from the compute platform. In a service-oriented architecture, developers are directly in charge of the configuration of their service. This configuration has to reflect our failover strategy, and every service needs to be configured to use exactly 50 percent of its allocated resources, which is what’s required to handle the doubled load during failover.
|
||||
|
||||
## Setting the right values
|
||||
|
||||
The main advantage of a service-oriented architecture is greater developer velocity. Developers can deploy the services they own many times a day without having to worry about batching code changes, merge conflicts, release schedules, and so on. Teams fully own their services and associated configurations, including resource allocation like CPU, memory, and autoscaling settings.
|
||||
|
||||
|
||||
|
||||
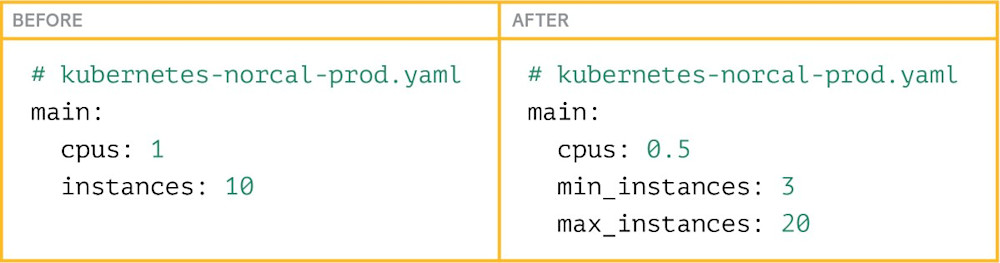
*Enabling service autoscaling on Yelp’s compute platform, PaaSTA, can be deceptively easy.*
|
||||
|
||||
Resource allocation is a challenge. In order to be failover-ready, every service needs precise resource allocation to ensure containers use exactly 50 percent of their resources in normal situations. How can we expect software engineers across dozens of teams to fiddle with these settings in production until they get it exactly right?
|
||||
|
||||
## Finding the optimal settings
|
||||
|
||||
Some core components of Yelp, like the search infrastructure, have been optimized for performance over time. Their owners know exactly how the application behaves under heavy production load, how many threads they can use, what the typical wait versus actual CPU time is, how frequent and expensive garbage collection operations are, and so on. However, most teams at Yelp don’t have all this knowledge. Most services work with the default values, and the only “tuning” we need to do consists of bumping up a few resources here and there as the service grows in popularity and complexity.
|
||||
|
||||
## Abstracting resource declaration
|
||||
|
||||
We needed to help our developers find the right settings for their services, so we invested in tooling to monitor, recommend, and even abstract away autoscaling settings and resource requirements for all production services. We now analyze services’ resource usage and generate optimized settings for CPU, memory, disk, and so on. Developers can opt out if they want to: A manually set value will always have priority over templated safe defaults and optimized defaults.
|
||||
|
||||
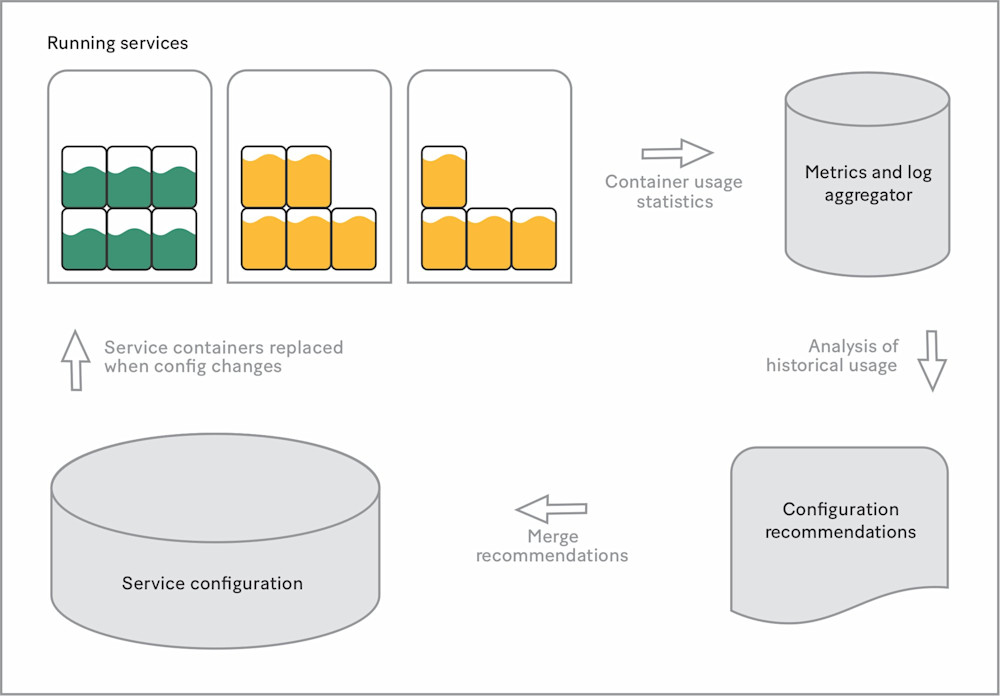
|
||||
|
||||
*New containers based on configuration recommendations have 50 percent usage.*
|
||||
|
||||
Generating optimized settings for CPU allows us to ensure that services autoscale correctly and have enough capacity for failover. We also reap reliability benefits. For example, if a service hits its memory limit and is killed, its optimized defaults will automatically be updated within two hours with a higher memory allocation. It now takes us less time to fix this particular issue than it took us to diagnose it in the days before autotuning.
|
||||
|
||||
### Autotuned defaults for all
|
||||
|
||||
After offering optimized settings as opt-ins for a few weeks and building tooling to monitor the system’s success metrics, we felt confident shifting from a recommendation system to optimized values enabled by default. We call this “autotuned defaults.” Unless it’s specifically opted out, every service now automatically declares and uses an optimal amount of resources. A side effect of this change is a significant reduction in compute cost due to the rightsizing of previously oversized services. Best of all, developers enjoy simpler service configurations.
|
||||
|
||||
## Setting ourselves up for success
|
||||
|
||||
Properly allocating the extra capacity required for an emergency failover means we always have the compute capacity we need. Automating service resource allocation removes a considerable burden for service owners and improves the process as a whole. In combination, these strategies simplify incident response and reduce downtime during the most serious outages.
|
||||
|
||||
One of the most interesting aspects of our failover and autoscaling strategy is organizational. By including the extra margin for failover inside every container, multiple teams have become more efficient. The production engineering team now has control over all service configurations, which is a prerequisite for a successful failover. The compute infrastructure team can focus on enhancing the platform without worrying too much about its ability to handle a failover. And developers don’t need to go through the time-consuming process of tuning the resource allocation or autoscaling configuration for their services. Instead, they can focus on what they do best: building a better product for our users and community.
|
||||
@@ -0,0 +1,63 @@
|
||||
# [Increment: Reliability] On adaptive capacity in incident response
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: John Allspaw, Beth Adele Long, and Dr. Richard Cook — Increment
|
||||
- **链接**: https://increment.com/reliability/adaptive-capacity-incident-response/
|
||||
|
||||
## 简介
|
||||
|
||||
In issue #236, I linked to an excellent paper by Dr. Richard Cook and Beth Long about engineering resilience in incident response. Now they’re back, teaming up with John Allspaw to summarize and expand on that paper!
|
||||
|
||||
## 正文
|
||||
|
||||
How do people—from ER doctors to air traffic controllers to software engineers—manage to keep complex systems working in the face of continuous challenges? This is the central question of resilience engineering.
|
||||
|
||||
Studies of resilience tend to focus on what resilience is and how it works. In contrast, resilience engineering seeks to enhance the resilience already present in a system. Since its emergence in the early 2000s, researchers have collaborated across fields such as human factors engineering and cognitive systems engineering to understand how complex work in hazardous domains across many different industries can succeed. And it’s been making significant inroads into the tech industry.
|
||||
|
||||
Since 2013, a growing number of companies have joined the resilience engineering community, in large part thanks to the [SNAFUcatchers Consortium](https://www.snafucatchers.com/), which brought researchers from Ohio State University into the offices (and lunch rooms) of some of [tech’s biggest names](https://www.snafucatchers.com/partners), including IBM, Salesforce, and Etsy. (Two of this article’s authors, Dr. Richard Cook and John Allspaw, are core members of the team. [Dr. David D. Woods](https://increment.com/reliability/resilience-engineering-david-woods/), interviewed elsewhere in this issue, is also a team member.) The collaboration paired university researchers with partner companies to examine, compare, and contrast their experiences anticipating and handling incidents in order to deepen their understanding of these critical events.
|
||||
|
||||
One result has been a burgeoning understanding of adaptive capacity—a person or organization’s capacity to adapt when circumstances change, such as during a major incident, a string of incidents, or organizational shifts—as a hallmark of resilience. This is explored in “[Building and Revising Adaptive Capacity Sharing for Technical Incident Response: A Case of Resilience Engineering](https://www.sciencedirect.com/science/article/pii/S0003687020301903),” a case study by Dr. Cook and Beth Long published in *Applied Ergonomics* in January 2021.
|
||||
|
||||
This article, a summary and expansion of Cook and Long’s findings, will examine one company’s approach to incident response as a framework for understanding adaptive capacity, and highlight takeaways for organizations looking to adopt a resilience engineering perspective.
|
||||
|
||||
## A study in incident response
|
||||
|
||||
In their paper, Cook and Long detail the case of consortium researchers and engineers from a participating company who met to discuss a recent barrage of incidents that had taxed the company’s incident handling capacity and contributed to burnout among responding engineers. The salvo of incidents made clear that their established incident response processes weren’t working. Development teams each had their own on-call engineer responsible for handling incidents that affected local components and subsystems, but this strategy fell short in the face of multiple complex, overlapping incidents that were difficult to diagnose and resolve.
|
||||
|
||||
Recognizing the need for a new approach, a group of experienced engineers established a support cadre to help respond to high-severity or difficult-to-resolve incidents, serving as a deep technical resource that could be tapped to support incident response. (Successfully sharing adaptive capacity in this way, Cook and Long noted, depends on specific characteristics such as the rate of incidents—not too low, not too high—as well as their duration—minutes to hours—and their magnitude—a combination of minor and major.)
|
||||
|
||||
The group, which initially included eight engineers and engineering managers from various teams, self-organized an on-call rotation so anyone at the company could summon them to provide their engineering and operational expertise. An on-call support engineer would participate in incident response if an incident crossed certain thresholds, such as high customer impact or long duration, allowing the other members of the incident support group to concentrate on their own tasks when not on call. The group members met weekly to review recent incidents and discuss how they should adjust their approach.
|
||||
|
||||
Members were aware that their participation in the group took time away from their primary work, and they tried to build in backstops to avoid conflicts. For example, a team of five engineers with one member in the incident support group could expect that engineer to be focused on incidents about one week out of eight. This support engineer would schedule work for their on-call week that was both interruptible and less taxing than that of their teammates. The workload of the engineer’s “home team,” however, stayed the same; the on-call support engineer’s decreased productivity was treated as overhead.
|
||||
|
||||
In theory, the on-call support engineer would participate in incidents only occasionally. In practice, however, they usually monitored all incidents’ progress, effectively staying on “hot standby.” Being alert to active incidents meant they could come up to speed faster if and when one required their expertise.
|
||||
|
||||
## The advantages of expert support
|
||||
|
||||
The organization quickly benefitted from this new process. For one thing, some incidents were resolved faster: Bringing their expertise and diverse incident experience, on-call support engineers were able to help first responders identify and resolve problems more efficiently. For another, the incident support group relieved some of the strain of managing incidents with severe consequences: First-responder engineers knew a specific person would appear when an incident was severe or long-running, which helped lessen their anxieties.
|
||||
|
||||
Lastly, this approach reduced the “fire alarm” effect. Previously, a serious incident might capture the attention and efforts of many senior engineers, disrupting work across teams. Now, non-responders could safely stay focused on their own tasks, knowing an incident support group member was on call and would engage if needed. Group members who were not on call, meanwhile, could focus on their home team’s work for seven out of eight weeks.
|
||||
|
||||
## How the approach evolved
|
||||
|
||||
Over the course of their first year in practice, the incident support group’s members continued to refine their processes. Initially, an incident commander would summon an on-call support engineer on an as-needed basis. But the group began to notice that responding engineers either delayed or avoided calling for help during long-lasting or severe incidents. The reasons varied: Some engineers got caught up in problem-solving and didn’t think to bring on extra support, while others were overconfident in their ability to resolve the incident without it.
|
||||
|
||||
In response, a group member wrote a program to track in-progress incidents and page an on-call support engineer under certain conditions, such as a particular duration or declared severity. This offloaded first responders’ request-for-help burden, and in some cases allowed the on-call support engineers to learn about incidents independently.
|
||||
|
||||
Over time, however, members dropped out of the group, which meant the remaining volunteers were on call more often, increasing the burden on their home teams. To lighten the load, the company built a pipeline to replenish the group. It began to recruit new members, offered training, established an apprenticeship program, and sought to make the role more attractive, for example by boosting its status within the organization (including with financial incentives), recognizing participation as part of career advancement, exempting support group members from their home teams’ on-call rotations, and establishing term limits in order to better distribute the workload across the org.
|
||||
|
||||
## Resilience engineering in the wild
|
||||
|
||||
The fact that resilience engineering can emerge organically, as it did at this company, suggests we can expect to find it elsewhere in tech—and in other fields, too. As this case study illustrates, the situations that foster it are those that tend to exhaust resilience. Constant demands can erode the adaptive capacity of a system and make resilience hard to sustain. Here, the engineers recognized a problem with their current incident response practices and worked to use their existing adaptive capacity more efficiently.
|
||||
|
||||
People working close to the sharp end of a system are often the ones to recognize the erosion of resilience and engineer temporary remedies. Ultimately, though, adaptive capacity has to be nourished and renewed. In this case, the company made an effort to do just that.
|
||||
|
||||
Simply adding adaptive capacity to an organization is likely to be difficult. For example, hiring seasoned experts may help, but even the most experienced new hire still needs time to learn about the system before they can offer support when usual problem-solving methods don’t pan out. Companies must husband their adaptive capacity; in this case, the gradual loss of incident support group members was a sign that the company needed to rethink its approach to recruitment and workload.
|
||||
|
||||
Notably, the group was mainly self-organized and lacked formal support from the company in its early days. Experts working on the day-to-day maintenance and repair of complex systems are generally more attuned to where adaptive capacity lives and how to extend it than those who work further from these systems. Here, they recognized a problem and took action, efficiently redirecting local resources to make resilience engineering possible. Only later did the company invest in the group more formally, which was likely a good thing: Hierarchical managerial decision-making might have been quite slow, frustrating the fast learning and flexibility that ultimately made the effort successful.
|
||||
|
||||
## Resilience engineering and you
|
||||
|
||||
This company’s experience is hardly unique. The tech industry, after all, is awash in incidents. New methods to address them crop up daily, and computational tools to help with incident response and post-incident evaluation are becoming more widespread. But resilience engineering is about more than approaches and tools. It’s about preparing to be unprepared—anticipating and planning for future incidents, detecting when our ability to handle them is threatened, and adjusting our attention and focus as needed.
|
||||
|
||||
Being able to keep large, complex, technology-intensive systems running is a primary function of online businesses, and the unpredictable nature of incidents will continue to require expertise that is expensive and hard to develop. Resilience engineering—the effective management of adaptive capacity—will be a crucial tool for organizations seeking to navigate the choppy waters of incident response. We hope this article offers an inlet for those who want to explore it in their own environments.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Security Chaos Engineering: How to Security Differently
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Aaron Rinehart — Verica
|
||||
- **链接**: https://www.verica.io/security-chaos-engineering-how-to-security-differently/
|
||||
|
||||
## 简介
|
||||
|
||||
A quick s/security/reliability/g and this is an SRE article; the same principles apply to both fields.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:URLError: [SSL: SSLV3_ALERT_HANDSHAKE_FAILURE] ssl/tls alert handshake failure (_ssl.c:1032)
|
||||
@@ -0,0 +1,149 @@
|
||||
# SRE2AUX: How Flight Controllers were the first SREs
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Geoff White — Blameless
|
||||
- **链接**: https://www.blameless.com/blog/how-flight-controllers-were-the-first-sres
|
||||
|
||||
## 简介
|
||||
|
||||
How can we apply the tenets and principles of NASA mission controllers to our SRE work?
|
||||
|
||||
## 正文
|
||||
|
||||
Fight Fires Faster
|
||||
|
||||
The platform for teams that are serious about incident management. Resolve incidents up to 90% faster and prevent them from happening again.
|
||||
|
||||
One platform that does it all.
|
||||
|
||||
On-call, AI-enriched automation, retrospectives — you name it. Everything you need to plan smarter, respond faster, and improve your reliability.
|
||||
|
||||
Slashed Mean Time to Mitigate by 91%
|
||||
|
||||
### “FireHydrant has dramatically improved our time to respond, which in turn has dramatically improved our time to mitigation.”
|
||||
|
||||
#### Sam Burke, SRE at Backblaze
|
||||
|
||||
Prepare for the unexpected
|
||||
|
||||
Be ready for any fire with the tools and built-in best practices that empower engineers to act faster.
|
||||
|
||||

|
||||
|
||||
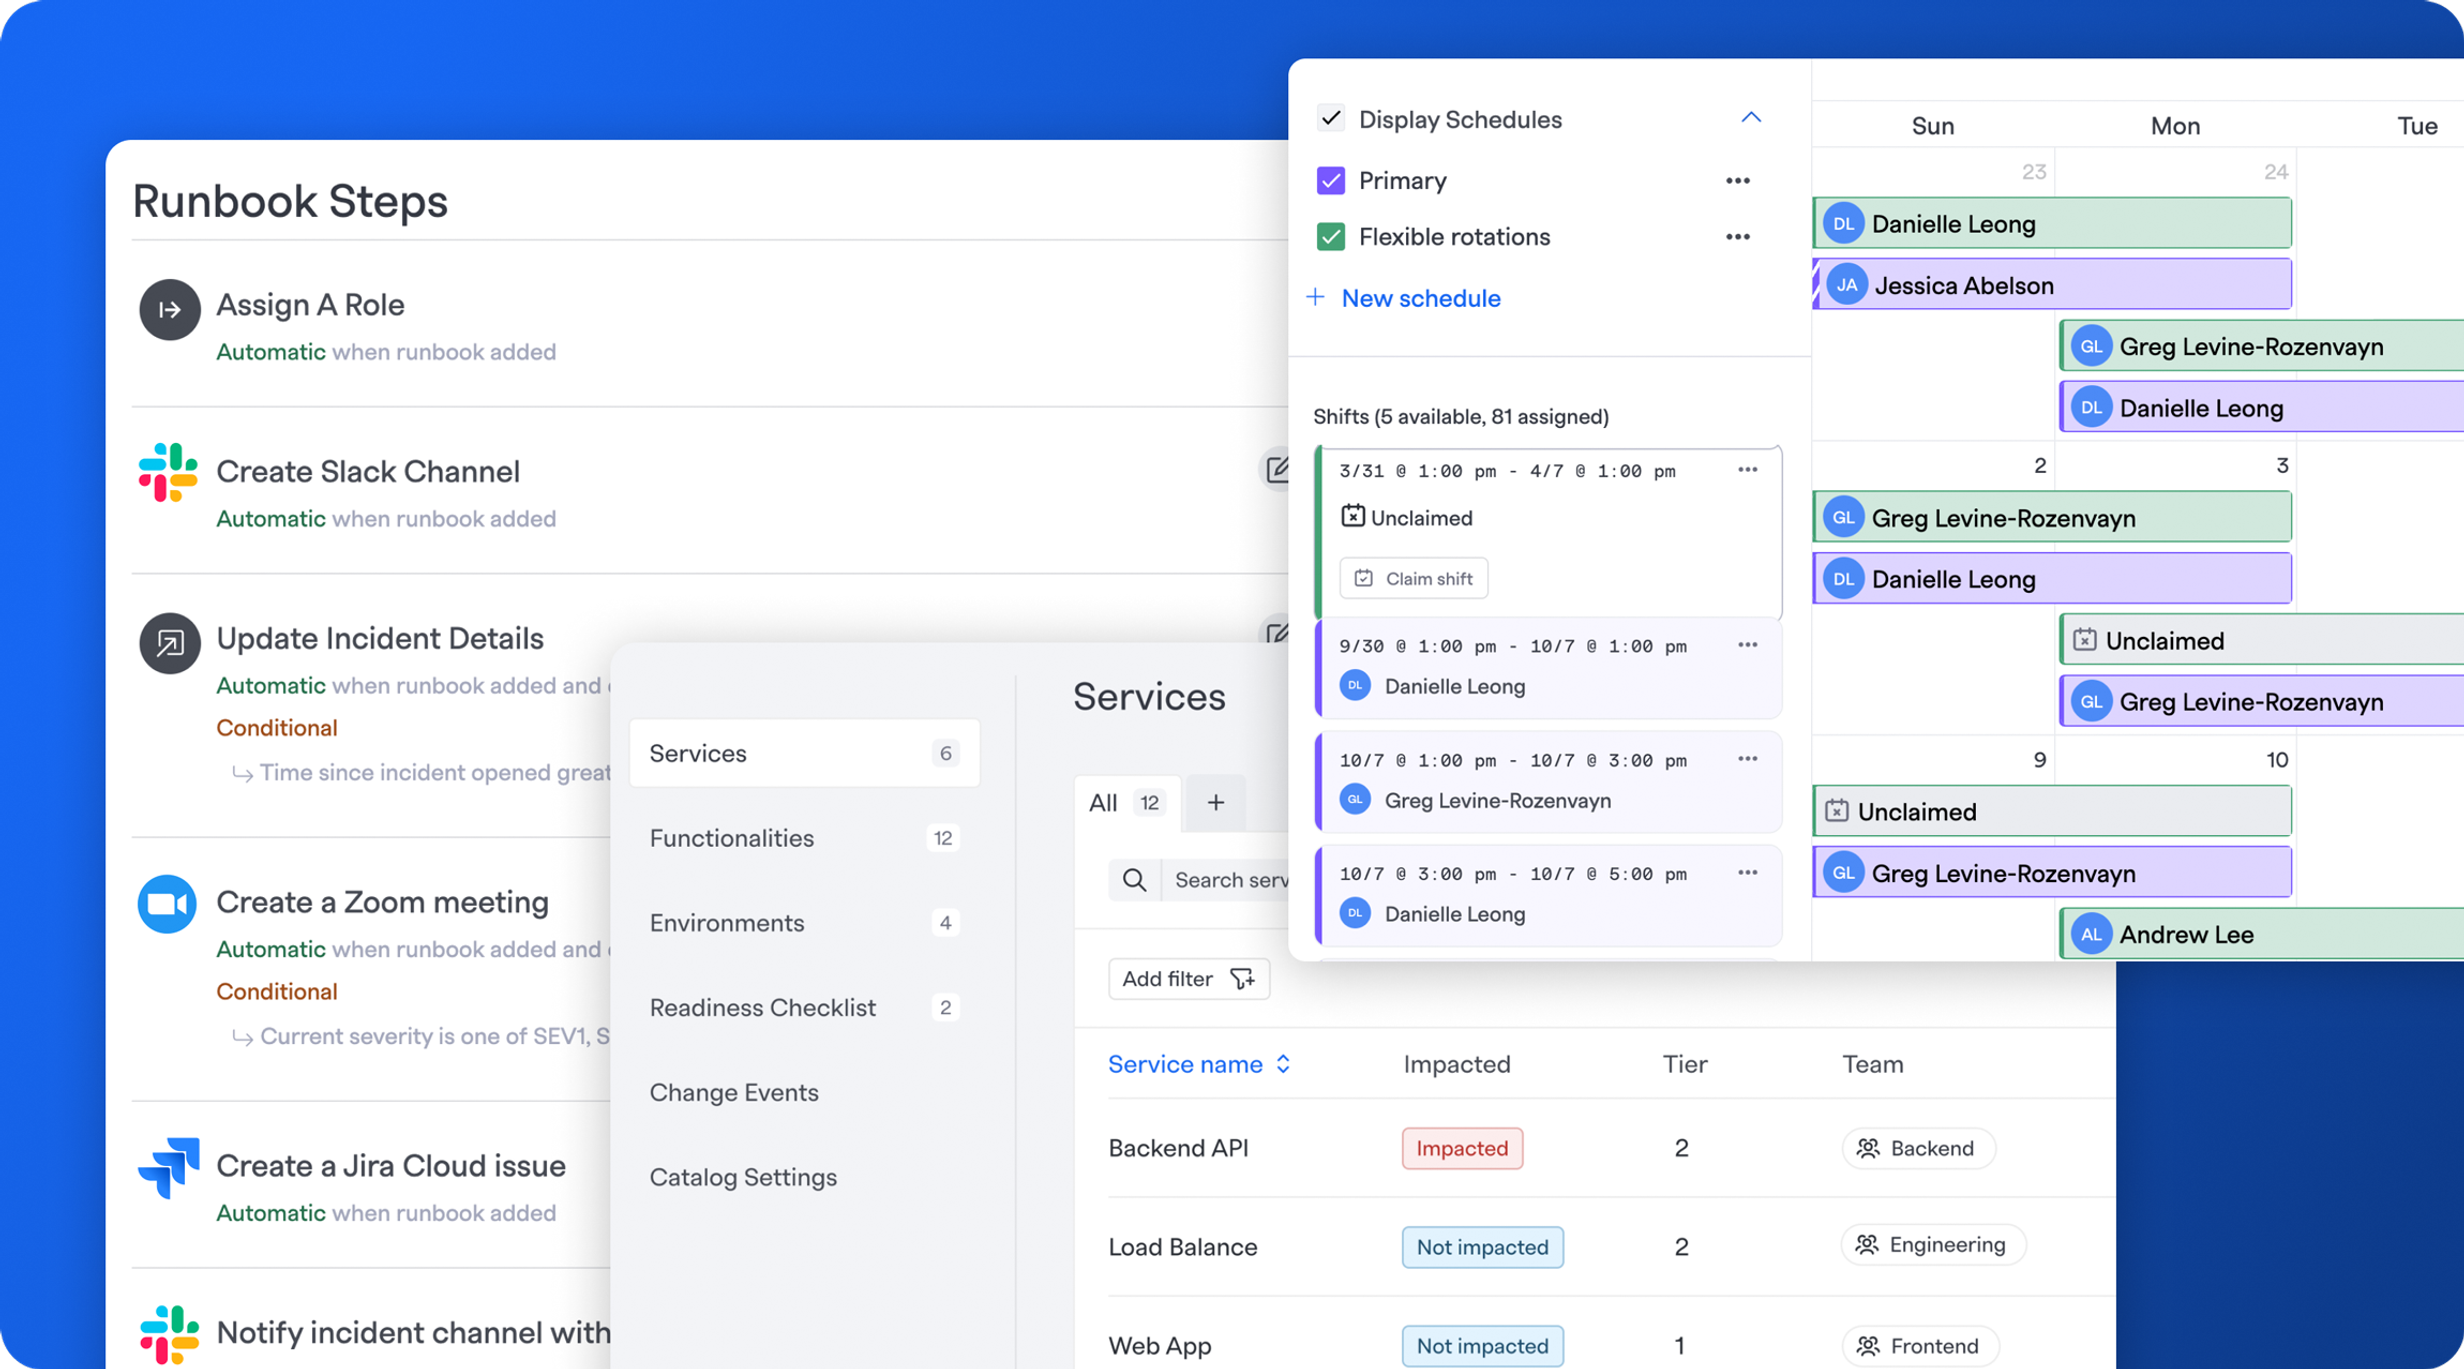
Automated Runbooks
|
||||
|
||||
Codify best practices, and respond faster every time.
|
||||
|
||||

|
||||
|
||||
On-Call & Alerting
|
||||
|
||||
Instantly know when something breaks — and who’s on it.
|
||||
|
||||

|
||||
|
||||
Service Catalog
|
||||
|
||||
Get full visibility into service ownership and dependencies.
|
||||
|
||||
|
||||
|
||||
Move fast with clear direction
|
||||
|
||||
Streamline every step of your workflow to collaborate efficiently and reduce downtime.
|
||||
|
||||

|
||||
|
||||
Seamless Collaboration
|
||||
|
||||
Resolve faster by managing incidents in Slack or Teams.
|
||||
|
||||

|
||||
|
||||
AI Insights
|
||||
|
||||
Reduce the workload with instant updates and transcripts.
|
||||
|
||||

|
||||
|
||||
Status Pages
|
||||
|
||||
Keep stakeholders informed without slowing response.
|
||||
|
||||
|
||||
|
||||
Turn data into decisions
|
||||
|
||||
Get the metrics and insights that matter — and the clarity to act on them.
|
||||
|
||||

|
||||
|
||||
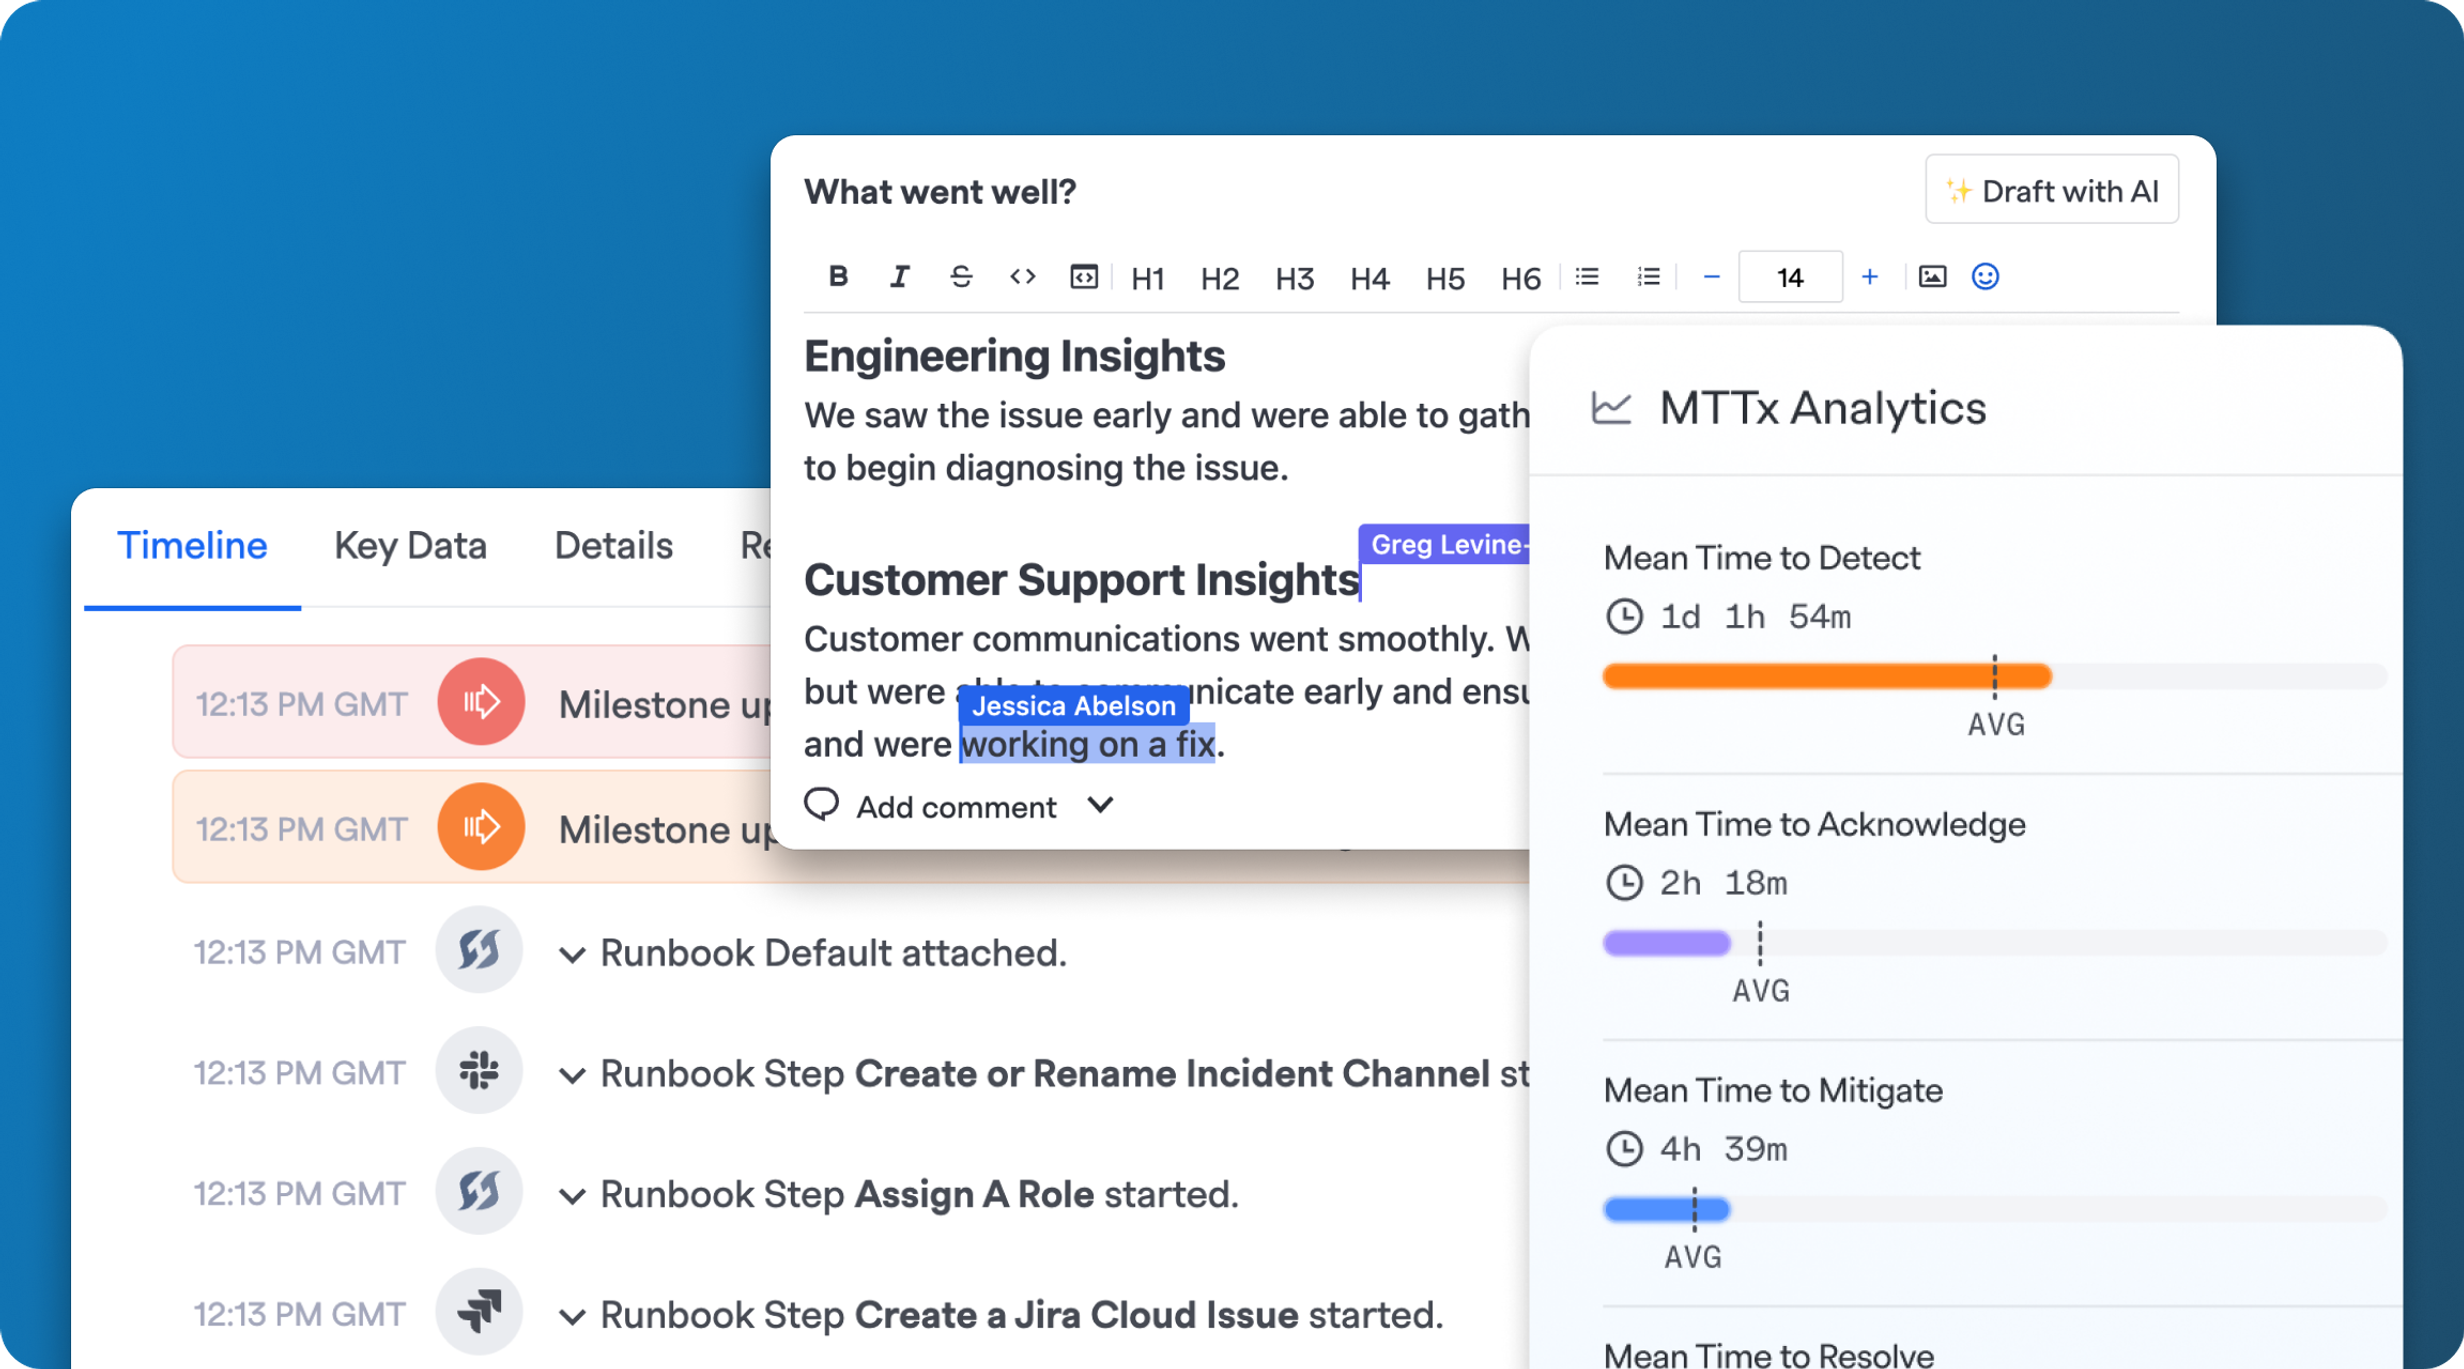
AI-Enhanced Retrospectives
|
||||
|
||||
Instant, actionable retros that actually lead to change.
|
||||
|
||||

|
||||
|
||||
Intelligent Follow-Ups
|
||||
|
||||
Action items, captured and assigned. Automatically.
|
||||
|
||||

|
||||
|
||||
Powerful Analytics
|
||||
|
||||
Track MTTx and patterns to sharpen your workflow.
|
||||
|
||||
|
||||
|
||||
AI that accelerates response and
|
||||
|
||||
simplifies the aftermath
|
||||
|
||||
FireHydrant's AI is like an extra set of hands during incidents, keeping your team focused on what matters most.
|
||||
|
||||
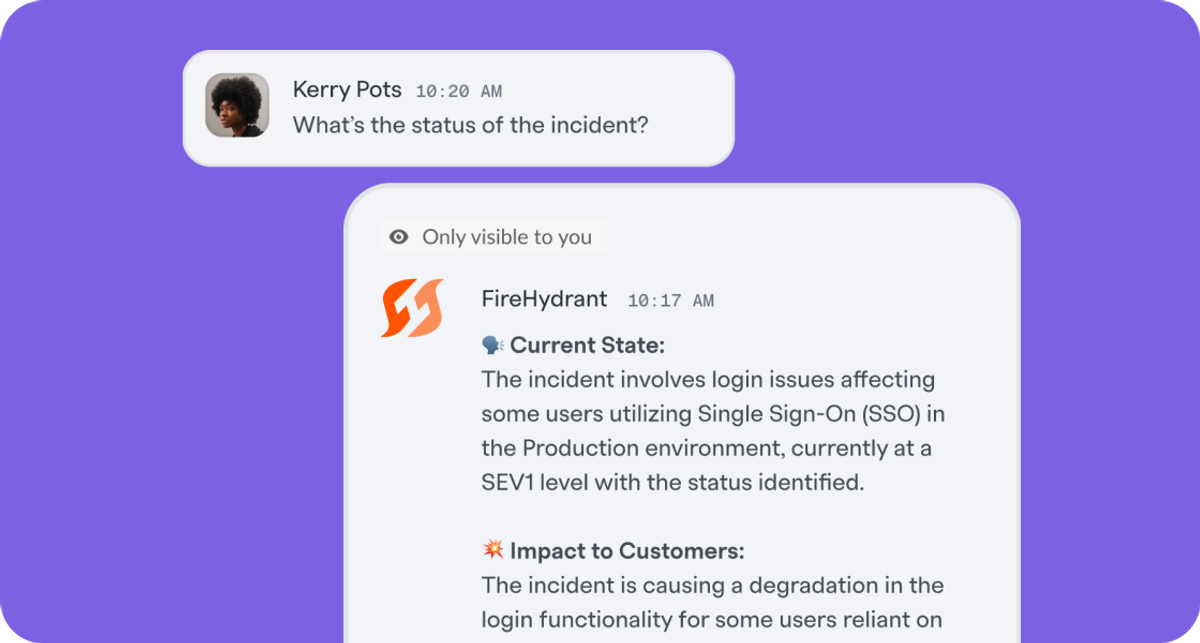
|
||||
|
||||
### Incident Summaries & Status Page Updates
|
||||
|
||||
Keep stakeholders and customers in-the-know, without the toil.
|
||||
|
||||
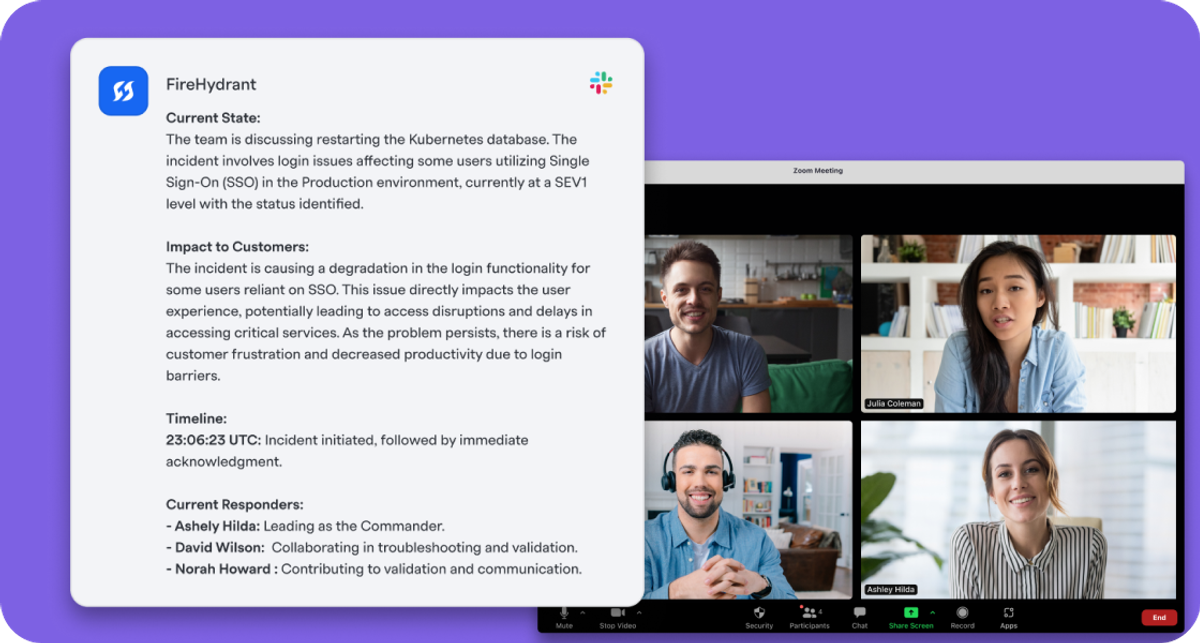
|
||||
|
||||
### Live Video Transcriptions (Zoom & Google Meet)
|
||||
|
||||
Every decision from your meeting, automatically documented.
|
||||
|
||||
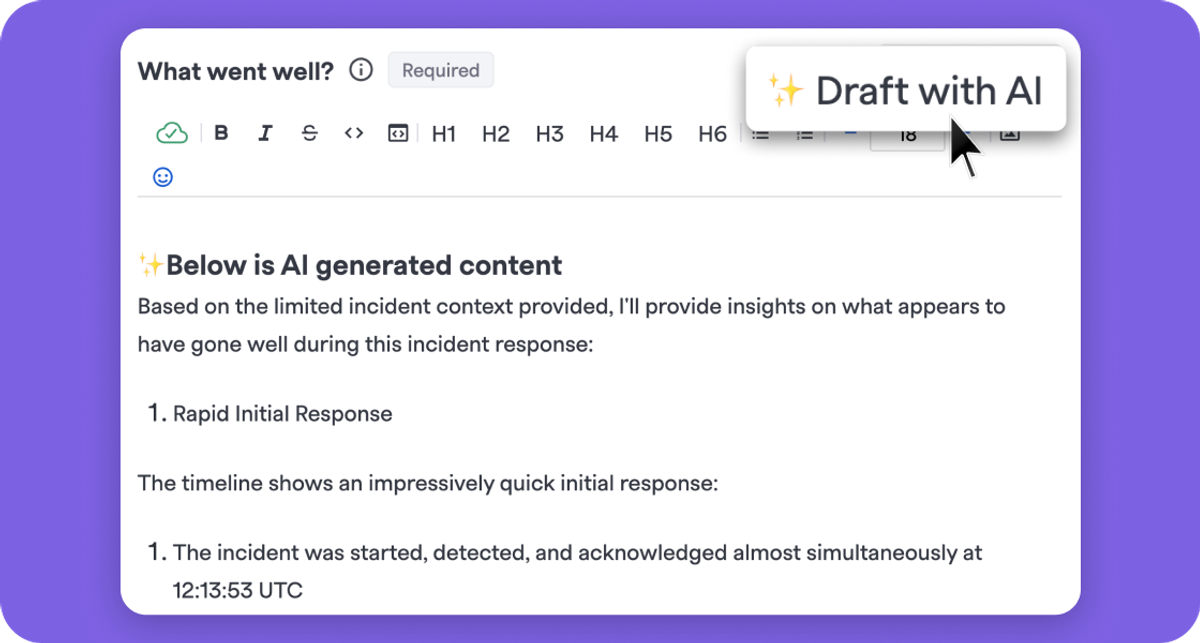
|
||||
|
||||
### AI-Enhanced Retrospectives
|
||||
|
||||
Actionable retros with all your incident data, ready in seconds.
|
||||
|
||||
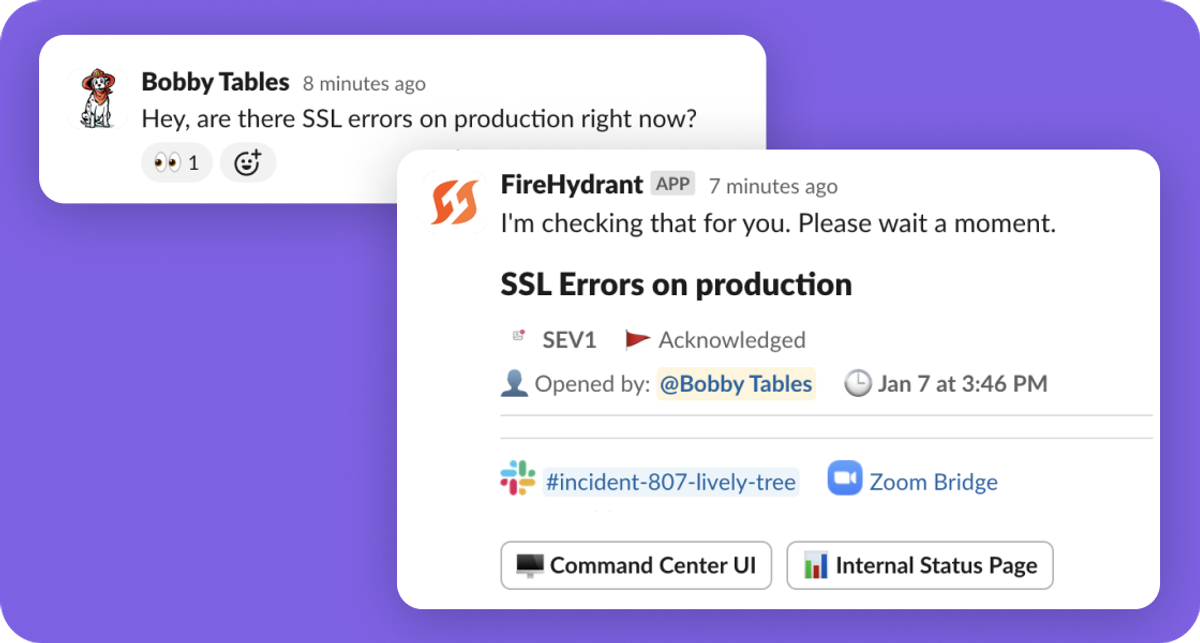
|
||||
|
||||
### Triage Channels
|
||||
|
||||
Ask anything. Get instant context to understand issues.
|
||||
|
||||
## Built by engineers who’ve been there
|
||||
|
||||
We built the tool we always wished we had. FireHydrant is fast, flexible, and built to scale — without the legacy tax.
|
||||
|
||||

|
||||
|
||||
### Enterprise-Grade
|
||||
|
||||
SOC 2 compliance, SSO, RBAC, audit logs, and SCIM — everything you need to stay secure, compliant, and in control at scale.
|
||||
|
||||

|
||||
|
||||
### Extensible
|
||||
|
||||
With 350+ API endpoints, Terraform support, and SDKs, FireHydrant adapts to your unique workflows — no rigid, one-size-fits-all limits.
|
||||
|
||||

|
||||
|
||||
### Accessible
|
||||
|
||||
Cost matters. That's why we price engineered our platform to fit for any team — without bloated costs or barriers to entry.
|
||||
@@ -0,0 +1,149 @@
|
||||
# SRE as Organizational Transformation: Lessons from Activist Organizers
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Chris Hendrix — Blameless
|
||||
- **链接**: https://www.blameless.com/blog/sre-as-organizational-transformation-lessons-from-activist-organizers
|
||||
|
||||
## 简介
|
||||
|
||||
Genius idea: we can take our lead from activists as we try to win over our organization to adopt SRE principles.
|
||||
|
||||
## 正文
|
||||
|
||||
Fight Fires Faster
|
||||
|
||||
The platform for teams that are serious about incident management. Resolve incidents up to 90% faster and prevent them from happening again.
|
||||
|
||||
One platform that does it all.
|
||||
|
||||
On-call, AI-enriched automation, retrospectives — you name it. Everything you need to plan smarter, respond faster, and improve your reliability.
|
||||
|
||||
Slashed Mean Time to Mitigate by 91%
|
||||
|
||||
### “FireHydrant has dramatically improved our time to respond, which in turn has dramatically improved our time to mitigation.”
|
||||
|
||||
#### Sam Burke, SRE at Backblaze
|
||||
|
||||
Prepare for the unexpected
|
||||
|
||||
Be ready for any fire with the tools and built-in best practices that empower engineers to act faster.
|
||||
|
||||

|
||||
|
||||
Automated Runbooks
|
||||
|
||||
Codify best practices, and respond faster every time.
|
||||
|
||||

|
||||
|
||||
On-Call & Alerting
|
||||
|
||||
Instantly know when something breaks — and who’s on it.
|
||||
|
||||

|
||||
|
||||
Service Catalog
|
||||
|
||||
Get full visibility into service ownership and dependencies.
|
||||
|
||||

|
||||
|
||||
Move fast with clear direction
|
||||
|
||||
Streamline every step of your workflow to collaborate efficiently and reduce downtime.
|
||||
|
||||

|
||||
|
||||
Seamless Collaboration
|
||||
|
||||
Resolve faster by managing incidents in Slack or Teams.
|
||||
|
||||

|
||||
|
||||
AI Insights
|
||||
|
||||
Reduce the workload with instant updates and transcripts.
|
||||
|
||||

|
||||
|
||||
Status Pages
|
||||
|
||||
Keep stakeholders informed without slowing response.
|
||||
|
||||

|
||||
|
||||
Turn data into decisions
|
||||
|
||||
Get the metrics and insights that matter — and the clarity to act on them.
|
||||
|
||||

|
||||
|
||||
AI-Enhanced Retrospectives
|
||||
|
||||
Instant, actionable retros that actually lead to change.
|
||||
|
||||

|
||||
|
||||
Intelligent Follow-Ups
|
||||
|
||||
Action items, captured and assigned. Automatically.
|
||||
|
||||

|
||||
|
||||
Powerful Analytics
|
||||
|
||||
Track MTTx and patterns to sharpen your workflow.
|
||||
|
||||

|
||||
|
||||
AI that accelerates response and
|
||||
|
||||
simplifies the aftermath
|
||||
|
||||
FireHydrant's AI is like an extra set of hands during incidents, keeping your team focused on what matters most.
|
||||
|
||||

|
||||
|
||||
### Incident Summaries & Status Page Updates
|
||||
|
||||
Keep stakeholders and customers in-the-know, without the toil.
|
||||
|
||||

|
||||
|
||||
### Live Video Transcriptions (Zoom & Google Meet)
|
||||
|
||||
Every decision from your meeting, automatically documented.
|
||||
|
||||

|
||||
|
||||
### AI-Enhanced Retrospectives
|
||||
|
||||
Actionable retros with all your incident data, ready in seconds.
|
||||
|
||||

|
||||
|
||||
### Triage Channels
|
||||
|
||||
Ask anything. Get instant context to understand issues.
|
||||
|
||||
## Built by engineers who’ve been there
|
||||
|
||||
We built the tool we always wished we had. FireHydrant is fast, flexible, and built to scale — without the legacy tax.
|
||||
|
||||

|
||||
|
||||
### Enterprise-Grade
|
||||
|
||||
SOC 2 compliance, SSO, RBAC, audit logs, and SCIM — everything you need to stay secure, compliant, and in control at scale.
|
||||
|
||||

|
||||
|
||||
### Extensible
|
||||
|
||||
With 350+ API endpoints, Terraform support, and SDKs, FireHydrant adapts to your unique workflows — no rigid, one-size-fits-all limits.
|
||||
|
||||

|
||||
|
||||
### Accessible
|
||||
|
||||
Cost matters. That's why we price engineered our platform to fit for any team — without bloated costs or barriers to entry.
|
||||
@@ -0,0 +1,281 @@
|
||||
# Atlas: Our journey from a Python monolith to a managed platform
|
||||
|
||||
- **期号**: SRE Weekly Issue #260(2021-03-07)
|
||||
- **作者**: Naphat Sanguansin and Utsav Shah — Dropbox
|
||||
- **链接**: https://dropbox.tech/infrastructure/atlas--our-journey-from-a-python-monolith-to-a-managed-platform
|
||||
|
||||
## 简介
|
||||
|
||||
This insightful observation caught my eye:
|
||||
|
||||
> It’s unnecessary overhead for a product team to plan capacity, set up good alerts and multihoming (automatically running in multiple data centers) for small, simple functionality.
|
||||
|
||||
## 正文
|
||||
|
||||
Dropbox, to our customers, needs to be a reliable and responsive service. As a company, we’ve had to scale constantly since our start, today serving more than 700M registered users in every time zone on the planet who generate at least 300,000 requests per second. Systems that worked great for a startup hadn’t scaled well, so we needed to devise a new model for our internal systems, and a way to get there without disrupting the use of our product.
|
||||
|
||||
In this post, we’ll explain why and how we developed and deployed Atlas, a platform which provides the majority of benefits of a [Service Oriented Architecture](https://en.wikipedia.org/wiki/Service-oriented_architecture), while minimizing the operational cost that typically comes with owning a service.
|
||||
|
||||
### Monolith should be by choice
|
||||
|
||||
The majority of software developers at Dropbox contribute to server-side backend code, and all server side development takes place in our server [monorepo](https://dropbox.tech/application/speeding-up-a-git-monorepo-at-dropbox-with--200-lines-of-code). We mostly use Python for our server-side product development, with more than 3 million lines of code belonging to our monolithic Python server.
|
||||
|
||||
It works, but we realized the monolith was also holding us back as we grew. Developers wrangled daily with unintended consequences of the monolith. Every line of code they wrote was, whether they wanted or not, shared code—they didn’t get to choose what was smart to share, and what was best to keep isolated to a single endpoint. Likewise, in production, the fate of their endpoints was tied to every other endpoint, regardless of the stability, criticality, or level of ownership of these endpoints.
|
||||
|
||||
In 2020, we ran a project to break apart the monolith and evolve it into a serverless managed platform, which would reduce code tangles and liberate services and their underlying engineering teams from being entwined with one another. To do so, we had to innovate both the architecture (e.g. [standardizing on gRPC](https://dropbox.tech/infrastructure/courier-dropbox-migration-to-grpc) and [using](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy) [Envoy’s g](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy)[RPC](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy)[-HTTP transcoding](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy)) and the operations (e.g. introducing autoscaling and canary analysis). This blog post captures key ideas and learnings from our journey.
|
||||
|
||||
## Metaserver: The Dropbox monolith
|
||||
|
||||
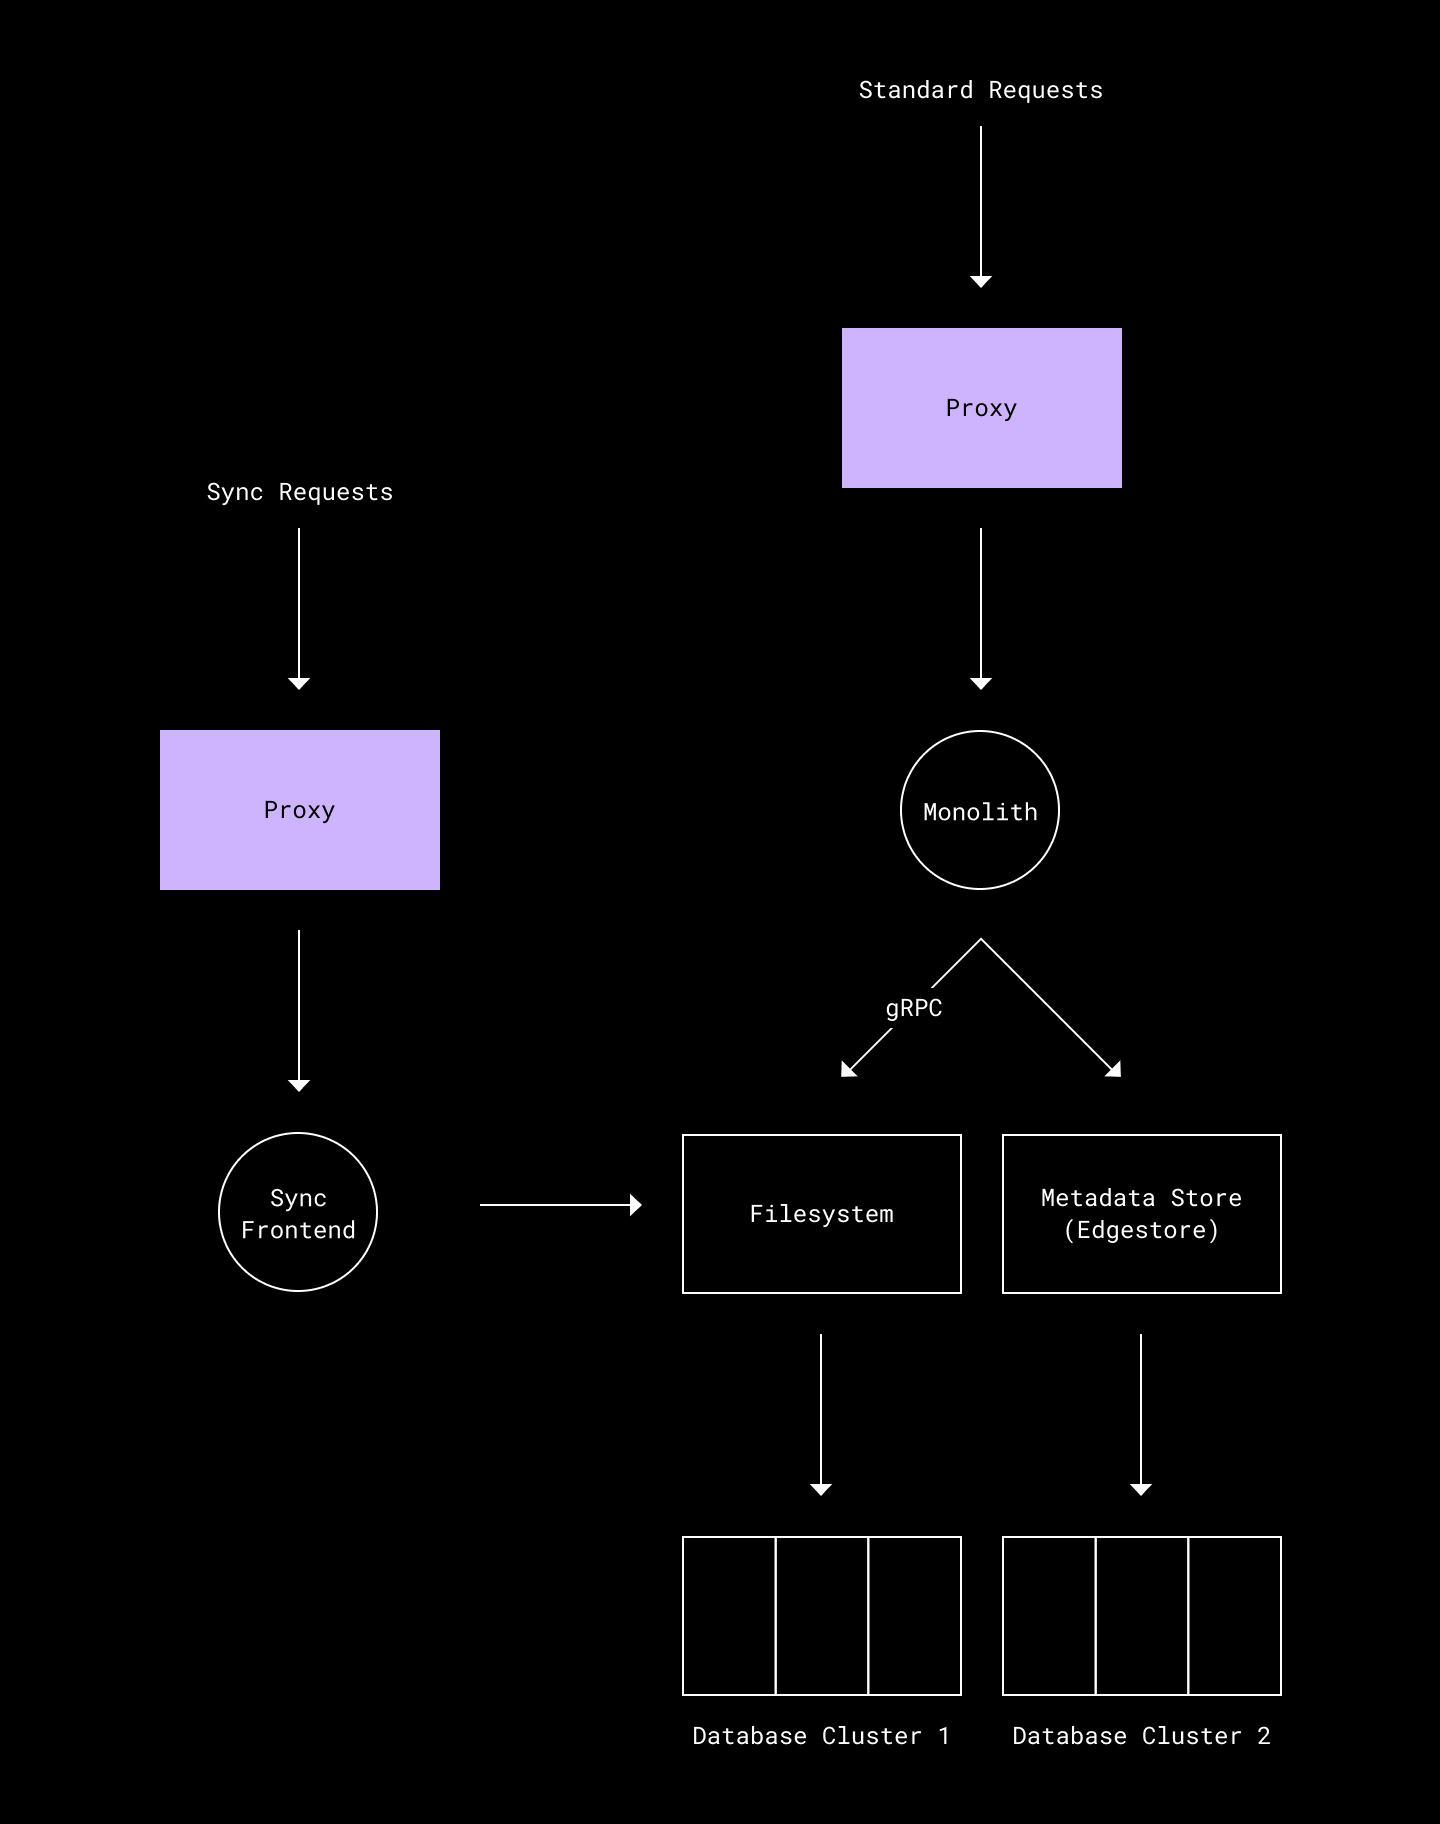
Dropbox’s internal service topology as of today can be thought of as a “solar system” model, in which a lot of product functionality is served by the monolith, but platform-level components like authentication, metadata storage, filesystem, and sync have been separated into different services.
|
||||
|
||||
About half of all commits to our server repository modify our large monolithic Python web application, Metaserver.
|
||||
|
||||
|
||||
|
||||
Extremely simplified view of existing serving stack
|
||||
|
||||
Metaserver is one of our oldest services, created in 2007 by one of our co-founders. It has served Dropbox well, but as our engineering team marched to deliver new features over the years, the organic growth of the codebase led to serious challenges.
|
||||
|
||||
### Tangled codebase
|
||||
|
||||
Metaserver’s code was originally organized in a simple pattern one might expect to see in a small open source project—library, model, controllers—with no centralized curation or guardrails to ensure the sustainability of the codebase. Over the years, the Metaserver codebase grew to become one of the most disorganized and tangled codebases in the company.
|
||||
|
||||
```
|
||||
//metaserver/controllers/ …
|
||||
//metaserver/model/ …
|
||||
//metaserver/lib/ …
|
||||
```
|
||||
Metaserver Code Structure
|
||||
|
||||
Because the codebase had multiple teams working on it, no single team felt strong ownership over codebase quality. For example, to unblock a product feature, a team would introduce import cycles into the codebase rather than refactor code. Even though this let us ship code faster in the short term, it left the codebase much less maintainable, and problems compounded.
|
||||
|
||||
|
||||
### Inconsistent push cadence
|
||||
|
||||
We push Metaserver to production for all our users daily. Unfortunately, with hundreds of developers effectively contributing to the same codebase, the likelihood of at least one critical bug being added every day had become fairly high. This would necessitate rollbacks and cherry picks of the entire monolith, and caused an inconsistent and unreliable push cadence for developers. Common best practices (for example, from [Accelerate](https://www.amazon.com/dp/B07B9F83WM/ref=dp-kindle-redirect?_encoding=UTF8&btkr=1)) point to fast, consistent deploys as the key to developer productivity. We were nowhere close to ideal on this dimension.
|
||||
|
||||
Inconsistent push cadence leads to unnecessary uncertainty in the development experience. For example, if a developer is working towards a product launch on day X, they aren’t sure whether their code should be submitted to our repository by day X-1, X-2 or even earlier, as another developer’s code might cause a critical bug in an unrelated component on day X and necessitate a rollback of the entire cluster completely unrelated to their own code.
|
||||
|
||||
### Infrastructure debt
|
||||
|
||||
With a monolith of millions of lines of code, infrastructure improvements take much longer or never happen. For example, it had become impossible to stage a rollout of a new version of an HTTP framework or Python on only non-critical routes.
|
||||
|
||||
Additionally, Metaserver uses a legacy Python framework unused in most other Dropbox services or anywhere else externally. While our internal infrastructure stack evolved to use industry standard open source systems like [gRPC](https://dropbox.tech/infrastructure/courier-dropbox-migration-to-grpc), Metaserver was stuck on a deprecated legacy framework that unsurprisingly had poor performance and caused maintenance headaches due to esoteric bugs. For example, the legacy framework only supports HTTP/1.0 while modern libraries have moved to HTTP/1.1 as the minimum version.
|
||||
|
||||
Moreover, all the benefits we developed or integrated in our internal infrastructure, like [i](https://dropbox.tech/infrastructure/monitoring-server-applications-with-vortex)[ntegrated metrics](https://dropbox.tech/infrastructure/monitoring-server-applications-with-vortex) and tracing, had to be hackily redone for Metaserver which was built atop different internal frameworks.
|
||||
|
||||
Over the past few years, we had spun up several workstreams to combat the issues we faced. Not all of them were all successful, but even those we gave up on paved the way to our current solution.
|
||||
|
||||
## SOA: the cost of operating independent services
|
||||
|
||||
We tried to break up Metaserver as part of a larger push around a Service Oriented Architecture (SOA) initiative. The goal of SOA was to establish better abstractions and separation of concerns for functionalities at Dropbox—all problems that we wanted to solve in Metaserver.
|
||||
|
||||
The execution plan was simple: make it easy for teams to operate independent services in production, then carve out pieces of Metaserver into independent services.
|
||||
|
||||
Our SOA effort had two major milestones:
|
||||
|
||||
1. Make it possible and easy to build services outside of Metaserver
|
||||
1. Extract core functionalities like identity management from the monolith and expose them via RPC, to allow new functionalities to be built outside of Metaserver
|
||||
2. Establish best practices and a production readiness process for smoothly and scalably onboarding new multiple services that serve customer-facing traffic, i.e. our live site services
|
||||
2. Break up Metaserver into smaller services owned and operated by various teams
|
||||
|
||||
The SOA effort proved to be long and arduous. After over a year and a half, we were well into the first milestone. However, the experience from executing that first milestone exposed the flaws of the second milestone. As more teams and services were introduced into the critical path for customer traffic, we found it increasingly difficult to maintain a high reliability standard. This problem would only compound as we moved up the stack away from core functionalities and asked product teams to run services.
|
||||
|
||||
### No one solution for everything
|
||||
|
||||
With this insight, we reassessed the problem. We found that product functionality at Dropbox could be divided into two broad categories:
|
||||
|
||||
- large, complex systems like all the logic around sharing a file
|
||||
- small, self-contained functionality, like the homepage
|
||||
|
||||
For example, the “Sharing” service involves stateful logic around access control, rate limits, and quotas. On the other hand, the homepage is a fairly simple wrapper around our metadata store/filesystem service. It doesn’t change too often and it has very limited day to day operational burden and failure modes. In fact, operational issues for most routes served by Dropbox had common themes, like unexpected spikes of external traffic, or outages in underlying services.
|
||||
|
||||
|
||||
This led us to an important conclusion:
|
||||
|
||||
- **Small, self contained functionality doesn’t need independently operated services.** This is why we built Atlas.
|
||||
- It’s unnecessary overhead for a product team to plan capacity, set up good alerts and multihoming (automatically running in multiple data centers) for small, simple functionality. Teams mostly want a place where they can write some logic, have it automatically run when a user hits a certain route, and get some automatic basic alerts if there are too many errors in their route. The code they submit to the repository should be deployed consistently, quickly and continuously.
|
||||
- Most of our product functionality falls into this category. Therefore, Atlas should optimize for this category.
|
||||
- Large components should continue being their own services, with which Atlas happily coexists.
|
||||
- Large systems can be operated by larger teams that sustainably manage the health of their systems. Teams should manage their own push schedules and set up dedicated alerts and verifiers.
|
||||
|
||||
## Atlas: a hybrid approach
|
||||
|
||||
With the fundamental sustainability problems we had with Metaserver, and the learning that migrating Metaserver into many smaller services was not the right solution for everything, we came up with Atlas, a managed platform for the self-contained functionality use case.
|
||||
|
||||
Atlas is a hybrid approach. It provides the user interface and experience of a “serverless” system like [AWS Fargate](https://aws.amazon.com/fargate/) to Dropbox product developers, while being backed by automatically provisioned services behind the scenes.
|
||||
|
||||
As we said, the goal of Atlas is to provide the majority of benefits of SOA, while minimizing the operational costs associated with running a service.
|
||||
|
||||
Atlas is “managed,” which means that developers writing code in Atlas only need to write the interface and implementation of their endpoints. Atlas then takes care of creating a production cluster to serve these endpoints. The Atlas team owns pushing to and monitoring these clusters.
|
||||
|
||||
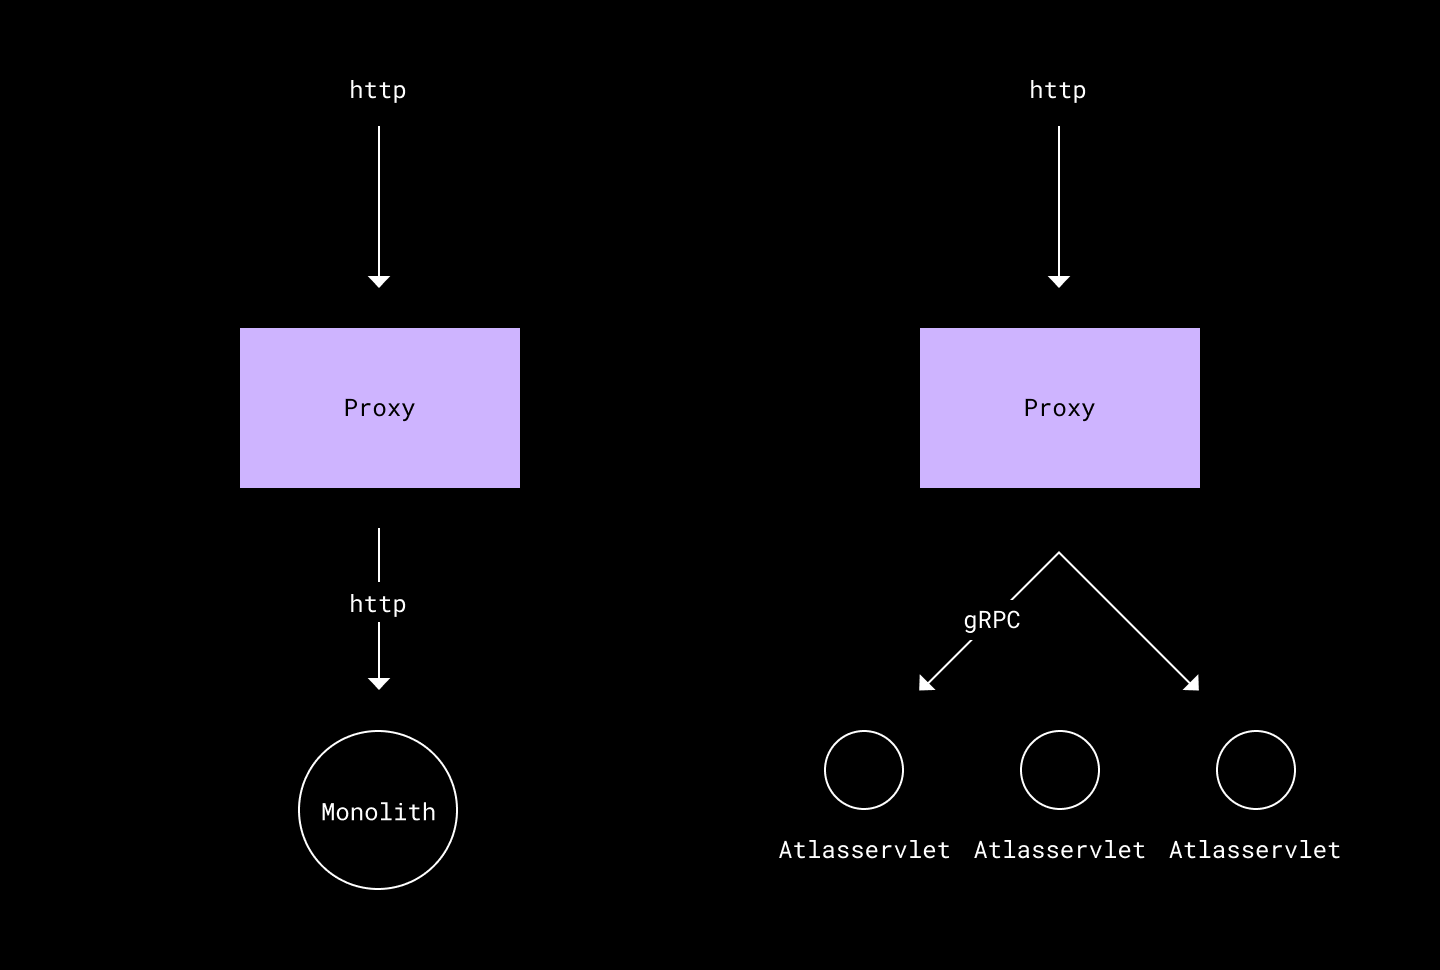
This is the experience developers might expect when contributing to a monolith versus Atlas:
|
||||
|
||||
|
||||
|
||||
Before and after Atlas
|
||||
|
||||
## Goals
|
||||
|
||||
We designed Atlas with five ideal outcomes in mind:
|
||||
|
||||
1. **Code structure improvements**
|
||||
Metaserver had no real abstractions on code sharing, which led to coupled code. Highly coupled code can be the hardest to understand and refactor, and the most likely to sprout bugs when modified. We wanted to introduce a structure and reduce coupling so that new code would be easier to read and modify.
|
||||
2. **Independent, consistent pushes**
|
||||
The Metaserver push experience is great when it works. Product developers only have to worry about checking in code which will automatically get pushed to production. However, the aforementioned lack of push isolation led to an inconsistent experience. We wanted to create a platform where teams were not blocked on push due to a bug in unrelated code, and create the foundation for teams to push their own code in the future.
|
||||
3. **Minimized operational busywork**
|
||||
We aimed to keep the operational benefits of Metaserver while providing some of the flexibility of a service. We set up automatic capacity management, automatic alerts, automatic canary analysis, and an automatic push process so that the migration from a monolith to a managed platform was smooth for product developers.
|
||||
4. **Infrastructure unification**
|
||||
We wanted to unify all serving to standard open source components like gRPC. We don’t need to reinvent the wheel.
|
||||
5. **Isolation**
|
||||
Some features like the homepage are more important than others. We wanted to serve these independently, so that an overload or bug in one feature could not spill over to the rest of Metaserver.
|
||||
|
||||
We evaluated using off-the-shelf solutions to run the platform. But in order to de-risk our migration and ensure low engineering costs, it made sense for us to continue hosting services on the same deployment orchestration platform used by the rest of Dropbox.
|
||||
|
||||
However, we decided to remove custom components, such as our custom request proxy [Bandaid](https://dropbox.tech/infrastructure/meet-bandaid-the-dropbox-service-proxy), and replace them with open source systems like [Envoy](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy) that met our needs.
|
||||
|
||||
## Technical design
|
||||
|
||||
The project involved a few key efforts:
|
||||
|
||||
**Componentization**
|
||||
|
||||
- De-tangle the codebase by feature into components, to prevent future tangles
|
||||
- Enforce a single owner per component, so new functionality cannot be tacked onto a component by a non-owner
|
||||
- Incentivize fewer shared libraries and more code sharing via RPC
|
||||
|
||||
**Orchestration**
|
||||
|
||||
- Automatically configure each component into a service in our deployment orchestration platform with <50 lines of boilerplate code
|
||||
- Configure a proxy (Envoy) to send a request for a particular route to the right service, instead of simply sending each request to a Metaserver node
|
||||
- Configure services to speak to one another in gRPC instead of HTTP
|
||||
|
||||
**Operationalization**
|
||||
|
||||
- Automatically configure a deployment pipeline that runs daily and pushes to production for each component
|
||||
- Set up automatic alerts and automatic analysis for regressions to each push pipeline to automatically pause and rollback in case of any problems
|
||||
- Automatically allocate additional hosts to scale up capacity via an autoscaler for each component based on traffic
|
||||
|
||||
Let’s look at each of these in detail.
|
||||
|
||||
### Componentization
|
||||
|
||||
**Logical grouping of routes via servlets** Atlas introduces Atlasservlets (pronounced “atlas servlets”) as a logical, atomic grouping of routes. For example, the home Atlasservlet contains all routes used to construct the homepage. The nav Atlasservlet contains all the routes used in the navigation bar on the Dropbox website.
|
||||
|
||||
In preparation for Atlas, we worked with product teams to assign Atlasservlets to every route in Metaserver, resulting in more than 200 Atlasservlets across more than 5000 routes. Atlasservlets are an essential tool for breaking up Metaserver.
|
||||
|
||||
```
|
||||
//atlas/home/ …
|
||||
//atlas/nav/ …
|
||||
//atlas/<some other atlasservlet>/ …
|
||||
```
|
||||
Atlas code structure, organized by servlets
|
||||
|
||||
Each Atlasservlet is given a private directory in the codebase. The owner of the Atlasservlet has full ownership of this directory; they may organize it however they wish, and no one else can import from it. The Atlasservlet code structure inherently breaks up the Metaserver code monolith, requiring every endpoint to be in a private directory and make code sharing an explicit choice rather than an unexpected outcome of contributing to the monolith.
|
||||
|
||||
Having the Atlasservlet codified into our directory path also allows us to automatically generate production configs that would normally accompany a production service. Dropbox uses the [Bazel](https://bazel.build/) build system for server side code, and we enforced prevention of imports through a Bazel feature called [visibility rules](https://docs.bazel.build/versions/master/visibility.html), which allows library owners to control which code can use their libraries.
|
||||
|
||||
**Breakup of import cycles** In order to break up our codebase, we had to break most of our Python import cycles. This took several years to achieve with a bunch of scripts and a lot of grunt work and refactoring. We prevented regressions and new import cycles through the same mechanism of Bazel visibility rules.
|
||||
|
||||
|
||||
## Orchestration
|
||||
|
||||
|
||||
|
||||
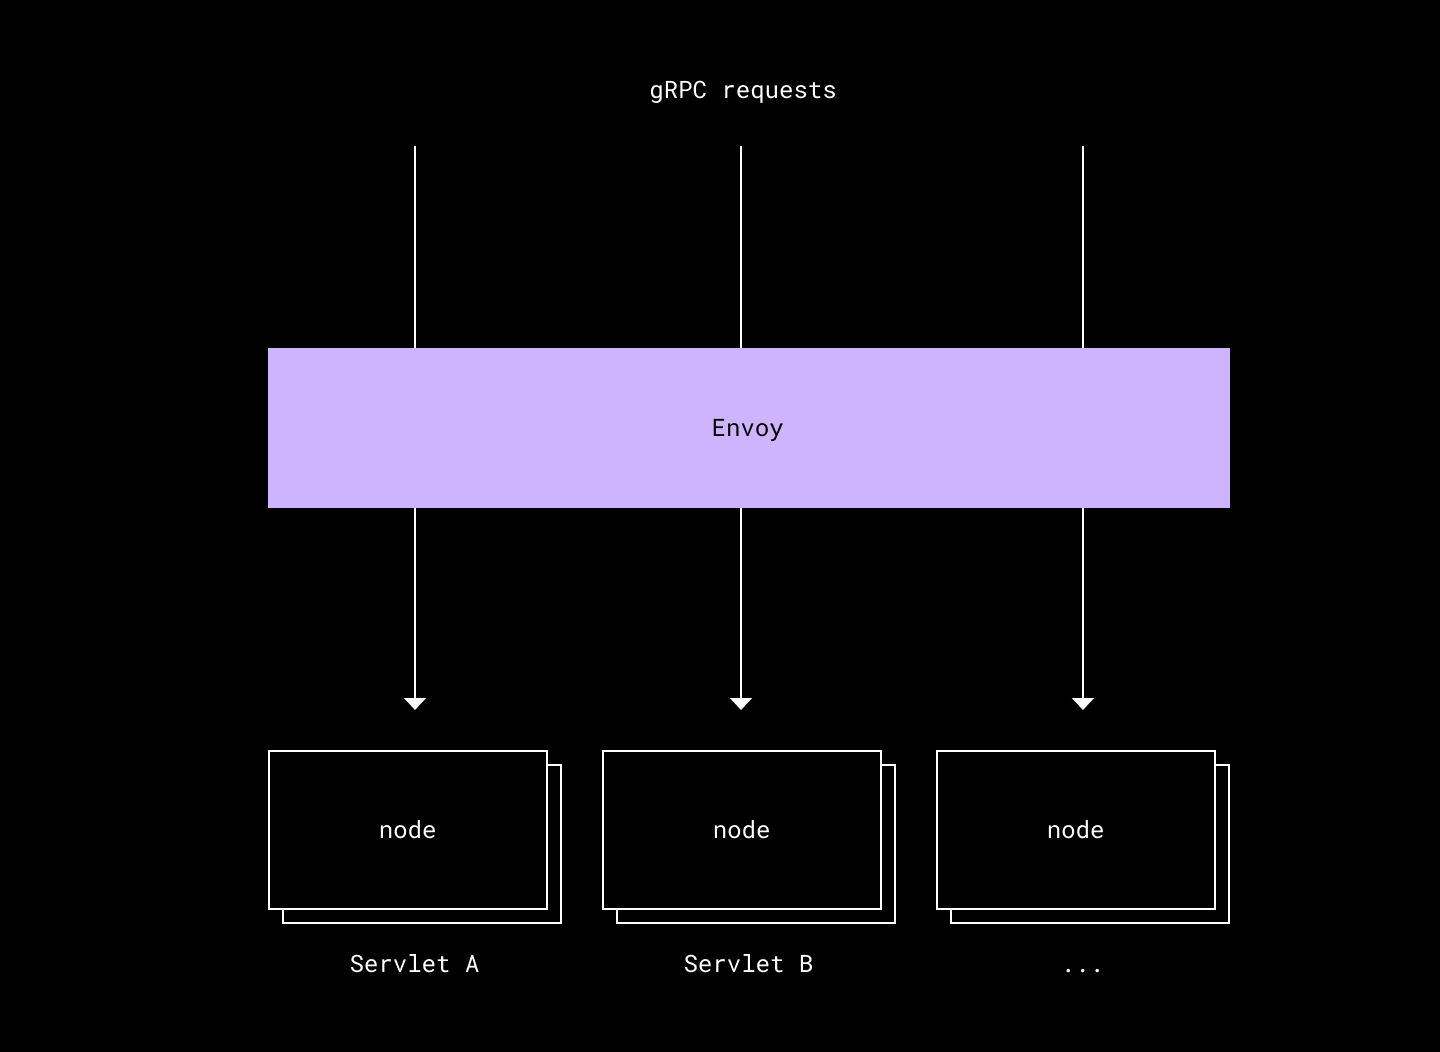
Atlas cluster strategy
|
||||
|
||||
In Atlas, every Atlasservlet is its own cluster. This gives us three important benefits:
|
||||
|
||||
- **Isolation by default**
|
||||
A misbehaving route will only impact other routes in the same Atlasservlet, which is owned by the same team anyway.
|
||||
- **Independent pushes**
|
||||
Each Atlasservlet can be pushed separately, putting product developers in control of their own destiny with respect to the consistency of their pushes.
|
||||
- **Consistency**
|
||||
Each Atlasservlet looks and behaves like any other internal service at Dropbox. So any tools provided by our infrastructure teams—e.g. periodic performance profiling—will work for all other teams’ Atlasservlets.
|
||||
|
||||
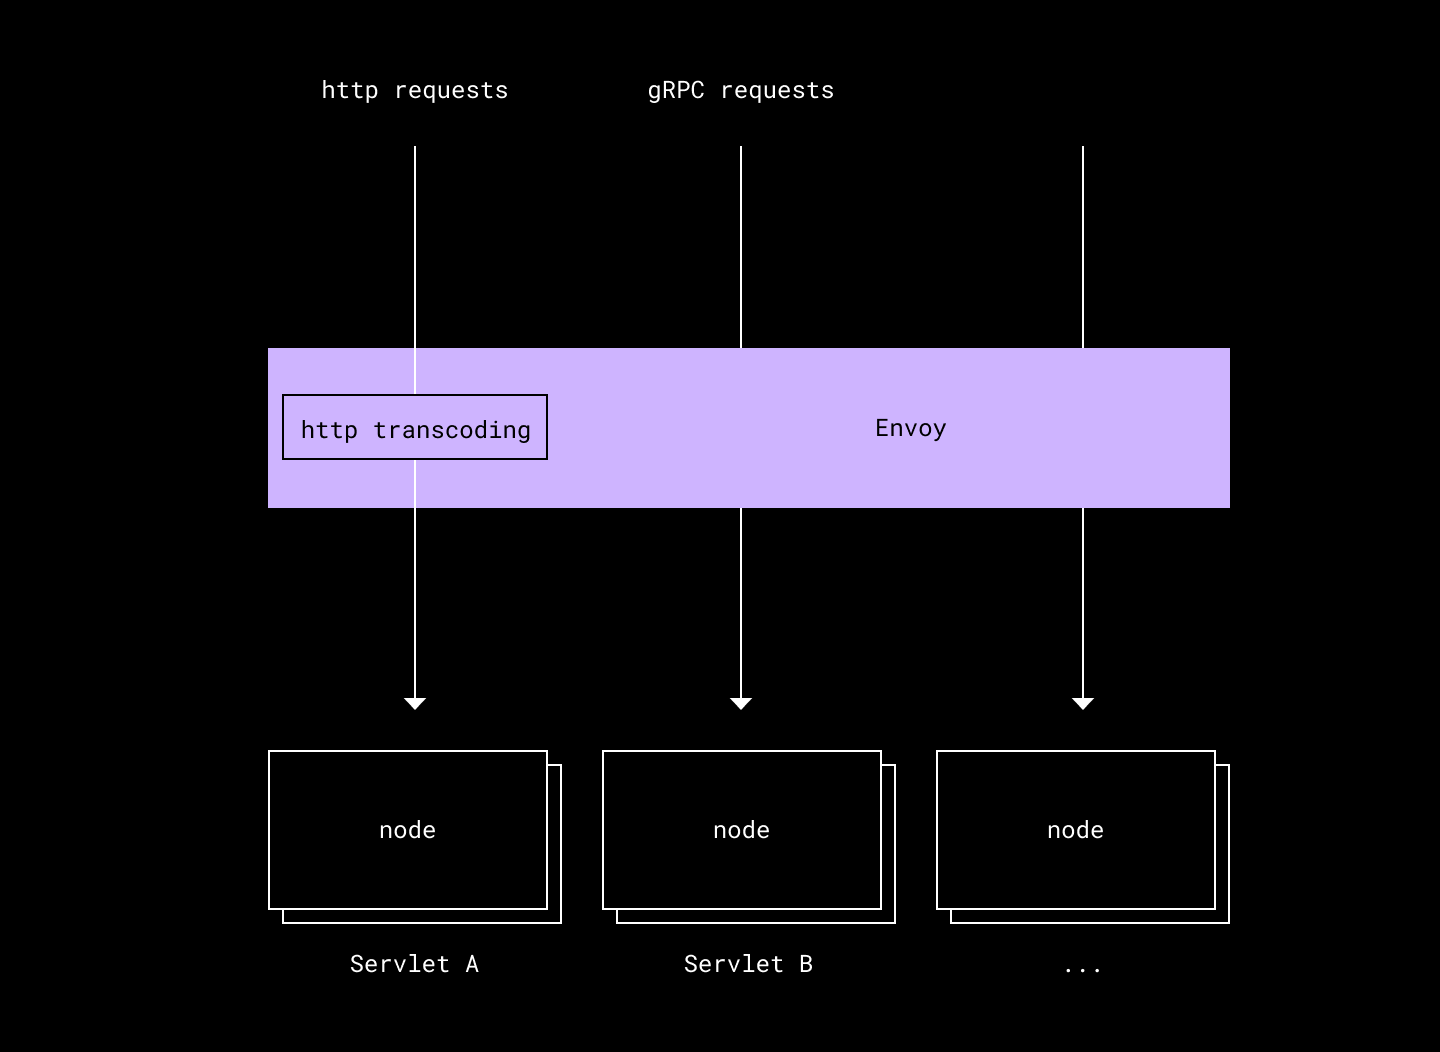
**gRPC Serving Stack** One of our goals with Atlas was to unify our serving infrastructure. We chose to standardize on gRPC, a widely adopted tool at Dropbox. In order to continue to serve HTTP traffic, we used the gRPC-HTTP transcoding feature provided out of the box in Envoy, our proxy and load balancer. You can read more about Dropbox’s adoption of
|
||||
|
||||
[gRPC](https://dropbox.tech/infrastructure/courier-dropbox-migration-to-grpc)and
|
||||
|
||||
[Envoy](https://dropbox.tech/infrastructure/how-we-migrated-dropbox-from-nginx-to-envoy)in their respective blog posts.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
http transcoding
|
||||
|
||||
In order to facilitate our migration to gRPC, we wrote an adapter which takes an existing endpoint and converts it into the interface that gRPC expects, setting up any legacy in-memory state the endpoint expects. This allowed us to automate most of the migration code change. It also had the benefit of keeping the endpoint compatible with both Metaserver and Atlas during mid-migration, so we could safely move traffic between implementations.
|
||||
|
||||
### Operationalization
|
||||
|
||||
Atlas’s secret sauce is the managed experience. Developers can focus on writing features without worrying about many operational aspects of running the service in production, while still retaining the majority of benefits that come with standalone services, like isolation.
|
||||
|
||||
The obvious drawback is that one team now bears the operational load of all 200+ clusters. Therefore, as part of the Atlas project we built several tools to help us effectively manage these clusters.
|
||||
|
||||
**Automated Canary Analysis** Metaserver (and Atlas by extension) is stateless. As a result one of the most common ways a failure gets introduced into the system is through code changes. If we can ensure that our push guardrails are as airtight as possible, this eliminates the majority of failure scenarios.
|
||||
|
||||
|
||||
|
||||
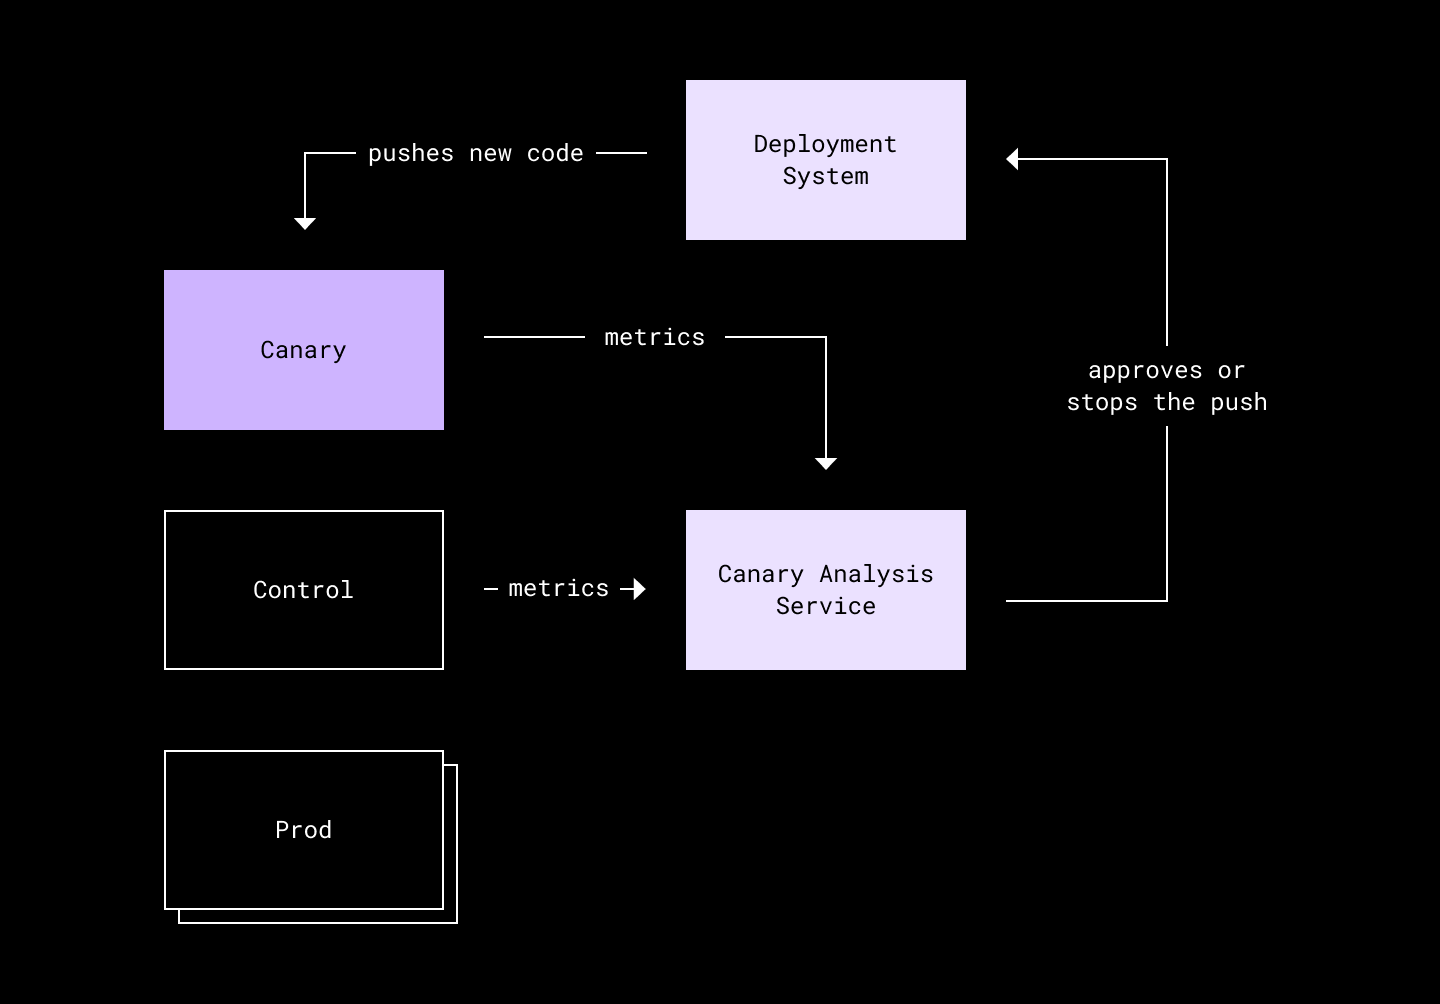
|
||||
|
||||
Canary analysis
|
||||
|
||||
We automate our failure checking through a simple canary analysis service very similar to Netflix’s [Kayenta](https://netflixtechblog.com/automated-canary-analysis-at-netflix-with-kayenta-3260bc7acc69?gi=fd8ce01f9fb6). Each Atlas service consists of three deployments: canary, control, and production, with canary and control receiving only a small random percentage of traffic. During the push, canary is restarted with the newest version of the code. Control is restarted with the old version of the code but at the same time as canary to ensure the operate from the same starting point.
|
||||
|
||||
We automatically compare metrics like CPU utilization and route availability from the canary and control deployments, looking for metrics where canary may have regressed relative to control. In a good push, canary will perform either equal to or better than control, and the push will be allowed to proceed. A bad push will be stopped automatically and the owners notified.
|
||||
|
||||
In addition to canary analysis, we also have alerts set up which are checked throughout the process, including in between the canary, control, and production pushes of a single cluster. This lets us automatically pause and rollback the push pipeline if something goes wrong.
|
||||
|
||||
Mistakes still happen. Bad changes may slip through. This is where Atlas’s default isolation comes in handy. Broken code will only impact its one cluster and can be rolled back individually, without blocking code pushes for the rest of the organization.
|
||||
|
||||
**Autoscaling and capacity planning** Atlas's clustering strategy results in a large number of small clusters. While this is great for isolation, it significantly reduces the headroom each cluster has to handle increases in traffic. Monoliths are large shared clusters, so a small RPS increase on a route is easily absorbed by the shared cluster. But when each Atlasservlet is its own service, a 10x increase in route traffic is harder to handle.
|
||||
|
||||
Capacity planning for 200+ clusters would cripple our team. Instead, we built an autoscaling system. The autoscaler monitors the utilization of each cluster in real time and automatically allocates machines to ensure that we stay above 40% free capacity headroom per cluster. This allows us to handle traffic increases as well as remove the need to do capacity planning.
|
||||
|
||||
The autoscaling system reads metrics from Envoy’s [Load Reporting Service](https://www.envoyproxy.io/docs/envoy/latest/api-v3/service/load_stats/v3/lrs.proto) and uses [request queue length](https://developer.squareup.com/blog/autoscaling-based-on-request-queuing/) to decide cluster size, and probably deserves its own blog post.
|
||||
|
||||
## Execution
|
||||
|
||||
### Stepping stones, not milestones
|
||||
|
||||
Many previous efforts to improve Metaserver had not succeeded due to the size and complexity of the codebase. This time around, we wanted to deliver value to product developers even if we didn’t succeed in fully replacing Metaserver with Atlas.
|
||||
|
||||
The execution plan for Atlas was designed with [stepping stones, not milestones](https://medium.com/@jamesacowling/stepping-stones-not-milestones-e6be0073563f) (as elegantly described by former Dropbox engineer James Cowling), so that each incremental step would provide sufficient value in case the next part of the project failed for any reason.
|
||||
|
||||
A few examples:
|
||||
|
||||
- We started off by speeding up testing frameworks in Metaserver, because we knew that an Atlas serving stack in tests might cause a regression in test times.
|
||||
- We had a constraint to significantly improve memory efficiency and reduce OOM kills when we migrated from Metaserver to Atlas, since we would be able to pack more processes per host and consume less capacity during the migration. We focused on delivering memory efficiency purely to Metaserver instead of tying the improvements to the Atlas rollout.
|
||||
- We designed a load test to prove that an Atlas MVP would be able to handle Metaserver traffic. We reused the load test to validate Metaserver’s performance on new hardware as part of a different project.
|
||||
- We backported workflow simplifications as much as feasible to Metaserver. For example, we backported some of the workflow improvements in Atlas to our web workflows in Metaserver.
|
||||
- Metaserver development workflows are divided into three categories based on the protocol: web, API, and internal gRPC. We focused Atlas on internal gRPC first to de-risk the new serving stack without needing the more risky parts like gRPC-HTTP transcoding. This in turn gave us an opportunity to improve workflows for internal gRPC independent of the remaining risky parts of Atlas.
|
||||
|
||||
### Hurdles
|
||||
|
||||
With a large migration like this, it’s no surprise that we ran into a lot of challenges. The issues faced could be their own blog post. We’ll summarize a few of the most interesting ones:
|
||||
|
||||
- The legacy HTTP serving stack contained quirky, surprising, and hard to replicate behavior that had to be ported over to prevent regressions. We powered through with a combination of reading the original source code, reusing legacy library functions where required, relying on various existing integration tests, and designing a key set of tests that compare byte-by-byte outputs of the legacy and new systems to safely migrate.
|
||||
- While splitting up Metaserver had wins in production, it was infeasible to spin up 200+ Python processes in our [integration testing framework](https://github.com/dropbox/dbx_build_tools) . We decided to merge the processes back into a monolith for local development and testing purposes. We also built heavy integration with our Bazel rules, so that the merging happens behind the scene and developers can reference Atlasservlets as regular services.
|
||||
- Splitting up Metaserver in production broke many non-obvious assumptions that could not be caught easily in tests. For example, some infrastructure services had hardcoded the identity of Metaserver for access control. To minimize failures, we designed a meticulous and incremental migration plan with a clear understanding of the risks involved at each stage, and slowly monitored metrics as we rolled out the new system.
|
||||
- Engineering workflows in Metaserver had grown organically with the monolith, arriving at a state where engineers had to page in an enormous amount of context to get the simplest work done. In order to ensure that Atlas prioritizes and solves major engineering pain points, we brought on key product developers as partners in the design, then went through several rounds of iteration to set up a roadmap that would definitively solve both product and infrastructural needs.
|
||||
|
||||
## Status
|
||||
|
||||
Atlas is currently serving more than 25% of the previous Metaserver traffic. We have validated the remaining migration in tests. We’re on a clear path to deprecate Metaserver in the near future.
|
||||
|
||||
## Conclusion
|
||||
|
||||
The single most important takeaway from this multi-year effort is that well-thought-out code composition, early in a project’s lifetime, is essential. Otherwise, technical debt and code complexity compounds very quickly. The dismantling of import cycles and decomposition of Metaserver into feature based directories was probably the most strategically effective part of the project, because it prevented new code from contributing to the problem and also made our code simpler to understand.
|
||||
|
||||
By shipping a managed platform, we took a thoughtful approach on how to break up our Metaserver monolith. We learned that monoliths have many benefits ([as](https://shopify.engineering/deconstructing-monolith-designing-software-maximizes-developer-productivity) [discussed by Shopify](https://shopify.engineering/deconstructing-monolith-designing-software-maximizes-developer-productivity)) and blindly splitting up our monolith into services would have increased operational load to our engineering organization.
|
||||
|
||||
In our view, developers don’t care about the distinction between monoliths and services, and simply want the lowest-overhead way to deliver end value to customers. So we have very little doubt that a managed platform which removes operational busywork like capacity planning, while providing maximum flexibility like fast releases, is the way forward. We’re excited to see the industry move toward such platforms.
|
||||
|
||||
### We’re hiring!
|
||||
|
||||
If you’re interested in solving large problems with innovative, unique solutions—at a company where your push schedule is more predictable : ) —please check out our [open positions](https://www.dropbox.com/jobs/teams/engineering#open-positions).
|
||||
|
||||
### Acknowledgements
|
||||
|
||||
Atlas was a result of the work of a large number of Dropboxers and Dropbox alumni, including but certainly not limited to: Agata Cieplik, Aleksey Kurkin, Andrew Deck, Andrew Lawson, David Zbarsky, Dmitry Kopytkov, Jared Hance, Jeremy Johnson, Jialin Xu, Jukka Lehtosalo, Karandeep Johar, Konstantin Belyalov, Ivan Levkivskyi, Lennart Jansson, Phillip Huang, Pranay Sowdaboina, Pranesh Pandurangan, Ruslan Nigmatullin, Taylor McIntyre, and Yi-Shu Tai.
|
||||
Reference in New Issue
Block a user