SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,49 @@
|
||||
# Avoid frostbite: Stop doing code freezes
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Robert Ross — FireHydrant
|
||||
- **链接**: https://firehydrant.io/blog/avoid-frostbite-stop-doing-code-freezes/
|
||||
|
||||
## 简介
|
||||
|
||||
It’s that time of year again, but maybe it’s time to rethink that code freeze.
|
||||
|
||||
## 正文
|
||||
|
||||
## Avoid frostbite: Stop doing code freezes
|
||||
|
||||
A code freeze is intentionally halting changes to your codebase and environments in an effort to reduce the risk of an outage.On the surface, pausing on deployments feels like a logical solution to preventing incidents. Unfortunately, this isn't the case.
|
||||
|
||||
[Robert Ross](https://firehydrant.io/authors/robert-ross/)
|
||||
|
||||
|
||||
|
||||
As the holiday season aggressively approaches I want to perform a public service announcement for everyone toying with the idea of a code freeze for the holidays: please don't. It’s getting cold outside and the season of peppermint mochas is upon us, which might get you thinking about putting a code freeze in place for the holidays. A Word of warning: instituting a code freeze may have unintended consequences.
|
||||
|
||||
A code freeze is intentionally halting changes to your codebase and environments in an effort to reduce the risk of an outage. On the surface, pausing on deployments feels like a logical solution to preventing incidents. Because most incidents are caused by some change, such as a code deployment, config change, etc., it stands to reason that a code freeze reduces the chances of an outage.
|
||||
|
||||
The truth is, incidents are inevitable. Code freezes ultimately do not lead to a decrease in incidents but will shift the incidents that you do have to unexpected places. Sometimes these incidents are so hard to diagnose that it will take longer to resolve them, and no one likes interruptions during a delicious turkey dinner.
|
||||
|
||||
#### Negative space is harder to comprehend#negative-space-is-harder-to-comprehend
|
||||
|
||||
In the absence of regular deploys, an incident can and will occur. It might be something straightforward like a memory leak that were obscured by the frequency of your deploys. But there are ones where you have no idea why the application with no recent changes has suddenly started to misbehave.
|
||||
|
||||
Let’s take a trip with the Ghost of Christmas Past. I was responsible for a Rails application that had stalled and all requests were timing out during the holiday season. The effects were felt by everyone in the whole company and a SEV1 incident was immediately declared. We were in a code freeze, so what on earth happened?
|
||||
|
||||
It became apparent that our application was running Postgres queries where their runtime suddenly ballooned, even for simple `SELECT` statements. It took hours for us to unravel what was really happening. Was an index missing? Are there connectivity problems to the database? Do we have a noisy neighbor? Based on our experience (we’d had those incidents in the past, who hasn't?), we couldn't quickly comprehend that *not deploying* the application was the final Jenga piece in this complex incident.
|
||||
|
||||
I'll make the story short. Our Rails application used a version of ActiveRecord that did not create prepared statements correctly for queries that involved date ranges (`WHERE created_at IS BETWEEN ? AND ?`). The way that Postgres works, our application was suddenly creating thousands and thousands of prepared statements for hundreds of database connections. Postgres stores prepared statements per connection in memory, and eventually... the database started swapping because it ran out of memory.
|
||||
|
||||
We *never* encountered this memory leak because we always released the resources by, you guessed it, deploying.
|
||||
|
||||
#### The January deploy frenzy#the-january-deploy-frenzy
|
||||
|
||||
Just because you’ve implemented a code freeze doesn't mean your team has stopped building and working on projects. Plenty of work is happening and being held on staging or in unmerged pull requests. When the first working day of January rolls around, absolute chaos can ensue as everyone starts the merge fire sale.
|
||||
|
||||
The log-jammed deploys going out in rapid succession are even more likely to cause an incident because now you have a substantial amount of new code that hasn't been in a production environment. Shipping smaller changes on a regular basis yields more stability than massive changesets. Rapidly changing your deployment cadence twice brings your system into a state that your system has never operated within, will your CI/CD pipeline hold up? What if you need to rollback a change from three merges ago? The sudden onslaught of production changes are far more likely to cause damage than staying the course and never stopping deploys at all.
|
||||
|
||||
#### Your current reliability is based on your current process#your-current-reliability-is-based-on-your-current-process
|
||||
|
||||
Everyone is always striving for a more reliable system. I'm not convinced that we're so dissatisfied with our current reliability that stopping deployments will solve our problems during our busiest seasons. This holiday season why not enjoy new deployments and that tasty peppermint mocha.
|
||||
|
||||
"Speed has never killed anyone. Suddenly becoming stationary, that's what gets you."
|
||||
@@ -0,0 +1,77 @@
|
||||
# 5 ways incidents made me a better engineer
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Lisa Karlin Curtis — incident.io
|
||||
- **链接**: https://incident.io/blog/incidents-made-me-a-better-engineer
|
||||
|
||||
## 简介
|
||||
|
||||
This article really gets to the heart of why I love a good incident. I mean, obviously, I want to minimize, incidents. I swear.
|
||||
|
||||
## 正文
|
||||
|
||||
November 16, 2021 — 5 min read
|
||||
|
||||
Incidents are a great opportunity to gather both context and skill. Understanding the [incident response lifecycle](https://incident.io/blog/what-is-the-incident-response-process) helps teams solve unexpected and challenging problems more effectively.
|
||||
|
||||
In my career, I've found incidents can be a great accelerator - for both myself and others around me. It was after leading my first incident at GoCardless that I started to feel really comfortable in the codebase and the team - this is what [building a culture of incident response](https://incident.io/blog/building-a-culture-of-incident-response) does for everyone. I had the same experience joining [incident.io](https://incident.io) (yes we do have incidents, and yes it is quite 🤯).
|
||||
|
||||
Incidents often occur at the edges of teams. That makes them a great chance to learn about stuff that isn't in your day-to-day remit.
|
||||
|
||||
The obvious example for me is infrastructure: at GoCardless we had an infrastructure group who provided a platform for us to deploy our services. I didn't interact with the infrastructure directly much in my first few months, so didn't have a strong mental model of how any of it fit together. That was a huge limitation on the kinds of problems I could solve. I couldn't make good decisions about how to best use our database, or how to manage asynchronous work, as I didn't understand the trade-offs.
|
||||
|
||||
Watching people solve incidents was the entrypoint I needed to start investigating and understanding our infrastructure, and how it connected to my day-to-day trade-offs.
|
||||
|
||||
Incidents are usually caused by (or manifest in) the most difficult parts of the systems we interact with. Seeing multiple incidents impact the same component is great way to learn about that component, while simultaneously signalling that understanding the component will be valuable.
|
||||
|
||||
I've been introduced to a number of domain areas via incidents including database replication (often the culprit), quorum (terrifying) and DNS (a classic). After getting some initial context during an incident, I could then spend some time reading about these concepts with confidence that it would prove useful.
|
||||
|
||||
We're not perfect: our job is hard and our code is very likely to go wrong at some point. Instead of trying to write perfect code, incidents have shown me that it's more important to make code that fails in safe ways. This includes:
|
||||
|
||||
- Making code alert loudly and clearly if it sees something that 'can't happen' (famous last words). Ideally, the alert should be easy to trace to a code comment, doc or commit message explaining why (when you wrote the code) you didn't think this would happen.
|
||||
- Keep the blast radius for failures as small as possible: think carefully about what should be considered 'critical' for a given request, and get everything else out of the way. Being unable to log a user tracking event should never degrade the customer experience.
|
||||
|
||||
While it's possible to read this stuff in textbooks, seeing the impact of these choices in real incidents is what taught me how to put this advice into practise.
|
||||
|
||||
I've been in many incidents where a graph or set of log lines has been the key bit of information to help diagnose the problem. It's also usually what tells us that the incident is over. Finding components with poor observability can be really stressful: it's like someone blindfolding you and asking you to find the front door. Possible, but not fun or efficient.
|
||||
|
||||
Watching more experienced colleagues use [incident response tools](https://incident.io/incident-response-slack) and observability dashboards, and then using them myself, taught me how to get the information I needed quickly. Once you understand how to use the information that's already there, it's easier to understand what other information would be useful when working on other projects.
|
||||
|
||||
Incidents help you map your [incident response team](https://incident.io/blog/how-to-structure-incident-response-teams) and meet people outside your day-to-day circle. Many of the colleagues I respected, valued and relied on most were not people I worked with day-to-day. It's a great change to find people who have different skill sets from your usual team mates. Maybe there's someone who knows lots about a particular technology, or someone who is a really great teacher. Having a network of talented people I could ask for advice has been the single most impactful accelerator for my growth.
|
||||
|
||||
- Get involved in incidents from day one! Even if you’re only at the very start of your career.
|
||||
- Be respectful of other people's time and situation. Observe quietly at first, note down questions to ask later.
|
||||
- Be honest with yourself and others about what you can and can't do alone. [Psychological safety in incident management](https://incident.io/blog/psychological-safety-in-incident-management) means it's safe to say "I want a pair" or "I need help." That's a great way to learn, but depending on the situation might not be appropriate.
|
||||
|
||||
Lisa Karlin Curtis
|
||||
|
||||
Technical Lead
|
||||
|
||||
Our rate limiter depends on Valkey. If Valkey goes down we fail open and stop limiting which isn't good enough for our platform. As an intern, I built per-pod in-memory top-k buffers so we keep rate limiting even with the backing store gone.
|
||||
|
||||
Anthony Oparaocha
|
||||
|
||||
September 2, 2026
|
||||
|
||||
Our entire event-driven platform ran through a single message broker, which made it a single point of failure. So we added a second one. This is the story of building an event load balancer, the queuing theory behind it, and the final chaos test where we turned off Pub/Sub in production and nobody noticed.
|
||||
|
||||
Patrick Hamann
|
||||
|
||||
+
|
||||
|
||||
Mike Fisher
|
||||
|
||||
August 11, 2026
|
||||
|
||||
Our learnings from implementing a product-wide read replica migrations, including some useful patterns for routing queries to replica and primary
|
||||
|
||||
Johanna Larsson
|
||||
|
||||
July 21, 2026
|
||||
|
||||
Ready for modern incident management? Book a call with one of our experts today.
|
||||
|
||||
- All-in-one incident management
|
||||
- Our unmatched speed of deployment
|
||||
- Why we’re loved by users and easily adopted
|
||||
- How we work for the whole organization
|
||||
@@ -0,0 +1,13 @@
|
||||
# Root Cause is for Plants, Not Software
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Courtney Nash — Verica
|
||||
- **链接**: https://www.verica.io/blog/root-cause-is-for-plants-not-software/
|
||||
|
||||
## 简介
|
||||
|
||||
This article draws on incident reports from The VOID to show how root cause analysis can be problematic.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:URLError: [SSL: SSLV3_ALERT_HANDSHAKE_FAILURE] ssl/tls alert handshake failure (_ssl.c:1032)
|
||||
@@ -0,0 +1,13 @@
|
||||
# How to Perform Incident Post-mortems: Identify Root Cause With “Five Whys”
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Søren Pedersen — Dzone
|
||||
- **链接**: https://dzone.com/articles/how-to-perform-incident-post-mortems-identify-root
|
||||
|
||||
## 简介
|
||||
|
||||
It’s interesting to read this article after reading the previous one. In the “my car won’t start”, I found myself immediately wondering, why was the vehicle not maintained? What factors contributed to that?
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 410
|
||||
@@ -0,0 +1,186 @@
|
||||
# The five phases of organizational reliability
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Google
|
||||
- **链接**: https://cloud.google.com/blog/products/devops-sre/the-five-phases-of-organizational-reliability
|
||||
|
||||
## 简介
|
||||
|
||||
These are the “phases”, although they stress that aiming for Visionary doesn’t make sense for all organizations.
|
||||
|
||||
> AbsentReactiveProactiveStrategicVisionary
|
||||
|
||||
## 正文
|
||||
|
||||
# What’s your org’s reliability mindset? Insights from Google SREs
|
||||
|
||||
##### Google Site Reliability Engineering team
|
||||
|
||||
*Editor’s note: There’s more to ensuring a product’s reliability than following a bunch of prescriptive rules. Today, we hear from some Google SREs—Vartika Agarwal, Senior Technical Program Manager, Development; Tracy Ferrell, Senior SRE Manager; Mahesh Palekar, Director SRE; and Magi Agrama, Senior Technical Program Manager, SRE—about how to evaluate your team’s current reliability mindset, and what you want it to be.*
|
||||
|
||||
Having a reliable software product can improve users’ trust in your organization, the effectiveness of your development processes, and the quality of your products overall. More than ever, product reliability is front and center, as outages negatively impact customers and their businesses. But in an effort to develop new features, many organizations limit their reliability efforts to what happens after an outage, and tactically solve for the immediate problems that sparked it. They often fail to realize that they can move quickly while still improving their product’s reliability.
|
||||
|
||||
At Google, we’ve given a lot of thought to product reliability—and several of its aspects are well understood, for example product or system design. What people think about less is the culture and the mindset of the organization that creates a reliable product in the first place. We believe that the reliability of a product is a property of the architecture of its system, processes, culture, as well as the mindset of the product team or organization that built it. In other words, reliability should be woven into the fabric of an organization, not just the result of a strong design ethos.
|
||||
|
||||
In this blog post, we discuss the lessons we’ve learned relevant to organizational or product leads who have the ability to influence the culture of the entire product team, from (but not limited to) engineering, product management, marketing, reliability engineering, and support organizations.
|
||||
|
||||
### Goals
|
||||
|
||||
Reliability should be woven into the fabric of how an organization executes. At Google, we’ve developed a terminology to categorize and describe your organization’s reliability mindset, to help you understand how intentional your organization is in this respect. Our ultimate goal is to help you improve and adopt product reliability practices that will permeate the ethos of the organization.
|
||||
|
||||
By identifying these reliability phases, we do not mean to offer a prescriptive list of things to do that will improve your product’s reliability. Nor should they be read as a set of mandated principles that everyone should apply, or be used to publicly label a team, spurring competition between teams. Rather, leaders should consider these phases as a way to help them develop their team’s culture, on the road to sustainably building reliable products.
|
||||
|
||||
### The organizational reliability continuum
|
||||
|
||||
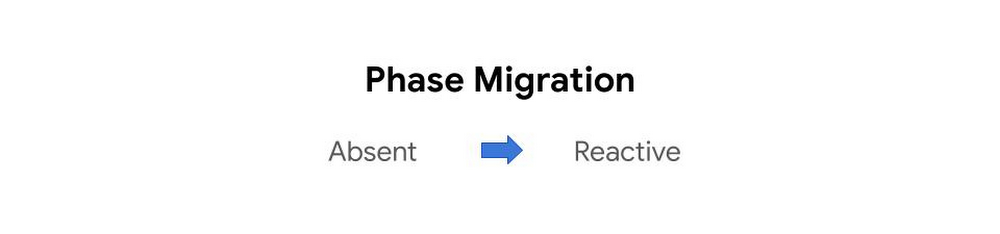
Based on our observations here at Google, there are five basic stages of organizational reliability, and they are based on the classic organizational model of absent, reactive, proactive, strategic and visionary. These phases describe the mindset of an organization at a point in time, and each one of them is characterized by a series of attributes, and is appropriate for different classes of workloads.
|
||||
|
||||
Absent: Reliability is a secondary consideration for the organization.
|
||||
|
||||
- A feature launch is the key organizational metric and is the focus for incentives
|
||||
- The majority of issues are found by users or testers. This organization is not aware of their long-term reliability risks.
|
||||
- Developer velocity is rarely exchanged for reliability.
|
||||
|
||||
*This reliability phase maybe appropriate for products and projects that are still under development.*
|
||||
|
||||
**Reactive****:** Responses to reliability issues/risks are tied to recent outages with sporadic follow-through and rarely are there longer-term investments in fixing system issues.
|
||||
|
||||
- Teams have some reliability metrics defined and react when required.
|
||||
- They write postmortems for outages and create action items for tactical fixes.
|
||||
- Reasonable availability is maintained through heroic efforts by a few individuals or teams
|
||||
- Developer productivity is throttled due to a temporary shift in priority on reliability work due to outages. Feature development may be frozen for a short period of time.
|
||||
|
||||
*This level is appropriate for products/projects in pre-launch or in a stable long-term maintenance phase.*
|
||||
|
||||
**Proactive:** Potential reliability risks are identified and addressed through regular organizational processes.
|
||||
|
||||
- Risks are regularly reviewed and prioritized.
|
||||
- Teams proactively manage dependencies and review their reliability metrics (SLOs)
|
||||
- New designs are assessed for known risks and failure modes early on. Graceful degradation is a basic requirement.
|
||||
- The business understands the need to continuously invest in reliability and maintain its balance with developer velocity.
|
||||
|
||||
*Most services/products should be at this level; particularly if they have a large blast radius or are critical to the business.*
|
||||
|
||||
**Strategic:**Organizations at this level manage classes of risk via systemic changes to architectures, products and processes.
|
||||
|
||||
- Reliability is inherent and ingrained in how the organization designs, operates and develops software. Reliability is systemic.
|
||||
- Complexity is addressed holistically through product architecture. Dependencies are constantly reduced or improved.
|
||||
- The cross-functional organization can sustain reliability and developer velocity simultaneously.
|
||||
- Organizations widely celebrate quality and stability milestones.
|
||||
|
||||
*This level is appropriate for services and products that need very high availability to meet business-critical needs.*
|
||||
|
||||
**Visionary:**The organization has reached the highest order of reliability and is able to drive broader reliability efforts within and outside the company (e.g., writing papers, sharing knowledge), based on their best practices and experiences.
|
||||
|
||||
- Reliability knowledge exists broadly across all engineers and teams at a fairly advanced level and is carried forward as they move across organizations.
|
||||
- Systems are self-healing.
|
||||
- Architectural improvements for reliability positively impact productivity (release velocity) due to reduction of maintenance work/toil.
|
||||
|
||||
*Very few services or products are at this level, and when they are, are industry leading.*
|
||||
|
||||
### *Where should you be on the reliability spectrum?*
|
||||
|
||||
|
||||
*Where should you be on the reliability spectrum?*
|
||||
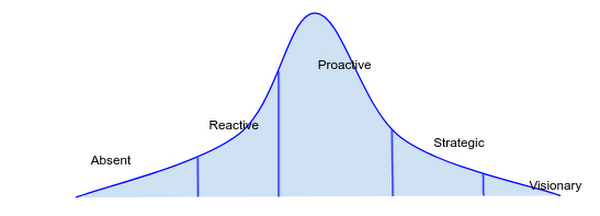
*It is very important to understand your organization does not necessarily need to be at the strategic or visionary phase. There is a significant cost associated with moving from one phase to another and a cost to remain very high on this curve. In our experience, being proactive is a healthy level to target and is ideal for most products.*
|
||||
|
||||
*To illustrate this point, here is a simple graph of where various Google product teams are on the organizational reliability spectrum; as you can see, it produces a standard bell-curve distribution. While many Google’s product teams have a reactive or proactive reliability culture, most can be described as proactive. You, as an organizational leader, must consciously decide to be at a level based on the product requirements and client expectations.*
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
Further, it’s common to have attributes across several phases, for example, an organization may be largely reactive with a few proactive attributes. Team culture will wax and wane between phases, as it takes effort to maintain a strategic reliability culture. However, as more of the organization embraces and celebrates reliability as a key feature, the cost of maintenance decreases.
|
||||
|
||||
The key to success is making an honest assessment of what phase you’re in, and then doing concerted work to move to the phase that makes sense for your product. If your organization is in the absent or reactive phase, remember that many products in nascent stages of their life cycle may be comfortable there (in both the startup and long term maintenance of a stable product).
|
||||
|
||||
### Reliability phases in action
|
||||
|
||||
To illustrate the reliability phases in practice, it is interesting to look at examples of organizations and how they have progressed or regressed through them.
|
||||
|
||||
It should be noted that all companies and teams are different and the progress through these phases can take varying amounts of time. It is not uncommon to take two to three years to move into a truly proactive state. In a proactive state all parts of the organization contribute to reliability without worrying that it will negatively impact feature velocity. Staying in the proactive phase also takes time and effort.
|
||||
|
||||
**Nobody can be a hero forever**
|
||||
|
||||
One infrastructure services team started small with a few well understood APIs. One key member of the team, a product architect, understood the system well and ensured that things ran smoothly by ensuring design decisions were sound and being at each major incident to rapidly mitigate the issue. This was the one person who understood the entire system and was able to predict what can and cannot impact its stability. But when they left the team, the system complexity grew by leaps and bounds. Suddenly there were many critical user-facing and internal outages.
|
||||
|
||||
Organizational leaders initiated both short and long-term reliability programs to restore stability. They focused on reducing the blast radius and the impact of global outages. Leadership recognized that to sustain this trajectory, they recognized that they had to go beyond engineering solutions and implement cultural changes such as recognizing reliability as their number-one feature. This led to broad training around reliability best practices, incorporating reliability in architectural/design reviews and recognizing and rewarding reliability beyond hero moments.
|
||||
|
||||
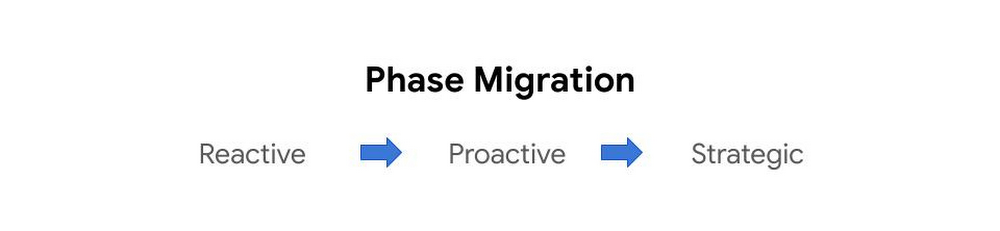
As a result, the organization evolved from a reactive to a strategic reliability mindset, aided by setting reliability as their number-one feature, recognizing and rewarding long-term reliability improvements, and adopting the systemic belief that reliability is everyone’s responsibility—not just that of a few heroes.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
### If you think you are done, think again
|
||||
|
||||
End users are highly dependent on the reliability of this product and it ties directly to user trust. For this reason, reliability was top of mind for one Google organization for years, and the product was held as the gold standard of reliability by other Google teams. The org was deemed visionary in its reliability processes and work.
|
||||
|
||||
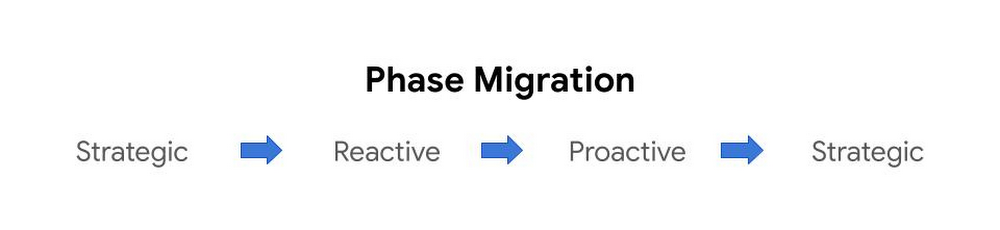
However, over the years, new products were added to the base service. The high level of reliability did not come as freely and easily as it did with the simpler product. Reliability was impacted at the cost of developer velocity and the organization moved to a more reactive reliability mindset.
|
||||
|
||||
To turn the ship around, the organization’s leaders had to be intentional about their reliability posture and overall practices, for example, how much they thought about and prioritized reliability. It took several years to move the team back to a strategic mindset.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
### Embrace reliability principles from the start
|
||||
|
||||
Another team with a new user-facing product was focused on adding features and growing their user base. Before they knew it, the product took off and saw exponential growth.
|
||||
|
||||
Unfortunately, their laser-focus on managing user requirements and growing user adoption led to high technical debt and reliability issues. Since the service didn’t start off with reliability as a primary focus, it was very hard to incorporate it after the fact.
|
||||
|
||||
Much of the code had to be re-written and re-architected to reach a sustainable state. The team’s leaders incentivized attention to reliability throughout the organization, from product management through to development and UX domains, constantly reminding the organization about the importance of reliability to the long-term success of the product. This mindshift took years to set in.
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
### Conclusion
|
||||
|
||||
It is important that cross-functional organizations be honest about their reliability journeys and determine what is appropriate for their business and product. It is not uncommon for organizations to move from one level to another and then back again as the product matures, stabilizes and then is sunset for the next generation. Getting to a strategic level can be 4+ years in the making and require very high levels of investment from all aspects of the business. Leaders should ensure their product requires this level of continued investment.
|
||||
|
||||
We encourage you to study your culture of reliability, assess what phase you are in, determine where you should be on the continuum and carefully and thoughtfully move there. Changing culture is hard and can not be done by edicts or penalties. Most of all, remember that this is a journey and the business is ever-evolving; you cannot set reliability on the shelf and expect it to maintain itself in perpetuity.
|
||||
|
||||
[DevOps & SRE](https://cloud.google.com/blog/products/devops-sre/evaluating-where-your-team-lies-on-the-sre-spectrum)
|
||||
|
||||
##### Are we there yet? Thoughts on assessing an SRE team’s maturity
|
||||
|
||||
Examining the key indicators that signal a mature SRE team.
|
||||
|
||||
By Alex Bramley • 7-minute read
|
||||
|
||||
|
||||
|
||||
##### Related articles
|
||||
|
||||
[Management Tools](https://cloud.google.com/blog/products/management-tools/cloud-monitoring-adds-long-lookback-alert-policies-for-promql)
|
||||
|
||||
### Anomaly detection using dynamic thresholds and two-year-long alerts in Cloud Monitoring
|
||||
|
||||
By Lee Yanco • 6-minute read
|
||||
|
||||

|
||||
|
||||
[Management Tools](https://cloud.google.com/blog/products/management-tools/alert-with-sql-in-cloud-monitoring-observability-analytics)
|
||||
|
||||
### From query to action: Introducing SQL alerting in Cloud Monitoring Observability Analytics
|
||||
|
||||
By Joy Wang • 4-minute read
|
||||
|
||||

|
||||
|
||||
[DevOps & SRE](https://cloud.google.com/blog/products/devops-sre/how-google-sre-is-using-agentic-ai-to-improve-operations)
|
||||
|
||||
### AI in SRE: Where and how Google is deploying agentic AI to improve operations
|
||||
|
||||
By Stevan Malesevic • 9-minute read
|
||||
|
||||
|
||||
|
||||
[Application Development](https://cloud.google.com/blog/products/application-development/gemini-cloud-assist-at-next26)
|
||||
|
||||
### Gemini Cloud Assist: Proactive cloud operations that work for you, even before you ask
|
||||
|
||||
By Michael Bachman • 5-minute read
|
||||
|
||||
|
||||
@@ -0,0 +1,77 @@
|
||||
# 3 Combat Sports Principles that Apply to Site Reliability Engineering
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Paul Marsicovetere — Formidable
|
||||
- **链接**: https://formidable.com/blog/2021/combat-sre/
|
||||
|
||||
## 简介
|
||||
|
||||
Not the field I would have expected to look to for lessons, but it totally works!
|
||||
|
||||
## 正文
|
||||
|
||||
# Insights
|
||||
|
||||
Perspectives from the intersection of business challenges and technology solutions, to inform enterprise leaders navigating the AI landscape.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
|
||||
### In conversation with our AI Lead: "I was looking for an engineering book that didn't exist, so I'm writing it."
|
||||
|
||||
Nearform · 11 Aug 2026 · 5 min read
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
|
||||
### When your AI ROI is flat, it’s time to get back to basics
|
||||
|
||||
[Ciarán Cosgrave](https://formidable.com/authors/ciar-n-cosgrave)· 25 Jun 2026 · 5 min read
|
||||
|
||||

|
||||
|
||||
|
||||
### Lessons from real-world failures using spec-driven development
|
||||
|
||||
[Alfonso Graziano](https://formidable.com/authors/alfonso-graziano)· 24 Jun 2026 · 5 min read
|
||||
|
||||

|
||||
|
||||
|
||||
### "I think my phone is listening to me"... What should CTOs do when AI knows what you never told it?
|
||||
|
||||
[Peri Kadaster](https://formidable.com/authors/peri-kadaster)· 17 Jun 2026 · 5 min read
|
||||
|
||||

|
||||
|
||||
|
||||
### The war on vibe coding – What belongs in the enterprise toolkit?
|
||||
|
||||
[Ciarán Cosgrave](https://formidable.com/authors/ciar-n-cosgrave)· 5 Jun 2026 · 4 min read
|
||||
|
||||

|
||||
|
||||
|
||||
### Beyond the code: A candid chat with BMad creator, Brian Madison
|
||||
|
||||
[Cian Clarke](https://formidable.com/authors/cian-clarke)· 3 Jun 2026 · 3 min read
|
||||
|
||||
## Looking for technical content?
|
||||
|
||||

|
||||
|
||||
|
||||
### Stop onboarding. Start shipping: how to master legacy code in 20 minutes.
|
||||
|
||||
Carmine Sacco · 21 May 2026 · 8 min read
|
||||
|
||||

|
||||
|
||||
|
||||
### Soloper: compressing the development phase of a mobile-to-web port with GitHub Copilot
|
||||
|
||||
Matteo Pietro Dazzi · 12 May 2026 · 10 min read
|
||||
@@ -0,0 +1,198 @@
|
||||
# Safe schema updates – Near-zero downtime database deployments
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Alex Yates — Octopus Deploy
|
||||
- **链接**: https://octopus.com/blog/safe-schema-updates-7-near-zero-downtime-deployments
|
||||
|
||||
## 简介
|
||||
|
||||
This article introduces a 3-phased approach for safe database schema changes: Expand, Rollout, and Contract.
|
||||
|
||||
## 正文
|
||||
|
||||
This blog post is part 7 of my safe schema updates series. Links to the other posts in this series are available below:
|
||||
|
||||
**Critiquing existing systems:**
|
||||
|
||||
**Imagining better systems:**
|
||||
|
||||
- [Part 2: Resilient vs robust IT systems](https://octopus.com/blog/safe-schema-updates-2-resilience-vs-robustness)
|
||||
- [Part 3: Continuous Integration is misunderstood](https://octopus.com/blog/safe-schema-updates-3-ci-is-misunderstood)
|
||||
- [Part 4: Loose coupling mitigates tech problems](https://octopus.com/blog/safe-schema-updates-4-loose-coupling-mitigates-tech-problems)
|
||||
- [Part 5: Loose coupling mitigates human problems](https://octopus.com/blog/safe-schema-updates-5-loose-coupling-mitigates-human-problems)
|
||||
|
||||
**Building better systems:**
|
||||
|
||||
- [Part 6: Provisioning dev/test databases](https://octopus.com/blog/safe-schema-updates-6-provisioning-databases)
|
||||
- [Part 7: Near-zero downtime database deployments](https://octopus.com/blog/safe-schema-updates-7-near-zero-downtime-deployments)
|
||||
- [Part 8: Strangling the monolith](https://octopus.com/blog/safe-schema-updates-8-strangling-the-monolith)
|
||||
|
||||
Small, frequent, and simple changes are safer. Big, infrequent, and complex changes are more dangerous. If you disagree, re-read this series from the beginning, starting with my [post about database delivery hell](https://octopus.com/blog/safe-schema-updates-1-delivery-hell).
|
||||
|
||||
Databases rarely exist in isolation. When making database schema changes, we usually need to consider dependencies. Databases typically serve front-end applications/services, which means schema changes often need to be coordinated with changes to other systems.
|
||||
|
||||
A period of downtime is probably required because we can’t risk serving mismatched versions:
|
||||
|
||||
1. The system is taken offline
|
||||
2. All the changes are deployed at once/in sequence
|
||||
3. The system is brought back online
|
||||
|
||||
Throughout this process, our users are locked out.
|
||||
|
||||
There are a hundred ways this could end badly. [The Phoenix Project](https://octopus.com/blog/devops-reading-list#phoenix) featured just such a disaster. A database update took longer than anticipated and critical systems could not be restored on time.
|
||||
|
||||
Despite the risk, if we have database schemas, it’s unwise to avoid making schema changes. Such a rigid strategy, over time, results in horrible architectures that do not reflect evolving business requirements.
|
||||
|
||||
Our goal is to enable the schema to evolve safely. Therefore, we need to ensure such deployments are executed small and often.
|
||||
|
||||
Unfortunately, the more downtime is required for each deployment, the less frequently we’ll be able to do it. We’ll never be deploying 10 times a day if each deployment requires an hour of downtime.
|
||||
|
||||
More likely, engineers will need to plan well-ahead and play politics to negotiate some downtime window. Probably overnight. (Tired workers aren’t known for their reliability, attention to detail, or problem-solving skills.)
|
||||
|
||||
Since these opportunities don’t come often, changes will be batched up. As many changes as possible will be crammed into the shortest possible window.
|
||||
|
||||
This… is stupid. (See opening paragraph.)
|
||||
|
||||
The inescapable conclusion: It’s essential that we perform schema changes with as little downtime as possible. Only through minimizing downtime, can we increase deployment frequency, decrease deployment size/complexity, and deliver safer schema updates.
|
||||
|
||||
In my experience, for all the talk about source control and deployment automation, the necessity to minimize downtime is under-appreciated by those who have database schemas and wish to keep them safe.
|
||||
|
||||
This post is not about the automation or execution of schema updates – there are [many other posts about that](https://octopus.com/blog/tag/database-deployments/1). This post is about patterns for minimizing downtime.
|
||||
|
||||
## Overloaded terminology: deployments and releases
|
||||
|
||||
Many people use the words “release” and “deployment” interchangeably, without considering the difference between them.
|
||||
|
||||
If you use Octopus Deploy (or a similar product) your idea of what “release” means may be the result of common naming conventions in your tooling. In most deployment automation tools a “release” is a specific version of your source code, a bunch of configuration variables, and a set of steps that need to be run to execute a “deployment”. You might consider a “release” to be something that gets “deployed”. The release happens first, and the deployment comes later. That probably feels completely natural to you.
|
||||
|
||||
You are in the minority.
|
||||
|
||||
To most people, and specifically to anyone in marketing, a “release” is something different. “Releasing” a new version of your software, or the latest iPhone, or the new Adele album, is about making it available and telling people about it. The thing is created in advance, and released later. The latest James Bond film was produced in 2020, but the release was delayed until 2021.
|
||||
|
||||
When talking about zero downtime deployments, we tend to use “release” in this second way. Deployments are about making changes, but releases are about revealing those changes to our users. When I use “release” in this post, I’m not referring to the preparation of a deployment, I’m talking about making updates visible to users.
|
||||
|
||||
It is crucial to differentiate between deploying changes and releasing/revealing those changes to users. These two things do not need to happen at the same time. In fact, it’s the ability to separate these events that enables zero downtime releases, as well as all sorts of other exciting practices, such as testing in production and some rapid rollback patterns.
|
||||
|
||||
## Application zero downtime patterns
|
||||
|
||||
This post is about database deployment, but databases don’t live in isolation. We need to start with some context.
|
||||
|
||||
Application deployment patterns that support zero downtime (more accurately, near-zero downtime) are generally split into two categories:
|
||||
|
||||
- Infrastructure-based
|
||||
- Application-based
|
||||
|
||||
### Infrastructure-based deployment patterns
|
||||
|
||||
**Infrastructure-based** techniques include [blue/green](https://martinfowler.com/bliki/BlueGreenDeployment.html) deployments, [canary releases](https://martinfowler.com/bliki/CanaryRelease.html), and cluster immune systems. They are typically based on clever load balancing tricks. The new code is deployed on new infrastructure, tested, and added into rotation.
|
||||
|
||||
By changing settings in our load balancer we can send traffic to either the new or old infra. This potentially allows us to “release” the new version gradually. First to 1% of our production traffic, then 5%, 10%, gradually throttling it as we watch the telemetry, our social media channels, and/or our support tickets to check everything is running smoothly.
|
||||
|
||||
If all goes well, the release will be gradually rolled out globally. If not, we can revert to the old version instantly by undoing the setting on the load balancer. We avoided any in-situ upgrades, so the old servers are still running and ready to receive the full load if required.
|
||||
|
||||
### Application-based deployment patterns
|
||||
|
||||
**Application-based** approaches tend to be based on [feature-toggles/flags](https://martinfowler.com/articles/feature-toggles.html). The old and new version will be deployed side by side, but which version gets executed can be managed with code and some external database.
|
||||
|
||||
For example, perhaps we’ve got a *featuretoggle* database running in production. After deploying our new code, each time a method in the application is called, it queries the *featuretoggle* database to find out whether some feature is enabled. Depending on the response, it could run either one block of code or another. Perhaps the *featuretoggle* database can throttle the rollout, by instructing the application to use the new code x% of the time.
|
||||
|
||||
This allows new features to be released or rolled back by changing a setting in an external database. No additional deployment is necessary.
|
||||
|
||||
We can take this further. Perhaps, if we have a new feature, but we are concerned about performance, we could run both blocks of code, but only display the old functionality in the UI. This is called dark launching, and it allows engineers to test the performance of their code with live production workloads, with an easy way to throttle up and down or kill the new code.
|
||||
|
||||
You can read more about application patterns in the post [Deploy != Release](https://blog.turbinelabs.io/deploy-not-equal-release-part-one-4724bc1e726b). This is also covered in more detail in [The DevOps Handbook](https://octopus.com/blog/devops-reading-list#handbook).
|
||||
|
||||
The thing that both infrastructure-based and application-based patterns have in common is that the code is deployed first, and released afterwards, in a controlled and testable manner, allowing for rapid, almost immediate, rollbacks.
|
||||
|
||||
What does this mean for databases? **Forward and backward compatibility is essential.**
|
||||
|
||||
## Expand/contract, for forward and backward compatibility
|
||||
|
||||
If we wish to make a schema change in the database which will affect our dependent services, and if we wish to avoid scheduled downtime, we are likely to be following one of the application or infrastructure-based patterns discussed above. In either case, we need to evolve the database through three phases.
|
||||
|
||||
1. **Expand:** Additive changes to database to support both the old and new versions of dependent applications.
|
||||
2. **Rollout:** New versions of applications deployed, tested, and released. Ideally in that order.
|
||||
3. **Contract:** Following rollout, we can safely delete the old schema objects.
|
||||
|
||||
This single, grand refactor is going to require multiple small schema changes. To avoid scheduling downtime, each change must have the following attributes:
|
||||
|
||||
- Can be executed independently of other steps or any other dependencies
|
||||
- Creates minimal risk
|
||||
- Has a fast roll-back option (that avoids either data loss, or significant and necessary data processing, which can cause all sorts of problems)
|
||||
|
||||
It’s easiest to explain with an example: Consider the splitting of a *fullName* column, into separate *firstName* and *lastName* columns. We can deliver this without any risky downtime windows or scary schema updates as follows:
|
||||
|
||||
**Expand:**
|
||||
|
||||
1. The new columns are added to the database. (Nothing risky about that.)
|
||||
2. If using stored procedures for adding/updating/deleting data, these stored procedures can be updated to add/update/delete into both the old and new columns.
|
||||
3. The existing data is gradually migrated in the background. (This can be drip fed without significant performance impact and the process can be paused or stopped if there are any issues.)
|
||||
|
||||
Now the database supports both versions.
|
||||
|
||||
**Rollout:**
|
||||
|
||||
1. When the data is reliably in sync in both the old and new columns, any read stored procedures can be pointed at the new columns.
|
||||
2. If the applications reference the columns directly, rather than going through stored procedures, rollout the new application versions using one of the infrastructure or application-based patterns described above.
|
||||
|
||||
Now the new stuff is released globally.
|
||||
|
||||
**Contract:**
|
||||
|
||||
1. In theory, we can delete the old columns. However, in systems with many poorly documented dependencies, there’s always the possibility that we missed something. Better to rename the old column first. (And update any stored procedures that updated the old columns.) If anyone complains, we can immediately fix it with another rename by restoring the old version of any stored procedures.
|
||||
2. In either case, after some period of time, we should schedule the deletion of the old columns. No one needs to see hundreds of objects appended with `_toDelete` . (Tip: try`_ToDeleteOn2021-12-01` instead. It somewhat focuses the mind, and we could even wrap some automated processes to backup and cull old objects.)
|
||||
|
||||
Refactor complete. As long as the steps are followed in this order, each step could be taken individually. None of these steps created an enormous risk. If there ever was a mistake, each step could be easily reverted.
|
||||
|
||||
## Summary
|
||||
|
||||
This is a much safer way to update your schemas. Crucially, since it does not require any downtime, these changes do not need to be batched up for release.
|
||||
|
||||
There may be some people reading this who think it will take longer. I’m afraid those people are still thinking in terms of long lead times for small changes. Perhaps they are thinking of change approval boards or they are imagining separate JIRA tickets for each step. Perhaps they are thinking of separate week-long testing cycles for each step.
|
||||
|
||||
Forget all that.
|
||||
|
||||
If this refactor needs approval, it should be reviewed as a whole, even if it’s executed in steps. And most of the testing and deployment pipeline should be automated.
|
||||
|
||||
Yes: This is harder. No one said this was going to be easy. We’re optimizing for safety, and that requires rigor and effort.
|
||||
|
||||
Of course, with more dependencies, this is harder. Some might think it’s unfeasible. Certainly this process requires a certain level of defensive programming and testing/telemetry in any dependent systems.
|
||||
|
||||
In an ideal world we’d be working with loosely coupled systems (see [part 4](https://octopus.com/blog/safe-schema-updates-4-loose-coupling-mitigates-tech-problems) and [part 5](https://octopus.com/blog/safe-schema-updates-5-loose-coupling-mitigates-human-problems) of my series). These are coded defensively by default and database dependencies are significantly reduced. Attributes that make all this a lot easier.
|
||||
|
||||
If your system is tightly-coupled, perhaps by now you are seeing the enormous benefits of loose-coupling. Perhaps you are also daunted by the perceived enormity of the challenge ahead: evolving your tangled web of dependencies into something safer.
|
||||
|
||||
## Next time
|
||||
|
||||
Next time, we finish this series by exploring the Strangler pattern. A method for safely refactoring complex, tightly-coupled systems.
|
||||
|
||||
Links to the other posts in this series are available below:
|
||||
|
||||
**Critiquing existing systems:**
|
||||
|
||||
**Imagining better systems:**
|
||||
|
||||
- [Part 2: Resilient vs robust IT systems](https://octopus.com/blog/safe-schema-updates-2-resilience-vs-robustness)
|
||||
- [Part 3: Continuous Integration is misunderstood](https://octopus.com/blog/safe-schema-updates-3-ci-is-misunderstood)
|
||||
- [Part 4: Loose coupling mitigates tech problems](https://octopus.com/blog/safe-schema-updates-4-loose-coupling-mitigates-tech-problems)
|
||||
- [Part 5: Loose coupling mitigates human problems](https://octopus.com/blog/safe-schema-updates-5-loose-coupling-mitigates-human-problems)
|
||||
|
||||
**Building better systems:**
|
||||
|
||||
- [Part 6: Provisioning dev/test databases](https://octopus.com/blog/safe-schema-updates-6-provisioning-databases)
|
||||
- [Part 7: Near-zero downtime database deployments](https://octopus.com/blog/safe-schema-updates-7-near-zero-downtime-deployments)
|
||||
- [Part 8: Strangling the monolith](https://octopus.com/blog/safe-schema-updates-8-strangling-the-monolith)
|
||||
|
||||
## Watch the webinars
|
||||
|
||||
Our first webinar discussed how loosely coupled architectures lead to maintainability, innovation, and safety. Part two discussed how to transition a mature system from one architecture to another.
|
||||
|
||||
### Database DevOps: Imagining better systems
|
||||
|
||||
[Database DevOps - Imagining a better way](https://www.youtube.com/watch?v=oJAbUMZ6bQY)
|
||||
|
||||
### Database DevOps: Building better systems
|
||||
|
||||
[Database DevOps - Building Better systems](https://www.youtube.com/watch?v=joogIAcqMYo)
|
||||
|
||||
Happy deployments!
|
||||
@@ -0,0 +1,227 @@
|
||||
# Debugging a weird ‘file not found’ error
|
||||
|
||||
- **期号**: SRE Weekly Issue #297(2021-11-21)
|
||||
- **作者**: Julia Evans
|
||||
- **链接**: https://jvns.ca/blog/2021/11/17/debugging-a-weird--file-not-found--error/
|
||||
|
||||
## 简介
|
||||
|
||||
Try to run a program, and you get “No such file or directory”, even though the program is right there. How can this happen?
|
||||
|
||||
## 正文
|
||||
|
||||
# Debugging a weird 'file not found' error
|
||||
|
||||
Yesterday I ran into a weird error where I ran a program and got the error “file not found” even though the program I was running existed. It’s something I’ve run into before, but every time I’m very surprised and confused by it (what do you MEAN file not found, the file is RIGHT THERE???!!??)
|
||||
|
||||
So let’s talk about what happened and why!
|
||||
|
||||
###
|
||||
|
||||
[the error](https://jvns.ca#the-error)
|
||||
|
||||
|
||||
Let’s start by showing the error message I got. I had a Go program called
|
||||
[serve.go](https://gist.github.com/jvns/6147bc21fbb60b0090d543bb5e240134), and I was trying to bundle it into a Docker container with this
|
||||
Dockerfile:
|
||||
|
||||
```
|
||||
FROM golang:1.17 AS go
|
||||
ADD ./serve.go /app/serve.go
|
||||
WORKDIR /app
|
||||
RUN go build serve.go
|
||||
FROM alpine:3.14
|
||||
COPY --from=go /app/serve /app/serve
|
||||
COPY ./static /app/static
|
||||
WORKDIR /app/static
|
||||
CMD ["/app/serve"]
|
||||
```
|
||||
This Dockerfile
|
||||
|
||||
1. Builds the Go program
|
||||
2. Copies the binary into an Alpine container
|
||||
|
||||
Pretty simple. Seems like it should work, right?
|
||||
|
||||
But when I try to run `/app/serve`, this happens:
|
||||
|
||||
```
|
||||
$ docker build .
|
||||
$ docker run -it broken-container:latest /app/serve
|
||||
standard_init_linux.go:228: exec user process caused: no such file or directory
|
||||
```
|
||||
But the file definitely does exist:
|
||||
|
||||
```
|
||||
$ docker run -it broken-container:latest ls -l /app/serve
|
||||
-rwxr-xr-x 1 root root 6220237 Nov 16 13:27 /app/serve
|
||||
```
|
||||
So what’s going on?
|
||||
|
||||
###
|
||||
|
||||
[idea 1: permissions](https://jvns.ca#idea-1-permissions)
|
||||
|
||||
|
||||
At first I thought “hmm, maybe the permissions are wrong?”. But this can’t be the problem, because:
|
||||
|
||||
- permission problems don’t result in a “no such file or directory” error
|
||||
- in any case when we ran `ls -l` , we saw that the file was executable
|
||||
|
||||
(I’m including this even though it’s “obviously” wrong just because I have a lot of wrong thoughts when debugging, it’s part of the process :) )
|
||||
|
||||
###
|
||||
|
||||
[idea 2: strace](https://jvns.ca#idea-2-strace)
|
||||
|
||||
|
||||
Then I decided to use strace, as always. Let’s see what stracing `/app/serve/` looks like
|
||||
|
||||
```
|
||||
$ docker run -it broken-container:latest /bin/sh
|
||||
$ /app/static # apk add strace
|
||||
(apk output omitted)
|
||||
$ /app/static # strace /app/serve
|
||||
execve("/app/serve", ["/app/serve"], 0x7ffdd08edd50 /* 6 vars */) = -1 ENOENT (No such file or directory)
|
||||
strace: exec: No such file or directory
|
||||
+++ exited with 1 +++
|
||||
```
|
||||
This is not that helpful, it just says “No such file or directory” again. But
|
||||
at least we know that the error is being thrown right away when we run the
|
||||
`evecve` system call, so that’s good.
|
||||
|
||||
Interestingly though, this is different from what happens when we try to strace a nonexistent binary:
|
||||
|
||||
```
|
||||
$ strace /app/asdf
|
||||
strace: Can't stat '/app/asdf': No such file or directory
|
||||
```
|
||||
###
|
||||
|
||||
[idea 3: google “enoent but file exists execve”](https://jvns.ca#idea-3-google-enoent-but-file-exists-execve)
|
||||
|
||||
|
||||
I vaguely remembered that there was some reason you could get an `ENOENT` error
|
||||
when executing a program even if the file did exist, so I googled it. This led me
|
||||
to [this stack overflow answer](https://superuser.com/a/507031)
|
||||
|
||||
which said, very helpfully:
|
||||
|
||||
When execve() returns the error ENOENT, it can mean more than one thing:
|
||||
|
||||
|
||||
- the program doesn’t exist;
|
||||
- the program itself exists, but it requires an “interpreter” that doesn’t exist.
|
||||
ELF executables can request to be loaded by another program, in a way very similar to `#!/bin/something` in shell scripts.
|
||||
|
||||
|
||||
That answer says that we can find the interpreter with `readelf -l $PROGRAM | grep interpreter`. So let’s do that!
|
||||
|
||||
###
|
||||
|
||||
[step 4: use `readelf`](https://jvns.ca#step-4-use-readelf)
|
||||
|
||||
|
||||
`readelf`
|
||||
I didn’t have `readelf` installed in the container and I wasn’t sure how to
|
||||
install it, so I ran `mount` to get the path to the container’s filesystem and
|
||||
then ran `readelf` from the host using that overlay directory.
|
||||
|
||||
(as an aside: this is kind of a weird way to do this, but as a result of writing
|
||||
a [containers zine](https://wizardzines.com/zines/containers) I’m used to doing
|
||||
weird things with containers and I think doing weird things is fun, so this way just seemed fastest to me at the time. That trick
|
||||
won’t work if you’re on a Mac though, it only works on Linux)
|
||||
|
||||
```
|
||||
$ mount | grep docker
|
||||
overlay on /var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/merged type overlay (rw,relatime,lowerdir=/var/lib/docker/overlay2/l/326ILTM2UXMVY64V7JFPCSDSKG:/var/lib/docker/overlay2/l/MGGPR357UOZZWXH3SH2AYHJL3E:/var/lib/docker/overlay2/l/EEEKSBSQ6VHGJ77YF224TBVMNV:/var/lib/docker/overlay2/l/RVKU36SQ3PXEQAGBRKSQRZFDGY,upperdir=/var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/diff,workdir=/var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/work,index=off)
|
||||
$ # (then I copy and paste the "merged" directory from the output)
|
||||
$ readelf -l /var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/merged/app/serve | grep interp
|
||||
[Requesting program interpreter: /lib64/ld-linux-x86-64.so.2]
|
||||
01 .interp
|
||||
03 .text .plt .interp .note.go.buildid
|
||||
```
|
||||
Okay, so the interpreter is `/lib64/ld-linux-x86-64.so.2`.
|
||||
|
||||
And sure enough, that file doesn’t exist inside our Alpine container
|
||||
|
||||
```
|
||||
$ docker run -it broken-container:latest ls /lib64/ld-linux-x86-64.so.2
|
||||
```
|
||||
###
|
||||
|
||||
[step 5: victory!](https://jvns.ca#step-5-victory)
|
||||
|
||||
|
||||
Then I googled a little more and found out that there’s a `golang:alpine`
|
||||
container that’s meant for doing Go builds targeted to be run in Alpine.
|
||||
|
||||
I switched to doing my build in the `golang:alpine` container and that fixed
|
||||
everything.
|
||||
|
||||
###
|
||||
|
||||
[question: why is my Go binary dynamically linked?](https://jvns.ca#question-why-is-my-go-binary-dynamically-linked)
|
||||
|
||||
|
||||
The problem was with the program’s interpreter. But I remembered that only dynamically linked programs have interpreters, which is a bit weird – I expected my Go binary to be statically linked! What’s going on with that?
|
||||
|
||||
First, I double checked that the Go binary was actually dynamically linked using `file` and `ldd`: (`ldd` lists the dependencies of a dynamically linked executable! It’s very useful!)
|
||||
|
||||
(I’m using the docker overlay filesystem to get at the binary inside the container again)
|
||||
|
||||
```
|
||||
$ file /var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/merged/app/serve
|
||||
/var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/merged/app/serve:
|
||||
ELF 64-bit LSB executable, x86-64, version 1 (SYSV), dynamically linked,
|
||||
interpreter /lib64/ld-linux-x86-64.so.2, Go
|
||||
BuildID=vd_DJvcyItRi4Q2RD0WL/z8P4ulttr6F6njfqx8CI/_odQWaUTR2e38bdHlD0-/ikjsOjlMbEOhj2qXv5AE,
|
||||
not stripped
|
||||
$ ldd /var/lib/docker/overlay2/1ed587b302af7d3182135d02257f261fd491b7acf4648736d4c72f8382ecba0d/merged/app/serve
|
||||
linux-vdso.so.1 (0x00007ffe095a6000)
|
||||
libpthread.so.0 => /usr/lib/libpthread.so.0 (0x00007f565a265000)
|
||||
libc.so.6 => /usr/lib/libc.so.6 (0x00007f565a099000)
|
||||
/lib64/ld-linux-x86-64.so.2 => /usr/lib64/ld-linux-x86-64.so.2 (0x00007f565a2b4000)
|
||||
```
|
||||
Now that I know it’s dynamically linked, it’s not that surprising that it didn’t work on a different system than it was compiled on.
|
||||
|
||||
Some Googling tells me that I can get Go to produce a statically linked binary by setting `CGO_ENABLED=0`. Let’s see if that works.
|
||||
|
||||
```
|
||||
$ # first let's build it without that flag
|
||||
$ go build serve.go
|
||||
$ file ./serve
|
||||
./serve: ELF 64-bit LSB executable, x86-64, version 1 (SYSV), dynamically linked, interpreter /lib64/ld-linux-x86-64.so.2, Go BuildID=UGBmnMfFsuwMky4-k2Mt/RaNGsMI79eYC4-dcIiP4/J7v5rNGo3sNiJqdgNR12/eR_7mqqrsil_Lr6vt-rP, not stripped
|
||||
$ ldd ./serve
|
||||
linux-vdso.so.1 (0x00007fff679a6000)
|
||||
libpthread.so.0 => /usr/lib/libpthread.so.0 (0x00007f659cb61000)
|
||||
libc.so.6 => /usr/lib/libc.so.6 (0x00007f659c995000)
|
||||
/lib64/ld-linux-x86-64.so.2 => /usr/lib64/ld-linux-x86-64.so.2 (0x00007f659cbb0000)
|
||||
$ # and now with the CGO_ENABLED_0 flag
|
||||
$ env CGO_ENABLED=0 go build serve.go
|
||||
$ file ./serve
|
||||
./serve: ELF 64-bit LSB executable, x86-64, version 1 (SYSV), statically linked, Go BuildID=Kq392IB01ShfNVP5TugF/2q5hN74m5eLgfuzTZzR-/EatgRjlx5YYbpcroiE9q/0Fg3zUxJKY3lbsZ9Ufda, not stripped
|
||||
$ ldd ./serve
|
||||
not a dynamic executable
|
||||
```
|
||||
It works! I checked, and that’s an alternative way to fix this bug – if I just set the
|
||||
`CGO_ENABLED=0` environment variable in my build container, then I can build a
|
||||
static binary and I don’t need to switch to the `golang:alpine` container for my builds. I
|
||||
kind of like that fix better.
|
||||
|
||||
And statically linking in this case doesn’t even produce a bigger binary (for
|
||||
some reason it seems to produce a slightly *smaller* binary?? I don’t know why
|
||||
that is)
|
||||
|
||||
I still don’t understand *why* it’s using cgo here, I ran `env | grep CGO` and I
|
||||
definitely don’t have `CGO_ENABLED=1` set in my environment, but I
|
||||
don’t feel like solving that mystery right now.
|
||||
|
||||
###
|
||||
|
||||
[that was a fun bug!](https://jvns.ca#that-was-a-fun-bug)
|
||||
|
||||
|
||||
I thought this bug was a nice way to see how you can run into problems when compiling a dynamically linked executable on one platform and running it on another one! And to learn about the fact that ELF files have an interpreter!
|
||||
|
||||
I’ve run into this “file not found” error a couple of times, and it feels kind of mind bending because it initially seems impossible (BUT THE FILE IS THERE!!! I SEE IT!!!). I hope this helps someone be less confused if you run into it!
|
||||
Reference in New Issue
Block a user