SRE weekly 所有文章
This commit is contained in:

119
sreweekly/markdown/313/01-when-to-hire-an-incident-commander.md
Normal file
119
sreweekly/markdown/313/01-when-to-hire-an-incident-commander.md
Normal file
@@ -0,0 +1,119 @@
|
||||
# When to hire an Incident Commander
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Ryan McDonald — FireHydrant
|
||||
- **链接**: https://firehydrant.io/blog/when-to-hire-an-incident-commander/
|
||||
|
||||
## 简介
|
||||
|
||||
Do you need an incident commander? (Yes.) This article is about how to staff your incident command rotation through a couple of different strategies.
|
||||
|
||||
## 正文
|
||||
|
||||
## When to hire an Incident Commander
|
||||
|
||||
Do you need a dedicated incident commander? We will explore what an incident commander is, what forms the role can take, and when you should consider the addition of a dedicated incident commander to your organization.
|
||||
|
||||
|
||||
|
||||
What comes to mind when you hear the term 'incident commander'? You are not alone if you think about fancy, tri-cornered hats, well-polished shoes, and a uniform weighed down by medals. The roles of incident commander, incident manager, or technical escalation manager have been typical in large organizations but are gaining popularity in smaller companies. For the purposes of this article, we will use the term 'incident commander,' but any of the above titles could work.
|
||||
|
||||
So, the question is, do you need a dedicated incident commander? Do you need a team of incident commanders?! Can you get by with a volunteer incident commander?
|
||||
|
||||
In this post, we will explore what an incident commander is, what forms the role can take, and when you should consider the addition of a dedicated incident commander to your organization.
|
||||
|
||||
# What is an incident commander?#what-is-an-incident-commander
|
||||
|
||||
At its core, an incident commander helps facilitate communication and the timely resolution of a software incident while balancing and minimizing risk to responding teams, the business, and customers. Imagine an authoritative project manager in charge of an impromptu, emergent, and maybe chaotic project with business-ending ramifications if it fails. If you are nodding right now: welcome; you've been involved in a large-scale incident before. If you were successful, someone probably stepped into this role, whether they held the title of Incident Commander or not.
|
||||
|
||||
Incident Commanders, especially of the dedicated variety, can also take on a variety of other supporting tasks outside of incidents, including but not limited to:
|
||||
|
||||
- Documentation and recording of incidents
|
||||
- Post-incident review facilitation and incident analysis
|
||||
- Collecting and aggregating data on uptime and other relevant incident metrics
|
||||
- Sharing learning from incidents
|
||||
- Incident process improvement across all responder organizations
|
||||
|
||||
The incident commander role, formalized or otherwise, is the linchpin of your response processes. Before you run out and hire a team of incident commanders, it's worth considering what organizational and functional conditions benefit most from having staff dedicated to the role.
|
||||
|
||||
# Does your organization need an incident commander?#does-your-organization-need-an-incident-commander
|
||||
|
||||
When might an organization consider minting an incident commander role? Below is a list of questions for self-assessing if your team is indeed ready for this unique role.
|
||||
|
||||
*Caveat*: These are generalizations to help organizations understand if there is space or need for an incident command role, not absolutes. The world of incidents, by its nature, is ripe with exceptions.
|
||||
|
||||
## Software and organizational complexity#software-and-organizational-complexity
|
||||
|
||||
Complexity in software can drive a greater need for coordination during an incident. Complexity in organizational structures and technical service dependencies quickly increase friction during incident response. Below are some common indicators of complexity that could warrant greater coordination during incidents.
|
||||
|
||||
**Are your engineering teams split by technical domain?** Typically domain-centric teams can require greater coordination if the problem exists between services or layers. Bringing together a group of people that do not frequently work with one another, particularly during a crisis, can often benefit from external facilitation and coordination.
|
||||
|
||||
**How much of your stack was not written by the team maintaining it?** For our purposes, we will assume Legacy software to mean 'software your teams have limited knowledge of.' This type of arrangement radically can increase the difficulty of triage efforts. Leveraging an incident commander to help locate domain experts can ensure responders are focused on triage, not lighting up Slack.
|
||||
|
||||
**How many external dependencies does your team have?** Specifically, does your organization leverage vendors for critical functionality, support multiple products, or have an internal 'platform' team(s) supporting in-house tools? These factors can add levels of complexity to the incident response beyond the technical triage efforts. Multiple products being impacted by an issue, internal or external tooling failures that many teams depend upon can quickly ratchet the levels of internal communication required.
|
||||
|
||||
**Is your organization rapidly growing or iterating on its incident management processes?** Hypergrowth and scaling processes can lead to incidents with new teams in unfamiliar process territory or older teams exposed to new processes for the first time. Having an expert to help guide the response increases consistency and efficiency. It also reduces spent figuring out the 'right way' to manage the incident or, worse yet, missing expectations from customers or internal stakeholders.
|
||||
|
||||
**Is your organization working towards compliance goals or catering to enterprise customers?** A well-documented and auditable incident process is a fantastic complement to the reams of documentation required to pass regulatory and compliance audits. In the case of B2B business, it can aid in clearing large organizations' procurement departments.
|
||||
|
||||
## What forms can an incident commander take?#what-forms-can-an-incident-commander-take
|
||||
|
||||
Incident commanders can add substantial value to an organization, but sometimes the idea of dedicating an entire headcount may not make sense given an organization's scale, maturity or complexity. Thankfully, incident command can scale down to nearly any organizational size. The spectrum of possible incident commanders bucketed broadly from voluntary to a dedicated role is outlined below.
|
||||
|
||||
### Volunteer#volunteer
|
||||
|
||||
A critical factor in a volunteer incident commander model is to ensure volunteers are sufficiently recognized, valued, and potentially even incentivized. Without support, this model will be short-lived.
|
||||
|
||||
**Organic**
|
||||
|
||||
Like many informal roles in growing organizations, your org may already have a de facto incident commander hiding in the ranks. This person will often live in support, operations, or an engineering role, equipped with greater-than-average customer empathy. If they have been around for long enough, they may also have technical instincts honed by repeated exposure to your organization's software on its worst days.
|
||||
|
||||
- Pro: The quality of the output from this ambitious volunteer can rival that of a full-time incident commander when well resourced.
|
||||
- Pro: Once identified, this person is a great candidate to help scale out a more intentionally developed group of volunteers.
|
||||
- Con: This person can be at risk of burnout and inevitably be a single failure point.
|
||||
- Con: In a large enough organization, it is unlikely that a single person can drive significant change to the incident process.
|
||||
|
||||
**Intentionally developed**
|
||||
|
||||
A group of volunteers with structured norms similar to a guild informally manage the 'incident program,' often with the help and guidance of an executive sponsor. Day jobs of these individuals are usually less critical than one might think, aside from having the flexibility to drop out of their everyday work to help manage an incident.
|
||||
|
||||
- Pro: Similar to above, volunteers are often passionate and can provide a high-quality commander experience for an organization.
|
||||
- Pro: A more distributed group can help shoulder the load and spread better practices more broadly than an individual
|
||||
- Pro: Greater resilience to attrition or similar single points of failure with an individual.
|
||||
- Con: Without executive sponsorship or other incentives, it can be challenging to maintain the inertia of this group.
|
||||
- Con: It can be challenging to drive process change if the group doesn't contain enough leadership representation or a folk across different job functions.
|
||||
|
||||
### Dedicated#dedicated
|
||||
|
||||
**Assigned roles**
|
||||
|
||||
*"All engineering managers|Directors|Support Duty Managers are responsible for managing incidents"* - In an instant, most likely after a severe incident was poorly handled, your C*O has deputized an entire subgroup of your organization to serve as an incident commander.
|
||||
|
||||
- Pro: Leveraging folks already on staff can be a cost savings
|
||||
- Pro: If incentives are aligned to their performance in this capacity, this group has the potential to deliver a quality experience.
|
||||
- Con: Under incentivized, 'Volun-told' incident commanders can be a mixed bag in skills, aptitude, and motivation. The consistency and predictability of processes can suffer without a higher degree of attention from a responsible party.
|
||||
|
||||
**Targeted assigned group**
|
||||
|
||||
An experienced group of folks that excel at incident management pick up the baton when asked.
|
||||
|
||||
- Pro: Leveraging folks already on staff can be a cost savings
|
||||
- Pro: These folks will often deliver a fantastic incident command experience.
|
||||
- Con: Due to the interrupt-driven nature of incidents, these individuals are more liable to burnout while shouldering the load of another day job.
|
||||
- Con: These high performers are hard to come by, and spending their energy on incident response can take away from other valuable initiatives.
|
||||
|
||||
**Full-time incident commander**
|
||||
|
||||
Incident command as a full-time role.
|
||||
|
||||
- Pro: Focus incidents can ensure efficient responses.
|
||||
- Pro: Non-technical follow-on tasks can be handled by these individuals, minimizing the impact on other responder groups.
|
||||
- Pro: Non-incident-engaged hours can be spent improving the program, gathering metrics for leadership/teams, sharing learning from incidents, and training responders.
|
||||
- Con: Requires a dedicated headcount that could be put into another business-critical area.
|
||||
- Con: Might be more attention than is required for smaller organizations or organizations with fewer incidents.
|
||||
|
||||
# Conclusion#conclusion
|
||||
|
||||
A dedicated incident commander can play an invaluable role in organizations operating sufficiently complex systems where reliability interruptions cause immense pain. Less dedicated models can work well in cases where complexity or incident frequency is lower.
|
||||
|
||||
Regardless of what model you use, (hopefully) someone will step up to manage software incidents in your organization, and FireHydrant is an incident commander's best friend. FireHydrant automates, facilitates, and removes toil from the incident management process, allowing whatever human or group you'd prefer to focus on to help drive incidents to resolution.
|
||||
@@ -0,0 +1,85 @@
|
||||
# How Cloud Downtime Insurance Became a Thing
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: L.S. Howard — Insurance JournalFull disclosure: Fastly, my employer, is mentioned.
|
||||
- **链接**: https://www.insurancejournal.com/news/international/2022/03/08/657170.htm
|
||||
|
||||
## 简介
|
||||
|
||||
What an interesting idea, an insurance plan that pays out automatically when a cloud provider has an outage.
|
||||
|
||||
## 正文
|
||||
|
||||
A single hour of downtime from mission-critical, third-party IT service providers can cost small and medium-sized enterprises tens of thousands of dollars, but traditional insurance often does not cover these significant losses.
|
||||
|
||||
That’s why the founders of Parametrix Insurance came up with the idea to cover clients for short-term cloud outages, network crashes and platform failures that last up to 12-24 hours. Its products are designed to close a vital business interruption protection gap by using parametric triggers that pay by the hour.
|
||||
|
||||
|
||||
|
||||
“The product was conceived with the understanding that everything was moving to the cloud, and the cloud was becoming the right place for businesses of any nature to house and process data. But at the same time, there were associated perils—like downtime—that were excluded and restricted from most policies, creating a huge coverage gap,” according to Neta Rozy, co-founder and chief technology officer of Parametrix Insurance, a New York-based managing general agent.
|
||||
|
||||
“We were surprised that this risk wasn’t covered before we started operating in this space. But as we built out our product, we better understood the reasons why and structured the company and our solution to make it possible,” she said.
|
||||
|
||||
Waiting periods for cyber insurance and other tech-related insurance start from at least eight hours and are usually more than 12 hours.
|
||||
|
||||
“One of the biggest challenges in offering this type of solution is having enough reliable data on outages to develop models to quantify downtime peril,” Rozy said in an emailed interview with *Carrier Management*.
|
||||
|
||||
Previously, she affirmed, this data had not been collected in a systematic way with the necessary accuracy and reliability. As a result, the company’s first order of business was to create the monitoring systems that would independently verify uptime and downtime for the cloud and other enterprise technologies, Rozy said.
|
||||
|
||||
“We set out to develop a cutting-edge system to monitor SaaS, PaaS and IaaS systems around the globe for downtime events, such as cloud outages, network crashes and platform failures,” she said, referring to software-as-a-service, platform-as-a-service and infrastructure-as-a-service systems.
|
||||
|
||||
“The goal was to quantify and measure the peril. The millions of data points our system collects daily are the basis for our insurance products. Monitoring is external and objective, which allows us to adopt a parametric model. It’s simple, transparent, easy to understand and carries plenty of appeal to businesses,” she explained.
|
||||
|
||||
By developing these data-driven insights, Parametrix was able to earn the trust of insurers and reinsurers and develop “solid, business-critical insurance products,” she affirmed. “We could ascertain that cloud downtime was uncorrelated with other perils and an entirely new market directly linked the fast-growing categories of cloud and tech spend.”
|
||||
|
||||
Parametrix further solidified the concept that this was an insurable peril by getting valuable feedback during its participation with Lloyd’s Lab, the Lloyd’s innovation accelerator.
|
||||
|
||||
“Once the monitoring system was in place and we had sufficient data to model cloud outages, we were able to gain the trust of certain underwriters of Lloyds of London and other top reinsurers,” Rozy said. The company has previously revealed it has capacity provider relationships with HannoverRe, TMK and other markets at Lloyds, and has broker relationships with major brokers such as Alliant, Arthur J. Gallagher, Brown & Brown, Howden Broking, Hub International, Lockton and Woodruff Sawyer.
|
||||
|
||||
Parametrix’s monitoring system continuously tracks the availability and performance of all of a client’s mission-critical third-party IT services without the need for any IT installations. Once the system identifies a downtime event in one of the services a client has insured, the client is automatically notified and will be indemnified within 15 business days, at the most, according to the company’s website.
|
||||
|
||||
The company coverage is typically $100,000 to $5 million for an annual policy, but limits can extend to $10 million per insured. Once the policy limits have been met (from one or multiple claim events), clients can renew their policies before the year ends. There is an agreed hourly coverage rate, and the coverage kicks in in as little as one hour.
|
||||
|
||||
“Parametrix is relevant for businesses of all sizes, from private to public. The only prerequisite is exposure to the cloud or other third-party IT services,” Rozy continued.
|
||||
|
||||
The product covers damages to intangible and tangible assets during a public cloud failure. “This can include lost revenue if a website is down, lost opportunities, lost productivity, tarnished brand reputation, missed SLAs [service level agreements] and customer compensation,” she said.
|
||||
|
||||
Coverage can kick in as soon as an hour after the start of a downtime event, and there are no cash deductibles. A policy can last up to 12-24 hours, after which other traditional cyber policies could kick in, she explained.
|
||||
|
||||
The money can be used to reduce the volatility of a company’s revenue stream and support the insured’s customers for lack of service, the company explained on its website.
|
||||
|
||||
**Proof-of-Concept**
|
||||
|
||||
The company rolled out its first cloud downtime product in 2020 in Israel. As a result of this successful proof-of-concept program, it now also sells an expanded roster of products in the U.S., Israel, Germany, Austria, Italy and Japan (via Sompo).
|
||||
|
||||
“We started with cloud downtime insurance, as it is often the highest spend item for businesses after payroll and it’s also one of their fastest growing line items. Moreover, the cloud has become the host of businesses’ most mission-critical resources, assets and tools,” said Rozy.
|
||||
|
||||
Howden has had a relationship with Parametrix since its launch. David Rees, executive director for Howden Specialty, said there was massive interest across the globe when the product was first launched, mainly because of this unique product that has a quick and simple payout mechanism and no claims settlement process.
|
||||
|
||||
By contrast, if business interruption is purchased under a cyber insurance policy, “there’s a waiting period on that policy, which stipulates that the computer system has to be down for 12 hours before the policy wording agrees it is a loss and allows a claim to be made,” he said in an interview.
|
||||
|
||||
This, Rees acknowledged, can be crippling for some insureds whose businesses rely on these third-party services.
|
||||
|
||||
Downtime of cloud providers can be covered in certain cases under cyber policies, but the coverage is limited by long waiting periods of 12 hours or more, narrowly named perils and only covering specific losses, which leaves clients exposed without any real chance of compensation, a Parametrix representative explained.
|
||||
|
||||
**Expansion Plans**
|
||||
|
||||
This year, the company will be expanding its coverage for outages of content delivery networks (CDNs), which most enterprise sites use to make their sites fast, Rozy said.
|
||||
|
||||
She cited [a real-life example from June of last year](https://www.carriermanagement.com/features/2021/06/21/222163.htm), when [CDN provider Fastly crashed](https://www.carriermanagement.com/news/2021/06/18/222126.htm) and websites such as Twitch, Reddit, GitHub, The New York Times, BBC, Lonely Planet, Shazam, The Rolling Stone and others crashed for more than an hour.
|
||||
|
||||
“Our plan is to cover more and more enterprise technologies and become the defacto standard for technology downtime insurance,” she said, citing other third-party IT services that are key to SMEs such as content delivery networks, e-commerce platforms, payment platforms, customer relationship management services and enterprise resource planning cloud solutions.
|
||||
|
||||
**This [article first was published](https://www.carriermanagement.com/features/2022/02/16/232735.htm) in Insurance Journal’s sister publication, [Carrier Management](https://www.carriermanagement.com/).**
|
||||
|
||||
Was this article valuable?
|
||||
|
||||
Here are more articles you may enjoy.
|
||||
|
||||
 Viewpoint: After 3 Years of Retreat, Insurance Capacity Is Returning to California
|
||||
|
||||
 GEICO Avoids Class Action Over Totaled Vehicle Payouts in New Jersey
|
||||
|
||||
 Lockton Named in NBA Investigation Into Clippers Salary Cap Circumvention
|
||||
|
||||
 Viewpoint: Reinsurance Market to Experience Further Softening, M&A on Ample Capacity
|
||||
@@ -0,0 +1,169 @@
|
||||
# Diary of a First-Time On-Call Engineer
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Anna Baker — LaunchDarkly (via The New Stack)
|
||||
- **链接**: https://thenewstack.io/diary-of-a-first-time-on-call-engineer/
|
||||
|
||||
## 简介
|
||||
|
||||
LaunchDarkly revamped the way that their on-call system works. Learn about the experience through the eyes of a newly-onboarded engineer.
|
||||
|
||||
## 正文
|
||||
|
||||
# Diary of a First-Time On-Call Engineer
|
||||
|
||||

|
||||
|
||||
[via](https://nappy.co/photo/2349)Nappy.
|
||||
|
||||
[LaunchDarkly](https://launchdarkly.com/?utm_content=sponsor+disclosure)sponsored this post. Insight Partners is an investor in LaunchDarkly and TNS.
|
||||
|
||||
|
||||
|
||||
[Anna Baker
|
||||
Anna Baker is a software engineer at LaunchDarkly, where she has spent the past few years advocating for inclusive processes and bridging the gap between product engineering and site reliability. She is also a part-time graduate student pursuing an M.S. in computer science at Georgia Tech.](https://github.com/annabkr)
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||
There is a clear business need for having engineers on call. One of the best ways to retain and gain customers is to deliver excellent, world-class service and a product they can rely on. Developing skills that drive business value not only will help engineers in their current role, but can prepare them for any role or level they may want in the future. Volunteering for on-call rotation can help the individual and the company.
|
||||
|
||||
While taking on a new opportunity is exciting, it also comes with nerves. Maybe you have commitments outside of work like grad school classes or family obligations. Maybe you enjoy your evenings and weekends. What do you do if an alert comes in about a service that you’re not familiar with?
|
||||
|
||||
Change can be scary, which is often why processes don’t change within organizations, but as companies grow, they may need to rethink their on-call rotation. Last year, LaunchDarkly modified our on-call process for engineers, as we had outgrown our previous model.
|
||||
|
||||
A few years ago, engineers worked together on one of two large teams: the Application team and the Backend Services team. Small groups of people would come together for projects, but then disperse when the project was over. The Backend Services team handled all the on-call responsibilities.
|
||||
|
||||
As we grew, we adopted the squad model. Each squad has an engineering manager, a product manager, a designer and five to seven engineers that work on a subset of our features.
|
||||
|
||||
After some time, the squad model evolved and adopted service ownership. Each squad became responsible for a subset of our backend services. However, we didn’t change the engineers who were on call in a substantial way. They were almost exclusively engineers who were at one point, or would have been*,* on the defunct Backend Services team. We decided a new process was needed.
|
||||
|
||||
## Change Happens
|
||||
|
||||
There were multiple discussions internally about what the new on-call process should look like. We needed to make sure the rotation was equitable and that we had appropriate coverage. In the end, we decided on the following:
|
||||
|
||||
- Squad members are on call during regular business hours for the services their squad owns.
|
||||
- For off-hours, responsibilities are distributed between the U.K. team during their normal business hours and the Virtual On-Call squad, a volunteer-based group of engineers split across two rotations that cover different subsets of our services, who take on primary responsibilities for the evening and weekend shifts.
|
||||
- On-call engineers with off-hours responsibilities are paid for their contribution.
|
||||
|
||||
If you’re considering changing your on-call rotation, have open conversations to get various perspectives on what works and what challenges might be encountered.
|
||||
|
||||
## How to Onboard New Engineers to the On-Call Rotation
|
||||
|
||||
One of the most important aspects is to have an engineering culture that fosters learning and psychological safety. On-call engineers need an onboarding process that sets them up for success, knowing that they will have help, that if something goes wrong, they won’t be blamed. Feeling safe to learn and explore means knowing it’s OK to make mistakes.
|
||||
|
||||
Be clear with people who are thinking to join an on-call rotation about what the expectations are.
|
||||
|
||||
I received the following message from my manager when I was thinking about joining the rotation.
|
||||
|
||||
“In general the expectation is to try your best with what you know, and if you don’t know how to address the issue, escalate. Over time the people that are being escalated to will think ‘hmm, next time if I don’t want to get a page, I should arm the virtual squad with whatever it needs to handle this.'”
|
||||
|
||||
In the weeks leading up to an inaugural shift, consider the following:
|
||||
|
||||
-
|
||||
- Provide online or in-person training to give engineers confidence in the process and in their ability to succeed at being on call.
|
||||
- Host meetings and conduct question-and-answer sessions for the on-call rotation.
|
||||
- Have managers or leads check in on how the new engineers are feeling and send a test page. Normalize that it’s OK to feel a rush of adrenaline when you get paged:
|
||||
|
||||
**Manager**: Was this your first time being paged?
|
||||
|
||||
**Me**: Yup
|
||||
|
||||
**Manager**: Did your heart skip a beat? At least 10 years into on-call, I still sort of jump when I get an alarm :-)
|
||||
|
||||
|
||||
- Establish a co-pilot system with experienced on-call engineers who will pair up with onboarding on-call engineers as their on-call backup for their first few shifts.
|
||||
- Assign new engineers to an experienced co-pilot for the rotation and devise a plan for how to communicate if needed.
|
||||
|
||||
## Diary of a First-Time On-Call Engineer
|
||||
|
||||
While the above advice may sound good in theory, you may be wondering, in practice, how do things go for new on-call engineers? I signed on to join the inaugural Virtual On-Call rotation, and below is my log of my first week on call.
|
||||
|
||||
### Day 1, Monday
|
||||
|
||||
At around 8:30 p.m., I was at home in my jammies playing “The Sims 4” when I got my first legitimate page. It was thrilling! I hopped on my computer.
|
||||
|
||||
Within minutes, I got another notification that a colleague on the other rotation had been paged for something related.
|
||||
|
||||
We both hopped online. I suggested that we start a public thread in the virtual squad Slack channel instead of direct messaging so people could learn from our mistakes and help us improve the onboarding process.
|
||||
|
||||
We spent about 45 minutes looking at the alert catalog, the runbook for the services and trying to fix the underlying problem. After getting more information, we realized it was not affecting customers and could wait until the team that owned the service came online.
|
||||
|
||||
I spent another 30 minutes updating the Captain’s Log, the log we use to communicate about events that might affect backend services, and notifying the squad that owned the service.
|
||||
|
||||
### Day 2, Tuesday
|
||||
|
||||
Silence.
|
||||
|
||||
### Day 3, Wednesday
|
||||
|
||||
At around 5:15 p.m., I got paged while still working.
|
||||
|
||||
Ironically, the cause for this alert was the remediation for Monday’s alert
|
||||
|
||||
We realized it was an alert for a piece of system architecture due for retirement and no longer serving customer traffic. We throttled the offending service and silenced the alert until the morning.
|
||||
|
||||
Badda bing, badda boom.
|
||||
|
||||
### Day 4, Thursday
|
||||
|
||||
At 9 a.m., the alert from the night before unsnoozed itself and let me know that I need to figure out what to do about it. Note that typically I would not have been responsible for on call during business hours, but I had set up the alert to unsnooze then since I knew I’d be at my computer.
|
||||
|
||||
I created a thread in my squad’s on-call channel since the alert was for a service my squad owned and within minutes, it was clear that we could delete the alert and permanently wind down the service. 🍰
|
||||
|
||||
### Day 5, Friday
|
||||
|
||||
Silence.
|
||||
|
||||
### Day 6, Saturday
|
||||
|
||||
This was by far the most eventful day.
|
||||
|
||||
### Morning
|
||||
|
||||
At 5 a.m., I got paged. I jumped out of bed and ran over to my computer.
|
||||
|
||||
The page self-resolved at 5:01 a.m. 🤣
|
||||
|
||||
Now wide awake, I spent some time on Google reading documentation about the service that had paged me before eventually going back to sleep.
|
||||
|
||||
### Afternoon
|
||||
|
||||
I dared to venture to a park nearby.
|
||||
|
||||
I brought my laptop and my cell phone with tethering capabilities and was prepared to run home if needed.
|
||||
|
||||
Of course, Murphy’s law, I got paged.
|
||||
|
||||
I pulled out my laptop, tethered my phone and popped online. Sitting at a playground picnic table, I re-ran the test that had failed and alerted me. It passed.
|
||||
|
||||
I was on standby but able to enjoy the rest of my day.
|
||||
|
||||
### Day 7, Sunday
|
||||
|
||||
I woke up and thanked PagerDuty for no 5 a.m. alert.
|
||||
|
||||
The rest of Sunday was quiet as well.
|
||||
|
||||
## What I Learned
|
||||
|
||||
At the beginning of the week, I was prepared to have to declare multiple incidents and getting paged constantly.
|
||||
|
||||
Instead, most days were quiet. I was surprised by how few alerts there were, especially low-priority alerts, which I thought were going to be incessant. I attribute this to LaunchDarkly’s commitment as an organization to scalability and investment in making our services production-ready.
|
||||
|
||||
Perhaps I got exceptionally lucky this week, but overall, it was enthralling, and I’m glad I volunteered. It gave me an incentive to Google things I wouldn’t typically research, read the alert catalog and service runbooks, and I learned a bunch.
|
||||
|
||||
- Was there an increased cognitive load from having LaunchDarkly in the back of my mind 24/7? Yes.
|
||||
- Did I check my phone too many times, anxious about missing an alert? Also, yes.
|
||||
- Will those things improve over time? Probably.
|
||||
- Was it thrilling? Did I learn anything? Yes and yes!
|
||||
|
||||
If you’re interested in learning more about incidents, sign up to attend [IRConf](http://irconf.io), a virtual event dedicated to all things incident response.
|
||||
|
||||
|
||||
[YOUTUBE.COM/THENEWSTACK
|
||||
|
||||
|
||||
Tech moves fast, don't miss an episode. Subscribe to our YouTube
|
||||
channel to stream all our podcasts, interviews, demos, and more.](https://youtube.com/thenewstack?sub_confirmation=1)
|
||||
24
sreweekly/markdown/313/04-2021-sre-report.md
Normal file
24
sreweekly/markdown/313/04-2021-sre-report.md
Normal file
@@ -0,0 +1,24 @@
|
||||
# 2021 SRE Report
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Catchpoint
|
||||
- **链接**: https://www.catchpoint.com/asset/sre-report-2021
|
||||
|
||||
## 简介
|
||||
|
||||
Catchpoint’s yearly SRE Report is out with four key findings. You have to fill out a form with your email address, and then the link to download the report is presented in your browser.
|
||||
|
||||
## 正文
|
||||
|
||||
**NOW AVAILABLE!** [**Download The SRE Report 2025**](https://www.catchpoint.com/asset/2025-sre-report)
|
||||
|
||||
This year’s report, written in partnership with DevOps Institute and VMware Tanzu, analyzed survey responses from more than 300 site reliability engineers across a range of industries and company sizes worldwide. It reveals a wide range of fascinating insights and concludes with an actionable path for SREs to consistently deliver customer value.
|
||||
|
||||
Here is a sneak peek into a few of the insights we dig into:
|
||||
|
||||
- Levels of toil are lower around the world. Why?
|
||||
- The rise in multiple providers highlights the need for Platform Ops.
|
||||
- The shift toward AIOps is slow.
|
||||
- Observability must expand to include digital experience metrics and business KPIs.
|
||||
|
||||
Download the SRE Report 2021 today!
|
||||
@@ -0,0 +1,324 @@
|
||||
# Little’s Law, Scalability and Fault Tolerance: The OS is your bottleneck. What you can do?
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Ron Pressler — Parallel Universe (via High Scalability)
|
||||
- **链接**: http://highscalability.com/blog/2014/2/5/littles-law-scalability-and-fault-tolerance-the-os-is-your-b.html
|
||||
|
||||
## 简介
|
||||
|
||||
This article shows why one-thread-per-request can be a bottleneck and presents alternatives.
|
||||
|
||||
## 正文
|
||||
|
||||
[Actor](https://highscalability.com/tag/actor/)
|
||||
|
||||
# TGl0dGxl4oCZcyBMYXcsIFNjYWxhYmlsaXR5IGFuZCBGYXVsdCBUb2xlcmFuY2U6IFRoZSBPUyBp cyB5b3VyIGJvdHRsZW5lY2suIFdoYXQgeW91IGNhbiBkbz8=
|
||||
|
||||
|
||||
|
||||
*This is a guest* *repost* *by Ron Pressler, the founder and CEO of* *Parallel Universe**, a Y Combinator company building advanced middleware for real-time applications.*
|
||||
|
||||
*Little’s Law helps us determine the maximum request rate a server can handle. When we apply it, we find that the dominating factor limiting a server’s capacity is not the hardware but the OS. Should we buy more hardware if software is the problem? If not, how can we remove that software limitation in a way that does not make the code much harder to write and understand?*
|
||||
|
||||
Many modern web applications are composed of multiple (often many) HTTP services (this is often called a micro-service architecture). This architecture has many advantages in terms of code reuse and maintainability, scalability and fault tolerance. In this post I’d like to examine one particular bottleneck in the approach, which hinders scalability as well as fault tolerance, and various ways to deal with it (I am using the term “scalability” very loosely in this post to refer to software’s ability to extract the most performance out of the available resources). We will begin with a trivial example, analyze its problems, and explore solutions offered by various languages, frameworks and libraries.
|
||||
|
||||
## Our Little Service
|
||||
|
||||
Let’s suppose we have an HTTP service accessed directly by the client (say, web browser or mobile app), which calls various other HTTP services to complete its task. This is how such code might look in Java:
|
||||
|
||||
```
|
||||
import ...;
|
||||
@Path("myservice")
|
||||
public class MyRestResource {
|
||||
private static final Client httpClient = ClientBuilder.newClient();
|
||||
@GET
|
||||
@Produces(MediaType.TEXT_HTML)
|
||||
public String getIt() {
|
||||
int failures = 0;
|
||||
// call foo (synchronous)
|
||||
String fooResponse = null;
|
||||
try {
|
||||
fooResponse = httpClient.target("http://s1.acme.com/foo").request().get().readEntity(String.class);
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
// call bar (synchronous)
|
||||
String barResponse = null;
|
||||
try {
|
||||
barResponse = httpClient.target("http://s1.acme.com/bar").request().get().readEntity(String.class);
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
|
||||
monitorOperation(failures);
|
||||
return combineResponses(fooResponse, barResponse);
|
||||
}
|
||||
}
|
||||
```
|
||||
To define a REST service, our example uses [JAX-RS](https://jersey.java.net/documentation/latest/user-guide.html?ref=highscalability.com#jaxrs-resources), though a plain Servlet or any other framework could have been used. To invoke other services, we use a [JAX-RS client](https://jersey.java.net/documentation/latest/user-guide.html?ref=highscalability.com#d0e3762), though other libraries could have been used (JAX-RS client is powerful and general, and supports integrating other libraries to perform the actual HTTP request; e.g. Jersey’s JAX-RS client integrates with Netty, Jetty or Grizzly clients).
|
||||
|
||||
To keep the example simple, instead of calling many “micro services”, we call just two, *foo* and *bar*, but we keep in mind that a real application might call many more. We also want to monitor failed service calls, so we count and report them.
|
||||
|
||||
Now let’s find the bottlenecks in our approach.
|
||||
|
||||
## Little’s Law
|
||||
|
||||
[Little’s Law](http://en.wikipedia.org/wiki/Little%27s_law?ref=highscalability.com) is a mathematical theorem useful in determining the capacity of a system such as ours that receives and processes external requests. For a *stable* system, it ties the average request arrival rate, *λ*, the average time each request is processed by the system, *W*, and the number of concurrent requests pending in the system, *L*, in a neat little formula:
|
||||
|
||||
*L = λW*
|
||||
|
||||
What’s remarkable about this result is that it does not depend on the precise distribution of the requests, the order in which requests are processed or any other variable that might have conceivably affected the result.
|
||||
|
||||
Here’s an example: if 1000 requests, on average, arrive each second, and each takes 0.5 seonds to process, on average, then our system is required to handle 1000*0.5 = 500 requests concurrently.
|
||||
|
||||
Normally, however, the system’s capacity, *L*, is a given, and the request processing time, *W*, is a feature of the software and depends on its complexity and internal latencies. If we know *L* and *W* we can figure out the rate of requests we can support:
|
||||
|
||||
*λ = L/W*
|
||||
|
||||
To handle more requests, we need to increase *L*, our capacity, or decrease *W*, our processing time, or latency.
|
||||
|
||||
What happens if requests arrive at a greater rate than *λ*? The system will no longer be stable. Requests will start queuing up. At first, they will experience much increased latency, but quickly system resources will be exhausted and the server will become unavailable.
|
||||
|
||||
## What Dominates the Capacity (*L*)
|
||||
|
||||
*L* is a feature of the environment (hardware, OS, etc.) and its limiting factors. It is the minimum of all limits constraining the number of concurrent requests. What are those limits?
|
||||
|
||||
Well, first, we have the number of concurrent TCP connections the server can support. Normally, a server can support several tens-of-thousands of concurrent TCP connections, and some shops have had success maintaining [over 2 million](http://blog.whatsapp.com/index.php/2012/01/1-million-is-so-2011/?ref=highscalability.com) open connections.
|
||||
|
||||
Second, we have bandwidth. Unless we are streaming HD video, the requests and responses travelling back and forth over the LAN are no more than a few kilobytes in length. If the total “chit-chat” volume of a single request is under 1MB (usually, it is well under), given today’s high-bandwidth LANs, our network could support anywhere between 100K to over a million concurrent requests (remember, we are talking about concurrent requests, not requests per second; services that require large message volumes usually take longer to process, so we’re those requests take longer than a second or even several seconds, and the network can handle that).
|
||||
|
||||
Third, there’s RAM. The number of concurrent requests that can fit in RAM depends on how much memory each request consumes, but assuming we can keep this to well below 1MB, and given the low cost of RAM, this number is probably well over 1 million, and certainly over several hundreds-of-thousands.
|
||||
|
||||
Fourth is the CPU. Just how many concurrent requests the CPU can support depends on the application logic, but given that most processing is done by the microservices and that most of the time our requests just wait for the microservices to responsd and don’t waste CPU, this number is anywhere between several hundreds of thousands and several millions. Indeed, productions systems employing similar architectures rarely report CPU as their bottleneck in practice.
|
||||
|
||||
So far, we have reason to believe we can keep *L* somewhere between 100K and 1 million. Sounds great, huh? But there is one more limiting factor: the OS. In our example, we employ the simple and familiar thread-per-request model. A request runs on a single OS thread to completion, and when it’s done, the web server is free to use that thread to serve other requests. So the number of concurrent request we can handle is also limited by the number of threads the OS can handle.
|
||||
|
||||
How do those threads behave? Well, they do some processing and then they block, waiting for a microservice to respond. Then they might do some more processing and block again. So the threads are not very busy (that’s why the CPU isn’t saturated), but they’re not just sitting there idle, either: the OS is required to schedule each of them anywhere between 2 and a few dozen times to complete the request.
|
||||
|
||||
So, how many such threads could the OS handle concurrently? That depends on the OS, but it is usually somewhere between 2K and 15K. Beyond that, thread scheduling will add significant latency to the requests, and once latency grows, *W* increases and *λ* drops again. Allowing the software to spawn thread willy-nilly may bring our application to its knees, so we usually set a hard limit on the number of threads we let the application spawn. This number is somewhere between 500 and 15K, but rarely more than that.
|
||||
|
||||
Because *L* is the *minimum* of all these limits, the OS scheduler suddenly dropped our capacity, *L*, from the high 100Ks-low millions, to well under 20,000!
|
||||
|
||||
In conclusion, if we use the thread-per-request model on good-enough hardware, *L* is *completely dominated* by the number of threads the OS can support without adding latency. We could, of course, buy more servers, but those cost money and incur many other hidden costs. We might be particularly reluctant to buy extra servers when we realize that software is the problem, and those servers we already have are under-utilized.
|
||||
|
||||
Before we look at other models that might work around this problem (and the issues they introduce), lets turn to examine *W*, the processing latency.
|
||||
|
||||
## Latency, in Sickness and in Health
|
||||
|
||||
Suppose our two micro-services, *foo* and *bar*, each take 500ms on average to return a response (including network latency). Since we call them sequentially (for the time being) our web service’s request processing time, or processing latency, is 1 second. That’s our *W*. Now, suppose we’ve allowed the web server to spawn up to 2000 threads (that’s now our *L*). According to Little’s law, we can handle up to
|
||||
|
||||
*λ = L/W* = 2000/1 = 2000
|
||||
|
||||
requests per second before we become unstable and crash. We figure that even taking into account traffic spikes that number is good enough.
|
||||
|
||||
Problem is, this calculation is only valid when both *foo* and *bar* are healthy. What happens if one of them experiences trouble which increases its latency to 10 seconds? From *W = 0.5 + 0.5 = 1* we’ve now gone to *W = 0.5 + 10 = 10.5* (let’s call it a round 10). What happened to *λ*? From 2000 requests per second it now dropped to 200, which we deem unacceptable.
|
||||
|
||||
So, to make our service fault-tolerant, we set timeouts for the service calls:
|
||||
|
||||
```
|
||||
@Path("myservice")
|
||||
public class MyRestResource {
|
||||
private static final Client httpClient;
|
||||
static {
|
||||
ClientConfig configuration = new ClientConfig();
|
||||
configuration.property(ClientProperties.CONNECT_TIMEOUT, TimeUnit.SECONDS.toMillis(2));
|
||||
configuration.property(ClientProperties.READ_TIMEOUT, TimeUnit.SECONDS.toMillis(2));
|
||||
httpClient = ClientBuilder.newClient(configuration);
|
||||
}
|
||||
// ...
|
||||
}
|
||||
```
|
||||
We’ve assigned our HTTP client a timeout parameter of 2 seconds to give it some leeway. This means that our maximum latency, even in the presence of failure, is 4 seconds, which yields a maximum request rate *λ* of 2000/4 = 500 per second.
|
||||
|
||||
In fact, we can do better. If *foo* goes bad and consistently times-out, there’s no need to try reaching it again and again, waiting for twho whole seconds each time. We can install a “circuit breaker” that trips if a service fails and prevents subsequent requests from attempting to call it. Ocassionally, a side process can sample *foo* to see if it has recovered, and if so, close the circuit again. This can bring our latency back to under 1 second, and our request handling capacity back to 2000 requests per second even in the event of a failure, at the cost of added complexity. This kind of circuit breaker mechanism is exactly what Netflix’s open source [Hystrix](https://github.com/Netflix/Hystrix?ref=highscalability.com) library provides. Its circuit breakers help prevent *W* from rising when something goes wrong. Also, instead of giving the server a single cap on the number of threads it can spawn, Hystrix makes it easy to allocate various capped thread-pools for different kinds of operations as a form of bulkheading failure (so that one operation that goes awry won’t exhaust all threads).
|
||||
|
||||
Now, assuming all our services are healthy or protected with circuit breakers, can we reduce *W* further? As a matter of fact we can, and quite easily, in fact. In our example, ee call *bar* only after *foo* returns, so their latencies are compounded. This might be OK for our little example, but if we call 20 services instead of 2, this could be a serious issue.
|
||||
|
||||
We notice that we don’t need the result of *foo* to call *bar*, so we can issue the two (or twenty) calls at the same time, let both them do their business in parallel, and absorb their latencies into one another. Here’s how we can do it in Java:
|
||||
|
||||
```
|
||||
@GET
|
||||
@Produces(MediaType.TEXT_HTML)
|
||||
public String getIt() throws InterruptedException{
|
||||
int failures = 0;
|
||||
// submit requests asynchronously
|
||||
Future<String> fooFuture = httpClient.target("http://s1.acme.com/foo").request().async().get().readEntity(String.class);
|
||||
Future<String> barFuture = httpClient.target("http://s1.acme.com/bar").request().async().get().readEntity(String.class);
|
||||
// collect responses (synchronously)
|
||||
String fooResponse = null;
|
||||
try {
|
||||
fooResponse = fooFuture.get();
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
String barResponse = null;
|
||||
try {
|
||||
barResponse = barFuture.get();
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
|
||||
monitorOperation(failures);
|
||||
return combineResponses(fooResponse, barResponse);
|
||||
}
|
||||
```
|
||||
Futures let us dispatch both requests at once, and then wait for their results. If all goes well, we’ve just reduced *W*, our processing latency, from 1 second to 500ms. The same applies for 20 or more service calls.
|
||||
|
||||
The result is that our server can now handle up to 4000 requests per second, even if we call quite a few micro services.
|
||||
|
||||
Is that the best we can do? Unfortunately yes. Short of somehow greatly optimizing both *foo* and *bar*, this is pretty much it, even though our hardware is still severely under-utilized. 4000 requests per second is the best we can do, and it might be much worse than that if we allow latency greater than 500ms for any of the micro services. What if this is not enough?
|
||||
|
||||
## Functional Callbacking
|
||||
|
||||
So we’ve taken down *W* as much as we could, but *L* is still constrained by the number of threads the OS can efficiently handle. The only thing left for us to do now is somehow increase *L*, and to do that we have no option other than abandon the thread-per-request model.
|
||||
|
||||
[Node.js](http://nodejs.org/?ref=highscalability.com) is a server side JavaScript framework used (primarily) for web applications. JavaScript is single-threaded, so Node has no choice when it comes to not using the OS thread scheduler. Let’s see how Node.js handles our problem:
|
||||
|
||||
```
|
||||
var http = require('http');
|
||||
http.createServer(myService).listen(8080);
|
||||
function myService(request, response) {
|
||||
var completed = 0;
|
||||
var failures = 0;
|
||||
var fooResponse;
|
||||
var barResponse;
|
||||
function checkCompletion() {
|
||||
if (completed == 2) {
|
||||
monitorOperation(failures);
|
||||
response.write(combineResponses(fooResponse, barResponse));
|
||||
response.end();
|
||||
}
|
||||
}
|
||||
http.get({host: 'http://s1.acme.com', port: 80, path: '/foo'}, function(resp){
|
||||
resp.on('data', function(chunk){
|
||||
fooResponse = chunk;
|
||||
completed++;
|
||||
checkCompletion();
|
||||
});
|
||||
}).on("error", function(e){
|
||||
completed++;
|
||||
failures++;
|
||||
checkCompletion();
|
||||
});
|
||||
http.get({host: 'http://s1.acme.com', port: 80, path: '/bar'}, function(resp){
|
||||
resp.on('data', function(chunk){
|
||||
fooResponse = chunk;
|
||||
completed++;
|
||||
checkCompletion();
|
||||
});
|
||||
}).on("error", function(e){
|
||||
completed++;
|
||||
failures++;
|
||||
checkCompletion();
|
||||
});
|
||||
}
|
||||
```
|
||||
Node request handlers do not have a thread for themselves and they don’t block. Instead, they run for a while, and when they need to wait for, say, a service call, they give the framework a callback to execute when the call completes. By doing that, Node has turned JavaScript’s lack of threading into an advantage. Because it can’t use a thread-per-request model, Node uses asynchronous callbacks which do not suffer from the OS thread limitation.
|
||||
|
||||
But while this approach completely eschews the OS thread limit problem, it introduces several others. First, any accidental blocking of a handler function, or even if it happens to be running a lengthy computation, effectively blocks the entire Node.js instance; no other requests can be processed. This is often mitigated by running several Node instances on one machine and load-balancing them, which also helps take advantage of all CPU cores, but it wastes RAM and makes parallelizing certain computational tasks difficult (the latter might or might not matter, depending on what you want to accomplish).
|
||||
|
||||
More importantly, however, it forces an asynchronous, callback-based programming style. This style is harder to write and harder to reason about, as your code is not executed in the order it is written. With complex, dependent operations, this style is the nightmare colloquially known as callback hell (Node.js is trying to make this simpler by adopting a more comprehensively-functional style with something called promises; we’ll look at a similar approach right away).
|
||||
|
||||
One of the things working in Node’s favor, however, is that it’s single threaded. Why is that good? Because it keeps our example code simpler. While the calls to *foo* and *bar* are submitted asynchronously and their callbacks can be executed at any time and any order (once they complete), we can still safely increment the `failures` and `completed` variables, because whenever the callbacks run, they will all run on the same thread – never concurrently. So while we have to wrap our heads around callbacks, thankfully we don’t need to factor concurrency races into the equation as well.
|
||||
|
||||
But the JVM does support multiple threads, and if you have them, why not use them? Let’s see how [Play](http://www.playframework.com/?ref=highscalability.com), a JVM web framework, handles the problem. Again, our goal is to avoid hogging an OS thread for the duration of the request:
|
||||
|
||||
```
|
||||
public static Promise<Result> getIt() {
|
||||
Promise<String> fooPromise = WS.url("http://s1.acme.com/foo").get().map(
|
||||
result -> result.toString();
|
||||
);
|
||||
Promise<String> barPromise = WS.url("http://s1.acme.com/foo").get().map(
|
||||
result -> result.toString();
|
||||
);
|
||||
// Not actually waiting
|
||||
Promise<List<ResultType>> results = Promise.waitAll(fooPromise, barPromise);
|
||||
return async(results.map((List<String> rs) -> {
|
||||
String fooResponse = rs.get(0);
|
||||
String barResponse = rs.get(1);
|
||||
// monitoring ????
|
||||
return ok(combineResponses(fooResponse, barResponse));
|
||||
}
|
||||
});
|
||||
}
|
||||
```
|
||||
Play is written in Scala, which supports (among other styles), and sometimes encourages, a functional programming style, and this is reflected in Play’s Java API as well. I’ve written the code sample above in Java 8 because prior versions of Java were verbose to the point of exhaustion when written in the functional style, while the Scala API requires understanding of Scala for-comprehensions.
|
||||
|
||||
In practice, the functional style is callback-based, but it usually contains rigorous mechanisms for combining callbacks, which, once you learn them, can make your code much more methodic.
|
||||
|
||||
So, the functions in lines 3 and 7 will be executed when their calls (to *foo* and *bar* respectively) complete, and the one in line 14 will after when both complete, because the two promises (essentially futures) were combined with `Promise.waitAll`.
|
||||
|
||||
But what about our failure count? We cannot keep it in a local variable or even in a class field because the two callbacks can be called on any thread, even concurrently, and if they were to modify any shared state, race conditions are bound to happen.
|
||||
|
||||
To solve this, we need those promises to return not just a string, but a string and some other additional monitoring values (yes, I know failures specifically are reported differently, but this holds true for any other monitoring value we may want to collect), combined in a new class we need to define.
|
||||
|
||||
In addition, because the callbacks are not executed in the same thread as the original request handler (or the same thread as one another) we cannot use any library functions that rely on `ThreadLocal` state. Threads are gone.
|
||||
|
||||
If you don’t like Play’s API (which certainly feels very foreign to Java), the Netflix [RxJava](https://github.com/netflix/rxjava?ref=highscalability.com) project offers a functional API that operates along the same principles, not tied to a single web framework, and more familiar to Java programmers (and a lot nicer, IMO).
|
||||
|
||||
So while the functional style is elegant and helps compose callbacks nicely and in an idiomatic manner, using it entails a pretty serious learning curve, and it might bring about some baffling problems and race-conditions if you happen to interact with code that does not play well with the functional bits. In short, once you go functional you might find that you need to go functional all the way (at least within the service), or risk some serious head scratchers, especially if you’re not programming in a language that restricts shared mutable state, like Clojure or Erlang (or Haskell, if you’re so inclined).
|
||||
|
||||
… aaaand that’s it. We’re no longer using threads to guide the flow of our code and delineate requests, so *L* is no longer dominated by the OS’s scheduling capacity. It is solely determined by our hardware capacity and whatever (hopefully small) overhead the frameworks/libraries we use incur. We only need to buy more hardware if our hardware is saturated.
|
||||
|
||||
All is well and good except for one thing: we’ve lost the thread-per-request model. Nobody likes nesting callbacks, and while some may argue that a functional style is the way to go no matter what you do, it is unfamiliar, arguably more difficult to reason about in some circumstances, and as yet unproven in the industry. Also, threads are nice. They give us a clear program flow along with a stack for intermediate state. Must we completely throw this wonderful abstraction out the window? Are scalability (and fault tolerance), and simple, easy to follow code mutually exclusive? Luckily, they are not.
|
||||
|
||||
## Lightweight Threads
|
||||
|
||||
If you remember how we started, it was by realizing that the server’s capacity, or *L* in Little’s formula, is dominated by the OS’s thread scheduling capability. Becasue we had to cap our threads at some relatively small number, they became a precious resource. The circuit-breakers and the functional programming style were required *because threads are expensive*. But what if they didn’t have to be?
|
||||
|
||||
Some languages, most notably Erlang and Go, provide lightweight threads (processes in Erlang; goroutines in Go). The open-source [Quasar](https://github.com/puniverse/quasar?ref=highscalability.com) library provides them on the JVM (where they’re called fibers). These lightweigh threads are not scheduled by the OS but by the language or library runtime. The runtime can often do a far better job than the OS at scheduling those lightweight threads because it knows more about their purpose. In particular it knows that they run in very short bursts and block very often; this is not generally true of heavyweight threads. The runtime scheduler usually employs what is known as M:N scheduling, where M lightweight threads are mapped onto N OS threads, with M » N.
|
||||
|
||||
Just like anything else, lightweight threads aren’t magic, and they have their own tradeoffs. Their main problem is that all blocking function calls you issue on a lightweight thread must be integrated with the scheduler. If a library function is not aware of the scheduler it might block the entire OS thread (Quasar monitors all running fibers and issues a warning when this happens; also, it easily handles non-frequent blocking of OS threads). In many circumstances, though, this is a very acceptable price to pay for keeping your code simple while gaining scalability and fault-tolerance. This is also not too hard to enforce, as blocking calls usually perform one of a small set of operations – network IO, file IO, or database calls – so making sure to only use libraries that are aware of your lightweight threads is usually easy (in fact, Quasar makes it very easy to turn any asynchronous, callback-based, API into a fiber-blocking API with a [simple mechanism](http://docs.paralleluniverse.co/quasar/?ref=highscalability.com#transforming-any-asynchronous-callback-to-a-fiber-blocking-operation)). And if Google’s [proposed user-level threads](https://www.youtube.com/watch?v=KXuZi9aeGTw&ref=highscalability.com) make it into the Linux kernel (which will then allow user code to schedule OS threads), Quasar will integrate with those and further reduce, or even completely remove, any possible conflict when integrating with non-fiber-aware blocking libraries.
|
||||
|
||||
The new open-source [Comsat](https://github.com/puniverse/comsat?ref=highscalability.com) library is a set of standard Java API implementations (like JAX-RS and JDBC) that integrate with Quasar fibers. So let’s see how we can re-write our original example to be scalable and fault-tolerant, this time using lightweight threads via Comsat:
|
||||
|
||||
```
|
||||
import ...;
|
||||
import co.paralleluniverse.fibers.ws.rs.client.AsyncClientBuilder;
|
||||
import co.paralleluniverse.fibers.SuspendExecution;
|
||||
@Path("myservice")
|
||||
public class MyRestResource {
|
||||
private static final Client httpClient = AsyncClientBuilder.newClient();
|
||||
@GET
|
||||
@Produces(MediaType.TEXT_HTML)
|
||||
public String getIt() throws InterruptedException, SuspendExecution {
|
||||
int failures = 0;
|
||||
// submit requests asynchronously
|
||||
Future<String> fooFuture = httpClient.target("http://s1.acme.com/foo").request().async().get().readEntity(String.class);
|
||||
Future<String> barFuture = httpClient.target("http://s1.acme.com/bar").request().async().get().readEntity(String.class);
|
||||
// collect responses (synchronously)
|
||||
String fooResponse = null;
|
||||
try {
|
||||
fooResponse = fooFuture.get();
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
String barResponse = null;
|
||||
try {
|
||||
barResponse = barFuture.get();
|
||||
} catch(ProcessingException e) {
|
||||
failures++;
|
||||
}
|
||||
|
||||
monitorOperation(failures);
|
||||
return combineResponses(fooResponse, barResponse);
|
||||
}
|
||||
}
|
||||
```
|
||||
You’ll notice that this is exactly the original example (after adding futures to absorb the two services’ latencies into each other) with some very minor changes! The first is adding `throws SuspendExecution` to our service method to designate it as a fiber-blocking method (alternatively you can annotate it with the `@Suspendable` annotation). The second is that we use the `AsyncClientBuilder` provided by Comsat, which provides the same JAX-RS client API, only with an implementation that is fiber-aware.
|
||||
|
||||
What about circuit-breakers? They’re not as critical now. We could add timeouts if we want to quickly respond back with a failure if one of the services takes too long, but other than that, we don’t mind the increased latency. Sure *W* might grow but *L* is now only contrained by the hardware. Fibers are cheap, and we can handle hundreds-of-thousands of them, or even millions, at once (we might still want to use a library like Hystrix to prevent an unbounded number of fibers from piling up, but even without it our server can recover gracefully from a short-term failure).
|
||||
|
||||
So we *can* have our cake and eat it, too! When you combine the awesome performance, stability, unparalleled tooling and monitoring of the JVM with the power and simplicity of lightweight threads, you can make the absolute most of your hardware while keeping your code simple, easy to understand, and familiar. You don’t even need to learn new APIs.
|
||||
|
||||
Both Clojure and Scala provide fiber-like functionality with Scala Async and Clojure’s wonderful core.async. But those are limited for use by their respective languages (i.e. they cannot integrate with other JVM languages), and even there, because they are based on macros, they are restricted to a single syntactical form: you can only explicitely block in the outermost “fiber” function – you can’t call another function that blocks.
|
||||
|
||||
## But What If I Like Functional Programming/CSP/Actors/Rx and Do Want to Learn New APIs?
|
||||
|
||||
That’s great! We like all of these concepts, but believe they should be used where they make sense as a computational model – when they make programming easier – not as a convoluted way to work around OS limitations. That’s why Quasar has Go-like channels complete with “reactive extensions” (or Rx) for good measure, as well as a full, Erlang-like actor system, all of which are built on top of the solid fiber foundation. They are great for making your business-logic, not just your service endpoints, scalable and fault tolerant. Quasar’s Clojure API, [Pulsar](https://github.com/puniverse/pulsar?ref=highscalability.com) is even compatible with core.async.
|
||||
|
||||
And while Comsat provides fiber-aware implementation of standard Java APIs, it also offers an optional API called Web Actors. Web Actors let you write web applications using the [actor model](http://en.wikipedia.org/wiki/Actor_model?ref=highscalability.com), popularized by Erlang. Web Actors give you excellent scalability and fault-tolerance, and are particularly fun to use in interactive web application, those that use WebSockets, or other server-push technologies (such as comet or SSE). Web Actors were discussed in our [previous blog post](http://blog.paralleluniverse.co/2014/01/28/web-actors-1/?ref=highscalability.com).
|
||||
|
||||
## Conclusion
|
||||
|
||||
Little’s law determines the load (request rate) a server can withstand given its (concurrent request) capacity and processing latency. We learned that when using the simple thread-per-request, the OS severly limits the server capacity. To maintain scalability and fault tolerance you must work around this limitation by either forgoing the simple thread-per-request model and adopting a functional programming style, or by using a language or a library that provides lightweight threads for your platform. If you’re developing for the JVM, [Quasar](https://github.com/puniverse/quasar?ref=highscalability.com) gives you lightweight threads (fibers), and [Comsat](https://github.com/puniverse/comsat?ref=highscalability.com) gives you fiber-aware implementations to standard Java APIs.
|
||||
101
sreweekly/markdown/313/06-on-the-brittleness-of-dashboards.md
Normal file
101
sreweekly/markdown/313/06-on-the-brittleness-of-dashboards.md
Normal file
@@ -0,0 +1,101 @@
|
||||
# On the Brittleness of Dashboards
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Fred Hebert — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/brittleness-of-dashboards/
|
||||
|
||||
## 简介
|
||||
|
||||
> And this is a truth about incidents: there are always more signals than there is attention available.
|
||||
|
||||
It’s so true.
|
||||
|
||||
## 正文
|
||||
|
||||
# On the Brittleness of Dashboards
|
||||
|
||||
Dashboards are one of the most basic and popular tools software engineers use to operate their systems. In this post, I’ll make the argument that their use is unfortunately too widespread, and that the…
|
||||
|
||||

|
||||
|
||||
By: [Fred Hebert](https://www.honeycomb.io/author/fred-hebert)
|
||||
|
||||
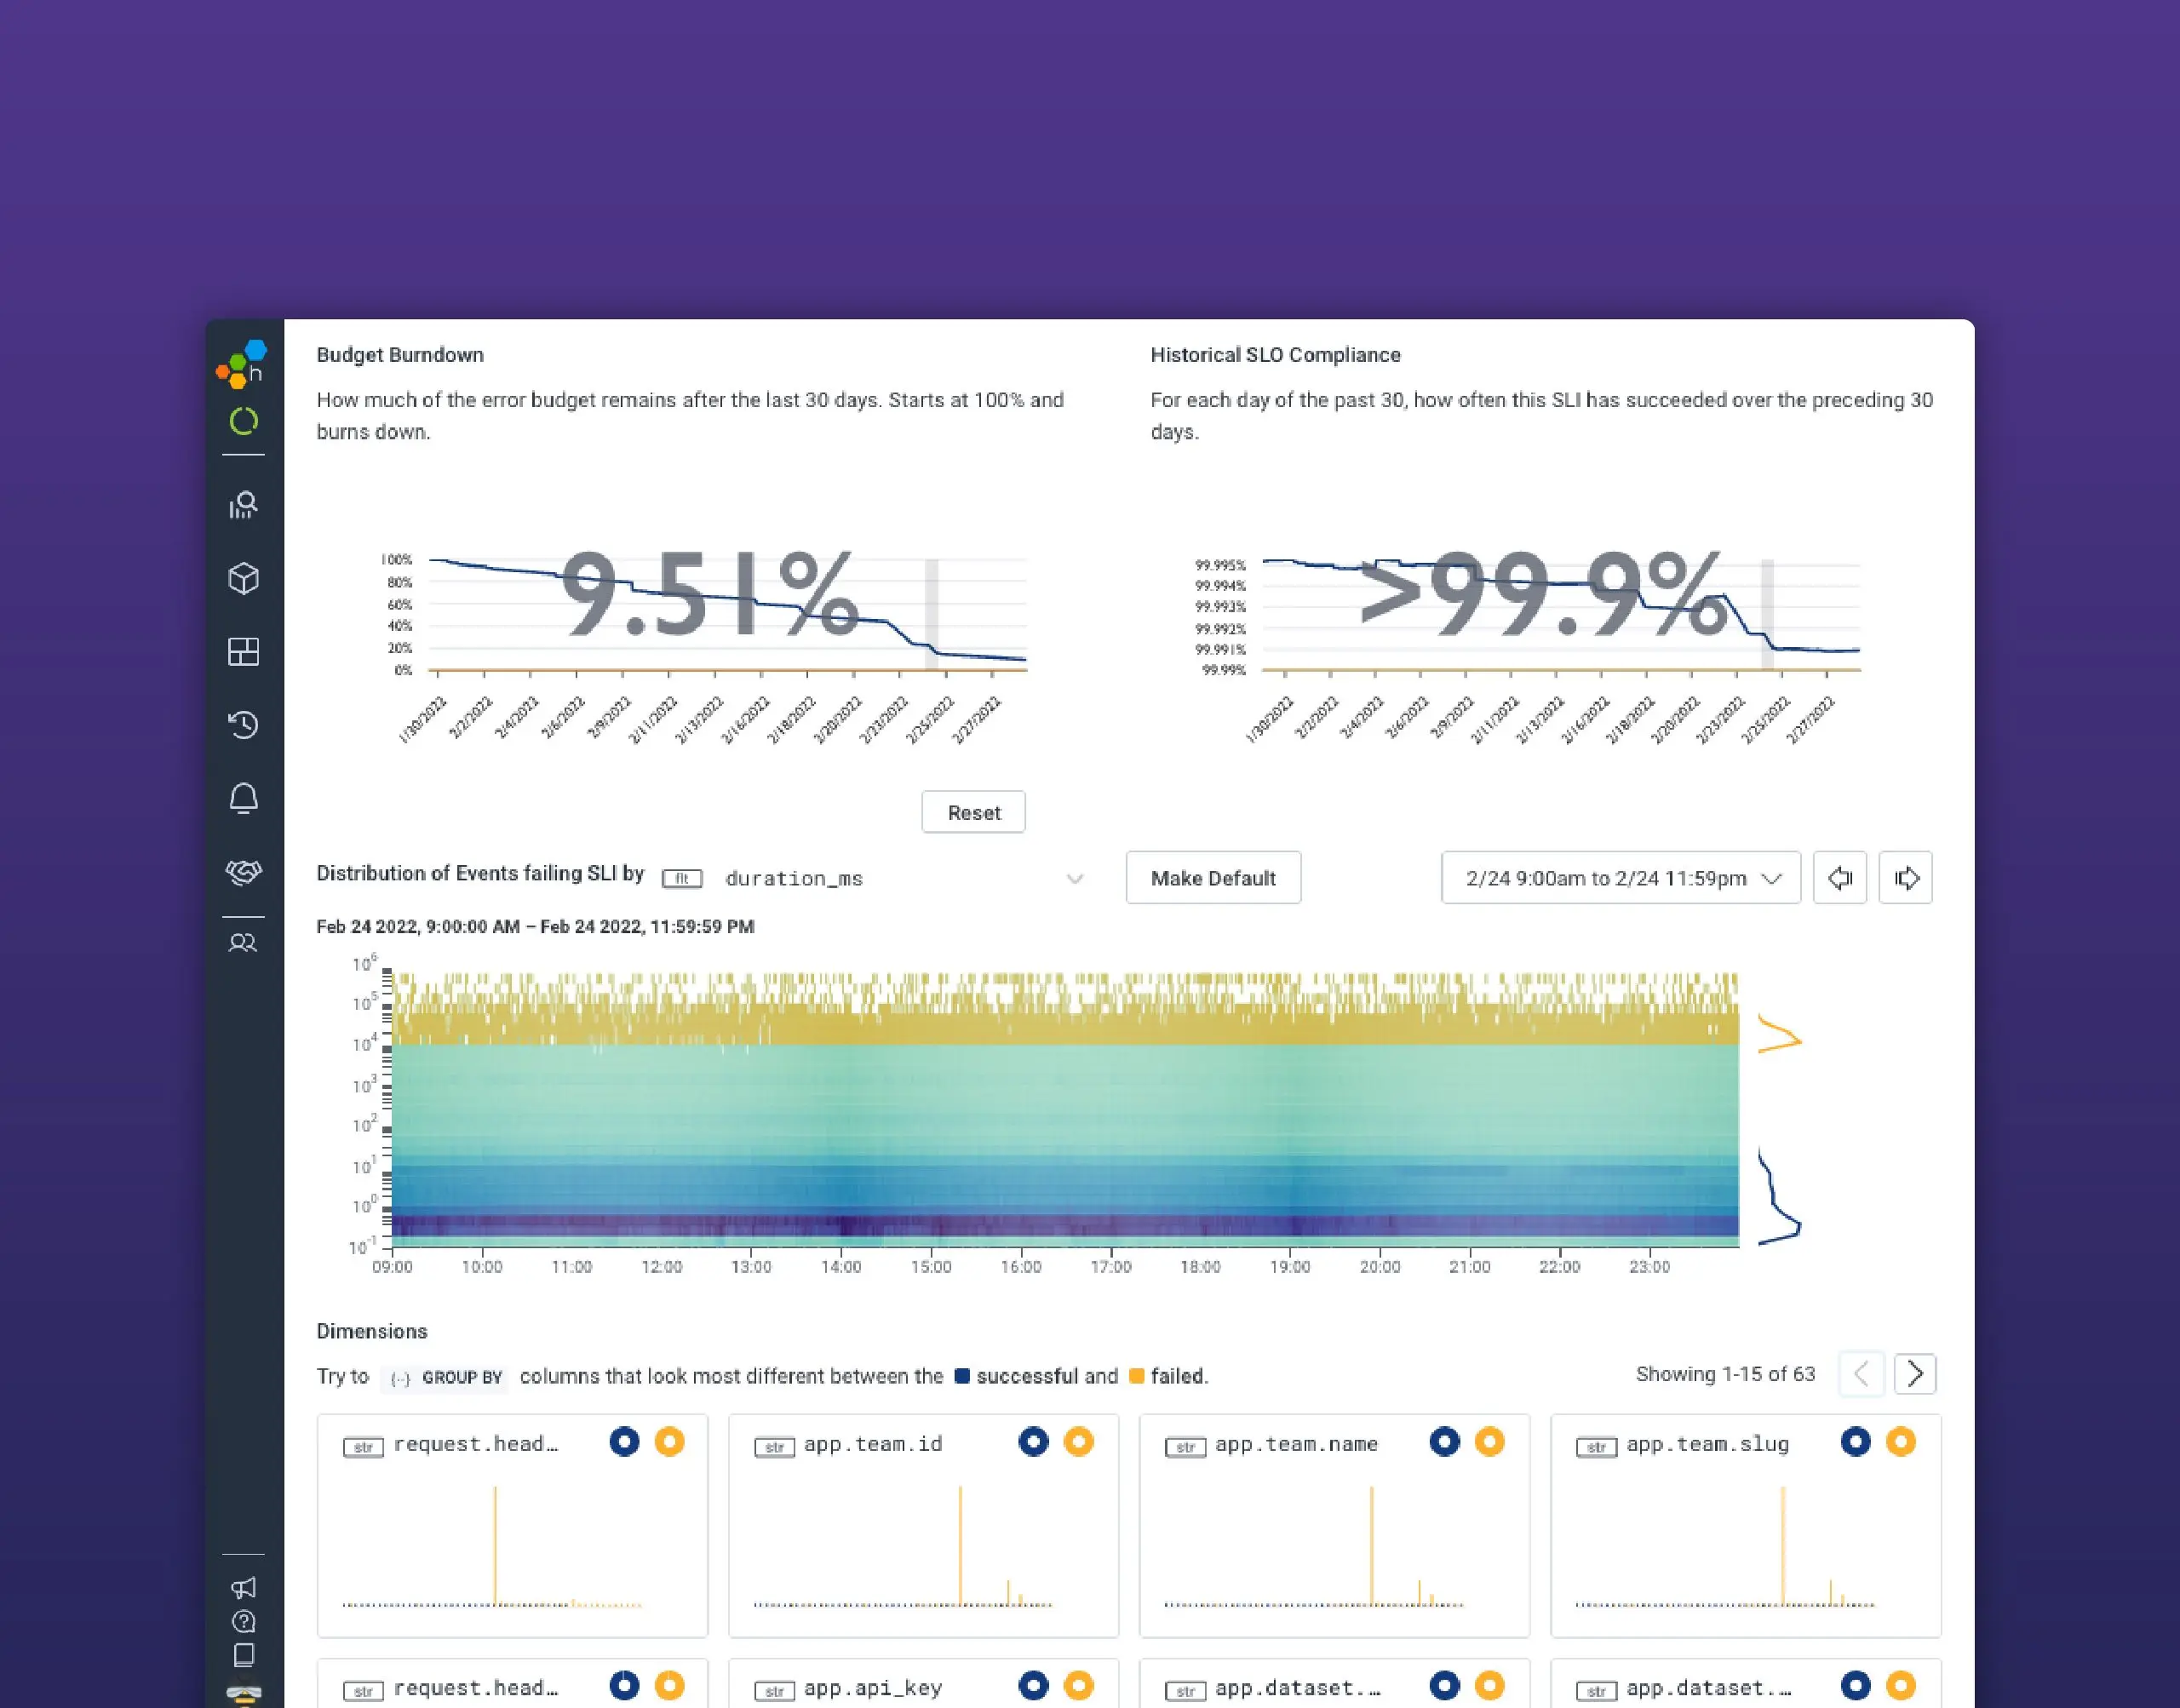
|
||||
|
||||
Dashboards are one of the most basic and popular tools software engineers use to operate their systems. In this post, I’ll make the argument that their use is unfortunately too widespread, and that the reflex we have to use and rely on them tends to drown out better, more adapted approaches, particularly in the context of incidents.
|
||||
|
||||
## **Why dashboards work**
|
||||
|
||||
Everything we do as Operators, DevOps, or Site Reliability Engineers (SREs) comes from a mental model. The mental model is our understanding of all the parts of the [socio-technical system](https://www.honeycomb.io/blog/the-future-of-software-is-a-sociotechnical-problem) and how they interact—what code is running, where and how it runs, who touches it, how it gets changed, how customers and users interact with it, the data it emits, and so on.
|
||||
|
||||
These mental models vary from people to people because nobody has the same experience and because all models—mental or not—[are wrong, but contextually useful](https://www.itsonlyamodel.com/). They are what lets us look into a tiny, narrow window into our systems, such as a set of limited metrics, and infer all sorts of hypotheses about the inner state of the system.
|
||||
|
||||
Over time, we can build the experience that lets us tie our mental models to the charts in a dashboard. We get a feel for the steady state—what is normal—and the sort of events and disruptions happening at various internal components that can result in expected fluctuations in the metrics.
|
||||
|
||||
It becomes a sort of high-speed, flexible, all-encompassing pattern recognition where you can glance at the dashboard and guess what’s right or wrong. And being in that position, with this ability, gives a powerful feeling of expertise.
|
||||
|
||||
## **Why dashboards are brittle**
|
||||
|
||||
Dashboards rely on a strong sense of normalcy; when used alone, each disruption to a metric’s change must be correlated to some cause that may be hard to find.
|
||||
|
||||
Changing reflexes takes time and effort. As such, if your system is changing all the time and the steady-state of all the metrics is not that steady, the ability to pattern match on fluctuations to know what is meaningful or not gets lost. In effect, to maintain that strong feeling of expertise, your understanding of the system needs to grow and adjust continuously. Your mental model must be updated.
|
||||
|
||||
This is particularly nefarious whenever you make a change to your system that changes what “normal” stands for. This pattern recognition we grow is a heuristic, and the heuristic is only good in certain contexts. When system changes require updating that sense of normalcy, we’re left to operate the system at production speed without the mental tools to do it quite as effectively anymore.
|
||||
|
||||
**In effect, you end up having to trade off being change-averse to protect your ability to sense the dashboard, or losing operational comfort in order to keep being able to adapt the system to a fast-changing world.**
|
||||
|
||||
## **How incidents unfold**
|
||||
|
||||
Outages are high-pressure, high-stakes situations, and when they happen:
|
||||
|
||||
- You can’t carefully analyze everything because there’s an emergency and lots of noise. When everything goes bad, the shock wave tends to hit most metrics in some way and you end up with heavy correlation with low causal clues.
|
||||
- You can’t thoroughly complete all actions because time pressure is high.
|
||||
- You are possibly responding out of context, tired, with other things on your mind, without a clear picture.
|
||||
|
||||
In short, you tend to *have even less attention available during an incident than outside of it.* Good incident response requires working with tools and patterns where *you need to think less than when you’re at rest.*
|
||||
|
||||
I’m emphasizing these sentences because they are critical. This sounds like an argument in favor of dashboards: fast pattern matching of signals generating fast explanations. We tend to use more dashboards because they’re tools that worked well when we had fewer, and we expect them to keep working tomorrow. As you add more data to each dashboard and grow the number of dashboards though, you’ll reach a point where they are no longer significantly useful *during an incident* because there is so much information going on that you can’t look at it all. In fact, you’ll find out that your operators only use a small subset of them and willingly ignore many of the metrics on them.
|
||||
|
||||
And this is a truth about incidents: there are always more signals than there is attention available. You can’t fix limited attention with more dashboards or more data; you generally help it with fewer and with better information organization.
|
||||
|
||||
Dashboards are a good way to expose information, but they’re not a good way to expose a lot of it. During an incident, the job includes communication, exploration, trying and running various commands, managing interrupts, looking over documentation, trying to make sense of events, and so on. Dashboards can’t demand your full attention because they won’t have it. You must keep them absolutely minimal and relevant. Accurate interpretation of crowded dashboards just isn’t compatible with high-pressure and high-stakes situations.
|
||||
|
||||
## **Where dashboards are adequate**
|
||||
|
||||
I like to compare the dashboards to the big display in a hospital room: body temperature, pulse rate, blood pressure, respiration rate, etc. Those can tell you when something looks wrong, but the context contained in the patient chart (and the patient themselves, generally in bed and at rest) is what allows interpretation to be effective. If all we have is the display but none of the rest—the patient could be anyone, anywhere in the world—then we’re never getting an accurate picture. The risk with the dashboard is having the metrics but not seeing or knowing about the rest changing.
|
||||
|
||||
I also like the comparison because these vitals are high-level signals that can let you know when something might be wrong, but they also are not a diagnostic on their own: they require to be interpreted in context. As far as I understand, none of these are sufficient for diagnostics; they’re rather used as a way to manage your attention at a very high level and as one of many sources of information.
|
||||
|
||||
Similarly, the dashboards we use for software systems should be high-level general concepts that mediate stimuli. They shouldn’t primarily be used for figuring out *why* something is wrong; instead, they should help us focus on whether something might be wrong.
|
||||
|
||||
Once again, the issue is that during an incident, there is too much data to sift through and too little attention available. We don’t know what will be going on. The context is too rich to be compressed into a few numbers. We likely won’t have the time to carefully look over each value and ponder it individually to figure out whether it’s important or not. **Our dashboards should be optimized to know what’s worth focusing on at a glance, not some sort of browser-based, tea-leaves reading session.**
|
||||
|
||||
## **Framing on-call interruptions**
|
||||
|
||||
One of the things I’ve tried to do here as an SRE has been to try and frame our on-call interruptions as their own user experience. The user flow starts with the alert, whether it’s received via a PagerDuty notification or a Slack message. I assume the operator is not looking at anything (they are possibly just waking up and in a bad mood) and currently doesn’t know what the situation is, but has a certain understanding of the system.
|
||||
|
||||
The alert itself should carry the base indications of what’s needed, either in its description or in links within the description:
|
||||
|
||||
- A quick description of the service(s) and the functionality the alert is about, in a sentence or two at most
|
||||
- The consequences of the alert situation extending in time, if anything other than unhappy users
|
||||
- The plausible or common failure modes and ways to quickly validate them (are you in a routine or abnormal situation?)
|
||||
- Ways to interact with that subsystem (common commands, links, and so on)
|
||||
- Background content that the responder may have wanted to read ahead of time because you never know what may be helpful or forgotten (design documents, past incidents, etc.)
|
||||
|
||||
Under that workflow, we need few dashboards. Particularly in the case of service-level objectives (SLOs), Honeycomb instantly shows what may or may not be an outlier through the [BubbleUp view](https://docs.honeycomb.io/working-with-your-data/bubbleup/). These can help hypothesis formation. In most cases, there’s a quick transition to an investigative mode that is very interactive, based on queries and richer data right away.
|
||||
|
||||
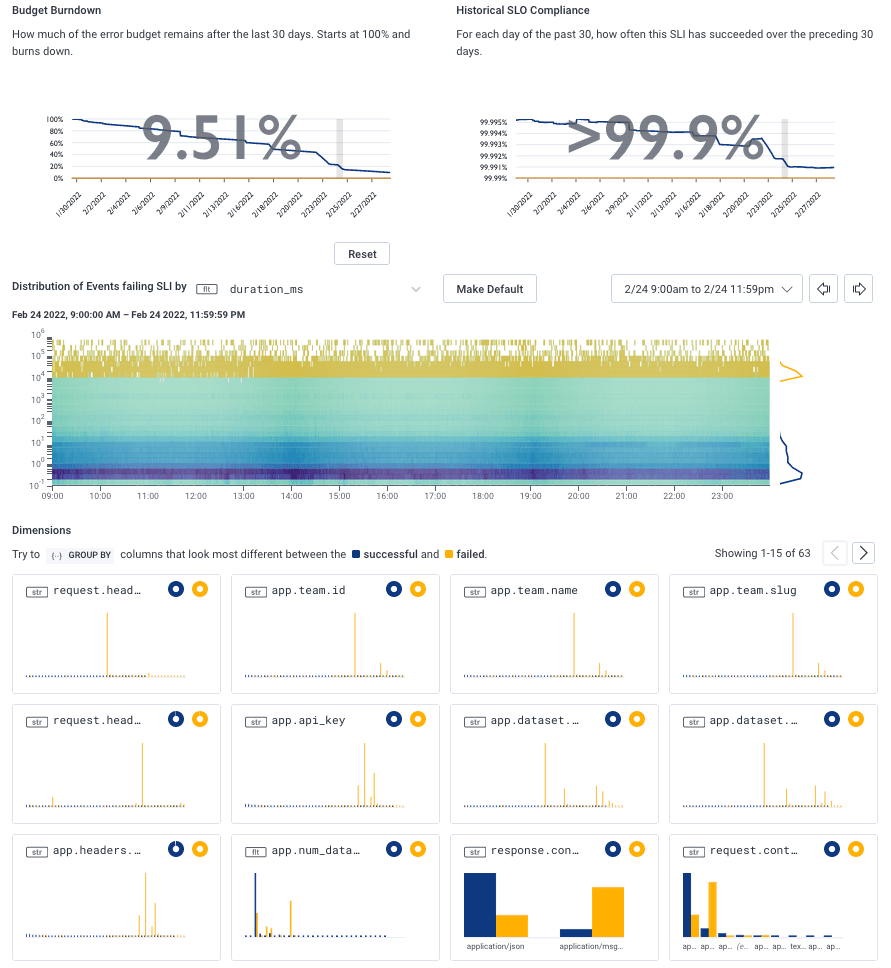
|
||||
|
||||
Trigger-based alerts are a case-by-case situation. Some may ask us to reach for a command line and poke at things directly, many will just redirect to a specific query, and a few will indeed redirect to a dashboard.
|
||||
|
||||
The alerts we have that do lead to dashboards try to keep them at a very high level, usually some informal variation of the[USE method](https://www.brendangregg.com/usemethod.html). They should not take more than a few seconds to comprehend or have much in terms of subtle details that must be extensively pondered ([Kafka](https://www.honeycomb.io/blog/scaling-kafka-observability-pipelines) is our biggest exception to this). They’re going to quickly orient the next line of investigation and that’s it.
|
||||
|
||||
Few dashboards in the traditional sense are required, and we rarely depend on pre-defined information displays. In general, the assumption is an alert that is based on high-level service indicators lets you bypass most of the requirements for a dashboard in the first place—we can skip most of the scan-and-match phase and direct the on-call engineer towards whatever gives them the most relevant context.
|
||||
|
||||
And the dashboard isn’t context, it’s the vitals. The context is richer than what the numbers directly carry and often lives outside of the observability tooling we have in place as well.
|
||||
|
||||
If you have more questions about dashboards or would like to share how you use them at your organization, we’d love to hear from you! Join us in our [Slack community Pollinators channel](https://join.slack.com/t/honeycombpollinators/shared_invite/zt-fv552707-y8m40UD2_~jonb1n9r5cNg) or [send us a tweet](https://twitter.com/honeycombio).
|
||||
|
||||
## Want to know more?
|
||||
|
||||
Talk to our team to arrange a custom demo or for help finding the right plan.
|
||||
@@ -0,0 +1,17 @@
|
||||
# Incident Analysis 101: Facilitating the Learning Review
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: Emily Ruppe — Jeli
|
||||
- **链接**: https://www.jeli.io/incident-analysis-101-facilitating-the-learning-review/
|
||||
|
||||
## 简介
|
||||
|
||||
If you’ve ever even considered running a retrospective, read this article.
|
||||
|
||||
This is my favorite piece of advice from this article:
|
||||
|
||||
> If you think ‘this might be a stupid question,’ ask it.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,64 @@
|
||||
# What Does AIOps Mean for SREs? It’s Complicated.
|
||||
|
||||
- **期号**: SRE Weekly Issue #313(2022-03-13)
|
||||
- **作者**: JJ Tang — RootlyThis article is published by my sponsor, Rootly, but their sponsorship did not influence its inclusion in this issue.
|
||||
- **链接**: https://rootly.com/blog/what-does-aiops-mean-for-sres-it-s-complicated
|
||||
|
||||
## 简介
|
||||
|
||||
I’m still not sure how I feel about AIOps. Fortunately, this article takes a measured stance while providing some useful insight.
|
||||
|
||||
> Conclusion: AI won’t replace SREs – but it can help
|
||||
|
||||
## 正文
|
||||
|
||||
If you’re an SRE, you might view AIOps with great excitement. By automating complex workflows and troubleshooting processes, AIOps could make your life as an SRE much easier.
|
||||
|
||||
Alternatively, SREs may choose to view AIOps with disdain. They might think of AIOps as just a fancy buzzword that doesn’t live up to its promises, and that can become a distraction from the [SRE tools that really matter](https://rootly.com/blog/7-essential-tools-for-sres).
|
||||
|
||||
Which perspective is right? Should SREs embrace AIOps with open arms, or should they resist marketers’ efforts to position AIOps as the latest, greatest tooling innovation in the IT industry?
|
||||
|
||||
Those are subjective questions that we can’t answer definitively, but let’s at least gain some perspective by examining what AIOps means for SREs.
|
||||
|
||||
## What is AIOps?
|
||||
|
||||
As you’ve probably heard by now if you keep up to date with your IT buzzwords, AIOps – which is short for [artificial intelligence for IT operations](https://www.appdynamics.com/topics/what-is-ai-ops) – is the use of AI and machine learning to help automate IT Ops workflows.
|
||||
|
||||
The big idea behind AIOps is that, by using AI and ML to perform advanced analysis of large volumes of data from IT systems, IT and [SRE teams](https://rootly.com/blog/how-many-sres-does-your-company-need-here-s-how-to-decide) can solve complex problems more efficiently than they could using a manual approach.
|
||||
|
||||
AIOps can, for example, help to surface the root cause of a performance issue in a complex, multi-layered environment like [Kubernetes](https://rootly.com/blog/how-kubernetes-can-both-help-and-hinder-incident-management-teams). Or, it could make recommendations about how best to resolve an incident.
|
||||
|
||||
AIOps entered the IT lexicon in 2016, when [Gartner coined the term](https://www.eweek.com/big-data-and-analytics/what-is-aiops/). At this point, it’s a relatively well established tool domain.
|
||||
|
||||
## How SREs view AIOps
|
||||
|
||||
Despite the fact that AIOps has been around for some time at this point, it doesn’t yet appear that many SREs have bought into the AIOps revolution. Catchpoint found in a [2021 survey](https://devops.com/sres-say-aiops-doesnt-live-up-to-the-hype/) that just 7.5 percent of SREs reported that AIOps tools delivered “high value” to their organizations.
|
||||
|
||||
It’s unclear exactly why SREs report low rates of excitement about AIOps. But we’d speculate that there are a few key factors at play:
|
||||
|
||||
- **AIOps is a new term for an old idea** : Many monitoring and observability tools have included at least basic AI and ML analytics features for a long time, starting before tool vendors slapped the AIOps label on their products. SREs probably realize this, and view AIOps to some extent as an effort by marketers to rebrand functionality that is not actually fundamentally new.
|
||||
- **AIOps is hard to implement** : Setting up an AIOps tool requires integrating it with diverse data sources and customizing it to fit your workflows and environment. It’s possible some SREs view this setup work as more effort than it’s worth.
|
||||
- **AIOps can’t replace human insight** : While AIOps tools may be useful to a point, it would be unwise to place blind trust in AIOps-based analyses or recommendations. For this reason, some SREs may believe that AIOps encourages organizations to rely too heavily on automated tools, at the cost of the expert analysis and perspective that only SREs can provide. (This is kind of like how it sometimes makes sense to[prioritize human intuition and expertise over playbooks](https://rootly.com/blog/what-sres-can-learn-from-capt-sully-when-to-follow-playbooks) .)
|
||||
|
||||
From an SRE’s perspective, then, AIOps may appear over-hyped, overly complicated and underperforming compared to traditional approaches to SRE.
|
||||
|
||||
## What SREs can gain from AIOps
|
||||
|
||||
SREs’ wariness toward AIOps is valid – but only to a point. It’s important not to let suspicions about the limitations of AIOps turn into excuses not to use AIOps at all. AIOps has some value to offer to SREs, even if it’s not perfect.
|
||||
|
||||
For example, AIOps can play a role in reducing toil. To the extent that AIOps tools can recognize complex patterns or interrelate data sets more quickly than human engineers, AIOps reduces the time SREs have to spend manually troubleshooting problems or poring over complicated information.
|
||||
|
||||
AIOps also helps to enable a more proactive approach to monitoring and incident management. If AIOps tools can alert SREs to emerging issues before SREs would otherwise recognize them, AIOps can help the SREs to get in front of the problems before they turn into true incidents. That’s better for SREs and end-users alike.
|
||||
|
||||
There is also an argument to be made that AIOps can help SREs do more with fewer engineering resources. If you can use AI to automate some aspects of monitoring and incident response, you can maintain the same levels of availability and performance with fewer human engineers on hand.
|
||||
|
||||
## Conclusion: AI won’t replace SREs – but it can help
|
||||
|
||||
None of the above is to say that AIOps can replace SREs, or that it magically solves every problem SREs face. Anyone who believes AIOps is a silver bullet has bought into the marketing hype to an unhealthy degree.
|
||||
|
||||
Nonetheless, AIOps tools do offer value to SREs. They make their jobs easier in some respects, and they can improve reliability outcomes.
|
||||
|
||||
So, while it’s wise to maintain a healthy perspective about the limitations of AIOps, SREs shouldn't rule out AIOps tools as one way to improve reliability engineering.
|
||||
|
||||
|
||||
{{subscribe-form}}
|
||||
Reference in New Issue
Block a user