SRE weekly 所有文章
This commit is contained in:

82
sreweekly/markdown/342/01-video-observability.md
Normal file
82
sreweekly/markdown/342/01-video-observability.md
Normal file
@@ -0,0 +1,82 @@
|
||||
# Video Observability
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Jeremy Blythe — evertz.ioFull disclosure: Honeycomb, my employer, is mentioned.
|
||||
- **链接**: https://evertz.io/blog/2022-09-22-video-observability
|
||||
|
||||
## 简介
|
||||
|
||||
> As a television broadcaster, how do I ensure that my channels are playing out the right thing for my viewers?
|
||||
|
||||
This is SRE applied to tv broadcasting: they replaced human monitoring of screens with an automated system.
|
||||
|
||||
## 正文
|
||||
|
||||
## Video Observability
|
||||
|
||||
### As a television broadcaster, how do I ensure that my channels are playing out the right thing for my viewers?
|
||||
|
||||
As a television broadcaster, how do I ensure that my channels are playing out the right thing for my viewers? Well, usually by watching and listening to it!
|
||||
|
||||
In the old days you would have a handful of channels, each broadcasting video and audio in a single language. You would hire an operator to sit in front of a few monitors and watch them all simultaneously.
|
||||
|
||||
### What’s in a stream?
|
||||
|
||||
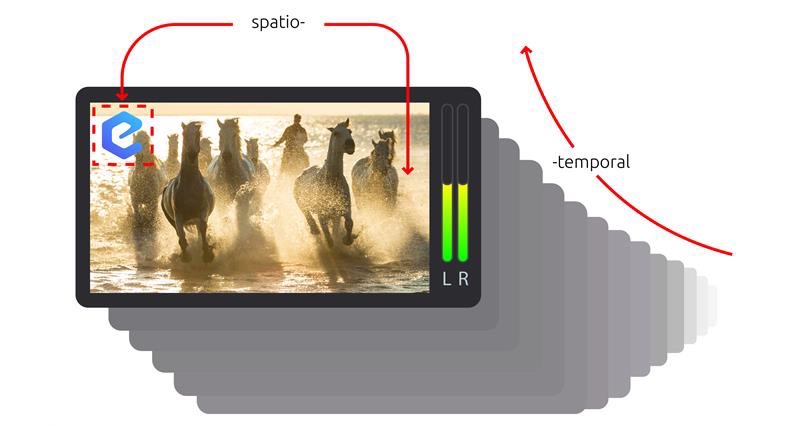
A television stream is made of multiple spatiotemporal elements. Temporally: frames of video are rendered one-by-one in front of your eyes typically between 24 and 60 frames per second. The audio samples run even faster and create the continuous sound you hear. Spatially: within each frame there are visible elements such as overlaid channel branding logos, closed-captions, pop-up graphics to entice you to watch more on the channel and many more. The complexity doesn’t end there. These days there are multiple audio and captions languages streamed at the same time so as a viewer you can choose to watch a show with Spanish audio and English captions for example. Finally, there’s a world of data encoded into non-visible parts of the signal that inform downstream components to perform some action, like deliver local advertisements when they decode a trigger.
|
||||
|
||||
|
||||
|
||||
|
||||
You can imagine the task of orchestrating all this complexity to come together into a seamless experience for the viewer! Playout automation services have been taking care of this problem for many years. Given a schedule describing the desired output, the automation controls a myriad of software services and hardware devices in real-time to produce the output stream.
|
||||
|
||||
|
||||
As stations have grown to hundreds of channels, and each channel might have station logos, closed-captions, pop-up graphics and half a dozen audio languages, monitoring has become a much more daunting task. The screens have become a huge video wall, with hundreds of streams visible simultaneously. Operators can select a stream to listen to one-by-one, but without being an amazing polyglot they can at best make an educated guess that what they are listening to sounds Portuguese-ish. But is it Portuguese or Brazilian-Portuguese? You can see how this doesn’t scale.
|
||||
|
||||
|
||||
|
||||
|
||||
To help the operators, automated monitoring tools have been developed. These check that the pictures have not degraded in some way or frozen or simply showing black. They’ll check that the audio is not silent and that the captions are present. But, not a great deal more than that.
|
||||
|
||||
These monitoring tools, like most monitoring, are only checking for known symptoms. For example, there are many error conditions that could lead to the stream showing black, so detectors were specifically invented to check for black. The trouble is, black sections are often intentional, particularly when transitioning into breaks or before end credits, so you may get false alarms.
|
||||
|
||||
## What do we want?
|
||||
|
||||
To draw an analogy with software unit testing, this legacy monitoring would be like all your tests passing simply because the code runs without crashing! What we really want is a way to check that the stream output matches our intent. A good unit-test asserts that, given a known input, an expected output is observed.
|
||||
|
||||
We want to be able to say, “At 8:30pm we should be showing season six, episode ten of “Better Call Saul”, the English, Spanish, French and German audio and captions should all be available. The channel logo should be showing in the top-right of the screen.”
|
||||
|
||||
So, give a copy of the schedule to a machine that can watch the stream and report discrepancies. Easy? No.
|
||||
|
||||
Humans are really good at answering that question about what should be happening at 8:30pm. They can glance at a small screen, read some notes about the episode and reason that it’s correct. They can check the correct channel logo is in the right place. They can tell the difference between these languages even if they are not fluent. Machines have a hard time with this.
|
||||
|
||||
“AI and Machine learning!”, I hear you cry. Yes, these types of problems are becoming more solvable using these techniques but, it’s expensive. Expensive to train and expensive run. It would end up costing more to monitor the channel than to produce it!
|
||||
|
||||
## What did we make?
|
||||
|
||||
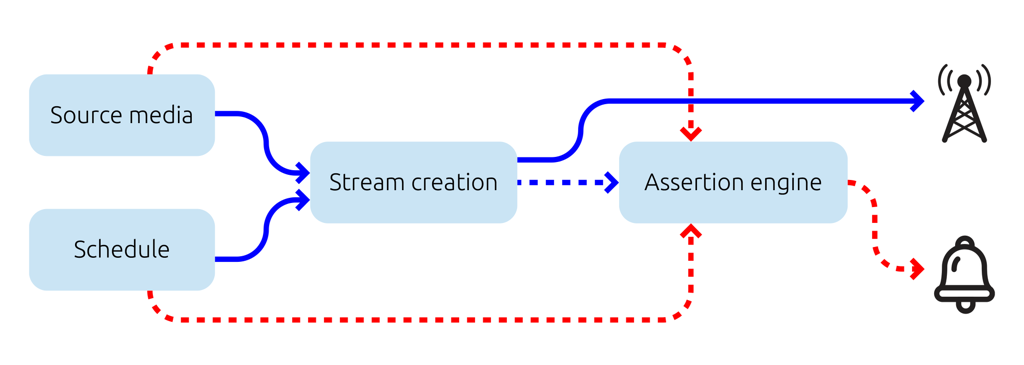
For evertz.io we’ve built a cost-efficient way to test, through assertions, that the scheduler’s intent is produced in the output stream. We use statistical methods over perceptual representations of the source content and output stream to produce similarity scores. Thresholds over these scores allow us to pass or fail an assertion.
|
||||
|
||||
|
||||
|
||||
|
||||
That question about what should be observed at 8:30pm is now answerable. And for 8:31 and 8:32 and 8:33… multiplied by as many channels as you like – the machines do not get overwhelmed. More so, it can do a better job than the human. An assertion will fail if you’re more than a few seconds out from where you should be in a show; an indicator of a problem that may lead to the cliffhanger getting cut off by an ad break! Like human operators, it’s not fluent in those languages, but it can statistically match what should be audible with what actually is. Therefore, it can check that Portuguese, Brazilian-Portuguese, French and Canadian-French are all present in the correct order through pattern matching. Not only that, but the machine will tell you that the correct seconds of the audio are playing at the correct time in the show, not simply, “Hmm, that sounds like French. Pass!”
|
||||
|
||||
Our patented technology can do all this and more using a few lambda functions and a single ARM CPU core per channel running our Rust assertion engine. Hard to beat that cost optimization!
|
||||
|
||||
## How do we make sense of it?
|
||||
|
||||
With assertions for every few seconds, when there is a failure there is a lot of data to comb through. And even once you’ve identified which spatiotemporal element is causing the failure, how do you go about identifying the cause? A modern playout chain is made up of a lot of moving parts, and a failure in any one of them could cause similar looking problems in the output.
|
||||
|
||||
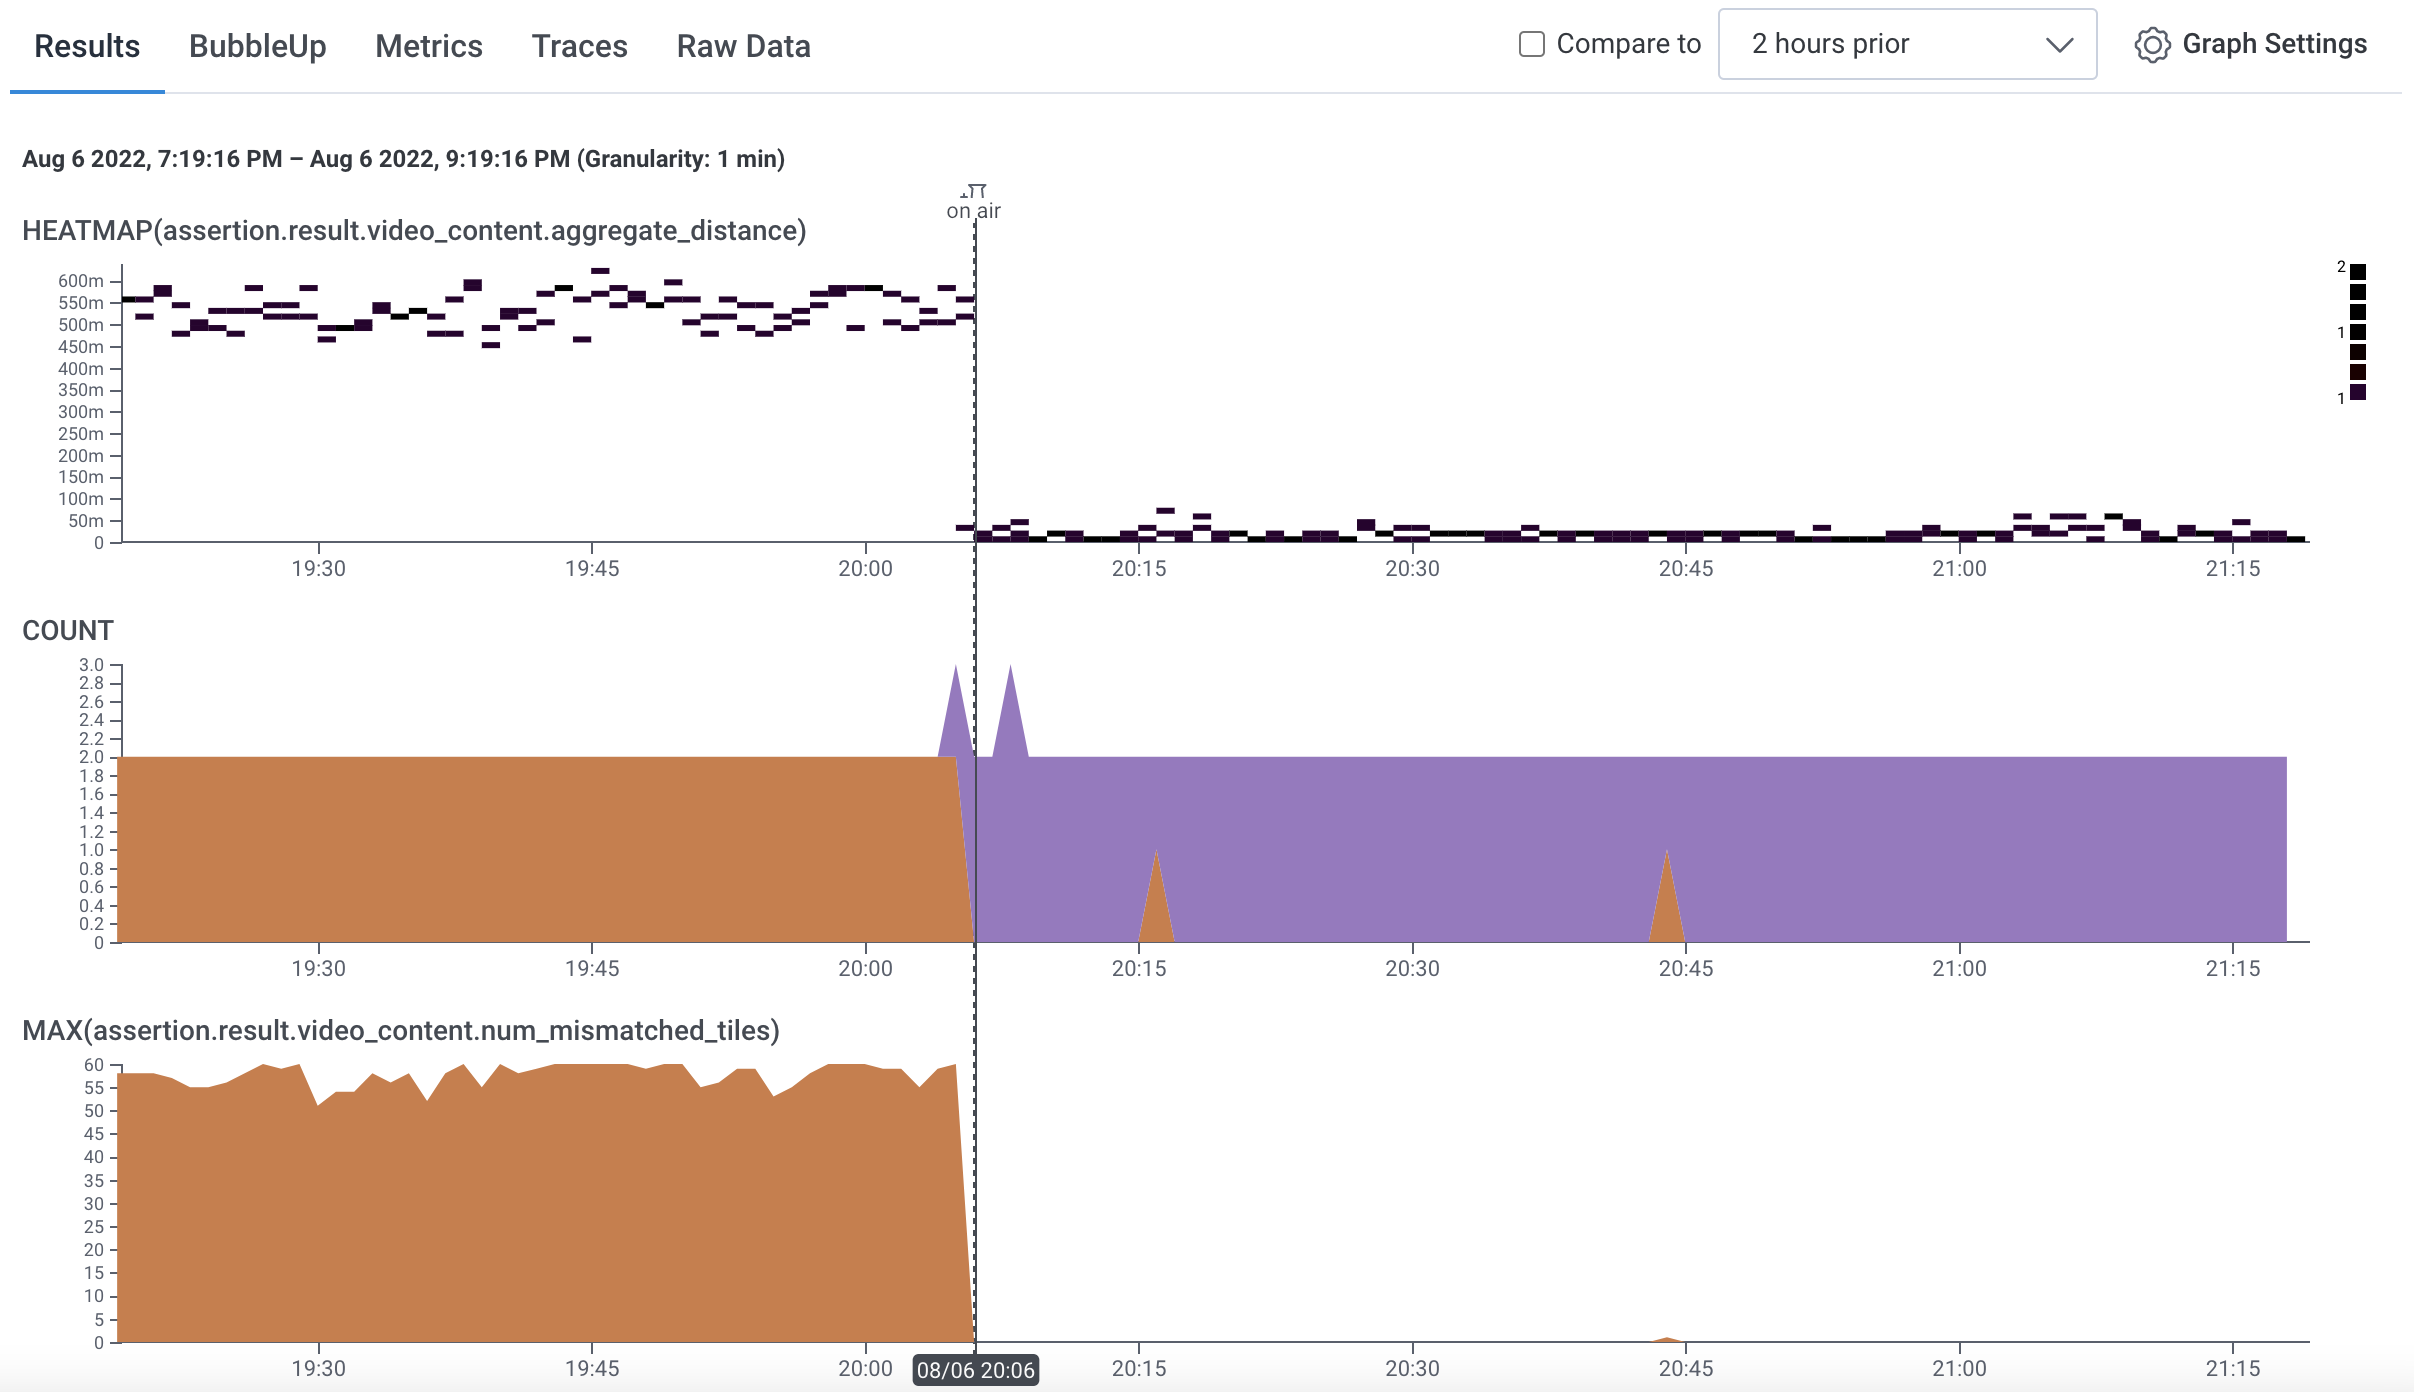
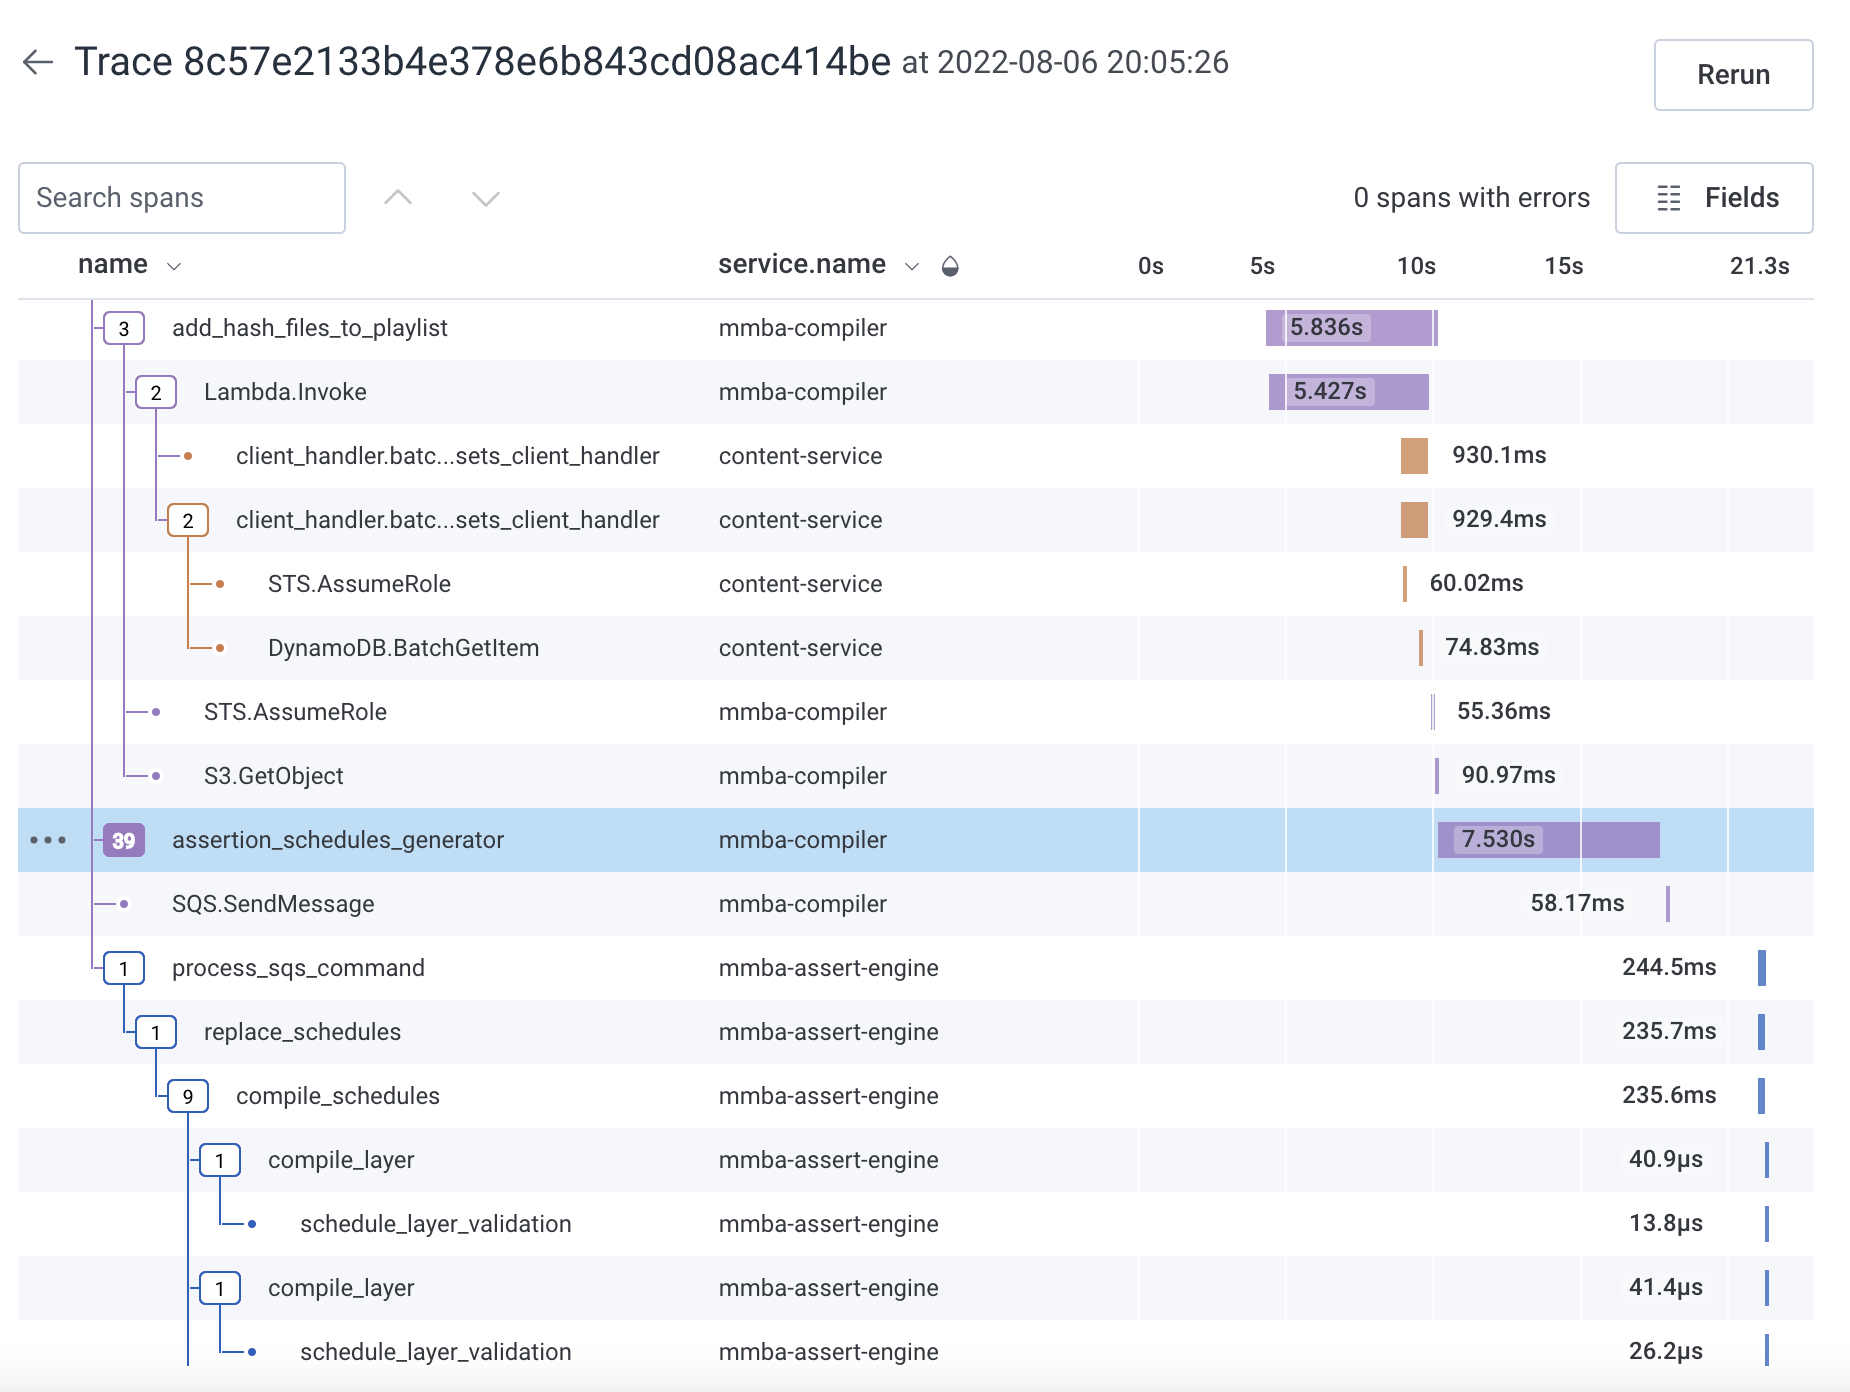
By using [Honeycomb](https://www.honeycomb.io/) to collect distributed tracing data across all elements of the playout chain, we can easily filter and zoom in on assertion failures. We can then use assertion trace attributes in queries across the services in the playout chain and pinpoint where the issue originated.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
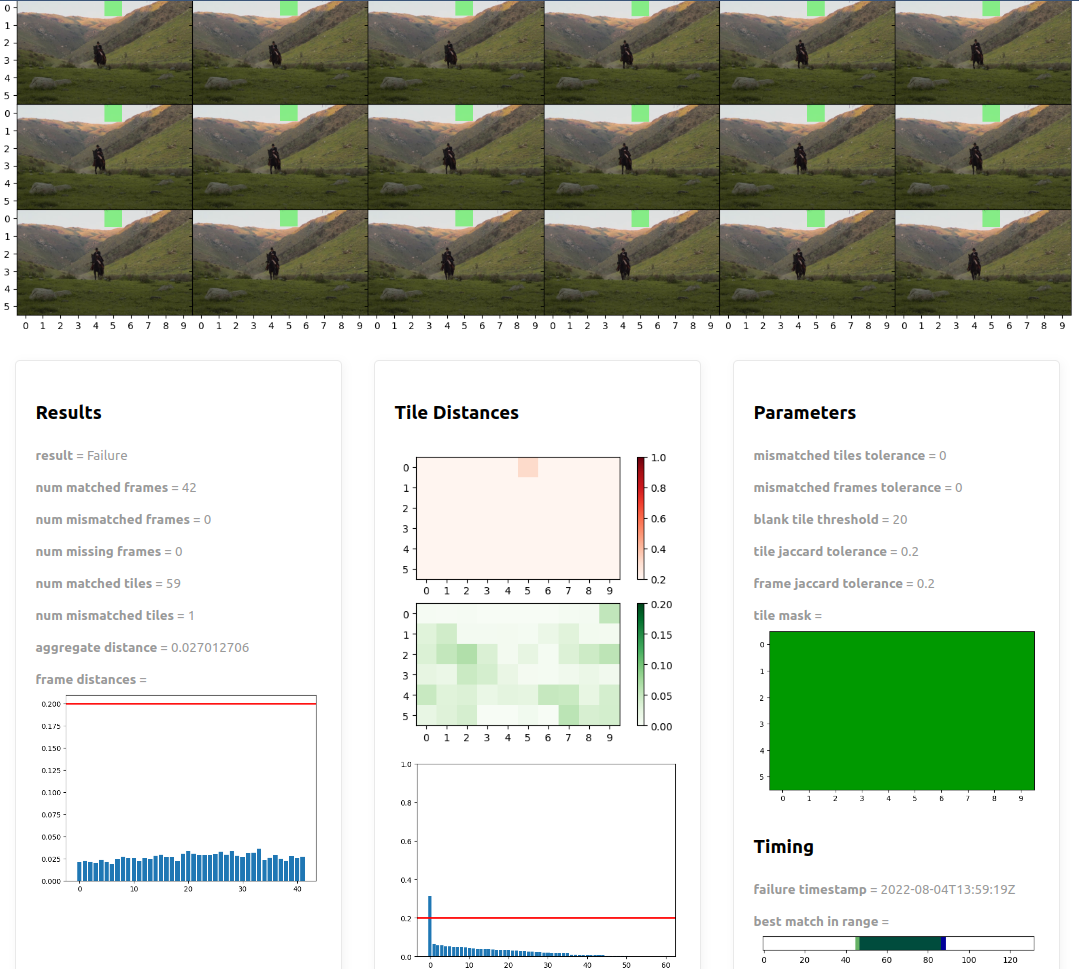
To help understand the failures, we attach a link to the [Honeycomb](https://www.honeycomb.io/) spans to our own tooling to visualize an individual assertion report:
|
||||
|
||||
|
||||
|
||||
|
||||
Not only can we get the detailed report but we can look back at the timeline of events that led up to it. By slicing and dicing the data we can look for trends, groups, previous outcomes given similar inputs, you name it! There’s a wealth of data to dig into.
|
||||
|
||||
With video observability we can ensure our production system is running smoothly. Our distributed tracing and high-cardinality data in [Honeycomb](https://www.honeycomb.io/) allows us to connect assertion outcomes to scheduled intent. We can safely deploy and release new versions of code to production multiple times a day; first to a [dogfood](https://en.wikipedia.org/wiki/Eating_your_own_dog_food) tenant and then a gradual roll-out to our customers. We can analyze not only the performance of the new code but the correctness of the output stream. Through integrations and webhooks we can even automatically trigger a rollback to the previous release to resolve issues much faster than any human-in-the-loop monitoring and incident management process.
|
||||
13
sreweekly/markdown/342/02-on-call-with-jérôme-petazzoni.md
Normal file
13
sreweekly/markdown/342/02-on-call-with-jérôme-petazzoni.md
Normal file
@@ -0,0 +1,13 @@
|
||||
# On-call with Jérôme Petazzoni
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Elena Boroda — Fiberplane
|
||||
- **链接**: https://fiberplane.dev/blog/on-call-with-jerome-petazzoni/
|
||||
|
||||
## 简介
|
||||
|
||||
An interview with an engineer about on-call practices, training folks for on-call, and chaos engineering.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
26
sreweekly/markdown/342/03-the-re-org-rag-i-m-my-own-vp.md
Normal file
26
sreweekly/markdown/342/03-the-re-org-rag-i-m-my-own-vp.md
Normal file
@@ -0,0 +1,26 @@
|
||||
# The Re-Org Rag (I’m My Own VP)
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Forrest Brazeal
|
||||
- **链接**: https://youtu.be/yDcaRklX7q4
|
||||
|
||||
## 简介
|
||||
|
||||
SRE: totally defined. Time for a reorg, and with a catchy tune!
|
||||
|
||||
## 正文
|
||||
|
||||
About
|
||||
Press
|
||||
Copyright
|
||||
Contact us
|
||||
Creators
|
||||
Advertise
|
||||
Developers
|
||||
Terms
|
||||
Privacy
|
||||
Policy & Safety
|
||||
How YouTube works
|
||||
Test new features
|
||||
NFL Sunday Ticket
|
||||
© 2026 Google LLC
|
||||
@@ -0,0 +1,113 @@
|
||||
# Keep Calm and Respond: A Beginner’s Heuristic to Incident Response
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Audrey Simonne — DZone
|
||||
- **链接**: http://dzone.com/articles/keep-calm-and-respond-a-beginners-heuristic-to-inc-1
|
||||
|
||||
## 简介
|
||||
|
||||
Great advice for incident response, backed up by real-world anecdotes.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](http://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](http://dzone.com)
|
||||
|
||||
# Keep Calm and Respond: A Beginner's Heuristic to Incident Response
|
||||
|
||||
Incidents are scary, but they don’t have to be.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](http://dzone.com/static/registration.html)
|
||||
|
||||
A few years ago, when working as a software developer building and maintaining internal platform components for a cloud company, I deleted an application from production as part of a deprecation. I had double and triple-checked references and done my due diligence communicating with the company. Within minutes, though, our alerting and monitoring systems began to flood our Slack channels, in a deluge of signals telling me something wasn’t working. The timing was pretty clear; I had broken production.
|
||||
|
||||
In medical dramas, the moment when things are about to go wrong is unmistakable. Sounds are muffled. High-pitched, prolonged beeps take over your ears. Vision blurs. When alarms sound, or danger is near, something takes over within you. Blood drains from your head, heat rises in your body, and your hands sweat as you begin to process the situation. Sometimes you confront the issue, sometimes you try to get as far away as possible, and sometimes, you just freeze. In my case, with red dashboards and a sudden influx of noise, I had turned into the surgical intern holding a scalpel for the first time over a critical patient, with no idea what to do.
|
||||
|
||||
Incidents are scary, but they don’t have to be. Doctors and surgeons undergo years of training to maintain their composure when approaching high pressure, highly complex, and high stakes problems. They have a wealth of experience to draw from in the form of their attendings and peers. They have established priorities and mental checklists to help them address the most pressing matters first: stop the bleeding and then fix the damage.
|
||||
|
||||
As cloud software becomes part of the critical path of our lives, incident response practices at an individual and organizational level are becoming formalized disciplines, as evidenced by the growth of site reliability engineering. As we grow collectively more experienced, incident response becomes less of an unfamiliar, stressful, or overwhelming experience and more like something you've trained and prepared for. As I’ve responded to incidents over my career, I’ve collected a few heuristics that have helped me turn my fight, flight, or freeze response into a reliable incident response practice:
|
||||
|
||||
- Understand what hurts for your users
|
||||
- Be kind to yourself and others
|
||||
- Information is key
|
||||
- Focus on sustainable response
|
||||
- Stop the bleeding
|
||||
- Apply fixes one at a time
|
||||
- Know your basics
|
||||
|
||||
## Understand What Hurts for Your Users
|
||||
|
||||
In times of emergency, you learn what is truly important. When creating dashboards and alerts, it’s very easy to alert on just about anything. Who doesn’t want to know when their systems are not working as expected? This is a trick question. You want to know when people can’t use your system as expected. When all your alerts are going off, and all your graphs are red, it becomes important to distinguish between signal and noise. The signal you want to prioritize is user impact. Ask yourself:
|
||||
|
||||
- What pain are users experiencing?
|
||||
- How widespread is the issue?
|
||||
- What is the business impact? Revenue loss? Data loss?
|
||||
- Are we in violation of our Service Level Agreements (SLAs)?
|
||||
|
||||
At the beginning of an incident, make a best effort estimate of impact based on the data that you have at hand. You can continue to assess the impact throughout the response time and even after an incident is resolved. If you’re working in an organization with a mature incident response practice, questions of impact will be codified and easy to answer. Otherwise, you can rely on metrics, logs, support tickets, or product data to make an educated guess. Use your impact estimate to determine what is the appropriate response and share your reasoning with other responders. Some companies have defined severity scales that dictate who should get paged and when. If not, think that the greater the impact, the more extreme the response. In the emergency room, the more severe and life-threatening your ailment, the faster you will be treated. A large wound will require stitches while a scratch will require a band-aid.
|
||||
|
||||
When I broke production by deleting a deprecated application, the first things I turned to were our customer-facing API response rates. The user error rate was over 45%; a user would encounter an error every other time they tried to do something in our product. Our users couldn’t view their accounts, pay their invoices, or do anything at all. With this information, I looked at our published severity scale and determined this required an immediate response, even though we were outside of business hours. I worked with our cloud operations team to get an incident channel created and the response initiated.
|
||||
|
||||
## Be Kind To Yourself and Others
|
||||
|
||||
In today’s world of complex distributed systems and unreliable networks, it is inevitable that one day, you will break production. It’s often seen as a rite of passage when you join new teams. It can happen to even the most seasoned of engineers; a very senior engineer I once worked with broke our whole application because they had forgotten to copy and paste a closing tag in some HTML. When it does happen, be kind to yourself and remember that when these things happen, you are not to blame. We work in complex systems that are not strictly technological. They are surrounded by humans and human processes that intersect them in messy ways. Outages are just the culmination of small mistakes that, in isolation, are not a big deal. In responding to and learning from incidents, we are figuring out how to make our systems better and improve the processes that surround them.
|
||||
|
||||
In the moment of the incident and in the postmortem, a process for learning from incidents, strive to remain “blameless.” To act blamelessly means that we assume responders made the best decision possible with the available information at the time. When something goes wrong, it is easy to point fingers. After the fact, it’s easy to identify more optimal decisions when you have all the information and have had time to analyze things outside of the heat of the moment. If we point fingers and assume we could have made better decisions, we close the opportunity to evaluate our weaknesses with candor. When blame is spread, discourse stops. Incident postmortems are discussions intended to understand how an incident happened, how to prevent it in the future, and how to respond better in the future, not a court in which we declare who is guilty and who is innocent. By being kind to yourself and others through the spirit of blamelessness, we learn and improve together.
|
||||
|
||||
## Information Is Key
|
||||
|
||||
An incident can be unpredictable and you never know what kind of information may be helpful to responders. Whether it is a daily standup or a monthly business review, we curate information for our audiences because these are well-known, well-controlled situations. However, an ongoing incident is not the right place to filter new information. Surfacing information throughout an incident serves two purposes. It gives responders more information to use as they make decisions, and it lets non-responders know the status of what is going on.
|
||||
|
||||
If there is an ongoing incident that is owned by another team and you are noticing abnormal behavior in your metrics and logs, surfacing that parts of your system are affected by the outage can help determine the breadth of impact and can influence response. One day, our alerts indicated that people were experiencing latency from our services and we started an incident. Around the same time, a second team told us about similar latency issues they had noticed. With this information, we were able to determine more quickly that the issue was really in the database and were able to page the correct team, resulting in a faster resolution. The other side of the coin is balance. If too many teams are surfacing the same information, it can easily become overwhelming for those managing the incident.
|
||||
|
||||
Having asynchronous incident communications readily available throughout the incident in a Slack channel or something similar can help keep various stakeholders like support or account representatives informed of the incident status. During our incidents, someone will periodically provide a situation report that will detail a rough timeline as well as the steps that have been taken to date. These sorts of updates help keep responders focused and stakeholders informed for a quick and effective resolution. As an added bonus, having the communication documented as it happened is very helpful in postmortems. The incident communications will give you a good idea of timeline, decisions taken, and resolutions.
|
||||
|
||||
|
||||
|
||||
|
||||
## Focus on Sustainable Response
|
||||
|
||||
In life and throughout an incident, it’s important to focus on the things you can control. This is especially relevant when you experience downtime because of a third-party vendor or a dependency on another team. Incident response is like your body’s stress response. It can give you the capability to accomplish great things in the name of self-preservation, and it’s not good to be in that state for a prolonged period of time. These periods of heightened stress can leave you exhausted afterward, and maintaining them is a sure recipe for burning yourself out. When you cannot do anything to directly impact the outcome of an incident, it’s time for you to stand down and let others take the lead.
|
||||
|
||||
One day, a large portion of our customers could not log in or sign up for new accounts because of an outage with a downstream vendor. Based on our severity scale, we would need to be working 24/7 to resolve the outage, but the only way to mitigate the issue would be to move to a new vendor. This was a monumental task that was not likely to be completed with quality late into the evening after a long work day. Keeping responders engaged would have been a sure way to burn them out and reduce response quality the next day. We made the call to stand down from the incident while we waited for a response from the vendor the next morning. We had workarounds in place for customers that would allow them to move forward in most cases, so we did the right thing and waited till morning.
|
||||
|
||||
On the other hand, in the morning, it was evident that we wouldn’t be able to get a timely resolution from the vendor. With the mounting burden on support and the growing impact of lost signups, we turned to fixes that we had control over and began the process of changing vendors. Using our knowledge of customer and support impact, we prioritized the vendor change for the areas that would unblock the most customers instead of trying to mitigate every failing system. Breaking down the problem into smaller pieces made it possible to take on this difficult task and spread out the work. This brought our time to resolution down and allowed us to make better decisions for later migrations without exhausting the incident response team.
|
||||
|
||||
## Stop the Bleeding
|
||||
|
||||
When you’re in incident response mode, center your efforts on addressing user pain first: how can we best alleviate the impact to our users? A mitigation is a fix that you can implement that will restore functionality or reduce the impact of a malfunctioning part. This could mean a rollback of a recent deployment, a manual workaround with support, or a temporary configuration change. When we develop features or enhance existing ones, we are designing, architecting, and refactoring for mid to long-term stability. When you’re finding mitigations, you may do things that you wouldn’t normally do because they are inherently short sighted, but provide relief to users while you find a more permanent stable solution. In an operating room, a surgeon may clamp an artery to control bleeding while they repair an organ, and they do so knowing full well that the artery cannot remain clamped indefinitely. You want to be able to develop fixes while your system is in a stable, if not functioning state.
|
||||
|
||||
During my application deletion fiasco, we were able to determine that only half of our live instances were trying to connect to the deleted application. Instead of trying to get the deleted application re-deployed, or fix the configuration for the broken services, we decided to route traffic away from the faulty instances. This left us temporarily with services running in only one region, but it allowed our users to continue to use the product while we found the permanent fix. We were able to introduce a new configuration and test that the deployments would work before rerouting traffic to them. It took us 30 minutes to route traffic away and another 60 minutes to fix the instances and reroute traffic to them, leading to only 30 minutes of downtime as opposed to what could have been 90 minutes of downtime.
|
||||
|
||||
## Apply Fixes One at a Time
|
||||
|
||||
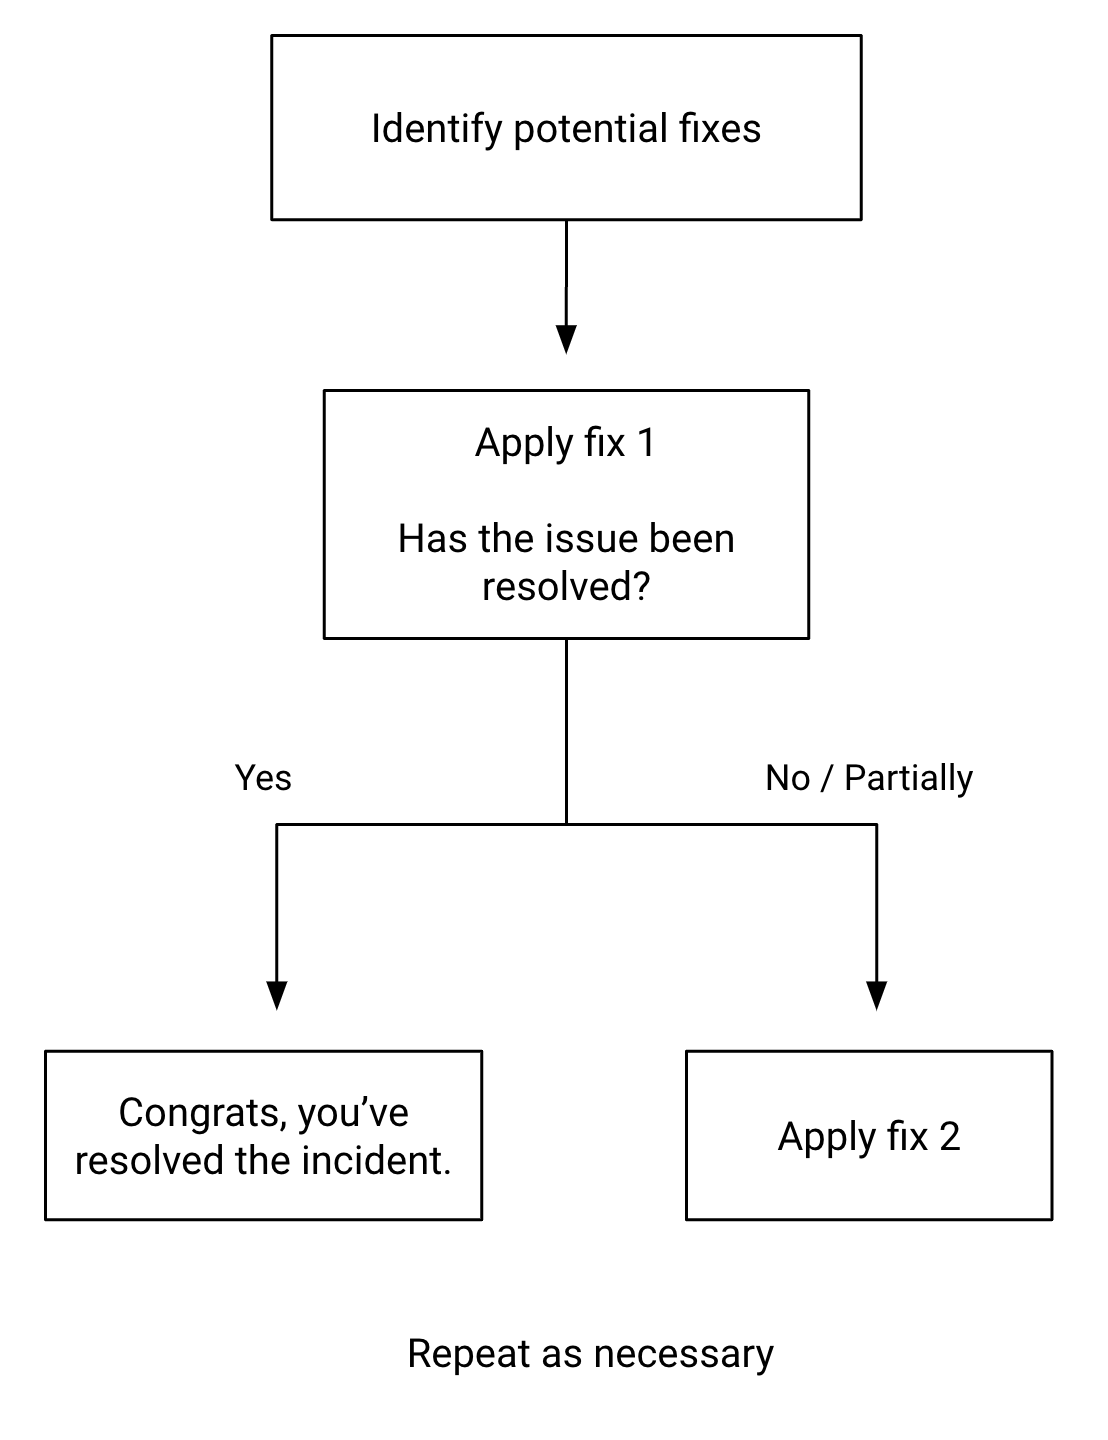
Incidents that have a singular cause are relatively easy to approach: you find the mitigation, you apply it, and then you fix the problem. However, not all problems stem from a single cause. Symptoms may hide other problems, and issues that are benign on their own may be problematic when combined with other factors. The relationships between all these factors may not even be evident at first. Distributed systems are large and complex. A single person might not be able to thoroughly understand the full breadth of the system. To find a root cause in these cases we must rely on examining the results of controlled input to better understand what is going on; in essence, performing an experiment that a certain fix will produce a certain result. If you make two concurrent fixes, how do you know which one fixed the issue? How do you know one of the solutions didn’t make things worse?
|
||||
|
||||
In another outage, one of our services was suddenly receiving large bursts of traffic, leading to latency in our database calls. Our metrics showed that the database calls were taking a long time, but the database metrics were showing that the queries were completing within normal performance thresholds. We couldn’t even find the source of the traffic. After a great deal of digging, and a deep dive into the inner workings of TCP, we found the issue! Our database connection pool was not configured well for bursty traffic. We prepared to deploy a fix. In the spirit of addressing user pain and working in the areas they could control, another team was investigating the issue in parallel. They had discovered that a deployment of theirs coincided with when the outage had begun and were preparing to do a rollback. In the spirit of surfacing information, both teams were coordinating through the incident channel. Before we applied either fix, someone brought up that we should apply one fix first to see if it addressed the problem. We moved to apply the change to the connection pool, and to our joy and then immediate dismay, we had fixed the original issue but not the customer outage. Our service still couldn’t handle the volume of traffic it was receiving. At that point the other team applied their rollback and the traffic returned to normal.
|
||||
|
||||
By applying these fixes separately, we discovered both a connection pool misconfiguration and a bug that was causing an application to call our service many more times than it needed to. If we had simply rolled back the deployment, it was possible that in the future, similar traffic would cause our service to fail, creating another outage. With methodical application of fixes, you can better identify root causes in complex distributed systems.
|
||||
|
||||
|
||||
|
||||
|
||||
## Know Your Basics
|
||||
|
||||
Distributed systems are hard. As a beginner or even a more seasoned engineer, fully understanding them at scale is not something that our brains are made to do. These systems have a wide breadth, the pieces are complex, and [they are constantly changing](https://dzone.com/articles/traditional-vs-modern-incident-response). However, all things in nature follow patterns, and distributed systems are no exception. You can use these to your advantage to know how to ask the right questions.
|
||||
|
||||
Distributed systems will often have centralized logging, metrics, and tracing. Microservices and distributed monoliths will often have API gateways or routers that provide a singular and consistent customer-facing interface to the disparate services that back them. These distributed services will likely make use of queueing mechanisms, cache stores, and databases. By having a high-level understanding of your implemented architecture, even without knowing all the complexity and nuance, you can engage the people on your team or at your company who do. A general surgeon knows how a heart works but may consult with a cardiothoracic surgeon if they find that the case requires more specialized knowledge. If you are familiar with the high-level architectural patterns in your application, you can ask the right questions to find the people with the information you need.
|
||||
|
||||
## Parting Thoughts
|
||||
|
||||
We rely on healthcare professionals to treat us when the complex systems that are our bodies don’t work as we expect them to. We’ve come to rely on them as people who will methodically break down what happens in our bodies, put us back together, and heal our pain. As software developers, we don’t directly hold lives in our hands the way health workers do, but we must recognize that the world is becoming more and more dependent on the systems we build. People are building their lives around our systems with varying degrees of impact. We build entertainment systems like games and social media, but also we build systems that pay people, help them pay their bills, and coordinate transportation. When a game is down, maybe we go for a walk. When an outage fails to disburse a check, it could mean the difference between making rent and becoming homeless. If someone cannot pay obligations due to system downtime, it may have huge repercussions on their life. Responsible practice of our craft, including incident response, is how we acknowledge our responsibility to those who depend on us. Use these heuristics to center yourself on the people who rely on your systems. For their sake, keep calm and respond.
|
||||
|
||||
Heuristic (computer science)
|
||||
systems
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
@@ -0,0 +1,13 @@
|
||||
# The Long Way Down: The crash of Air France flight 447
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Admiral Cloudberg
|
||||
- **链接**: https://admiralcloudberg.medium.com/the-long-way-down-the-crash-of-air-france-flight-447-8a7678c37982
|
||||
|
||||
## 简介
|
||||
|
||||
There’s a lot to learn from in this air accident. A chilling example: several quirks of the plane’s automation combined to effectively tell the pilot to continue pushing the plane to stall.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,115 @@
|
||||
# Atomic Commitment: The Unscalability Protocol – Marc’s Blog
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Marc Brooker
|
||||
- **链接**: http://brooker.co.za/blog/2022/10/04/commitment.html
|
||||
|
||||
## 简介
|
||||
|
||||
When sharding a database, if transactions can span shards, then it can be very difficult to reason about the system’s maximum throughput.
|
||||
|
||||
> For example, splitting a single-node database in half could lead to worse performance than the original system.
|
||||
|
||||
## 正文
|
||||
|
||||
I am an engineer at Amazon Web Services (AWS) in Seattle, where I work on agentic AI, especially safety and policy for agentic AI. Before that, I worked on EC2, EBS, databases, serverless, and serverless databases.
|
||||
|
||||
All opinions are my own.
|
||||
|
||||
Let’s consider a single database system, running on one box, good for 500 requests per second.
|
||||
|
||||
```
|
||||
┌───────────────────┐
|
||||
│ Database │
|
||||
│(good for 500 rps) │
|
||||
└───────────────────┘
|
||||
```
|
||||
What if we want to access that data more often than 500 times a second? If by *access* we mean *read*, we have a lot of options. If be *access*, we mean *write* or even *perform arbitrary transactions on*, we’re in a trickier situation. Tricky problems aside, we forge ahead by splitting our dataset into two shards:
|
||||
|
||||
```
|
||||
┌───────────────────┐ ┌───────────────────┐
|
||||
│ Database shard 1 │ │ Database shard 2 │
|
||||
│(good for 500 rps) │ │(good for 500 rps) │
|
||||
└───────────────────┘ └───────────────────┘
|
||||
```
|
||||
If we’re just doing single row reads and writes, we’re most of the way there. We just need to add a routing layer that can decide which shard to send each access to, and we’re done<sup>[1](http://brooker.co.za#foot1)</sup>:
|
||||
|
||||
```
|
||||
┌────────────┐
|
||||
│ Router │
|
||||
└────────────┘
|
||||
┬
|
||||
┌─────────┴───────────┐
|
||||
▼ ▼
|
||||
┌───────────────────┐ ┌───────────────────┐
|
||||
│ Database shard 1 │ │ Database shard 2 │
|
||||
│(good for 500 rps) │ │(good for 500 rps) │
|
||||
└───────────────────┘ └───────────────────┘
|
||||
```
|
||||
But what if we have transactions? To make the complexity reasonable, and speed us on our journey, let’s define a *transaction* as an operation that does writes to multiple rows, based on some condition, atomically. By *atomically* we mean that either all the writes happen or none of them do. By *based on some condition* we mean the transactions can express ideas like “reduce my bank balance by R10 as long as it’s over R10 already”.
|
||||
|
||||
But how do we ensure atomicity across multiple machines? This is a classic computer science problem called [Atomic Commitment](https://en.wikipedia.org/wiki/Atomic_commit). The classic solution to this classic problem is [Two-phase commit](https://en.wikipedia.org/wiki/Two-phase_commit_protocol), maybe the most famous of all distributed protocols. There’s a *lot* we could say about atomic commitment, or even just about two-phase commit. In this post, I’m going to focus on just one aspect: atomic commitment has weird scaling behavior.
|
||||
|
||||
**How Fast is our New Database?**
|
||||
|
||||
The obvious question after sharding our new database is *how fast is it?* How much throughput can we get out of these two machines, each good for 500 transactions a second.
|
||||
|
||||
The optimist’s answer is 500 + 500 = 1000. We doubled capacity, and so can now do more work. But we need to remind the optimist that we’re solving a distributed transaction problem here, and that at least some transactions go to both shards.
|
||||
|
||||
For the next step in our analysis, we want to measure the mean number of shards any given transaction will visit. Let’s call it *k*. For *k = 1* we get perfect scalability! For *k = 2* we get no scalability at all: both shards need to be visited on every transaction, so we only get 500 transactions a second out of the whole thing. The capacity of the database is the sum of the per-node capacities, divided by *k*.
|
||||
|
||||
**How do we spread the data?**
|
||||
|
||||
We haven’t mentioned, so far, how we decide which data to put onto which shard. This is a whole complex topic and active research area of its own. The problem is a tough one: we want to spread the data out so about the same number of transactions go to each shard (avoiding *hot shards*), and we want to minimize the number of shards any given transaction touches (minimize *k*). We have to do this in the face of, potentially, very non-uniform access patterns.
|
||||
|
||||
But let’s put that aside for now, and instead model how *k* changes with the number of rows in each transaction (*N*), and number of shards in the database (*s*). Borrowing from [this StackExchange answer](https://stats.stackexchange.com/a/296053), and assuming that each transaction picks uniformly from the key space, we can calculate:
|
||||
|
||||
$k = s \left( 1 - \left( \frac{s-1}{s} \right) ^ N \right)$
|
||||
|
||||
You can picture that in your head, right? If, like me, you probably can’t, it looks like this:
|
||||
|
||||

|
||||
|
||||
|
||||
*k* is fairly nicely behaved for small *N* or small *s*, but things start to get ugly when both *N* and *s* are large. Remember that the absolute maximum throughput we can get out of this database is
|
||||
|
||||
$\mathrm{Max TPS} \propto \frac{s}{k}$
|
||||
|
||||
Let’s consider the example of *N=10*. How does the maximum TPS vary with *s* as we increase the number of shards from 1 to 10:
|
||||
|
||||
$\mathrm{Max TPS}(s = 1..10, N=10) \propto [1.000000, 1.000978, 1.017648, 1.059674, 1.120290, 1.192614, 1.272359, 1.356991, 1.444974, 1.535340]$
|
||||
|
||||
Oof! For *N = 10*, adding a second shard only increases our throughput by something like 1% for uniformly distributed keys! The classic solution is to hope that your keys aren’t uniformly distributed, and that you can keep *k* low without causing hotspots. A nice solution, if you can get it.
|
||||
|
||||
**But wait, it gets worse!**
|
||||
|
||||
This is where our old friend, concurrency, comes back to haunt us. Let’s think about what happens when we get into the state where each shard can only handle one more transaction<sup>[2](http://brooker.co.za#foot2)</sup>, and two transactions come in, each wanting to access both shards.
|
||||
|
||||
```
|
||||
┌────┐ ┌────┐
|
||||
│ T1 │ │ T2 │
|
||||
└────┘ └────┘
|
||||
│ │
|
||||
│ │
|
||||
┌─────┴─────────┴──────┐
|
||||
│ │
|
||||
▼ ▼
|
||||
┌───────────────────┐ ┌───────────────────┐
|
||||
│ Database shard 1 │ │ Database shard 2 │
|
||||
│ (can only handle │ │ (can only handle │
|
||||
│ one more) │ │ one more) │
|
||||
└───────────────────┘ └───────────────────┘
|
||||
```
|
||||
Clearly, only one of T1 and T2 can succeed. They can also, sadly, both fail. If T1 gets to shard 1 first, and T2 gets to shard 2 first, neither will get the capacity it needs from the other shard. Then both fail<sup>[3](http://brooker.co.za#foot3)</sup>. We can look at this using a simulation, and see how pronounced the effect can be:
|
||||
|
||||

|
||||
|
||||
|
||||
In this simulation, with Poisson arrivals, offered load far in excess of the system capacity, and uniform key distribution, goodput for *N = 10* drops significantly as the shard number increases, and doesn’t recover until *s = 6*. This effect is surprising, and counter-intuitive. Effects like this make transaction systems somewhat uniquely hard to scale out. For example, splitting a single-node database in half could lead to worse performance than the original system.
|
||||
|
||||
Fundamentally, this is because scale-out depends on [avoiding coordination](https://brooker.co.za/blog/2021/01/22/cloud-scale.html) and atomic commitment is all about coordination. Atomic commitment is the anti-scalability protocol.
|
||||
|
||||
**Footnotes**
|
||||
|
||||
*done done* . Building scale-out databases even for single-row accesses turns out to be super hard in other ways. For a good discussion of that, check out the 2022[DynamoDB paper](https://www.usenix.org/conference/atc22/presentation/vig) .
|
||||
*could* , but that would have other bad impacts. In general, long queues are really bad for system stability.
|
||||
@@ -0,0 +1,96 @@
|
||||
# GitHub Availability Report: September 2022
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Jakub Oleksy — GitHub
|
||||
- **链接**: https://github.blog/2022-10-05-github-availability-report-september-2022/
|
||||
|
||||
## 简介
|
||||
|
||||
Through Ubuntu’s unattended-upgrades system, a systemd update was installed that broke systemd-resolved, which in turn broke GitHub Codespaces. The systemd bug report they link to is also well worth a read.
|
||||
|
||||
## 正文
|
||||
|
||||
# GitHub Availability Report: September 2022
|
||||
|
||||
In September, we experienced one incident that resulted in degraded performance across GitHub services. We also experienced one incident resulting in significant impact to Codespaces. We are still investigating that incident and will include it in next month’s report. This report also sheds light into an incident that impacted Codespaces in August and an incident that impacted Actions in August.
|
||||
|
||||
|
||||
|
||||
|
|
||||
|
||||
5 minutes
|
||||
|
||||
|
||||
In September, we experienced one incident that resulted in significant impact and degraded state of availability to multiple GitHub services. We also experienced one incident resulting in significant impact to Codespaces. We are still investigating that incident and will include it in next month’s report. This report also sheds light into an incident that impacted Codespaces in August and an incident that impacted GitHub Actions in August.
|
||||
|
||||
**September 8 19:44 UTC (lasting 5 hours and 11 minutes)**
|
||||
|
||||
On September 8, 2022 at 19:44 UTC, our monitoring detected an increase in the number of pull request merge failures. The impact was concentrated on Enterprise Managed Users (EMUs) with a small number of bot accounts also affected.
|
||||
|
||||
Within 45 minutes, we traced the cause to a data transition that removed inconsistent data from profile records. Unfortunately, the transition incorrectly operated on EMU accounts, removing some data that is required to successfully merge pull requests via the UI and our API. CLI merges were unaffected.
|
||||
|
||||
We restored the data from backup, but this took longer than we had anticipated. We simultaneously pursued a workaround in code, but opted not to proceed with it as it could introduce data inconsistencies. Our restore operation resolved the issue with our pull request monitors having recovered by September 9, 2022 at 00:55 UTC.
|
||||
|
||||
Following this incident, we have made changes to our data transition procedures to allow for faster restores and transitions that can be automatically rolled back without relying on backups. We are also working on multiple improvements to our testing processes as they relate to EMUs.
|
||||
|
||||
**September 28 03:53 UTC (lasting 1 hour and 16 minutes)**
|
||||
|
||||
Our alerting systems detected an incident that impacted most Codespaces customers. Due to the recency of this incident, we are still investigating the contributing factors and will provide a more detailed update on cause and remediation in the October Availability Report, which we will publish the first Wednesday of November.
|
||||
|
||||
**Follow up to August 29 12:51 UTC (lasting 5 hours and 40 minutes)**
|
||||
|
||||
On August 29, 2022 at 12:51 UTC, our monitoring detected an increase in Codespaces create and start errors. We also started seeing DNS-related networking errors in some running Codespaces where outbound DNS resolutions were failing. At 14:19 UTC, we updated the status for Codespaces from yellow to red due to broad user impact.
|
||||
|
||||
This incident was caused by an Ubuntu [security patch in systemd](https://bugs.launchpad.net/ubuntu/+source/systemd/+bug/1988119) that broke DNS resolution. In recent versions of Ubuntu, unattended upgrades for security fixes are enabled by default. Codespaces host VMs were using the default recommended settings to apply security patches automatically on running VMs. When this patch was published, Codespaces host VMs started installing and applying the patch after the VM was created. Once the patch was installed on a VM, DNS resolution was broken. Depending on the timing of when the patch was installed on the host VM, this led to a few different failure modes, including failure creating/starting Codespaces or failure, making outbound network calls inside of a codespace that was already running.
|
||||
|
||||
Once we identified systemd’s DNS resolver configuration as the source of these errors, we were able to mitigate the issue by disabling systemd’s DNS resolver and manually configuring an upstream DNS resolver IP address. We deployed a change to the DNS configuration on the host VMs at 18:13 UTC. By 18:21 UTC, we started seeing positive signs of recovery in our metrics and changed the status to yellow. Ten minutes later, at 18:31 UTC, all metrics were fully healthy and the incident was resolved.
|
||||
|
||||
Following this incident, we are updating our DNS configuration to reduce dependencies on systemd’s DNS resolver. We are also investigating whether we should continue to use unattended upgrades for security patches. Disabling unattended upgrades will give us more deterministic behavior at runtime, preventing external changes from breaking Codespaces. We will remain fully capable of quickly patching VMs across our fleet even with unattended upgrades disabled.
|
||||
|
||||
**Follow up to August 18 14:33 UTC (lasting 3 hours and 23 minutes)**
|
||||
|
||||
This incident occurred in August but was left out of the [August report](https://github.blog/2022-09-07-github-availability-report-august-2022/) because it did not result in a widespread outage. Several GitHub Actions customers experienced issues because of the degradation so we decided to include it retroactively.
|
||||
|
||||
At 14:13 UTC, there was a sudden spike in traffic to GitHub Actions which resulted in a higher than usual write load on our services. A majority of our services handled this graciously, but one of our internal services that is used for generating security tokens started returning 503 Service Unavailable errors to requests, triggering an alert to the engineering team. Further investigation revealed that the token database was experiencing a performance degradation which, compounded by the increased load, caused us to hit the database’s max concurrent connections limit. This was made worse due to a mismatch between our client-side throttling limits and database capacity, which resulted in our throttling thresholds allowing more traffic than this database had capacity to handle.
|
||||
|
||||
We mitigated the issue by scaling up the impacted database while also allowing a higher number of concurrent connections to it. The impacted service went back to a healthy state and the incident was considered resolved at 17:36 UTC. In addition to the immediate actions, we have improved our monitoring and alerting to allow faster remediation. We are also evaluating changes to our throttling mechanisms to better account for this traffic pattern.
|
||||
|
||||
## [In summary](https://github.blog#in-summary)
|
||||
|
||||
Please follow our [status page](https://www.githubstatus.com/) for real-time updates on status changes. To learn more about what we’re working on, check out the [GitHub Engineering Blog](https://github.blog/category/engineering/).
|
||||
|
||||
## Tags:
|
||||
|
||||
## Written by
|
||||
|
||||
## Related posts
|
||||
|
||||
|
||||
|
||||
###
|
||||
|
||||
[GitHub availability report: August 2026](https://github.blog/news-insights/company-news/github-availability-report-august-2026/)
|
||||
|
||||
|
||||
|
||||
In August, we experienced five incidents that resulted in degraded performance across GitHub services.
|
||||
|
||||
|
||||
|
||||
###
|
||||
|
||||
[The August 17 outage, and the work ahead](https://github.blog/news-insights/company-news/the-august-17-outage-and-the-work-ahead/)
|
||||
|
||||
|
||||
|
||||
An update on the August 17 outage and the steps we’re taking to improve reliability.
|
||||
|
||||
|
||||
|
||||
###
|
||||
|
||||
[Your guide to GitHub Universe 2026 is here: The schedule just launched!](https://github.blog/news-insights/company-news/your-guide-to-github-universe-2026-is-here-the-schedule-just-launched/)
|
||||
|
||||
|
||||
|
||||
The GitHub Universe session catalog is live. Explore interactive workshops, community talks, demos, and panels. Plus, register before August 19 to save $300.
|
||||
@@ -0,0 +1,44 @@
|
||||
# There is no “Three Mile Island” event coming for software
|
||||
|
||||
- **期号**: SRE Weekly Issue #342(2022-10-09)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2022/10/08/there-is-no-three-mile-island-event-coming-for-software/
|
||||
|
||||
## 简介
|
||||
|
||||
Why not?
|
||||
|
||||
> we’re, unfortunately, too good at explaining away failures without making any changes to our priors.
|
||||
|
||||
## 正文
|
||||
|
||||
In [Critical Digital Services: An Under-Studied Safety-Critical Domain](https://link.springer.com/content/pdf/10.1007/978-3-031-07805-7_4), John Allspaw asks:
|
||||
|
||||
Critical digital services has yet to experience its “Three-Mile Island” event. Is
|
||||
|
||||
such an accident necessary for the domain to take human performance seriously? Or can it translate what other domains have learned and make productive use of
|
||||
|
||||
those lessons to inform how work is done and risk is anticipated for the future?
|
||||
|
||||
|
||||
I don’t think the software world will ever experience such an event.
|
||||
|
||||
## The effect of TMI
|
||||
|
||||
The [Three Mile Island accident](https://en.wikipedia.org/wiki/Three_Mile_Island_accident) (TMI) is notable, not because of the immediate impact on human lives, but because of the profound effect it had on the field of safety science.
|
||||
|
||||
Before TMI, the prevailing theories of accidents was that they were because of issues like mechanical failures (e.g., bridge collapse, boiler explosion), unsafe operator practices, and mixing up physical controls (e.g., switch that lowers the landing gear looks similar to switch that lowers the flaps).
|
||||
|
||||
But TMI was different. It’s not that the operators were doing the wrong things, but rather that they did the right things based on their understanding of what was happening, but their understanding of what was happening, which was based on the information that they were getting from their instruments, didn’t match reality. As a result, the actions that they took contributed to the incident, even though they did what they were supposed to do. (For more on this, I recommend watching Richard Cook’s excellent lecture: [It all started at TMI, 1979](https://vimeo.com/showcase/6184024/video/85909644)).
|
||||
|
||||
TMI led to a kind of Cambrian explosion of research into human error and its role in accidents. This is the beginning of the era where you see work from researchers such as Charles Perrow, Jens Rasmussen, James Reason, Don Norman, David Woods, and Erik Hollnagel.
|
||||
|
||||
## Why there won’t be a software TMI
|
||||
|
||||
TMI was significant because it was an event that could not be explained using existing theories. I don’t think any such event will happen in a software system, because I think that ***every complex software system failure can be “explained”, even if the resulting explanation is lousy.*** No matter what the software failure looks like, someone will always be able to identify a “root cause”, and propose a solution (more automation, better procedures). I don’t think a complex software failure is capable of creating TMI style cognitive dissonance in our industry: we’re, unfortunately, too good at explaining away failures without making any changes to our priors.
|
||||
|
||||
We’ll continue to have [Therac-25s](https://en.wikipedia.org/wiki/Therac-25), [Knight Capitals](https://en.wikipedia.org/wiki/Knight_Capital_Group), [Air France 447s](https://surfingcomplexity.blog/2014/09/30/cloud-software-fragility-and-air-france-447/), [737 Maxs](https://bookshop.org/books/flying-blind-the-737-max-tragedy-and-the-fall-of-boeing-9780593460177/9780385546492), [911 outages](https://www.theverge.com/2014/10/3/6414949/911-call-failures-fcc), [Rogers outages](https://www.reuters.com/business/media-telecom/rogers-communications-services-down-thousands-users-downdetector-2022-07-08/), and [Tesla autopilot deaths](https://www.theverge.com/2022/7/27/23280461/tesla-autopilot-crash-motorcyclist-fatal-utah-nhtsa). Some of them will cause enormous loss of human life, and will result in legislative responses. But no such accident will compel the software industry to, as Allspaw puts it, take human performance seriously.
|
||||
|
||||
Our only hope is that the software industry eventually learns the lessons that the safety science learned from the original TMI.
|
||||
|
||||
Never say never
|
||||
Reference in New Issue
Block a user