SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,80 @@
|
||||
# There Is No Shame in Customer-Reported Incidents
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Robert Ross — FireHydrant + The New Stack
|
||||
- **链接**: https://thenewstack.io/there-is-no-shame-in-customer-reported-incidents/
|
||||
|
||||
## 简介
|
||||
|
||||
Don’t beat yourself up! This is like another form of blamelessness.
|
||||
|
||||
## 正文
|
||||
|
||||
# There Is No Shame in Customer-Reported Incidents
|
||||
|
||||

|
||||
|
||||
[via](https://pixabay.com/photos/alarm-light-siren-emergency-959592/)Pixabay.
|
||||
|
||||
[FireHydrant](https://firehydrant.com/?utm_content=sponsor+disclosure)sponsored this post.
|
||||
|
||||
I was at a community event over the summer, talking to other incident management practitioners when I heard one of them mention that he was mortified when a recent incident was only uncovered after it was reported by a customer.
|
||||
|
||||
I really felt for the guy because I’ve been there before too. And honestly, I bet most people who’ve been involved in [managing incidents](https://thenewstack.io/running-more-low-severity-incidents-is-improving-our-culture/) have also had this experience.
|
||||
|
||||
It’s not an uncommon scenario, but it shouldn’t be a painful one. It’s time to remove the shame around the idea of the customer-reported incident by talking about it. I’ll go first.
|
||||
|
||||
## Customers Are Another Form of Alerts
|
||||
|
||||
This was at a company I worked at back in my on-call responder days. We updated our deployment pipelines to use [Spinnaker](https://spinnaker.io/). We assumed since it was used by a lot of big companies, it was perfect for our situation too and was production ready.
|
||||
|
||||
We set it up so all deployments and the data about them were stored in Redis, and that’s how Spinnaker knew the current state of deploy. And since that wasn’t complex enough for us, we then used Jenkins to run our tests and build deployable artifacts; when the build turned green, it would launch a deployment pipeline in Spinnaker.
|
||||
|
||||
Then one day, Redis died on us, which meant Spinnaker lost all context for what it should be doing and what — and this is a crucial point — it had done in the past. It didn’t even produce bugs, so there was nothing that our monitoring or observability tools could have alerted us to. In fact, we only found out there was a problem because our customer support team notified us that they were getting reports of the fonts looking different on our website. Then came alerts in the form of, “Hey, where’d this page go?”
|
||||
|
||||
Because Spinnaker had no idea that it had executed a deployment pipeline for a successful build three months ago, thousands of deployments had been kicked off. The entire website was reverted to one that was three months old. Chaos ensued, and we just turned Spinnaker off. We literally just cut the power to it, then manually deployed the website’s current version.
|
||||
|
||||
There was a lot that went wrong here. We weren’t production ready, we architected an overly complex solution, but one thing I don’t count as going wrong with this incident is that we heard about it through customer support.
|
||||
|
||||
On the contrary, we were grateful. We never would’ve uncovered this problem — or it at least would’ve taken longer to do so — if it hadn’t been for our customers reporting it. There’s no shame there, [only an opportunity to learn](https://thenewstack.io/the-need-to-decouple-human-error-from-incident-response/) and make it right.
|
||||
|
||||
## Build Trust with Your Customers
|
||||
|
||||
Especially for those of us who have a lot of high-tech companies as our customers, it’s understood that bugs happen, products go down or, in my example, websites inexplicably revert to old versions.
|
||||
|
||||
Unless you’re dealing with a catastrophic incident involving missing or leaked data, most customers will give you the grace of understanding that these things happen. What you do in these situations is much more important than the fact that the alert came from a customer.
|
||||
|
||||
When you’re known for handling your worst moments well, people pay attention. I remember last year when Fastly went down in a big way. The company’s stock actually went up the next day because people were impressed by not only how quickly they remediated the problem but also [how quickly and clearly they communicated](https://www.fastly.com/blog/summary-of-june-8-outage) what was going on.
|
||||
|
||||
Slack’s another one that does a great job of this. By treating [minor bugs like incidents](https://twitter.com/bobbytables/status/1525076991220797441), and publicly declaring them even when they might affect only a small percentage of people, it’s managed to train people to check their status page or Twitter feed when they experience an issue. And when your customers know what to expect from you, and know they can depend on you, they’re more likely to stick with you.
|
||||
|
||||
Expectation-setting like this doesn’t happen accidentally, and it doesn’t happen overnight. Instead, it requires making proactive communication a priority of your incident response process. A few best practices to keep in mind include:
|
||||
|
||||
### **Have a Centralized Source of Truth for Your Latest Updates**
|
||||
|
||||
This is most likely on a status page. Whether it’s your public status page or customer-specific private status page, it should only host the most up-to-date and accurate information, and it should be easily accessible when a customer is trying to figure out what’s wrong.
|
||||
|
||||
### **Communicate Early, Often and Consistently**
|
||||
|
||||
When customers are affected, it’s important to get your message out early. You’ll want to make sure that your message is clear, honest and easy to understand. Your message should be unified across your status page, emails, social media and messages from customer-facing teams. It’s essential to train your team if they will be directly speaking with customers, so make sure you know how to work with other departments such as customer success or marketing.
|
||||
|
||||
### **Be Accountable and Take Ownership**
|
||||
|
||||
Most importantly, you should own the incident. The sentiment “honesty is the best policy” fully applies here, and customers will appreciate your transparency.
|
||||
|
||||
### **Learn from Your Incidents**
|
||||
|
||||
The key here is to partner closely with your customer support team and treat interactions with them as a two-way street. Customer- or CS-reported incidents give you a front-row look at how your customers interact with your product, and that’s an unparalleled learning opportunity. You get a deeper understanding of not only how your customers use your product, but also what they expect from you during an incident. By implementing these learnings after the incident is resolved, you truly move forward in building trust with your customers.
|
||||
|
||||
## Remove the Shame
|
||||
|
||||
Back to the story I started with about the mortified responder. His comment was met with several, “Yeah, that’s happened to us too” stories from the other responders in the room, which did a great thing: It removed the shame for him.
|
||||
|
||||
The more we talk about our incidents, with both our customers and with each other, the more we can move our industry toward a culture of psychological safety and promote a culture of [learning from incidents](https://thenewstack.io/firehydrant-managing-incidents-without-the-chaos/). There will always be incidents. And customers will always be one of the ways that we find out about them. We shouldn’t strive for perfection, but instead for open communication and reflection.
|
||||
|
||||
|
||||
[YOUTUBE.COM/THENEWSTACK
|
||||
|
||||
|
||||
Tech moves fast, don't miss an episode. Subscribe to our YouTube
|
||||
channel to stream all our podcasts, interviews, demos, and more.](https://youtube.com/thenewstack?sub_confirmation=1)
|
||||
@@ -0,0 +1,247 @@
|
||||
# Reduce software outage risk with passive guardrails
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Ash Patel — SREPath
|
||||
- **链接**: https://www.srepath.com/reduce-software-outage-risk-with-passive-guardrails/
|
||||
|
||||
## 简介
|
||||
|
||||
> In this article, I will share with you how setting up passive guardrails in and around developer workflows can reduce the frequency and severity of incidents and outages.
|
||||
|
||||
## 正文
|
||||
|
||||
***Shocking fact:*** only 10-25% of software outages are because of hardware or network failure. The rest are the result of human error like misconfiguration — paraphrasing *Martin Kleppman, Designing Data-Intensive Applications*
|
||||
|
||||
|
||||
In this article, I will share with you how setting up passive guardrails in and around developer workflows can reduce the frequency and severity of incidents and outages.
|
||||
|
||||
We will cover:
|
||||
|
||||
- why passive guardrails are important *and*
|
||||
- how they can be implemented
|
||||
|
||||
## Why passive guardrails are important
|
||||
|
||||
Passive guardrails save Site Reliability Engineers (SREs) from becoming the secret police for management to shame developers when they make mistakes. Let me explain.
|
||||
|
||||
Extreme situations of an incident or outage may involve management openly chastising developers as a whole or individually.
|
||||
|
||||
Higher managers might delegate this task to the people who own reliability. Guess who that is? Yes, you, the humble Site Reliability Engineer.
|
||||
|
||||
**Reality check:** we can push the blameless culture as much as we want within engineering circles, but we have to consider that a large part of management doesn’t buy into our cultural fancies
|
||||
|
||||
A way to prevent this peril is to employ passive guardrails that keep developers within safe confines.
|
||||
|
||||
From a developer’s perspective, it would only seem to serve as a means to stay on a well-trodden “golden path”, [as described by Spotify’s platform engineers](https://engineering.atspotify.com/2020/08/how-we-use-golden-paths-to-solve-fragmentation-in-our-software-ecosystem/).
|
||||
|
||||
By definition, guardrails are controls that prevent deviations from required behaviors.
|
||||
|
||||
Let’s delineate active versus passive guardrails.
|
||||
|
||||
-
|
||||
**Active guardrails** can be seen as the rules and policies that govern day-to-day behaviors and must be consciously considered when deploying code or altering the system. They are seen as*punishable if circumvented* .
|
||||
-
|
||||
**Passive guardrails** , on the other hand, are a more subtle way to drive behavior. They create boundaries that form a relatively unconscious workflow after some time. They are seen as a*mishap or accident if somehow bypassed* .
|
||||
|
||||
**Here’s a real-life, non-software example of a passive guardrail:**
|
||||
|
||||
Think of when you drive along the highway. You are not thinking about the median strip and lines that set a passive boundary between your vehicle and traffic going in the opposite direction. But they’re there to keep your mind focused in the right direction.
|
||||
|
||||
Remember, developers are focused on launching features as quickly and efficiently as possible. Very few would (or at least should) be distraught at not having root access to production servers or being intentionally guided around tools and platforms.
|
||||
|
||||
Some benefits of passive guardrails for you and your SRE team will be:
|
||||
|
||||
- less time, mental bandwidth, and energy spent on enforcing policies and procedures
|
||||
- less animosity from developers
|
||||
- reduced manual toil due to more automated processes and built-in mechanisms (passive guardrails inherently rely on automation)
|
||||
|
||||
Developers benefit as well, as they should. They can:
|
||||
|
||||
- move faster with launching services to production without your active involvement
|
||||
- cut their risk of accidentally bypassing best practices & protocols because these will be already baked into the workflow
|
||||
|
||||
## Techniques for implementing passive guardrails
|
||||
|
||||
We will cover in detail 7 techniques that support the passive software guardrail concept:
|
||||
|
||||
1. Doubtless software system design
|
||||
2. Clone production to full-featured sandbox
|
||||
3. Pre-production checklist for developers to follow
|
||||
4. 2-person authentication for deploys
|
||||
5. Stagger rollout of code changes
|
||||
6. Have an early warning system for failure
|
||||
7. Service snapshots for rapid rollback
|
||||
|
||||
These techniques are an amalgamation of several ideas I’ve noted across several books, including *Seeking SRE* (Blank-Edelman, 2018) and *Designing Data-Intensive Applications* (Kleppmann, 2017), as well as SRECon talks like *[Confessions of a Systems Engineer](https://youtu.be/F1HLaTUJy_s) by David Argent*.
|
||||
|
||||
Let’s begin.
|
||||
|
||||
### Doubtless software system design
|
||||
|
||||
In my opinion, a well-designed system should be the first step to setting passive guardrails for developers. It should remove any ambiguity or doubt from their minds when they get around to launching their service.
|
||||
|
||||
This means having **discretely developed and well-documented service boundaries, APIs, and admin interfaces**.
|
||||
|
||||
When ambiguity is removed, the path to launch becomes crystal clear, with developer improvisation (and subsequently error) potential approaching 0%.
|
||||
|
||||
Here’s an example from Netflix on system design acting as a passive guardrail:
|
||||
|
||||
“Some changes we incorporate into tooling might be called a guardrail. A concrete example is an additional step in deployment added to Spinnaker that detects when someone attempts to remove all cluster capacity while still taking significant amounts of traffic. This guardrail helps call attention to a possibly dangerous action, which the engineer was unaware was risky. This is a method of “just in time” context.” — *in Seeking SRE: Conversations About Running Production Systems at Scale by David N. Blank-Edelman*
|
||||
|
||||
|
||||
Achieving this kind of result may involve creating tool features or prompts to guide developers through key steps. All of this will be a balancing act because you risk making all of these components too restrictive or minimalistic.
|
||||
|
||||
Give enough power to these components for developers to continue being happy with them. This means consistently taking honest feedback from all stakeholders to improve the system design to meet their changing needs.
|
||||
|
||||
### Clone production to full-featured sandbox
|
||||
|
||||
One of the most common complaints I have heard from operations engineers about developers is that “they code on ‘monster’ local machines that have 32MB RAM and then wonder why VMs in production with much less RAM allocation keep struggling”.
|
||||
|
||||
Developers are almost always working on features in isolation from production. There’s a good rationale for this: to prevent experimental work from negatively impacting real-world services and users.
|
||||
|
||||
And so, developers code away at their services with unknowns at play. Some developers may have:
|
||||
|
||||
- some idea of what the data will look and play like but lack the complete picture.
|
||||
- an indication of resource demand, but even still nowhere near the true numbers.
|
||||
- little insight into how hard users are pushing the software in other areas of the system
|
||||
|
||||
The end result is that developers risk factoring code for an idealistic world that doesn’t truly reflect your software’s user base or data.
|
||||
|
||||
You can’t blame a developer for any of the above. They are working in a sandbox, after all.
|
||||
|
||||
A solution to this unfortunate problem is to continually give developers a realistic sandbox that reflects the service as it stands in production.
|
||||
|
||||
By doing this, you would be enabling a safe environment for developers to manipulate and test code in an environment that:
|
||||
|
||||
1. reflects the “real world” system AND
|
||||
2. continues to safeguard the production system from experimental work
|
||||
|
||||
### Pre-production checklist for developers to follow
|
||||
|
||||
Software teams launch services to production more frequently than ever before, and they make many ongoing tweaks to these services. It is critical to help them effectively launch changes.
|
||||
|
||||
Google has a dedicated team of launch coordination engineers (LCE) for this effort, but we are not Google. We’ll forego the extra title and cost as most organizations that aren’t Google-scale cannot justify it.
|
||||
|
||||
In many organizations, SREs review, consult, collaborate, and even contribute, but the final responsibility for production delivery remains with the product engineering team that owns a given service.
|
||||
|
||||
With tight resources in place, SREs can create pre-launch assessments that make sense for developers and prevent future mishaps in production.
|
||||
|
||||
The pre-launch assessment may be called a myriad of terms depending on the organization, like *Production Readiness Checklist* or *Operational Readiness Review*.
|
||||
|
||||
Google’s book, *Site Reliability Engineering (2016)*, has a section on [ensuring reliable product launches](https://sre.google/sre-book/reliable-product-launches/). Below are examples of the kinds of questions you’ll find in their pre-launch checklist:
|
||||
|
||||
- Are you storing persistent data? If yes, make sure you backup the data (here are instructions)
|
||||
- Could a user abuse your service? If yes, implement rate limiting and query quotas. (here’s the link to a service to help you do this)
|
||||
|
||||
The book’s authors assert that “in practice, there is a near-infinite number of questions to ask about any system, and it is easy for the checklist to grow to an unmanageable size.” So they follow a few logical rules to elucidate the right path:
|
||||
|
||||
- importance of questions must be substantiated from experience, like a launch disaster
|
||||
- instructions given to developers must be concrete, practical and reasonable
|
||||
- stay on top of changes in the system and reflect these in the question/instruction set
|
||||
- run regular reviews (once to twice a year) of the pre-launch checklist to ensure the above
|
||||
|
||||
You may also develop your own SRE checklist for covering key infrastructure components that the service will rely on. That checklist may cover issues concerning some or all of the following:
|
||||
|
||||
- Security – authentication, secrets management, TLS, vulnerability scanning
|
||||
- Observability – availability metrics, tracing, monitoring, alerting
|
||||
- Storage and backups – statefulness, backup availability, and practices
|
||||
- Networking – VPCs, subnets, IPs, service discovery, mesh, and more
|
||||
- Performance – benchmarking, load testing, tuning components, etc
|
||||
- Capacity – horizontal scaling, vertical scaling, availability zoning
|
||||
- Cost management – reserved vs. spot resources, closing underused resources
|
||||
- Testing – automated testing after commits, scheduled testing, test coverage
|
||||
|
||||
You will need to factor in how dependencies will evolve. New ones will emerge and existing ones will alter or deprecate. There will be upstream and downstream impacts from these changes on components that rely on them.
|
||||
|
||||
### Implement 2-person authentication
|
||||
|
||||
Not to be mistaken with 2-factor authentication (2FA), which relies on a single user confirming their intent to a certain action through a secondary device. You may have seen 2FA when trying to log into sensitive systems like your banking service.
|
||||
|
||||
Why not have the same level of corroboration when your system is, for example:
|
||||
|
||||
- expecting a major commit or
|
||||
- a critical service is due for an update
|
||||
|
||||
But instead of the lone developer making these necessary commits by authenticating with their mobile device, have 2 people — both being engineers — sign off on the work.
|
||||
|
||||
What’s the rationale behind this?
|
||||
|
||||
1. It puts a second pair of eyes on the code and pre-launch checklist
|
||||
2. It may cause an unconscious need within developers not to let their peers down
|
||||
|
||||
The humble engineer may think twice about their code quality before it reaches production. After all, “I don’t want sloppy code to get in the way of the good rapport I have with my colleague.”
|
||||
|
||||
Check out this [infrastructure-as-code (IAC) example for 2-person authentication](https://www.srepath.com/sre-safer-infrastructure-as-code-iac#IAC-2-person-authentication)
|
||||
|
||||
### Stagger rollout of code changes
|
||||
|
||||
Pushing code to production has inherent risks. Pushing code across the entire customer base, region, or organization at once amplifies risk. How can you mitigate this risk?
|
||||
|
||||
I recommend a segment-based staggered rollout to minimize the blast radius of erroneous code changes in production. Examples of segments include:
|
||||
|
||||
- the least fussy customer base, then through the general userbase all the way out to more discerning customers
|
||||
- a single VM to a group of VMs to a region, then across regions
|
||||
|
||||
This process should be as automated as possible and should force the developer to think. In order to implement this guardrail effectively, you will need to work out:
|
||||
|
||||
- how to segment your users and VMs for appropriate blast radius size
|
||||
- how quickly to roll out the changes across these segmented groups
|
||||
|
||||
Set a reasonable time interval to allow for the detection of anomalies and failures in production.
|
||||
|
||||
Besides segmenting by audience or machine, you may also consider the following approaches to reducing blast radius:
|
||||
|
||||
I will explore them more in-depth in a future write-up.
|
||||
|
||||
### Have an early warning system for failure
|
||||
|
||||
In a way, software systems are not that different from weather systems. You want to know as early as possible when problems are beginning to surface so that you can prevent a problem from turning into a full-blown disaster.
|
||||
|
||||
Or at least minimize the damage from the incoming disaster.
|
||||
|
||||
Observability is the name of this game, and it should serve as the bread and butter of any software engineering team. You may consider setting up a full telemetry suite that tracks performance as well as service uptime. This would include:
|
||||
|
||||
-
|
||||
*logging* relevant system events
|
||||
-
|
||||
*tracing* across services for issues
|
||||
-
|
||||
*monitoring* resource usage and performance
|
||||
|
||||
As an early warning system, observability can advise developers and SREs where tweaks and more resources are required — before a deluge of users and usage takes the system down.
|
||||
|
||||
I will cover observability in-depth in a dedicated write-up in the future, as the breadth and complexity of the capability lend it such a privilege.
|
||||
|
||||
### Service snapshots for rapid rollback
|
||||
|
||||
Let’s say you’ve done all of the above, and yet something still goes wrong. What will you do?
|
||||
|
||||
A viable solution is to take time-interval snapshots of services-in-production, as well as platform configurations (like .tf and YAML files). See an error crop up from the latest update? Roll back to a point that doesn’t break your software-in-production.
|
||||
|
||||
The time interval will depend on your ability and appetite to automate snapshots, as well as frequencies of deployment and platform changes.
|
||||
|
||||
You will essentially have multiple viable versions of the same code that can be shifted to and fro as necessitated by operational needs and challenges.
|
||||
|
||||
Netflix SREs employ this practice in their Spinnaker continuous delivery platform. The platform ensures new code changes are automatically deployed in a blue-green fashion.
|
||||
|
||||
*I think we’ve all worked at companies where we upgrade something, and it turns out it was bad, and we spend the night firefighting it because we’re trying to get the site back up because the patch didn’t work. [Instead of that] when we go to put new code into production… we just push a new version alongside the current code base. It’s that red/black or blue/green – whatever people call it at their company… if something breaks in the canary… we immediately roll back. This brings recovery down from hours to minutes.* — Coburn Watson, Director of Reliability, Performance and Cloud Infrastructure at Netflix, in the book “Seeking SRE: Conversations About Running Production Systems at Scale” (2018)
|
||||
|
||||
|
||||
In effect, older code is still active on one VM while the newly deployed code is running on another. If the new code deployment fails, the system reverts to the most recent reliably-running code.
|
||||
|
||||
## Bibliography
|
||||
|
||||
1. Kleppmann, M. (2018). *Designing data-intensive applications: the big ideas behind reliable, scalable, and maintainable systems. O’Reilly* Media.
|
||||
2. Blank-Edelman, D.N. (2018). *Seeking SRE* . O’Reilly Media.
|
||||
3.
|
||||
*SREcon Conversations with David Argent, Amazon (August 2020)* . [online] Available at:[https://www.youtube.com/watch?v=F1HLaTUJy_s](https://www.youtube.com/watch?v=F1HLaTUJy_s) [Accessed 20-22 Oct. 2022].
|
||||
4.
|
||||
*5 Lessons Learned From Writing Over 300,000 Lines of Infrastructure Code* . [online] Available at:[https://www.youtube.com/watch?v=RTEgE2lcyk4](https://www.youtube.com/watch?v=RTEgE2lcyk4) [Accessed 18-20 Oct. 2022].
|
||||
|
||||
|
||||
|
||||
[see all](https://www.srepath.com/author/kashaup/))
|
||||
|
||||
- [#34 From Cloud to Concrete: Should You Return to On-Prem?](https://www.srepath.com/sre-2016-book-reaction-chapter-1-part-1-3/) – March 26, 2024
|
||||
- [#33 Inside Google’s Data Center Design](https://www.srepath.com/sre-2016-book-reaction-chapter-1-part-1-2/) – March 19, 2024
|
||||
- [#32 Clarifying Platform Engineering’s Role (with Ajay Chankramath)](https://www.srepath.com/platform-engineering-role-software-operations/) – March 14, 2024
|
||||
@@ -0,0 +1,46 @@
|
||||
# Disney SRE “Proximity Powered Engineering” Culture: Jason Cox at DOES 2022
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Shaaron A Alvares — InfoQ
|
||||
- **链接**: https://www.infoq.com/news/2022/10/disney-sre-empathy/
|
||||
|
||||
## 简介
|
||||
|
||||
This conference talk summary outlines the three main lessons Jason Cox learned as director of SRE at Disney.
|
||||
|
||||
## 正文
|
||||
|
||||
The DevOps Enterprise Summit held its first in-person conference in Las Vegas since 2019 and the pandemic. [Jason Cox](https://www.linkedin.com/in/jasoncox3/), director, Global SRE at the Walt Disney Company, and co-author of "[Investments Limited](https://www.amazon.com/dp/1950508536/ref=tsm_1_fb_lk)", kicked off the conference with a presentation describing how, in the last few years, he developed a world-class centralized shared services Site Reliability Engineering organization based on "proximity-powered empathy engineering" and three core values, "Listen" – "Empathize" – "Actually Help".
|
||||
|
||||
Cox leads Disney’s Global SRE group, a centralized shared services team providing reliability engineering to the entire company. Shared Services are often not well-integrated, nor appreciated, because they focus on maximizing cost reduction and are not always well aligned with the problems their business and engineers are trying to solve. Cox shared a model he deployed in the last few years, along with the learnings, that enabled his organization to succeed and earn its stakeholders’ trust.
|
||||
|
||||

|
||||
|
||||
|
||||
### Lesson 1 – Listen: Know the Business - Know the Mission - Know the Team
|
||||
|
||||
Know the Business: the first thing to do is to connect with the business and to listen, understand what they need, what their business is about, how they ship their products, and what are the complications they face to get there.
|
||||
|
||||
Know the Mission and the Team, because it is equally important to understand their North Star, their vision, and goals, where they are trying to go, and again listen to their teams’ struggles along the way.
|
||||
|
||||
### Lesson 2 – Empathize: Shared Mission - Shared Struggles - Shared Wins
|
||||
|
||||
If we want to connect to the business, we need to know their frame of reference, and we can do this by putting ourselves in their shoes. We can better understand and empathize with the problems and challenges they face, and connect as one team, one family. Cox developed a "proximity powered empathy engineering culture" where SRE engineers don’t wait for their business to go to them; instead, they go to them. They understand the pains they face and help relieve them by providing real help in real-time.
|
||||
|
||||
When we listen and empathize with people, we find out that they are actually looking for help, which leads to the third lesson.
|
||||
|
||||
### Lesson 3 - Go See and Actually Help: Build Community - Build Trust - Build Magic Together
|
||||
|
||||
Do something to help them. If you do, people will come to expect that you can help them and will look forward to seeing you again - Taiichi Ohno.
|
||||
|
||||
|
||||
Cox and his team looked at opportunities where the business needed SRE support and developed an SRE community to network more effectively with all technology groups across Disney. As they embedded with more business areas, the more they were solicited to come and help. That’s why, according to Cox, it’s very important to:
|
||||
|
||||
"Be a community partner not a command tower"
|
||||
|
||||
|
||||
They invested in other areas to build their SRE Community: they contributed to establishing and sustaining the Jedi Engineering Training Academy, a center dedicated to furthering engineering excellence and knowledge sharing; they help technologists connect to other technologies, businesses to businesses, they create opportunities to learn from internal and external experts; they go on location to help ship great products content and experiences, all this with the objective of giving time back to the business, "because, as a shared service, that's really what we should be doing".
|
||||
|
||||
Cox and his Global SRE organization put the [#1 Agile Value first](https://agilemanifesto.org/): Individuals and Interactions over Processes and Tools. In this article, we shared how he fosters a [generative culture](https://www.infoq.com/articles/DevOps-Culture-Change/) at Disney that supports his teams and his customers. In the business's own words:
|
||||
|
||||
Your team is unbelievable, and I mean that. Thanks to you and your team for stepping in and making this a world-class site. - Creative director, ABC
|
||||
@@ -0,0 +1,13 @@
|
||||
# How Meta production engineers solve the problem of scale
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Jason Kalich — Meta
|
||||
- **链接**: https://tech.fb.com/ideas/2022/10/how-meta-production-engineers-solve-the-problem-of-scale/
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s a look at how Meta has structured its Production Engineer role, their name for SREs.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 400
|
||||
@@ -0,0 +1,149 @@
|
||||
# The computer errors from outer space
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Chris Baraniuk — BBC
|
||||
- **链接**: https://www.bbc.com/future/article/20221011-how-space-weather-causes-computer-errors
|
||||
|
||||
## 简介
|
||||
|
||||
Bit-flips caused by cosmic rays seem incredibly rare, but they become more likely as we make circuits smaller and our infrastructures larger.
|
||||
|
||||
## 正文
|
||||
|
||||
# The computer errors from outer space
|
||||
|
||||
 Nasa
|
||||
|
||||
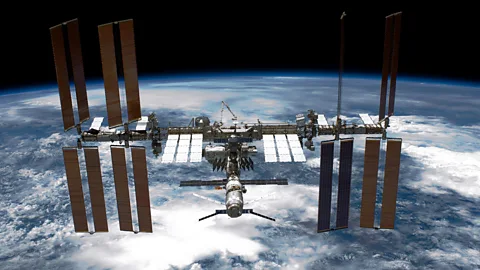
**The Earth is subjected to a hail of subatomic particles from the Sun and beyond our solar system which could be the cause of glitches that afflict our phones and computers. And the risk is growing as microchip technology shrinks.**
|
||||
|
||||
Zap. A muscle in her chest twitched. Zap. And again. Marie Moe could feel it. She could even see it. She looked down and the muscle, just to the left of her breastbone, was visibly pulsating. Convulsing with the rhythm of a vigorous heartbeat.
|
||||
|
||||
The cyber-security researcher was on a plane, about 20 minutes from its destination, Amsterdam, when it started. Fear gripped her. She knew immediately that something was wrong with her pacemaker, the small medical device implanted in her chest that used electrical impulses to steady her heartbeat.
|
||||
|
||||
Could one of the wires that connected the pacemaker to her heart have got damaged? Or come loose? Moe alerted the cabin crew, who at once arranged for an ambulance to be ready and waiting for her at the airport. Had the plane been any further from Amsterdam, the pilot would have made an emergency landing at another airport, she was told.
|
||||
|
||||
When Moe arrived at a nearby hospital, doctors pored over her. A pacemaker technician soon found the problem. It was the gadget's tiny computer. Data stored inside the pacemaker's computer, so crucial to its functioning, had somehow got corrupted.
|
||||
|
||||
And for Moe, the prime suspect that she says most likely sparked this unsettling episode was a cosmic ray from outer space: a chain of subatomic particles slamming into one another in the Earth's atmosphere, like balls colliding on a snooker table, with one eventually careering into her pacemaker's built-in computer mid-flight.
|
||||
|
||||
The theory is that, upon impact, it caused an electrical imbalance that altered the computer's memory – and ultimately changed her understanding of the life-saving technology inside her forever.
|
||||
|
||||
When computers go wrong, we tend to assume it's just some software hiccup, a bit of bad programming. But ionising radiation, including rays of protons blasted towards us by the sun, can also be the cause. These incidents, called [single-event upsets](https://www.sciencedirect.com/science/article/pii/B9781782422211000071), are rare and it can be impossible to be sure that cosmic rays were involved in a specific malfunction because they leave no trace behind them.
|
||||
|
||||
And yet they have been singled out as the possible culprits behind numerous extraordinary cases of computer failure. From a vote-counting machine that added thousands of non-existent votes to a candidate's tally, to a commercial airliner that suddenly dropped hundreds of feet mid-flight, injuring dozens of passengers.
|
||||
|
||||
 Nasa
|
||||
|
||||
As human society only becomes more dependent on digital technology, it's worth asking how big a risk cosmic rays pose to our way of life. Not least because, with the [continuing miniaturisation of microchip technology](https://www.bnl.gov/tandem/capabilities/seu.php), the charge required to corrupt data is getting smaller all the time, meaning it is actually getting easier for cosmic rays to have this effect.
|
||||
|
||||
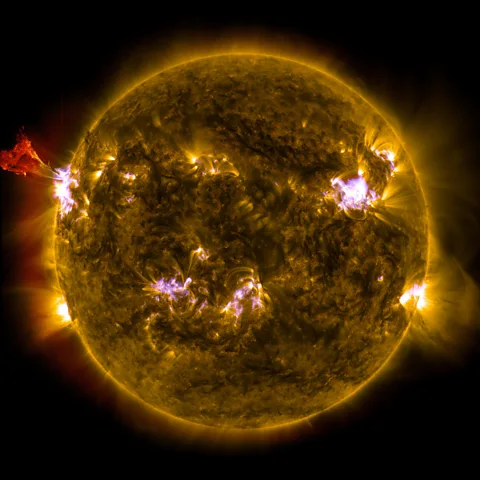
Plus, since giant ejections from the sun can sometimes send huge waves of particles towards Earth, what's called space weather, an unnerving prospect looms: we could see much more disruption to computers than we're used to during a massive geomagnetic storm in the future.
|
||||
|
||||
Moe's frightening experience with her pacemaker happened in 2016. Once she was discharged from hospital, she received a detailed report from her pacemaker's manufacturer about what had happened. "That's where I learned about the bit flips," recalls Moe, who is now a senior consultant at cyber-security firm Mandiant.
|
||||
|
||||
Inside the pacemaker's computer memory, data is stored in the form of bits – often referred to as "ones and zeroes". But the report explained that some of these bits had reversed, or flipped, altering the data and causing a software error. Think of it like pressing the wrong end of the rocker in a long row of light switches. A part of the room will stay dark.
|
||||
|
||||
In this case, the error prompted the pacemaker to go into "backup programme mode", says Moe, and it began pacing her heart at a default 70 beats per minute with a heightened impulse. "That's what caused the very uncomfortable twitching," she explains.
|
||||
|
||||
In order to fix it, the pacemaker technician had to reset the device to factory settings in the hospital and these were later reconfigured appropriately to suit Moe's heart. But the report offered no definitive conclusions as to why those pivotal bits had flipped in the first place. One possibility mentioned, however, was cosmic radiation. "It's hard to be 100% sure," says Moe. "I don't have any other explanation to offer you."
|
||||
|
||||
That such a thing can happen has been understood since at least the 1970s, when researchers showed that radiation from outer space could [affect the computers on satellites](https://ieeexplore.ieee.org/document/4328188). This radiation can take various forms and originate from a number of different sources, both inside and outside our Solar System. But here's what one scenario might look like: protons blasted towards Earth by the Sun smash into atoms in our atmosphere, releasing neutrons from the nuclei of those atoms. These high energy neutrons don't have a charge but they can go on to smash into other particles, triggering secondary radiation that does have a charge. Because bits in computer memory devices are sometimes stored as a tiny electrical charge, that secondary radiation now flying around can upend the bits, flipping them from one state to another, which changes the data.
|
||||
|
||||
*You might also be interested to read:*
|
||||
|
||||
Cosmic radiation increases in prevalence with altitude, mainly because our atmosphere helps to shield us from the majority of it. Air travellers, for example, [are more exposed to this radiation](https://www.nasa.gov/feature/goddard/2017/nasa-studies-cosmic-radiation-to-protect-high-altitude-travelers) than people on the ground, which is why air crews have limitations on the amount of time they can spend flying each month. But if this subatomic hurly-burly was behind Moe's pacemaker glitch, it must be an extraordinarily rare occurrence, she stresses.
|
||||
|
||||
"The benefit of having a pacemaker very much outweighs this risk," she adds. "I actually feel more confident trusting my device because I know it has this backup in case something goes wrong with the code."
|
||||
|
||||
But the impact of cosmic rays on other computers could, in theory, be disastrous. In one much-discussed incident, a 2008 Qantas Airways flight over Western Australia [fell hundreds of feet twice within 10 minutes](https://www.atsb.gov.au/publications/investigation_reports/2008/aair/ao-2008-070.aspx), injuring dozens of passengers on board – many of whom were not in their seats or buckled up at the time. Several suffered bruises to their limbs while others knocked their heads against the interior of the cabin, for example. One child who was wearing a seatbelt was jolted so badly that they suffered injuries to their abdomen.
|
||||
|
||||
An [investigation by the Australian Transport Safety Bureau](https://www.atsb.gov.au/publications/investigation_reports/2008/aair/ao-2008-070.aspx) found that, prior to the erratic behaviour of the plane, erroneous computer data in the on-board systems had misrepresented the angle at which the aircraft was flying. This prompted the two automated nose-dives. As for what actually set off this chain of events, the report noted: "there was insufficient evidence available to determine whether [an ionising particle altering computer data] could have triggered the failure mode" – meaning that it remains a possibility. In contrast, all the other possible triggers considered by investigators were judged as "very unlikely" and one other as "unlikely".
|
||||
|
||||
 Alexander Gerst/ESA
|
||||
|
||||
There's also the case of [the voting machine in Belgium](https://www.independent.co.uk/news/science/subatomic-particles-cosmic-rays-computers-change-elections-planes-autopilot-a7584616.html) in 2003 that gave a political candidate in an election 4,096 additional votes. Some have theorised that this, too, was the result of ionising radiation messing with a computer.
|
||||
|
||||
And what about the speedrunner – someone who tries to complete video games in record time – who experienced a weird glitch in Super Mario 64 back in 2013? To the gamer's surprise, Mario suddenly teleported upwards in the game, a behaviour [later traced back to a flipped bit](https://www.thegamer.com/how-ionizing-particle-outer-space-helped-super-mario-64-speedrunner-save-time/) in the code that determines the position, in 3D, of the moustachioed character at any given time. Analysis uncovered little in the way of an explanation for this behaviour, dubbed an upwarp, and so the possibility of cosmic particles interfering with the game cartridge arose in discussions about the incident.
|
||||
|
||||
More recently in April 2022, Travis Long, a software engineer at Mozilla, posted a blog in which he explained that the huge swathes of [telemetry data](https://firefox-source-docs.mozilla.org/toolkit/components/telemetry/index.html) that the company routinely gathers from users of its Firefox web browser [sometimes contain unexplained errors, on the order of individually flipped bits](https://blog.mozilla.org/data/2022/04/13/this-week-in-glean-what-flips-your-bit/). Long noted that a recent bug associated with these tiny errors coincided with a geomagnetic storm.
|
||||
|
||||
"I started to really wonder if we could possibly have detected a cosmic event through these single-event upsets in our telemetry data," he wrote.
|
||||
|
||||
Whether ionising radiation is behind them or not, we can encounter flipped bits as we browse the internet. In 2010, a cyber-security researcher called Artem Dinaburg, who now works for the appropriately named firm Trail of Bits, realised this. He registered a handful of domain names that were similar to popular domains but with one incorrect character in the url.
|
||||
|
||||
Take "bbc.com" as an example. If you were to mistype it, you might enter "bbx.com" by accident, given that "x" is beside "c" on English computer keyboards. A bit error is different. It means that at least one bit in the binary code that represents each of the characters in "bbc.com" is wrong. In binary, the letter "b" is "01100010" while "c" is "01100011". If you flip just one bit, let's say the last bit of the code for "c", turning it from 1 to 0, then it becomes "b" and you'd end up at "bbb.com" instead.
|
||||
|
||||
How cosmic rays flip bits
|
||||
|
||||
Single event upsets (SEUs) occur in computer circuits when high-energy particles such as neutrons or muons from cosmic rays or gamma-rays strike the silicon used in microchips. This generates an [electric charge that can change the internal voltage of nearby transistors](https://eprints.ucm.es/id/eprint/28903/1/eprintsucm28903.pdf), corrupting the data stored there. In some cases these events can destroy the microelectronics completely, rendering the computer useless, but it can also lead to temporary changes that affect the machine's behaviour.
|
||||
|
||||
A bit flip isn't something that is itself visible to a computer user, though they might notice the consequences. A bit flip happens within the computer's memory and, in the processing of a URL, it could occur at various stages, such as when your computer requests a web page on the internet or when the web server to which you connect responds to that request.
|
||||
|
||||
Once Dinaburg had some bit-altered URLs registered, he just sat back and waited. "To my huge surprise, I started getting things connecting," he recalls. "In a lot of the world's computers, there are single bit errors, or sometimes multiple bit errors that happen, and if they happen at just the right place at just the right time, they can affect what domain your software is looking up."
|
||||
|
||||
The problem with all of the above examples is that there is no way to prove that a cosmic particle was behind any of them. And though some may lean towards that explanation, it can easily be challenged by more mundane theories. Dinaburg says computer memory bugs could be behind a lot of [the connections he recorded in his experiment](https://web.archive.org/web/20210318044902/https:/dinaburg.org/bitsquatting.html), for example.
|
||||
|
||||
And last year, the speedrunner who experienced the weird Super Mario glitch posted a video to YouTube [of his game frozen mid-play](https://www.youtube.com/shorts/ba32YZ6I4Yg).
|
||||
|
||||
The title of the video, "Was it really an ionising particle, though?" appeared to jokingly suggest that the speedrunning incident might have just been a random game glitch. A fellow speedrunner who uses the pseudonym pannenkoek2012 and who offered $1,000 (£900) to anyone who could explain why Mario teleported suddenly in the 2013 incident tells BBC Future, "I lean towards hardware malfunction" – rather than cosmic rays as the culprit.
|
||||
|
||||
In certain scenarios, there's enough data to indicate that radiation was behind multiple bit flips. To return to satellites, one group of researchers recently investigated more than 2,000 bit errors logged by a satellite over roughly two years in orbit. The team [published the results of this work in 2020](https://www.sciencedirect.com/science/article/abs/pii/S0273117720309054). The data errors were automatically corrected during the satellite's flight but, had they stayed in place, they would have misrepresented the vehicle's position.
|
||||
|
||||
By analysing the satellite's memory records, the researchers were able to plot when and where the errors occurred during its orbit. A huge number of the errors were clustered in an area called the South Atlantic Anomaly (SAA), where there is heightened cosmic radiation above the Earth's surface. It is well-known that this plays havoc with computer systems on satellites and spacecraft. According to Nasa, astronauts on the space shuttle [used to notice that their laptops sometimes crashed when the space shuttle, now no longer in service, passed through the SAA](https://www.nasa.gov/mission_pages/shuttle/flyout/flyfeature_shuttlecomputers.html).
|
||||
|
||||
 Alamy
|
||||
|
||||
But for single errors that occur more or less randomly on or nearer the ground, proving the involvement of cosmic rays is not easy. The slipperiness of the subatomic particles zooming all around us is not news to Paolo Rech at Trento University in Italy. "It's impossible to be conclusive. That is the fun part," he says, referring to incidents such as the Super Mario upwarp. And yet the possibility that such particles can cause tiny yet impactful data errors in computer systems is not in dispute, as Rech explains.
|
||||
|
||||
In lab experiments, he has some equipment that can accelerate neutrons artificially in order to point them at electronics and track the bit errors that the flow of particles induces. It's designed to emulate the neutron flux at ground level on Earth – but multiplied 100 million times.
|
||||
|
||||
"Rather than waiting months or years to discover an error, you can have errors in seconds or minutes," he says, referring to work that he and his colleagues at the ISIS Neutron and Muon Source in the UK and Los Alamos National Labs in the US have conducted.
|
||||
|
||||
It's a way of studying the effects that single-event upsets could have out in the wild, just sped up for convenience. Rech and his colleagues have a specific goal in mind, though. With the rise of self-driving car technology, it's possible that computer systems on these vehicles could malfunction due to cosmic rays. What if, during an automated trip, imagery from a camera mounted at the front of the car became corrupted and the on-board computer failed to spot a person walking out in front of the vehicle?
|
||||
|
||||
By generating imagery with distortions that could conceivably be caused by cosmic rays, and using this to train artificial neural networks, Rech says he and colleagues have reduced the chances of such an error 10-fold. However, the research is yet to be published and he says he's not allowed to reveal what the starting level of accuracy was during the experiments.
|
||||
|
||||
Such interventions could make self-driving cars of the future safer but they wouldn't eliminate the possibility of a cosmic ray causing other problems. And this raises an interesting conundrum for insurers.
|
||||
|
||||
"In a world of fully autonomous vehicles, how can you prove the accident happened because of cosmic rays?" says Rech. "That is very challenging. I mean, it's impossible, by definition." In ambiguous cases, disputes over whether a human or technology manufacturer – or space weather – was at fault might be difficult to resolve.
|
||||
|
||||
One other point. Rech says it would, in principle, be possible for someone to try and induce bit errors in a computer system intentionally (and perhaps maliciously) by building a particle accelerator and aiming it at a computer's memory modules. It would be very difficult to actually do this effectively, however, he adds.
|
||||
|
||||
Natural sources of radiation remain the most important. And when it comes to cosmic rays, or space weather, it's important to make clear that it is just like Earth's weather – it varies. Sometimes big storms arise.
|
||||
|
||||
In early September 1859, the most intense geomagnetic storm ever recorded raged in the planet's atmosphere. The Carrington Event, named after British astronomer Richard Carrington, was caused by [solar flares that flung huge quantities of subatomic particles towards Earth](https://www.bbc.com/future/article/20130823-all-eyes-on-the-space-storms). The geomagnetic activity caused incredible displays of aurora borealis and induced charges in electrical wires. Some telegraph operators reported seeing sparks bursting out of their equipment.
|
||||
|
||||
If such an event were to occur in the future, it could theoretically damage power lines and internet cables across many regions, says Sangeetha Abdu Jyothi at the University of California, Irvine. "There is also this risk of charged particles causing data corruption," she adds. "Right now, the actual extent of damage, it's very difficult to predict."
|
||||
|
||||
 Don Despain/Alamy
|
||||
|
||||
Daniel Whiteson, also at the University of California, Irvine, agrees, adding that such an incident could potentially be "catastrophic" and that our understanding of the physics inside the Sun is not well-developed enough to allow us to be able to predict major solar ejections well in advance.
|
||||
|
||||
He and colleagues have proposed [a method for gathering data from millions of smartphone cameras](https://arxiv.org/abs/2102.03466) – which are sensitive to some subatomic particles – in order to detect instances of electromagnetic interference. That could help us better understand the prevalence and nature of cosmic rays that reach us here on Earth.
|
||||
|
||||
Separately, Michael Aspinall at Lancaster University in the UK and colleagues recently highlighted plans at the Royal Society's Summer Exhibition to build a neutron monitoring device in Great Britain. It would help to plug a gap in our ability to track the neutrons whizzing around us, he argues: "There's less than 50 of these ground-level neutron monitors still operational, none of them are in the UK."
|
||||
|
||||
The monitor would be built in either Scotland or Cornwall and if it detected a dangerous spike in neutron activity in the future, such information could be passed on to the UK Met Office, which might then advise aviation authorities to ground planes or take other precautionary action.
|
||||
|
||||
It's important to put all of this in context. Crucially, it is highly unlikely that cosmic rays are causing significant errors in computer systems on a regular basis. Data centre manager Tony Grayson, of Compass Datacenters in the US, says he has never felt the need to discuss the threat posed by radiation with colleagues in the industry. That's largely because small bit-level errors in data are often inconsequential, or corrected by automated error-checking software.
|
||||
|
||||
Going to great lengths to shield a data centre from cosmic rays, say by lining it with lead, would be eye-wateringly expensive. It's much easier and cheaper to just keep geographically distributed backups of data. If the worst happens, customers can be shifted over to the backup server, says Grayson.
|
||||
|
||||
But for some applications, cosmic rays are taken very seriously. Consider the pile of electronics in a modern plane that connects the pilot's controls to the rudder, for example. Tim Morin, technical fellow at semiconductor firm Microchip, says major aerospace and defence manufacturers use components that are resistant to certain cosmic ray effects. His company is among those that supply these components.
|
||||
|
||||
"It's just immune to single-event upsets caused by neutrons," he says. "We are not affected by that."
|
||||
|
||||
Morin declines to elaborate on exactly the approach his firm took to manufacture computer chips that are untroubled by neutron interference, except to say that it is to do with materials and circuit design.
|
||||
|
||||
Clearly, not every application requires such high-level protection. And it's also not possible to achieve this with every kind of computer memory, Morin adds. But for organisations that put planes and satellites above our heads, it is obviously an important consideration.
|
||||
|
||||
The technology upon which practically all of us now depend has varying levels of risk associated with it. But it's important to note that, as the transistors in computer chips get smaller in newer, more advanced semiconductors, [they get more susceptible to electromagnetic interference](https://sst.semiconductor-digest.com/2017/12/how-to-tame-the-electromagnetic-interference-in-the-fabs-and-beyond/), too.
|
||||
|
||||
"The charge needed to reverse a state is smaller," explains Rech. If only a very tiny charge is required, the chances of a subatomic particle inducing such a charge go up, in principle. Plus, there are growing numbers of computer chips out there, in devices from phones to washing machines. "The overall area that can be corrupted is actually significantly increasing," says Rech. The subatomic rain falling down on our devices has ever more targets to strike.
|
||||
|
||||
The consequences of that could conceivably be dire but, so far, it's hard to known to what extent this could harm us or the systems that power the modern world. For Marie Moe, the strange behaviour of her pacemaker on that flight to Amsterdam six years ago led to a heightened knowledge of the device that is so important for the healthy functioning of her heart. It even [aided her research](https://www.darkreading.com/risk/hacking-yourself-marie-moe-and-pacemaker-security/d/d-id/1338960) into the cyber-security vulnerabilities of pacemakers.
|
||||
|
||||
If a stray neutron really was behind it all, that's quite a chain reaction. So at least there can be positive outcomes from bit flips, as well as scary ones.
|
||||
|
||||
"I'm really happy, actually," she says, "that this happened to me."
|
||||
|
||||
--
|
||||
@@ -0,0 +1,114 @@
|
||||
# Partial Cloudflare outage on October 25, 2022
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: John Graham-Cumming — Cloudflare
|
||||
- **链接**: https://blog.cloudflare.com/partial-cloudflare-outage-on-october-25-2022/
|
||||
|
||||
## 简介
|
||||
|
||||
Cloudflare shares details about their 87-minute partial outage this past Tuesday.
|
||||
|
||||
## 正文
|
||||
|
||||
# Partial Cloudflare outage on October 25, 2022
|
||||
|
||||
This post is also available in [Deutsch](https://blog.cloudflare.com/de-de/partial-cloudflare-outage-on-october-25-2022/), [Español](https://blog.cloudflare.com/es-es/partial-cloudflare-outage-on-october-25-2022/), [Français](https://blog.cloudflare.com/fr-fr/partial-cloudflare-outage-on-october-25-2022/), [日本語](https://blog.cloudflare.com/ja-jp/partial-cloudflare-outage-on-october-25-2022/), and [简体中文](https://blog.cloudflare.com/zh-cn/partial-cloudflare-outage-on-october-25-2022/).
|
||||
|
||||

|
||||
|
||||
Today, a change to our Tiered Cache system caused some requests to fail for users with status code 530. The impact lasted for almost six hours in total. We estimate that about 5% of all requests failed at peak. Because of the complexity of our system and a blind spot in our tests, we did not spot this when the change was released to our test environment.
|
||||
|
||||
The failures were caused by side effects of how we handle cacheable requests across locations. At first glance, the errors looked like they were caused by a different system that had started a release some time before. It took our teams a number of tries to identify exactly what was causing the problems. Once identified we expedited a rollback which completed in 87 minutes.
|
||||
|
||||
We’re sorry, and we’re taking steps to make sure this does not happen again.
|
||||
|
||||
### Background
|
||||
|
||||
One of Cloudflare’s products is our Content Delivery Network, or CDN. This is used to cache assets for websites globally. However, a data center is not guaranteed to have an asset cached. It could be new, expired, or has been purged. If that happens, and a user requests that asset, our CDN needs to retrieve a fresh copy from a website’s origin server. But the data center that the user is accessing might still be pretty far away from the origin server. This presents an additional issue for customers: every time an asset is not cached in the data center, we need to retrieve a new copy from the origin server.
|
||||
|
||||
To improve cache hit ratios, we introduced [Tiered Cache](https://blog.cloudflare.com/introducing-smarter-tiered-cache-topology-generation/). With Tiered Cache, we organize our data centers in the CDN into a hierarchy of “lower tiers” which are closer to the end users and “upper tiers” that are closer to the origin. When a cache-miss occurs in a lower tier, the upper tier is checked. If the upper tier has a fresh copy of the asset, we can serve that in response to the request. This improves performance and reduces the amount of times that Cloudflare has to reach out to an origin server to retrieve assets that are not cached in lower tier data centers.
|
||||
|
||||

|
||||
|
||||
### Incident timeline and impact
|
||||
|
||||
At 08:40 UTC, a software release of a CDN component containing a bug began slowly rolling out. The bug was triggered when a user visited a site with either Tiered Cache, Cloudflare Images, or Bandwidth Alliance configured. This bug caused a subset of those customers to return HTTP Status Code 530 — an error. Content that could be served directly from a data center's local cache was unaffected.
|
||||
|
||||
We started an investigation after receiving customer reports of an intermittent increase in 530s after the faulty component was released to a subset of data centers.
|
||||
|
||||
Once the release started rolling out globally to the remaining data centers, a sharp increase in 530s triggered alerts along with more customer reports, and an incident was declared.
|
||||
|
||||

|
||||
|
||||
*Requests resulting in a response with status code 530*
|
||||
|
||||
We confirmed a bad release was responsible by rolling back the release in a data center at 17:03 UTC. After the rollback, we observed a drop in 530 errors. After this confirmation, an accelerated global rollback began and the 530s started to decrease. Impact ended once the release was reverted in all data centers configured as Tiered Cache upper tiers at 18:04 UTC.
|
||||
|
||||
Timeline:
|
||||
|
||||
- 2022-10-25 08:40: The release started to roll out to a small subset of data centers.
|
||||
- 2022-10-25 10:35: An individual customer alert fires, indicating an increase in 500 error codes.
|
||||
- 2022-10-25 11:20: After an investigation, a single small data center is pinpointed as the source of the issue and removed from production while teams investigate the issue there.
|
||||
- 2022-10-25 12:30: Issue begins spreading more broadly as more data centers get the code changes.
|
||||
- 2022-10-25 14:22: 530s errors increase as the release starts to slowly roll out to our largest data centers.
|
||||
- 2022-10-25 14:39: Multiple teams become involved in the investigation as more customers start reporting increases in errors.
|
||||
- 2022-10-25 17:03: CDN Release is rolled back in Atlanta and root cause is confirmed.
|
||||
- 2022-10-25 17:28: Peak impact with approximately 5% of all HTTP requests resulting in an error with status code 530.
|
||||
- 2022-10-25 17:38: An accelerated rollback continues with large data centers acting as Upper tier for many customers.
|
||||
- 2022-10-25 18:04: Rollback is complete in all Upper Tiers.
|
||||
- 2022-10-25 18:30: Rollback is complete.
|
||||
|
||||
During the early phases of the investigation, the indicators were that this was a problem with our internal DNS system that also had a release rolling out at the same time. As the following section shows, that was a side effect rather than the cause of the outage.
|
||||
|
||||
### Adding distributed tracing to Tiered Cache introduced the problem
|
||||
|
||||
In order to help improve our performance, we routinely add monitoring code to various parts of our services. Monitoring code helps by giving us visibility into how various components are performing, allowing us to determine bottlenecks that we can improve on. Our team recently added additional distributed tracing to our Tiered Cache logic. The tiered cache entrypoint code is as follows:
|
||||
|
||||
* Before:
|
||||
|
||||
```
|
||||
function _M.go()
|
||||
-- code to run here
|
||||
end
|
||||
```
|
||||
* After:
|
||||
|
||||
```
|
||||
local trace_fn = require("opentracing").trace_fn
|
||||
local function go()
|
||||
-- code to run here
|
||||
end
|
||||
function _M.go()
|
||||
trace_fn(ngx.ctx, "tiered_cache_rewrite", go)
|
||||
end
|
||||
```
|
||||
The code above wraps the existing go() function with trace_fn() which will call the go() function and then reports its execution time.
|
||||
|
||||
However, the logic that injects a function to the opentracing module clears control headers on every request:
|
||||
|
||||
```
|
||||
require("opentracing").configure_module(conf,
|
||||
-- control header extractor
|
||||
function(ctx)
|
||||
-- Always clear the headers.
|
||||
clear_control_headers()
|
||||
--
|
||||
```
|
||||
Normally, we extract data from these control headers before clearing them as a routine part of how we process requests.
|
||||
|
||||
But internal tiered cache traffic expects the control headers from the lower tier to be passed as-is. The combination of clearing headers and using an upper tier meant that information that might be critical to the routing of the request was not available. In the subset of requests affected, we were missing the hostname to resolve by our internal DNS lookup for origin server IP addresses. As a result, a 530 DNS error was returned to the client.
|
||||
|
||||
### Remediation and follow-up steps
|
||||
|
||||
To prevent this from happening again, in addition to the fixing the bug, we have identified a set of changes that help us detect and prevent issues like this in the future:
|
||||
|
||||
- Include a larger data center that is configured as a Tiered Cache upper tier in an earlier stage in the release plan. This will allow us to notice similar issues more quickly, before a global release.
|
||||
- Expand our acceptance test coverage to include a broader set of configurations, including various Tiered Cache topologies.
|
||||
- Alert more aggressively in situations where we do not have full context on requests, and need the extra host information in the control headers.
|
||||
- Ensure that our system correctly fails fast in an error like this, which would have helped identify the problem during development and test.
|
||||
|
||||
### Conclusion
|
||||
|
||||
We experienced an incident that affected a significant set of customers using Tiered Cache. After identifying the faulty component, we were able to quickly rollback and remediate the issue. We are sorry for any disruption this has caused our customers and end users trying to access services.
|
||||
|
||||
Remediations to prevent such an incident from happening in the future will be put in place as soon as possible.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Ops to Bots — Smartening incident recovery
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Vivek Aggarwal — Razorpay
|
||||
- **链接**: https://engineering.razorpay.com/what-goes-behind-managing-production-alerts-204f186ce865
|
||||
|
||||
## 简介
|
||||
|
||||
In reaction to a major outage, these folks revamped their alerting and incident response systems. Here’s what they changed.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
83
sreweekly/markdown/345/08-give-your-tail-a-nudge.md
Normal file
83
sreweekly/markdown/345/08-give-your-tail-a-nudge.md
Normal file
@@ -0,0 +1,83 @@
|
||||
# Give Your Tail a Nudge
|
||||
|
||||
- **期号**: SRE Weekly Issue #345(2022-10-30)
|
||||
- **作者**: Marc Brooker
|
||||
- **链接**: http://brooker.co.za/blog/2022/10/21/nudge.html
|
||||
|
||||
## 简介
|
||||
|
||||
The author of this post sought to test a simple algorithm from a research paper that purported to reduce tail latency. Yay for independent verfication!
|
||||
|
||||
## 正文
|
||||
|
||||
I am an engineer at Amazon Web Services (AWS) in Seattle, where I work on agentic AI, especially safety and policy for agentic AI. Before that, I worked on EC2, EBS, databases, serverless, and serverless databases.
|
||||
|
||||
All opinions are my own.
|
||||
|
||||
We all care about tail latency (also called *high percentile* latency, also called *those times when your system is weirdly slow*). Simple changes that can bring it down are valuable, especially if they don’t come with difficult tradeoffs. [Nudge: Stochastically Improving upon FCFS](https://arxiv.org/pdf/2106.01492.pdf) presents one such trick. The Nudge paper interests itself in tail latency compared to First Come First Served (FCFS)<sup>[1](http://brooker.co.za#foot1)</sup>, for a good reason:
|
||||
|
||||
While advanced scheduling algorithms are a popular topic in theory papers, it is unequivocal that the most popular scheduling policy used in practice is still First-Come First-Served (FCFS).
|
||||
|
||||
|
||||
This is all true. Lots of proposed mechanisms, pretty much everybody still uses FCFS (except for some systems using LIFO<sup>[2](http://brooker.co.za#foot2)</sup>, and things like CPU and IO schedulers which often use more complex heuristics and priority levels<sup>[3](http://brooker.co.za#foot3)</sup>). But this simplicity is good:
|
||||
|
||||
However, there are also theoretical arguments for why one should use FCFS. For one thing, FCFS minimizes the maximum response time across jobs for any finite arrival sequence of jobs.
|
||||
|
||||
|
||||
The paper then goes on to question whether, despite this optimality result, we can do better than FCFS. After all, minimizing the maximum doesn’t mean doing better across the whole tail. They suggest a mechanism that does that, which they call Nudge. Starting with some intuition:
|
||||
|
||||
The intuition behind the Nudge algorithm is that we’d like to basically stick to FCFS, which we know is great for handling the extreme tail (high 𝑡), while at the same time incorporating a little bit of prioritization of small jobs, which we know can be helpful for the mean and lower 𝑡.
|
||||
|
||||
|
||||
And going on to the algorithm itself:
|
||||
|
||||
However, when a “small” job arrives and finds a “large” job immediately ahead of it in the queue, we swap the positions of the small and large job in the queue. The one caveat is that a job which has already swapped is ineligible for further swaps.
|
||||
|
||||
|
||||
Wow, that really is a simple little trick! If you prefer to think visually, here’s Figure 1 from the Nudge paper:
|
||||
|
||||
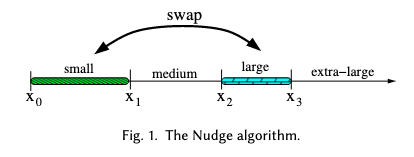
|
||||
|
||||
|
||||
**But does it work?**
|
||||
|
||||
I have no reason to doubt that Nudge works, based on the analysis in the paper, but that analysis is likely out of the reach of most practitioners. More practically, like all closed-form analysis it asks and answers some very specific questions, which isn’t as useful for exploring the effect that applying Nudge may have on our systems. So, like the coward I am, I turn to simulation.
|
||||
|
||||
The simulator ([code here](https://github.com/mbrooker/simulator_example/blob/main/nudge/nudge.py)) follows the [simple simulation](https://brooker.co.za/blog/2022/04/11/simulation.html) approach I like to apply. It considers a system with a queue (using either Nudge or FCFS), a single server, Poisson arrivals, and service times picked from three different Weibull distributions with different means and probabilities. You might call that an M/G/1 system, if you like [Kendall’s Notation](https://en.wikipedia.org/wiki/Kendall%27s_notation).
|
||||
|
||||
What we’re interested in, in this simulation, is the effect across the whole tail, and for different loads on the system. We define load (calling it ⍴ for traditional reasons) in terms of two other numbers: the mean arrival rate λ, and the mean completion rate μ, both in units of jobs/second.
|
||||
|
||||
$$
|
||||
\rho = \frac{\lambda}{\mu}
|
||||
$$
|
||||
Obviously when $\rho > 1$ the queue is filling faster than it’s draining and [you’re headed for catastrophe more quickly than you think](https://brooker.co.za/blog/2021/08/05/utilization.html). Considering the effect of queue tweaks for different loads seems interesting, because we’d expect them to have very little effect at low load (the queue is almost always empty), and want to make sure they don’t wreck things at high load.
|
||||
|
||||
Here are the results, as a cumulative latency distribution, comparing FCFS with Nudge for three different values of ⍴:
|
||||
|
||||
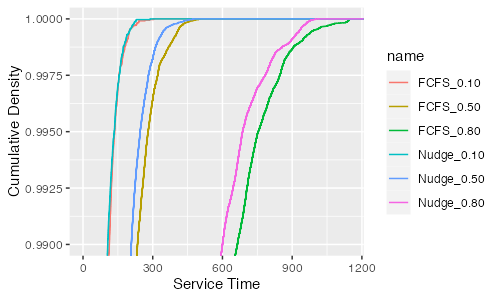
|
||||
|
||||
|
||||
That’s super encouraging, and suggests that Nudge works very well across the whole tail in this model.
|
||||
|
||||
**More questions to answer**
|
||||
|
||||
There are a lot more interesting questions to explore before putting Nudge into production. The most interesting one seems to be whether it works with our real-world tail latency distributions, which can have somewhat heavy tails. The Nudge paper says:
|
||||
|
||||
In this paper, we choose to focus on the case of light-tailed job size distributions.
|
||||
|
||||
|
||||
but defends this by saying (correctly) that most real-world systems truncate the tails of their job size distributions (with mechanisms like timeouts and limits):
|
||||
|
||||
Finally, while heavy-tailed job size distributions are certainly prevalent in empirical workloads …, in practice, these heavy-tailed workloads are often truncated, which immediately makes them light-tailed. Such truncation can happen because there is a limit imposed on how long jobs are allowed to run.
|
||||
|
||||
|
||||
Which is almost ubiquitous in practice. It’s very hard indeed to run a stable distributed system where job sizes are allowed to have unbounded cost<sup>[4](http://brooker.co.za#foot4)</sup>. Whether our tails are *bounded enough* for Nudge to behave well is a good question, which we can also explore with simulation.
|
||||
|
||||
The other important question, of course, is how it generalizes to larger systems with multiple layers of queues, multiple servers, and more exciting arrival time distributions. Again, we can explore all those questions through simulation (you might be able to explore them in closed-form too, but that’s beyond my current skills).
|
||||
|
||||
**Summary**
|
||||
Overall, Nudge is a very cool result. In its effectiveness and simplicity it reminds me of [the power of two random choices](https://brooker.co.za/blog/2012/01/17/two-random.html) and [Always Go Left](https://dl.acm.org/doi/10.1145/792538.792546). It may be somewhat difficult to implement, especially if the additional synchronization required to do the compare-and-swap dance is a big issue.
|
||||
|
||||
**Footnotes**
|
||||
|
||||
[Linux’s elevator](https://github.com/torvalds/linux/blob/master/block/elevator.c) could bring amazing performance gains by reducing head movement in hard drives. Most folks these days are just firing their IOs at an SSD (with a*noop* scheduler).
|
||||
Reference in New Issue
Block a user