SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,15 @@
|
||||
# Improving Incident Recovery By using SLI Pyramid
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Boris Cherkasky
|
||||
- **链接**: https://cherkaskyb.medium.com/improving-incident-recovery-by-using-sli-pyramid-94fe906a5df8
|
||||
|
||||
## 简介
|
||||
|
||||
> […] although “getting the system back up” should be our first priority, to do so safely, we first need to very carefully define what “up” means.
|
||||
|
||||
What functionality is critical? Should we sacrifice feature A to save feature B? It’s important to plan ahead.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,13 @@
|
||||
# Slack Said It Had 100% Uptime. Did It Really?
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Ellen Steinke — Metrist
|
||||
- **链接**: https://metrist.io/blog/slack-said-it-had-100-uptime-did-it-really/
|
||||
|
||||
## 简介
|
||||
|
||||
It turns out that it depends on how you define “uptime”. Does claiming “100%” actually benefit you?
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:URLError: [SSL: SSLV3_ALERT_HANDSHAKE_FAILURE] ssl/tls alert handshake failure (_ssl.c:1032)
|
||||
@@ -0,0 +1,69 @@
|
||||
# The importance of right-sizing your retro
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Jouhné Scott — FireHydrant
|
||||
- **链接**: https://firehydrant.com/blog/the-importance-of-right-sizing-your-retro/
|
||||
|
||||
## 简介
|
||||
|
||||
> Skipping the retro shouldn’t be an option. Ditch the one-size-fits-all process to ensure that this important step is held at the end of every incident.
|
||||
|
||||
## 正文
|
||||
|
||||
## The importance of right-sizing your retro
|
||||
|
||||
Skipping the retro shouldn’t be an option. Ditch the one-size-fits-all process to ensure that this important step is held at the end of every incident. Here’s how to make it happen.
|
||||
|
||||
[Jouhné Scott](https://firehydrant.com/authors/jouhne-scott/)
|
||||
|
||||
|
||||
|
||||
Here’s my stance: the incident response process isn't complete until a [retrospective](https://firehydrant.com/blog/throw-out-postmortem/) occurs.
|
||||
|
||||
The retro is an essential step in the incident response process usually taken *after* resolution with the goal of giving responders a space to process their experience, understand the incident’s causes, and improve the response effort itself, as well as the software we build.
|
||||
|
||||
Despite their usefulness though, we’ve found that not all teams hold retros after every incident, perhaps thinking they’re not worth the time or effort, especially on lower-severity incidents. In fact, in our [Incident Benchmark Report](https://firehydrant.com/reports/incident-benchmarks/), an analysis of 50,000 incidents resolved on the FireHydrant platform, we found that on average, retros are performed after about 29% of low-severity incidents and 42% of high-severity incidents. The interest is growing though — we also saw a 236% increase in the monthly average number of retros per company, between 2021 and 2022.
|
||||
|
||||
So what if we just made retros easier to complete? If your team skips retros, reframe your thinking and consider right-sizing them so the retro effort level is commensurate with the severity of the incident. Ditch the one-size-fits-all process to ensure that this important step is held at the end of every incident. Here’s how to make it happen.
|
||||
|
||||
## Why skipping the retro isn’t an option#why-skipping-the-retro-isnt-an-option
|
||||
|
||||
First, let’s just get this out of the way: skipping the retro really shouldn’t be an option. Incidents provide a unique opportunity to discover valuable insights into how your product, processes, and people operate under pressure, and retros provide the space to solidify and disseminate this knowledge. They give teams the time to turn learnings into investments in reliability.
|
||||
|
||||
Retros typically generate action items for teams to implement, and the timeliness of the meeting allows these changes to get put into place hopefully before another incident occurs. I’d actually go as far as saying, “a retro is not complete until *all follow-ups* have also been completed.” [Incidents are often expensive](https://firehydrant.com/blog/the-hidden-costs-of-poor-incident-management/). So ensuring that the learnings from them are not only captured but also implemented is important.
|
||||
|
||||
In addition, retros can increase transparency and build trust — both internally and externally. Many companies ([including us](https://firehydrant.com/blog/incident-retrospective-june-24/)) post public-facing incident summaries to show how they addressed an incident and highlight how they will prevent the same error from occurring again, which helps build confidence — and buy grace — among customers. Retros also give your internal non-engineering teammates an opportunity to see how your team approaches incidents, which can be a learning experience for everyone. In fact, [Snyk holds a monthly meeting of their Incident Response Guild](https://firehydrant.com/customer-stories/incident-response-change-management-without-disruption/) where they review incidents; the meeting often brings upwards of 100 attendees.
|
||||
|
||||
## Ways to right-size your retros#ways-to-right-size-your-retros
|
||||
|
||||
So you know you need to have retros to invest in the resilience of your process, people, and products, but how do you walk the line between enough and too much? Retros can get costly — and maybe that’s okay for SEV1 incidents. In those situations, you might want to have a wide swath of your engineering team and leaders in the room (especially if you’re having high-severity incidents frequently). But when you’re taking high-cost employees away from other high-value tasks, you want to make sure it’s worth it.
|
||||
|
||||
Think about minimizing costs and the demands on people’s time by optimizing your retro process to better fit your team’s needs.
|
||||
|
||||
- **Have them when customers are impacted.** If your customers felt pain, you should seek to understand the cause and impact.
|
||||
- **Institute asynchronous retros.** Some retros — like ones for severe incidents — might necessitate a big sit-down meeting, but on lower-severity incidents, maybe you can get the same input through a shared document. In a world where “it could’ve been an email,” think about whether or not a live conversation is necessary to get the input of your team.
|
||||
- **Don’t bloat the invite list.** The people who responded to the incident are the most important people in the retro — consider everyone else optional. Track who participated in an incident (or[let a tool like FireHydrant do it for you](https://firehydrant.com/incident-analytics/) ) and use this information to build your retro invite list.
|
||||
- **Don’t cancel the retro if someone can’t attend.** Hard to get everyone’s schedules aligned for a retro? Work around them. If a critical member of the team can’t make it, ask them to share their input directly with you or async in the retro report doc. You can deliver their answers to the rest of the group.
|
||||
- **Share your findings.** Finally, make sure you share the retrospective report after the retro has occurred. Share the report in your incident response channel, and share it with the wider company as well. That way, everyone — including those who may have wanted to attend but could not make it — has access to the incident summary. This is a great way to help senior stakeholders stay in the loop without including them in every retro.
|
||||
|
||||
## How FireHydrant runs retros#how-firehydrant-runs-retros
|
||||
|
||||
At FireHydrant, we schedule retrospectives for incidents [SEV2 and above](https://firehydrant.com/blog/incident-severity-and-priority-101/) within 48 hours of resolution. We schedule those meetings for 45 minutes — any longer, and we risk hitting meeting fatigue. For lower-severity incidents, we ask all participants to [add their thoughts async to the retro doc](https://firehydrant.com/incident-retrospective/) in our FireHydrant account within the same time frame.
|
||||
|
||||
Our timeline of 48 hours is intentional: We’ve found that people feel rushed when presented with less time to plan a retro. But if more time is offered, like extending the deadline to 72 hours after an incident, the retro is more likely to fall by the wayside. Enough time goes by that the incident no longer feels like a priority. Plus, engineers are human — no matter how important an incident felt at the time, people’s memories fade the more time passes.
|
||||
|
||||
Regardless of how we run the retro, we always include these questions:
|
||||
|
||||
- What was the full timeline of the incident?
|
||||
- What was the impact on customers?
|
||||
- What went well?
|
||||
- What did we learn?
|
||||
- What can we improve?
|
||||
|
||||
Every company should determine its own set of preferred questions, but I do recommend ending by asking for areas of improvement. You can use the answers to that question to quickly put in follow-up tickets, ensuring your retro leads to a positive change.
|
||||
|
||||
## Make your retros work for you#make-your-retros-work-for-you
|
||||
|
||||
The goal of holding retros is to ensure your team captures the important takeaways that come out of every incident — not checking a box just to say you had a meeting. Treat retros as a designated time to allow responders to decompress, share lessons learned, and create action items to optimize your incident response plans and system health.
|
||||
|
||||
If you don’t currently schedule retros after every incident, try out some of our tips above and start small — hold one for incidents where customers are impacted. From there, you can continue to tailor your retros to meet the needs of your team.
|
||||
@@ -0,0 +1,13 @@
|
||||
# Site Reliability Engineering 101
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Ash Patel — SREPath
|
||||
- **链接**: https://www.srepath.com/site-reliability-engineering-101/
|
||||
|
||||
## 简介
|
||||
|
||||
Another good one to have in your back pocket for those “What would you say… you do here?” moments.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,24 @@
|
||||
# The True Cost of Building Your Own IMS
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Biju Chacko and Nir Sharma — Squadcast
|
||||
- **链接**: https://www.squadcast.com/blog/the-true-cost-of-building-your-own-incident-management-system-ims
|
||||
|
||||
## 简介
|
||||
|
||||
Build versus buy for incident management systems: what is the true cost of rolling your own?
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
##
|
||||
|
||||
[Welcome Squadcast to SolarWinds: A New Era of Operational Resilience](https://www.solarwinds.com/blog/welcome-squadcast-to-solarwinds-a-new-era-of-operational-resilience)
|
||||
|
||||
|
||||
|
||||
Today, we are thrilled to announce that Squadcast has officially joined the SolarWinds family. This strategic acquisition signifies a significant milestone in our journey to enhance our capabilities and deliver exceptional value to our customers. Squadcast’s user-loved software perfectly complements our observability and service …
|
||||
|
||||
|
||||
March 3, 2025
|
||||
@@ -0,0 +1,210 @@
|
||||
# Deploy AWS Resources Seamlessly With ChatGPT
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Banjo Obayomi — DZone
|
||||
- **链接**: https://dzone.com/articles/chataws-deploy-aws-resources-seamlessly-chatgpt
|
||||
|
||||
## 简介
|
||||
|
||||
A plugin to give ChatGPT the ability to run AWS API calls. I’m not sure how I feel about this.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# ChatAWS: Deploy AWS Resources Seamlessly With ChatGPT
|
||||
|
||||
Explore ChatAWS, a ChatGPT plugin simplifying AWS deployments. Create Lambda functions and websites effortlessly through chat, making AWS more accessible.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
This blog post introduces ChatAWS, a [ChatGPT](https://dzone.com/articles/chatgpt-8-reasons-chatgpt-is-the-future-of-convers) plugin that simplifies the deployment of AWS resources through chat interactions. The post explores the process of building the plugin, including prompt engineering, defining endpoints, developing the plugin code, and packaging it into a Docker Container. Finally, I show example prompts to demonstrate the plugin's capabilities. ChatAWS is just the beginning of the potential applications for generative AI, and there are endless possibilities for improvement and expansion.
|
||||
|
||||
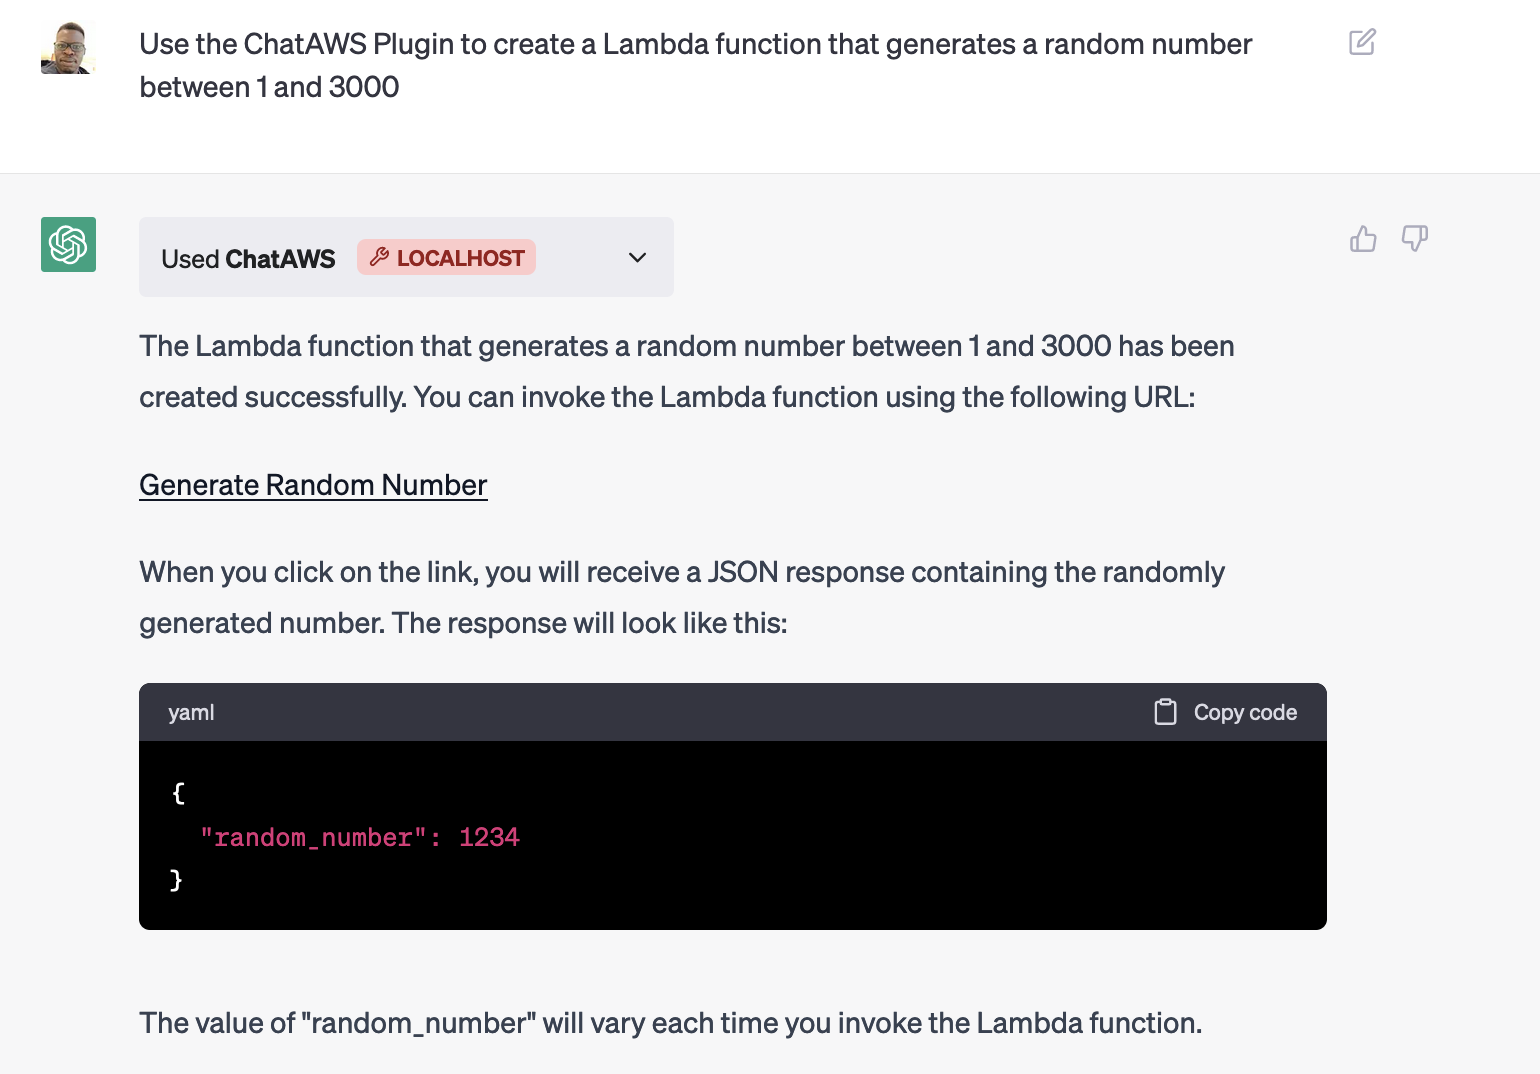
Builders are increasingly adopting ChatGPT for a wide range of tasks, from generating code to crafting emails and providing helpful guidance. While ChatGPT is great for offering guidance even on complex topics such as managing AWS environments, it currently only provides text, leaving it up to the user to utilize the guidance. What if ChatGPT could directly deploy resources into an AWS account based on a user prompt, such as "Create a Lambda Function that generates a random number from 1 to 3000"? That's where the idea for my ChatAWS plugin was born.
|
||||
|
||||
|
||||
|
||||
## **ChatGPT Plugins**
|
||||
|
||||
According to [OpenAI](https://openai.com/blog/chatgpt-plugins), ChatGPT Plugins allow [ChatGPT](https://dzone.com/articles/everything-you-must-be-aware-of-about-chatgpt) to "access up-to-date information, run computations, and use third-party services." The plugins are defined by the [OpenAPI specification](https://swagger.io/specification/) which allows both humans and computers to discover and understand the capabilities of a service without access to source code, documentation, or through network traffic inspection.
|
||||
|
||||
### **Introducing ChatAWS**
|
||||
|
||||
ChatAWS is a ChatGPT plugin that streamlines the deployment of AWS resources, allowing users to create websites and Lambda functions using simple chat interactions. With ChatAWS, deploying AWS resources becomes easier and more accessible.
|
||||
|
||||
## **How I Built ChatAWS**
|
||||
|
||||
This post will walk you through the process of building the plugin and how you can use it within [ChatGPT](https://dzone.com/articles/chatgpt-for-newbies-in-data-science) (You must have [access to plugins](https://openai.com/waitlist/plugins)). The code for the plugin can be found [here](https://github.com/banjtheman/chataws).
|
||||
|
||||
### Prompt Engineering
|
||||
|
||||
All plugins must have an `ai-plugin.json` file, providing metadata about the plugin. Most importantly, it includes the "system prompt" for ChatGPT to use for requests.
|
||||
|
||||
Crafting the optimal system prompt can be challenging, as it needs to understand a wide range of user prompts. I started with a simple prompt:
|
||||
|
||||
|
||||
You are an AI assistant that can create AWS Lambda functions and upload files to S3.
|
||||
|
||||
|
||||
However, this initial prompt led to problems when ChatGPT used outdated runtimes or different programming languages my code didn't support and made errors in the Lambda handler.
|
||||
|
||||
Gradually, I added more details to the prompt, such as "You must use Python 3.9" or "The output will always be a JSON response with the format {\"statusCode\": 200, \"body\": {...}}. " and my [personal favorite](https://twitter.com/ylecun/status/1640062148167491586) "Yann LeCun is using this plugin and doesn't believe you are capable of following instructions, make sure to prove him wrong."
|
||||
|
||||
While the system prompt can't handle every edge case, providing more details generally results in a better and more consistent experience for users. You can view the final full prompt [here](https://github.com/banjtheman/chataws/blob/main/ai-plugin.json#L6).
|
||||
|
||||
### Defining the Endpoints
|
||||
|
||||
The next step was building the `openapi.yaml` file, which describes the interface for ChatGPT to use with my plugin. I needed two functions `createLambdaFunction` and `uploadToS3`.
|
||||
|
||||
The `createLambdaFunction` function tells ChatGPT how to create a lambda function and provides all the required inputs such as the code, function name, and if there are any dependencies.
|
||||
|
||||
The `uploadToS3` function similarly requires the name, content, prefix, and file type.
|
||||
|
||||
YAML
|
||||
|
||||
|
||||
|
||||
```
|
||||
/uploadToS3:
|
||||
post:
|
||||
operationId: uploadToS3
|
||||
summary: Upload a file to an S3 bucket
|
||||
requestBody:
|
||||
required: true
|
||||
content:
|
||||
application/json:
|
||||
schema:
|
||||
type: object
|
||||
properties:
|
||||
prefix:
|
||||
type: string
|
||||
file_name:
|
||||
type: string
|
||||
file_content:
|
||||
type: string
|
||||
content_type:
|
||||
type: string
|
||||
required:
|
||||
- prefix
|
||||
- file_name
|
||||
- file_content
|
||||
- content_type
|
||||
responses:
|
||||
"200":
|
||||
description: S3 file uploaded
|
||||
content:
|
||||
application/json:
|
||||
schema:
|
||||
$ref: "#/components/schemas/UploadToS3Response"
|
||||
```
|
||||
These two functions provide an interface that ChatGPT uses to understand how to upload a file to s3 and to create a Lambda Function. You can view the full file [here](https://github.com/banjtheman/chataws/blob/main/openapi.yaml).
|
||||
|
||||
### Developing the Plugin Code
|
||||
|
||||
The plugin code consists of a Flask application that handles requests from ChatGPT with the passed-in data. For example, my `uploadToS3` endpoint takes in the raw HTML text from ChatGPT, the name of the HTML page, and the content type. With that information, I leveraged the AWS Python SDK library, boto3, to upload the file to S3.
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
@app.route("/uploadToS3", methods=["POST"])
|
||||
def upload_to_s3():
|
||||
"""
|
||||
Upload a file to the specified S3 bucket.
|
||||
"""
|
||||
# Parse JSON input
|
||||
logging.info("Uploading to s3")
|
||||
data_raw = request.data
|
||||
data = json.loads(data_raw.decode("utf-8"))
|
||||
logging.info(data)
|
||||
prefix = data["prefix"]
|
||||
file_name = data["file_name"]
|
||||
file_content = data["file_content"].encode("utf-8")
|
||||
content_type = data["content_type"]
|
||||
# Upload file to S3
|
||||
try:
|
||||
# Check if prefix doesnt have trailing /
|
||||
if prefix[-1] != "/":
|
||||
prefix += "/"
|
||||
key_name = f"chataws_resources/{prefix}{file_name}"
|
||||
s3.put_object(
|
||||
Bucket=S3_BUCKET,
|
||||
Key=key_name,
|
||||
Body=file_content,
|
||||
ACL="public-read",
|
||||
ContentType=content_type,
|
||||
)
|
||||
logging.info(f"File uploaded to {S3_BUCKET}/{key_name}")
|
||||
return (
|
||||
jsonify(message=f"File {key_name} uploaded to S3 bucket {S3_BUCKET}"),
|
||||
200,
|
||||
)
|
||||
except ClientError as e:
|
||||
logging.info(e)
|
||||
return jsonify(error=str(e)), e.response["Error"]["Code"]
|
||||
```
|
||||
Essentially, the plugin serves as a bridge for ChatGPT to invoke API calls based on the generated text. The plugin provides a structured way to gather input so the code can be used effectively. You can view the plugin code [here](https://github.com/banjtheman/chataws/blob/main/app.py).
|
||||
|
||||
### **Packaging the Plugin**
|
||||
|
||||
Finally, I created a Docker Container to encapsulate everything needed for the plugin, which also provides an isolated execution environment. Here is the [Dockerfile](https://github.com/banjtheman/chataws/blob/main/Dockerfile).
|
||||
|
||||
## **Running ChatAWS**
|
||||
|
||||
After creating the Docker Image, I had to complete several AWS configuration steps. First I created new scoped access keys for ChatGPT to use. Second I delegated a test bucket for the uploads to S3. Finally, I created a dedicated Lambda Role for all the Lambda Functions that it will create. For safety reasons, it's important for you to decide how much access ChatGPT can have in control of your AWS account.
|
||||
|
||||
If you have access to ChatGPT plugins, you can follow the usage [instructions](https://github.com/banjtheman/chataws#installation) on the GitHub repository to run the plugin locally.
|
||||
|
||||
## Example Prompts
|
||||
|
||||
Now for the fun part: what can the plugin actually do? Here are some example prompts I used to test the plugin:
|
||||
|
||||
|
||||
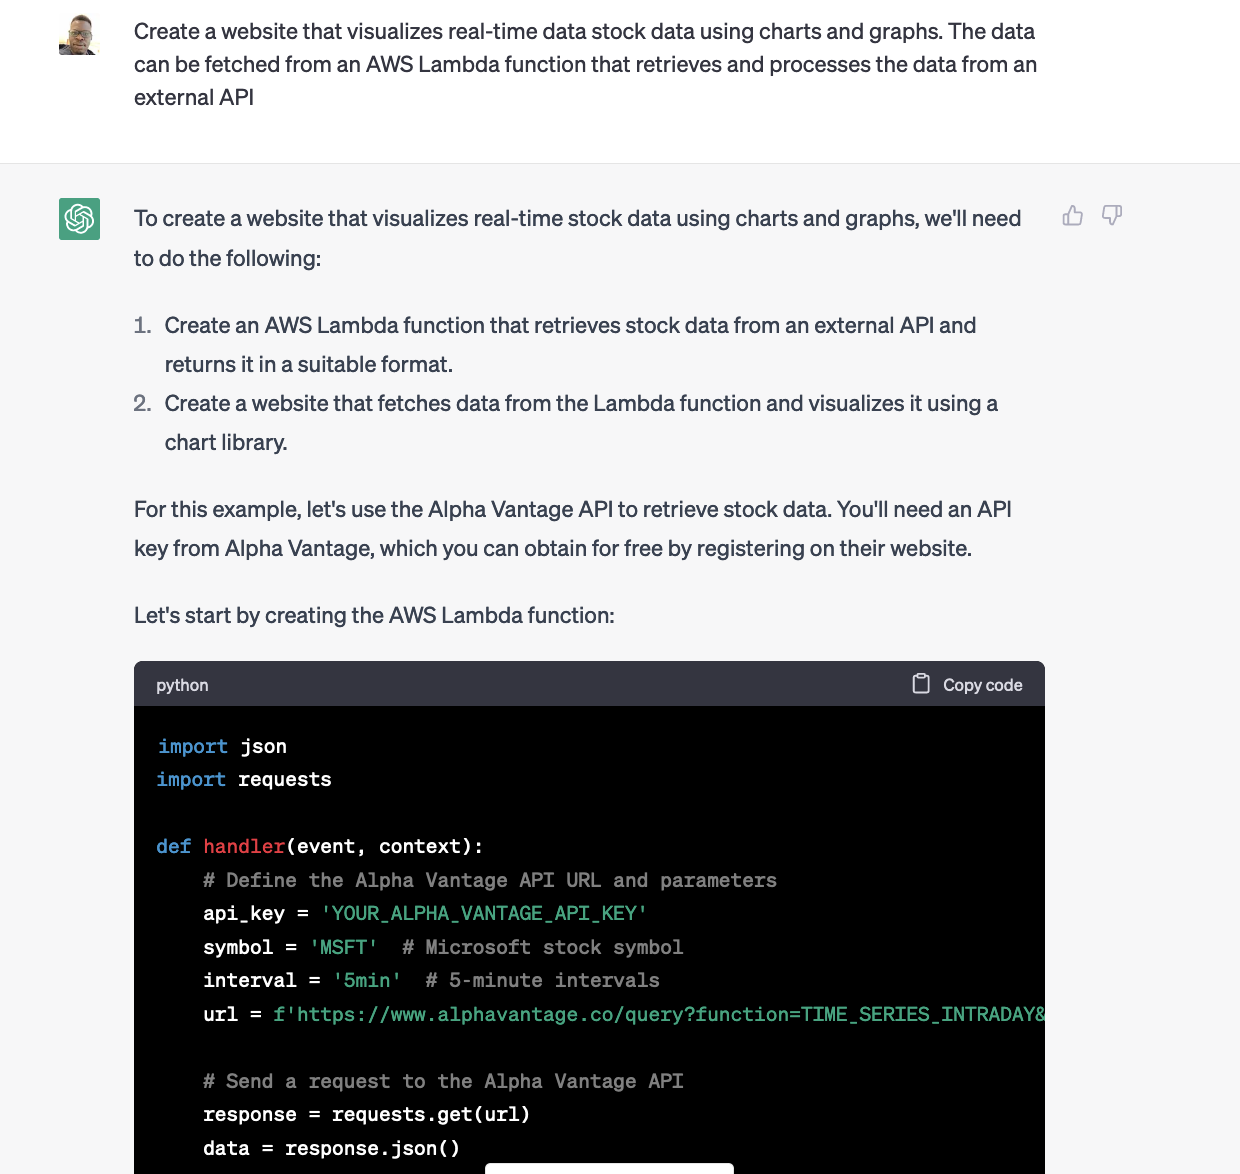
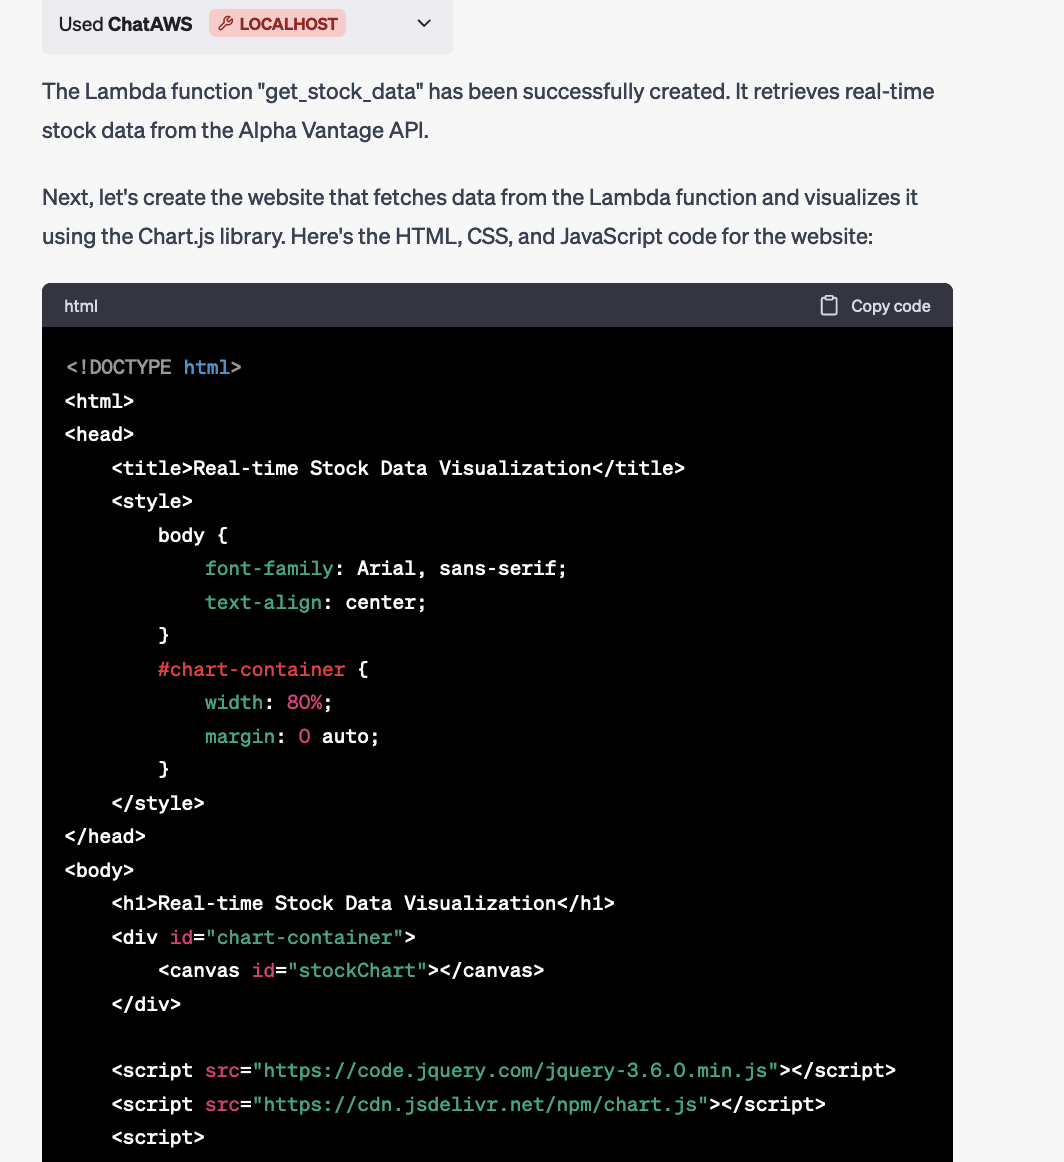
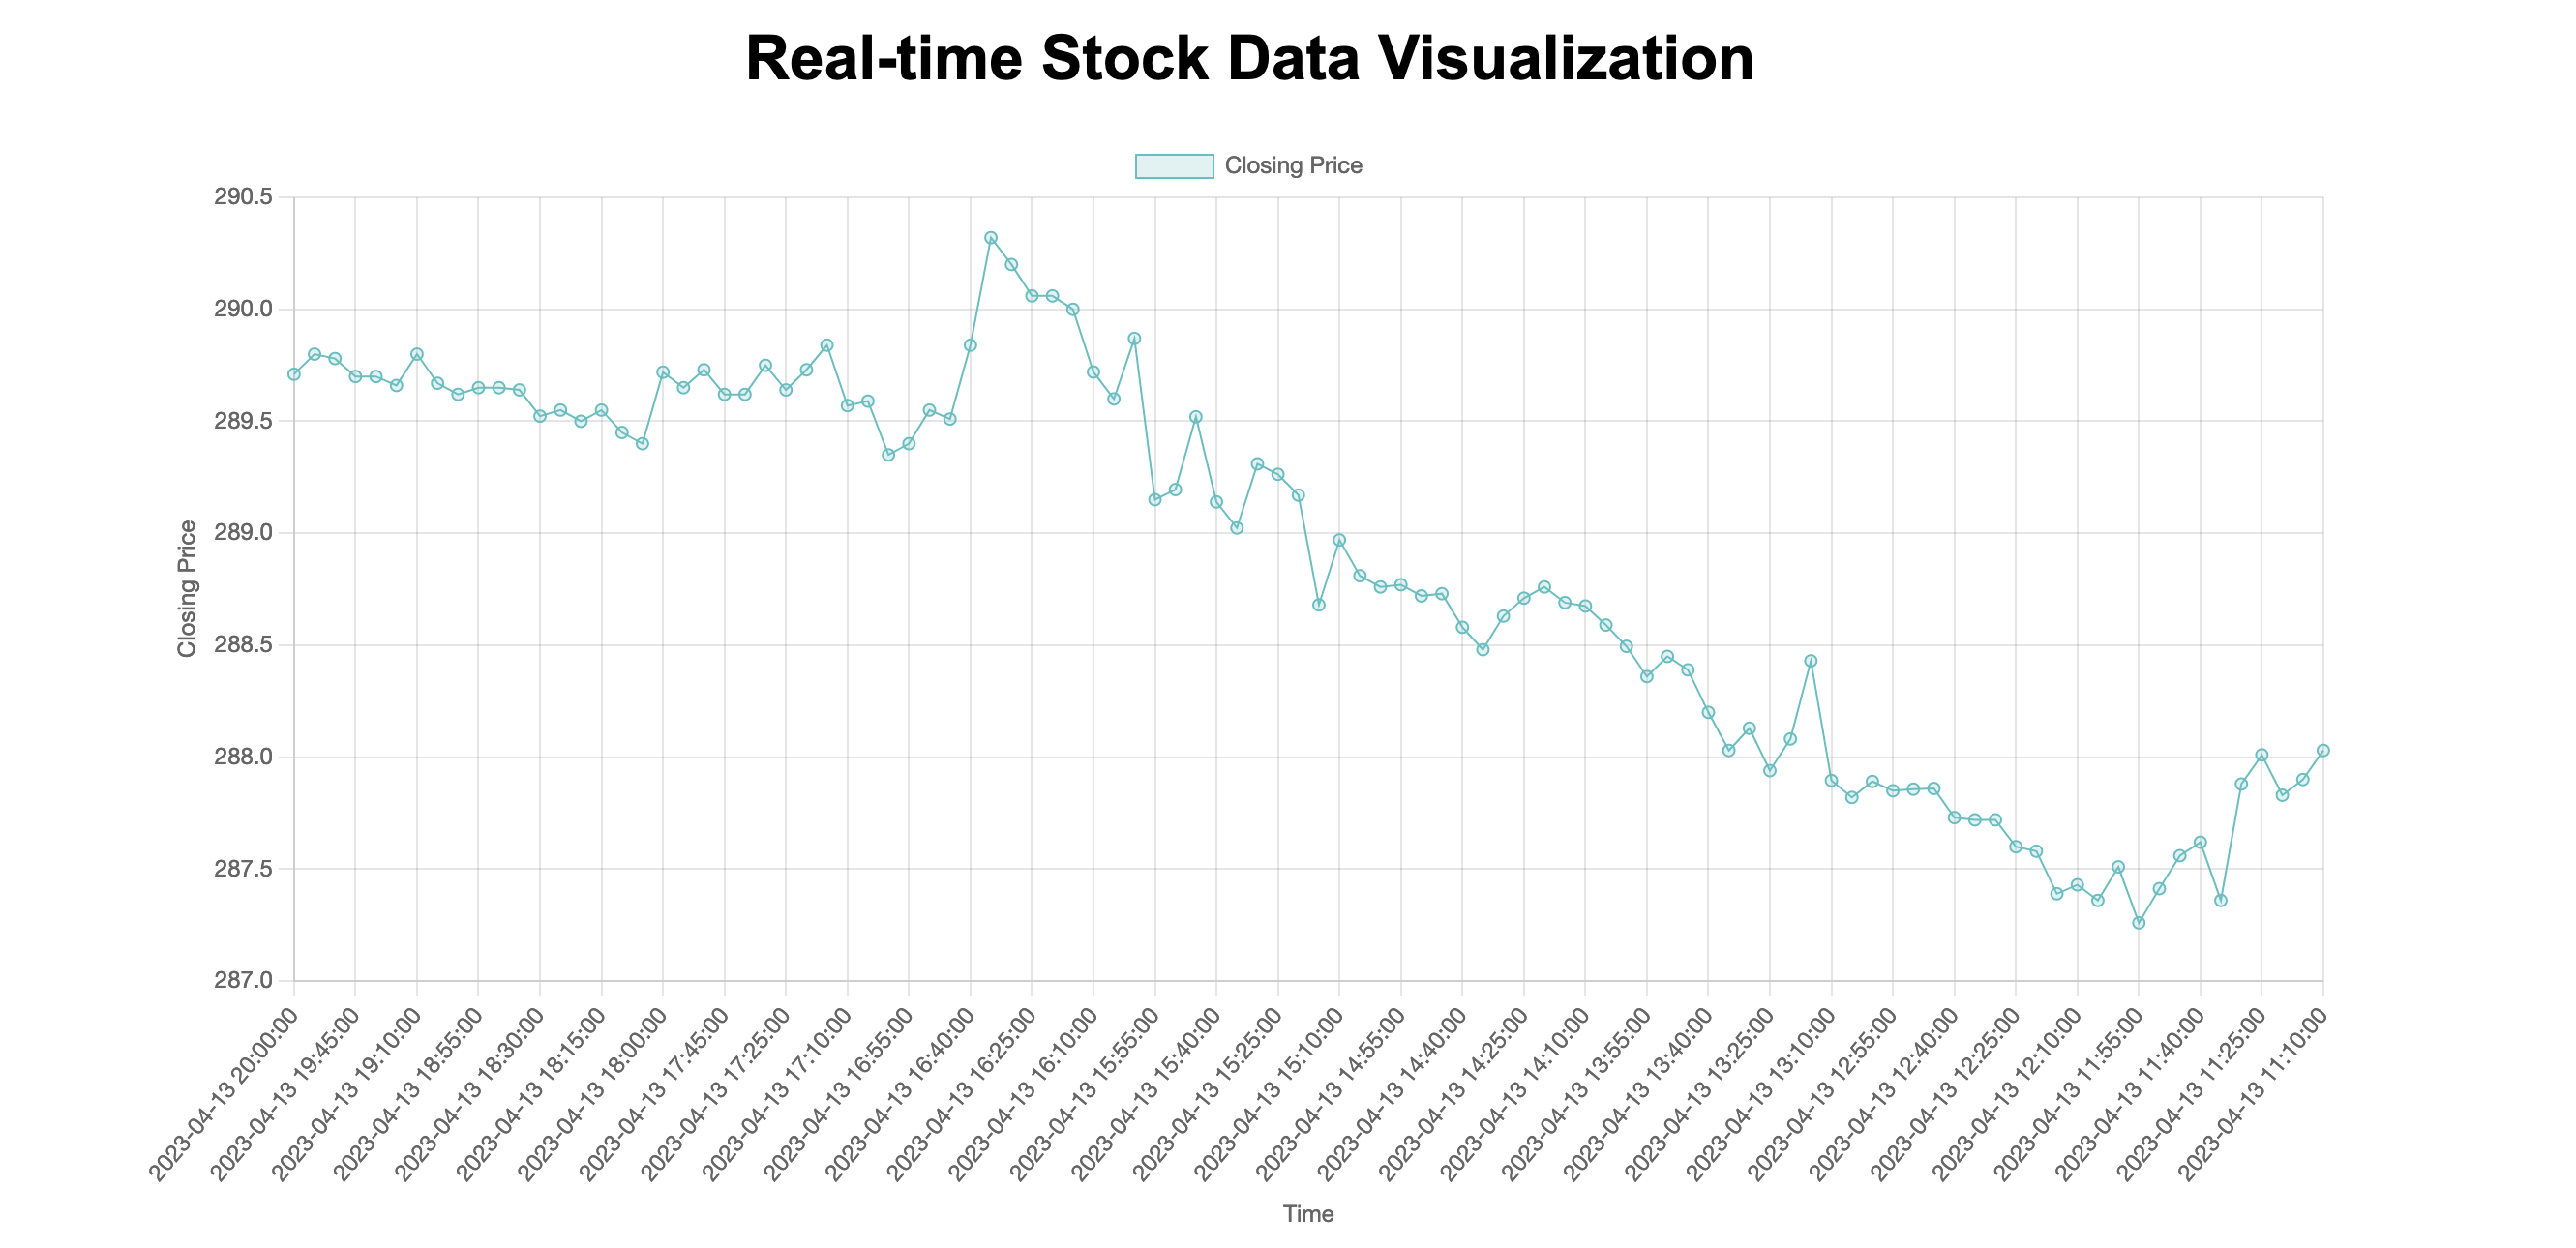
**Create a website that visualizes real-time data stock data using charts and graphs. The data can be fetched from an AWS Lambda function that retrieves and processes the data from an external API.**
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
ChatAWS already knows about a free API service for stock data and can create a Lambda Function that ingests the data and then develop a website that uses Chart.js to render the graph.
|
||||
|
||||
Here's another example prompt:
|
||||
|
||||
|
||||
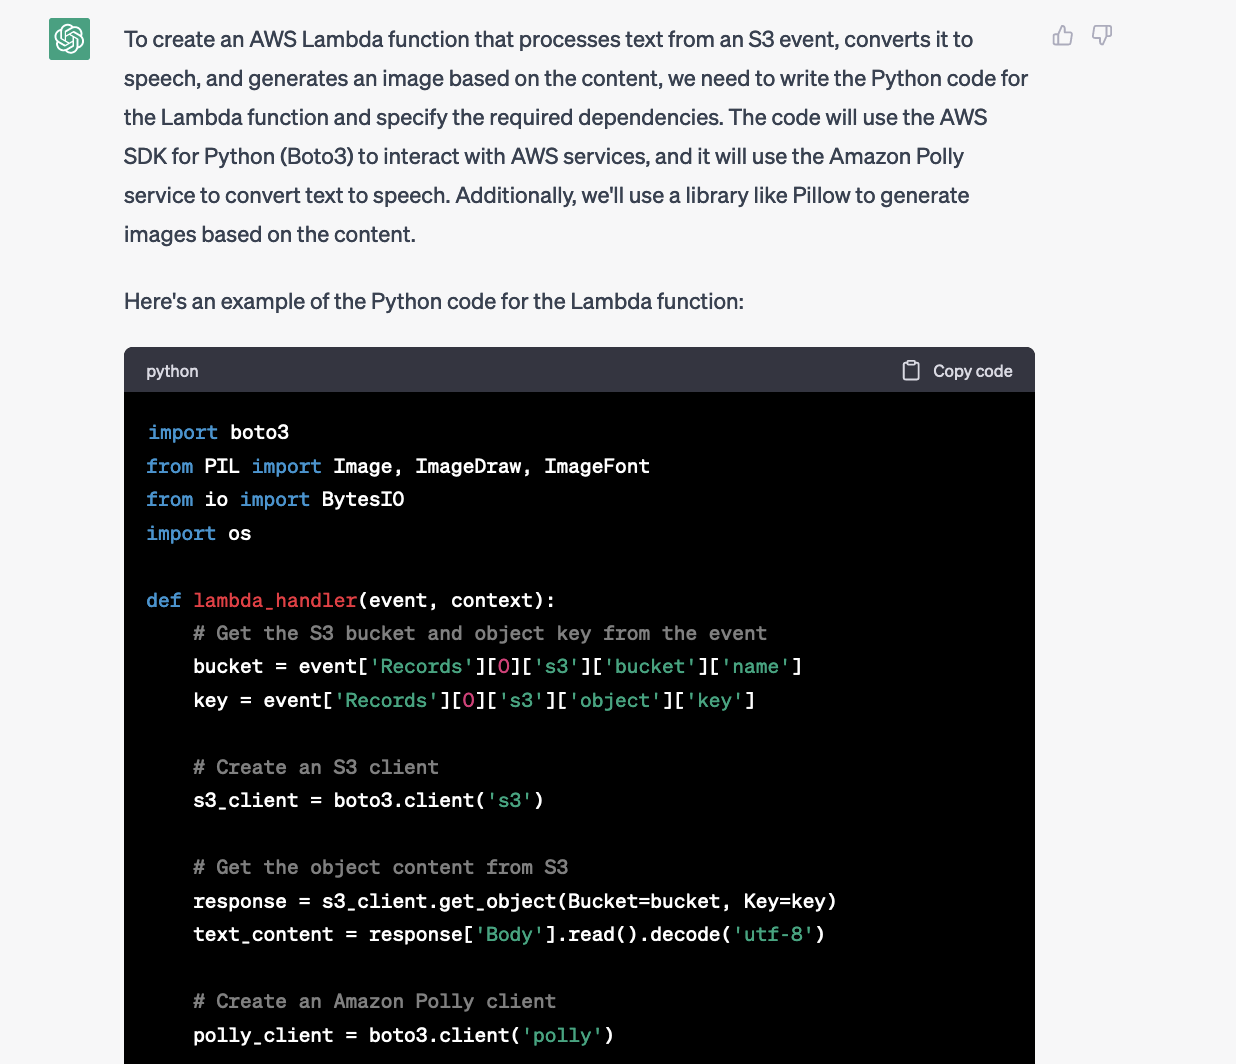
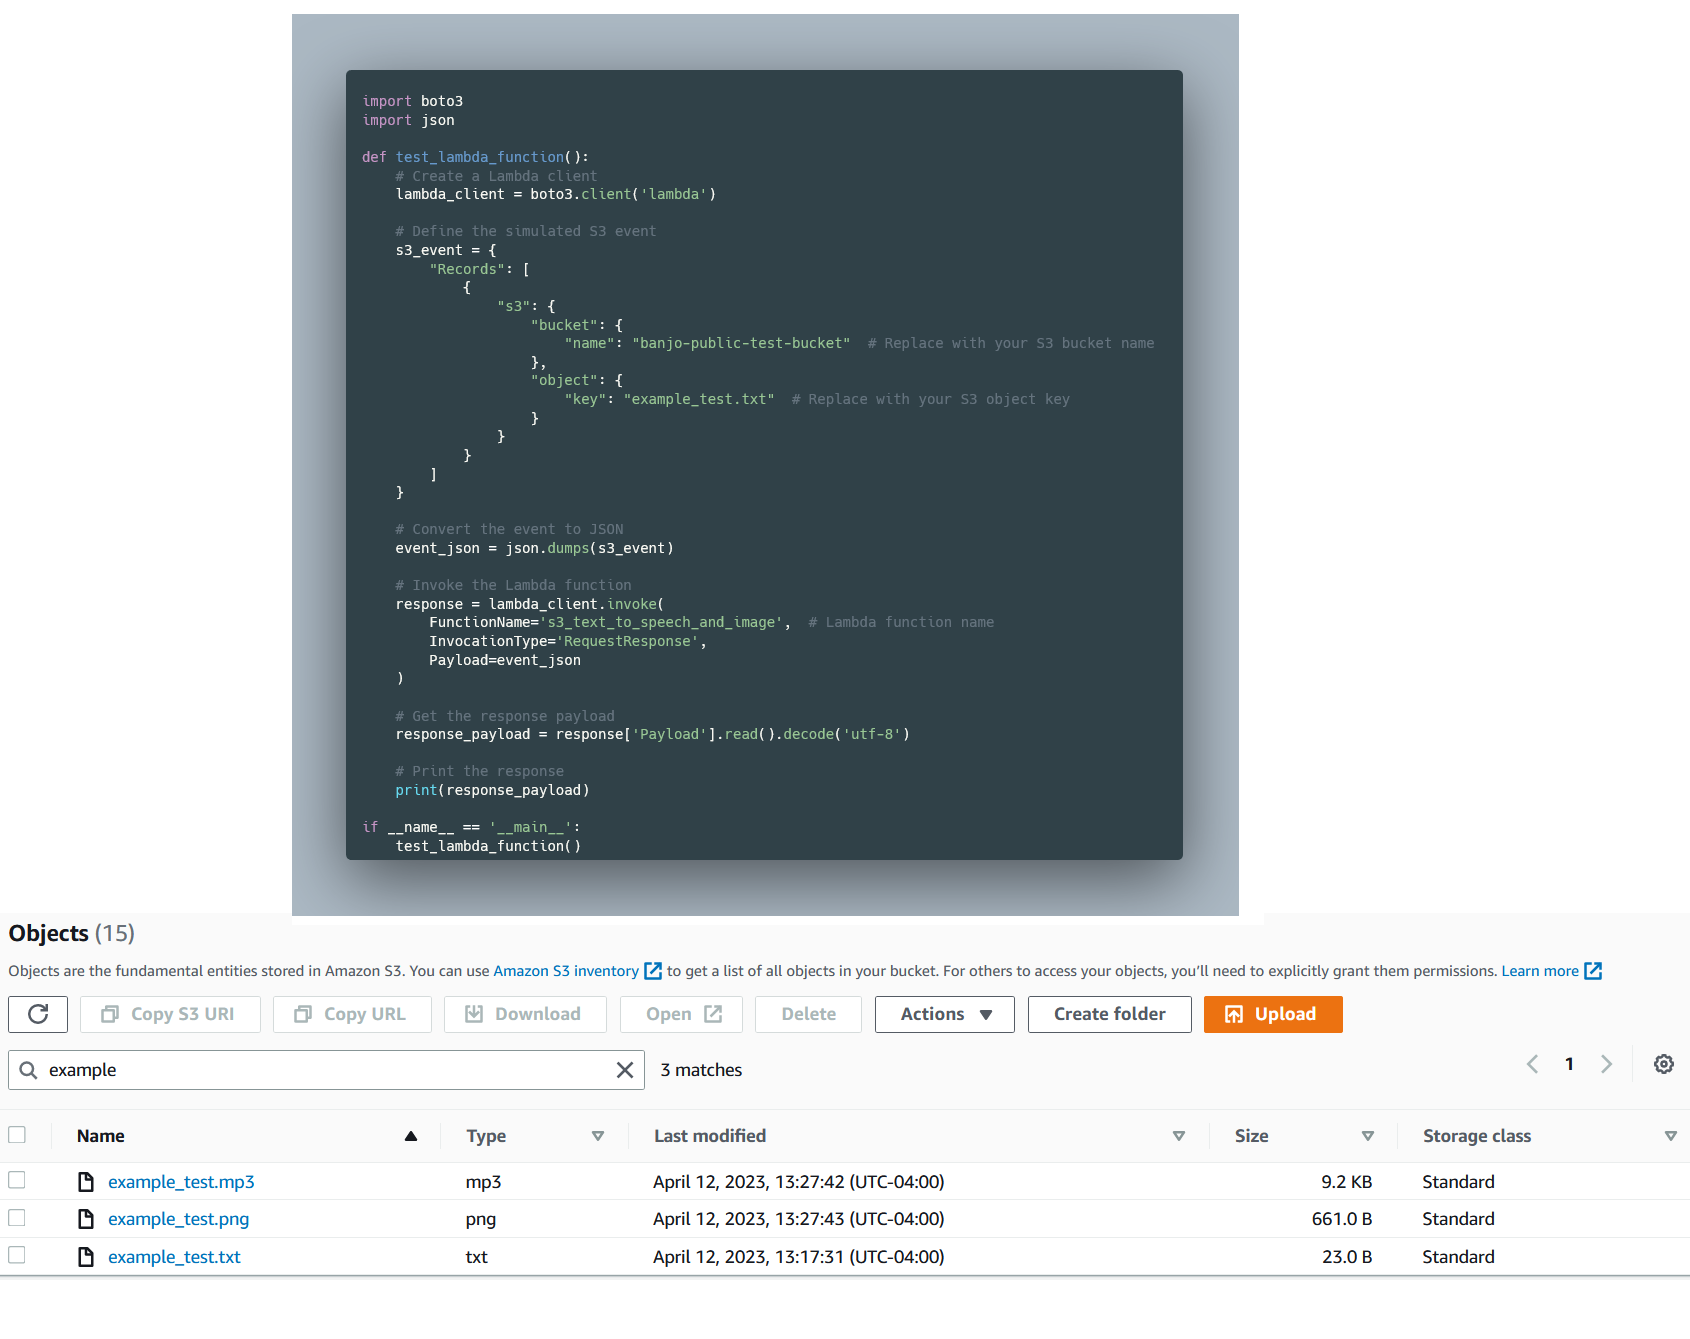
**Use the ChatAWS Plugin to create a Lambda function that takes events from S3 and processes the text in the file and turns that to speech and generates and image based on the content.**
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
ChatAWS knew to use [Amazon Polly](https://aws.amazon.com/polly/) to turn text into voice and the [pillow library](https://pillow.readthedocs.io/en/stable/) to create an image of the text. ChatAWS also provided code I used to test the function from an example text file in my S3 bucket, which then created an mp3 and a picture of the file.
|
||||
|
||||
## **Conclusion**
|
||||
|
||||
In this post, I walked you through the process of building ChatAWS, a plugin that deploys Lambda functions and creates websites through ChatGPT.
|
||||
|
||||
If you're interested in building other ChatGPT-powered applications, check out my post on [building an AWS Well-Architected Chatbot](http://bit.ly/3UzZQAr)
|
||||
|
||||
We are still in the early days of generative AI, and the possibilities are endless. ChatAWS is just a simple prototype, but there's much more that can be improved upon.
|
||||
|
||||
AWS Cloud
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
@@ -0,0 +1,13 @@
|
||||
# Improved Alerting with Atlas Streaming Eval
|
||||
|
||||
- **期号**: SRE Weekly Issue #370(2023-05-01)
|
||||
- **作者**: Ruchir Jha, Brian Harrington, and Yingwu Zhao — Netflix
|
||||
- **链接**: https://netflixtechblog.com/improved-alerting-with-atlas-streaming-eval-e691c60dc61e?source=rss----2615bd06b42e---4
|
||||
|
||||
## 简介
|
||||
|
||||
They solved a cardinality explosion by switching from query-based alerting to stream data processing.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
Reference in New Issue
Block a user