SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,37 @@
|
||||
# Precise Communication Saves Lives
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Dr. Rob Poston
|
||||
- **链接**: https://robpostonblog.wordpress.com/2023/10/12/precise-communication-saves-lives/
|
||||
|
||||
## 简介
|
||||
|
||||
A cardiac surgeon draws lessons from the Tenerife commercial airline disaster and applies them to communication in the operating room.
|
||||
|
||||
## 正文
|
||||
|
||||
On a foggy day on Tenerife island in 1979, jumbo jets from KLM and Pan Am airlines were inadvertently on the same runway waiting to takeoff and return back to their home countries of Amsterdam and USA. The captain of a KLM jet radioed to Air Traffic Control (ATC) “we are now at takeoff”. ATC assumed that ambiguous phrase meant they were at the takeoff position, not that they were actively taking off. ATC responded “OK”. That had a confirmatory effect that was not intended and led KLM to assume it was a clearance for takeoff. After initiating full thrust of the jet, the Pan Am captain called out on the radio at that time that he was blocking the way. It was evident from black box recordings that the KLM captain did not hear this warning due to radio interference caused by both pilots talking at the same time and the message was not repeated. Both jets collided on the runway, **[immediately killing close to 600 people](https://simpleflying.com/tenerife-disaster-45-years-legacy/)**.
|
||||
|
||||
In healthcare, investigations of accidents that harm patients are done internally and in a confidential manner by hospital staff and employed physicians. As a result, they are **[not that effective at improving care](https://www.nejm.org/doi/full/10.1056/NEJMsa1004404)**. In contrast, aviation accidents are never confidential. External federal regulators (NTSB, FAA) respond to the public’s demand to stop another tragedy by performing extensive and rigorous investigations of all accidents that lead to real change. The **[international aviation community concluded](https://www.faasafety.gov/files/gslac/courses/content/232/1081/finaldutchreport.pdf)** that Tenerife happened due to poor communication between pilots and ATC. The following corrective actions were implemented that remain in place today: English is required to be the common working language in a cockpit for all airlines worldwide, a list of standardized phrases was developed with the word “OK” prohibited. The word “takeoff” is now spoken only when permission is given for actual takeoff. Until actual permission is granted for takeoff, pilots and ATC controllers should use the word “departure”. All ATC clearance to aircraft already lined up on the runway for takeoff must include the prefix “hold position”.
|
||||
|
||||
It was also noted that a radio broadcast of a football match was heard in the background in tower transmissions in Tenerife. That was criticized as a possible distraction from the difficult duties of ATC on that day. Aviation regulations now prohibit any activity in the cockpit that is not required for safe operation during the critical moments of an airline flight and the use of cell phones or the internet at any point during a flight (see: cfr § 121.542). Cell phones must be turned off inside ATC operational areas.
|
||||
|
||||
The unmistakable lesson of this tragedy is the mandate for concise, standardized aeronautical language in radio communications on a runway. It is a slipup for a pilot to want to takeoff when there is another jet on the runway. Human slipups have happened since the beginning of our existence. Communication techniques developed after Tenerife help trap inevitable errors so they don’t turn into a catastrophe. Others on the team cross check safety critical decisions and actions of the pilot by being good listeners and asking clarifying questions. Callouts/readbacks (also known as closed loop communication) are used to relay safety critical information. Tools such as checklists limit dependence on a fallible memory. There is clear evidence that this culture change is working. There has not been a fatal crash involving a US airline since 2009.
|
||||
|
||||
Performing anesthesia for a patient undergoing robotic cardiac surgery is at times analogous to navigating a jumbo jet around a crowded, foggy runway. It is well recognized that the induction of anesthesia can upset the equilibrium of patients with cardiac problems. A drop in blood pressure can make a sick heart unhappy. That leads to a further drop in blood pressure, potentially triggering a vicious cycle. Everyone in a cardiac OR has seen this situation play out, which means that we have strong situational awareness and have **[developed many tactics to trap this issue before catastrophe](https://anesth.unboundmedicine.com/anesthesia/view/ClinicalAnesthesiaProcedures/728492/all/Anesthesia_for_Cardiac_Surgery___Induction#:~:text=Induction%20of%20general%20anesthesia%20and,unstable%20patient%20prior%20to%20induction.)**. Robotic surgery injects unfamiliar fog into that story. A double lumen tube is placed in the airway and one of the lungs to be deflated in order to make space within the chest for robotic instruments to navigate. Will the same tactics we use to restore homeostasis with a standard open case work again now? All bets are off. The best hope for safety is to maintain situational awareness and let the collective wisdom of a vigilant team uncover the right corrective responses.
|
||||
|
||||
We maintain situational awareness and create collective wisdom in an OR after clamping one lumen of a double lumen ETT by acting like a pilot poised to takeoff from a runway. The entire team becomes vigilant for three major hazards. First is what happens when deflating the correct lung. It leads to an array of **[subclinical effects on cardiac pathophysiology](https://roboticctsurgery.com/wp-content/uploads/2015/10/robotic-Cardiac-anesthesia-guide.pdf)** that is usually (but not always) well tolerated by the patient. Mild arterial and alveolar hypoxia and hypercarbia trigger pulmonary vasoconstriction. At times, that leads to right ventricular dysfunction and new onset tricuspid regurgitation. Those issues can reduce cardiac output and coronary perfusion, leading to further reductions in pressure and cardiac output and potential for a vicious cycle that might not resolve with reinflating the lung. The team must be ready to go on the heart-lung machine urgently as the only option.
|
||||
|
||||
Second is when the wrong lung was deflated. After the clamp is placed on the ETT, narrow robotic ports are inserted into the chest through the ribs. Similar to laparoscopic surgery, CO2 is then insufflated into the thorax at around 6-8 mmHg pressure in order to create space to operate by pushing the heart and lung away from the relevant anatomy. If the wrong lung in the opposite chest cavity was deflated, then that means both lungs will be compressed at this point. This obviously will not be tolerated. Even worse, the severe decompensation will not be anticipated leading to a less efficient response.
|
||||
|
||||
Third is when the double lumen tube is in an incorrect position so that clamping either lumen of the ETT results in complete cessation of air flow. This problem is usually immediately recognized by monitoring parameters on the ventilator and therefore quickly corrected.
|
||||
|
||||
We avoid error with one lung ventilation using the **[same concise standardized language](https://pubmed.ncbi.nlm.nih.gov/31140044/)** as in the cockpit of an airline. At the clinically appropriate time, the surgeon initiates a callout for isolation of either the left or right lung. The CRNA or anesthesiologist reads back that request and places a clamp on the appropriate lumen of the ETT and callout where the clamp was placed – left or right sided lumen. The surgeon will read back that callout and confirm this was the correct side. It is not effective to say “clamped” or wait to callout that the clamp was placed until confirming an appropriate change in vent parameters. The drapes covering up the ETT are analogous to having to communicate through a radio. The surgeon cannot visually confirm which side of the ETT was clamped. It is the precise moment that the clamp is placed that the surgical team is monitoring for any changes in hemodynamics that would prompt quick action. The quicker the better.
|
||||
|
||||
The point of precise communication is not perfection in how we talk to each other. Perfectionism leads to paralysis. I accept that anyone can and will do it wrong. Just last week I whispered during a robotic coronary bypass case that I had “placed an occlusion device on the coronary”, which was quite different than my routine bark of “LAD occluded!” It is necessary to occlude a coronary artery while the heart is beating in order to sew a bypass graft. Doing this through a small thoracic incision – like the surgical drapes – hinders others seeing what I am doing and being vigilant for potential adverse effects. The surgical tech asked me if calling out things differently meant something. In other words, nonstandard language sent an unintended message. Heart surgery is too hard to put anyone at an unnecessary disadvantage. Working in a noisy operating room creates a signal to noise problem. Nonstandard language makes the search for signals among the noise more difficult, contributing to **[cognitive fatigue](https://karger.com/uin/article/104/3-4/301/305887/Mental-Fatigue-Evaluation-of-Surgical-Teams-during)** and taxing our **[bandwidth for staying vigilant](https://journals.lww.com/annalsofsurgery/citation/2015/03000/attentional_capacity__an_essential_aspect_of.31.aspx#:~:text=Attentional%20capacity%20is%20a%20precious,to%20operate%20safely%20and%20effectively.)**. Being precise allows others to notice imperfection and focus on important things.
|
||||
|
||||
Another lesson from Tenerife is to watch out for two people speaking at the same time. This is a recipe for miscommunication. Throw in radio interference, surgical drapes or small incisions and this ever-present risk can turn lethal. When faced with predictable hazards, high performance teams establish ground rules. Ours is: “If you didn’t hear it repeated back, then you didn’t say it.” This puts full responsibility for communicating safety critical information on the sender (not the receiver) to keep trying until the intended recipient(s) acknowledges hearing it out loud. This rule helps defuse the defensiveness that often follows miscommunication. A common reaction is for the sender to take an impromptu poll of those in the room whether they heard what was said. This frustrating and futile debate is resolved by asking if ‘it was repeated back’. If not, ‘then you didn’t say it.’ Closed loop communication happens when everyone in the room acknowledges critical information verbally out loud and asks clarifying questions if necessary. Closing the loop also benefits the receiver. Remembering new information is enormously affected by what a receiver does immediately after hearing it. A common problem in an OR is being distracted by something which erases what you just heard. Repeating back what you heard improves memory through a **[psychological phenomenon called the “production effect.”](https://www.psychologytoday.com/us/blog/memory-medic/201712/enhance-memory-the-production-effect)** There is a big memory advantage of saying words aloud over simply listening to them silently. Better memory helps to maintain situational awareness, so that everyone in the room is constantly aware of critical events in a procedure and able to project what might happen into the future.
|
||||
|
||||
It took a decade before the safety culture mandated by the Tenerife investigation led to improvements in airline safety. Even if there is some resistance to this change right now, the truth is that this is the right thing to do. At some point the behaviors I am describing will certainly be mandated by regulation; the aviation industry has made it clear that the stakes are too high to accept ineffective communication. But why wait? Our patients want us to enhance their safety today.
|
||||
|
||||
## 3 thoughts on “Precise Communication Saves Lives”
|
||||
@@ -0,0 +1,82 @@
|
||||
# Why create a post mortem document?
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Emily Ruppe — Jeli
|
||||
- **链接**: https://www.jeli.io/blog/why-create-a-post-mortem-document
|
||||
|
||||
## 简介
|
||||
|
||||
Creating an incident write-up is an expensive investment. This article will tell you why it’s worthwhile.
|
||||
|
||||
## 正文
|
||||
|
||||
A **postmortem** (or post-mortem) is a process intended to help you learn from past incidents. It typically involves an analysis or discussion soon after an event has taken place.
|
||||
|
||||
Postmortems typically involve blame-free analysis and discussion soon after an incident or event has taken place. An artifact is produced that includes a detailed description of exactly what went wrong in order to cause the incident, along with a list of steps to take in order to prevent a similar incident from occurring again in the future. An analysis of how your incident response process itself worked during the incident should also be included in the discussion. **The value of postmortems comes from helping institutionalize a culture of continuous improvement.** This way, teams are better prepared when another incident inevitably occurs with mission- or business-critical systems.
|
||||
|
||||
As your systems scale and become more complex, failure is inevitable, assessment and remediation is more involved and time-consuming, and it becomes increasingly painful to repeat recurring mistakes. Not having data when you need it is expensive.
|
||||
|
||||
Streamlining the postmortem process is key to helping your team get the most from their postmortem time investment: spending less time conducting the postmortem, while extracting more effective learnings, is a faster path to increased operational maturity. In fact, the true value of postmortems comes from helping institutionalize a positive culture around frequent and iterative improvement.
|
||||
|
||||
#### **Why Do Postmortems?**
|
||||
|
||||
During [incident response](https://www.pagerduty.com/resources/learn/what-is-incident-response/), the team is 100% focused on restoring service. They should not be wasting time and mental energy thinking about how to do something optimally or performing a deep dive on what caused the incident. Doing this could further delay remediation efforts and convolute the resolution process. That’s why postmortems are essential—they provide a peacetime opportunity to reflect once the issue is no longer impacting users. **The postmortem process drives focus, instills a culture of learning, and identifies opportunities for improvement that otherwise would be lost.**
|
||||
|
||||
Without a postmortem you fail to recognize what you’re doing right, where you could improve, and most importantly, how to avoid making the same mistakes in the future. Writing an effective postmortem allows you to learn quickly from your mistakes and improve your systems and processes. A well-designed, blameless postmortem allows teams to continuously learn, serving as a way to iteratively improve your infrastructure and incident response process. Be sure to write detailed and accurate postmortems in order to get the most benefit out of them.
|
||||
|
||||
**Organizations may refer to the postmortem process in slightly different ways:**
|
||||
|
||||
- Learning Review
|
||||
- After-Action Review
|
||||
- Incident Review
|
||||
- Incident Report
|
||||
- Post-Incident Review
|
||||
- Root Cause Analysis (or RCA)
|
||||
|
||||
#### Streamline the postmortem process
|
||||
|
||||
The specifics around conducting postmortems vary from organization to organization. Regardless of the process, the primary purpose of postmortems should be learning, whether it’s about the systems being managed, the process being followed, or how the organization executes during a crisis. Additional goals, including identification and implementation of system or process improvements, may be realized depending on the process followed.
|
||||
|
||||
In general, an effective postmortem report tells a story. Incident postmortem reports should include the following:
|
||||
|
||||
- **A high-level summary of what happened**
|
||||
Which services and customers were affected? How long and severe was the issue? Who was involved in the response? How did we ultimately fix the problem?
|
||||
- **A root cause analysis**
|
||||
What were the origins of failure? Why do we think this happened?
|
||||
- **Steps taken to diagnose, assess, and resolve**
|
||||
What actions were taken? Which were effective? Which were detrimental?
|
||||
- **A timeline of significant activity**
|
||||
Centralize key activities from chat conversations, incident details, and more.
|
||||
- **Learnings and next steps**
|
||||
What went well? What didn’t go well? How do we prevent this issue from happening again?
|
||||
|
||||
#### The blameless postmortem
|
||||
|
||||
A [blameless post-mortem](https://www.pagerduty.com/blog/blameless-post-mortems-strategies-for-success/) is critical for understanding failures by trying to understand how a mistake was made, instead of who made the mistake. “You ignore the ‘this person did that’ part,” explains PagerDuty Engineering Manager Arup Chakrabarti. “What matters most is the customer impact, and that’s what you focus on.” This is a crucial tool leveraged by many leading organizations such as Etsy, a pioneer for [blameless postmortems](https://codeascraft.com/2012/05/22/blameless-postmortems/), for ensuring postmortems have the right tone, empowering engineers to give truly objective accounts of what happened by eliminating the fear of punishment.
|
||||
|
||||
Some make the argument that the blameless postmortem [might not seem possible](https://techbeacon.com/blameless-postmortems-dont-work-heres-what-does) because humans are hardwired for blame. They advocate “blame-aware” postmortems in which teams acknowledge the instinct to blame, but focus their attention onto actionable takeaways instead.
|
||||
|
||||
Whichever terminology resonates with your team, the key point is that postmortem discussions should be safe spaces in which teams can be completely honest and oriented around improving for the future instead of blaming others for the past.
|
||||
|
||||
#### **When Do You Do a Postmortem?**
|
||||
|
||||
Teams should conduct a postmortem after every major incident (any incident that is a Sev-2 or Sev-1). This includes any time incident response is triggered–even if it is later discovered that severity was actually lower, it was a false alarm, or it quickly recovered without intervention. A postmortem should not be neglected in these cases because it is still an opportunity to review what did and did not work well in the incident response process. If the incident should not have triggered incident response, it is worthwhile understanding why it did so monitoring can be tuned to avoid unnecessarily triggering incident response in the future. Doing this analysis and follow-up action will help prevent alert fatigue going forward.
|
||||
|
||||
Postmortems are done shortly after the incident is resolved, while the context is still fresh for all responders. Just as resolving a major incident becomes top priority when it occurs, completing the postmortem is prioritized over planned work. Completing the postmortem is the final step of your incident response process. Delaying the postmortem delays key learning that will prevent the incident from recurring.
|
||||
|
||||
#### **Who Is Responsible for the Postmortem?**
|
||||
|
||||
At the end of a major incident call, or very shortly after, the [Incident Commander](https://response.pagerduty.com/training/incident_commander/) selects and directly notifies one responder to own the postmortem. Note that the postmortem owner is not solely responsible for completing the postmortem themselves. **Writing a postmortem is a collaborative effort** and should include everyone involved in the incident response. While engineering will lead the analysis, the postmortem process should involve management, customer support, and business communications teams. The postmortem owner coordinates with everyone who needs to be involved to ensure it is completed in a timely manner.
|
||||
|
||||
It is important to designate a single owner to avoid the bystander effect. If you ask all responders or a team to do the postmortem, you risk everyone assuming someone else is doing it, therefore no one does. When selecting an owner you may choose a single individual who meets any of the following criteria:
|
||||
|
||||
- Took a leadership role investigating during the incident
|
||||
- Performed a task that led to stabilizing the service
|
||||
- Was the primary on-call responder for the most heavily affected service
|
||||
- Manually triggered the incident to initiate incident response
|
||||
|
||||
Doing the postmortem is not a punishment, and the owner is not the person that “caused” the incident. Effective postmortems are blameless. In complex systems, there is never a single cause, but a combination of factors that lead to failure. The owner is simply an accountable individual who performs select administrative tasks, follows up for information, and drives the postmortem to completion. Writing the postmortem will ultimately be a collaborative effort, but selecting a single owner to orchestrate this collaboration helps ensure it is done.
|
||||
|
||||
#### Best practices and more
|
||||
|
||||
PageDuty offers a completely free [postmortem handbook](https://www.pagerduty.com/resources/ebook/post-mortem-handbook/) that shares industry best practices and includes a [postmortem template](https://www.pagerduty.com/resources/ebook/post-mortem-template). Use it to help you formalize your own postmortem process to make it as easy as possible for your team to respond to issues. Even better, postmortems are now part of the PagerDuty platform — sign up for a [free 14-day trial](https://www.pagerduty.com/free-trial/) and streamline the entire postmortem process with automated timeline building, collaborative editing, actionable insights, and more.
|
||||
@@ -0,0 +1,68 @@
|
||||
# Optimism vs Pessimism in Distributed Systems
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Marc Brooker
|
||||
- **链接**: http://brooker.co.za/blog/2023/10/18/optimism.html
|
||||
|
||||
## 简介
|
||||
|
||||
The optimism and pessimism in this article are about the likelihood of contention and conflicts between actors in a distributed system, and it’s a fascinating way of looking at things.
|
||||
|
||||
## 正文
|
||||
|
||||
I am an engineer at Amazon Web Services (AWS) in Seattle, where I work on agentic AI, especially safety and policy for agentic AI. Before that, I worked on EC2, EBS, databases, serverless, and serverless databases.
|
||||
|
||||
All opinions are my own.
|
||||
|
||||
Avoiding coordination is the [one fundamental thing](https://brooker.co.za/blog/2021/01/22/cloud-scale.html) that allows us to build distributed systems that out-scale the performance of a single machine<sup>[1](http://brooker.co.za#foot1)</sup>. When we build systems that avoid coordinating, we end up building components that make assumptions about what other components are doing. This, too, is fundamental. If two components can’t check in with each other after every single step, they need to make assumptions about the ongoing behavior of the other component.
|
||||
|
||||
One way to classify these assumptions is into *optimistic* and *pessimistic* assumptions. I find it very useful, when thinking through the design of a distributed system, to be explicit about each assumption each component is making, whether that assumption is *optimistic* or *pessimistic*, and what exactly happens if the assumption is wrong. The choice between pessimistic and optimistic assumptions can make a huge difference to the scalability and performance of systems.
|
||||
|
||||
I generally think of optimistic assumptions as ones that avoid or delay coordination, and pessimistic assumptions as ones that require or seek coordination. The optimistic assumption assumes it’ll get away with its plans. The pessimistic assumption takes the bull by the horns and makes sure it will.
|
||||
|
||||
To make this concrete, let’s consider some examples.
|
||||
|
||||
**Example 1: Caches**
|
||||
|
||||
Distributed caches almost always make assumptions about whether the data they are holding is changed or not. Unlike with CPUs<sup>[2](http://brooker.co.za#foot2)</sup>, distributed caches typically aren’t *coherent*, but we still want them to be *eventually consistent*. By *eventually consistent* we mean that if the write stream stops, the caches eventually all converge on containing the same data. In other words, inconsistencies are relatively short-lived.
|
||||
|
||||
Possibly the most common way of ensuring this property—that inconsistencies are short-lived—is with a time to live (TTL). This simply means that the cache only keeps items around for a certain fixed period of time. The TTL provides a strong<sup>[3](http://brooker.co.za#foot3)</sup> upper bound on how stale an item can be. This is a simple, strong, and highly popular mechanism. It’s also a *pessimistic* one: the cache is doing extra work assuming that the item has changed. In systems with a low per-item write rate, that pessimistic assumption can be wrong much more often than it’s right.
|
||||
|
||||
One downside of the pessimistic approach TTL takes is that it means the cache empties when it can’t talk to the authority. This is unavoidable: caches simply can’t provide strongly bounded staleness (or any other strong recency guarantee) if they can’t reach the authority<sup>[4](http://brooker.co.za#foot4)</sup>. Thus the pessimistic TTL approach has a strong availability disadvantage: if a network partition or authority downtime lasts longer than the TTL, the cache hit rate will drop to zero.
|
||||
|
||||
Two more optimistic patterns are quite commonly used to address this situation (especially in DNS and networking systems). One approach is to synchronously try fetch the new item, but then *optimistically* continue to use the old one if that’s possible (optimistic because it’s making the optimistic assumption that the item hasn’t change). A subtly different approach is to asynchronously try fetch the new item, and use the old one until that can complete. These protocol seem very similar to TTL, but are deeply fundamentally different. They don’t offer strong recency or staleness guarantees, but can tolerate indefinite network partitions<sup>[5](http://brooker.co.za#foot5)</sup>.
|
||||
|
||||
**Example 2: OCC**
|
||||
|
||||
Optimistic concurrency control and its tradeoffs with pessimistic locking-based approaches is a classic topic (maybe the most classic topic) in distributed databases. I won’t try advance that debate here. Instead, to summarize: *optimistic concurrency control* is a way of implementing isolated (as in ACID I) transactions that assumes that other concurrent transactions don’t conflict, and detecting at the last moment if that assumption is wrong. *Pessimistic* approaches like the classic two-phase locking, on the other hand, do a whole lot of coordination based on the assumption that other transactions do conflict, and it’s worth detecting that early while there’s still time to avoid duplicate work and make smart scheduling decisions.
|
||||
|
||||
OCC systems, in general, coordinate less than pessimistic systems when their optimistic assumption is right, and more than pessimistic systems when the optimistic assumption is wrong.
|
||||
|
||||
Comparing these two is approaches is a hard enough first-order problem, but to complicate things further the choice between optimism and pessimism leads to a number of second-order problems too. For example, the number of contending transactions depends on the number of concurrent transactions, and the number of concurrent transactions depends on lock wait times in pessimistic systems and retry rates in optimistic systems. In both kinds of systems, this leads to a direct feedback loop between past contention and future contention.
|
||||
|
||||
**Example 3: Leases**
|
||||
|
||||
[Leases](https://dl.acm.org/doi/10.1145/74851.74870) are a kind of time-based lock widely used in distributed systems. In most systems, a lease is replacing a number of coordination steps. One component takes a lease, and then uses that lease as a license to multiple things without worrying that other components are doing conflicting things, or may disagree, or whatever. Freed from the worry about conflicts, the lease-holding component can avoid coordinating and go ahead at full speed.
|
||||
|
||||
Leases are an interesting blend of pessimism (*I’m assuming other things are going to conflict with my work, so I’m going to stop them in their tracks*) and optimism (*I’m assuming I can go ahead without coordination for the next bounded period of time*). If the pessimism is wrong, all the heartbeating and updating and storing of leases is wasted work. As is the time other components could have spent doing work which they wasted while waiting for the lease.
|
||||
|
||||
**Conclusion**
|
||||
|
||||
One way I like to reason about the behavior of systems is by writing sentences of the form “this component is assuming that…”
|
||||
|
||||
For our TTL example, we could write statements like:
|
||||
|
||||
- *This component is assuming that clients are OK with seeing stale data as long as the staleness is bounded* , and
|
||||
- *This cache is assuming that the items it holds have changed, and should be checked after every TTL expiry* , and
|
||||
- *This cache is assuming that clients would rather experience unavailability or higher latency than see items that are more stale than the TTL bound* .
|
||||
|
||||
These statements are a tool to help structure our thinking about the behavior of the system. The third one—the availability-staleness tradeoff—is especially powerful because its often a hidden assumption people make when choosing a strict TTL.
|
||||
|
||||
By coloring each assumption as *pessimistic* (coordination-requiring) or *optimistic* (coordination-avoiding), we can also structure our thinking about the best time to coordinate, and make sure we’re being consistent in our choices about when and why coordination is needed.
|
||||
|
||||
**Footnotes**
|
||||
|
||||
*coherent* using protocols like[MESI](https://en.wikipedia.org/wiki/MESI_protocol) . These protocols are interesting, because they allow coordination avoidance for unmodified items, at the cost of tracking state and ownership and assuming that the coherency protocol is correctly executed by all participants.
|
||||
[Section 5.2 of Highly Available Transactions](https://arxiv.org/pdf/1302.0309.pdf) , for which they cite[Gilbert and Lynch](https://users.ece.cmu.edu/~adrian/731-sp04/readings/GL-cap.pdf) somewhat hand-wavingly. I will continue the hand-waving here.
|
||||
*C* . If you’re a[PACELC](https://brooker.co.za/blog/2014/07/16/pacelc.html) kinda person, you might call the strict TTL variant PCEL, and the less-strict variants PAEL.
|
||||
[Andy Pavlo lecture](https://www.youtube.com/watch?v=MM0J0_LX8cg) , or Harding et al’s excellent 2017 paper[An Evaluation of Distributed Concurrency Control](https://www.cs.cmu.edu/~pavlo/papers/p553-harding.pdf) , or Kung and Papadimitriou’s classic 1979 paper[An Optimality Theory of Concurrency Control for Databases](http://www.eecs.harvard.edu/~htk/publication/1979-sigmod-kung-papadimitriou.pdf) , or Agrawal et al’s 1987 classic[Concurrency Control Performance Modeling: Alternatives and Implication](https://web.eecs.umich.edu/~jag/eecs584/papers/acl.pdf) (thanks Peter Alvaro for reminding me about this one), or the OCC OG[On Optimistic Methods for Concurrency Control](https://www.eecs.harvard.edu/~htk/publication/1981-tods-kung-robinson.pdf) .
|
||||
@@ -0,0 +1,13 @@
|
||||
# A guide to running Incident Command
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Jonathan Word
|
||||
- **链接**: https://argoday.medium.com/incident-command-guide-9872b51d7c94
|
||||
|
||||
## 简介
|
||||
|
||||
> Here is a guide for how to be an effective Incident Commander and get things fixed as quickly as possible as part of an efficient Incident Management process.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,80 @@
|
||||
# Paper: Four Concepts for Resilience Engineering
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Fred Hebert (summary)Dr. David Woods (original paper)
|
||||
- **链接**: https://ferd.ca/notes/paper-four-concepts-for-resilience-engineering.html
|
||||
|
||||
## 简介
|
||||
|
||||
The four concepts are Rebound, Robustness, Graceful Extensibility, and Sustained Adaptability, and this research paper summary explains each concept.
|
||||
|
||||
## 正文
|
||||
|
||||
## Paper: Four Concepts for Resilience Engineering
|
||||
|
||||
Here is an interesting little bit from a novel I read during the summer of 2022, which had a quick note about the term “resilience.” I’m translating loosely from French:
|
||||
|
||||
Term borrowed from metallurgy, appropriated by pop-science psychiatrists and countless mediocre motivational speakers, resilience is one of the most overloaded words of this era. Synonymous with a capacity to overcome obstacles and to grow despite adversity for the common man, resilience rather points to the quality of materials that can return to their original form after having been hammered, burnt, twisted, or put under some tension.
|
||||
|
||||
|
||||
To apply to humans while respecting the original etymology, we must first abandon all notions of naive optimism. The psychopath who maintains his psychological rigidity while interrogated is resilient, the drug addict who finds himself still tolerant to drug effects after a forced withdrawal is resilient, the soldier who lets himself be be showered by enemy fire in a lost battle is resilient; those who show resignation are more resilient than the optimists. It is therefore not a question of reaching for the higher planes of virtue, but to be unwavering to your true nature. Mother Teresa and Adolf Hitler both represent excellent resilience models.
|
||||
|
||||
|
||||
The novel is [Ta mort a moi](https://www.goodreads.com/book/show/52233197-ta-mort-moi), and the tone is for sure cynical, but I did enjoy the heavy pessimistic contrast with resilience as used in resilience engineering, and the idea that evolving and adapting is very different from resilience, which is just about returning to your original shape regardless of whether it is good or not.
|
||||
|
||||
So how does resilience engineering define resilience? Well that's this week's paper, once again by David Woods, titled [Four concepts for resilience and the implications for the future of resilience engineering](https://www.researchgate.net/publication/276139783_Four_concepts_for_resilience_and_the_implications_for_the_future_of_resilience_engineering). The paper opens by admitting that the popularity of the term has led to confusion regarding what it means in the first place. I recall seeing other papers which held the ill-defined term as one of the biggest weakness of a discipline named after it. All the different uses seen around the place have been categorized into 4 groups by Woods: rebounding, robustness, graceful extensibility, and sustained adaptability.
|
||||
|
||||
#### Rebound
|
||||
|
||||
Why do some communities, groups, or individuals recover from traumatic disrupting events or repeated stressors better than others to resume previous normal functioning? Most research there asserts that the difference comes from which resources and capabilities were present *before* the disruptions, not from the what happens when surprised. The paper quotes:
|
||||
|
||||
the ability to deal with a crisis situation is largely dependent on the structures that have been developed before chaos arrives. The event can in some ways be considered a brutal and abrupt audit: at a moment's notice, everything that was left unprepared becomes a complex problem, and every weakness comes rushing to the forefront
|
||||
|
||||
|
||||
A second important aspect is that research focusing on rebound cares a lot more about the fact that disruptions are *surprises*, rather than the nature of each individual disruption's characteristics. The surprise challenges a model and forces revisions into the system.
|
||||
|
||||
This creates a weird effect where this structure of research drives towards studying another definition of resilience (graceful extensibility): to deal with disruption, the capability to adapt has to already be there, and considers the resilience *as a potential*. But you can only measure the potential by validating it across disruptions, which this definition doesn't like focusing on.
|
||||
|
||||
In short, a lot of questions about resilience are about why or how organizations rebound, but the research has mostly moved on to study systems where there is an ongoing and continual ability to adapt and adjust.
|
||||
|
||||
#### Robustness
|
||||
|
||||
This is generally perceived to be a conflation of resilience with another term—the ability to absorb disruptions—robustness. More robustness means your system can tolerate a broader range of disturbances while still responding effectively. Generally, robust control works, and only works, for cases where the disturbances are well-modelled.
|
||||
|
||||
This definition therefore remains sensitive to the question about what happens when the disturbance is outside the scope of what was modelled. The typical failure mode here is one where the system reaches its limits and suddenly collapses. Woods states that brittleness tends to just live at boundaries of robustness. Cybersecurity is an interesting domain here where you can be extremely robust to specific types of threats, but once the attack is novel, using a different approach, everything goes bad.
|
||||
|
||||
The naive understanding of robustness is that you can continuously expand the envelope of the stressors you can cope with. In practice, empirical research has shown that it is in fact more often a tradeoff: the things you can handle mean there are other things to which you become more fragile. This, once more, pushes towards the two latter definitions, which focus more on ways to adapt than ways to predict, because that tradeoff is more and more considered to be fundamental and unavoidable (think, for example, of heuristics and limits to attention).
|
||||
|
||||
#### Graceful Extensibility
|
||||
|
||||
Graceful extensibility is a sort of play on the idea of graceful degradation. Rather than asking the question how or why do people, systems, organizations bounce back, this line of approach asks: how do systems stretch to handle surprises? Resources are finite, environments changing, and their boundaries shift in ways that requires stretching and elasticity. A tenet here is that without the ability to stretch and adjust, your brittleness is far more severe than expected during normal operations, and generally exposed through extremely rapid collapses.
|
||||
|
||||
So a big question is where's the boundary? We never know, incidents define it. There's a rate and tempo to events that let us get a glimpse of what it might be, so they can be looked at, tracked, and exercised. A common challenging scenario is how an organism that deals with "normal" challenges deals with two of them happening at once, for example, because this risks overextending the system.
|
||||
|
||||
The idea here is influenced by Safety-I (studying and preventing failures) vs. Safety-II (studying and enhancing successes), such that graceful extensibility can be seen as a positive attribute: how do we create a readiness-to-respond that is a strength and can be leveraged in all sorts of situations, rather than narrowing it to being the avoidance of negative effects?
|
||||
|
||||
Contrasted with rebounds, the approach to this is to look at past challenges, and see them as a way to gauge the potential to adapt to new surprises in the future. It also allows the idea of studying sequences and series of rebounds on a longer-term view of the system. How do they succeed and how do they fail?
|
||||
|
||||
Systems tend to fail when exhausting their capacity to mobilize response as disturbances grow and cascade, something dubbed decompensation. This tends to be detected when the ability to recover from a crisis takes longer and longer, which is the impending sense of a tipping point or collapse. The positive version of it is the anticipation of bottlenecks and crunches, and being able to deal with them. There are things that can be done to aid this resilience potential, but it contains its own challenges, where an organization can hinder its own capacity while trying to improve it.
|
||||
|
||||
This leads to the fourth definition, sustained adaptability
|
||||
|
||||
#### Sustained Adaptability
|
||||
|
||||
This refers to the ability manage/regulate adaptive capacities of systems. In short, while the past can be used to calibrate the potential for future resilience, the past is also not predictive and you can hit walls where the capacity is gone. Resilience-as-sustained-adaptability asks 3 questions:
|
||||
|
||||
1. what governance or architectural characteristics explain systems that succeed or fail at sustained adaptation?
|
||||
2. what design principles and techniques would allow one to engineer a system that adapts in a sustained manner?
|
||||
3. how would you know you're succeeding?
|
||||
|
||||
Expected challenges to sociotechnical systems over their life cycle include:
|
||||
|
||||
- surprises will keep challenging boundaries
|
||||
- conditions and contexts will keep changing and shifting the boundaries
|
||||
- adaptive shortfalls will happen and people will have to step in
|
||||
- the factors that provide adaptability and the needs for them will shift over time
|
||||
- classes of changes will happen and the system as a whole will need to readjust itself and its relationships
|
||||
|
||||
A whole lot of the discipline is therefore interested in all the tradeoffs people make, that biological systems (or ecosystems) make, and particularly which are fundamental and how they apply to other systems as well. An agenda of this type of resilience is in managing capacities dedicated to resilience. In this perspective, it makes sense to say a system is resilient, or not, based on how well it balances all the tradeoffs, or not.
|
||||
|
||||
Woods states that the yield from the first two types of resilience has been low. The latter two approaches, the most positive ones, tend to provide better lines of inquiries, though the discipline is still young.
|
||||
@@ -0,0 +1,130 @@
|
||||
# Revolutionizing Real-Time Streaming Processing: 4 Trillion Events Daily at LinkedIn
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Bingfeng Xia and Xinyu Liu — LinkedIn
|
||||
- **链接**: https://engineering.linkedin.com/blog/2023/revolutionizing-real-time-streaming-processing--4-trillion-event
|
||||
|
||||
## 简介
|
||||
|
||||
> Apache Beam played a pivotal role in revolutionizing and scaling LinkedIn’s data infrastructure. Beam’s powerful streaming capabilities enable real-time processing for critical business use cases, at a scale of over 4 trillion events daily through more than 3,000 pipelines.
|
||||
|
||||
## 正文
|
||||
|
||||
# Revolutionizing Real-Time Streaming Processing: 4 Trillion Events Daily at LinkedIn
|
||||
|
||||
*Authors: [Bingfeng Xia](https://www.linkedin.com/in/xiabingfeng) and [Xinyu Liu](https://www.linkedin.com/in/xinyu-liu-b0b21648)*
|
||||
|
||||
## Background
|
||||
|
||||
At LinkedIn, Apache Beam plays a pivotal role in stream processing infrastructures that process over 4 trillion events daily through more than 3,000 pipelines across multiple production data centers. This robust framework empowers near real-time data processing for critical services and platforms, ranging from machine learning and notifications to anti-abuse AI modeling. With over 950 million members, ensuring that our platform is running smoothly is critical to connecting members to opportunities worldwide.
|
||||
|
||||
In this case study, LinkedIn's Bingfeng Xia, Engineering Manager, and Xinyu Liu, Senior Staff Engineer, shed light on how the Apache Beam programming model's unified, portable, and user-friendly data processing framework has enabled a multitude of sophisticated use cases and revolutionized streaming processing at LinkedIn. This technology has [optimized cost-to-serve by 2x](https://engineering.linkedin.com/blog/2023/unified-streaming-and-batch-pipelines-at-linkedin--reducing-proc) by unifying stream and batch processing through Apache Samza and Apache Spark runners, enabled real-time ML feature generation, reduced time-to-production for new pipelines from months to days, allowed for processing time-series events at over 3 million queries per second, and more. For our members, this means that we’re able to serve more accurate job recommendations, improve feed recommendations, and identify fake profiles at a faster rate, etc.
|
||||
|
||||
## LinkedIn Open-Source Ecosystem and Journey to Beam
|
||||
|
||||
LinkedIn has a rich history of actively contributing to the open-source community, demonstrating its commitment by creating, managing, and utilizing various open-source software projects. The LinkedIn engineering team has [open-sourced over 75 projects](https://engineering.linkedin.comhttps://engineering.linkedin.com/open-source) across multiple categories, with several gaining widespread adoption and becoming part of [the Apache Software Foundation](https://www.apache.org/).
|
||||
|
||||
To enable the ingestion and real-time processing of enormous volumes of data, LinkedIn built a custom stream processing ecosystem largely with tools developed in-house (and subsequently open-sourced). In 2010, they introduced [Apache Kafka](https://kafka.apache.org/), a pivotal Big Data ingestion backbone for LinkedIn’s real-time infrastructure. To transition from batch-oriented processing and respond to Kafka events within minutes or seconds, they built an in-house distributed event streaming framework, [Apache Samza](https://samza.apache.org/). This framework, along with Apache Spark for batch processing, formed the basis of LinkedIn’s [lambda architecture](https://en.wikipedia.org/wiki/Lambda_architecture) for data processing jobs. Over time, LinkedIn's engineering team expanded the stream processing ecosystem with more proprietary tools like [Brooklin](https://github.com/linkedin/Brooklin/), facilitating data streaming across multiple stores and messaging systems, and [Venice](https://github.com/linkedin/venice), serving as a storage system for ingesting batch and stream processing job outputs, among others.
|
||||
|
||||
Though the stream processing ecosystem with Apache Samza at its core enabled large-scale stateful data processing, LinkedIn’s ever-evolving demands required higher scalability and efficiency, as well as lower latency for the streaming pipelines. The lambda architecture approach led to operational complexity and inefficiencies, because it required maintaining two different codebases and two different engines for batch and streaming data. To address these challenges, data engineers sought a higher level of stream processing abstraction and out-of-the-box support for advanced aggregations and transformations. Additionally, they needed the ability to experiment with streaming pipelines in batch mode. There was also a growing need for multi-language support within the overall Java-prevalent teams due to emerging machine learning use cases requiring Python.
|
||||
|
||||
The release of [Apache Beam](https://beam.apache.org/about/) in 2016 proved to be a game-changer for LinkedIn. Apache Beam offers an open-source, advanced unified programming model for both batch and streaming processing, making it possible to create a large-scale common data infrastructure across various applications. With support for Python, Go, and Java SDKs and a rich, versatile API layer, Apache Beam provided the ideal solution for building sophisticated multi-language pipelines and running them on any engine.
|
||||
|
||||
|
||||
|
||||
*“When we started looking at Apache Beam, we realized it was a very attractive data processing framework for LinkedIn’s demands: not only does it provide an advanced API, but it also allows for converging stream and batch processing and multi-language support. Everything we were looking for and out-of-the-box.” ~* Xinyu
|
||||
|
||||
Recognizing the advantages of Apache Beam's unified data processing API, advanced capabilities, and multi-language support, LinkedIn began onboarding its first use cases and developed the [Apache Samza runner for Beam](https://beam.apache.org/documentation/runners/samza/) in 2018. By 2019, Apache Beam pipelines were powering several critical use cases, and the programming model and framework saw extensive adoption across LinkedIn teams. Xinyu Liu showcased the benefits of migrating to Apache Beam pipelines during [Beam Summit Europe 2019](https://www.youtube.com/watch?v=uQcpr34RUKY&t=1694s).
|
||||
|
||||
## Apache Beam Use Cases at LinkedIn
|
||||
|
||||
### Unified Streaming And Batch Pipelines
|
||||
|
||||
Some of the first use cases that LinkedIn migrated to Apache Beam pipelines involved both real-time computations and periodic backfilling. One example was LinkedIn's standardization process. Standardization consists of a series of pipelines that use complex AI models to map LinkedIn user inputs, such as job titles, skills, or education history, into predefined internal IDs. For example, a LinkedIn member who lists their current position as "Chief Data Scientist" has their job title standardized for relevant job recommendations.
|
||||
|
||||
|
||||
|
||||
LinkedIn's standardization process requires both real-time processing to reflect immediate user updates and periodic backfilling to refresh data when new AI models are introduced. Before adopting Apache Beam, running backfilling as a streaming job required over 5,000 GB-hours in memory and nearly 4,000 hours in total CPU time. This heavy load led to extended backfilling times and scaling issues, causing the backfilling pipeline to act as a "noisy neighbor" to colocated streaming pipelines and failing to meet latency and throughput requirements. Although LinkedIn engineers considered migrating the backfilling logic to a batch Spark pipeline, they abandoned the idea due to the unnecessary overhead of maintaining two different codebases.
|
||||
|
||||
*“We came to the question: is it possible to only maintain one codebase but with the ability to run it as either a batch job or streaming job? The unified Apache Beam model was the solution.”* ~ Bingfeng
|
||||
|
||||
The Apache Beam APIs enabled LinkedIn engineers to implement business logic once within a unified Apache Beam pipeline that efficiently handles both real-time standardization and backfilling. Apache Beam offers [PipelineOptions](https://beam.apache.org/releases/javadoc/current/org/apache/beam/sdk/options/PipelineOptions.html), enabling the configuration and customization of various aspects, such as the pipeline runner and runner-specific configurations. The extensibility of Apache Beam transforms allowed LinkedIn to [create a custom composite transform](https://beam.apache.org/documentation/programming-guide/#composite-transforms) to abstract away I/O differences and switch target processing on the fly based on data source type (bounded or unbounded). In addition, Apache Beam’s abstraction of the underlying infrastructure and the ability to "write once, run anywhere" empowered LinkedIn to seamlessly switch between data processing engines. Depending on the target processing type, streaming, or batch, the unified Apache Beam standardization pipeline can be deployed through the Samza cluster as a streaming job or through the Spark cluster as a batch backfilling job.
|
||||
|
||||
Hundreds of streaming Apache Beam jobs now power real-time standardization, listening to events 24/7, enriching streams with additional data from remote tables, performing necessary processing, and writing results to output databases. The batch Apache Beam backfilling job runs weekly, effectively handling 950 million member profiles at a rate of over 40,000 profiles per second. Apache Beam infers data points into sophisticated AI and machine learning models and joins complex data such as job types and work experiences, thus standardizing user data for search indexing or to run recommendation models.
|
||||
|
||||
The migration of backfilling logic to a unified Apache Beam pipeline and its execution in batch mode resulted in a significant 50% improvement in memory and CPU usage efficiency (from ~5000 GB-hours and ~4000 CPU hours to ~2000 GB-hours and ~1700 CPU hours) and an impressive 94% acceleration in processing time (from 7.5 hours to 25 minutes). More details about this use case can be found on [LinkedIn’s engineering blog](https://engineering.linkedin.com/blog/2023/unified-streaming-and-batch-pipelines-at-linkedin--reducing-proc).
|
||||
|
||||
### Anti-Abuse & Near Real-Time AI Modeling
|
||||
|
||||
LinkedIn is firmly committed to creating a trusted environment for its members, and this dedication extends to safeguarding against various types of abuse on the platform. To achieve this, the Anti-Abuse AI Team at LinkedIn plays a crucial role in creating, deploying, and maintaining AI and deep learning models that can detect and prevent different forms of abuse, such as fake account creation, member profile scraping, automated spam, and account takeovers.
|
||||
|
||||
Apache Beam fortifies LinkedIn’s internal anti-abuse platform, Chronos, enabling abuse detection and prevention in near real-time. Chronos relies on two streaming Apache Beam pipelines: the Filter pipeline and the Model pipeline. The Filter pipeline reads user activity events from Kafka, extracts relevant fields, aggregates and filters the events, and then generates filtered Kafka messages for downstream AI processing. Subsequently, the Model pipeline consumes these filtered messages, aggregates member activity within specific time windows, triggers AI scoring models, and writes the resulting abuse scores to various internal applications, services, and stores for offline processing.
|
||||
|
||||
The flexibility of Apache Beam's pluggable architecture and the availability of various I/O options seamlessly integrated the anti-abuse pipelines with Kafka and key-value stores. LinkedIn has dramatically reduced the time it takes to label abusive actions, cutting it down from 1 day to just 5 minutes and processing time-series events at an impressive rate of over 3 million queries per second. Apache Beam empowered near real-time processing, significantly bolstering LinkedIn's anti-abuse defenses. The nearline defenses are able to catch scrapers within minutes after they start to scrape and this leads to more than 6% improvement in detecting logged-in scrapping profiles.
|
||||
|
||||
*“Apache Beam enabled revolutionary, phenomenal performance improvements - the anti-abuse processing accelerated from 1 day to 5 minutes. We have seen more than 6% improvement in detecting logged-in scrapping profiles.”*
|
||||
|
||||
~ Xinyu
|
||||
|
||||
### Notifications Platform
|
||||
|
||||
As a social media network, LinkedIn heavily relies on instant notifications to drive member engagement. To achieve this, Apache Beam and Apache Samza together power LinkedIn’s large-scale Notifications Platform that generates notification content, pinpoints the target audience, and ensures the timely and relevant distribution of content.
|
||||
|
||||
The streaming Apache Beam pipelines have intricate business logic and handle enormous volumes of data in a near real-time fashion. The pipelines consume, aggregate, partition, and process events from over 950 million LinkedIn members and feed the data to downstream machine learning models. The ML models perform distributed targeting and scalable scoring on the order of millions of candidate notifications per second based on the recipient member’s historical actions and make personalized decisions for the recipient for each notification on the fly. As a result, LinkedIn members receive timely, relevant, and actionable activity-based notifications, such as connection invites, job recommendations, daily news digests, and other activities within their social network, through the right channels.
|
||||
|
||||
The advanced Apache Beam API offers complex aggregation and filtering capabilities out-of-the-box, and its programming model allows for the creation of reusable components. These features enable LinkedIn to expedite development and streamline the scaling of the Notifications platform as they transition more notification use cases from Samza to Beam pipelines.
|
||||
|
||||
*“LinkedIn’s member engagement is greatly driven by how timely we can send relevant notifications. Apache Beam enabled a scalable, near real-time infrastructure behind this business-critical use case.”* ~ Bingfeng
|
||||
|
||||
### Real-Time ML Feature Generation
|
||||
|
||||
LinkedIn's core functionalities, such as job recommendations and search feed, heavily rely on ML models that consume thousands of features related to various entities like companies, job postings, and members. However, before the adoption of Apache Beam, the original offline ML feature generation pipeline suffered from a delay of 24 to 48 hours between member actions and the impact of those actions on the recommendation system. This delay resulted in missed opportunities, because the system lacked sufficient data about infrequent members and failed to capture the short-term intent and preferences of frequent members. In response to the growing demand for a scalable, real-time ML feature generation platform, LinkedIn turned to Apache Beam to address the challenge.
|
||||
|
||||
Using Managed Beam as the foundation, LinkedIn developed a hosted platform for ML feature generation. The ML platform provides AI engineers with real-time features and an efficient pipeline authoring experience, all while abstracting away deployment and operational complexities. AI engineers create feature definitions and deploy them using Managed Beam. When LinkedIn members take actions on the platform, the streaming Apache Beam pipeline generates fresher machine learning features by filtering, processing, and aggregating the events emitted to Kafka in real-time and writes them to the feature store. Additionally, LinkedIn introduced other Apache Beam pipelines responsible for retrieving the data from the feature store, processing it, and feeding it into the recommendation system.
|
||||
|
||||
The powerful Apache Beam streaming processing platform played a pivotal role in eliminating the delay between member actions and data availability, achieving an impressive end-to-end pipeline latency of just a few seconds. This significant improvement allowed LinkedIn's ML models to take advantage of up-to-date information and deliver more personalized and timely recommendations to our members, leading to significant gains in business metrics.
|
||||
|
||||
### Managed Streaming Processing Platform
|
||||
|
||||
As LinkedIn's data infrastructure grew to encompass over 3,000 Apache Beam pipelines, catering to a diverse range of business use cases, LinkedIn's AI and data engineering teams found themselves overwhelmed with managing these streaming applications 24/7. The AI engineers encountered several technical challenges while creating new pipelines, including the intricacy of integrating multiple streaming tools and infrastructures into their frameworks, and limited knowledge of the underlying infrastructure when it came to deployment, monitoring, and operations. These challenges led to a time-consuming pipeline development cycle, often lasting one to two months. Apache Beam enabled LinkedIn to create Managed Beam, a managed streaming processing platform that is designed to streamline and automate internal processes. This platform makes it easier and faster for teams to develop and operate sophisticated streaming applications while reducing the burden of on-call support.
|
||||
|
||||
|
||||
|
||||
The Apache Beam SDK empowered LinkedIn engineers to create custom workflow components as reusable sub-DAGs (Directed Acyclic Graphs) and expose them as standard PTransforms. These PTransforms serve as ready-to-use building blocks for new pipelines, significantly speeding up the authoring and testing process for LinkedIn AI engineers. By abstracting the low-level details of underlying engines and runtime environments, Apache Beam allows engineers to focus solely on business logic, further accelerating time to development.
|
||||
|
||||
When the pipelines are ready for deployment, Managed Beam's central control plane comes into play, providing essential features like a deployment UI, operational dashboard, administrative tools, and automated pipeline lifecycle management.
|
||||
|
||||
Apache Beam's abstraction facilitated the isolation of user code from framework evolution during build, deployment, and runtime. To ensure the separation of runner processes from user-defined functions (UDFs), Managed Beam packages the pipeline business logic and the framework logic as two separate JAR files: framework-less artifacts and framework artifacts. During pipeline execution on a YARN cluster, these pipeline artifacts run in a Samza container as two distinct processes, communicating through gRPC. This setup enabled LinkedIn to take advantage of automated framework upgrades, scalable UDF execution, log separation for easier troubleshooting, and multi-language APIs, fostering flexibility and efficiency.
|
||||
|
||||
Apache Beam also underpinned Managed Beam's autosizing controller tool, which automates hardware resource tuning and provides auto-remediation for streaming pipelines. Streaming Apache Beam pipelines self-report diagnostic information, such as metrics and key deployment logs, in the form of Kafka topics. Additionally, LinkedIn's internal monitoring tools report runtime errors, such as heartbeat failures, out-of-memory events, and processing lags. The Apache Beam diagnostics processor pipeline aggregates, repartitions, and windows these diagnostic events before passing them to the autosizing controller and writing them to Apache Pinot, LinkedIn's OLAP store for Managed Beam's operational and analytics dashboards. Based on the pre-processed and time-windowed diagnostic data, the autosizing controller generates sizing actions or restarting actions, and then forwards them to the Managed Beam control plane. The Managed Beam control plane then scales LinkedIn's streaming applications and clusters.
|
||||
|
||||
*“Apache Beam helped streamline operations management and enabled fully-automated autoscaling, significantly reducing the time to onboard new applications. Previously, onboarding required a lot of manual 'trial and error' iterations and deep knowledge of the internal system and metrics.”*
|
||||
|
||||
~ Bingfeng
|
||||
|
||||
The extensibility, pluggability, portability, and abstraction of Apache Beam formed the backbone of LinkedIn's Managed Beam platform. The Managed Beam platform accelerated the time to author, test, and stabilize streaming pipelines from months to days, facilitated fast experimentation, and almost entirely eliminated operational costs for AI engineers.
|
||||
|
||||
## Summary
|
||||
|
||||
Apache Beam played a pivotal role in revolutionizing and scaling LinkedIn's data infrastructure. Beam's powerful streaming capabilities enable real-time processing for critical business use cases, at a scale of over 4 trillion events daily through more than 3,000 pipelines.
|
||||
|
||||
The versatility of Apache Beam empowered LinkedIn’s engineering teams to optimize their data processing for various business use cases:
|
||||
|
||||
- Apache Beam's unified and portable framework allowed LinkedIn to consolidate streaming and batch processing into unified pipelines. These unified pipelines resulted in a 2x optimization in cost-to-serve, a 2x improvement in processing performance, and a 2x improvement in memory and CPU usage efficiency.
|
||||
- LinkedIn's anti-abuse platform leveraged Apache Beam to process user activity events from Kafka in near-real-time, achieving a remarkable acceleration from days to minutes in labeling abusive actions. This processing acceleration led to a 21% enhancement in identifying fake accounts, a 15% improvement in detecting scraping activities, and a substantial 30% improvement in detecting abusive users.
|
||||
- By adopting Apache Beam, LinkedIn was able to transition from an offline ML feature generation pipeline with a 24- to 48-hour delay to a real-time platform with an end-to-end pipeline latency at the millisecond or second level.
|
||||
- Apache Beam’s abstraction and powerful programming model enabled LinkedIn to create a fully managed stream processing platform, thus facilitating easier authoring, testing, and deployment and accelerating time-to-production for new pipelines from months to days.
|
||||
|
||||
Apache Beam boasts seamless plug-and-play capabilities, integrating smoothly with Apache Kafka, Apache Pinot, and other core technologies at LinkedIn, all while ensuring optimal performance at scale. As LinkedIn continues experimenting with new engines and tooling, the Apache Beam portability future-proofs our ecosystem against any changes in the underlying infrastructure.
|
||||
|
||||
*“By enabling a scalable, near real-time infrastructure behind business-critical use cases, Apache Beam empowers LinkedIn to leverage the freshest data and process it in real-time to create timely recommendations and personalized experiences, ultimately benefiting LinkedIn's vast network of over 950 million members worldwide.”* ~ Xinyu
|
||||
|
||||
## Acknowledgements
|
||||
|
||||
Big thanks to the entire Stream Processing Infrastructure team members who have been tirelessly developing the performant, resilient, and scalable stream processing infrastructures and delivering significant customer impact. Special thanks to the continuous support from our leadership Kartik Paramasivam, Renu Tewari, Anthony Asta, and Gary Yang.
|
||||
|
||||
Many thanks to the peer reviewers for this blog Hai Lu, Prateek Maheshwari, Peter Poon, and Shangjin Zhang.
|
||||
|
||||
Last but not least, we extend our heartfelt thanks to all stream processing users and stakeholders at LinkedIn for their valuable feedback, innovative ideas, unwavering commitment, and real-world use cases that are the driving force behind our advancements.
|
||||
|
||||
Related articles
|
||||
101
sreweekly/markdown/398/07-automating-dead-code-cleanup.md
Normal file
101
sreweekly/markdown/398/07-automating-dead-code-cleanup.md
Normal file
@@ -0,0 +1,101 @@
|
||||
# Automating dead code cleanup
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Will Shackleton, Andy Pincombe, and Katriel Cohn-Gordon — Meta
|
||||
- **链接**: https://engineering.fb.com/2023/10/24/data-infrastructure/automating-dead-code-cleanup/
|
||||
|
||||
## 简介
|
||||
|
||||
Meta’s SCARF tool automatically scans for unused (dead) code and creates pull requests for their removal, on a daily basis.
|
||||
|
||||
## 正文
|
||||
|
||||
- Meta’s Systematic Code and Asset Removal Framework (SCARF) has a subsystem for identifying and removing dead code.
|
||||
- SCARF combines static and dynamic analysis of programs to detect dead code from both a business and programming language perspective.
|
||||
- SCARF automatically creates change requests that delete the dead code identified from the program analysis, minimizing developer costs.
|
||||
|
||||
In our last blog post on [automatic product deprecation](https://engineering.fb.com/2023/10/17/data-infrastructure/automating-product-deprecation-meta/), we talked about the complexities of product deprecations, and a solution Meta has built called the Systematic Code and Asset Removal Framework (SCARF). As an example, we looked at [Moments](https://about.fb.com/news/2015/06/introducing-moments/), the photo sharing app Meta launched in 2015 and eventually shut down in 2019, and how SCARF can help with the deprecation process through its workflow management capabilities. We discussed how SCARF saves engineering time by identifying the correct order of tasks for cleaning up a product and how it can be blocked from automating the cleanup when there are intersystem dependencies. This naturally leads to the question: How do we automatically unblock SCARF when there is code that references an asset?
|
||||
|
||||
## Dead code removal in SCARF
|
||||
|
||||
SCARF contains a subsystem that automatically identifies dead code through a combination of static, runtime, and application analysis. It leverages this analysis to submit change requests to remove this code from our systems. This automated dead code removal improves the quality of our systems and also unblocks unused data removal in SCARF when the dead code includes references to data assets that prevent automated data cleanup.
|
||||
|
||||
## Code analysis
|
||||
|
||||
SCARF’s code analysis subsystem gathers information from a variety of sources. First, a code dependency graph for each language is extracted from our compilers via [Glean](https://glean.software/). This is then augmented with further information, like the usage of API endpoints from operational logs that determine whether an endpoint is used at runtime. Additional examples of domain-specific usage encoded include:
|
||||
|
||||
- Script invocations for internal developer tools and system management commands.
|
||||
- Template hooks for dynamically rendering pages in the [Instagram Django backend and URI handler and routing](https://instagram-engineering.com/web-service-efficiency-at-instagram-with-python-4976d078e366) .
|
||||
- Async’s dynamically referenced dispatch methods ([Meta’s deferred job execution service](https://engineering.fb.com/2020/08/17/production-engineering/async/) ).
|
||||
|
||||
SCARF must be capable of introspecting any and all types of dynamic usage in addition to the static dependency graph to make accurate determinations of whether a piece of code is truly safe to remove. These are combined and form an augmented dependency graph.
|
||||
|
||||
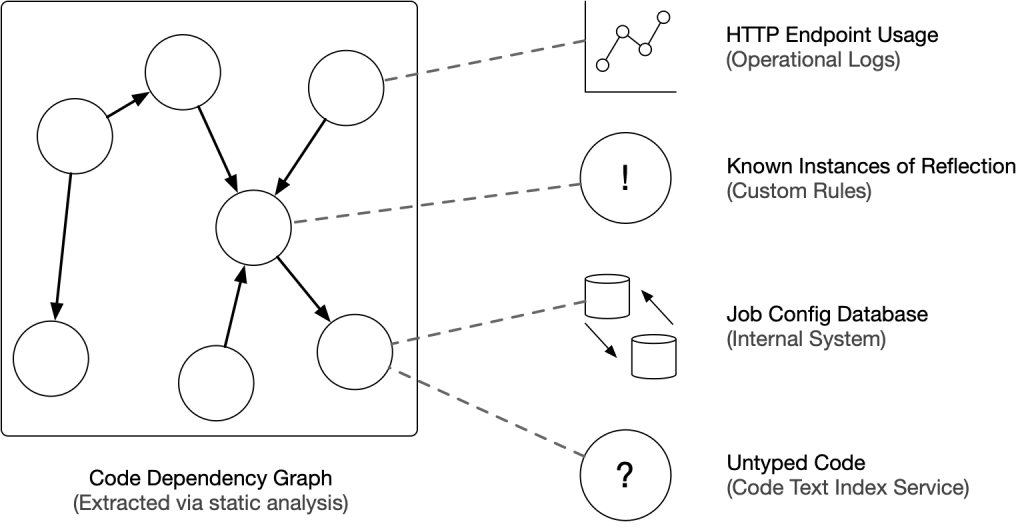
|
||||
|
||||
|
||||
SCARF supports multiple programming languages. This is very important, as products at Meta may have client code written in Java, Objective-C, and JavaScript, with server code written in [Hack](https://hacklang.org/), and some backend infrastructure written in [Python](https://engineering.fb.com/2023/10/05/developer-tools/python-312-meta-new-features/). All of these pieces of code should be deleted as they all combine to form the same dependency graph since they are associated via APIs and other known forms of dynamic and language-spanning references.
|
||||
|
||||
SCARF operates at a symbol level as opposed to a file level, which allows for more granular analysis and cleanup. For example, an individual variable that is unused in a function will have its own fully qualified symbol, which allows for more granular cleanup than is possible at the file level.
|
||||
|
||||
## Garbage collection
|
||||
|
||||
SCARF analyzes the augmented dependency graph to identify unreachable nodes and subgraphs that can be deleted and will automatically generate code change requests to delete the corresponding code on a daily basis. A key benefit of analyzing the complete graph is that we can detect and delete cycles, where different parts of the codebase depend on each other. Deleting entire subgraphs accelerates the deletion of dead code and provides a better experience for the engineers leveraging this automation in their deprecations.
|
||||
|
||||
It’s important that the graph contains the augmented information, as static analysis alone may not reveal links between components created through dynamic references or runtime language features. There is a trade-off, though, in that augmenting the graph with dynamic usage information requires the full processing of the indexed code and the subsequent data analysis pipelines that provide the metrics. This increases the end to end duration of the entire process which can make prototyping new features or capabilities more difficult.
|
||||
|
||||
Earlier versions of SCARF avoided this upfront cost by taking a different approach. It analyzed each discoverable symbol individually and at runtime would run classifiers that queried for static and dynamic references in order to find dead root nodes — pieces of code with no inbound dependencies. This did not require the upfront construction of the complete dependency graph and simplified the process of running the system over small subsets of the codebase. As a result, it was trivial to prototype new classifiers that identified potential dynamic references without requiring time-consuming indexing or data analysis.
|
||||
|
||||
However, this longer end-to-end development cycle led to a dramatic improvement in coverage. The transition from analyzing individual symbols to the entire graph led to a nearly 50% increase in dead code removed from one of Meta’s largest codebases. The new approach improves visibility into the state of our codebases: how much is alive, how much is dead, and how much of that we are removing in any given pass of SCARF.
|
||||
|
||||
## Fine-tuning the dependency graph
|
||||
|
||||
Many of the dependencies that we index using Glean are for patterns of code invocation which do not necessarily block the deletion of that code. For example, let’s say we had a class PhotoRenderer, and the only dependency on it was in code like this:
|
||||
|
||||
```
|
||||
if isinstance(renderer, PhotoRenderer):
|
||||
return renderer.render_photo()
|
||||
else:
|
||||
return renderer.render_generic()
|
||||
```
|
||||
In this case, the references to PhotoRenderer and render_photo() can be removed, and the code changed to this:
|
||||
|
||||
`return renderer.render_generic()`
|
||||
In this example, the class, PhotoRenderer, was **inlined** based on a rule derived from the semantics of Python: if there are no places where the PhotoRenderer class is instantiated, we can be confident that this code cannot take the first branch and it is therefore dead.
|
||||
|
||||
In some cases, we derive these rules based on our application semantics as opposed to language semantics. Imagine this code:
|
||||
|
||||
```
|
||||
uri_dispatch = {
|
||||
'/home/': HomeController,
|
||||
'/photos/': PhotosController,
|
||||
...
|
||||
}
|
||||
```
|
||||
If we only analyzed a language-level dependency graph, it would be impossible to determine whether or not PhotosController is ever referenced as it can be invoked via this URI dispatch mechanism. However, if we know from our application analysis that the ‘/photos/’ endpoint never receives any requests in production, then we could remove the corresponding entry from this dictionary.
|
||||
|
||||
There’s no inherent way to infer this given Python’s language semantics, but our domain-specific logging and graph augmentation allow us to inform SCARF that this operation is safe.
|
||||
|
||||
## Automating code changes
|
||||
|
||||
At Meta, we heavily automate changes to code. We built an internal service, called CodemodService, which empowers engineers to deploy configurations to automate code changes at scale. SCARF was the first instance of company-wide, fully automated code changes at Meta, and was built hand-in-hand alongside CodemodService. Today, CodemodService also powers hundreds of other types of automated code changes at Meta, from automating the formatting of code, automatically removing completed experiments, empowering large-scale API migrations, to improving coverage of strong types in partially-typed languages like Python and Hack.
|
||||
|
||||
## Dead code removal at scale
|
||||
|
||||
SCARF uses CodemodService to create code change requests for engineers to review. These change requests incorporate human-readable descriptions informing engineers about the analysis that determined the targeted code is provably dead.
|
||||
|
||||
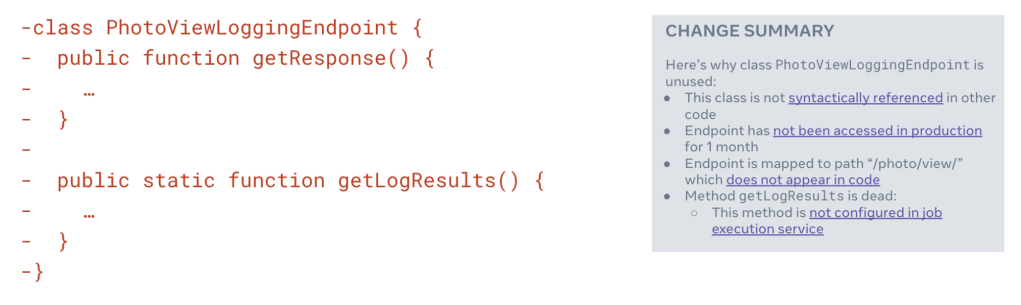
|
||||
|
||||
|
||||
SCARF has grown to analyze hundreds of millions of lines of code; and five years on, it has automatically deleted more than 100 million lines of code in over 370,000 change requests. False-positives caught by engineers during code review are triaged and used to improve the analysis that SCARF performs and typically reflect new sources of dynamic usage that our augmented graphs must account for. Sometimes these misunderstood dynamic references can lead to incorrect deletion of code, and these deletions can make it to production. Meta has [other mechanisms in place to catch these problems](https://engineering.fb.com/2017/08/31/web/rapid-release-at-massive-scale/) and we take such incidents very seriously.
|
||||
|
||||
In some languages, we have such high confidence in our analysis that we can automatically accept and merge the change requests without human intervention to make better use of engineers’ valuable time.
|
||||
|
||||
## Is dead code removal sufficient?
|
||||
|
||||
SCARF’s automated dead code removal accelerates the process of shutting down and removing the code and data for deprecated products, but it does not solve it fully. Beyond the problems caused by interconnectivity, we are constantly improving our ability to integrate across all languages, systems, and frameworks at Meta. It is difficult to accurately cover every type of usage of code and data that enables our systems to determine what is truly dead.
|
||||
|
||||
Our systems also err on the side of caution, by searching for textual references to code and data through our [BigGrep system](https://www.facebook.com/watch/?v=1911812842425144) and not solely relying on the curated graphs produced through Glean and our dynamic usage augmentations. This is a fallback safety mechanism that helps avoid accidentally deleting MySQL tables that are referenced by name in other languages and preventing deletions of dynamically invoked code in languages like Hack, Python, and JavaScript that can call code through string references or use *eval*. This approach can cause false negatives, but avoids false positives. When automating the removal of dead code, those are a more serious problem.
|
||||
|
||||
As mentioned in [our first post](https://engineering.fb.com/2023/10/17/data-infrastructure/automating-product-deprecation-meta/) of this series, SCARF provides workflow management features that work together with the dead code subsystem to provide a cohesive experience for fully deprecating products and features. Crucially, our engineers can iterate on code changes faster than our automation! If an engineer understands that a change has rendered a branch of code (and therefore an entire subgraph) unreachable, they can easily incorporate that deletion into their changes without waiting for our infrastructure to index the new code, analyze it, and eventually get around to submitting its automated changes. Engineers sometimes find it more productive to manually delete things rather than waiting to see if the automated systems will clean it up for them later.
|
||||
|
||||
In the next and final blog post in this series, which covers [automating data removal](https://engineering.fb.com/2023/10/31/data-infrastructure/automating-data-removal/), we will look at SCARF’s unused data type subsystem that Meta has built that, in conjunction with the dead code subsystem, amplifies Meta’s data minimization capabilities by automating the removal of dead and unused assets.
|
||||
13
sreweekly/markdown/398/08-kubernetes-and-kernel-panics.md
Normal file
13
sreweekly/markdown/398/08-kubernetes-and-kernel-panics.md
Normal file
@@ -0,0 +1,13 @@
|
||||
# Kubernetes And Kernel Panics
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: Kyle Anderson — Netflix
|
||||
- **链接**: https://netflixtechblog.com/kubernetes-and-kernel-panics-ed620b9c6225
|
||||
|
||||
## 简介
|
||||
|
||||
Netflix built a system that detects kernel panics in k8s nodes and annotates the resulting orphaned pods so that it’s clear what happened to them.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,13 @@
|
||||
# Webinar: Resilience Engineering in 2024: Challenges, Trends & Priorities
|
||||
|
||||
- **期号**: SRE Weekly Issue #398(2023-11-12)
|
||||
- **作者**: —
|
||||
- **链接**: https://us06web.zoom.us/webinar/register/6016990483627/WN_9f_m63fmQSCybl5iZvktEA#/registration
|
||||
|
||||
## 简介
|
||||
|
||||
This upcoming webinar will cover a range of topics around resilience engineering and incident response, with two big names we’ve seen in many past issues: Chris Evans (incident.io) and Courtney Nash (Verica).
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
Reference in New Issue
Block a user