SRE weekly 所有文章
This commit is contained in:

110
sreweekly/markdown/427/01-why-didn-t-you-status.md
Normal file
110
sreweekly/markdown/427/01-why-didn-t-you-status.md
Normal file
@@ -0,0 +1,110 @@
|
||||
# Why didn’t you status?
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Ross Brodbeck
|
||||
- **链接**: https://hross.substack.com/p/why-didnt-you-status
|
||||
|
||||
## 简介
|
||||
|
||||
Written by a GitHub employee, this article seeks to answer the titular question, with discussions of noise reduction concerns and incidents that affect only a subset of customers.
|
||||
|
||||
## 正文
|
||||
|
||||
At GitHub we [status fairly frequently](https://www.githubstatus.com/) (6 times in May so far — 18 times in April), especially compared to other providers. I often see questions from our customers (or support reps) about why we didn’t status for a particular issue or why their SLA is different from what appears on our status page.
|
||||
|
||||
Let’s take a minute to demystify this process a bit, although before I do it might be worth mentioning that we take availability (and outages) very seriously and I would hate for a post on statusing to sound like a bunch of excuses (it’s not — there is a continuous availability push at GitHub and we keep working to get better).
|
||||
|
||||
Now might also be a good time to note that views expressed here are my own and not those of my employer.
|
||||
|
||||
Here are some high level takeaways I talk about more below:
|
||||
|
||||
- Statusing is based on the amount of customer impact.
|
||||
- SLAs are not the same as status page outages.
|
||||
- Not every customer is impacted by every outage.
|
||||
|
||||

|
||||
|
||||
[GitHub status page](https://www.githubstatus.com/)as of May 2024.
|
||||
|
||||
## Why didn’t you status?
|
||||
|
||||
I get this question a lot so here’s a few reasons why we might not have statused a particular issue for a customer.
|
||||
|
||||
### The incident didn’t impact enough people.
|
||||
|
||||
This is a version of [your 9’s not being my 9’s](https://rachelbythebay.com/w/2019/07/15/giant/), but the unfortunate truth is that we do not status for every customer impacting incident. Sometimes we know about things and we still don’t status them. Why not?
|
||||
|
||||
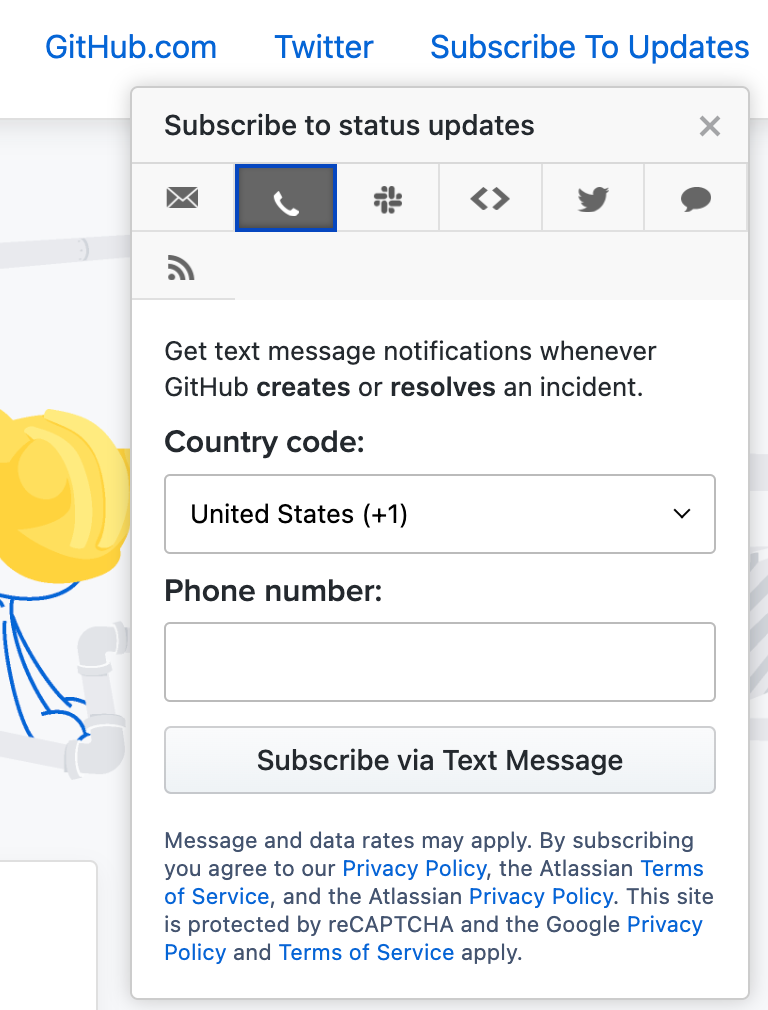
At the time I write this our status page has over 22,000 subscribers; 4,000 of whom get a text message every time we post something there. It is a blunt instrument that needs to be wielded with care. Telling 22,000 people “we have a problem!” is something we can’t take lightly or they’ll stop listening to us.
|
||||
|
||||
|
||||
|
||||
We define thresholds for impact before we declare a public incident, and there is not some nefarious reason for this like hiding incidents — it is to avoid spamming our customers with every small blip in every service. We only tell you when there are incidents that start to have broad reaching impact.
|
||||
|
||||
Does a problem with a single customer warrant a post to our status page? What about a problem impacting a feature that “makes things look weird” but doesn’t break anything? There is nuance in how we decide on posting.
|
||||
|
||||
### We missed something.
|
||||
|
||||
I’d like to think we’ve made a lot of improvements in how we measure customer impact on the various endpoints at GitHub since I’ve been here but that doesn’t mean we don’t have blind spots. Sometimes, our measurements are flawed and we don’t realize something is broken (usually at that point we get customer reports). Nowadays these cases are pretty rare, but they still happen.
|
||||
|
||||
I can at least say, with the confidence of someone who has analyzed hundreds of incidents at GitHub over the past few years, that we are much better at detecting incidents these days and it’s rare when we don’t know something is wrong. I can also say with high confidence that when we don’t detect an incident, it is one of the first things we call out as a fix in the incident review.
|
||||
|
||||
### We don’t use automation to update our public status.
|
||||
|
||||
Right now humans update our status page, not machines, and humans are slower to do things than their robot counterparts.
|
||||
|
||||
When we’re talking about 22,000 people I think that it’s important to provide information with updates and having automatic outages posted without detailed information usually confuses customers who typically want to know:
|
||||
|
||||
1. What is the actual problem and am I impacted by it?
|
||||
2. When are you going to fix it?
|
||||
|
||||
Neither of these things is easy to automate and that means we can sometimes be late to the party when we status.
|
||||
|
||||
## Why do you status so often?
|
||||
|
||||
On the other hand, I also get questions about why we status so often. Is our availability that bad? Why are there all of these incidents? Do these count against the SLA?
|
||||
|
||||
Some of our customers are large enterprises who rely on us every day and they have people who watch our status page and hold us accountable when we have incidents.
|
||||
|
||||
I wouldn’t want it any other way (it is nice to work for a company where we have a large amount of impact on the day to day of so many developers) but it does lead to questions.
|
||||
|
||||
Here are some reasons why we status more often than you might think.
|
||||
|
||||
### We maintain higher standards for statusing than our [availability SLA](https://github.com/customer-terms/github-online-services-sla).
|
||||
|
||||
Public Status does not equal SLA. This is important for a number of reasons:
|
||||
|
||||
1. I consider the SLA to be the absolute minimum bar we need to meet in order not to hand our customers money. This isn’t the bar we’re actually trying to meet for our product, **it is the absolute minimum** .
|
||||
2. We should do better than letting people know when we are hitting the absolute minimum bar for availability. If we start to detect a problem we should let people know so they can react accordingly.
|
||||
3. The SLA doesn’t cover a number of products and features ( [there are 8 broad categories listed in that document](https://github.com/customer-terms/github-online-services-sla) and 10 on our status page). Even if we don’t cover it in our SLA, we should still let customers know if it stops working.
|
||||
|
||||
### Not every customer is impacted by every outage.
|
||||
|
||||
Sometimes it can get lost that when we post to our status page we are not telling every single customer they will encounter a problem. We are telling them it’s more likely.
|
||||
|
||||
There are often incidents that do not impact certain classes of customers at all, or impact them only slightly. If you measure the raw “downtime minutes” of our status page it will give you an inaccurate impression of the actual downtime of a single customer.
|
||||
|
||||
Still, we don’t want to be [beholden to transparency calculus](https://blog.lawrencejones.dev/status-pages/) and it’s important to separate our status page from our SLA, even if it makes us “look worse”.
|
||||
|
||||
### We have hundreds of features.
|
||||
|
||||
As it turns out, we have a lot of things that can break. There are already 10 different buckets of “stuff” on our status page and that doesn’t even include email, dependabot, etc, etc.
|
||||
|
||||
We have a way to declare an incident without attaching it to a specific service which means I expect some of these features to break periodically and end up on the status page. It’s the nature of maintaining so many different features and products.
|
||||
|
||||
### We can still do better.
|
||||
|
||||
The reality is that there are still plenty of places where we can do better with our availability (and we are working diligently in those areas).
|
||||
|
||||
Ultimately, [nobody cares](https://a16z.com/nobody-cares/) about the things we are trying to fix — they want GitHub to be reliable and available all the time — and our job is to get the complex system we steward to the point where things that break have so little impact as to not be noticed by our end users.
|
||||
|
||||
## How to deal with statusing as a customer.
|
||||
|
||||
If you’re a customer it can feel pretty bad to see a service you rely on status. There are a few things you can do that might help you navigate the status page waters:
|
||||
|
||||
1. **Always file support tickets when you encounter an outage, whether it has been reported on the status page or not.** This might be intuitive, but sometimes customers assume that because we reported an outage they should not file a ticket. There are some good reasons to file support tickets: (1) we read them and compare them to outages so they will help make sure we can verify our own metrics, (2) we care about your feedback and it gets back to the engineering teams, (3) if you do encounter a time when we haven’t statused yet it is good to make sure we know.
|
||||
2. **Recognize that statusing doesn’t automatically mean impact to your day to day workflow** (sometimes it does, but you should verify). All outages are not equal and it’s important to verify how you are impacted, rather than only rely on the status page updates.
|
||||
3. **Consider your backup plan for business critical operations.** We publish an SLA to advertise our availability but some customers have higher demands than the published numbers. If you’re in that segment then you need to have a backup plan for an outage. At the least, you need to understand your dependencies and what your break glass scenarios are.
|
||||
|
||||
## Conclusion
|
||||
|
||||
It’s important to remember there are humans at both ends of the status process and we are all (hopefully) trying our best to keep our software running as best we can. While some of the trappings of SLAs and impact can get tricky, it’s important to be as transparent as possible when statusing, while still respecting the giant megaphone that it represents.
|
||||
File diff suppressed because one or more lines are too long
@@ -0,0 +1,13 @@
|
||||
# Trial by Fire: Tales from the SRE Frontlines — Ep2: The Scary ApplicationSet
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Tanat Lokejaroenlarb — Adevinta
|
||||
- **链接**: https://medium.com/adevinta-tech-blog/trial-by-fire-tales-from-the-sre-frontlines-ep2-the-scary-applicationset-ec1a2d491562
|
||||
|
||||
## 简介
|
||||
|
||||
> Understand the safeguard configuration of the ArgoCD’s ApplicationSet through the experience of our SRE who learned from an incident
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
13
sreweekly/markdown/427/04-make-two-trips.md
Normal file
13
sreweekly/markdown/427/04-make-two-trips.md
Normal file
@@ -0,0 +1,13 @@
|
||||
# Make Two Trips
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Thomas A. Limoncelli — ACM Queue
|
||||
- **链接**: http://queue.acm.org/detail.cfm?id=3664275
|
||||
|
||||
## 简介
|
||||
|
||||
Sometimes it’s better to do something in multiple passes, even if it’s less efficient. This applies to individual programs and major deployments alike.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,36 @@
|
||||
# The problem with a root cause is that it explains too much
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2024/05/26/the-problem-with-a-root-cause-is-that-it-explains-too-much/
|
||||
|
||||
## 简介
|
||||
|
||||
Another thought-provoking take on the argument that there is no one root cause.
|
||||
|
||||
## 正文
|
||||
|
||||
The recent performance of the stock market brings to mind the comment of a noted economist who was once asked whether the market is a good leading indicator of general economic activity. Wonderful, he replied sarcastically, it has predicted nine of the last four recessions. – Alfred L. Malabre Jr., 1968 March 4, The Wall Street Journal
|
||||
|
||||
|
||||
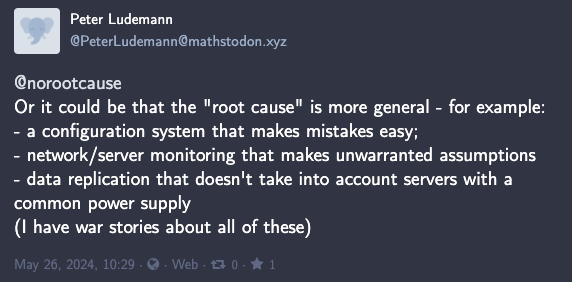
In response to my [previous post](https://surfingcomplexity.blog/2024/05/25/the-error-term-isnt-pareto-distributed/), Peter Ludemann made the [following observation](https://mathstodon.xyz/@PeterLudemann/112508573499274573) on Mastodon:
|
||||
|
||||
|
||||
|
||||
This post makes the case for why I would still call these *contributors* rather than *root causes*, even though they certainly sound root-cause-y. (They’re also fantastic examples of *risks* that are very common in the types of systems we work in, but that’s not the topic of this particular post).
|
||||
|
||||
Let’s take the first one, “a configuration system that makes mistakes easy.” I’d ask the question, “does an incident occur every single time somebody uses the configuration system?” I don’t know the details of the particular incident(s) that Peter is alluding to, but I’m willing to bet that this isn’t true. Rather, I assume what he is saying is that the configuration system is fundamentally unsafe in some way (e.g., it’s too easy to unintentionally take a dangerous action), and every once in a while a dangerous mistake would happen and an incident would occur.
|
||||
|
||||
What this means is that ***the unsafe configuration system by itself isn’t sufficient for the incident to occur***! The config system enables incidents to occur, but it doesn’t, by itself, create the incident. Rather, it’s a combination of the configuration system, and some other factors, that trigger incidents. Maybe incidents only manifests when there is a particular action a user is trying to take, or maybe some people know how to work around the sharp edges and others don’t, or other things.
|
||||
|
||||
This may sound like sophistry. After all, the configuration system is an unsafe operator interface. The lesson from an incident is that we should fix it! However, here’s the problem with that line of thinking. The truth is that there are *many* types of these sorts of problems in a system. I like to call these problems *vulnerabilities*, even though people usually reserve that term in a security context. Peter gives three examples, but our systems are really shot through with these sorts of vulnerabilities. There are all sorts of unsafe operator interfaces, [assumptions that have become invalidated with change](https://surfingcomplexity.blog/2024/03/26/the-problem-with-invariants-is-that-they-change-over-time/), dangerous potential interactions between components, and so on. These vulnerabilities are the sorts of issues that the safety researcher James Reason referred to as *latent pathogens*. Reason is the one who proposed the [Swiss cheese model](https://en.wikipedia.org/wiki/Swiss_cheese_model), with the latent pathogens being the holes in the cheese.
|
||||
|
||||
My problem with labeling these vulnerabilities as *root causes* is that this obscures how our systems actually spend most of their time up, even though these vulnerabilities are always present. Let’s say you were able to identify every vulnerability you had in a system. If you label each one as a root cause of an outage, then your system should be down all of the time, because these vulnerabilities are all present in your system!
|
||||
|
||||
But your system *isn’t* down all of the time: in fact, it’s up more often than it’s down, even though these vulnerabilities are omnipresent. ***And the reason your system is up more than it’s down is that these vulnerabilities are not, by themselves, sufficient to take down a system.*** If you label these vulnerabilities as root causes, you make it impossible to understand to how your system actually succeeds. And if you don’t know how it succeeds, you can’t understand how it fails. You’re like the economist predicting recessions that don’t happen.
|
||||
|
||||
Now, whether we label these vulnerabilities as *root causes* or not, they clearly represent a risk to your system. But we have an additional problem: [we live in the adaptive universe](https://surfingcomplexity.blog/2020/01/19/there-is-no-escape-from-the-adaptive-universe/). That means we don’t actually have the resources (in particular, the time) to identify and patch all of these vulnerabilities. And, even if we could stop the world, find them all, and fix them all, and start the world again, our system keeps changing over time, and new vulnerabilities would set in. And that doesn’t even take into account how [patching these vulnerabilities can create new ones](https://surfingcomplexity.blog/2017/06/24/a-conjecture-on-why-reliable-systems-fail/). The adaptive universe also teaches us that our work will inevitably introduce new vulnerabilities because we only have a finite amount of time to actually do that work. Mistaking problems with individual components with the general problem of finite resources is the [component substitution fallacy](https://surfingcomplexity.blog/2023/04/15/missing-the-forest-for-the-trees-the-component-substitution-fallacy/).
|
||||
|
||||
In short, labeling vulnerabilities as *root causes* is dangerous because it blinds us to the nature of how complex systems manage to stay up and running most of the time, even though vulnerabilities within the system are always with us. Now, these vulnerabilities are still risks! However, they may or may not manifest as incidents. In addition, we can’t predict which ones will bite us, and we don’t have the resources to root all of them out. We use “this just bit us so we should address it because otherwise it will bite us again” a heuristic, but it’s an implicit one. What we should be asking is “given that we have limited resources, is spending the time addressing this particular vulnerability worth the opportunity cost of delaying other work?”
|
||||
|
||||
## One thought on “The problem with a root cause is that it explains too much”
|
||||
@@ -0,0 +1,13 @@
|
||||
# Kubernetes Tip: What Happens To Pods Running On Node That Become Unreachable?
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Bhargav Bhikkaji
|
||||
- **链接**: https://medium.com/tailwinds-navigator/kubernetes-tip-what-happens-to-pods-running-on-node-that-become-unreachable-3d409f734e5d
|
||||
|
||||
## 简介
|
||||
|
||||
I referenced this at work the other day, but the interesting bit is that the pod-eviction-timeout option has been removed in Kubernetes 1.27 and I’ve had difficulty finding out what it was replaced by.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
135
sreweekly/markdown/427/07-incident-summaries-using-llms.md
Normal file
135
sreweekly/markdown/427/07-incident-summaries-using-llms.md
Normal file
@@ -0,0 +1,135 @@
|
||||
# Incident Summaries using LLMs
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Karl Stoney
|
||||
- **链接**: https://karlstoney.com/incident-summaries-using-llms/
|
||||
|
||||
## 简介
|
||||
|
||||
> How to use llama-2 7b to generate summaries of your incidents, using Cloudflare workers and Workers AI.
|
||||
|
||||
It’s a complete how-to using an open source LLM.
|
||||
|
||||
## 正文
|
||||
|
||||
# Incident Summaries using LLMs
|
||||
|
||||
How to use llama-2 7b to generate summaries of your incidents, using Cloudflare workers and Workers AI. Including Pirate mode.
|
||||
|
||||
If you've read some of my other posts such as [Alert and Incident](https://karlstoney.com/enriching-alerts-with-service-metadata/) enrichment, you'll know that we use Slack to pull together all the interested parties when we experience any sort of problem in a production environment.
|
||||
|
||||
Those channels can naturally become quite noisy as engineers discuss the problem, product folks ask for updates, etc. For anyone coming into the incident after the fact we found it could be quite an overwhelming amount of information to try and digest. We started initially by asking people to "pin" the most important lines as they go, but even that can get noisy - what we needed was a short summary.
|
||||
|
||||
## The Solution
|
||||
|
||||
If only there was a new cool trending technology that would allow us to automatically summarise a bunch of text content into an easily digestible paragraph? Oh wait, there is - [Large Language Models](https://en.wikipedia.org/wiki/Large_language_model?ref=karlstoney.com). Whilst I've been using tools such as [Copilot](https://github.com/features/copilot?ref=karlstoney.com) for a while now - with mixed results, where I've found LLM's really useful is restructuring text. I find myself regularly using [ChatGPT](https://chat.openai.com/auth/login?ref=karlstoney.com) to reword things (I've used it for some of the excerpts for articles on this site).
|
||||
|
||||
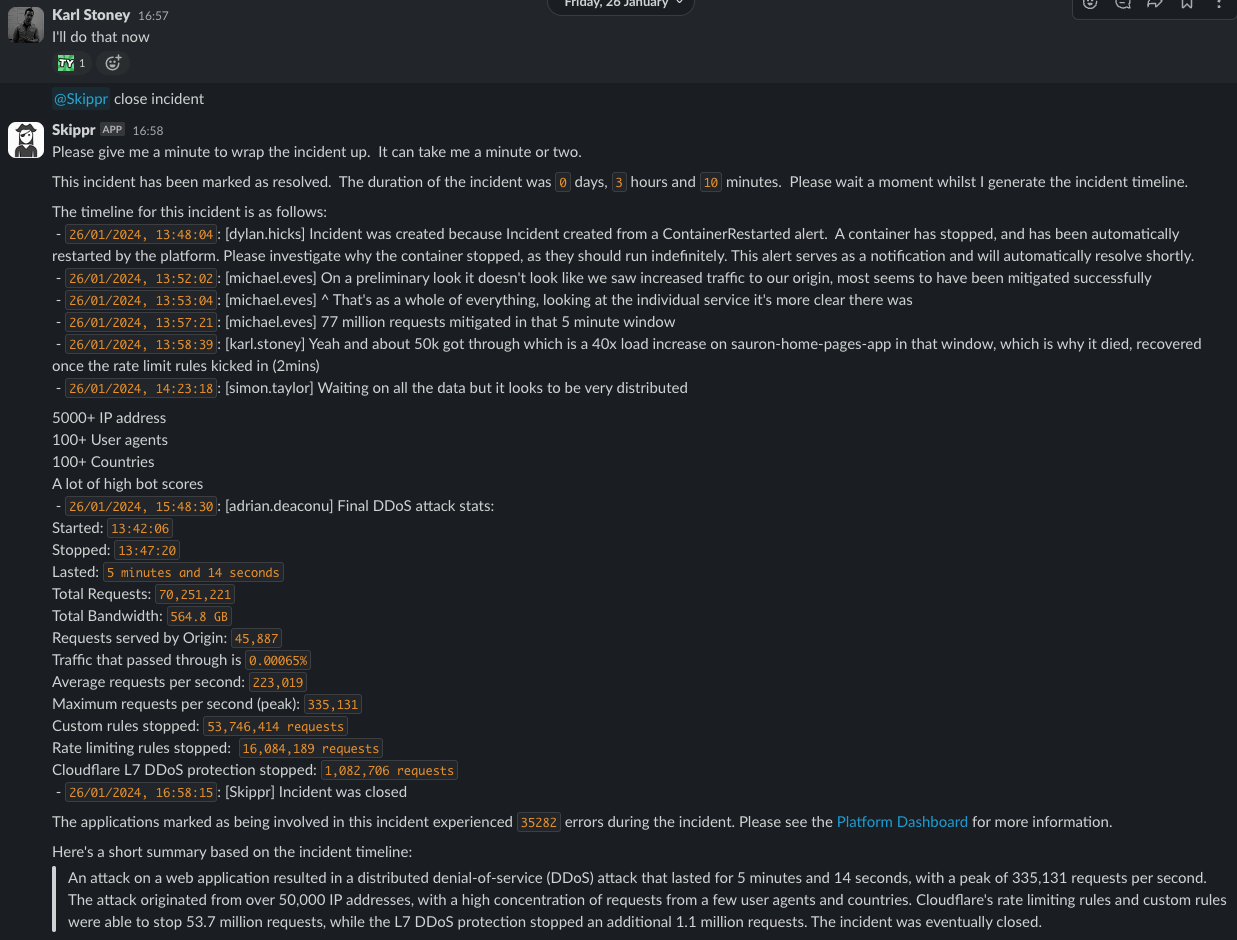
For privacy reasons I wanted to avoid using ChatGPT - so I decided to pipe the pinned timeline through an OSS LLM (llama2 7b) and ask it to generate a short paragraph. It does a pretty great job - and lets people quickly understand what happened. Here's one from when we got DDOS'd recently!
|
||||
|
||||
|
||||
|
||||
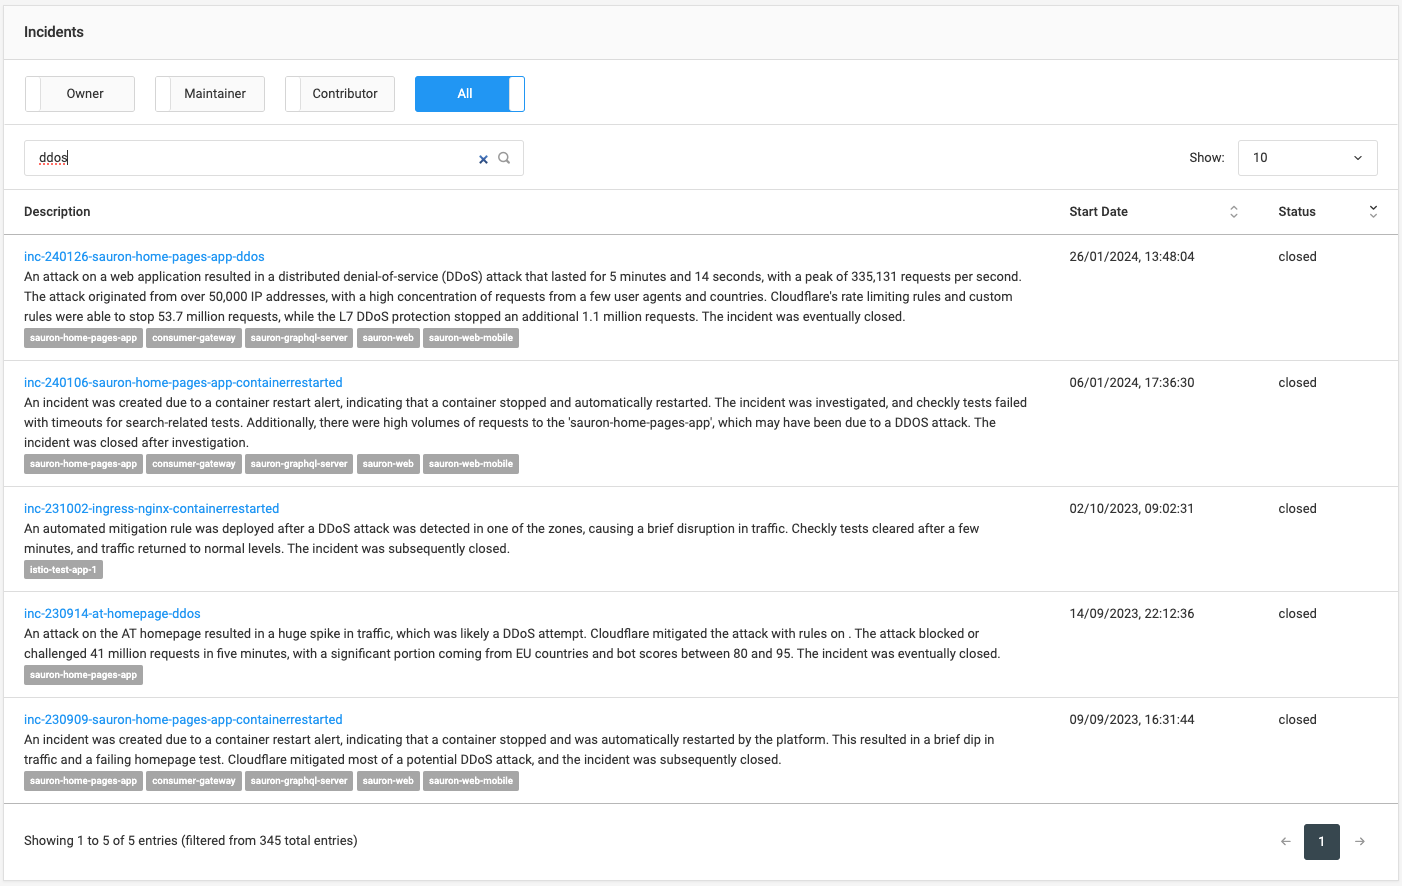
This summary is what appears when searching for Incidents on our internal dashboards:
|
||||
|
||||
|
||||
|
||||
## How to build it yourself
|
||||
|
||||
LLM's aren't new. However what's really changed over the past few years is how accessible they have become to people who have no data science background (such as myself). OSS models like [Llama-2](https://ai.meta.com/llama/?ref=karlstoney.com) appeared, and tools like [Ollama](https://ollama.ai/?ref=karlstoney.com) made is super easy to run them on your local machine. However deploying and running them was (and is) still a bit challenging, for instance - typically you'll need access to GPUs (which are actually quite expensive to provision).
|
||||
|
||||
This is where [Cloudflare Workers AI](https://developers.cloudflare.com/workers-ai/?ref=karlstoney.com) fills a gap for me. If you haven't used [Cloudflare Workers](https://developers.cloudflare.com/workers/?ref=karlstoney.com) before, I strongly suggest giving it a go. They're just lambda's integrated into your Cloudflare account behind all the other goodies you get from Cloudflare. Workers AI builds on top of that and gives you the ability to run a [collection of OSS LLMs](https://developers.cloudflare.com/workers-ai/models/?ref=karlstoney.com) in workers, on Cloudflares GPUs, and they make it as simple as invoking a function.
|
||||
|
||||
Their developer experience with [wrangler](https://developers.cloudflare.com/workers/wrangler/?ref=karlstoney.com) is exceptional and theirs a lively and active [Discord](https://discord.gg/cloudflaredev?ref=karlstoney.com) community of people working with the product. You can even develop your worker locally, run it locally, but have it execute on the remote GPU. It's pretty special.
|
||||
|
||||
### Server Side
|
||||
|
||||
I'm not going to repeat the great content already available on Cloudflares website for setting up a basic project with wrangler, you can read it [here](https://developers.cloudflare.com/workers-ai/get-started/workers-wrangler/?ref=karlstoney.com). It's super simple and will take you all of 5 minutes.
|
||||
|
||||
Once you've got a basic project up and running, you can create an API endpoint that runs `llama2-7b` in just a few lines of code:
|
||||
|
||||
```
|
||||
import { Ai } from '@cloudflare/ai'
|
||||
import { Hono } from 'hono'
|
||||
export type Bindings = {
|
||||
AI: Ai
|
||||
}
|
||||
const app = new Hono<{ Bindings: Bindings }>()
|
||||
app.post('/ml/question', async (c) => {
|
||||
const { text } = await c.req.json()
|
||||
if (!text) {
|
||||
return new Response('No text provided', { status: 400 })
|
||||
}
|
||||
const ai = new Ai(c.env.AI)
|
||||
const prompt: string[] = [
|
||||
'My name is Skippr and I help with Software Engineering problems.',
|
||||
'I do not ask questions, I only respond to prompts. I never suggest follows up questions.',
|
||||
'My answers are concise and to the point, I do not guess.'
|
||||
]
|
||||
const messages = [
|
||||
...prompt.map((item) => ({ role: 'assistant', content: item })),
|
||||
{ role: 'user', content: text }
|
||||
]
|
||||
const output = await ai.run('@cf/meta/llama-2-7b-chat-fp16', {
|
||||
messages
|
||||
})
|
||||
return new Response(JSON.stringify(output))
|
||||
})
|
||||
```
|
||||
The key things here:
|
||||
|
||||
- I'm using [hono](https://hono.dev/?ref=karlstoney.com) for routing. Think express, just slimmed down for the edge.
|
||||
- I'm creating a `POST` endpoint,`/ml/question` which expects a json payload with`content`
|
||||
- I'm adding some content to the prompt which is appended as an `assistant` role on each request. This is where you can tweak how you want your bot to respond.
|
||||
- I build up my prompts and pass them to the Workers AI function `ai.run`
|
||||
|
||||
You can run this locally with `wrangler dev --remote`, the `--remote` part here tells wrangler to execute the function on Cloudflares remote infra/gpus. It does so completely transparently to you - it really is a first class developer experience.
|
||||
|
||||
At this point we have an endpoint that you can post a question to, and get a response:
|
||||
|
||||
```
|
||||
curl -H "content-type: application/json" -XPOST -d '{"text":"hi, what is your name?"}' http://127.0.0.1:8787/ml/question
|
||||
{"response":"My name is Skippr."}
|
||||
```
|
||||
Pretty dam cool hey? [Get it deployed](https://developers.cloudflare.com/workers/get-started/guide/?ref=karlstoney.com#4-deploy-your-project) and lets move onto the client side.
|
||||
|
||||
### Client Side
|
||||
|
||||
This, and the `assistant` context above, fall very much into the realms of [prompt engineering](https://www.mckinsey.com/featured-insights/mckinsey-explainers/what-is-prompt-engineering?ref=karlstoney.com), which is the practice of crafting your inputs to LLMs to get the desired output. I've crudely found you just need to iterate over different structures of inputs to get the output you desire.
|
||||
|
||||
In our case, we just wanted to get the pinned items from the channel. So when the incident was closed via the `@Skippr close incident` command, we use the slack [conversations.history](https://api.slack.com/methods/conversations.history?ref=karlstoney.com) command to retrieve the content of the channel, and then filtered it for the pinned items. We then mapped that into a timeline that looks something like this:
|
||||
|
||||
```
|
||||
[hh:mm:ss] An incident was created by user-1, because reason
|
||||
[hh:mm:ss] [user-1] Pinned item from what user1 said
|
||||
[hh:mm:ss] [user-2] Pinned item from what user2 said
|
||||
[hh:mm:ss] An incident was closed
|
||||
```
|
||||
Our prompt was then the above information, wrapped in `"`, followed by our request, for example:
|
||||
|
||||
```
|
||||
"[hh:mm:ss] An incident was created by user-1, because reason
|
||||
[hh:mm:ss] [user-1] Pinned item from what user1 said
|
||||
[hh:mm:ss] [user-2] Pinned item from what user2 said
|
||||
[hh:mm:ss] An incident was closed"
|
||||
This was a timeline of an incident that is now closed, please summarise the timeline above in one paragraph of about 100 words without quoting dates or times:
|
||||
```
|
||||
This is what we would then send as the `text` field on the body of our request to our `/ml/question` endpoint:
|
||||
|
||||
```
|
||||
{
|
||||
response: 'An incident was created by user-1 due to a reason. User-1 then pinned an item from what user-1 said. Later, user-2 pinned an item from what user-2 said. Finally, the incident was closed.'
|
||||
}
|
||||
```
|
||||
Wonderful! Give it a go yourself, experiment with different prompts, experiment with asking for outputs for different personas perhaps? Have you ever wanted to take technical output but make it less-technical for business stakeholders? Put that in your prompt. Want your incident summaries in pirate form? Easy:
|
||||
|
||||
```
|
||||
{
|
||||
response: 'Arrrr, here be the timeline of the incident, me hearty! User-1 created the incident because of a reason, then user-2 pinned an item from what user-1 said. Later, user-2 pinned an item from what user-2 said, and then the incident be closed! Yarrr, a fine summary of the timeline, me matey!'
|
||||
}
|
||||
```
|
||||
## Conclusion
|
||||
|
||||
I think of LLMs as somewhat of a black box, as a more typical software engineer - it's quite alien to me to have a function of which I don't understand the internals, that gives me a non-deterministic output, that can be influenced by the structure of my input which is just free form text. As a result I can't really write tests that assert on the output, and that makes me uncomfortable using them for anything more "serious" right now. There are plentiful amounts of examples where unbounded [chat bots have gone of the rails](https://news.sky.com/story/dpd-customer-service-chatbot-swears-and-calls-company-worst-delivery-service-13052037?ref=karlstoney.com). I'll be interested to see how testing / building confidence in the outputs evolves. This is likely where the folks with more of a data science background will shine!
|
||||
|
||||
But don't let any of that put you off, as you can see here - with minimal effort - using platforms such as Cloudflare Workers AI, you can get stuck in yourself.
|
||||
|
||||

|
||||
@@ -0,0 +1,42 @@
|
||||
# Incident 2023-12-04: Data leak and loss in some free tier databases
|
||||
|
||||
- **期号**: SRE Weekly Issue #427(2024-06-02)
|
||||
- **作者**: Turso
|
||||
- **链接**: https://turso.tech/blog/incident-2023-12-04-data-leak-and-loss-in-some-free-tier-databases-7cba5bc7
|
||||
|
||||
## 简介
|
||||
|
||||
Here’s a great incident writeup from last December that I came across this week.
|
||||
|
||||
By the way, if you see or write an incident followup post, I’d be grateful if you sent a link my way!
|
||||
|
||||
## 正文
|
||||
|
||||
Data leak and loss in some free tier databases on 2023-12-04
|
||||
|
||||
0.07% of databases under management were incorrectly configured with an empty backup identifier, which caused a data leak. The conservative fix we applied to the leak, lead to the possible loss of the most recent data in those databases.
|
||||
|
||||
A change that made possible for the empty backup identifier to be used was made to the system on November 20th. On December 1st, internal procedures led to those backups being used to recreate the databases. This was noticed and reported on December 4th 8:10 AM UTC, and fixed on December 4th 9:17 AM UTC.
|
||||
|
||||
Databases on Turso's free tier may scale to zero after one hour of inactivity. They are scaled back to one automatically upon receiving a network request. Usually this is completely invisible to the users, except for added latency on the initial request.
|
||||
|
||||
However, in rare situations, our cloud provider ([fly.io](http://fly.io/)) is unable to restore the process due to lack of resource availability in the host. In those cases, we destroy the machine and recreate it from the S3 backup. Each database has a separate backup identifier, through which we know which snapshot to restore.
|
||||
|
||||
From time to time, we migrate databases to newer version. A bug in that process caused some databases created to use an empty backup identifier. Effectively, the databases in that small set were now sharing a backup storage bucket. In effect, instead of pointing to `s3://bucket/backup_id/`, the affected databases were pointing to `s3://bucket//`.
|
||||
|
||||
When some databases failed to scale back to one, recreation happened from a shared location, the null ID. This caused both the data loss and data leak mentioned above.
|
||||
|
||||
We fixed the issue, by re-running the migration with the correct parameters and recreating the affected databases with their December 1st backup from the correct backup ID. Since we considered any data past December 1st to be shared between those databases, any writes done after that point were discarded.
|
||||
|
||||
We were able to determine all databases pointing to an invalid and shared backup ID by querying metadata for databases with the faulty backup ID. We could also scan our object store buckets and verify that no other databases were affected.
|
||||
|
||||
While we know the root cause quite well by now, there are still a few things we must do to ensure this never happens again. Some of these things are internal processes and others are improving our current mechanisms. In both of these cases, we take this very seriously and have diverted a majority of our engineering efforts to prevent any future data loss and data leaks. Preventing these is the #0 goal for Turso.
|
||||
|
||||
While we have not fully reviewed every piece of code related to the incident we have already identified a few big ticket items that we have already fixed and/or plan on fixing ASAP. As part of that we expect the following changes:
|
||||
|
||||
- Additional internal checks from both our control plane and data plane to ensure backup's are for the correct database. This also means improving the data isolation in our backups similar to how we have data isolation for our running databases.
|
||||
- Improve our ability to check for faulting configuration and to self heal or notify a team member that there is an issue so we can fix it. Essentially have a narrower band of allowed configurations and to be more strict by default.
|
||||
- Improve our deployment methods to prevent migrations from breaking backup ID's.
|
||||
- Add better mechanisms for being notified of security incidents either via twitter or via email at ([security@turso.tech](mailto:security@turso.tech) ). Please reach out if you notice anything!
|
||||
|
||||
We are embarrassed for this incident and the pain that it has caused our customers and our team. We have and will be implementing improved processes to prevent this in the future, but we need to be more rigorous going forward about how we handle data and the practices we use to prevent these issues. This will have my full attention and priority going into the new year as we plan to provide better features for data isolation and multi-tenancy. Thanks to [Schlez](https://twitter.com/galstar) for notifying us and allowing us to get to a solution quickly. We hope we can regain some of the trust from the community going forward.
|
||||
Reference in New Issue
Block a user