SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,286 @@
|
||||
# Automate Rotating Credentials using Terraform
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Andy Leap — Mixpanel
|
||||
- **链接**: https://engineering.mixpanel.com/automate-rotating-credentials-using-terraform-b0e7dab4d793
|
||||
|
||||
## 简介
|
||||
|
||||
This article shows how to use timed_rotating and multirotate_set to regularly rotate credentials using Terraform.
|
||||
|
||||
## 正文
|
||||
|
||||
# Automate Rotating Credentials using Terraform
|
||||
|
||||
At Mixpanel, keeping your data secure is of the utmost importance. We strictly adhere to security best practices, including rotating credentials often. Anyone who has to rotate credentials periodically knows that, without automation, it can be a super time consuming task. This article will discuss our novel approach to automating credential rotations using terraform.
|
||||
|
||||
## Rotation == Toil
|
||||
|
||||
Without any automation in place, rotating credentials is pure toil. You have to have an engineer go in and create a new credential and then update everything that uses it regularly. If the credentials don’t expire, you don’t have a strong incentive to be diligent. If they do expire, you are deliberately scheduling a future outage. Obviously, both of these options are bad. As an engineer on the DevInfra team at Mixpanel, one of my main enemies is toil. So any kind of “oh, we should manually update a dozen or more secrets with new credentials every month” is just antithetical to my very role.
|
||||
|
||||
So let’s start working on how we can automate this process.
|
||||
|
||||
## Terraform
|
||||
|
||||
Terraform is the bog standard way of automating anything involving cloud platforms, so it seems like an obvious choice for this stuff. Let’s ensure that, though, so we’ll start by setting up an example for testing. We run on GCP, so GCP service accounts are commonly used for giving services access to various GCP resources, as well as for allowing external services to reach into our GCP stuff on our behalf.
|
||||
|
||||
We’ll create a simple service account:
|
||||
|
||||
```
|
||||
resource "google_service_account" "rotation-test" {
|
||||
account_id = "rotation-test"
|
||||
display_name = "Rotation Test Account"
|
||||
}
|
||||
```
|
||||
and create a service account key for that account
|
||||
|
||||
```
|
||||
resource "google_service_account_key" "rotation-test" {
|
||||
service_account_id = google_service_account.rotation-test.id
|
||||
}
|
||||
```
|
||||
Run `terraform plan` on this, and you get:
|
||||
|
||||
```
|
||||
# google_service_account.rotation-test will be created
|
||||
+ resource "google_service_account" "rotation-test" {
|
||||
+ account_id = "rotation-test"
|
||||
+ disabled = false
|
||||
+ display_name = "Rotation Test Account"
|
||||
+ email = (known after apply)
|
||||
+ id = (known after apply)
|
||||
+ member = (known after apply)
|
||||
+ name = (known after apply)
|
||||
+ project = "mixpanel-tools"
|
||||
+ unique_id = (known after apply)
|
||||
}
|
||||
# google_service_account_key.rotation-test will be created
|
||||
+ resource "google_service_account_key" "rotation-test" {
|
||||
+ id = (known after apply)
|
||||
+ key_algorithm = "KEY_ALG_RSA_2048"
|
||||
+ name = (known after apply)
|
||||
+ private_key = (sensitive value)
|
||||
+ private_key_type = "TYPE_GOOGLE_CREDENTIALS_FILE"
|
||||
+ public_key = (known after apply)
|
||||
+ public_key_type = "TYPE_X509_PEM_FILE"
|
||||
+ service_account_id = (known after apply)
|
||||
+ valid_after = (known after apply)
|
||||
+ valid_before = (known after apply)
|
||||
}
|
||||
Plan: 2 to add, 0 to change, 0 to destroy.
|
||||
```
|
||||
So we can apply this and export that private_key field to somewhere and we’ve got our service account. We’ll go ahead and throw that in now:
|
||||
|
||||
```
|
||||
resource "google_secret_manager_secret" "rotation-test" {
|
||||
secret_id = "rotation-test-key"
|
||||
replication {
|
||||
auto {}
|
||||
}
|
||||
}
|
||||
resource "google_secret_manager_secret_version" "rotation-test" {
|
||||
secret = google_secret_manager_secret.rotation-test.id
|
||||
secret_data = google_service_account_key.rotation-test.private_key
|
||||
}
|
||||
```
|
||||
And after planning and applying, we have a service account with a key, with the credentials loaded into GCP secrets manager. But this key is static, and we need to rotate it. Simple thing first, we can just taint the service account key in terraform
|
||||
|
||||
`terraform taint google_service_account_key.rotation-test`
|
||||
Plan that and apply it:
|
||||
|
||||
```
|
||||
google_service_account_key.rotation-test: Destroying... [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/e7e71f25bfa52b39bef5273387e1f1be5b218b02]
|
||||
google_secret_manager_secret.rotation-test: Creating...
|
||||
google_service_account_key.rotation-test: Destruction complete after 0s
|
||||
google_service_account_key.rotation-test: Creating...
|
||||
google_secret_manager_secret.rotation-test: Creation complete after 0s [id=projects/mixpanel-tools/secrets/rotation-test-key]
|
||||
google_service_account_key.rotation-test: Creation complete after 0s [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/3dd8bd10e9a34ca4b0b115caef84311f5151ba31]
|
||||
google_secret_manager_secret_version.rotation-test: Creating...
|
||||
google_secret_manager_secret_version.rotation-test: Creation complete after 1s [id=projects/839233470602/secrets/rotation-test-key/versions/1]
|
||||
```
|
||||
and we’ve got a new key. But this is manual effort, so how can we automate this? Well, Terraform has a bunch of providers, including some that aren’t actually managing any kind of external resources, like the Time provider, which has a `time_rotating` resource. Reading the description, it seems ideal, so let’s try it out (with a very fast rotation, so I don’t spend weeks/months writing this post)
|
||||
|
||||
```
|
||||
resource "time_rotating" "rotation-test" {
|
||||
rotation_minutes = 5
|
||||
}
|
||||
resource "google_service_account_key" "rotation-test" {
|
||||
service_account_id = google_service_account.rotation-test.id
|
||||
keepers = {
|
||||
rotation = time_rotating.rotation-test.id
|
||||
}
|
||||
}
|
||||
```
|
||||
Applying this will immediately trigger the creation of a new service account key and update the secret with the new value
|
||||
|
||||
```
|
||||
google_secret_manager_secret_version.rotation-test: Destroying... [id=projects/839233470602/secrets/rotation-test-key/versions/1]
|
||||
google_secret_manager_secret_version.rotation-test: Destruction complete after 0s
|
||||
google_service_account_key.rotation-test: Destroying... [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/3dd8bd10e9a34ca4b0b115caef84311f5151ba31]
|
||||
google_service_account_key.rotation-test: Destruction complete after 0s
|
||||
time_rotating.rotation-test: Creating...
|
||||
time_rotating.rotation-test: Creation complete after 0s [id=2024-07-24T20:12:33Z]
|
||||
google_service_account_key.rotation-test: Creating...
|
||||
google_service_account_key.rotation-test: Creation complete after 1s [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/03f5bc6e8d62bc30b4739c6016374d0608053bc4]
|
||||
google_secret_manager_secret_version.rotation-test: Creating...
|
||||
google_secret_manager_secret_version.rotation-test: Creation complete after 0s [id=projects/839233470602/secrets/rotation-test-key/versions/2]
|
||||
```
|
||||
And then, after a little over 5 minutes we plan and apply again
|
||||
|
||||
```
|
||||
google_secret_manager_secret_version.rotation-test: Destroying... [id=projects/839233470602/secrets/rotation-test-key/versions/2]
|
||||
google_secret_manager_secret_version.rotation-test: Destruction complete after 0s
|
||||
google_service_account_key.rotation-test: Destroying... [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/03f5bc6e8d62bc30b4739c6016374d0608053bc4]
|
||||
google_service_account_key.rotation-test: Destruction complete after 0s
|
||||
time_rotating.rotation-test: Creating...
|
||||
time_rotating.rotation-test: Creation complete after 0s [id=2024-07-24T20:18:29Z]
|
||||
google_service_account_key.rotation-test: Creating...
|
||||
google_service_account_key.rotation-test: Creation complete after 1s [id=projects/mixpanel-tools/serviceAccounts/rotation-test@mixpanel-tools.iam.gserviceaccount.com/keys/5d7dee0097010a88a1792f3fb79423ea6a0f0f77]
|
||||
google_secret_manager_secret_version.rotation-test: Creating...
|
||||
google_secret_manager_secret_version.rotation-test: Creation complete after 0s [id=projects/839233470602/secrets/rotation-test-key/versions/3]
|
||||
```
|
||||
Success! Terraform is rotating our service account key automatically for us!
|
||||
|
||||
## Invalidation
|
||||
|
||||
Unfortunately, now we run into a rather thorny issue, invalidation. Terraform immediately destroys the old service account key and creates a new one, which means that anything using that secret loses access to our project until it gets the updated credentials. If you are using Kubernetes, pods can take up to a minute to update secrets. [External Secrets Operator](https://external-secrets.io/) (which we use) can add up to an hour on top of that. Furthermore, some services might only load the secret on startup. This all boils down to our initial path causing outages every time it rotates the credential.
|
||||
|
||||
The common fix here is to have 2 (or more) credentials, rotating them in an offset pattern, and using whichever is the newest at all times. That way, when you update, you are invalidating the older key, which is (hopefully) not in use anymore, and creating a new key, which is now passed out to all the services.
|
||||
|
||||
Let’s implement this:
|
||||
|
||||
```
|
||||
resource "time_rotating" "rotation-test" {
|
||||
count = 2
|
||||
rotation_minutes = 5
|
||||
}
|
||||
resource "google_service_account_key" "rotation-test" {
|
||||
count = 2
|
||||
service_account_id = google_service_account.rotation-test.id
|
||||
keepers = {
|
||||
rotation = time_rotating.rotation-test[count.index].id
|
||||
}
|
||||
}
|
||||
locals {
|
||||
older = timecmp(time_rotating.rotation-test[0].id, time_rotating.rotation-test[1].id) > 0 ? 1 : 0
|
||||
}
|
||||
resource "google_secret_manager_secret_version" "rotation-test" {
|
||||
secret = google_secret_manager_secret.rotation-test.id
|
||||
secret_data = google_service_account_key.rotation-test[local.older].private_key
|
||||
}
|
||||
```
|
||||
This technically works, though it’s… not fun to set up, as initially on applying, the keys will rotate simultaneously, so you don’t get any benefit. You can do a custom import on the rotating_time objects to get them offset, or just wait half the period and `terraform state rm time_rotating.rotation-test[1]` to force it to rotate early and thus offset them, but there’s a deeper issue here. The `time_rotating` resource doesn’t rotate on a fixed schedule, i.e. 1:00:00PM then 1:05:00PM then 1:10:00PM, but instead considers the planning time as the start of a new rotation period. If the first one was at 1:00:00PM, but you don’t plan/apply again til 1:05:30PM, the next expiration will be 1:10:30PM, not 1:10:00PM. This can compound over time, til you potentially wind up with both keys rotating at the same time again, which then becomes an outage, and a particularly nasty one as you’ve probably got something doing those apply operations automatically (which we do, I’ll circle back to that later)
|
||||
|
||||
How do we fix this? I did a bunch of research, and… couldn’t find any answers. Plenty of threads about other people running into the same issues, but no solutions in sight. So I did what any sane engineer would do…
|
||||
|
||||
## We wrote a Terraform provider: multirotate_set
|
||||
|
||||
We released a Terraform provider to plug all the aforementioned gaps once and for all:[multirotate_set](https://registry.terraform.io/providers/mixpanel/multirotate/latest/docs/resources/set)
|
||||
|
||||
Let’s put our new `multirotate_set` resource into play:
|
||||
|
||||
```
|
||||
resource "multirotate_set" "rotation-test" {
|
||||
rotation_period = "5m"
|
||||
number = 2
|
||||
}
|
||||
resource "google_service_account_key" "rotation-test" {
|
||||
count = 2
|
||||
service_account_id = google_service_account.rotation-test.id
|
||||
keepers = {
|
||||
rotation = multirotate_set.rotation-test.rotation_set[count.index].expiration
|
||||
}
|
||||
}
|
||||
resource "google_secret_manager_secret_version" "rotation-test" {
|
||||
secret = google_secret_manager_secret.rotation-test.id
|
||||
secret_data = google_service_account_key.rotation-test[multirotate_set.rotation-test.current_rotation].private_key
|
||||
}
|
||||
```
|
||||
A bit simpler than the `time_rotating` shenanigans. And after 5 minutes, we get:
|
||||
|
||||
```
|
||||
# multirotate_set.rotation-test will be updated in-place
|
||||
resource "multirotate_set" "rotation-test" {
|
||||
! current_rotation = 1 -> 0
|
||||
! last_rotate = "2024-07-24T20:52:25Z" -> "2024-07-24T20:57:25Z"
|
||||
rotation_set = [
|
||||
{
|
||||
! creation = "2024-07-24T20:47:25Z" -> "2024-07-24T20:52:42Z"
|
||||
! expiration = "2024-07-24T20:52:25Z" -> "2024-07-24T21:02:25Z"
|
||||
# (1 unchanged attribute hidden)
|
||||
},
|
||||
# (1 unchanged element hidden)
|
||||
]
|
||||
# (3 unchanged attributes hidden)
|
||||
}
|
||||
```
|
||||
along with the service account key being recreated, and the secret value updating. Success! Again!
|
||||
|
||||
## Enhancement: Expiration
|
||||
|
||||
One thing that’s missing, in my eyes, is key expiration. This is more of an optional thing, but it does look better on audits and is more of a forcing function to make sure you are rotating keys. This is starting to get into the specifics of GCP + Terraform, but let’s carry on and get it done.
|
||||
|
||||
First up: GCP won’t create an expiring service account key for you, so you’re stuck doing things manually, but that’s what Terraform is for. Start with a private key.
|
||||
|
||||
```
|
||||
resource "tls_private_key" "rotation-test" {
|
||||
count = 2
|
||||
algorithm = "RSA"
|
||||
rsa_bits = 2048
|
||||
lifecycle {
|
||||
replace_triggered_by = [multirotate_set.rotation-test.rotation_set[count.index]]
|
||||
}
|
||||
}
|
||||
```
|
||||
The private key triggers the rotation, as we want a brand new key each time. Next up, generate a self-signed cert.
|
||||
|
||||
```
|
||||
resource "tls_self_signed_cert" "rotation-test" {
|
||||
count = 2
|
||||
private_key_pem = tls_private_key.rotation-test[count.index].private_key_pem
|
||||
subject {
|
||||
common_name = "unused"
|
||||
}
|
||||
validity_period_hours = 1
|
||||
allowed_uses = [
|
||||
"key_encipherment",
|
||||
]
|
||||
}
|
||||
```
|
||||
Note that you want the validity period to be longer than the rotation period, so the key stays valid. Next up, pass that off to Google.
|
||||
|
||||
```
|
||||
resource "google_service_account_key" "rotation-test" {
|
||||
count = 2
|
||||
service_account_id = google_service_account.rotation-test.id
|
||||
public_key_data = base64encode(tls_self_signed_cert.rotation-test[count.index].cert_pem)
|
||||
}
|
||||
```
|
||||
And the final step, where it gets a little more complex as Google isn’t doing it for you: Build a credentials file to use, and stick it somewhere. (GCP secrets manager in this case)
|
||||
|
||||
```
|
||||
resource "google_secret_manager_secret_version" "rotation-test" {
|
||||
secret = google_secret_manager_secret.rotation-test.id
|
||||
secret_data = jsonencode({
|
||||
type : "service_account",
|
||||
project_id : resource.google_service_account.rotation-test.project,
|
||||
"private_key_id" : resource.tls_private_key.rotation-test[multirotate_set.rotation-test.current_rotation].id,
|
||||
"private_key" : resource.tls_private_key.rotation-test[multirotate_set.rotation-test.current_rotation].private_key_pem,
|
||||
"client_email" : resource.google_service_account.rotation-test.email,
|
||||
"client_id" : resource.google_service_account.rotation-test.unique_id,
|
||||
"auth_uri" : "<https://accounts.google.com/o/oauth2/auth>",
|
||||
"token_uri" : "<https://oauth2.googleapis.com/token>",
|
||||
"auth_provider_x509_cert_url" : "<https://www.googleapis.com/oauth2/v1/certs>",
|
||||
"client_x509_cert_url" : "<https://www.googleapis.com/robot/v1/metadata/x509/${resource.google_service_account.rotation-test.email}>"
|
||||
})
|
||||
}
|
||||
```
|
||||
And there you go! Rotating, expiring credentials without outages. As long as you keep on top of applying the terraform regularly of course.
|
||||
|
||||
## Automation
|
||||
|
||||
It is trivial to set up a GitHub Action or some other kind of cron job to automate running terraform apply on a regular schedule. You could definitely stop there and you can consider your problem solved. However, definitely wanted to call out a SaaS tool we use that makes this automation super trival: [Terrateam](https://terrateam.io/). With Terrateam, all we had to do to start rotating our credentials automatically was flip on [drift detection and auto reconciliation](https://terrateam.io/features/drift), and bing bang boom, our credentials get automatically rotated regularly. No more toil.
|
||||
|
||||
Before tackling this credential rotation automation problem, we had already deployed [Terrateam](https://terrateam.io/) to help us scale our Terraform usage to meet the needs of 70+ engineers working in a monorepo. By enabling a gitops style Terraform workflow, we’ve completely sidestepped all the issues that come with multiple devs stepping on each other’s toes trying to make changes to terraform configurations at the same time. Terrateam has been great a great partner in deploying Terraform at scale, I’m always happy to recommend them whenever given the opportunity to do so!
|
||||
|
||||
If you enjoy eliminating toil like we did in this blog — Mixpanel engineering is [hiring](https://mixpanel.com/jobs/)!
|
||||
119
sreweekly/markdown/438/02-making-room-for-some-lint.md
Normal file
119
sreweekly/markdown/438/02-making-room-for-some-lint.md
Normal file
@@ -0,0 +1,119 @@
|
||||
# Making Room for Some Lint
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Fred Hebert — HoneycombFull disclosure: Honeycomb is my employer.
|
||||
- **链接**: https://www.honeycomb.io/blog/making-room-for-lint
|
||||
|
||||
## 简介
|
||||
|
||||
After an incident involving a database schema change, this engineer created a linting system for schema changes to catch painful ones that would cause a full table rewrite.
|
||||
|
||||
## 正文
|
||||
|
||||
# Making Room for Some Lint
|
||||
|
||||
It’s one of my strongly held beliefs that errors are constructed, not discovered. However we frame an incident’s causes, contributing factors, and context ends up influencing the shape of the corrective items (if any) that get created. I’ll cover these ideas by using our June 3rd incident where a database migration caused a large outage by locking up a shared database and making it run out of connections.
|
||||
|
||||

|
||||
|
||||
By: [Fred Hebert](https://www.honeycomb.io/author/fred-hebert)
|
||||
|
||||
|
||||
|
||||
It’s one of my strongly held beliefs that errors are constructed, not discovered. However we frame an incident’s causes, contributing factors, and context ends up influencing the shape of the corrective items (if any) that get created. I’ll cover these ideas by using our June 3rd incident where a database migration caused a large outage by locking up a shared database and making it run out of connections.
|
||||
|
||||
## **The incident—and the potential for blame**
|
||||
|
||||
From our [short public review](https://status.honeycomb.io/incidents/z1ptbq6mz65y), this element came out as most significant:
|
||||
|
||||
The migration involved was related to modifying an ENUM set on a database table, which unexpectedly caused a full table rewrite. It had previously run without issue on smaller databases, leading to a false sense of security. Additionally, two prior changes to the same ENUM field had not caused any performance issues. After the restart we made sure that data integrity was properly maintained, that all caches were properly aligned, and that the overall migration could safely complete. We are currently looking at strengthening our ability to spot risky migrations ahead of time (regardless of how well they worked on other databases in other environments).
|
||||
|
||||
Each Honeycomb engineer who writes a database migration is responsible for shepherding it through the stages. As they write it, it gets applied in their own dev environment, and on the CI suites to run all the usual tests. They get a code review, and once the code is merged, it gets applied to at least four environments automatically: Dogfood (which monitors production) and Kibble (which monitors Dogfood) in both our US and EU regions. Once they have succeeded, the engineer can then run a command to apply the migration in the production environments.
|
||||
|
||||
Basically, there is a process, there are validation and verification checks, and there’s someone looking at what happens. Yet, things still break from time to time. If we were to look for a quick solution, it would be easy to think that some things were lacking, that someone missed something. To name a few potential ones:
|
||||
|
||||
- The engineer who wrote the migration possibly wasn’t thorough enough or knowledgeable enough
|
||||
- The engineers who reviewed the pull request possibly weren’t paying enough attention or knowledgeable enough
|
||||
- The engineers who wrote or reviewed the pull request possibly weren’t the right people to do the job
|
||||
- The organization as a whole did not provide enough training or guidance
|
||||
|
||||
These are classic diagnoses, and some were brought up in the midst of the incident: teams with more SQL expertise weren’t on the reviewer list due to a code owner’s misconfiguration. The risky pattern itself (editing an ENUM in a non-additive manner) was sort of a surprise to everyone involved, but we could have been satisfied with our review simply by spreading the knowledge about it and enforcing reviews by experts.
|
||||
|
||||
However, database migrations have been a risk for a long while at Honeycomb, as they have in multiple other organizations. Some database migrations we ran in the past straight up failed, hung, caused outages, or in some cases triggered rare bugs in whatever version of MySQL we were running that created extended performance degradation.
|
||||
|
||||
While there are approaches that structurally reduce the likelihood of such issues (“store data differently”) or others that can provide better safety nets (“have a better load simulation environment”), they tend to be rather costly for uncertain benefits—would a new data store have no trade-offs? Would a better test environment actually catch these issues with low maintenance overheads?
|
||||
|
||||
New to Honeycomb? Get your **free account** today.
|
||||
|
||||
## **On-call week is for ops work**
|
||||
|
||||
A suggestion made by someone years ago was that we should lint MySQL migrations. Some patterns are bound to be risky, and these could be detected as part of continuous integration to warn people, particularly since for the entire history of Honeycomb, all database schema changes have been numbered and versioned. [Linting](<https://en.wikipedia.org/wiki/Lint_(software)>) provides a cheap feedback loop, requires little setup, and can capture risky patterns even if they aren’t all covered.
|
||||
|
||||
Maybe the increased confidence of a linter saying “this is okay” could be good enough. There’s always a risk that safety nets provide a false sense of trust for, but that false sense of trust is often there: we don’t know what we don’t know, and because not everyone knows the same stuff, we often get surprised either way.
|
||||
|
||||
There was an easy way to find out: I was [on call](https://www.honeycomb.io/blog/tracking-on-call-health) the week after the incident and I had this in mind. One of the policies Honeycomb has is that **whenever you’re on call, you don’t do project work. The on-call engineer’s job, aside from escalations and incidents, is to make on-call better for everyone**. The end result of this is that if you’re on call, and have a bit of downtime, you’re free to explore solutions and improvements, paying down forms of [tech debt](https://www.honeycomb.io/blog/anything-but-tech-debt) you think impact reliability, write documentation, or improve instrumentation. Anything you can point at and say “this should make on-call easier” may fit in that week.
|
||||
|
||||
That let me give myself the mandate of just seeing what could be done and experimenting, [regardless of the action items](https://ferd.ca/the-review-is-the-action-item.html).
|
||||
|
||||
## **Setting up the linter**
|
||||
|
||||
After researching and eliminating many candidates, we settled on [Atlas](https://atlasgo.io/versioned/lint), which has a full SaaS offering, but also has [offline community editions](https://atlasgo.io/community-edition)—which we chose to use. They have a [full list of checks](https://atlasgo.io/lint/analyzers#checks), some of which are specifically related to the ENUM issue we saw.
|
||||
|
||||
The problem upon trying it was that the linter did not detect the issue. It just took the migrations and said they were all fine. That is, a migration like this
|
||||
|
||||
```
|
||||
ALTER TABLE test
|
||||
-- assume the enum is currently specified as ENUM('A', 'B', 'C', 'D')
|
||||
CHANGE enum_col enum_col ENUM('A', 'B', 'C') NOT NULL DEFAULT 'A';
|
||||
```
|
||||
would succeed every time. What I found out is that as Atlas connected to an empty database to run tests, we could force it to complain by mandating an algorithm:
|
||||
|
||||
```
|
||||
ALTER TABLE test
|
||||
-- assume the enum is currently specified as ENUM('A', 'B', 'C', 'D')
|
||||
CHANGE enum_col enum_col ENUM('A', 'B', 'C') NOT NULL DEFAULT 'A',
|
||||
ALGORITHM=INPLACE;
|
||||
```
|
||||
With this specification, we then get warnings such as:
|
||||
|
||||
```
|
||||
Error: executing statement: Error 1846 (0A000): ALGORITHM=INPLACE is
|
||||
not supported. Reason: Cannot change column type INPLACE. Try ALGORITHM=COPY.
|
||||
```
|
||||
This is a bit of a cheat that relies on specifying algorithms for DDL operations:
|
||||
|
||||
- INSTANT means the operations only modify metadata in the data dictionary. An exclusive metadata lock on the table may be taken briefly during the execution phase of the operation. Table data is unaffected, making operations instantaneous.
|
||||
- INPLACE means the operations avoid copying table data but may rebuild the table in place. An exclusive metadata lock on the table may be taken briefly during preparation and execution phases of the operation. Typically, concurrent operations (INSERT, UPDATE, DELETE) are supported.
|
||||
- COPY means operations are performed on a copy of the original table, and table data is copied from the original table to the new table row by row. Concurrent operations (INSERT, UPDATE, DELETE) are not permitted.
|
||||
|
||||
Basically, any COPY operation on either a large table or a table used in a lot of queries will likely hang a production database and should be rethought.
|
||||
|
||||
So what we did is simply add a little script that checks that any ALTER TABLE statement specifies an algorithm that is not COPY. This makes the linter check effective and ensures we won’t interrupt production transactions with migrations.
|
||||
|
||||
## **Working around it**
|
||||
|
||||
The thing with automation of this kind is that it can do a great job at spotting common issues, but a terrible one at properly handling subtle elements that can be contextual.
|
||||
|
||||
Most good linters have syntactic rules in place that let you override its values and checks. Atlas has simple ones that disable rules piecemeal by putting them right before a statement, so we added a way to disable the ALGORITHM check mentioned earlier. Statements like the following can be added to any migration file:
|
||||
|
||||
```
|
||||
-- precheck:nolint algorithm // can be put anywhere before a statement
|
||||
-- atlas:nolint CHECK_A [CHECK_B ... CHECK_N] // must be right before a statement
|
||||
```
|
||||
These are “acknowledgements” of whatever the linter told you before you merge your migration. We trust people to make the right calls, and if it turns out to be surprising, we’ll also be around to help fix whatever happens.
|
||||
|
||||
All this information is in a document right next to the linter’s code. Our biggest problem right now is tying the visible linter error to the relevant information in our internal documentation.
|
||||
|
||||
## **Knowing, as an organization**
|
||||
|
||||
Since we only see a few migrations a year that cause problems, we haven’t yet had the opportunity to see the new linter capture anything, aside from it having asked a few people to explicitly put in their algorithm annotation, and to acknowledge some risks.
|
||||
|
||||
However, it seems like an interesting balance between the proactive (but prohibitively costly) approach of training everyone to become SQL experts, and an ever-forgiving approach of letting people be surprised by production changes and then doing the repair work. Linting finds a decent spot in the middle—and for cheap—and as such, it may plug some holes more effectively than other methods.
|
||||
|
||||
Overall, I still feel that the best driver for improvements like this is **having the latitude to take ownership and implement these experiments**.
|
||||
|
||||
There’s always a little something wrong with systems. Sometimes your on-call shift is spent working on fixing urgent stuff, but some weeks are eerily calm. What are you going to do during your next, *calmer* on-call shift? Let us know in [Pollinators](https://docs.honeycomb.io/troubleshoot/community/), our Slack community!
|
||||
|
||||
## Want to know more?
|
||||
|
||||
Talk to our team to arrange a custom demo or for help finding the right plan.
|
||||
@@ -0,0 +1,107 @@
|
||||
# From four to five 9s of uptime by migrating to Kubernetes
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Matheus Lichtnow — WorkOS
|
||||
- **链接**: https://workos.com/blog/from-four-to-five-9s-of-uptime-by-migrating-to-kubernetes
|
||||
|
||||
## 简介
|
||||
|
||||
Finding Heroku and alternative services lacking for various reasons, these folks built their own Heroku-like platform on top of Kubernetes and migrated their service to it.
|
||||
|
||||
## 正文
|
||||
|
||||
# From four to five 9s of uptime by migrating to Kubernetes
|
||||
|
||||
When we launched User Management along with a free tier of up to 1 million MAUs, we faced several challenges using Heroku: the lack of an SLA, limited rollout functionality, and inadequate data locality options. To address these, we migrated to Kubernetes on EKS, developing a custom platform called Terrace to streamline deployment, secret management, and automated load balancing.
|
||||
|
||||
## User Management and Scale
|
||||
|
||||
In 2023 we launched [WorkOS User Management](https://workos.com/docs/user-management) with a free tier that includes 1 million monthly active users. We quickly realized that Heroku couldn't support a vision that big. Here are the four biggest challenges we faced:
|
||||
|
||||
- No SLA — Heroku does not provide an SLA, making it much more difficult for us to provide one to our customers.
|
||||
- Limiting rollout functionality — With the 99.99% of uptime target, we needed a platform that could both quickly rollout a new version and support more sophisticated rollout strategies, such as blue/green and canary deployments.
|
||||
- Security — Heroku’s Private Spaces run within AWS VPCs, but given its platform nature, it is very difficult to address vectors of attack. [See Heroku’s most recent severe incident](https://status.heroku.com/incidents/2413) .
|
||||
- Fine grained data locality — While Heroku allows apps to be deployed in multiple regions, they will always lag behind in availability when compared to the underlying Infrastructure as a Service (IaaS), which is AWS.
|
||||
|
||||
Since the initial stages of the migration, we sought for a platform that would allow us to customize it to fit our needs. We knew that the migration was going to be a risky and lengthy process, and we wanted to do it only once, so any custom bits we needed, we could either reach for OSS or build it ourselves.
|
||||
|
||||
We evaluated various vendors, including ECS, OpenShift, Render, and fly.io, to see if they could meet our needs. While each had promising features, they either lacked one of our key requirements or didn't offer the customization tools we wanted. Ultimately, we chose Kubernetes on EKS as the underlying platform.
|
||||
|
||||
## Our Own Kubernetes Flavor
|
||||
|
||||
Our main goal with this new platform was to create a seamless, efficient way to deploy new services. We wanted the "golden path" to be fast and easy, and even when deviating from it, the experience would remain user-friendly.
|
||||
|
||||
To provide this experience to our users, we built Terrace, a Heroku like platform on top of EKS that allowed engineers to create their own apps in TypeScript without having to learn about the nooks and crannies of Kubernetes.
|
||||
|
||||
The team had mixed experiences with Kubernetes, and one key lesson we learned was to avoid having special clusters, meaning treating them like cattle, not pets. Clusters can break, and when they do, the remediation that follows can be painful. To address this, we aimed to use Terraform for our clusters, making it easy, fast, and automated to bring them up or down. This included both the clusters themselves and their Operators and Controllers.
|
||||
|
||||
With clusters up and running, we identified the functionalities in Heroku that we wanted to replicate in Terrace.
|
||||
|
||||
### Secret Injection
|
||||
|
||||
Heroku has the concept of [Config Vars](https://devcenter.heroku.com/articles/config-vars), which are key value pairs that are injected as environment variables into each app. It also offers the functionality to synchronize these values from 3rd party vendors, such as AWS SSM, Doppler and Vault. We wanted to maintain this ability, which can be summarized in two steps:
|
||||
|
||||
1. Synchronize secrets through the integration
|
||||
2. Rollout new replicas with the updated secrets
|
||||
|
||||
First, we decided to use the [External Secrets Operator](https://external-secrets.io/latest/), which allows us to pull secrets from multiple vendors and inject them as Secret resources in our clusters.
|
||||
|
||||
Next, we went with [Reloader](https://docs.stakater.com/reloader/). This Kubernetes Controller watches for changes in Secret resources and triggers rolling upgrades on the tied Workloads.
|
||||
|
||||
The final workflow should feel familiar to engineers, as it is similar to how Heroku operates. Engineers will update the secrets in the third-party vendor, which will then sync with the Secret resources in the clusters and trigger a rolling upgrade on the corresponding workload.
|
||||
|
||||
### Automated Load Balancing, TLS and DNS
|
||||
|
||||
Choosing the right Ingress Controller is a common topic when migrating to Kubernetes since there are a lot of different implementations, each one focusing on specific use cases ([curated list by The Kubernetes Authors](https://kubernetes.io/docs/concepts/services-networking/ingress-controllers/)). We ended up choosing the [AWS Application Load Balancer Controller](https://kubernetes-sigs.github.io/aws-load-balancer-controller/v2.8/) for its robust EKS integration and automated TLS management by leveraging its [AWS Certificate Manager integration](https://kubernetes-sigs.github.io/aws-load-balancer-controller/v2.8/guide/ingress/annotations/#certificate-arn). This meant that we could automatically spin up load balancers with their TLS certificates getting automatically renewed.
|
||||
|
||||
On the DNS side, we wanted our CNAME records to be automatically created and synced with whatever records the load balancers had, so we leveraged the [ExternalDNS controller](https://kubernetes-sigs.github.io/external-dns/v0.14.2/). This detects the hosts present on the rules of each Ingress resource and creates the appropriate DNS records in the configured DNS provider.
|
||||
|
||||
### Machine Provisioning
|
||||
|
||||
When using an IaaS abstraction like Heroku, we wanted to avoid thinking about provisioning machines to run our apps. For example, if we had to scale it to a million replicas, the platform should do the heavy lifting and give us the hardware to run it. There were two options to address this: [Cluster Autoscaler](https://github.com/kubernetes/autoscaler/tree/master/cluster-autoscaler) and [Karpenter](https://karpenter.sh/). We decided to go with the latter due to its more complete feature set and documentation.
|
||||
|
||||
### Application Management
|
||||
|
||||
Although the `kubectl` CLI is in a very good state today, managing complex apps can become very difficult. We evaluated two options for managing our apps, [ArgoCD](https://argo-cd.readthedocs.io/en/stable/) and [Argonaut](https://www.argonaut.dev/). We decided to go with ArgoCD on this one due to its extension capabilities and maturity as a solution.
|
||||
|
||||
With the necessary tools in place, we faced another important decision: should our infrastructure team manage every service, or should we make it self-serve for other teams? To decide, we considered our team sizes and our automation goals. We chose the self-serve option, but with clearly defined escape hatches. This approach would create an abstraction layer for most engineers to work with, while still allowing them to manage their own Kubernetes tasks if needed.
|
||||
|
||||
### The Path to Self Serving
|
||||
|
||||
The abstraction we chose was similar to Heroku’s Apps and Processes, where each App could contain multiple processes that would be deployed to multiple clusters. Since our codebase is mostly done with TypeScript, we decided to go with the same tech stack. Enter [cdk8s](https://cdk8s.io/), which is a tool that allows writing Kubernetes resources in multiple languages, including TypeScript.
|
||||
|
||||
Here's the flow we envisioned for generating the Kubernetes manifests:
|
||||
|
||||

|
||||
|
||||
This direction provided us with more flexibility for building apps when compared to other popular solutions like Helm. This meant that instead of just templating, we had all of the Node.js ecosystem at our disposal, so customizing each app was easy. This is especially true with cdk8s, since its own abstraction allows us to attach any Kubernetes resources to its [Chart](https://cdk8s.io/docs/latest/basics/chart/) object.
|
||||
|
||||
With our abstraction on top of cdk8s done, all that was left was a way to get the generated Kubernetes resources from our apps to be managed by ArgoCD, our application manager. We had two options here, either a Git artifact repository where we would push changes on every deploy or extending ArgoCD and make it understand cdk8s. Since automation was a general theme of this migration, we went with latter. Luckily, ArgoCD was just moving its [Sidecar Plugin](https://argo-cd.readthedocs.io/en/stable/operator-manual/config-management-plugins/#sidecar-plugin) functionality out of beta, which we took advantage of.
|
||||
|
||||
For the Sidecar Plugin to work, we had to first build a Docker image with the proper [Config Management Plugin](https://argo-cd.readthedocs.io/en/stable/operator-manual/config-management-plugins/#write-the-plugin-configuration-file) file located at `/home/argocd/cmp-server/config/plugin.yaml` and add it as a sidecar container of ArgoCD’s Repo Server. Here’s an example `plugin.yaml` file:
|
||||
|
||||
Now we can build the Docker image with the YAML file above and attach it as a sidecar container in ArgoCD’s Repo Server:
|
||||
|
||||
Follow by adding the Docker image above as an ArgoCD’s Repo Server sidecar container:
|
||||
|
||||
Now you are able to create an ArgoCD Application resources using the new plugin. Here’s how it looks like:
|
||||
|
||||
For further configuration on how to leverage parameters and environment variables in the plugin, check out [ArgoCD’s docs](https://argo-cd.readthedocs.io/en/stable/operator-manual/config-management-plugins/#sidecar-plugin).
|
||||
|
||||
## Migration and Results
|
||||
|
||||
During the migration process, we decided to do two different types of load tests in our apps. We started out with short bursts of requests and after making sure that it was working properly on those scenarios, we performed soak tests that mimicked the network traffic we had in production. The idea here was to understand how normal operations, such as deployments, including ones that could bring the service down, would impact the system reliability.
|
||||
|
||||
During the soak tests, we discovered some configurations that needed tweaking. More importantly, we gained the ability to fully understand what was happening throughout our system. With Heroku, we struggled with observability because most of the stack was a black box to us. Now, we can identify and understand all the failure modes in our system.
|
||||
|
||||
After the migration, our uptime improved significantly, from four nines to consistently achieving five nines over 7 and 30-day periods across all services. This increase is directly related to our improved ability to gain insights from our systems and fine-tune them accordingly.
|
||||
|
||||
Another factor enhancing our system's reliability is the speed at which we can roll out changes. On Heroku, deploying a new version could take up to 12 minutes. In Terrace, new versions are rolled out in just 2-3 minutes. This speed difference can elevate uptime from three to four nines in a 7-day window.
|
||||
|
||||
## The Future of Terrace
|
||||
|
||||
Reflecting on our initial goals, the only need we haven't yet implemented is deploying to different data localities. However, we have the capability to achieve this easily, so it will be our focus in the near future.
|
||||
|
||||
Currently, we use rolling updates for rollouts. While this approach allows us to move quickly, we want to ensure that critical paths in our product remain bug-free and reliable. To achieve this, we plan to experiment with blue/green and canary deployment strategies.
|
||||
|
||||
Additionally, our strategy with ArgoCD’s Sidecar Plugin has some downsides, particularly with ArgoCD’s UI. The UI can feel sluggish because it attempts to go through the plugin flow on page loads within the Application view. To address this, we plan to build a Terrace Operator. This operator will apply a single [Custom Resource](https://kubernetes.io/docs/concepts/extend-kubernetes/api-extension/custom-resources/) containing all the app and process definitions, and then create all the necessary resources for them to work efficiently.
|
||||
@@ -0,0 +1,51 @@
|
||||
# What every SRE should know about GNU/Linux resolvers and Dual-Stack applications
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Viacheslav Biriukov
|
||||
- **链接**: https://biriukov.dev/docs/resolver-dual-stack-application/0-sre-should-know-about-gnu-linux-resolvers-and-dual-stack-applications/
|
||||
|
||||
## 简介
|
||||
|
||||
It’s anything but simple to handle IPv4 and IPv6 in your service. This article covers the nitty-gritty details including dual-stack resolvers and Happy Eyeballs.
|
||||
|
||||
## 正文
|
||||
|
||||
#
|
||||
What every SRE should know about GNU/Linux resolvers and Dual-Stack applications
|
||||
[#](https://biriukov.dev#what-every-sre-should-know-about-gnulinux-resolvers-and-dual-stack-applications)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
**Contents**
|
||||
|
||||
In this series of posts, I’d like to make a deep dive into the GNU/Linux local facilities used to convert a domain name or hostname into IP addresses, specifically in the context of dual-stack applications. This process of resolution is one of the oldest forms of networking abstraction, designed to replace hard-to-remember network addresses with human-readable strings. Although it may seem simple at first glance, the entire process involving stub resolvers is filled with complexities and subtle nuances. One contributing factor to this complexity is the growing number of IPv6 addresses, which, although not increasing at the pace everyone might want, is gradually changing servers and clients to support dual-stack hosts. Thus a seamless transition to IPv6 become an important feature and should occur without degrading user experience or increasing response latency.
|
||||
|
||||
|
||||
|
||||
[\[©\]](https://www.cyberciti.biz/humour/a-haiku-about-dns/)
|
||||
|
||||
We will start with a brief history of resolvers, exploring how they evolved, the issues and problems that the `getaddrinfo()` aims to resolve, and what happens under the hood: how it interacts with the name service switch (`NSS`), caches results, and aids in building applications suited for a dual-stack world with both IPv4 and IPv6 address families. This abstraction and address-agnostic approach are essential to modern software development, and a sloppy implementation can lead to subtle bugs that are hard to debug in production. That’s why we will cover the dual stack applications more thoroughly from both client and server perspectives, trying to understand the order of using available destination addresses from a list of IPv4 and IPv6 addresses, and exploring algorithms to improve response latency in cases of network routing instability or misconfiguration.
|
||||
|
||||
We will also examine the most feature-rich alternative `C` language resolver, `c-ares`, discussing its potential advantages and why you might consider using it. However, our discussion will not be limited to `C` stub resolvers; we will also cover mainstream languages such as `Python`, `Go` (`Golang`), `Rust`, `Java`, and `NodeJS`, focusing on their internals, decisions and trade-offs.
|
||||
|
||||
Another important topic is how to configure and manage `/etc/resolv.conf` on modern GNU/Linux systems. At first glance, managing `/etc/resolv.conf` might seem straightforward – simply add a nameserver and a search domain. But when a system has multiple physical interfaces (e.g., LAN and WiFi) and several virtual ones such as VPN tunnels, all configured with DHCP clients, the situation becomes more complex. Each DHCP server might provide its own nameservers and a search domain, necessitating some logic to coordinate and reconcile these changes. Modern GNU/Linux distributions usually employ `systemd-resolved` to address this issue, and we will explore its capabilities.
|
||||
|
||||
As usual, we will touch on related topics to dual-stack programs, such as IPv4-mapped addresses, different ways to bind sockets for dual-stack servers, and how `systemd` can help manage listener sockets.
|
||||
|
||||
After we have gained a complete understanding of the resolving process, tools, and solutions, we will examine several popular load balancers: Nginx, Envoy (Envoyproxy), and HAProxy. These are excellent examples because they are designed to be dual-stack for both clients (downstreams) and backends (upstreams).
|
||||
|
||||
Finally, we’ll review some new and advanced topics not always directly related to a local stub resolver and dual stack applications but certainly important for domain name resolution and promising in terms of refining the resolving process in various directions: DNS push notifications, the new DNS resource record HTTPS, DNS over TLS (DoT), DNS over HTTPS (DoH), oblivious DNS (ODNS), and DNSSEC.
|
||||
|
||||
But before we kick off, here is some preparational information.
|
||||
|
||||
##
|
||||
Setup playground
|
||||
[#](https://biriukov.dev#setup-playground)
|
||||
|
||||
All examples in this series are runnable and represent real, working code. To follow along and experiment with the code effectively – a great way to learn – you’ll need a setup similar to mine. I use the latest LTS [Ubuntu 24.04](https://releases.ubuntu.com/noble/) cloud image on my macOS, managed under the [lima](https://github.com/lima-vm/lima) project, which allows me to run Linux containers.
|
||||
|
||||
For testing domain name resolution, I’m using “`microsoft.com`” for all tests because it provides multiple `A` and `AAAA` records. Additionally, its DNS server shuffles records with every call, which can help easily determine if the answer is served from the cache or not.
|
||||
|
||||
[Read next chapter →](https://biriukov.dev/docs/resolver-dual-stack-application/1-what-is-a-stub-resolver/)
|
||||
@@ -0,0 +1,84 @@
|
||||
# Thankful for incidents: embracing chaos to find clarity
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Shayon Mukherjee
|
||||
- **链接**: https://www.tines.com/blog/engineering-incidents-improvement/
|
||||
|
||||
## 简介
|
||||
|
||||
What’s great about an incident? It helps uncover latent flaws in your system, as happened to these folks during a Redis upgrade.
|
||||
|
||||
## 正文
|
||||
|
||||
**In this blog post, Tines software engineer Shayon Mukherjee shares how lessons from a recent incident led to improved platform resilience and more comprehensive testing practices.**
|
||||
|
||||
It was a typical late June afternoon when we embarked on what seemed a routine Redis cluster upgrade across approximately 40 customer stacks. The upgrade was essential, influenced by a previous outage that highlighted the risks of not using more robust instances and better networking support on those instance types.
|
||||
|
||||
This wasn't the first time we performed such an upgrade, nor is it going to be the last time. But little did we know that this upgrade would soon reveal an unseen issue that lay dormant, undetected, and ready to teach us a valuable lesson.
|
||||
|
||||
A few moments into the upgrade process, our monitoring systems flagged the Toolkit API Down alarm. [__Tines Toolkit__](https://www.tines.com/blog/introducing-the-tines-toolkit/) is a Tines [__response-enabled webhooks__](https://www.tines.com/docs/actions/types/webhook#response-enabled-webhooks)-powered service. This alert was the first signal of something amiss. The webhooks were timing out, [__affecting crucial customer workflows__](https://status.tines.com/incidents/jgXSym). The immediate response was swift - our engineers triggered a force deployment to flush out any bad state from our containers, bringing things back online within a few minutes. But this was just the beginning. Now we needed to understand what had actually happened.
|
||||
|
||||
### [**How does it all work?**](https://www.tines.com#how-does-it-all-work)
|
||||
|
||||
**How does it all work?**
|
||||
|
||||
In our system, [__response-enabled webhooks__](https://www.tines.com/docs/actions/types/webhook#response-enabled-webhooks) play a critical role, especially in how they interact with Redis Pub/Sub to manage real-time data flows. Before we dive further into the bug, let's take a quick minute to understand the system first.
|
||||
|
||||
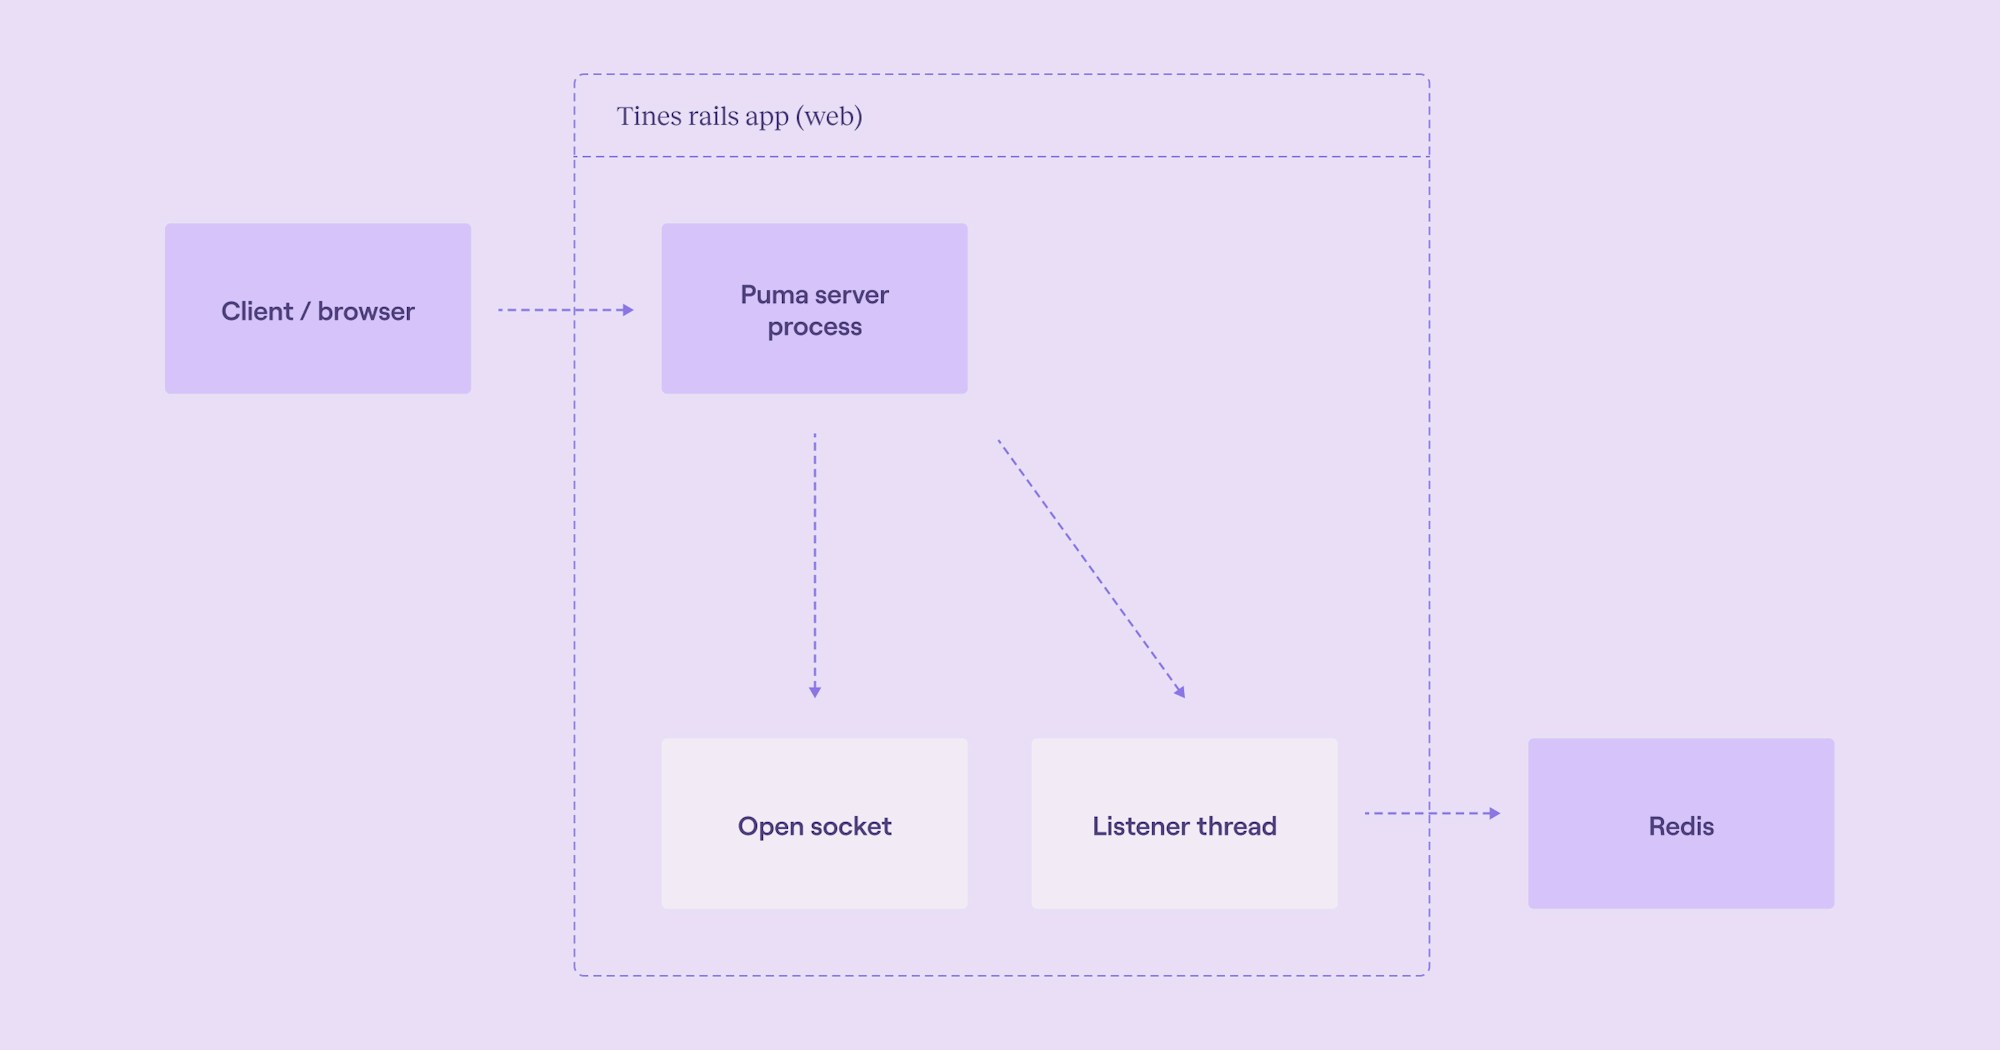
Our application is built using [__Ruby on Rails__](https://rubyonrails.org/), with [__Puma__](https://github.com/puma/puma) as our web server and [__Rack__](https://github.com/rack/rack) as the web server interface. For [__response-enabled webhooks__](https://www.tines.com/docs/actions/types/webhook#response-enabled-webhooks), we use a technique known as Socket Hijacking to make async webhooks function like synchronous ones.
|
||||
|
||||
When a webhook request is received, Rack performs what's known as “Full Socket Hijacking.” This process closes the Rails response object, which frees up the request handling thread (inside Puma) to return to the pool of available workers while maintaining the socket connection to the client. This allows the Puma server to accept new web requests without blocking the response for the synchronous webhook, all the while keeping the socket connection open with the client to return a response once it is available.
|
||||
|
||||
Another important part of this system is a simple Redis Pub/Sub implementation running from a dedicated listener thread inside the web server. When a webhook is received, we enqueue the relevant Tines Action Run and open a Redis subscription (from the thread) to listen for the event received when the Tines story exit action generates the response. We then proxy it back to the client.
|
||||
|
||||
|
||||
|
||||
## [**The hidden bug**](https://www.tines.com#the-hidden-bug)
|
||||
|
||||
**The hidden bug**
|
||||
|
||||
Normally, this dedicated listener thread maintains a persistent connection with Redis to receive and process messages. However, during the upgrade, it encountered connectivity issues, and without any system alerts or logs, the Redis persistent connection died. This failure is one of those classic cases of "the server is running but nothing is working,” just a quiet stoppage that gradually led to service degradation as new webhook requests could no longer be processed.
|
||||
|
||||
It took us a while to reach this conclusion. It required an examination of logs, reading the code, formulating hypotheses, and running some controlled failure cases. We were eventually able to recreate the scenario both locally and in production, and felt confident that this failure mode was the primary contributing factor to the incident.
|
||||
|
||||
This incident highlighted something in our system’s architecture: a lack of a good error handling or recovery mechanism for the webhook's listener thread during Redis connectivity or similar issues.
|
||||
|
||||
This oversight meant that a single point of failure could lead to disruptions in our production environment, a lesson that was both surprising and invaluable for our ongoing efforts to build a more resilient platform.
|
||||
|
||||
|
||||
### [**Lessons from the incident**](https://www.tines.com#lessons-from-the-incident)
|
||||
|
||||
**Lessons from the incident**
|
||||
|
||||
This incident, albeit stressful, was a blessing in disguise. It exposed a critical vulnerability in how our webhook system was designed. The reliance on a single listener thread without a robust fail open mechanism was something that we had overlooked. But thanks to this incident, it was brought to light under circumstances that allowed us to respond without major consequences.
|
||||
|
||||
We learned that our preparations for zero-downtime capabilities during Redis updates were incomplete. We had not considered [__response-enabled webhooks__](https://www.tines.com/docs/actions/types/webhook#response-enabled-webhooks) in our chaos testing scenarios. This incident was a good reminder of the importance of comprehensive testing and the need for a holistic view of system dependencies and resilience, particularly for non-traditional parts of our system that might not be well-understood.
|
||||
|
||||
### [**Embracing the incident**](https://www.tines.com#embracing-the-incident)
|
||||
|
||||
**Embracing the incident**
|
||||
|
||||
Incidents happen to everyone, but how you deal with them and learn from them is what counts. What stands out about incidents like these is not just the immediate impact or the technical breakdowns but the invaluable insight they provide into our systems.
|
||||
|
||||
Each incident, especially one that uncovers fundamental flaws, is an opportunity to improve, harden our systems, and ensure better service for our users.
|
||||
|
||||
|
||||
They push us to think creatively about solutions and to fortify areas we hadn't even considered before.
|
||||
|
||||
### [**Action items**](https://www.tines.com#action-items)
|
||||
|
||||
**Action items**
|
||||
|
||||
While we’re happy that our automated monitoring caught the issue and we were able to mitigate the incident in a very short period, we still want to strive for more. We’ve already ensured the singleton thread acts in a reconciliation loop so that it can withstand similar issues in the future.
|
||||
|
||||
We’re committed to improving our resilience across the board. To achieve this, we’ll be conducting periodic and controlled chaos testing, which will include actions like taking down both our primary and ephemeral data stores to ensure that critical Tines workflows remain unaffected. This process should not only allow us to uncover more hidden unknowns like the ones we saw above but also catch regressions in our tooling and practices as we scale.
|
||||
|
||||
### [**Reflecting on the incident**](https://www.tines.com#reflecting-on-the-incident)
|
||||
|
||||
**Reflecting on the incident**
|
||||
|
||||
As we continue to build and maintain complex software systems, incidents like these are not just inevitable, they’re necessary.
|
||||
|
||||
|
||||
They teach us about our systems' resilience, the effectiveness of our responses, and the areas that need more attention. They force us to confront the realities of our designs and our decisions.
|
||||
|
||||
So, in a way, we should be thankful for each incident. After all, each one gives us a chance to be better than we were the day before. Let's be thankful for these incidents - they are, indeed, our best friends in the ever-evolving landscape of complex systems.
|
||||
@@ -0,0 +1,145 @@
|
||||
# Managing Vendor Incidents: Customer Impact That Isn’t Your Fault
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Mandi Walls — PagerDuty
|
||||
- **链接**: https://www.pagerduty.com/blog/managing-vendor-incidents/
|
||||
|
||||
## 简介
|
||||
|
||||
Tips on how to handle vendor incidents, from runbooks to incident management and post-incident review.
|
||||
|
||||
## 正文
|
||||
|
||||
|
||||
|
||||
- [PagerDuty](https://www.pagerduty.com/) /
|
||||
- [Blog](https://www.pagerduty.com/blog) /
|
||||
- [Incident Management & Response](https://www.pagerduty.com/blog/category/incident-management-response/) /
|
||||
- Managing Vendor Incidents: Customer Impact That Isn’t Your Fault
|
||||
|
||||
# Blog
|
||||
|
||||
# Managing Vendor Incidents: Customer Impact That Isn’t Your Fault
|
||||
|
||||
[Mandi Walls](https://www.pagerduty.com/blog/author/mwalls/)August 8, 2024 | 9 min read
|
||||
|
||||
One of the first key tenets of cloud computing was that “you own your own [availability](https://www.whoownsmyavailability.com/)”, the idea being that the public cloud providers were making infrastructure available to you, and your organization had to decide what to use and how to use it in order to meet your organization’s goals. The cloud providers have no knowledge of your applications or their KPIs.
|
||||
|
||||
Over the last 10 years or so, more organizations have become increasingly more reliant on cloud computing facilities and other SaaS providers for many core functions of their technical stack. That’s been great! Teams get to focus on the core business features that create value and provide an individual business with revenue without worrying about many of the more mundane requirements of their tech stack.
|
||||
|
||||
This dependence has brought risk. Cloud providers have experienced outages due to [configuration errors](https://www.cnbc.com/2021/12/09/how-the-aws-outage-wreaked-havoc-across-the-us.html), [distributed denial of service attacks](https://www.forbes.com/sites/kateoflahertyuk/2024/07/31/microsoft-confirms-new-outage-was-triggered-by-cyberattack/) (DDOS), and even [catastrophic fires](https://www.datacenterdynamics.com/en/analysis/ovhcloud-fire-france-data-center/).
|
||||
|
||||
How should a team handle an incident that lies with an upstream provider? What can we bring from our experiences handling our own incidents?
|
||||
|
||||
We won’t be able to fix these types of incidents on our own. Many teams will have to sit and wait out the problem. Others will weigh the cost of a migration or failover, and some will have already done so by the time the rest of us notice there’s an issue.
|
||||
|
||||
**Who Owns the Vendor Relationship During an Incident?**
|
||||
|
||||
Managing vendor relationships often falls to a procurement, finance, or legal team. So much of vendor management is about contracts, payment terms, and SLAs. During a vendor incident, though, the teams integrating directly with the vendor’s products need to be in the loop for vendor communications.
|
||||
|
||||
If your cloud infrastructure vendor is experiencing an outage, maybe your SRE team will be on top of notifications and status updates; if your billing vendor is involved, probably the team that manages your payment processing flow. Developer tools or Developer Experience teams may be on the lookout for problems with version control systems, build and deploy, or monitoring systems.
|
||||
|
||||
Knowing in advance which teams are responsible for which vendor relationships is important for being able to verify that your organization is or is not impacted by a vendor incident, knowing when the incident has been fully mitigated and service completely restored, and for determining what impact the incident had on your users.
|
||||
|
||||
Keep this information handy and make sure it is up to date as part of your incident preparedness. In PagerDuty, you can even define a [service](https://support.pagerduty.com/main/docs/services-and-integrations#section-configuring-services-and-integrations) representing a vendor and add contact information, runbooks, and other data to the service definition to help your response, as well as an escalation policy that notifies the team that interfaces with the vendor.
|
||||
|
||||
**Get Your Info from the Source**
|
||||
|
||||
For large incidents and major outages, the events are often the main tech news story of the day. Information will be in the mainstream media, on social media, and on specialized mailing lists dedicated to particular products, or just [outages](https://puck.nether.net/mailman/listinfo/outages) in general.
|
||||
|
||||
For your primary vendors – services that sit in your productivity or revenue-generating paths – know if they host a [status page](https://support.pagerduty.com/main/docs/status-pages-overview) and where it lives. Best practice suggests that these status pages be hosted off their main domain names, so you might not find them at company.com/status. They might also have dedicated social media accounts devoted to service status updates.
|
||||
|
||||
*If they don’t have a status page, they might have a customer notification email list that you’ll need to subscribe to.*
|
||||
|
||||
Your organization’s chat platform also probably allows your team to integrate with your vendor status pages, providing another avenue for teammates to determine if an incident is happening on the vendor.
|
||||
|
||||
Additionally, there are now a number of third-party reporting platforms that provide additional information:
|
||||
|
||||
- [Downdetector](https://downdetector.com/) ,[Down for Everyone or Just Me](https://downforeveryoneorjustme.com/) , and others – track outages for large commercial sites as well as mobile providers. These are super user-friendly and helpful for folks who aren’t sure if the problem they’re seeing is just on their end or more widespread.
|
||||
- The [Internet Weather Map](https://www.internetweathermap.com/map) reports on network lag globally. Helpful if your customers are worldwide. More for the network nerds.
|
||||
|
||||
**Your Vendor Runbook**
|
||||
|
||||
When a vendor has an incident, as a customer, you’ll want some information at hand. Establish a runbook for your key vendors so you’ll know who to contact and how.
|
||||
|
||||
Note key information in your runbook:
|
||||
|
||||
- Your organization’s account numbers or IDs so they can be referenced when contacting support.
|
||||
- Email addresses or contact information for your account managers and the vendor’s support team.
|
||||
- Contract information such as packages and features you’ve purchased, as well as the level of support you have, if applicable. If you have an elevated support package, you want to be aware of that; it may include special contact points.
|
||||
- Status of your account and renewal date. Make sure your account isn’t expired before reporting an issue.
|
||||
- Any vendor-specific reporting requirements, like error codes or stack traces that might be helpful to gather.
|
||||
|
||||
Also note in your vendor runbook if you have an idea of when it will be important to contact the vendor at all. During large outages that impact hundreds or even thousands of customers, you might not need or want to contact the vendor, but rely on the public status information. For incidents that don’t have indications of larger impact, your teams will want to reach out.
|
||||
|
||||
**While You Wait**
|
||||
|
||||
Public incidents can be super interesting to folks in your organization. They are dramatic! They’re in the news! Everyone is distracted!
|
||||
|
||||
Incidents can be a huge waste of time across your organization for those reasons. If people feel like they can’t get work done because a vendor is having an incident, your team needs a communications plan to keep people informed.
|
||||
|
||||
Your Major Incident workflows can help you keep distractions to a minimum, even when your team isn’t actively managing a remediation.
|
||||
|
||||
- Establish the internal point of contact. Designate someone from the team that owns the relationship to stay in touch with the vendor or to monitor the vendor’s status. Pass this responsibility off after a few hours if the incident persists.
|
||||
- Establish how information will be shared. Use your existing stakeholder communications channels, so your team isn’t searching for information somewhere unexpected.
|
||||
- If a vendor incident has impacts on your customers, liaise with your support teams for customer notifications and your own status updates.
|
||||
|
||||
Many vendor incidents are resolved in a relatively timely manner. Large, complex systems like AWS, Azure, and even GitHub have smaller incidents around some subsystems fairly regularly. These are easy enough to wait out, though they may impact your productivity. Some things to consider for these incidents:
|
||||
|
||||
- Decide when or if your team should call a deploy freeze, and who will have the authority to make that decision, including executive-level support.
|
||||
- Determine where internal communication will happen. Make sure everyone knows what is happening.
|
||||
- Designate a team member to monitor the vendor status and give the all clear.
|
||||
|
||||
For larger, more widespread, or longer-running incidents, your disaster recovery (DR) plan may be needed. Hopefully you’ve practiced it recently!
|
||||
|
||||
You likely won’t have full coverage for a DR plan. It’s rare to have full redundancy of all your providers, at least in the short term. The ability to switch version control system providers or build and deploy providers, even during longer outages, is hard and expensive.
|
||||
|
||||
Infrastructure and data DR plans are more common, and what many folks have in mind when they are owning their own availability. Your DR plan may include any number of features, but some basics to keep in mind include:
|
||||
|
||||
- Know when to declare a disaster and initiate a failover. Establish thresholds for customer impact, revenue impact, and other key metrics.
|
||||
- Establish executive responsibility and communications.
|
||||
- Initiate a Major Incident, or DR Incident if you have one, so all teams are on alert.
|
||||
- Have predetermined success and QA tests ready to go.
|
||||
|
||||
**Your Post-Vendor-Incident Review**
|
||||
|
||||
After a significant vendor incident, your team will be in a place to decide if the vendor has lost your trust as a customer. At this point your folks in procurement, finance, or legal should be involved to determine if SLAs were violated and your company is owed a credit or refund from the vendor.
|
||||
|
||||
The teams utilizing the vendor should evaluate whether the incident was impactful enough to trigger a vendor change. Weighing the cost of incident(s) against the switching costs and available features should be handled after the incident is concluded, when the team can fully evaluate how the vendor handled the incident from start to finish.
|
||||
|
||||
As with any PIR, determine if your actions were effective and make any updates needed to your vendor runbook:
|
||||
|
||||
- Was all of your information up to date?
|
||||
- Were your communications methods from the vendor and internal to your teams effective?
|
||||
- Were you able to recover functionality when the vendor claimed service to be restored, or were there other actions required?
|
||||
- Was there anything else that slowed down your notice of the incident or recovery afterwards?
|
||||
|
||||
**Conclusion**
|
||||
|
||||
Vendor incidents are stressful, not only because of their potential impact on our organizations, but often because of the feeling of helplessness our responders feel when issues are out of their hands. Preparing in advance for vendor issues will help keep your teams informed and make recovery more efficient.
|
||||
|
||||
Check out [this comprehensive checklist](https://www.pagerduty.com/resources/whitepaper/checklist-is-your-team-ready-for-outages/) designed to help you identify and address critical gaps in your incident management process.
|
||||
|
||||
|
||||
#### You may also love these...
|
||||
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
@@ -0,0 +1,27 @@
|
||||
# Incidents as keys to a lot of value
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2024/07/27/incidents-as-keys-to-a-lot-of-value/
|
||||
|
||||
## 简介
|
||||
|
||||
Cool trick:
|
||||
|
||||
> […] when an operational surprise happens, someone will remember “Oh yeah, I remember reading about something like this when incident XYZ happened”, and then they can go look up the incident writeup to incident XYZ and see the details that they need to help them respond.
|
||||
|
||||
## 正文
|
||||
|
||||
One of the workhorses of the modern software world is the *key-value store*. there are key-value services such as [Redis](https://redis.io/) or [Dynamo](https://www.amazon.science/publications/dynamo-amazons-highly-available-key-value-store), and some languages build key-value data structures right in to the language (examples include [Go](https://go.dev/blog/maps), [Python](https://docs.python.org/3/tutorial/datastructures.html#dictionaries) and [Clojure](https://clojure.org/reference/data_structures#Maps)). Even relational databases, which are not themselves key-value stores, are frequently built on top of a [data structure that exposes a key-value interface](https://surfingcomplexity.blog/2024/07/04/modeling-b-trees-in-tla/).
|
||||
|
||||
Key-value data structures are often referred to as *maps* or *dictionaries*, but here I want to call attention to the less-frequently-used term ***associative array***. This term evokes the associative nature of the store: the value that we store is associated with the key.
|
||||
|
||||
When I work on an incident writeup, I try to capture details and links to the various artifacts that the incident responders used in order to diagnose and mitigate the incident. Examples of such details include:
|
||||
|
||||
- dashboards (with screenshots that illustrate the problem and links to the dashboard)
|
||||
- names of feature flags that were used or considered for remediation
|
||||
- relevant Slack channels where there was coordination (other than the incident channel)
|
||||
|
||||
Why bother with these details? I see it as a strategy to tackle the problem that Woods and Cook refer to in [Perspectives on Human Error: Hindsight Biases and Local Rationality](https://www.researchgate.net/publication/251196331_Perspectives_on_Human_Error_Hindsight_Biases_and_Local_Rationality) as *the problem of inert knowledge*. There may be information about that we learned at some point, but we can’t bring it to bear when an incident is happening. However, we humans are good at remembering other incidents! And so, my hope is that when an operational surprise happens, someone will remember “Oh yeah, I remember reading about something like this when incident *XYZ* happened”, and then they can go look up the incident writeup to incident XYZ and see the details that they need to help them respond.
|
||||
|
||||
In other words, the previous incidents act as keys, and the content of the incident write-ups act as the value. If you make the incident write-ups memorable, then people may just remember enough about them to look up the write-ups and page in details about the relevant tools right when they need them.
|
||||
@@ -0,0 +1,106 @@
|
||||
# Let’s Consign CAP to the Cabinet of Curiosities
|
||||
|
||||
- **期号**: SRE Weekly Issue #438(2024-08-18)
|
||||
- **作者**: Marc Brooker
|
||||
- **链接**: http://brooker.co.za/blog/2024/07/25/cap-again.html
|
||||
|
||||
## 简介
|
||||
|
||||
While the CAP theorem may be technically correct, the actual limitations it imposes on real-world systems have nuance.
|
||||
|
||||
> The reality is that CAP is nearly irrelevant for almost all engineers building cloud-style distributed systems, and applications on the cloud.
|
||||
|
||||
## 正文
|
||||
|
||||
I am an engineer at Amazon Web Services (AWS) in Seattle, where I work on agentic AI, especially safety and policy for agentic AI. Before that, I worked on EC2, EBS, databases, serverless, and serverless databases.
|
||||
|
||||
All opinions are my own.
|
||||
|
||||
Brewer’s CAP theorem, and Gilbert and Lynch’s [formalization of it](https://users.ece.cmu.edu/~adrian/731-sp04/readings/GL-cap.pdf), is the first introduction to hard trade-offs for many distributed systems engineers. Going by the vast amounts of ink and bile spent on the topic, it is not unreasonable for new folks to conclude that it’s an important, foundational, idea.
|
||||
|
||||
The reality is that CAP is nearly irrelevant for almost all engineers building cloud-style distributed systems, and applications on the cloud. It’s much closer to relevant for developers of intermittently connected mobile and IoT applications, and space where the trade-off is typically seen as common sense already.
|
||||
|
||||
We’ll start with this excellent diagram from Bernstein and Das’s [Rethinking Eventual Consistency](https://www.microsoft.com/en-us/research/wp-content/uploads/2016/02/sigtt611-bernstein.pdf):
|
||||
|
||||
|
||||
|
||||
|
||||
CAP interests itself in the first two boxes. If there’s no partition (everybody can speak to everybody), we’re OK. Where CAP goes off the rails is the second box: if a quorum of replicas is available to the client, they can still get both strong consistency, and uncompromised availability.
|
||||
|
||||
*What do we mean when we say Available?*
|
||||
|
||||
Consider the quorum system below. We have seven clients. Six are on the majority (quorum<sup>[1](http://brooker.co.za#foot1)</sup>) side, and are smiling because they can enjoy *both* availability and strong consistency (provided the system doesn’t allow the seventh client to write). The frowning client is out in the cold. They can get stale reads, but can’t write, so they’re frowning.
|
||||
|
||||
|
||||
|
||||
|
||||
The formalized CAP theorem would call this system *unavailable*, based on their definition of *availability*:
|
||||
|
||||
every request received by a non-failing node in the system must result in a response.
|
||||
|
||||
|
||||
Most engineers, operators, and six of seven clients, would call this system *available*. This difference in definitions for a [common everyday term](https://brooker.co.za/blog/2018/02/25/availability-liveness.html) causes no end of confusion. Including among those who (incorrectly) claim that this system can’t offer consistency and availability to the six happy clients. It can.
|
||||
|
||||
*Can we make the seventh client happy?*
|
||||
|
||||
As system operators, we still don’t love this situation, and would like all seven of our clients to be happy. This is where we head down to the third box in Bernstein and Das’s diagram, which gives us two choices.
|
||||
|
||||
- We can accept writes on both sides, provided those writes can be merged later in a sensible way, and offer eventually-consistent reads on both sides.
|
||||
- We can find another way to make the seventh client happy.
|
||||
|
||||
The majority of the websites and systems you interact with day-to-day take the second path.
|
||||
|
||||
Here’s how that works:
|
||||
|
||||
|
||||
|
||||
|
||||
Seven happy clients talk to our service via a load balancer. DNS, multi-cast, or some other mechanism directs them towards a healthy load balancer on the healthy side of the partition. The load balancer directs traffic to the healthy replicas, from that healthy side. None of the clients need to be aware that a network partition exists (except a small number who may see their connection to the bad side drop, and be replaced by a connection to the good side).
|
||||
|
||||
If the partition extended to the whole big internet that clients are on, this wouldn’t work. But they typically don’t.
|
||||
|
||||
*Extending to Architectures On the Cloud*
|
||||
|
||||
Architectures in the cloud, or in any group of datacenters, do need to deal with network partitions an infrastructure failures. They do that using the same mechanism.
|
||||
|
||||
|
||||
|
||||
|
||||
Applications are deployed in multiple datacenters. A combination of load balancer and some routing mechanism (like DNS) directs customers to healthy copies of the application that can get to a quorum of replicas. Clients are none the wiser, and all have a smile on their faces.
|
||||
|
||||
*The CAP Theorem is Irrelevant*
|
||||
|
||||
The point of these simple, and perhaps simplistic, examples is that CAP trade-offs aren’t a big deal for cloud systems (and cloud-like systems across multiple datacenters). In practice, the redundant nature of connectivity and ability to use routing mechanisms to send clients to the healthy side of partitions means that the vast majority of cloud systems can offer both strong consistency and high availability to their clients, even in the presence of the most common types of network partitions (and other failures).
|
||||
|
||||
This doesn’t mean the CAP theorem is wrong, just that it’s not particularly practically interesting.
|
||||
|
||||
It also doesn’t mean that there aren’t interesting trade-offs to be considered. Interesting ones include trade-offs between on-disk durability and write latency, between read latency and write latency, between consistency and latency, between latency and throughput, between consistency and throughput<sup>[2](http://brooker.co.za#foot2)</sup>, between isolation and throughput, and many others. Almost all of these trade-offs are more practically important to the cloud system engineer than CAP.
|
||||
|
||||
*When is CAP Relevant?*
|
||||
|
||||
CAP tends to be most relevant to the folks who seem to talk about it least: engineers designing and building systems in intermittently connected environments. IoT. Environmental monitoring. Mobile applications. These tend to be cases where one device, or a small group of them, can be partitioned off from the internet mother ship due to awkward physical situations. Like somebody standing the way of the laser. Or power failures. Or getting in an elevator.
|
||||
|
||||
In these settings, applications simply must visit the bottom right corner of Bernstein and Das’s diagram. They must figure out whether to accept writes, and how to merge them, or they must be unavailable for updates. It’s also worth noting that these applications tend not to contain full replicas of the data set, and so read availability may also be affected by loss of connectivity.
|
||||
|
||||
I suspect that these folks don’t think about CAP for the same reason you don’t think about air: it’s just part of their world.
|
||||
|
||||
*What About Correctness?*
|
||||
|
||||
My point here isn’t that you can ignore partitions. Network partitions (and other kinds of failures) absolutely do happen. Systems need to be designed, and continuously tested, to ensure that their behavior during and after network partitions maintains their contract with clients. That contract will likely include isolation, consistency, atomicity, and durability promises. Once again, the trade-off space here is deep, and CAP’s particular definition of correctness (*linearizability*<sup>[3](http://brooker.co.za#foot3)</sup>) is both too narrow to be generally useful, and likely not the criterion that is going to drive the majority of design decisions. Similarly, network partitions are only one part of a good model of failures. For example, they don’t capture re-ordering or multi-delivery of messages, both of which are important to consider in both protocols and implementations.
|
||||
|
||||
CAP is both an insufficient mental model for correctness in stateful distributed systems, and not a particularly good basis for a sufficient model.
|
||||
|
||||
*A challenge*
|
||||
|
||||
The point of this post isn’t merely to be the ten billionth blog post on the CAP theorem. It’s to issue a challenge. A request. Please, if you’re an experienced distributed systems person who’s teaching some new folks about trade-offs in your space, don’t start with CAP. Maybe start by talking about durability versus latency (how many copies? where?). Or one of the [hundred impossibility results from this Nancy Lynch paper](https://dl.acm.org/doi/abs/10.1145/72981.72982). If you absolutely want to talk about a trade-off space with a cool acronym, maybe start with [CALM](https://arxiv.org/pdf/1901.01930.pdf), [RUM](https://stratos.seas.harvard.edu/files/stratos/files/rum.pdf), or even [PACELC](https://www.cs.umd.edu/~abadi/papers/abadi-pacelc.pdf).
|
||||
|
||||
Let’s consign CAP to the cabinet of curiosities.
|
||||
|
||||
*Footnotes*
|
||||
|
||||
1.
|
||||
*majority* and*quorum* interchangeably, despite the fact that some systems have*quorums* that are not*majorities* . The predominant case is that*quorum* is a simple*majority* .
|
||||
2.
|
||||
[Anna](https://dsf.berkeley.edu/jmh/papers/anna_ieee18.pdf) Key-Value store from Chenggang Wu and team at Berkeley is one great example of an exploration of a trade-off space.
|
||||
3.
|
||||
[Herlihy and Wing](https://cs.brown.edu/~mph/HerlihyW90/p463-herlihy.pdf) you should do that. The point isn’t that*linearizability* isn’t useful, it’s that it’s only a local property of single objects (see Section 3.1 of the paper).
|
||||
Reference in New Issue
Block a user