SRE weekly 所有文章
This commit is contained in:

289
sreweekly/markdown/453/04-go-profiling-in-production.md
Normal file
289
sreweekly/markdown/453/04-go-profiling-in-production.md
Normal file
@@ -0,0 +1,289 @@
|
||||
# Go Profiling in Production
|
||||
|
||||
- **期号**: SRE Weekly Issue #453(2024-12-01)
|
||||
- **作者**: Gaurav Maheshwari — Oodle
|
||||
- **链接**: https://blog.oodle.ai/go-profiling-in-production/
|
||||
|
||||
## 简介
|
||||
|
||||
A primer on using Golang’s profiling tools including CPU profiling, memory profiling, goroutine leak analysis, and execution tracing.
|
||||
|
||||
## 正文
|
||||
|
||||
# Go Profiling in Production
|
||||
|
||||
|
||||
|
||||
**TL;DR**
|
||||
|
||||
- Go's built-in profiler, **pprof** , exposes CPU, heap, goroutine, block, and mutex profiles through`net/http/pprof` ; run it on a dedicated localhost-only port.
|
||||
- `go tool pprof -http=:8080 "http://localhost:6060/debug/pprof/profile?seconds=30"` collects a 30-second CPU profile and opens it as a flame graph.
|
||||
- Comparing heap profiles with `-diff_base` isolates memory growth between two points in time.
|
||||
- `pprof.Do` profiler labels attribute CPU time to individual tenants in a multi-tenant service.
|
||||
- Go 1.25's Flight Recorder keeps the last few seconds of execution trace in memory, so you can capture an incident after it happens.
|
||||
|
||||
**Profiling a Go application in production** is how we find CPU, memory, and goroutine bottlenecks at Oodle before they turn into incidents.
|
||||
|
||||
At Oodle, we use Golang for our backend services. In an earlier blog post ([Go faster!](https://blog.oodle.ai/high-performance-in-golang/)), we discussed optimization techniques for performance and scale, with a specific focus on reducing memory allocations. In this post, we'll explore the profiling tools we use. Golang provides a rich set of [profiling tools](https://go.dev/doc/diagnostics?ref=blog.oodle.ai) to help uncover code bottlenecks.
|
||||
|
||||
## Our Setup
|
||||
|
||||
We use the standard [net/http/pprof](https://pkg.go.dev/net/http/pprof?ref=blog.oodle.ai) package to register handlers for profiling endpoints. As part of our service startup routine, we run a profiler server on a dedicated port.
|
||||
|
||||
```
|
||||
import (
|
||||
_ "net/http/pprof"
|
||||
)
|
||||
...
|
||||
var profilerPort = flaggy.GetEnvStringVar(
|
||||
"PROFILER_PORT",
|
||||
"profiler_port",
|
||||
"Profiler port",
|
||||
"6060",
|
||||
)
|
||||
func StartProfilerServer(ctx context.Context) {
|
||||
go func() {
|
||||
http.ListenAndServe(fmt.Sprintf("localhost:%s", *profilerPort), nil)
|
||||
}()
|
||||
}
|
||||
```
|
||||
This setup allows us to collect various profiles exposed by the `net/http/pprof` package on-demand.
|
||||
|
||||
**A note on safety:** never expose `/debug/pprof` on a public interface; profiling endpoints reveal internal details and add load. Bind them to localhost as above and reach them via port-forward or a private network.
|
||||
|
||||
**Go profiling tools at a glance**
|
||||
|
||||
| Profile / tool | How to collect | What it answers |
|
||||
|---|---|---|
|
||||
| CPU profile | /debug/pprof/profile?seconds=30 | Where CPU time goes |
|
||||
| Heap profile | /debug/pprof/heap (compare with -diff_base ) | What is allocating and retaining memory |
|
||||
| Goroutine dump | /debug/pprof/goroutine?debug=2 | Leaked or blocked goroutines |
|
||||
| Block profile | /debug/pprof/block · off by default; enable with runtime.SetBlockProfileRate | Where goroutines wait (channels, locks) |
|
||||
| Mutex profile | /debug/pprof/mutex · off by default; enable with runtime.SetMutexProfileFraction | Lock contention hotspots |
|
||||
| Execution trace | /debug/pprof/trace?seconds=5 | Why goroutines aren't running (scheduling, GC) |
|
||||
| Flight Recorder (Go 1.25+) | runtime/trace.FlightRecorder | The seconds leading up to an incident |
|
||||
| Continuous profiling | Pyroscope, Parca | Trends over time, across the fleet |
|
||||
|
||||
**How to profile a Go service in production:**
|
||||
|
||||
1. Import `net/http/pprof` and serve it on a dedicated localhost port.
|
||||
2. Collect a CPU profile: `go tool pprof -http=:8080 "http://localhost:6060/debug/pprof/profile?seconds=30"` .
|
||||
3. Read the flame graph; the widest frames are your hottest paths.
|
||||
4. Snapshot the heap twice and diff: `go tool pprof -diff_base heap_t0.prof heap_t1.prof` .
|
||||
5. Dump goroutines when things hang: `/debug/pprof/goroutine?debug=2` .
|
||||
6. For rare incidents, keep Go 1.25's Flight Recorder running and snapshot after the event.
|
||||
|
||||
## CPU Profiling
|
||||
|
||||
CPU profiling helps understand where CPU time is being spent in the code. To collect a CPU profile, we can hit the `/debug/pprof/profile` endpoint with a `seconds` parameter.
|
||||
|
||||
```
|
||||
curl http://localhost:6060/debug/pprof/profile?seconds=30 -o cpu.prof
|
||||
```
|
||||
After collecting the profile, we can analyze it using the `go tool pprof` command.
|
||||
|
||||
```
|
||||
go tool pprof -http=:8080 cpu.prof
|
||||
```
|
||||
**Note:**
|
||||
|
||||
Both of the above steps can be combined into a single command:
|
||||
|
||||
```
|
||||
go tool pprof -http=:8080 http://localhost:6060/debug/pprof/profile?seconds=30
|
||||
```
|
||||
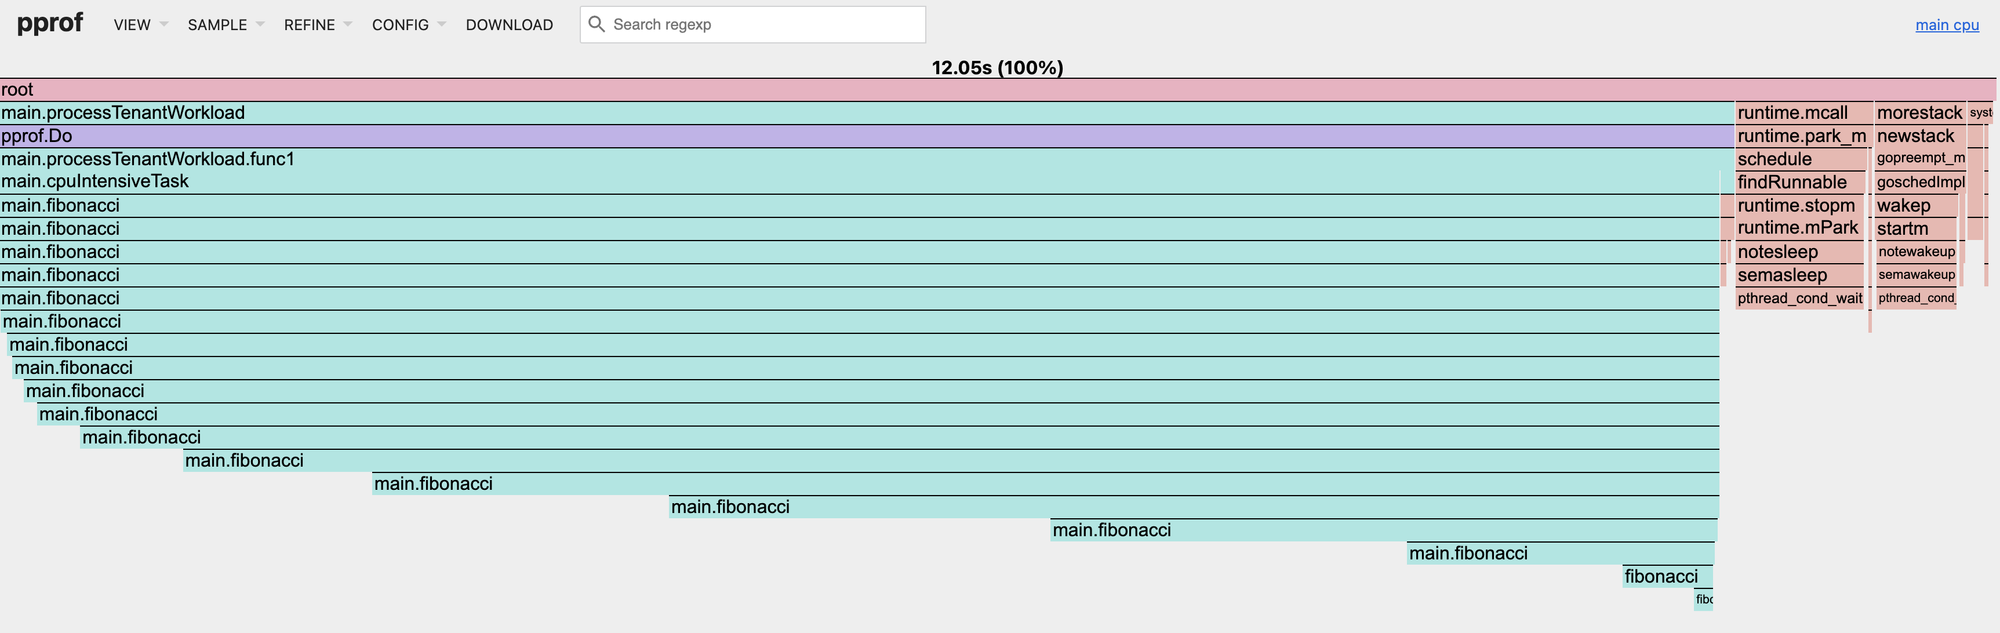
This command starts a local HTTP server and opens the profile in the browser. We frequently use [flame graphs] ([https://www.brendangregg.com/flamegraphs.html](https://www.brendangregg.com/flamegraphs.html?ref=blog.oodle.ai)) for profile analysis.
|
||||
|
||||
|
||||
|
||||
|
||||
**Note:**
|
||||
|
||||
All screenshots referenced in this blog post are for the [demo application](https://gist.github.com/mgaurav/80910918ff2fe3694e86c2462bfbadd2?ref=blog.oodle.ai).
|
||||
|
||||
### Per-tenant profiles in a multi-tenant service
|
||||
|
||||
Per-tenant profiler labels use Go's `pprof.Do` to tag CPU samples with a tenant identifier, so one profile can show exactly which tenant drives load in a multi-tenant service.
|
||||
|
||||
As a multi-tenant SaaS platform, Oodle serves many tenants from the same deployment. Ingestion and query loads vary significantly among tenants. To understand CPU profiles for individual tenants, we use [profiler labels] ([https://rakyll.org/profiler-labels/](https://rakyll.org/profiler-labels/?ref=blog.oodle.ai)) to add tenant identifiers to the profiles.
|
||||
|
||||
```
|
||||
pprof.Do(ctx, pprof.Labels("tenant_id", tenantID), func(ctx context.Context) {
|
||||
// Your code here.
|
||||
})
|
||||
```
|
||||
These profiler labels attach additional information to stack frames in the collected profiles, enabling per-tenant CPU attribution analysis.
|
||||
|
||||
```
|
||||
$ go tool pprof cpu.prof
|
||||
File: cpu
|
||||
Type: cpu
|
||||
...
|
||||
(pprof) tags
|
||||
tenant_id: Total 10.6s
|
||||
6.7s (63.31%): tenant1
|
||||
3.9s (36.69%): tenant2
|
||||
```
|
||||
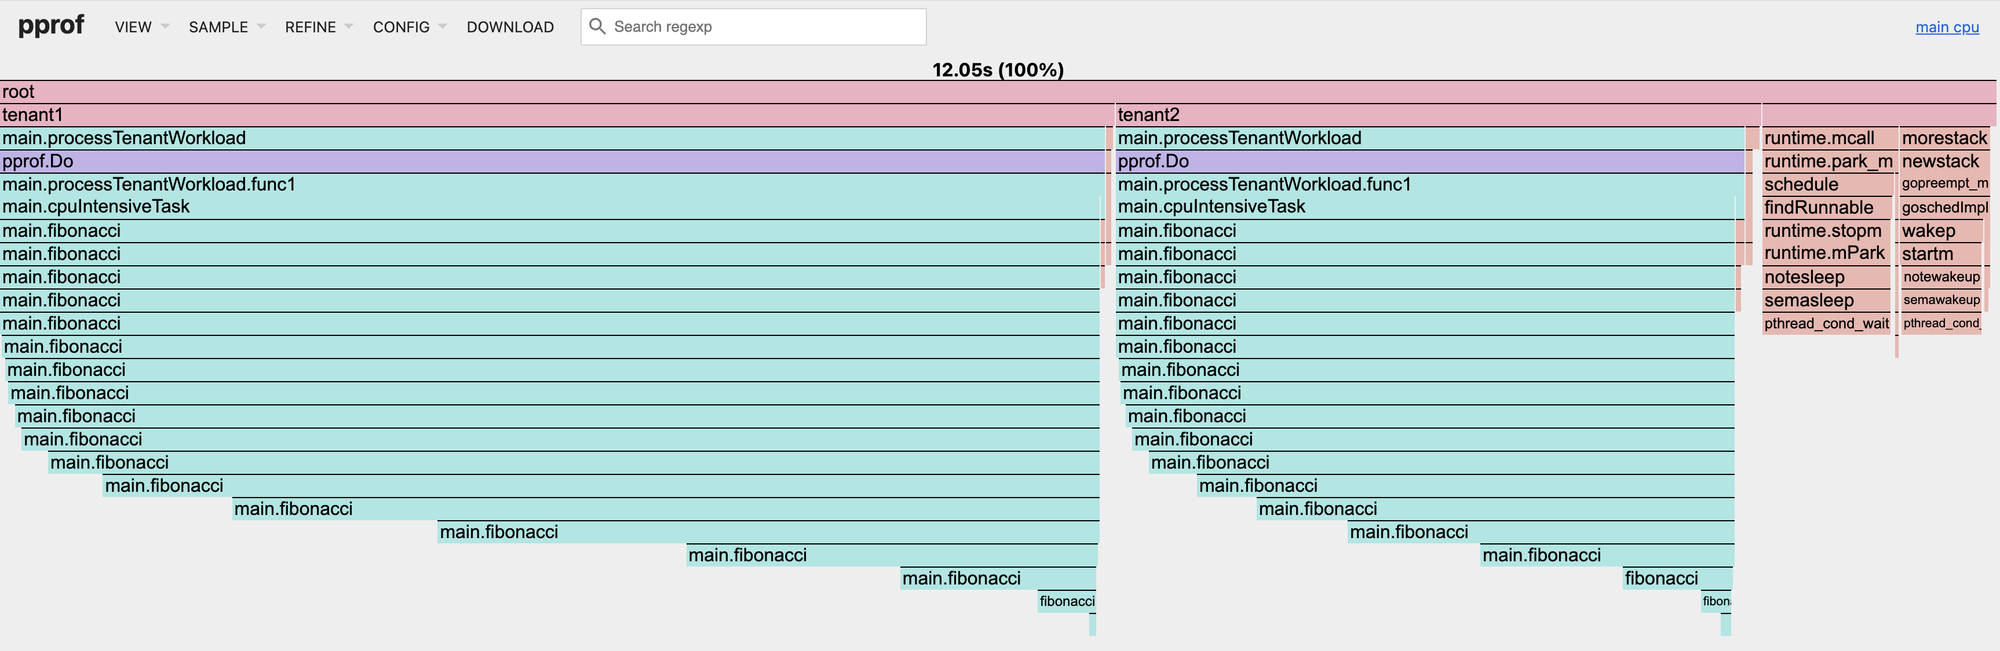
We can also use the [tagroot](https://www.markhansen.co.nz/pprof-tagroot/?ref=blog.oodle.ai) argument to add the tenant identifier as a pseudo stack frame at the callstack root.
|
||||
|
||||
```
|
||||
go tool pprof -http=:8080 -tagroot tenant_id cpu.prof
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Memory Profiling
|
||||
|
||||
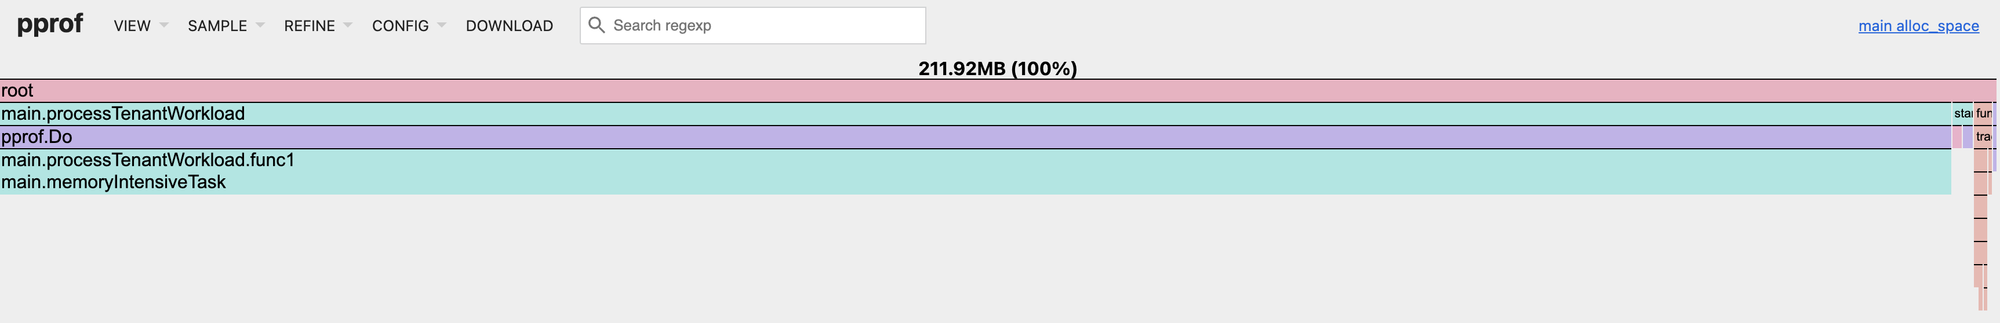
Memory profiling helps identify where memory allocations occur. Since Golang is a memory-managed language, minimizing allocations is crucial for reducing Garbage Collection (GC) overhead. Using our profiler server, we can collect a memory profile via the `/debug/pprof/heap` endpoint.
|
||||
|
||||
```
|
||||
go tool pprof -http=:8080 http://localhost:6060/debug/pprof/heap
|
||||
```
|
||||
|
||||
|
||||
|
||||
**Note:**
|
||||
|
||||
Collecting memory profiles at different times and comparing them helps understand the service's memory behavior. Use the `-diff_base` flag to compare two profiles:
|
||||
|
||||
```
|
||||
go tool pprof -http=:8080 -diff_base heap_0935.prof heap_0940.prof
|
||||
```
|
||||
In practice the `-diff_base` workflow looks like this: save `/debug/pprof/heap` once when the service is healthy and again when memory is elevated, then open the diff; the entries with the largest positive `inuse_space` delta are what grew. Two related profiles answer different questions: the **heap** profile shows live memory (use it to find retention), while the **allocs** profile shows cumulative allocations since start (use it to find GC pressure).
|
||||
|
||||
### Automated Memory Profiling
|
||||
|
||||
Memory footprint of a program can vary significantly depending on the workload. If the memory allocation rate is higher than the Garbage Collection (GC) rate, it can lead to Out of Memory (OOM) crashes. To understand memory usage patterns during high-memory situations, we use an auto profiler that:
|
||||
|
||||
1. Captures memory profiles when footprint exceeds a percentage threshold
|
||||
2. Uploads these profiles to object storage for offline analysis
|
||||
3. Rate-limits profile collection to prevent excessive uploads
|
||||
|
||||
Here is a rough blueprint of the auto profiler:
|
||||
|
||||
```
|
||||
import (
|
||||
"runtime/metrics"
|
||||
"pontus.dev/cgroupmemlimited"
|
||||
)
|
||||
func startAutoProfiler(ctx context.Context) error {
|
||||
memSamples := make([]metrics.Sample, 2)
|
||||
memSamples[0].Name = "/memory/classes/total:bytes"
|
||||
memSamples[1].Name = "/memory/classes/heap/released:bytes"
|
||||
profileLimit := cgroupmemlimited.LimitAfterInit * (*autoProfilerPercentageThreshold / 100)
|
||||
go func() {
|
||||
ticker := time.NewTicker(*profilerInterval)
|
||||
for {
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
return
|
||||
case <-ticker.C:
|
||||
metrics.Read(memSamples)
|
||||
inUseMem := memSamples[0].Value.Uint64() - memSamples[1].Value.Uint64()
|
||||
if inUseMem > profileLimit {
|
||||
if !limiter.Allow() { // rate limiter
|
||||
continue
|
||||
}
|
||||
var buf bytes.Buffer
|
||||
if err := pprof.WriteHeapProfile(&buf); err != nil {
|
||||
continue
|
||||
}
|
||||
// Upload the profile to object storage
|
||||
}
|
||||
}
|
||||
}
|
||||
}()
|
||||
}
|
||||
```
|
||||
## Goroutine Analysis
|
||||
|
||||
While Golang makes concurrent programming easier with its powerful [concurrency primitives](https://go.dev/doc/effective_go?ref=blog.oodle.ai#concurrency) like Goroutines and Channels, it's also possible to introduce goroutine leaks. For examples of common goroutine leak patterns, see [this](https://www.uber.com/blog/leakprof-featherlight-in-production-goroutine-leak-detection/?ref=blog.oodle.ai) blog post.
|
||||
|
||||
We use [goleak](https://github.com/uber-go/goleak?ref=blog.oodle.ai) to detect goroutine leaks in our tests. Enable it in a test by adding a `TestMain` function at the package level:
|
||||
|
||||
```
|
||||
func TestMain(m *testing.M) {
|
||||
goleak.VerifyTestMain(m)
|
||||
}
|
||||
```
|
||||
To collect a goroutine dump from our services, we can use the `debug/pprof/goroutine` endpoint:
|
||||
|
||||
```
|
||||
curl "http://localhost:6060/debug/pprof/goroutine?debug=2" -o goroutine.dump
|
||||
```
|
||||
The goroutine dump is a text file containing stack traces of all process goroutines. For analyzing dumps with thousands of goroutines, we use [goroutine-inspect](https://github.com/linuxerwang/goroutine-inspect?ref=blog.oodle.ai), which provides helpful deduplication and search functionality.
|
||||
|
||||
## Execution Tracing
|
||||
|
||||
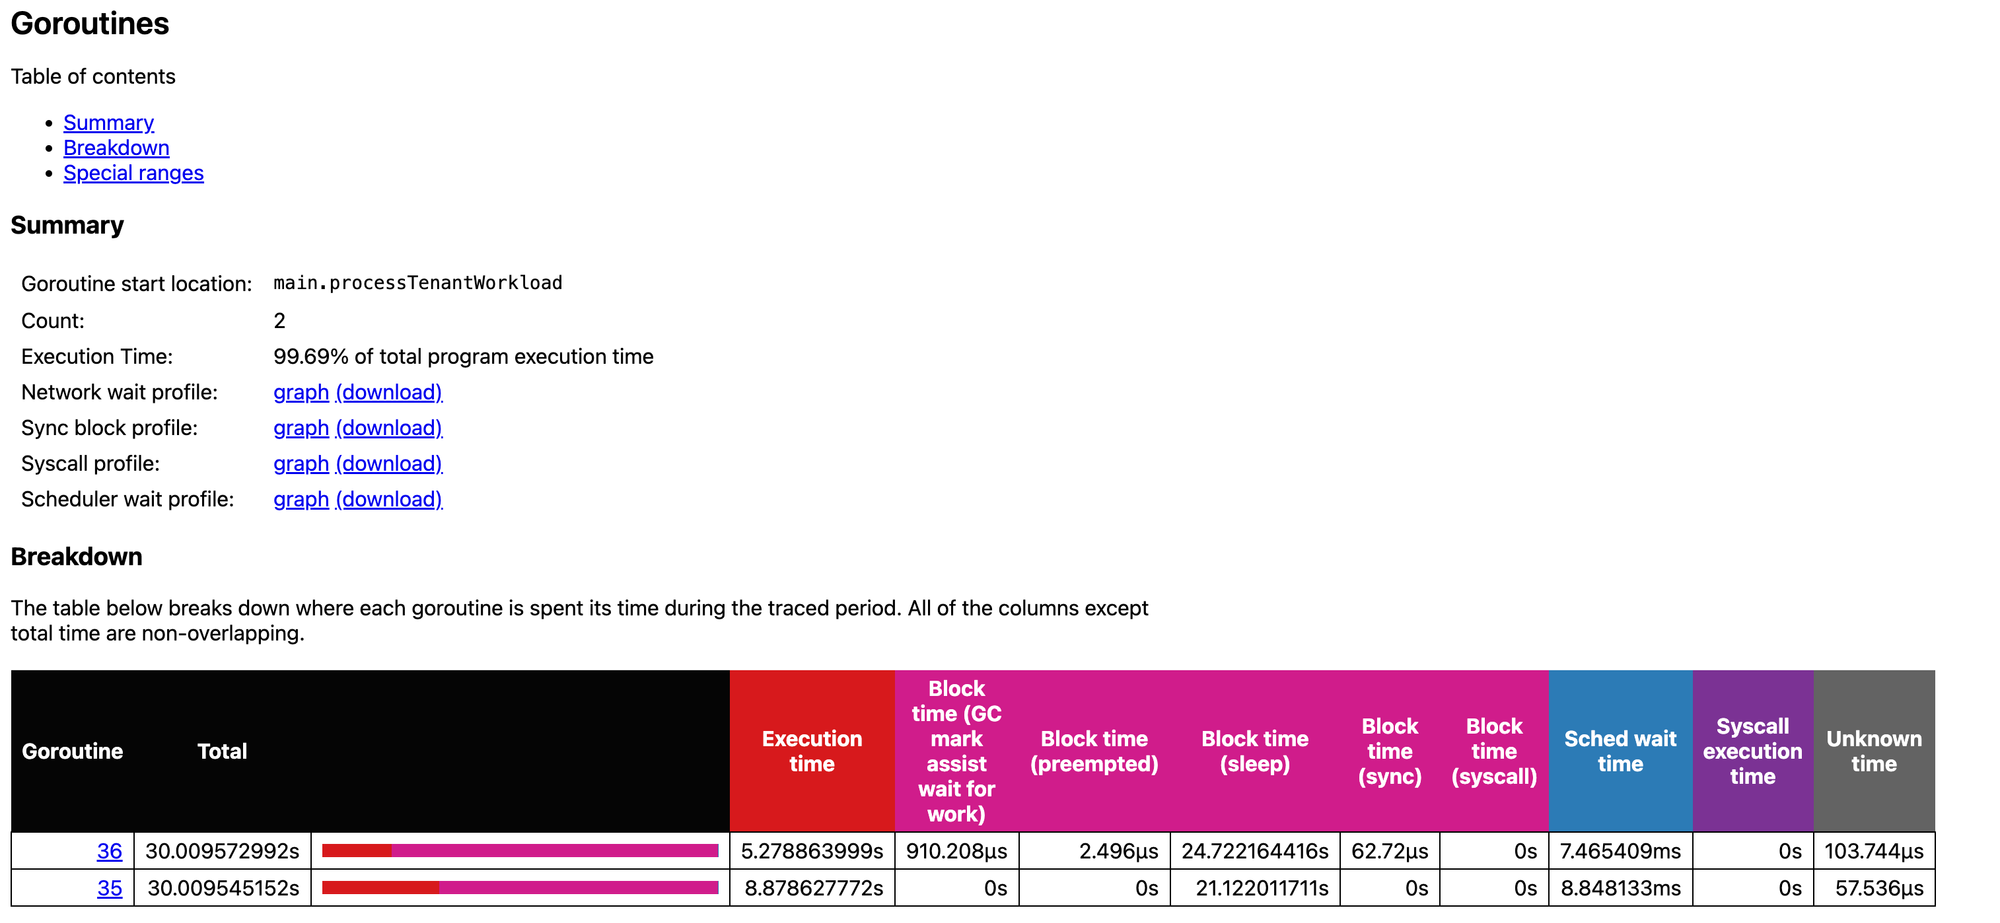
Execution tracing helps you understand how goroutines are scheduled and where they might be blocked. It captures several types of events:
|
||||
|
||||
1. Goroutine lifecycle (creation, start, and end)
|
||||
2. Blocking events (syscalls, channels, locks)
|
||||
3. Network I/O operations
|
||||
4. System calls
|
||||
5. Garbage collection cycles
|
||||
|
||||
While CPU profiling shows which functions consume the most CPU time, execution tracing reveals why goroutines might not be running. It helps identify if a goroutine is blocked on a mutex, waiting for a channel, or simply not getting enough CPU time. For a comprehensive introduction to execution tracing, see [this blog post](https://blog.gopheracademy.com/advent-2017/go-execution-tracer/?ref=blog.oodle.ai).
|
||||
|
||||
To collect an execution trace, use the `debug/pprof/trace` endpoint:
|
||||
|
||||
```
|
||||
curl "http://localhost:6060/debug/pprof/trace?seconds=30" -o trace.prof
|
||||
```
|
||||
To analyze the collected trace, use the `go tool trace` command:
|
||||
|
||||
```
|
||||
go tool trace trace.prof
|
||||
```
|
||||
|
||||
|
||||
|
||||
Recent versions of Go have [significantly reduced](https://go.dev/blog/execution-traces-2024?ref=blog.oodle.ai) the overhead of execution tracing, making it practical for use in production environments.
|
||||
|
||||
**Where Go execution tracing stands in 2026:** Go 1.25 (August 2025) promoted the flight recorder into the standard library as [runtime/trace.FlightRecorder](https://go.dev/blog/flight-recorder?ref=blog.oodle.ai).
|
||||
|
||||
It keeps the last few seconds of the execution trace in an in-memory ring buffer, so instead of collecting a trace window on demand and hoping the problem recurs, a service can snapshot the moments leading up to an incident (a failed health check, a latency spike) with `FlightRecorder.WriteTo`.
|
||||
|
||||
It complements the on-demand `/debug/pprof/trace` flow above: on-demand tracing for planned investigations, the flight recorder for events you can't predict.
|
||||
|
||||
For **continuous profiling** rather than on-demand snapshots; always-on profiles, queryable over time across your fleet; see [Pyroscope](https://grafana.com/oss/pyroscope/?ref=blog.oodle.ai) and [Parca](https://www.parca.dev/?ref=blog.oodle.ai); Oodle ingests [Pyroscope profiles](https://docs.oodle.ai/integrations/profiling/pyroscope?ref=blog.oodle.ai).
|
||||
|
||||
## Summary
|
||||
|
||||
Production profiling in Go comes down to a small, repeatable workflow: expose `net/http/pprof` on a localhost-only port, pull a CPU profile when latency climbs, diff heap snapshots when memory grows, dump goroutines when things hang, and reach for execution tracing — or Go 1.25's flight recorder — when you need to see *why* goroutines aren't running.
|
||||
|
||||
That is the setup we run at Oodle: the same endpoints, plus per-tenant profiler labels and automated capture for the incidents we can't predict.
|
||||
|
||||
The CPU profiles you collect in production can also feed [profile-guided optimization](https://go.dev/doc/pgo?ref=blog.oodle.ai): check a representative profile in as `default.pgo` and Go (1.21+) uses it to optimize your hot paths at build time; a natural companion to the techniques in our [post on optimizing Go performance](https://blog.oodle.ai/high-performance-in-golang/).
|
||||
|
||||
See what these profiles look like against live, high-scale production data in the [Oodle playground](https://play.oodle.ai/?ref=blog.oodle.ai).
|
||||
|
||||
**Frequently asked questions**
|
||||
|
||||
### How do I profile a Go application in production?
|
||||
|
||||
Register `net/http/pprof` handlers and serve them on a dedicated localhost-only port at startup. You can then collect CPU, heap, goroutine, and trace profiles on demand from its endpoints without redeploying; keep the port unexposed publicly.
|
||||
|
||||
### How do I collect and view a CPU profile with pprof?
|
||||
|
||||
Run `go tool pprof -http=:8080 "http://localhost:6060/debug/pprof/profile?seconds=30"`. It samples 30 seconds of CPU and opens an interactive flame graph in your browser.
|
||||
|
||||
### How do I track down growing memory usage in a Go service?
|
||||
|
||||
Capture `/debug/pprof/heap` at two points in time and compare them with `go tool pprof -diff_base`. For spikes you can't predict, automate capture when memory crosses a threshold; see the auto-profiler blueprint above.
|
||||
|
||||
### How do I find goroutine leaks in Go?
|
||||
|
||||
Use [goleak](https://github.com/uber-go/goleak?ref=blog.oodle.ai) in `TestMain` to catch leaks in tests, and `/debug/pprof/goroutine?debug=2` dumps in production. For dumps with thousands of goroutines, goroutine-inspect deduplicates and searches stacks.
|
||||
|
||||
### What other profiles does net/http/pprof expose?
|
||||
|
||||
Block, mutex, allocs, and threadcreate profiles.
|
||||
|
||||
Block and mutex profiling are off by default; enable them with `runtime.SetBlockProfileRate` and `runtime.SetMutexProfileFraction` at startup (they carry a small overhead); without those calls the endpoints return empty profiles.
|
||||
|
||||
**Related reading on the Oodle blog**
|
||||
|
||||
- Fix what the profiles find: [Go faster! Golang performance optimization in production](https://blog.oodle.ai/high-performance-in-golang/)
|
||||
- Scale the monitoring around your services: [Scaling Prometheus: from single node to enterprise-grade observability](https://blog.oodle.ai/scaling-prometheus-from-single-node-to-enterprise-grade-observability/)
|
||||
- The platform these practices power: [How Oodle keeps observability fast at scale](https://blog.oodle.ai/how-oodle-keeps-observability-fast-at-scale/)
|
||||
Reference in New Issue
Block a user