SRE weekly 所有文章
This commit is contained in:

15
sreweekly/markdown/499/01-fix-mas-countdown.md
Normal file
15
sreweekly/markdown/499/01-fix-mas-countdown.md
Normal file
@@ -0,0 +1,15 @@
|
||||
# Fix-mas Countdown
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Uptime Labs and Adaptive Capacity Labs
|
||||
- **链接**: https://uptimelabs.io/fixmas/
|
||||
|
||||
## 简介
|
||||
|
||||
The folks at Uptime Labs and Advanced Capacity Labs have announced an advent calendar for this December.
|
||||
|
||||
Note: In order to take part, you’ll need to provide an email address to subscribe. I gave that some serious thought before including this here, but ultimately, I have a lot of trust for the folks at both ACL and Uptime Labs, since they’ve both produced so much awesome content that’s been featured here. I’m interested to see what this collab will bring!
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 404
|
||||
@@ -0,0 +1,13 @@
|
||||
# From Static Rate Limiting to Adaptive Traffic Management in Airbnb’s Key-Value Store
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Shravan Gaonkar — Airbnb
|
||||
- **链接**: https://medium.com/airbnb-engineering/from-static-rate-limiting-to-adaptive-traffic-management-in-airbnbs-key-value-store-29362764e5c2
|
||||
|
||||
## 简介
|
||||
|
||||
Cool trick: divide short-term P95 latency by the long-term P95 to detect load spikes and adjust rate limits on-the-fly.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,146 @@
|
||||
# Failure is inevitable: Learning from a large outage, and building for reliability in depth at Datadog
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Laura de Vesine, Rob Thomas, AND Maciej Kowalewski
|
||||
- **链接**: https://www.datadoghq.com/blog/engineering/rethinking-reliability/
|
||||
|
||||
## 简介
|
||||
|
||||
Datadog shares the bigger-picture lessons they learned and improvements they made since their major 2023 outage, including an emphasis on graceful degradation.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
Laura de Vesine
|
||||
|
||||

|
||||
|
||||
Rob Thomas
|
||||
|
||||

|
||||
|
||||
Maciej Kowalewski
|
||||
|
||||
In March 2023, Datadog experienced a rare, widespread [incident](https://www.datadoghq.com/blog/2023-03-08-multiregion-infrastructure-connectivity-issue/) that left large parts of our infrastructure only partially functional, but from a customer’s perspective, our platform looked completely down. This **square-wave failure pattern**—up, then instantly down—revealed critical limitations in how our systems degraded and our ability to serve our customers. Since then, we’ve rethought our approach to failure across our products and infrastructure.
|
||||
|
||||
In this post, we explain what we learned from the incident, how we responded, and what it takes to build for graceful degradation at scale.
|
||||
|
||||
## [The problem: What our March 2023 incident taught us](https://www.datadoghq.com#the-problem-what-our-march-2023-incident-taught-us)
|
||||
|
||||
Revisiting [our March 2023 incident](https://www.datadoghq.com/blog/engineering/2023-03-08-deep-dive-into-platform-level-impact/), the immediate cause was an unsupervised global update, which caused a restart interaction that removed connectivity to approximately **50–60%** of our Kubernetes nodes in production. While that level of platform loss would have a significant impact on any system, the effect on the Datadog platform was a nearly complete loss of user-facing functionality. Our web interface mostly self-recovered quickly, but logs, metrics, alerting, traces, and various other products and features critical to our customers’ operations were fully unavailable. Pages loaded, but displayed no data.
|
||||
|
||||
## [Why classical root-cause analysis wasn’t enough](https://www.datadoghq.com#why-classical-root-cause-analysis-wasnt-enough)
|
||||
|
||||
Classical incident analysis usually traces back to the **precipitating event**—often called **root cause**—that caused a system to become unstable, and focuses on remediating that cause. In this case, we could easily identify our global update mechanism for critical security patches as the precipitating event for this outage. We also identified that this mechanism was a legacy system. Since its original implementation, we had built lifecycle automation for all nodes that could apply changes, including for critical CVEs, across our entire fleet using a “normal,” regularly exercised update mechanism. We disabled the fleet-wide CVE pull as soon as we identified it as the trigger for the incident, with no loss of security or reliability.
|
||||
|
||||
The challenge with this kind of causal analysis is that there are an infinite number of events that might destabilize a system and lead to a significant outage. In this case, the trigger was an automated update, but across the industry, major incidents have been caused by everything from certificate expiry to daylight saving time bugs, leap day handling, system-wide cascading overload, configuration pushes, and beyond. To truly build a more resilient and reliable Datadog, it became clear that we could not rely on fixing the precipitating event alone. Nor is it feasible to prevent every possible perturbation of reality that causes an incident.
|
||||
|
||||
## [Why this incident hit our users so hard](https://www.datadoghq.com#why-this-incident-hit-our-users-so-hard)
|
||||
|
||||
Instead of focusing solely on the precipitating event, we turned to a more pragmatic engineering question: **Why was this incident so bad?**
|
||||
|
||||
While the impact to our systems was significant, it was not total. At peak, approximately **40–50%** of our Kubernetes nodes were still running and connecting. But from a user’s perspective, the failure was binary. The platform appeared completely down.
|
||||
|
||||
Historically, we had optimized service design to guarantee **data correctness**, often in ways that prioritized **full stop** over showing **almost correct** data. Under normal operating conditions, this is the right choice. Say you are using a metric like `aws.ec2.host_ok`, which is tagged with the host ID and records a value of `1` if the host is up and running, with a monitor that will fire if the sum (total number of hosts running) falls below a threshold. A minor delay in processing this metric could make it appear as though only 50% of your hosts are actually running, resulting in spurious alerts. To avoid this, our system would wait to report query values until tags for the metric had been fully processed, ensuring accuracy over partial visibility.
|
||||
|
||||
This bias to accuracy works well under normal circumstances, with systems fully up and running. But during a large-scale outage, it produces a **square-wave failure pattern: we cannot report on any data, because some data is missing**. This problem can be compounded by several factors: queuing systems that process in order, which can cause results to stall behind a single stuck issue and prevent real-time data from being shown immediately with recovery; retry logic that overloads downstream systems; and system designs that force specific metrics to be processed on particular nodes.
|
||||
|
||||
Overall, we identified a pattern in our systems design that needed to change: we had built with the assumption that the only way to handle failure was to prevent it entirely—or to stop everything—rather than finding ways to degrade gracefully and continue delivering value to customers, even under extreme conditions.
|
||||
|
||||
## [Why graceful degradation became a priority](https://www.datadoghq.com#why-graceful-degradation-became-a-priority)
|
||||
|
||||
Reliability has always been a priority for Datadog. We know our customers depend on us for their business, and we take that responsibility extremely seriously. But prioritizing reliability had led us to build **never-fail** architectures—systems in which components and services had to be fully functional to serve customer use cases. We built for reliability largely through redundancy, designing systems so that those components never go down in the first place.
|
||||
|
||||
This incident introduced a shift in mindset. Instead of only trying to prevent failure at every level of the system, we had to accept that no action on our part—no matter how heroic—could prevent all failures. We had to invest in not only preventing failures, but also in **failing better** when they inevitably occur.
|
||||
|
||||
Failing better means continuing to serve our customers’ priorities even when parts of the system are failing. For most of our products, that means:
|
||||
|
||||
- Data is never lost, even if it’s late.
|
||||
- Real-time data takes priority, and we avoid spending scarce resources on processing stale data.
|
||||
- Whenever possible, we serve partial-but-accurate results instead of nothing at all.
|
||||
|
||||
## [How we approached the solution](https://www.datadoghq.com#how-we-approached-the-solution)
|
||||
|
||||
With this new mindset in hand, we began making changes product by product to enable graceful degradation under unavoidable failures. Mechanically, we approached this as a company-wide program, with contributions from many individual product teams. While **graceful degradation** is a broadly applicable principle, how to implement it for any given product depends heavily on its specific customer use cases and its internal architecture. Still, common themes emerged across teams as we worked toward this goal.
|
||||
|
||||
### [Preventing data loss with persistent intake storage](https://www.datadoghq.com#preventing-data-loss-with-persistent-intake-storage)
|
||||
|
||||
During the original outage, we lost a limited but non-zero amount of customer data in unrecoverable ways. Based on our priorities outlined above, addressing the causes of this data loss was critical. **Our analysis found that one major factor was a lack of disk-based persistence at the very beginning of some processing pipelines.**
|
||||
|
||||
This gap led to data loss in two ways. First, where data was only in memory or a local disk, losing the node meant that not-yet-replicated data was lost. While our pipelines typically write to replicated data stores early in processing, some did so *after* acknowledging receipt. This approach allowed us to provide low-latency responses at intake. This meant that some data existed only on the local node and wasn’t eligible for agent retries. When those were lost, so was the data.
|
||||
|
||||
Second, our post-intake replicated data stores were often unable to accept writes following the catastrophic node loss. That meant even intake nodes that stayed online could lose data as memory and local disk buffers overflowed as the incident went on.
|
||||
|
||||
A **never-fail** approach to solving this would have relied on somehow keeping the replicated data stores able to accept data—an impossible expectation, since catastrophic failure modes are not limited to just node loss. Instead, we worked under the assumption that these data stores **would** fail, and we built substantially more robust persistent disk storage to persist data as part of intake, no matter what goes wrong. **This allows us to replay data no matter what kind of failure occurs.**
|
||||
|
||||
### [Making live data available faster](https://www.datadoghq.com#making-live-data-available-faster)
|
||||
|
||||
When we examined why this outage prevented us from serving live monitoring data, a few themes emerged. First, many of our systems were built to process all data indiscriminately, in the order it was received. This approach makes sense if you are building a system that you assume can never fail. It is simple to reason about and offers strong correctness guarantees.
|
||||
|
||||
We’ve since made changes that allow some services to **skip forward** over a processing backlog and catch up to live data as quickly as possible during recovery. We also recognized that not all telemetry data is equal—for example, some powers high-urgency monitors—and we’ve built (and continue to build) internal QoS mechanisms to prioritize processing more important data first.
|
||||
|
||||
Second, we found that in many cases, systems’ automated recovery behavior—such as processing backlogs, retries, and so on—actually made recovery slower. We addressed this by **updating retry logic in affected systems**. Retries now go to a different backend to avoid persistent failure with limited downstream failure scopes, use strong backoff mechanisms to reduce overloading, and fall back to dead letter queues sooner to avoid halting processing on single “bad” packets. We also introduced mechanisms to **throttle backlog recovery**, ensuring that old data does not preempt live data processing.
|
||||
|
||||
Finally, we found that scarce compute resources were not always directed to the most important services for live customer data. We resolved this by introducing **prioritization at the infrastructure and compute level**: we added a `PriorityClass` mechanism for our Kubernetes workloads, implemented a faster and more responsive autoscaler, and we conducted a global audit of job priorities.
|
||||
|
||||
### [Removing architectural bottlenecks and technical debt](https://www.datadoghq.com#removing-architectural-bottlenecks-and-technical-debt)
|
||||
|
||||
In some cases, the reasons for our **square-wave failure** were tightly linked to service architecture, accumulated technical debt, and historical caching decisions. For example, our metrics processing pipeline was originally designed to de-duplicate tags using a large, shared Cassandra cluster as a durable cache.
|
||||
|
||||
Over time, the need for this shared cache had diminished as services in the pipeline shifted toward relying on local caches for tag lookup. While there were plans to eventually deprecate this shared cache cluster, it was still on the critical path for processing metrics at the time of this incident. Unfortunately, a large Cassandra cluster is slow to rebuild after losing many nodes. This caused a significant delay in recovering service for customers.
|
||||
|
||||
After this incident, we prioritized removing this cache pathway to **reduce the number of non-local critical dependencies for serving real-time metrics queries**. In other cases, we identified services that could fall back to replicas or local caches and **serve slightly stale data** during backend failures, but weren’t yet configured to do so.
|
||||
|
||||
### [Scaling recovery and building for shared fate](https://www.datadoghq.com#scaling-recovery-and-building-for-shared-fate)
|
||||
|
||||
We also observed several cases where recovery was [delayed by the sheer scale of systems to recover](https://www.datadoghq.com/blog/engineering/2023-03-08-deep-dive-into-platform-level-recovery/), circular dependencies in our recovery tooling, and generally slow service startup times.
|
||||
|
||||
To address recovery at scale, we introduced additional horizontal sharding along with improvements to shared fate and data locality. For example, we moved from a single site-wide Vault instance for certificate issuance to cluster-local Vault instances with additional fallback options. While running and syncing these instances is more complex operationally, it dramatically improves our ability to begin recovery quickly—even in catastrophic scenarios— by **eliminating single bottleneck services** that were already near their scaling limits.
|
||||
|
||||
For our internal tooling (tools to recover our tools), we analyzed circular dependencies and shared-fate risks across systems like our build infrastructure, database recovery tooling, and Kafka deployment automation. We added **manual break-glass mechanisms** wherever a circular dependency could prevent recovery of our systems.
|
||||
|
||||
When looking at slow service startup, we found two common causes. The first was a **scarcity of compute resources**, which we addressed using Kubernetes priority mechanisms. The second was **services loading large, processing-intensive caches into memory at startup**. We shortened lookback windows for these caches and adjusted their data format to not require startup processing.
|
||||
|
||||
### [Maintaining control of the system](https://www.datadoghq.com#maintaining-control-of-the-system)
|
||||
|
||||
The changes we’ve made are designed to allow the system to gracefully adapt to disruption on its own, without human intervention. In some cases, we achieved that by designing the system such that failure modes naturally cause degradation that makes the most sense to the user. In others, we relied on detecting and responding to failures—for example, through automated circuit breaking or failovers. While those mechanisms **shouldn’t require human action to trigger**, we also **allow operators to override the behavior** in case of false negatives or false positives.
|
||||
|
||||
The control plane built for this purpose is also designed to degrade gracefully in case of failures. We’ve designed layers of break glass procedures that allow us to continue controlling system behaviors—perhaps with a degraded experience for operators, or requiring experts to propagate changes semi-manually. **All elements of the system, even its internal control plane, should be designed to work as well as possible even under failure.**
|
||||
|
||||
### [Replaying chaos at scale](https://www.datadoghq.com#replaying-chaos-at-scale)
|
||||
|
||||
As we built and rolled out these solutions, we used chaos testing to validate our improvements. Test plans include explicit hypotheses about how services should behave under degraded conditions, with a focus on the degradation condition itself (for example, not enough capacity to serve all traffic) rather than the specific mechanism that causes it.
|
||||
|
||||
These scenarios enable ongoing, fully automated chaos testing—confirming that our systems are now significantly better at serving customers, even under major failure scenarios.
|
||||
|
||||
## [What we’ve learned](https://www.datadoghq.com#what-weve-learned)
|
||||
|
||||
Designing our systems around inevitable failure—while still preventing failures wherever possible—represented a significant shift for many of our designs. Because the changes that enable graceful degradation often require rethinking fundamental design assumptions, we’ve taken a deliberate, careful approach. We certainly don’t want to cause new issues while trying to prevent future ones!
|
||||
|
||||
While the particulars of how to design for graceful degradation will always depend on individual services, systems, and products, we’ve identified some useful patterns and techniques:
|
||||
|
||||
- **Always start with what’s important to the end user.** Prioritizing real user needs through the end-to-end experience is at the heart of any graceful degradation story.
|
||||
- **Persist data early.** If data durability is critical, persist data as early as possible in the processing pipeline.
|
||||
- **Avoid global control systems that influence many services.** They often become new, complex failure modes.
|
||||
- **Data and query prioritization (without building a complex control plane) is key to fast recovery.** This includes strategies like processing data out of order, de-prioritizing backlogs, and so on.
|
||||
- **Check retries and caching carefully.** They’re useful, but have sharp edges and “footguns” that can make major incidents much worse if not carefully examined.
|
||||
- **Reduce technical debt dependencies.** Added complexity can be a ticking time bomb.
|
||||
- **Invest in break-glass tooling.** While smart engineers can often break circular dependencies in the moment, tooling is a better strategy.
|
||||
- **Fix your tools, not just your systems.** Tools to fix your tools are as important as tools to run your systems.
|
||||
|
||||
As we’ve made these changes to our systems, we’ve already seen that incidents are typically shorter and less disruptive. Live monitoring data and alerts, in particular, recover faster as part of system restoration. While the rare and unpredictable nature of incidents means that aggregate measures can give only an incomplete story, we see promising trends over the past two years. Notably:
|
||||
|
||||
We have a 30% decline in the number of significant incidents affecting customers’ monitors.
|
||||
|
||||
Our median time to mitigate customer impact for incidents in our logs product is down 10%; at the 95th percentile, that time is down almost 50%.
|
||||
|
||||
Incidents in our metrics product have much more limited blast radius—*most* metrics incidents affect only a limited number of metrics we process, usually less than 10%.
|
||||
|
||||
## [Building for failure—on purpose](https://www.datadoghq.com#building-for-failure-on-purpose)
|
||||
|
||||
No system can prevent every failure, but we can design for better outcomes when failure inevitably happens. The March 2023 incident reminded us that incident failures and user experience don’t always align, and that recovering quickly isn’t just about restoring systems—it’s about restoring the right systems in the right order.
|
||||
|
||||
By prioritizing graceful degradation, Datadog is building an even more resilient, customer-focused infrastructure.
|
||||
|
||||
Interested in solving problems like these at scale? **We’re hiring!**
|
||||
181
sreweekly/markdown/499/04-why-we-re-leaving-serverless.md
Normal file
181
sreweekly/markdown/499/04-why-we-re-leaving-serverless.md
Normal file
@@ -0,0 +1,181 @@
|
||||
# Why we’re leaving serverless
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Andreas Thomas — Unkey
|
||||
- **链接**: https://www.unkey.com/blog/serverless-exit
|
||||
|
||||
## 简介
|
||||
|
||||
This article does a really good job of laying out the problems with serverless that led them to leave: having to layer on significant complexity to deal with the limits of running in Cloudflare workers.
|
||||
|
||||
## 正文
|
||||
|
||||
# Why we're leaving serverless
|
||||
|
||||
|
||||
|
||||
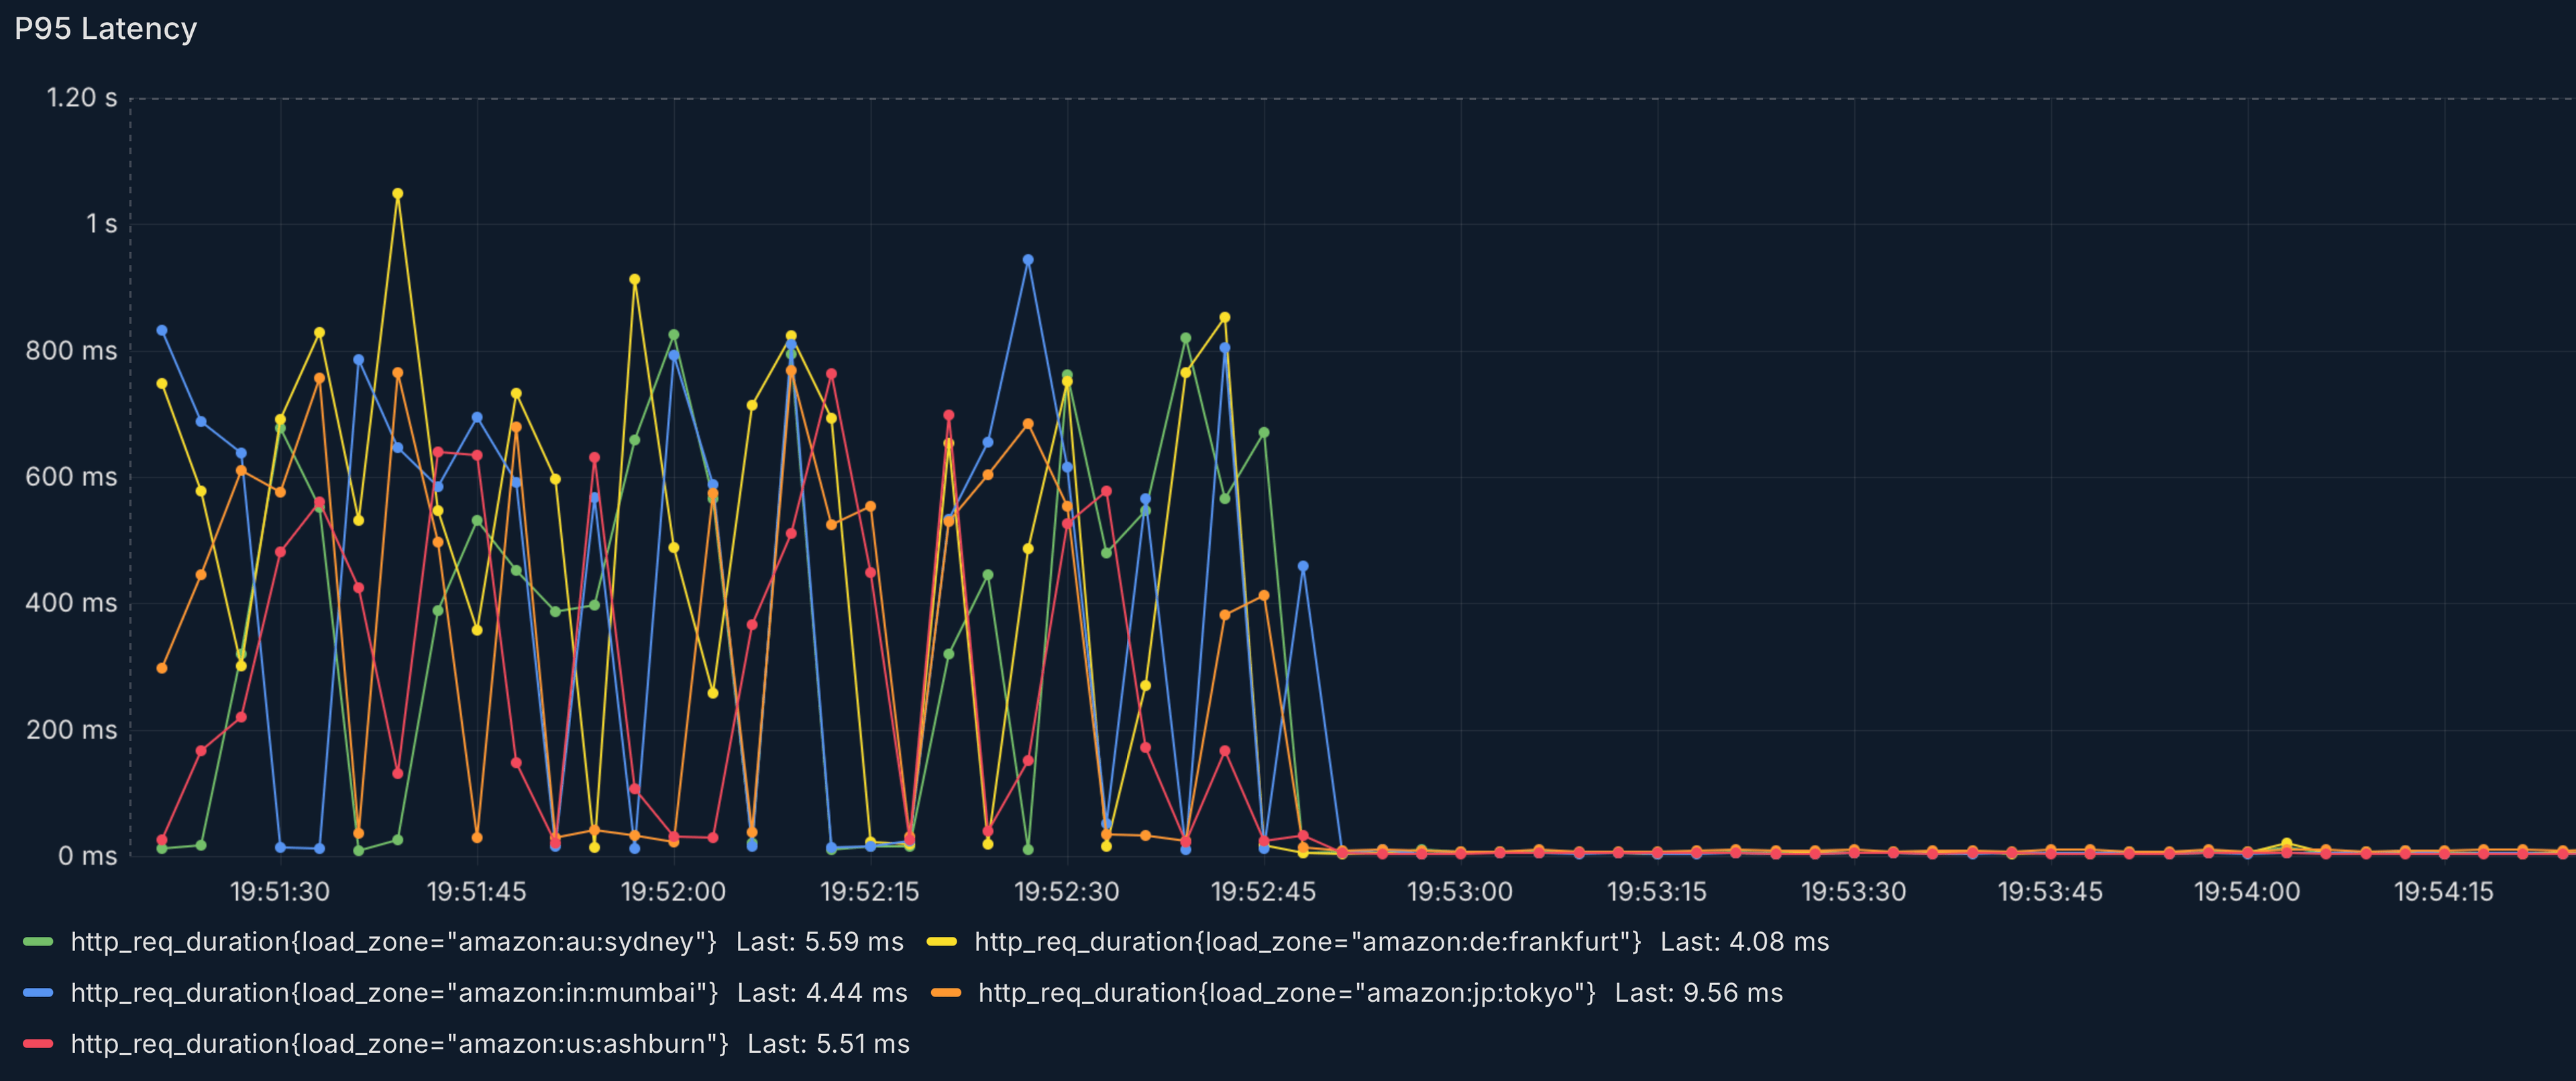
Every millisecond matters when you're in the critical path of API authentication. After two years of fighting serverless limitations, we rebuilt our entire API stack and slashed the end-to-end latency.
|
||||
|
||||
|
||||
|
||||
When we launched our API on Cloudflare Workers, it seemed like the perfect choice for an API authentication service. Global edge deployment, automatic scaling, and pay-per-use pricing. What's not to love?
|
||||
|
||||
Fast forward, and we've completely rebuilt it using stateful Go servers. The result is a 6x performance improvement and a dramatically simplified architecture that enabled self-hosting and platform independence.
|
||||
|
||||
**TL;DR:**
|
||||
|
||||
- Moved from Cloudflare Workers to Go servers
|
||||
- Lowered latency by 6x
|
||||
- Eliminated complex caching workarounds and data pipeline overhead
|
||||
- Simplified architecture from distributed system to straightforward application
|
||||
- Enabled self-hosting and platform independence
|
||||
|
||||
Here's the story of why we made this move, the problems that forced our hand, and what we learned along the way.
|
||||
|
||||
## The Performance Wall We Hit
|
||||
|
||||
When developers integrate Unkey into their request path, our latency directly impacts their users' experience. We knew we needed to be fast, but serverless was fighting us every step of the way.
|
||||
|
||||
### The Caching Problem
|
||||
|
||||
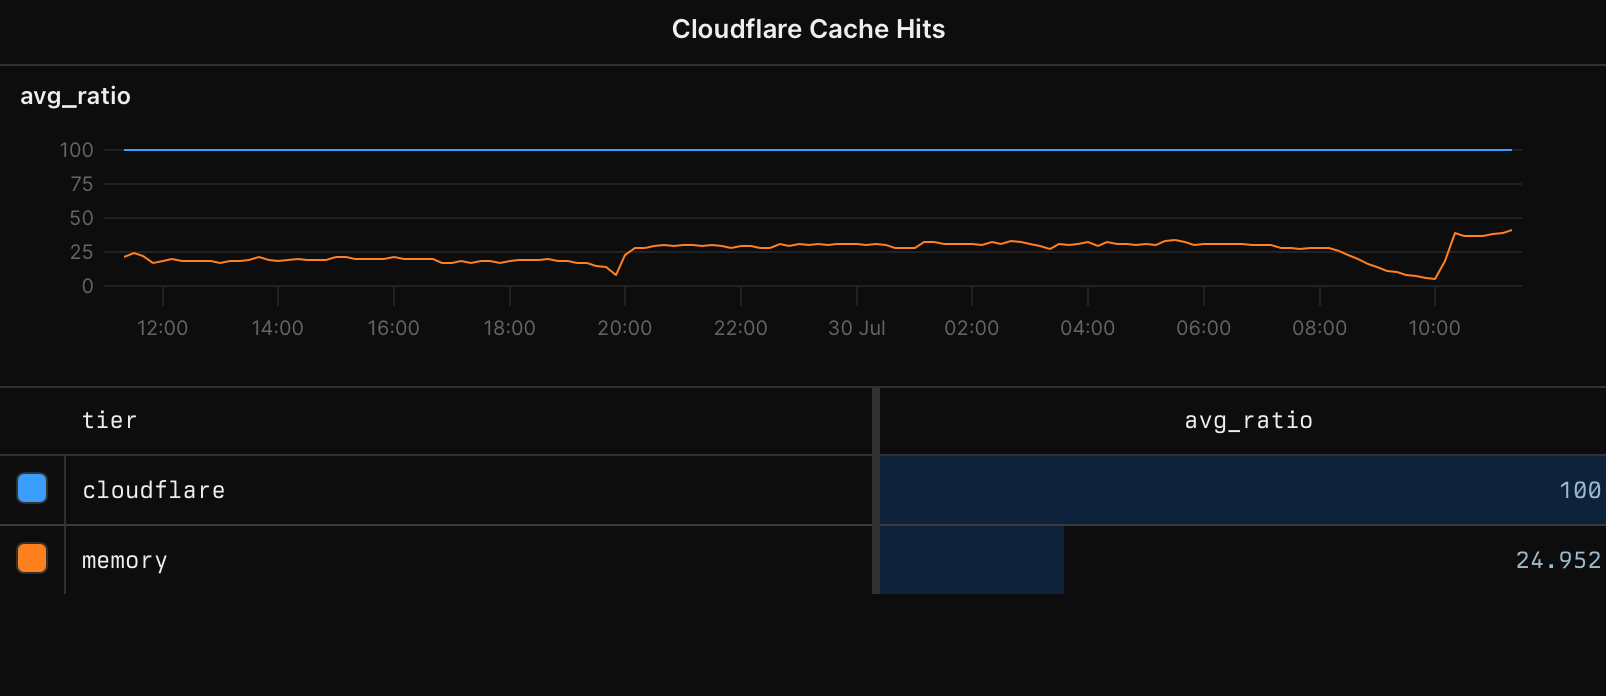
The fundamental issue was caching. In serverless, you have no guaranteed persistent memory between function invocations. Every cache read requires a network request to an external store, and that's where things got painful. We still used the global scope trick to cache some data across invocations, but the hit rates were very low.
|
||||
|
||||
|
||||
|
||||
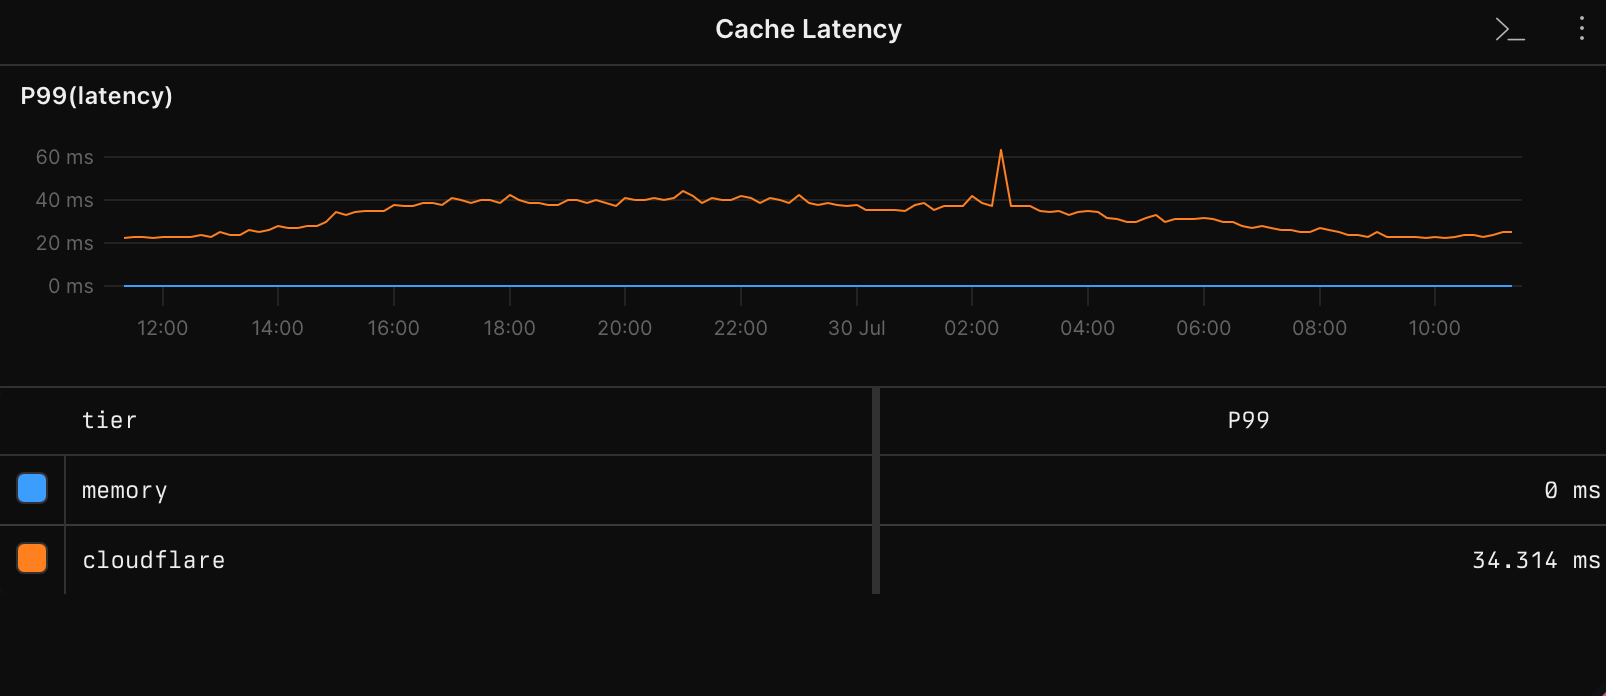
And while Cloudflare's cache had a very good hit rate, the latency was just not acceptable. It consistently took 30ms+ at p99 for cache reads. That's not necessarily terrible if you compare it to other networked caches, but when you're trying to build a sub-10ms API, it's a showstopper.
|
||||
|
||||
|
||||
|
||||
Our caching strategy used SWR across multiple tiered caches, but here's the thing: zero network requests are always faster than one network request. No amount of stacking external caches could get us around this fundamental limitation.
|
||||
|
||||
### The SaaS Glue Problem
|
||||
|
||||
Serverless promised everyone you wouldn't need to worry about operations, it just works. And for the actual function execution that was indeed our experience too. Cloudflare Workers themselves were very stable. However, you end up needing multiple other products to solve artificial problems that serverless itself created.
|
||||
|
||||
Need caching? Add Redis. Need batching? Add a Queue and downstream handler. Need real-time features? Add Something. Each service adds latency, complexity, and another point of failure in addition to charging you for their services.
|
||||
|
||||
What's frustrating is that these aren't inherent technical challenges but limitations imposed by the serverless model. In a traditional server, you'd have all of these capabilities built-in or easily accessible without network hops.
|
||||
|
||||
We ended up having to use Cloudflare Durable Objects, Cloudflare Logstreams, Cloudflare Queues, Cloudflare Workflows and then actually some homemade stateful servers on top of that.
|
||||
|
||||
We found ourselves constantly evaluating and integrating new SaaS products, not to add business value, but just to work around the constraints of our chosen architecture. Many "simple" features required researching vendors, comparing pricing, handling authentication for yet another service, and debugging network issues between systems we don't control.
|
||||
|
||||
### The Data Pipeline Nightmare
|
||||
|
||||
Performance wasn't our only problem. Getting data out of serverless functions was equally challenging.
|
||||
|
||||
**The Batching Problem**
|
||||
|
||||
Our API emits events for every key verification, rate limit, and API call. In traditional servers, you'd batch these events in memory and flush them periodically. In serverless, you have to flush on every single function invocation because the function might disappear after handling the request.
|
||||
|
||||
This led us to build an elaborate and overly complex pipeline:
|
||||
|
||||
**For Analytics Events:**
|
||||
|
||||
We built chproxy specifically because ClickHouse doesn't like thousands of tiny inserts. It's a Go service that buffers events and sends them in large batches. Each Cloudflare Worker would send individual analytics events to `chproxy`, which would then aggregate and send them to ClickHouse.
|
||||
|
||||
**For Metrics and Logs:**
|
||||
|
||||
To get metrics and logs out of Cloudflare Workers and into Axiom, we couldn't just send them directly because Axiom would sometimes reject them due to rate limits. We had to build a buffering service that would aggregate logs and metrics before sending them to Axiom without breaking the bank. Initially we thought we could just use Cloudflare Queues, but it would've been way too expensive. I think it was around trippling our current costs just to add queues.
|
||||
|
||||
Our metrics became elaborate JSON logs that Cloudflare would capture, then we had another worker acting as logdrain consumer. The consumer worker would parse the payload from Cloudflare, split the metrics events from log events and then send them off to Axiom.
|
||||
|
||||
We essentially built a distributed event processing system with multiple failure points just to work around serverless limitations.
|
||||
|
||||
## The Solution: Stateful Simplicity
|
||||
|
||||
When we decided to rebuild our API in Go for v2, the difference was immediately obvious. Instead of that complex pipeline, we could just batch events in memory and flush directly every few seconds or whenever the buffer reached a certain size.
|
||||
|
||||
That's it. No auxiliary services, no complex log pipelines, no coordination. Just straightforward batching that any server application would do.
|
||||
|
||||
### Performance Results
|
||||
|
||||
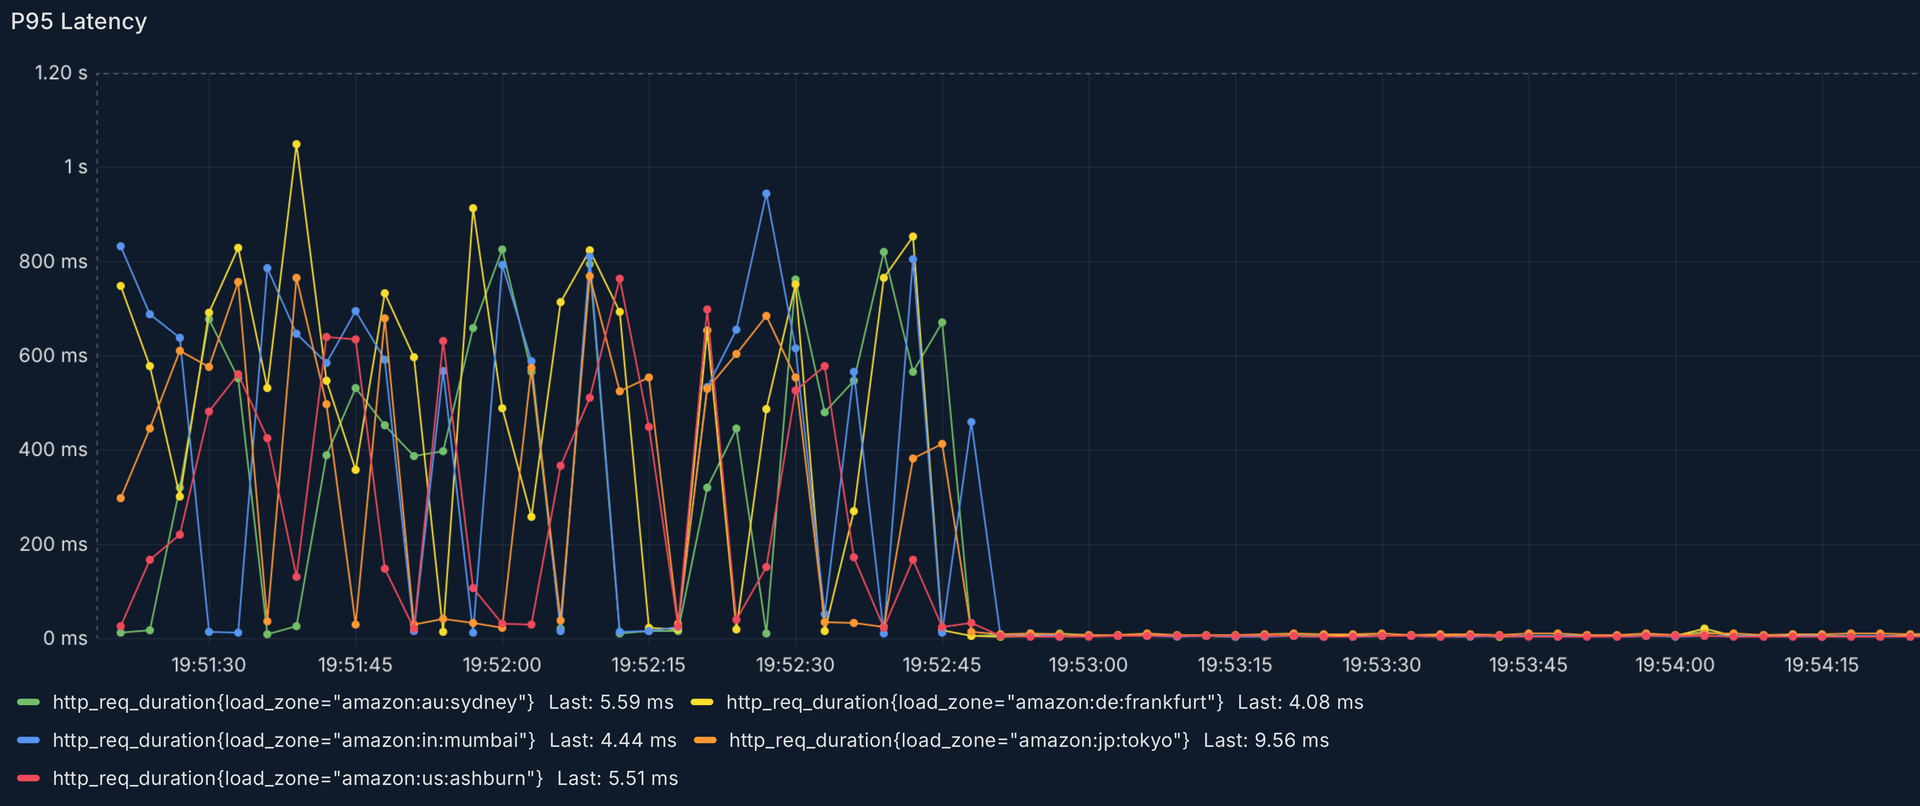
Being easier to operate or think about is one thing, but not really what our users care about. They care about performance. So how much faster is it?
|
||||
|
||||
|
||||
|
||||
We tested calling our `/v1/keys.verifyKey` endpoint from multiple regions and then switching over to `/v2/keys.verifyKey`. I think it's pretty easy to spot in the chart above.
|
||||
|
||||
Now you might say, it's kind of unfair to measure the latency from the same cloud provider as where the API runs. However that's where most of our customers are located too. So maybe this is an unfair comparison, but it accurately reflects the reality of our users' experiences. It's worth noting that the v1 API runs in over 300 POPs around the world and has datacenters in each of those regions as well.
|
||||
|
||||
## Strategic Benefits Beyond Performance
|
||||
|
||||
The move to stateful servers also unlocked other benefits.
|
||||
|
||||
### Self-Hosting
|
||||
|
||||
Being tied to Cloudflare's runtime meant our customers couldn't self-host Unkey. While the Workers runtime is technically open source, getting it running locally (even in dev mode) is incredibly difficult.
|
||||
|
||||
With standard Go servers, self-hosting becomes trivial:
|
||||
|
||||
This isn't just about customer choice. It dramatically improved our own development experience. Developers can now spin up the entire Unkey stack locally in seconds, making debugging and testing infinitely easier.
|
||||
|
||||
### Developer Experience Transformation
|
||||
|
||||
The complexity tax of serverless was affecting our entire team. Every new feature required thinking about:
|
||||
|
||||
- How to work around function limits
|
||||
- How to handle data persistence between invocations
|
||||
- How to debug issues across distributed log pipelines
|
||||
- How to test locally with Cloudflare-specific APIs
|
||||
|
||||
### Platform Independence
|
||||
|
||||
Perhaps most importantly, we're no longer locked into Cloudflare's ecosystem. We can deploy anywhere, use any database, and integrate with any third-party service without worrying about runtime compatibility.
|
||||
|
||||
## Migration Strategy and Lessons
|
||||
|
||||
We used the migration as an opportunity to fix API design issues that had accumulated over time. The new v2 API runs alongside the old v1, and customers can use both during the deprecation period.
|
||||
|
||||
The one advantage of keeping serverless around? It doesn't cost us much to keep the v1 API running as usage dwindles to zero. We're essentially getting a free migration period.
|
||||
|
||||
### What We Kept
|
||||
|
||||
We didn't throw out everything about our serverless approach:
|
||||
|
||||
- **Global edge deployment:** We're using AWS Global Accelerator to maintain low latency worldwide
|
||||
- **Automatic scaling:** Fargate handles scaling for us without the serverless constraints
|
||||
|
||||
### Rate Limiter Performance Boost
|
||||
|
||||
One area where the improvement has been particularly dramatic is our rate limiter. In the serverless model, we had to make significant tradeoffs between speed, accuracy, and cost. The distributed nature made achieving all three nearly impossible.
|
||||
|
||||
With stateful servers and in-memory state, we've been able to build a rate limiter that's faster, more accurate, and actually reduces our operational costs. We'll dive deep into this in a future post.
|
||||
|
||||
## When Serverless Makes Sense (And When It Doesn't)
|
||||
|
||||
This isn't an anti-serverless post. Serverless is fantastic for many use cases:
|
||||
|
||||
- **Infrequent workloads:** When you're not running consistently, the scaling-to-zero economics are unbeatable
|
||||
- **Simple request/response patterns:** When you don't need persistent state or complex data pipelines
|
||||
- **Event-driven architectures:** Serverless excels at responding to events without managing infrastructure
|
||||
|
||||
But serverless struggles when:
|
||||
|
||||
- **You need consistent low latency:** External networked dependencies kill performance
|
||||
- **You require persistent state:** Working around statelessness creates complexity
|
||||
- **You have high-frequency workloads:** The per-invocation model becomes expensive
|
||||
- **You need fine-grained control:** Platform abstractions can become limitations
|
||||
|
||||
### The Complexity Tax
|
||||
|
||||
The biggest lesson from our migration is understanding the complexity tax of working around platform limitations.
|
||||
|
||||
In serverless, we built:
|
||||
|
||||
- A sophisticated caching library to work around statelessness
|
||||
- Multiple auxiliary services for data batching
|
||||
- Complex log pipelines for metrics collection
|
||||
- Elaborate workarounds for local development
|
||||
|
||||
In stateful servers, all of that disappeared. We went from a distributed system with many moving parts to a straightforward application architecture.
|
||||
|
||||
Sometimes the best solution isn't to work around limitations but to choose a different foundation.
|
||||
|
||||
## What's Next
|
||||
|
||||
We're currently running on AWS Fargate behind Global Accelerator, but this is temporary. Next year, we're launching "Unkey Deploy", our own deployment platform that will let customers (and us) run Unkey anywhere they want.
|
||||
|
||||
The move to stateful Go servers was the first step in making Unkey truly portable and self-hostable. Stay tuned for more details on that front.
|
||||
|
||||
Want to see the implementation details? Both our serverless and stateful APIs are open source in our GitHub repository. The serverless version is in [`apps/api/`](https://github.com/unkeyed/unkey/tree/main/apps/api) and the new Go version is in [`go/apps/api/`](https://github.com/unkeyed/unkey/tree/main/go/apps/api).
|
||||
13
sreweekly/markdown/499/05-reliability-and-fault-tolerance.md
Normal file
13
sreweekly/markdown/499/05-reliability-and-fault-tolerance.md
Normal file
@@ -0,0 +1,13 @@
|
||||
# Reliability and Fault Tolerance
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Oakley Hall
|
||||
- **链接**: https://medium.com/@oakley349/reliability-and-fault-tolerance-6861884a3433
|
||||
|
||||
## 简介
|
||||
|
||||
This article explains the two concepts of reliability and fault tolerance and how they relate.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,13 @@
|
||||
# r/sre: Today I caused a production incident with a stupid bug
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: u/Deep-Jellyfish-2383 and others — reddit
|
||||
- **链接**: https://www.reddit.com/r/sre/comments/1p1crnq/today_i_caused_a_production_incident_with_a/
|
||||
|
||||
## 简介
|
||||
|
||||
This one could easily be titled, “Today, major system failures meant that I was able to take down production really easily.” There’s some great discussion in the comments, and I hope the author feels better.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:trafilatura returned empty
|
||||
@@ -0,0 +1,324 @@
|
||||
# Advancing Our Chef Infrastructure: Safety Without Disruption
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Archie Gunasekara — Slack
|
||||
- **链接**: https://slack.engineering/advancing-our-chef-infrastructure-safety-without-disruption/
|
||||
|
||||
## 简介
|
||||
|
||||
Slack shows how they changed their monolithic Chef cookbook change deployment process to reduce risk, by breaking production up into 6 separate environments.
|
||||
|
||||
## 正文
|
||||
|
||||
Last year, I wrote a blog post titled [Advancing Our Chef Infrastructure](https://slack.engineering/advancing-our-chef-infrastructure/), where we explored the evolution of our Chef infrastructure over the years. We talked about the shift from a single Chef stack to a multi-stack model, and the challenges that came with it – from updating how we handle cookbook uploads to navigating the limitations around Chef searches.
|
||||
|
||||
If you haven’t had a chance to read that post yet, I highly recommend checking it out first to get the full context for this post.
|
||||
|
||||
At Slack, keeping our service reliable is always the top priority. In my [last post](https://slack.engineering/advancing-our-chef-infrastructure/), I talked about the first phase of our work to make Chef and EC2 provisioning safer. With that behind us, we started looking at what else we could do to make deploys even safer and more reliable.
|
||||
|
||||
One idea we explored was moving to Chef Policyfiles. That would have meant replacing roles and environments and asking dozens of teams to change their cookbooks. In the long run, it might have made things safer, but in the short term it would have been a huge effort and added more risk than it solved.
|
||||
|
||||
So instead, this post is about the path we chose: improving our existing EC2 framework in a way that doesn’t disrupt cookbooks or roles, while still giving us more safety in our Chef deployments.
|
||||
|
||||
## Splitting Chef Environments
|
||||
|
||||
Previously, each instance had a cron job that triggered a Chef run every few hours on a set schedule. These scheduled runs were primarily for compliance purposes — to ensure our fleet remained in a consistent and defined configuration state. To reduce risk, the timing of these cron jobs was staggered across availability zones, helping us avoid running Chef on all nodes simultaneously. This strategy gave us a buffer: if a bad change was introduced, it would only impact a subset of nodes initially, giving us a chance to catch and fix the issue before it spread.
|
||||
|
||||
However, this approach had a critical limitation. With a single shared production environment, even if Chef wasn’t running everywhere at once, any newly provisioned nodes would immediately pick up the latest (possibly bad) changes from that shared environment. This became a significant reliability risk, especially during large scale-out events, where dozens or hundreds of nodes could start up with a broken configuration.
|
||||
|
||||
To address this, we split our single production Chef environment into multiple buckets: `prod-1`, `prod-2`, …, `prod-6`. Service teams could still launch instances as “prod,” but behind the scenes we mapped each instance to one of these more specific environments based on its Availability Zone. That way, new nodes no longer pulled from one global source of truth – they were evenly distributed across isolated environments, which added an extra layer of safety and resilience.
|
||||
|
||||
At Slack, our base AMIs include a tool called `Poptart Bootstrap`, which is baked in during the AMI build process. This tool runs via cloud-init at instance boot time and is responsible for tasks such as creating the node’s Chef object, setting up any required DNS entries, and posting a success or failure message to Slack (with customisable channels based on the team that owns the node).
|
||||
|
||||
To support the environment split, we extended `Poptart Bootstrap` to include logic that inspects the node’s AZ ID and assigns it to one of the numbered production Chef environments. This change allowed us to stop pointing all production nodes at a single shared Chef environment and instead spread them across multiple environments.
|
||||
|
||||
Previously, changing the cookbook versions in the single prod environment affected the entire fleet. With this new bucketed approach, we gained the flexibility to update each environment independently. Now, a change to a single environment only impacts nodes in specific AZs, significantly reducing risk and blast radius during deployments.
|
||||
|
||||

|
||||
|
||||
|
||||
With this approach, we promote the latest cookbook changes to the sandbox environments at the top of the hour. These changes are then managed by a Kubernetes cron job and rolled out to the dev environments at the top of the hour, and finally begin rolling out to production environments starting at 30 minutes past the hour.
|
||||
|
||||
`prod-1` is treated as our canary production environment. It receives updates every hour (assuming there have been new changes merged into the cookbooks) to ensure that changes are regularly exercised in a real production setting – alongside our sandbox and dev environments. This enables us to catch production-impacting issues early and in smaller, safer increments.
|
||||
|
||||
Changes to `prod-2` through `prod-6` are rolled out using a release train model. Before a new version is deployed to `prod-2`, we ensure the previous version has successfully progressed through all production environments up to `prod-6`. This staggered rollout minimises blast radius and gives us the opportunity to catch regressions earlier in the release train.
|
||||
|
||||
If we waited for a version to pass through all environments before updating `prod-1` – as we do with `prod-2` onward – we’d end up testing artifacts with large, cumulative changes. By contrast, updating prod-1 frequently with the latest version allows us to detect issues closer to when they were introduced.
|
||||
|
||||
Here’s an example showing how artifact version A moves through each environment in this release cycle:
|
||||
|
||||
### Hour X:00
|
||||
|
||||
```
|
||||
Sandbox ---> Version A (Latest)
|
||||
Dev ---> Version A (Latest)
|
||||
Prod-1 (no change - currently at version Z)
|
||||
Prod-2 (no change - currently at version Z)
|
||||
Prod-3 (no change - currently at version Z)
|
||||
Prod-4 (no change - currently at version Z)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
### Hour X:30
|
||||
|
||||
(Now that Prod-2 to Prod-6 are all on the same version, we’ll begin updating them again)
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version A)
|
||||
Dev (no change - currently at version A)
|
||||
Prod-1 ---> Version A (dev version)
|
||||
Prod-2 ---> Version A (prod-1 version)
|
||||
Prod-3 (no change - currently at version Z)
|
||||
Prod-4 (no change - currently at version Z)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
Someone committed a change, resulting in the creation of a new artifact called B.
|
||||
|
||||
### Hour (X + 1):00
|
||||
|
||||
```
|
||||
Sandbox ---> Version B (Latest)
|
||||
Dev ---> Version B (Latest)
|
||||
Prod-1 (no change - currently at version A)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version Z)
|
||||
Prod-4 (no change - currently at version Z)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
### Hour (X + 1):30
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version B)
|
||||
Dev (no change - currently at version B)
|
||||
Prod-1 ---> Version B (dev version)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 ---> Version A (prod-2 version)
|
||||
Prod-4 (no change - currently at version Z)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
Someone committed a change, resulting in the creation of a new artifact called C.
|
||||
|
||||
### Hour (X + 2):00
|
||||
|
||||
```
|
||||
Sandbox ---> Version C (Latest)
|
||||
Dev ---> Version C (Latest)
|
||||
Prod-1 (no change - currently at version B)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version Z)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
### Hour (X + 2):30
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version C)
|
||||
Dev (no change - currently at version C)
|
||||
Prod-1 ---> Version C (dev version)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 ---> Version A (prod-3 version)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
Someone committed a change, resulting in the creation of a new artifact called D.
|
||||
|
||||
### Hour (X + 3):00
|
||||
|
||||
```
|
||||
Sandbox ---> Version D (Latest)
|
||||
Dev ---> Version D (Latest)
|
||||
Prod-1 (no change - currently at version C)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 (no change - currently at version Z)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
### Hour (X + 3):30
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version D)
|
||||
Dev (no change - currently at version D)
|
||||
Prod-1 ---> Version D (dev version)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 ---> Version A (prod-4 version)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
Someone committed a change, resulting in the creation of a new artifact called E.
|
||||
|
||||
### Hour (X + 4):00
|
||||
|
||||
```
|
||||
Sandbox ---> Version E (Latest)
|
||||
Dev ---> Version E (Latest)
|
||||
Prod-1 (no change - currently at version D)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 (no change - currently at version A)
|
||||
Prod-6 (no change - currently at version Z)
|
||||
```
|
||||
### Hour (X + 4):30
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version E)
|
||||
Dev (no change - currently at version E)
|
||||
Prod-1 ---> Version E (dev version)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 (no change - currently at version A)
|
||||
Prod-6 ---> Version A (prod-5 version)
|
||||
```
|
||||
Someone committed a change, resulting in the creation of a new artifact called F.
|
||||
|
||||
### Hour (X + 5):00
|
||||
|
||||
```
|
||||
Sandbox ---> Version F (Latest)
|
||||
Dev ---> Version F (Latest)
|
||||
Prod-1 (no change - currently at version E)
|
||||
Prod-2 (no change - currently at version A)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 (no change - currently at version A)
|
||||
Prod-6 (no change - currently at version A)
|
||||
```
|
||||
Now that Prod-2 to Prod-6 are all on the same version, we’ll begin updating them again and this cycle will continue till the end of time.
|
||||
|
||||
### Hour (X + 5):30
|
||||
|
||||
```
|
||||
Sandbox (no change - currently at version F)
|
||||
Dev (no change - currently at version F)
|
||||
Prod-1 ---> Version F (dev version)
|
||||
Prod-2 ---> Version F (prod-1 version)
|
||||
Prod-3 (no change - currently at version A)
|
||||
Prod-4 (no change - currently at version A)
|
||||
Prod-5 (no change - currently at version A)
|
||||
Prod-6 (no change - currently at version A)
|
||||
```
|
||||
As you can see above, changes now take a bit longer to roll out across all our production nodes. However, this delay provides valuable time between deployments across different availability zones, allowing us to catch and address any issues before problematic changes are fully propagated.
|
||||
|
||||
By introducing split production environments (e.g., `prod-1` to `prod-6`), we’ve been able to sidestep the old problem of new nodes pulling in a bad config the moment they came online. Now, each node is tied to the environment for its AZ, and changes roll out gradually instead of everywhere at once. That means if something goes wrong in one AZ, we can keep scaling safely in the others while we fix the issue.
|
||||
|
||||
It’s a much more resilient setup than before – we’ve taken away the single point of failure and built in guardrails that make the whole system safer and more predictable.
|
||||
|
||||
## What changed in the way we trigger Chef?
|
||||
|
||||
Now that we have multiple production Chef environments, each one receives updates at different times. For example, if a version is currently in the middle of being rolled out, the next version must wait until that rollout is fully completed across all production environments. On the other hand, when there are no updates in progress, a new version can be rolled out to all environments more quickly.
|
||||
|
||||
Because of this variability, triggering Chef via a fixed cron schedule is no longer practical – we can’t reliably predict when a given Chef environment will receive new changes. As a result, we’ve moved away from scheduled runs and instead built a new service that triggers Chef runs on nodes based on signals. This service ensures Chef only runs when there are actual updates available, improving both safety and efficiency.
|
||||
|
||||
### Chef Summoner
|
||||
|
||||
|
||||
|
||||
|
||||
If you remember from my previous blog post, we built a service called Chef Librarian that watches for new Chef cookbook artifacts and uploads them to all of our Chef stacks. It also exposes an API endpoint that allows us to promote a specific version of an artifact to a given environment.
|
||||
|
||||
We recently enhanced Chef Librarian to send a message to an S3 bucket whenever it promotes a version of an artifact to an environment. The contents of that S3 bucket look like this:
|
||||
|
||||
```
|
||||
agunasekara@z-ops-agunasekara-iad-dinosaur:~ >> s3-tree BUCKET_NAME
|
||||
BUCKET_NAME
|
||||
└── chef-run-triggers
|
||||
├── basalt
|
||||
│ ├── ami-dev
|
||||
│ ├── ami-prod
|
||||
│ ├── dev
|
||||
│ ├── prod
|
||||
│ ├── prod-1
|
||||
│ ├── prod-2
|
||||
│ ├── prod-3
|
||||
│ ├── prod-4
|
||||
│ ├── prod-5
|
||||
│ ├── prod-6
|
||||
│ └── sandbox
|
||||
└── ironstone
|
||||
├── ami-dev
|
||||
├── ami-prod
|
||||
├── dev
|
||||
├── prod
|
||||
├── prod-1
|
||||
├── prod-2
|
||||
├── prod-3
|
||||
├── prod-4
|
||||
├── prod-5
|
||||
├── prod-6
|
||||
└── sandbox
|
||||
```
|
||||
Under the chef-run-triggers key, we maintain a nested structure where each key represents one of our Chef stacks. Within each stack key, there are additional keys for each environment name.
|
||||
|
||||
Each of these environment keys contains a JSON object with contents similar to the example below:
|
||||
|
||||
```
|
||||
{
|
||||
"Splay": 15,
|
||||
"Timestamp": "2025-07-28T02:02:31.054989714Z",
|
||||
"ManifestRecord": {
|
||||
"version": "20250728.1753666491.0",
|
||||
"chef_shard": "basalt",
|
||||
"datetime": 1753666611,
|
||||
"latest_commit_hash": "XXXXXXXXXXXXXX",
|
||||
"manifest_content": {
|
||||
"base_version": "20250728.1753666491.0",
|
||||
"latest_commit_hash": "XXXXXXXXXXXXXX",
|
||||
"author": "Archie Gunasekara <agunasekara@slack-corp.com>",
|
||||
"cookbook_versions": {
|
||||
"apt": "7.5.23",
|
||||
...
|
||||
"aws": "9.2.1"
|
||||
},
|
||||
"site_cookbook_versions": {
|
||||
"apache2": "20250728.1753666491.0",
|
||||
...
|
||||
"squid": "20250728.1753666491.0"
|
||||
}
|
||||
},
|
||||
"s3_bucket": "BUCKET_NAME",
|
||||
"s3_key": "20250728.1753666491.0.tar.gz",
|
||||
"ttl": 1756085811,
|
||||
"upload_complete": true
|
||||
}
|
||||
}
|
||||
```
|
||||
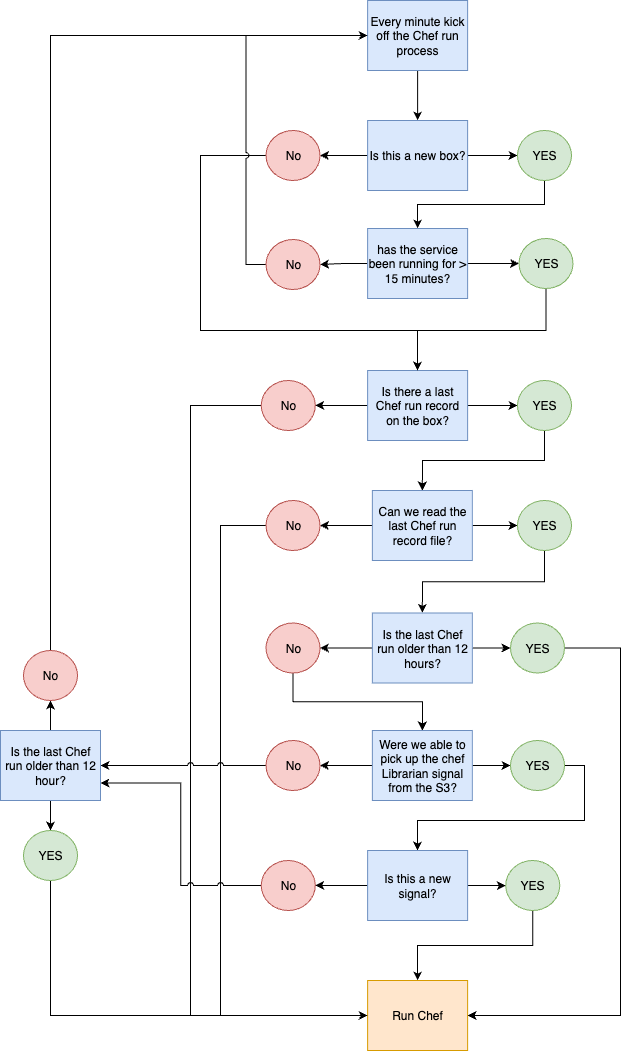
Next, we built a service called Chef Summoner. This service runs on every node at Slack and is responsible for checking the S3 key corresponding to the node’s Chef stack and environment. If a new version is present in the signal sent out by Chef Librarian, the service reads the configured splay value and schedules a Chef run accordingly.
|
||||
|
||||
The splay is used to stagger Chef runs so that not all nodes in a given environment and stack try to run Chef at the same time. This helps avoid spikes in load and resource contention. We can also customize the splay depending on our needs – for example, when we trigger a Chef run using a custom signal from Librarian and want to spread the runs out more intentionally.
|
||||
|
||||
However, if no changes are merged and no new Chef artifacts are built, Librarian has nothing to promote, and no new signals are sent out. Despite that, we still need to ensure Chef runs at least once every 12 hours to maintain compliance and ensure nodes stay in their expected configuration state. So, Chef Summoner will also run Chef at least once every 12 hours, even if no new signals have been received.
|
||||
|
||||
The Summoner service keeps track of its own state locally – this includes things like the last run time and the artifact version used – so it can compare any new signals with the most recent run and determine whether a new Chef run is required.
|
||||
|
||||
The overall flow looks like this:
|
||||
|
||||
|
||||
|
||||
|
||||
Now that Chef Summoner is the primary mechanism we rely on to trigger Chef runs, it becomes a critical piece of infrastructure. After a node is provisioned, subsequent Chef runs are responsible for keeping Chef Summoner itself up to date with the latest changes.
|
||||
|
||||
But if we accidentally roll out a broken version of Chef Summoner, it may stop triggering Chef runs altogether – making it impossible to roll out a fixed version using our normal deployment flow.
|
||||
|
||||
To mitigate this, we bake in a fallback cron job on every node. This cron job checks the local state that Chef Summoner stores (e.g., last run time and artifact version) and ensures Chef has been run at least once every 12 hours. If the cron job detects that Chef Summoner has failed to run Chef in that timeframe, it will trigger a Chef run directly. This gives us a recovery path to push a working version of Chef Summoner back out.
|
||||
|
||||
In addition to this safety net, we also have tooling that allows us to trigger ad hoc Chef runs across the fleet or a subset of nodes when needed.
|
||||
|
||||
## What’s Next?
|
||||
|
||||
All of these recent changes to our EC2 ecosystem have made rolling out infrastructure changes significantly safer. Teams no longer have to worry about a bad update impacting the entire fleet. While we’ve come a long way, the platform is still not perfect.
|
||||
|
||||
One major limitation is that we still can’t easily support service-level deployments. In theory, we could create a dedicated set of Chef environments for each service and promote artifacts individually – but with the hundreds of services we operate at Slack, this quickly becomes unmanageable at scale.
|
||||
|
||||
With that in mind, we’ve decided to mark our legacy EC2 platform as feature complete and move it into maintenance mode. In its place, we’re building a brand-new EC2 ecosystem called Shipyard, designed specifically for teams that can’t yet move to our container-based platform, Bedrock.
|
||||
|
||||
Shipyard isn’t just an iteration of our old system – it’s a complete reimagining of how EC2-based services should work. It introduces concepts like service-level deployments, metric-driven rollouts, and fully automated rollbacks when things go wrong.
|
||||
|
||||
We’re currently building a Shipyard and targeting a soft launch this quarter, with plans to onboard our first two teams for testing and feedback. I’m excited to share more about Shipyard in my next blog post – stay tuned!
|
||||
@@ -0,0 +1,23 @@
|
||||
# You’ll never see attrition referenced in an RCA
|
||||
|
||||
- **期号**: SRE Weekly Issue #499(2025-11-30)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2025/11/02/youll-never-see-attrition-referenced-in-an-rca/
|
||||
|
||||
## 简介
|
||||
|
||||
The author discusses reasons why engineer attrition won’t appear in a public incident write-up, and may well not appear in a private one, either.
|
||||
|
||||
## 正文
|
||||
|
||||
In the wake of the [recent AWS us-east-1 outage](https://aws.amazon.com/message/101925/), I saw speculation online about how the departure of experienced engineers played a role in the outage. The most notable one was from the acerbic cloud economist Corey Quinn, in a column he wrote for The Register: [Amazon brain drain finally sent AWS down the spout](https://www.theregister.com/2025/10/20/aws_outage_amazon_brain_drain_corey_quinn/). Amazon’s recent announcement that it will be [laying off about 14,000 employees](https://techstory.in/inside-amazons-2025-layoffs-why-14000-jobs-were-cut-and-what-comes-next/), which includes cuts to AWS, has added fuel to that fire, as I saw in a [LinkedIn post by Java luminary and former AWS-er James Gosling](https://www.linkedin.com/feed/update/urn:li:activity:7390531807277932544/) that referenced another speculative column on the subject [Amazon Just Proved AI Isn’t The Answer Yet Again](https://www.planetearthandbeyond.co/p/amazon-just-proved-ai-isnt-the-answer?r=6hpwx&triedRedirect=true). I’m not going to comment on the accuracy of these assessments, or more broadly the role that attrition played on this particular incident, because I don’t have any special knowledge here. Instead, I want to use this as an opportunity to talk about the relationship between attrition and incidents, and how that relationship is captured in incident write-ups, both public and internal.
|
||||
|
||||
In a public incident write-up, or an RCA provided by a vendor to a customer, you’re never going to see any discussion of the role of attrition. This is because, as noted by John Allspaw in his post [What makes public posts about incidents different from analysis write-ups](https://www.adaptivecapacitylabs.com/2021/08/22/what-makes-public-posts-about-incidents-different-from-analysis-write-ups/), the purpose of a public write-up is to *reassure the audience that the problem that caused the incident is being addressed.* This means that the write-up will focus on describing a technical problem and alluding to the technical solution that is being addressed to fix the problem. Attrition isn’t a technical problem, it’s a completely different type of phenomenon. And, as we’ve seen with the recent Amazon layoff announcement, attrition is sometimes an explicit business decision. If a company like Amazon mentioned attrition in a public write-up, it would be much more difficult to answer a question like “how will your upcoming layoff increase the risk of incidents?” There’s no plausible deniability (“it won’t increase the risk of incidents”) if you’ve previously talked about attrition in a public write-up. Because talking about attrition doesn’t fulfill the confidence-building role of the write-up, it’s not going to ever find its way into a document intended for outsiders.
|
||||
|
||||
Internal incident write-ups serve a different purpose, and so they don’t have this problem. Indeed, in my own career, I have seen references to the departure of expertise in internal incident write-ups. The first example that comes to mind is the *hot potato* scenario where there’s a critical service where the original authors are no longer at the company, and the team that originally owned it no longer exists, and so another team becomes responsible for operating that service, even though they don’t have deep knowledge of how the service actually works, and it is so reliable that the team that now owns it doesn’t accumulate operational experience with it. I would wager that every tech company of a certain size has seen this pattern. I’ve also frequently heard discussion of [bus factor](https://en.wikipedia.org/wiki/Bus_factor), which is an explicit reference to attrition risk.
|
||||
|
||||
Still, while referencing attrition isn’t a taboo in an internal incident write-up the way it is in a public incident write-up, you’re still not likely to see the topic discussed there. Internal incident write-ups take a narrow view of system failures, focusing on technical details. I wrote a blog post several years ago titled [What’s allowed to count as a cause?](https://surfingcomplexity.blog/2021/07/18/whats-allowed-to-count-as-a-cause/), and attrition is an example of an issue that falls squarely in the “not allowed to count” category.
|
||||
|
||||
Now, you might say, “Lorin, this is exactly why *five whys* is good, so we can zoom out to identify systemic issues.” My response would be, “attrition is never going to be the sole reason for a failure in a complex system, and identifying only attrition as a factor is just as bad as identifying a different factor and neglecting attrition, because you’re missing so much.” I think of the role of attrition as a contributor to incidents the way that smoking is a contributor to lung cancer, or that climate change is a contributor to severe weather events. It isn’t possible to attribute a particular incidence of lung cancer to smoking, or a particular severe storm to climate changes: smoking is neither necessary nor sufficient for lung cancer, and climate change is neither necessary nor sufficient for a particular storm to be severe. But as with attrition, smoking and climate changes are factors that increase risk. If you use a *root cause analysis* approach to understanding incidents, you’ll miss the role of contributing factors like attrition.
|
||||
|
||||
I would go so far to say that organizational factors play a role in every major incident, where attrition is just one example of an organizational factor. The fact that these don’t appear in the write-up says more about the questions that people didn’t ask than it does about the nature of the incident.
|
||||
Reference in New Issue
Block a user