SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,368 @@
|
||||
# Building SRE Error Budgets for AI/ML Workloads: A Practical Framework
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Varun Kumar Reddy Gajjala — DZone
|
||||
- **链接**: https://dzone.com/articles/building-sre-error-budgets-for-ai-ml-workloads
|
||||
|
||||
## 简介
|
||||
|
||||
> ML systems decay gradually instead of breaking suddenly, so we need error budgets for model accuracy, data freshness, and fairness — not just uptime.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# Building SRE Error Budgets for AI/ML Workloads: A Practical Framework
|
||||
|
||||
ML systems decay gradually instead of breaking suddenly, so we need error budgets for model accuracy, data freshness, and fairness — not just uptime.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
Here's a problem I've seen happen far too often: your recommendation system is functioning, spitting out results in milliseconds, and meeting all its infrastructure SLAs. Everything is looking rosy in the dashboard world. Yet engagement has plummeted by 40% because your model has been pointless for several weeks.
|
||||
|
||||
On behalf of your traditional error budget? You're golden. According to your product team? The system is broken.
|
||||
|
||||
ML systems fail in ways that were not accounted for in classical [SRE practices](https://dzone.com/articles/the-guide-to-sre-principles). A model does not 'go down'; it gradually deteriorates. Data pipelines can be 'working' while providing garbage to the model. And you won't even realize this until users start to complain or, worst, quietly depart.
|
||||
|
||||
The past few years spent breaking and fixing ML systems have taught me that we need a paradigm shift in our error budget. Here's how it works.
|
||||
|
||||
## Understanding the Limitations of Conventional Error Budgets
|
||||
|
||||
The challenge here is that "reliability" in ML does not live on a one-dimensional spectrum. Your [API](https://dzone.com/articles/everything-you-should-know-about-apis) could be functioning correctly even if your model is not working. Your model could be working correctly even if your data pipeline is providing stale features to your model. You could be doing great on your aggregate numbers even if you're treating some users unfairly.
|
||||
|
||||
What I've found is that you need to break down four different error budgets.
|
||||
|
||||
## Mapping These to Actual Error Budgets
|
||||
|
||||
Before delving into each dimension, I must clarify the application of these to conventional SRE error budgets — not merely health checks:
|
||||
|
||||
For each dimension, you require:
|
||||
|
||||
• **SLI (service level indicator)**: What you're measuring
|
||||
|
||||
• **SLO (service level objective)**: Your target over time
|
||||
|
||||
• **Error budget**: How much you can miss the SLO before you take action
|
||||
|
||||
Here's what model quality means with concrete examples:
|
||||
|
||||
**SLI**: Accuracy of the model compared with the baseline, hourly
|
||||
|
||||
**SLO**: Accuracy ≥ 92% of Baseline over the rolling 7 days
|
||||
|
||||
**Error budget**: 8% allowable error in 7 days
|
||||
|
||||
**Burn rate**: Monitor hourly; warn for burning above 10% of budget daily
|
||||
|
||||
The main difference versus an error budget is that you're measuring degradation relative to a known-good state as opposed to just measuring success or failure. The math is exactly the same in both cases — a time budget that gets spent if you don't meet your SLO.
|
||||
|
||||
Now, let's consider every dimension one by one:
|
||||
|
||||
## 1. Infrastructure Error Budget
|
||||
|
||||
These are your standard SRE metrics: uptime, latency, and success rate of requests. It's old news, but you should have this as your baseline.
|
||||
|
||||
**What I monitor**: 99.95% availability, latency of sub-150ms at p95, 99.9% success rate
|
||||
|
||||
## 2. Model Quality Error Budget
|
||||
|
||||
This is where it gets fascinating. You must specify at what point you are willing to let the degradation of your model become noisy.
|
||||
|
||||
**What I track**:
|
||||
|
||||
• Model accuracy vs baseline accuracy (typically up to 8% loss)
|
||||
|
||||
• Percentage of low-confidence predictions
|
||||
|
||||
• Distribution of feature drift via statistical tests
|
||||
|
||||
Here's how I can determine degradation:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Compare Current Performance with Your Personal Benchmark
|
||||
accuracy_degradation = (baseline_accuracy - current_accuracy) / baseline_accuracy
|
||||
budget_burn_rate = accuracy_degradation / acceptable_degradation
|
||||
```
|
||||
**Real example**: Accuracy decreased from 95% to 93%, my threshold is 8%
|
||||
|
||||
As for drift detection, I employ the Kolmogorov-Smirnov test:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Verify distribution of features has changed
|
||||
from scipy.stats import ks_2samp
|
||||
statistic, p_value = ks_2samp(baseline_features, current_features)
|
||||
drift_alert = p_value < 0.05
|
||||
```
|
||||
**One thing that bit me**: Tie your model accuracy metrics to business metrics. Rather than accuracy percentages, track something your PM cares about — for example, "click-through rate stays within 95% of baseline."
|
||||
|
||||
## 3. Data Quality Error Budget
|
||||
|
||||
Garbage in, garbage out. However, the ML system "garbage" needs a different definition.
|
||||
|
||||
What matters:
|
||||
|
||||
• Feature completeness score (my target is 99%+)
|
||||
|
||||
• Feature freshness degree (how many features are stale?)
|
||||
|
||||
• Schema violations
|
||||
|
||||
**Simple quality check**:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
def simple_quality_check(features):
|
||||
missing_rate = missing_features / total_features
|
||||
stale_rate = stale_features / total_features
|
||||
data_quality_score = min(1 - missing_rate, 1 - stale_rate)
|
||||
meets_sli = data_quality_score > 0.99
|
||||
```
|
||||
Traditional data pipelines only cared about having a correct schema. When working with [machine learning](https://dzone.com/articles/machine-learning-unleashing-the-power-of-artificia), you also want to ensure that your data features are fresh enough and that your distributions look fairly regular. I've been burned before working on pipelines that "worked" but passed day-old data, making our model irrelevant.
|
||||
|
||||
## 4. Fairness Error Budget
|
||||
|
||||
In your case, fairness can be either desirable or mandatory. Regardless, it should be tracked.
|
||||
|
||||
What I monitor:
|
||||
|
||||
• Differences in accuracy across demographic groups (this is under 5%)
|
||||
|
||||
• False positive rate parity across segments
|
||||
|
||||
To calculate disparate impact:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Determine disparate impact
|
||||
group_A_rate = predictions[group == 'A'].mean()
|
||||
group_B_rate = predictions[group == 'B'].mean()
|
||||
disparity = abs(group_A_rate - group_B_rate)
|
||||
violation = disparity > 0.05 # flag if over 5%
|
||||
```
|
||||
There is no such dimension in traditional SRE because a traditional system is not involved in people's decision-making. However, as soon as your machine learning system starts approving loans or ranking candidates for jobs, you want to determine whether your system is treating people fairly.
|
||||
|
||||
### Critical Caveats
|
||||
|
||||
Fairness metrics are extremely domain-specific and complex from a legal standpoint. The metrics that I am presenting here are only examples, and demographic parity is not necessarily a good thing for every problem you want to solve. Before using fairness budgets:
|
||||
|
||||
- Discuss with lawyers the way in which fairness may be considered in your regulatory environment
|
||||
- Coordinate with the product and policy teams on identifying the acceptable tradeoffs
|
||||
- Reflect on whether you have the right to maintain, process, or use sensitive attributes for monitoring purposes
|
||||
- Do not use simplistic parity checks as the sole indicators of fairness
|
||||
|
||||
In regulated industries such as finance, healthcare, or hiring, you require knowledge that goes beyond the capabilities of any framework.
|
||||
|
||||
## How to Actually Implement This
|
||||
|
||||
### Step 1: Determine How Reliability Applies in Your Business
|
||||
|
||||
Don't begin with metrics in mind. Begin with conversations instead. "What is a broken model in the eyes of my PM?" "What will make my users grumble?"
|
||||
|
||||
For an ML-driven search functionality, you can choose:
|
||||
|
||||
- **Infrastructure** : Less than 200 ms (p95)
|
||||
- **Model quality** : Relevance scores greater than 0.85 relative to human assessors
|
||||
- **Data quality** : Less than 1% of queries missing critical features
|
||||
- **Fairness** : Search diversity preserved when considering different user categories
|
||||
|
||||
### Step 2: Establish Your Baseline
|
||||
|
||||
Run your system in a stable state for 30 days. Observe what "good" looks like.
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Calculate your baseline during a stable period
|
||||
baseline = {
|
||||
'accuracy': np.percentile(stable_metrics['accuracy'], 50),
|
||||
'p95_latency': np.percentile(stable_metrics['latency'], 95),
|
||||
'drift_threshold': calculate_drift_threshold(stable_features)
|
||||
}
|
||||
```
|
||||
This becomes your north star. All else shall be measured from that.
|
||||
|
||||
### Step 3: Define Ownership
|
||||
|
||||
This is crucial. Each dimension must have a "clear owner" to make decisions and take actions:
|
||||
|
||||
**Infrastructure budget → SRE owns**:
|
||||
|
||||
• Right to suspend deployments
|
||||
|
||||
• Authority to reverse modifications
|
||||
|
||||
• Infrastructure scaling authority
|
||||
|
||||
**Model quality budget → ML engineering owns**:
|
||||
|
||||
• Authority for triggering retraining
|
||||
|
||||
• Authority to roll back to previous model version
|
||||
|
||||
• Power to increase monitoring frequency
|
||||
|
||||
**Data quality budget → data engineering owns**:
|
||||
|
||||
• Power to halt data pipelines
|
||||
|
||||
• Authority to enable fallback data sources
|
||||
|
||||
• Right to disregard upstream data
|
||||
|
||||
**Fairness budget → ML + product + legal own together**:
|
||||
|
||||
• Needs a multi-stakeholder decision for any actions
|
||||
|
||||
• Product evaluates business impact
|
||||
|
||||
• Legal specifies compliance requirements
|
||||
|
||||
• ML applies technical solutions
|
||||
|
||||
If the budget constraints are conflicting, such that model quality is satisfactory, but fairness is violated, then the more constraining budget prevails. If you have depleted your fairness budget, you cannot just rely on your predictions for satisfactory accuracy.
|
||||
|
||||
### Step 4: Monitor Everything
|
||||
|
||||
Establish dashboards to measure all four key dimensions. Here's how I calculate the composite health factors:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Current health across dimensions
|
||||
dimensions = {
|
||||
'infrastructure': 0.95, # meeting 95% of SLO
|
||||
'model_quality': 0.88, # at 88% of baseline
|
||||
'data_quality': 0.98,
|
||||
'fairness': 0.96
|
||||
}
|
||||
# Weight them according to what is important to your business
|
||||
weights = {
|
||||
'infrastructure': 0.3,
|
||||
'model_quality': 0.35,
|
||||
'data_quality': 0.2,
|
||||
'fairness': 0.15
|
||||
}
|
||||
composite_score = sum(dimensions[d] * weights[d] for d in dimensions)
|
||||
```
|
||||
**Critical note**: The composite score is solely for executive visibility. Hard enforcement always happens on a per-dimension basis. Having a 90% composite score does not supersede a violation in any dimension. You are in violation if you blow your fairness budget.
|
||||
|
||||
### Step 5: Know What to Do When Budgets Blow Up
|
||||
|
||||
This list should be recorded prior to having a situation on your hands:
|
||||
|
||||
- **Infrastructure budget spent out** : Stop deployments, undo changes made, see if scale is required
|
||||
- **Model quality budget used up** : Kick off the retraining process, think about reverting to the former model version, and look at what changed in your dataset
|
||||
- **Data Quality budget exhausted** : Check your upstream data sources, validate your ETL pipeline, turn on feature fallbacks if you have them
|
||||
- **Fairness budget used up** : If it's bad, then simply stop making predictions for those subgroups. Don't release it to society until you figure out where you introduced unfair bias and retrain.
|
||||
|
||||
## A Real Example: Fraud Detection
|
||||
|
||||
Let me illustrate what I mean with a system for preventing fraud that I built for a fintech company.
|
||||
|
||||
Our error budgets:
|
||||
|
||||
- **Infrastructure** : 99.99% uptime, under 100ms at p95
|
||||
- **Model quality** : Precision above 95%, Recall above 90%, False Positive Rate below 2%
|
||||
- **Data quality** : +99.5% feature completion rate, <1% stale features
|
||||
- **Fairness** : FPR differences across merchant types <3%
|
||||
|
||||
Here's what our code for monitoring looked like:
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Validating the health of each batch of predictions made
|
||||
def check_fraud_detection_health(predictions, features, ground_truth):
|
||||
# Did model quality degrade?
|
||||
current_precision = precision_score(ground_truth, predictions)
|
||||
precision_violation = (baseline - current_precision) / baseline > 0.02
|
||||
# Are features getting stale?
|
||||
stale_rate = features[features['age_hours'] > 24].shape[0] / len(features)
|
||||
data_violation = stale_rate > 0.01
|
||||
# Fairness issues regarding various merchants?
|
||||
fprs = calculate_fpr_by_category(predictions, ground_truth)
|
||||
fairness_violation = max(fprs.values()) - min(fprs.values()) > 0.03
|
||||
return any([precision_violation, data_violation, fairness_violation])
|
||||
```
|
||||
**The "interesting" part**: All these dimensions are actually tested in every prediction batch. It helps you detect issues early, as data quality problems could become evident before affecting model performance.
|
||||
|
||||
## A Few Things I've Learned
|
||||
|
||||
### Use Rolling Windows Where Time-Based Budgets Are Required
|
||||
|
||||
Monthly budgets aren't really effective in ML either. You may have a bad week when you're retraining your model, but you can't waste the rest of the budget.
|
||||
|
||||
*I use 7-day rolling windows instead — still time budgets, but with a sliding window.*
|
||||
|
||||
Python
|
||||
|
||||
|
||||
|
||||
```
|
||||
from collections import deque
|
||||
# Measurements deque with maxlen of 7 days * 24 hours
|
||||
measurements = deque(maxlen=168)
|
||||
measurements.append({'timestamp': now, 'accuracy': current_accuracy})
|
||||
avg_accuracy = sum([m['accuracy'] for m in measurements]) / len(measurements)
|
||||
budget_ok = avg_accuracy >= target_accuracy
|
||||
```
|
||||
This provides some buffer for recovering from transient problems without having to call bankruptcy for the month. You're still measuring reliability over time (the point of error budgets), but the window slides smoothly rather than restarting each month.
|
||||
|
||||
### Budget According to What Is Happening
|
||||
|
||||
In a large product rollout, I'll cut model quality budgets (can't have the model shaming us during peak traffic) while relaxing latency requirements slightly. It's fine to adjust these based on context, just be sure to record the reasoning behind adjustments as they happen.
|
||||
|
||||
### Be Alert for Cascading Failures
|
||||
|
||||
"Garbage in, garbage out" applies here, too: bad data input leads to bad model output, which, in turn, results in more attempts and fallbacks, thus more load on the infrastructure. It is where having budgets per dimension comes in handy, as it allows you to zero in on where the problem actually occurred.
|
||||
|
||||
## Wrapping Up
|
||||
|
||||
Conventional error budgets account for failures in infrastructure, such as servers becoming unavailable and requests timing out. They fail to account, however, for failure in ML, which occurs in terms of model drift, pipelines with stale features, and biased predictions in terms of user segments.
|
||||
|
||||
This framework identifies these failures early. By monitoring the degradation of model quality with time, you address the issue before it affects users. By monitoring the freshness of the data, you identify the pipeline failures before their impact affects your predictions. By monitoring fairness, you identify bias before it turns into a compliance issue.
|
||||
|
||||
The actual gains in reliability come from the following three sources:
|
||||
|
||||
- **Earlier detection** : You detect degradation trends before outages
|
||||
- **Root cause clarity** : When quality goes down, you know if it's the infrastructure or the quality of the data
|
||||
- **Clear accountability** : Every factor has a clear owner who has clear action power
|
||||
|
||||
You want to start with the budget on infrastructure and the quality of models. Get familiar with tracking the baseline and calculating the burn rate. Once you're comfortable with that, you can integrate the data quality tracking. Fairness tracking is what you want to do last. It's the most complex aspect of fairness, and it's the most dependent on the domain.
|
||||
|
||||
Your set of metrics will be different from mine in specifics. A recommendation system can deal with variation in its accuracy results better compared to the fraud detector system. However, the model that consists of four aspects, budgets that consider time intervals, and ownership that is clearly stated has proved to be effective throughout the models involving ML that I have used before.
|
||||
|
||||
The aim is not about preventing all cases of model deterioration. It is about understanding it, comprehending why it happens, and having the power to correct it before it shatters user trust.
|
||||
|
||||
Site reliability engineering
|
||||
Framework
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
@@ -0,0 +1,202 @@
|
||||
# Why Enterprises Overfund Failure and Underfund Prevention
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Florian Hoeppner
|
||||
- **链接**: https://techaccelerationandresilience.com/blog-posts/why-enterprises-overfund-failure-and-underfund-prevention
|
||||
|
||||
## 简介
|
||||
|
||||
> Enterprises rarely fail because they don’t care about reliability.They fail because:failure is loud,prevention is quiet,and budgeting systems are wired to respond to noise.
|
||||
|
||||
## 正文
|
||||
|
||||
# Why Enterprises Overfund Failure and Underfund Prevention
|
||||
|
||||
Most reliability debates start with technology and end with frustration.
|
||||
|
||||
——————————————-
|
||||
|
||||
Want to try it out? Take the 5-minute Reliability U-Curve Assessment → reliabilityeconomics.com/benchmark
|
||||
|
||||
———————————————
|
||||
|
||||
Do we need more redundancy?
|
||||
|
||||
More automation?
|
||||
|
||||
More “nines”?
|
||||
|
||||
But after working with large enterprises for years, I’ve come to a different conclusion:
|
||||
|
||||
*Most organizations don’t have a reliability problem. They have a failure-funding problem.*
|
||||
|
||||
|
||||
### The hidden bias in how reliability gets funded
|
||||
|
||||
In theory, organizations want stability, resilience, and predictable delivery.
|
||||
|
||||
In practice, money flows very differently.
|
||||
|
||||
There are two fundamentally different cost buckets:
|
||||
|
||||
- **Failure cost (reactive):** incidents, war rooms, hotfixes, customer impact, escalation overhead
|
||||
- **Prevention cost (proactive):** SLOs, automation, resilience patterns, testing, observability, compliance-by-design
|
||||
|
||||
Only one of these is *visible and urgent*.
|
||||
|
||||
Failure cost:
|
||||
|
||||
- shows up as outages,
|
||||
- triggers executive attention,
|
||||
- creates immediate pressure to “do something.”
|
||||
|
||||
Prevention cost:
|
||||
|
||||
- is mostly invisible,
|
||||
- pays off over time,
|
||||
- competes with feature delivery and short-term KPIs.
|
||||
|
||||
So organizations do what humans and systems always do under pressure:
|
||||
|
||||
they **optimize for what hurts now**, not for what compounds later.
|
||||
|
||||
### Why “we’ll fix it in incident response” feels rational (but isn’t)
|
||||
|
||||
From a budgeting perspective, failure remediation feels safe:
|
||||
|
||||
- Incidents are real.
|
||||
- Customers are angry.
|
||||
- Regulators are watching.
|
||||
- Action is justified.
|
||||
|
||||
Prevention, on the other hand, requires belief:
|
||||
|
||||
- belief that future incidents will be avoided,
|
||||
- belief that automation will pay off,
|
||||
- belief that today’s effort reduces tomorrow’s cost.
|
||||
|
||||
That belief is hard to defend in quarterly planning cycles.
|
||||
|
||||
The result is a predictable pattern:
|
||||
|
||||
- incident response teams grow,
|
||||
- processes accrete,
|
||||
- coordination overhead increases,
|
||||
- and yet reliability outcomes improve only marginally.
|
||||
|
||||
This is how organizations end up **spending more every year on failure without ever feeling “done.”**
|
||||
|
||||
### The reliability U-curve (in one sentence)
|
||||
|
||||
As reliability improves:
|
||||
|
||||
- **failure cost goes down** ,
|
||||
- **prevention cost goes up** ,
|
||||
- and **total cost forms a U-shape** .
|
||||
|
||||
The bottom of that curve is the point where **total spend is minimized**.
|
||||
|
||||
Most enterprises never intentionally look for that point.
|
||||
|
||||
They drift along the curve driven by incidents, not economics.
|
||||
|
||||
### Why this is not a failure-mode or probability model
|
||||
|
||||
A common (and valid) objection is:
|
||||
|
||||
*“Failure costs depend on likelihood, failure modes, SLAs, and contracts. You can’t aggregate this.”*
|
||||
|
||||
|
||||
That’s true, at the *failure-mode* level.
|
||||
|
||||
But this is not a failure-mode model.
|
||||
|
||||
It’s a **portfolio-level diagnostic** designed to answer a simpler question:
|
||||
|
||||
Are we structurally overpaying for failure compared to prevention for this service or journey?
|
||||
|
||||
|
||||
At that level:
|
||||
|
||||
- recurring operational failures already “price in” likelihood,
|
||||
- black-swan events should be treated separately and selectively,
|
||||
- and perfect modeling is often the enemy of usable decisions.
|
||||
|
||||
This is not about precision.
|
||||
|
||||
It’s about **direction**.
|
||||
|
||||
### What happens when you make both sides visible
|
||||
|
||||
When organizations put **failure cost and prevention cost side by side**, something interesting happens.
|
||||
|
||||
They realize that:
|
||||
|
||||
- incident labor and coordination time dominate downtime cost,
|
||||
- release delays and context switching are real economic drag,
|
||||
- compliance overhead is often paid manually instead of being automated,
|
||||
- and prevention is often far cheaper than the failures it could eliminate.
|
||||
|
||||
In many large environments, it’s not unusual to see:
|
||||
|
||||
*monthly failure cost 5–10× higher than prevention spend*
|
||||
|
||||
for a single tier-1 service.
|
||||
|
||||
|
||||
At that point, the conversation changes.
|
||||
|
||||
Not because of SRE ideology, but because of economics.
|
||||
|
||||
### The shift that actually matters
|
||||
|
||||
This isn’t about chasing “five nines.”
|
||||
|
||||
It’s about shifting from:
|
||||
|
||||
- **funding failure because it’s visible** ,
|
||||
to
|
||||
- **funding prevention because it’s cheaper** .
|
||||
|
||||
That shift only happens when:
|
||||
|
||||
- engineering brings data about failure drag,
|
||||
- finance helps frame recurring cost,
|
||||
- leadership sets explicit risk tolerance.
|
||||
|
||||
Reliability improves not because teams try harder, but because **the system starts rewarding the right investments**.
|
||||
|
||||
### A practical starting point
|
||||
|
||||
You don’t need a perfect model to begin.
|
||||
|
||||
Pick:
|
||||
|
||||
- one service or customer journey,
|
||||
- estimate monthly failure cost,
|
||||
- estimate monthly prevention cost,
|
||||
- sanity-check outcomes via SLOs or error budgets.
|
||||
|
||||
The goal is not to be “right.”
|
||||
|
||||
The goal is to stop being **blind**.
|
||||
|
||||
### Final thought
|
||||
|
||||
Enterprises rarely fail because they don’t care about reliability.
|
||||
|
||||
They fail because:
|
||||
|
||||
- failure is loud,
|
||||
- prevention is quiet,
|
||||
- and budgeting systems are wired to respond to noise.
|
||||
|
||||
Until we change that, we’ll keep getting better at fixing incidents, and worse at preventing them.
|
||||
|
||||
→ If you want a practical starting point, message me **“INVERSION”** and I’ll share a lightweight diagnostic to estimate your current position on the U-curve and where the optimum likely sits.
|
||||
|
||||
→ We explore these ideas in much more depth in our book, *Mastering Site Reliability Engineering in Enterprise,* a complete guide to building resilient, chaos-tolerant systems, available on Amazon and Springer.
|
||||
|
||||
Book (Amazon): [Mastering Site Reliability Engineering in Enterprise now on](https://www.amazon.com/Mastering-Site-Reliability-Engineering-Enterprise/dp/B0DYHQXZBQ/) [amazon.com](http://amazon.com/)
|
||||
|
||||
Book (Springer): [Mastering Site Reliability Engineering in Enterprise on Springer](https://doi.org/10.1007/979-8-8688-1448-8)
|
||||
@@ -0,0 +1,13 @@
|
||||
# Automating RDS Postgres to Aurora Postgres Migration
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Ram Srivasta Kannan, Wale Akintayo, Jay Bharadwaj, John Crimmins, Shengwei Wang, and Zhitao Zhu — Netflix
|
||||
- **链接**: https://netflixtechblog.com/automating-rds-postgres-to-aurora-postgres-migration-261ca045447f
|
||||
|
||||
## 简介
|
||||
|
||||
They had hundreds of databases to migrate, so they built a tested, self-service migration workflow.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,196 @@
|
||||
# Shedding old code with ecdysis: graceful restarts for Rust services at Cloudflare
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Manuel Olguín Muñoz — Cloudflare
|
||||
- **链接**: https://blog.cloudflare.com/ecdysis-rust-graceful-restarts/
|
||||
|
||||
## 简介
|
||||
|
||||
I love the technical description of socket juggling to achieve a graceful restart. I could swear that this technique has been around for decades though, for example in TinyMUX et al…
|
||||
|
||||
## 正文
|
||||
|
||||
# Shedding old code with ecdysis: graceful restarts for Rust services at Cloudflare
|
||||
|
||||

|
||||
|
||||
ecdysis | *ˈekdəsəs* |
|
||||
|
||||
noun
|
||||
|
||||
the process of shedding the old skin (in reptiles) or casting off the outer
|
||||
|
||||
cuticle (in insects and other arthropods).
|
||||
|
||||
|
||||
How do you upgrade a network service, handling millions of requests per second around the globe, without disrupting even a single connection?
|
||||
|
||||
One of our solutions at Cloudflare to this massive challenge has long been [**__ecdysis__**](https://github.com/cloudflare/ecdysis), a Rust library that implements graceful process restarts where no live connections are dropped, and no new connections are refused.
|
||||
|
||||
Last month, **we open-sourced ecdysis**, so now anyone can use it. After five years of production use at Cloudflare, ecdysis has proven itself by enabling zero-downtime upgrades across our critical Rust infrastructure, saving millions of requests with every restart across Cloudflare’s [__global network__](https://www.cloudflare.com/network/).
|
||||
|
||||
It’s hard to overstate the importance of getting these upgrades right, especially at the scale of Cloudflare’s network. Many of our services perform critical tasks such as traffic routing, [__TLS lifecycle management__](https://www.cloudflare.com/application-services/solutions/certificate-lifecycle-management/), or firewall rules enforcement, and must operate continuously. If one of these services goes down, even for an instant, the cascading impact can be catastrophic. Dropped connections and failed requests quickly lead to degraded customer performance and business impact.
|
||||
|
||||
When these services need updates, security patches can’t wait. Bug fixes need deployment and new features must roll out.
|
||||
|
||||
The naive approach involves waiting for the old process to be stopped before spinning up the new one, but this creates a window of time where connections are refused and requests are dropped. For a service handling thousands of requests per second in a single location, multiply that across hundreds of data centers, and a brief restart becomes millions of failed requests globally.
|
||||
|
||||
Let’s dig into the problem, and how ecdysis has been the solution for us — and maybe will be for you.
|
||||
|
||||
**Links**: [GitHub](https://github.com/cloudflare/ecdysis) **|** [crates.io](https://crates.io/crates/ecdysis) **|** [docs.rs](https://docs.rs/ecdysis)
|
||||
|
||||
### Why graceful restarts are hard
|
||||
|
||||
The naive approach to restarting a service, as we mentioned, is to stop the old process and start a new one. This works acceptably for simple services that don’t handle real-time requests, but for network services processing live connections, this approach has critical limitations.
|
||||
|
||||
First, the naive approach creates a window during which no process is listening for incoming connections. When the old process stops, it closes its listening sockets, which causes the OS to immediately refuse new connections with `ECONNREFUSED`. Even if the new process starts immediately, there will always be a gap where nothing is accepting connections, whether milliseconds or seconds. For a service handling thousands of requests per second, even a gap of 100ms means hundreds of dropped connections.
|
||||
|
||||
Second, stopping the old process kills all already-established connections. A client uploading a large file or streaming video gets abruptly disconnected. Long-lived connections like WebSockets or gRPC streams are terminated mid-operation. From the client’s perspective, the service simply vanishes.
|
||||
|
||||
Binding the new process before shutting down the old one appears to solve this, but also introduces additional issues. The kernel normally allows only one process to bind to an address:port combination, but [__the SO_REUSEPORT socket option__](https://man7.org/linux/man-pages/man7/socket.7.html) permits multiple binds. However, this creates a problem during process transitions that makes it unsuitable for graceful restarts.
|
||||
|
||||
When `SO_REUSEPORT` is used, the kernel creates separate listening sockets for each process and [__load balances new connections across these sockets__](https://lwn.net/Articles/542629/). When the initial `SYN` packet for a connection is received, the kernel will assign it to one of the listening processes. Once the initial handshake is completed, the connection then sits in the `accept()` queue of the process until the process accepts it. If the process then exits before accepting this connection, it becomes orphaned and is terminated by the kernel. GitHub’s engineering team documented this issue extensively when [__building their GLB Director load balancer__](https://github.blog/2020-10-07-glb-director-zero-downtime-load-balancer-updates/).
|
||||
|
||||
### How ecdysis works
|
||||
|
||||
When we set out to design and build ecdysis, we identified four key goals for the library:
|
||||
|
||||
1. **Old code can be completely shut down** post-upgrade.
|
||||
2. **The new process has a grace period** for initialization.
|
||||
3. **New code crashing during initialization is acceptable** and shouldn’t affect the running service.
|
||||
4. **Only a single upgrade runs in parallel** to avoid cascading failures.
|
||||
|
||||
ecdysis satisfies these requirements following an approach pioneered by NGINX, which has supported graceful upgrades since its early days. The approach is straightforward:
|
||||
|
||||
1. The parent process `fork()` s a new child process.
|
||||
2. The child process replaces itself with a new version of the code with `execve()` .
|
||||
3. The child process inherits the socket file descriptors via a named pipe shared with the parent.
|
||||
4. The parent process waits for the child process to signal readiness before shutting down.
|
||||
|
||||

|
||||
|
||||
Crucially, the socket remains open throughout the transition. The child process inherits the listening socket from the parent as a file descriptor shared via a named pipe. During the child's initialization, both processes share the same underlying kernel data structure, allowing the parent to continue accepting and processing new and existing connections. Once the child completes initialization, it notifies the parent and begins accepting connections. Upon receiving this ready notification, the parent immediately closes its copy of the listening socket and continues handling only existing connections.
|
||||
|
||||
This process eliminates coverage gaps while providing the child a safe initialization window. There is a brief window of time when both the parent and child may accept connections concurrently. This is intentional; any connections accepted by the parent are simply handled until completion as part of the draining process.
|
||||
|
||||
This model also provides the required crash safety. If the child process fails during initialization (e.g., due to a configuration error), it simply exits. Since the parent never stopped listening, no connections are dropped, and the upgrade can be retried once the problem is fixed.
|
||||
|
||||
ecdysis implements the forking model with first-class support for asynchronous programming through [__Tokio__](https://tokio.rs) and s`ystemd` integration:
|
||||
|
||||
- **Tokio integration** : Native async stream wrappers for Tokio. Inherited sockets become listeners without additional glue code. For synchronous services, ecdysis supports operation without async runtime requirements.
|
||||
- **systemd-notify support** : When the`systemd_notify` feature is enabled, ecdysis automatically integrates with systemd’s process lifecycle notifications. Setting`Type=notify-reload` in your service unit file allows systemd to track upgrades correctly.
|
||||
- **systemd named sockets** : The`systemd_sockets` feature enables ecdysis to manage systemd-activated sockets. Your service can be socket-activated and support graceful restarts simultaneously.
|
||||
|
||||
Platform note: ecdysis relies on Unix-specific syscalls for socket inheritance and process management. It does not work on Windows. This is a fundamental limitation of the forking approach.
|
||||
|
||||
### Security considerations
|
||||
|
||||
Graceful restarts introduce security considerations. The forking model creates a brief window where two process generations coexist, both with access to the same listening sockets and potentially sensitive file descriptors.
|
||||
|
||||
ecdysis addresses these concerns through its design:
|
||||
|
||||
**Fork-then-exec**: ecdysis follows the traditional Unix pattern of `fork()` followed immediately by `execve()`. This ensures the child process starts with a clean slate: new address space, fresh code, and no inherited memory. Only explicitly-passed file descriptors cross the boundary.
|
||||
|
||||
**Explicit inheritance**: Only listening sockets and communication pipes are inherited. Other file descriptors are closed via `CLOEXEC` flags. This prevents accidental leakage of sensitive handles.
|
||||
|
||||
**seccomp compatibility**: Services using seccomp filters must allow `fork()` and `execve()`. This is a tradeoff: graceful restarts require these syscalls, so they cannot be blocked.
|
||||
|
||||
For most network services, these tradeoffs are acceptable. The security of the fork-exec model is well understood and has been battle-tested for decades in software like NGINX and Apache.
|
||||
|
||||
### Code example
|
||||
|
||||
Let’s look at a practical example. Here’s a simplified TCP echo server that supports graceful restarts:
|
||||
|
||||
```
|
||||
use ecdysis::tokio_ecdysis::{SignalKind, StopOnShutdown, TokioEcdysisBuilder};
|
||||
use tokio::{net::TcpStream, task::JoinSet};
|
||||
use futures::StreamExt;
|
||||
use std::net::SocketAddr;
|
||||
#[tokio::main]
|
||||
async fn main() {
|
||||
// Create the ecdysis builder
|
||||
let mut ecdysis_builder = TokioEcdysisBuilder::new(
|
||||
SignalKind::hangup() // Trigger upgrade/reload on SIGHUP
|
||||
).unwrap();
|
||||
// Trigger stop on SIGUSR1
|
||||
ecdysis_builder
|
||||
.stop_on_signal(SignalKind::user_defined1())
|
||||
.unwrap();
|
||||
// Create listening socket - will be inherited by children
|
||||
let addr: SocketAddr = "0.0.0.0:8080".parse().unwrap();
|
||||
let stream = ecdysis_builder
|
||||
.build_listen_tcp(StopOnShutdown::Yes, addr, |builder, addr| {
|
||||
builder.set_reuse_address(true)?;
|
||||
builder.bind(&addr.into())?;
|
||||
builder.listen(128)?;
|
||||
Ok(builder.into())
|
||||
})
|
||||
.unwrap();
|
||||
// Spawn task to handle connections
|
||||
let server_handle = tokio::spawn(async move {
|
||||
let mut stream = stream;
|
||||
let mut set = JoinSet::new();
|
||||
while let Some(Ok(socket)) = stream.next().await {
|
||||
set.spawn(handle_connection(socket));
|
||||
}
|
||||
set.join_all().await;
|
||||
});
|
||||
// Signal readiness and wait for shutdown
|
||||
let (_ecdysis, shutdown_fut) = ecdysis_builder.ready().unwrap();
|
||||
let shutdown_reason = shutdown_fut.await;
|
||||
log::info!("Shutting down: {:?}", shutdown_reason);
|
||||
// Gracefully drain connections
|
||||
server_handle.await.unwrap();
|
||||
}
|
||||
async fn handle_connection(mut socket: TcpStream) {
|
||||
// Echo connection logic here
|
||||
}
|
||||
```
|
||||
The key points:
|
||||
|
||||
1. **`build_listen_tcp`** creates a listener that will be inherited by child processes.
|
||||
2. **`ready()`** signals to the parent process that initialization is complete and that it can safely exit.
|
||||
3. **`shutdown_fut.await`** blocks until an upgrade or stop is requested. This future only yields once the process should be shut down, either because an upgrade/reload was executed successfully or because a shutdown signal was received.
|
||||
|
||||
When you send `SIGHUP` to this process, here’s what ecdysis does…
|
||||
|
||||
*…on the parent process:*
|
||||
|
||||
- Forks and execs a new instance of your binary.
|
||||
- Passes the listening socket to the child.
|
||||
- Waits for the child to call `ready()` .
|
||||
- Drains existing connections, then exits.
|
||||
|
||||
*…on the child process:*
|
||||
|
||||
- Initializes itself following the same execution flow as the parent, except any sockets owned by ecdysis are inherited and not bound by the child.
|
||||
- Signals readiness to the parent by calling `ready()` .
|
||||
- Blocks waiting for a shutdown or upgrade signal.
|
||||
|
||||
### Production at scale
|
||||
|
||||
ecdysis has been running in production at Cloudflare since 2021. It powers critical Rust infrastructure services deployed across 330+ data centers in 120+ countries. These services handle billions of requests per day and require frequent updates for security patches, feature releases, and configuration changes.
|
||||
|
||||
Every restart using ecdysis saves hundreds of thousands of requests that would otherwise be dropped during a naive stop/start cycle. Across our global footprint, this translates to millions of preserved connections and improved reliability for customers.
|
||||
|
||||
### ecdysis vs alternatives
|
||||
|
||||
Graceful restart libraries exist for several ecosystems. Understanding when to use ecdysis versus alternatives is critical to choosing the right tool.
|
||||
|
||||
[**__tableflip__**](https://github.com/cloudflare/tableflip) is our Go library that inspired ecdysis. It implements the same fork-and-inherit model for Go services. If you need Go, tableflip is a great option!
|
||||
|
||||
[**__shellflip__**](https://github.com/cloudflare/shellflip) is Cloudflare’s other Rust graceful restart library, designed specifically for Oxy, our Rust-based proxy. shellflip is more opinionated: it assumes systemd and Tokio, and focuses on transferring arbitrary application state between parent and child. This makes it excellent for complex stateful services, or services that want to apply such aggressive sandboxing that they can’t even open their own sockets, but adds overhead for simpler cases.
|
||||
|
||||
### Start building
|
||||
|
||||
ecdysis brings five years of production-hardened graceful restart capabilities to the Rust ecosystem. It’s the same technology protecting millions of connections across Cloudflare’s global network, now open-sourced and available for anyone!
|
||||
|
||||
Full documentation is available at [__docs.rs/ecdysis__](https://docs.rs/ecdysis), including API reference, examples for common use cases, and steps for integrating with `systemd`.
|
||||
|
||||
The [__examples directory__](https://github.com/cloudflare/ecdysis/tree/main/examples) in the repository contains working code demonstrating TCP listeners, Unix socket listeners, and systemd integration.
|
||||
|
||||
The library is actively maintained by the Argo Smart Routing & Orpheus team, with contributions from teams across Cloudflare. We welcome contributions, bug reports, and feature requests on [__GitHub__](https://github.com/cloudflare/ecdysis).
|
||||
|
||||
Whether you’re building a high-performance proxy, a long-lived API server, or any network service where uptime matters, ecdysis can provide a foundation for zero-downtime operations.
|
||||
|
||||
Start building: [__github.com/cloudflare/ecdysis__](https://github.com/cloudflare/ecdysis)
|
||||
@@ -0,0 +1,63 @@
|
||||
# Lots of AI SRE, no AI incident management
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2026/02/14/lots-of-ai-sre-no-ai-incident-management/
|
||||
|
||||
## 简介
|
||||
|
||||
Lorin goes into what an AI incident manager might look like, since no tools of the sort exist yet.
|
||||
|
||||
## 正文
|
||||
|
||||
With the value of AI coding tools now firmly established in the software industry, the next frontier is AI SRE tools. There are a number of AI SRE vendors. In some cases, vendors are adding AI SRE functionality to extend their existing product lineup, a quick online search reveals one such as [PagerDuty’s SRE Agents](https://www.pagerduty.com/platform/ai-agents/sre/), [Datadog’s Bits AI SRE](https://www.datadoghq.com/product/ai/bits-ai-sre/), [incident.io’s AI SRE](https://incident.io/ai-sre), [Microsoft’s Azure SRE Agent](https://azure.microsoft.com/en-us/products/sre-agent/), and [Rootly’s AI SRE](https://rootly.com/ai-sre). There are also a number of pure play AI SRE startups: the ones I’ve heard of are [Cleric](https://cleric.ai/), [Resolve.ai](https://resolve.ai/), [Anyshift.io](https://www.anyshift.io/), and [RunWhen](https://www.runwhen.com/). My sense of the industry is that AI SRE is currently in the evaluation phase, compared to the coding tools which are in the adoption phase.
|
||||
|
||||
What I want to write about today is not so much what these AI tools do contribute to resolving incidents, but rather what they don’t contribute. These tools are focused on diagnostic and mitigation work. The idea is to try to automate as much as possible the work of figuring out what the current problem is, and then resolving it. I think most of the focus is, rightly, on the diagnostic side at this stage, although I’m sure automated resolution is also something being pursued. But what none of these tools try to do, as far as I can tell, is *incident management*.
|
||||
|
||||
The work of incident response always involves a group of engineers: some of them are officially on-call, and others are just jumping in to help. Incident management is the coordination work that helps this ad-hoc team of responders work together effectively to get the diagnostic and remediation work done. Because of this, we often say that incident response is a team sport. Incidents involve some sort of problem with the system as a whole, and because everybody in the organization only has partial knowledge of the whole system, we typically need to pool that knowledge together to make sense of what’s actually happening right now in the system. For example, if a database is currently being overloaded, the folks who own the database could tell you that there’s been a change in query pattern, but they wouldn’t be able to tell you *why* that change happened. For that, you’d need to talk to the team that owns the system that makes those queries.
|
||||
|
||||
## Fixation: the single-agent problem
|
||||
|
||||
|
||||
|
||||
[Sincerely Media](https://unsplash.com/photos/two-white-rabbits-JkgVHEFSolA)
|
||||
|
||||
Another reason why we need multiple people responding to incidents is that humans are prone to a problem known as *fixation*. You might know it by the more colloquial term *tunnel vision*. A person will look at a problem from a particular perspective, and that can be problematic if the person addressing the problem has a perspective that is not well-matched to solving that problem. You can even see fixation behavior in the current crop of LLM coding tools: they will sometimes keep going down an unproductive path in order to implement a feature or try to resolve an error. While I expect that future coding agents will suffer less from fixation, given that genuinely intelligent humans frequently suffer from this problem, I don’t think that we’ll ever see an individual coding agent get to the point where it completely avoids fixation traps.
|
||||
|
||||
One solution to the problem of fixation is to intentionally inject a diversity of perspectives by having multiple individuals attack the problem. In the case of AI coding tools, we deal with the problem of fixation by having a human supervise the work of the coding agent. The human spots when the agent falls down a fixation rabbit hole, and prompts the agent to pursue a different strategy in order to get it back on track. Another way to leverage multiple individuals to is to strategically have them pursue different strategies. For example, in the early oughts, there was a lot of empirical software engineering research into an approach called [perspective-based reading](https://www.cs.umd.edu/~basili/publications/journals/J79.pdf) for reviewing software artifacts like requirements or design documents. The idea is that you would have multiple reviewers, and you would explicitly assign a reviewer a particular perspective. For example, let’s say you wanted to get a requirements document reviewed. You could have one reviewer read it from the perspective of a *user*, another from the perspective of a *designer*, and a third from the perspective of a *tester*. The idea here is that reading from a different perspective would help identify different kinds of defects in the artifact.
|
||||
|
||||
Getting back to incidents, the problem of fixation arises when a responder latches on to one particular hypothesis about what’s wrong with the system, and continues following on that particular line of investigation, even though it doesn’t bear fruit. As discussed above, having responders with a diverse set of perspectives provides a defense against fixation. This may take the form of multiple lines of doing multiple lines of investigation, or even just somebody in the response asking a question like, “How do we know the problem isn’t Y rather than X?”
|
||||
|
||||
I’m convinced that an individual AI SRE agent will never be able to escape the problem of fixation, and so that incident response will necessarily involve multiple agents. Yes, there will be some incidents where a single AI agent is sufficient. But incident response is a 100% game: you need to recover from *all* of them. That means that eventually you’ll need to deploy a team of agents, whether they’re humans, AI, or a mix. And that means incident response will require coordination: in particular, maintaining common ground.
|
||||
|
||||
## Maintaining common ground is active work
|
||||
|
||||
During an incident, many different things are happening at once. There are multiple signals that you need to keep track of, like “what’s the current customer impact?”, “is the problem getting better, worse, or staying the same?”, “what are the current hypotheses?”, “which graphs support or contradict those hypotheses?” The responders will be doing diagnostic work, and they’ll be performing interventions to the system, sometimes to try to mitigate (e.g., “roll back that feature flag that aligns in time”), and other times to support the diagnostic work (e.g., “we need to make a change to figure out if hypothesis X is actually correct.”)
|
||||
|
||||
The incident manager helps to maintain common ground: they make sure that everybody is on the same page, by doing things like helping bring people up to speed on what’s currently going on, and ensuring people know which lines of investigation are currently being pursued and who (if anyone) is currently pursuing them.
|
||||
|
||||
If a responder is just joining an incident, an AI SRE agent is extremely useful as a summary machine. You can ask it the question, “what’s going on?”, and it can give you a concise summary of the state of play. But this is a passive use case: you prompt it, and it gives a response. But because the state of the world is changing rapidly during the incident, the accuracy of that answer will decay rapidly with time. Keeping the current state of things up to date in the minds of the responders is an *active* struggle against entropy.
|
||||
|
||||
An effective AI incident manager would have to be able to identify what type of coordination help people need, and then provide that assistance. For example, the agent would have to be able to identify when the responders (be they human or agent) were struggling and then proactively take action to assist. It would need a model of the mental models of the responders to know when to act and what to action to take in order to re-establish common ground.
|
||||
|
||||
Perhaps there is work in the AI SRE space to automate this sort of coordination work. But if there is, I haven’t heard of it yet. The focus today is on creating individual responder agents. I think these agents will be an effective addition to an incident response team. I’d love it if somebody built an effective incident management AI bot. But it’s a big leap from AI SRE agent to AI incident management agent. And it’s not clear to me how well the coordination problem is understood by vendors today.
|
||||
|
||||
An AI SRE agent off working on it’s own without coordinating with humans and other agents, seems like a recipe for creating more problems. The SRE agent changes a thing only nothing else knows about that change. Something else changes it back because unaware that broke it. SRE changes it again. Repeat ad infinitum.
|
||||
|
||||
Without the AI involved, we see that plenty of the time, an unreported change in behavior is the cause of an incident. The lack of change coordination causes issues all the time. Many of those are intended as “fixes.”
|
||||
|
||||
Relying solely on an AI-based SRE would not be fully effective, as it could lead to untracked changes and limited visibility into what has actually been modified. A more balanced and reliable approach would be to combine the strengths of both AI-driven SRE systems and human engineers to ensure accountability, context-aware decision-making, and effective issue resolution at the site reliability engineering level.
|
||||
|
||||
This is exactly the gap we’re solving. While everyone’s building AI SRE (diagnostics/mitigation), we’re building AI incident management – coordination, common ground, and the human side of incidents. We’re building an orchestrator with a pager of AI agents to handle exactly that. Check us out at vibraniumlabs.ai – would love your take.
|
||||
|
||||
The fixation problem you describe has an economic dimension that makes it worse. Of 34 enterprise services I’ve assessed, teams spending over 25% of capacity on reactive work are 2.3x more likely to report 11+ monthly incidents. Those teams don’t have the capacity for the coordination work you’re describing. They’re too deep in the single-agent reactive loop to step back and maintain common ground. The AI SRE tools that automate diagnosis might free up that capacity in theory. But the coordination gap you’ve identified means the freed capacity doesn’t automatically become better incident management. It becomes faster individual diagnosis without the shared understanding that prevents fixation. You end up with an AI agent that’s confidently wrong about the root cause and no coordination layer to catch it. The missing piece isn’t just an AI incident manager. It’s the economic signal that tells organizations they’re under-investing in the coordination layer in the first place. Most teams I assess have never measured how much capacity goes to reactive individual work versus the prevention and coordination work that makes incidents smaller and shorter.
|
||||
|
||||
This is a great illustration of why the name “AI SRE” doesn’t sit right with so many people. What these tools actually do is automated diagnostics, maybe some remediation. That’s useful, but it’s not SRE. The core of SRE work, as you lay out here, is coordination: maintaining common ground, breaking fixation, pulling the right knowledge into the room at the right time. Calling a diagnostic agent an “AI SRE” is like calling autocomplete an “AI software engineer.” The name sets expectations the tech can’t meet yet. But that’s what the industry went with, and hard to change that…As usual, good stuff Lorin.
|
||||
|
||||
The fixation and partial context point is sharp. Vendor AI agents can pull from GitHub and read commits, but they’re scanning diffs, not understanding intent. They don’t know why a change was made or what the engineer was trying to fix. A coding agent that’s been in the repo all day has that context.
|
||||
|
||||
That’s what drove our approach with Runframe. Instead of building our own AI agent, we opened up our API (via MCP) so the agent already running in Cursor or Claude Code can page on-call, create incidents, and log findings to the timeline. Same agent that just helped debug the deploy can now act on the incident.
|
||||
|
||||
I don’t think we’ve solved the coordination problem you describe. But I think the starting point is giving the agent with the deepest context the tools to act, rather than spinning up another vendor agent with a shallow view.
|
||||
|
||||
Wrote up our thinking here: https://runframe.io/blog/your-ai-already-knows-your-system-better-than-ours
|
||||
@@ -0,0 +1,392 @@
|
||||
# When Kubernetes Forgets: The 90-Second Evidence Gap
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Shamsher Khan — DZone
|
||||
- **链接**: https://dzone.com/articles/kubernetes-the-90-second-evidence-gap
|
||||
|
||||
## 简介
|
||||
|
||||
By default, Kubernetes keeps a pretty short event history. This article argues that what we really need is the ability to know the state of the system at a specific time.
|
||||
|
||||
## 正文
|
||||
|
||||
-
|
||||
 [Post an Article](https://dzone.com/content/article/post.html)
|
||||
-
|
||||
[Manage My Drafts](https://dzone.com)
|
||||
|
||||
# When Kubernetes Forgets: The 90-Second Evidence Gap
|
||||
|
||||
Kubernetes heals too fast, losing diagnostic context. Engineers reconstruct incidents manually. Time-bounded queries, correlation, and intent tracking preserve evidence.
|
||||
|
||||
Join the DZone community and get the full member experience.
|
||||
|
||||
[Join For Free](https://dzone.com/static/registration.html)
|
||||
|
||||
## The Contradiction
|
||||
|
||||
At 3:47 AM, your monitoring dashboard shows a healthy Kubernetes cluster — 99.97% availability. Your customers report a complete outage.
|
||||
|
||||
Ninety seconds later, the pod has self-healed. Metrics look normal. The restart counter reads “1.” But why it restarted — what actually happened — has vanished. This isn’t a tooling failure. The system simply recovered faster than a human could observe.
|
||||
|
||||
## The Experiment
|
||||
|
||||
To study this 90-second diagnostic gap, I ran a controlled experiment. The goal wasn’t full-scale production, but to recreate the timing behavior of failures that self-heal quickly. The failure type — OOMKill followed by pod restart — behaves the same in small and large clusters; only the impact scale differs.
|
||||
|
||||
### **Environment**
|
||||
|
||||
- **Cluster** : 3-node Minikube (Kubernetes v1.31)
|
||||
- **Pod** : 128Mi memory limit
|
||||
- **Monitoring** : Prometheus + Grafana
|
||||
- **Event retention** : Default event (1 hour OR 1000 events)
|
||||
|
||||
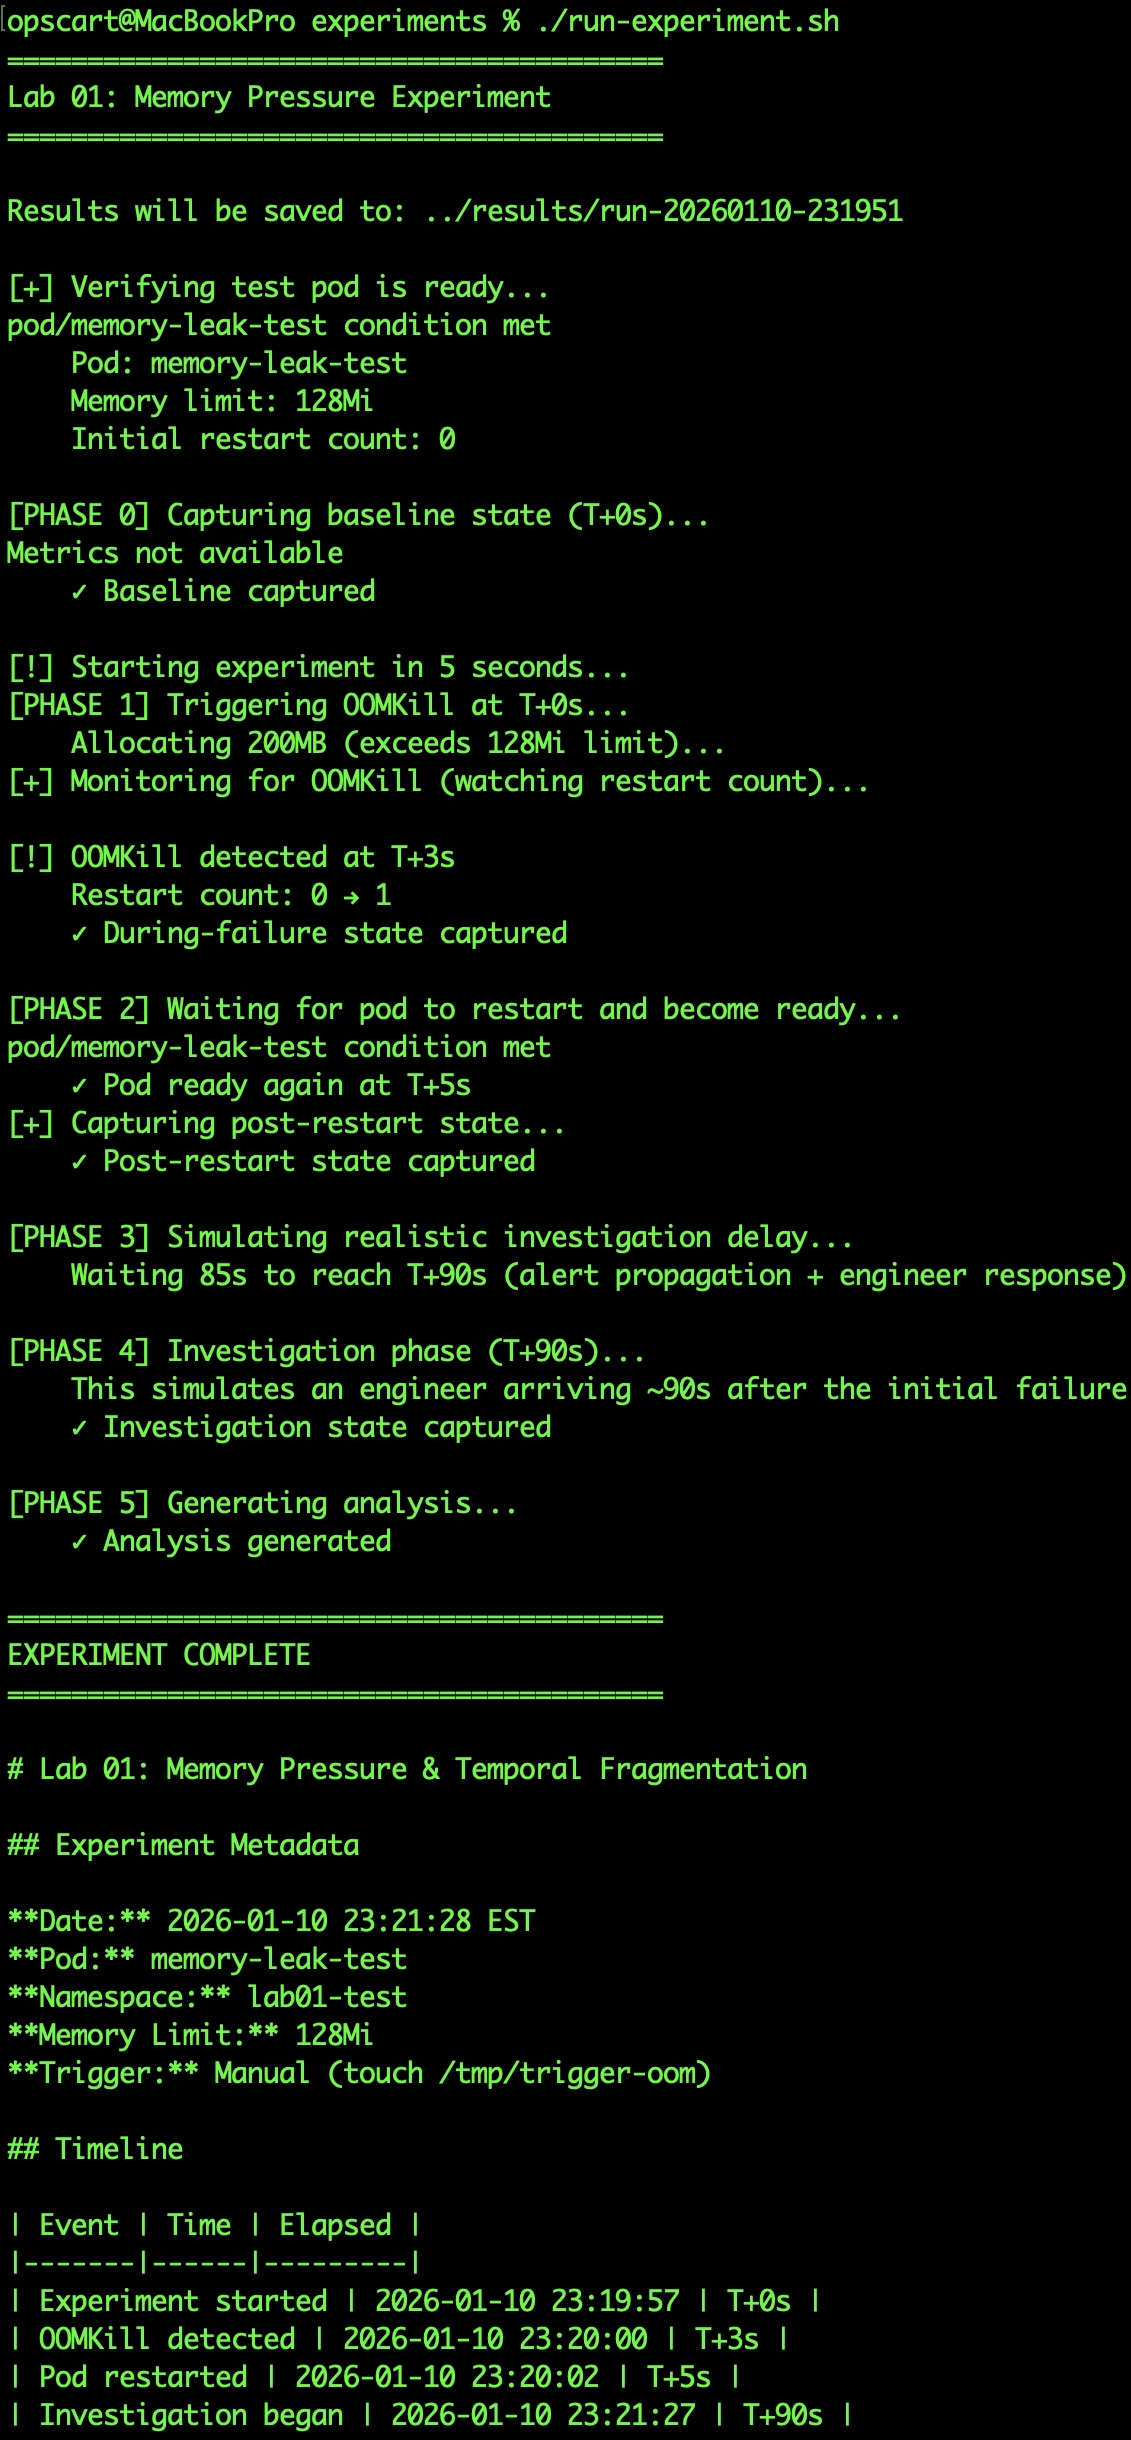
**The scenario**: A pod gradually leaks memory until the kernel OOMKills it. [Kubernetes](https://dzone.com/articles/demystifying-kubernetes) restarts the pod automatically. An engineer investigates **90 seconds later**, simulating realistic alert propagation and context-switch delays.text switching, and initial triage.
|
||||
|
||||
### **Timeline**
|
||||
|
||||
- **T+0s** : Pod running, healthy baseline
|
||||
- **T+3s** : Memory hits limit, kernel OOMKills the container
|
||||
- **T+5s** : Kubernetes restarts the pod
|
||||
- **T+90s** : Engineer begins investigation
|
||||
|
||||
**Key finding**: The failure lasted only 3 seconds; Kubernetes recovered in 2. By the time a human arrived, all critical Kubernetes decision context had vanished, even though application logs remained.
|
||||
|
||||
|
||||
|
||||
|
||||
This experiment focuses on Kubernetes decision context, not application log retention. Even organizations with mature centralized logging face this diagnostic gap.
|
||||
|
||||
## What the Engineer Sees
|
||||
|
||||
The following artifacts represent what an on-call engineer can reasonably observe 90 seconds after recovery.
|
||||
|
||||
**Pod status**:
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
$ kubectl get pod memory-leak-test -n lab01-test
|
||||
NAME READY STATUS RESTARTS AGE
|
||||
memory-leak-test 1/1 Running 1 (90s ago) 2m
|
||||
```
|
||||
The pod appears healthy. Restart count is visible. But why did it restart?
|
||||
|
||||
**Pod details**:
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
$ kubectl describe pod memory-leak-test -n lab01-test
|
||||
...
|
||||
Last State: Terminated
|
||||
Reason: OOMKilled
|
||||
Exit Code: 1
|
||||
Started: Sat, 10 Jan 2026 23:19:42 -0500
|
||||
Finished: Sat, 10 Jan 2026 23:19:57 -0500
|
||||
```
|
||||
Good — the engineer can see it was [OOMKilled](https://dzone.com/articles/why-my-java-application-is-oomkilled). But this raises more questions than it answers:
|
||||
|
||||
- What was the memory usage pattern before the kill?
|
||||
- What triggered the memory spike?
|
||||
- Has this happened before?
|
||||
- What else was happening on that node?
|
||||
|
||||
**Events**:
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
$ kubectl get events -n lab01-test | grep -i oom
|
||||
# No results
|
||||
```
|
||||
The OOM event has already rotated out. In this experiment, it disappeared in under 90 seconds—faster than a realistic human response time.
|
||||
|
||||
**Previous logs**:
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
$ kubectl logs memory-leak-test -n lab01-test --previous
|
||||
# May or may not be available
|
||||
```
|
||||
In this case, previous container logs were accessible. But this varies by configuration — many clusters lose terminated container logs immediately.
|
||||
|
||||
**The diagnostic questions that remain unanswered**:
|
||||
|
||||
- What was the memory usage 30 seconds before OOMKill?
|
||||
- What code path triggered the allocation?
|
||||
- Were there ConfigMap changes before the spike?
|
||||
- What was the node resource state at failure time?
|
||||
- Is this a pattern, or a one-time event?
|
||||
|
||||
These questions require manual correlation across [Prometheus](https://dzone.com/articles/what-is-prometheus-and-why-you-should-use-it), logs, and platform state — none of which preserve the temporal context needed for efficient diagnosis.
|
||||
|
||||
## The Missing Diagnostic Primitive
|
||||
|
||||
What Kubernetes lacks is **time-bounded state correlation** — the ability to query “what was true at time T” and correlate signals across system boundaries within a temporal window.
|
||||
|
||||
This isn’t a missing feature. It’s a missing architectural capability.
|
||||
|
||||
Databases preserve write-ahead logs that enable point-in-time recovery. Distributed tracing systems preserve request context across service boundaries. Kubernetes preserves intent (desired state in etcd), but not execution history — what decisions were made, what resources were available, what constraints applied.
|
||||
|
||||
Without this primitive, diagnosis becomes archaeology: reconstructing the past state from fragmentary evidence rather than querying preserved truth.
|
||||
|
||||
## How the Gap Breaks in Practice
|
||||
|
||||
This single architectural gap creates three distinct failure modes in production diagnostics.
|
||||
|
||||
### Temporal Decay
|
||||
|
||||
**Without time-bounded queries, Kubernetes forgets failures faster than humans can observe them**.
|
||||
|
||||
Events rotate by default after 1 hour OR 1000 events, whichever comes first. In active clusters, 1000 events can accumulate in minutes. In our experiment, OOM evidence disappeared in under 90 seconds.
|
||||
|
||||
Container logs from terminated pods have variable retention—some clusters preserve them briefly, others lose them immediately. Current metrics show the post-recovery state, not the failure state.
|
||||
|
||||
**Kubernetes treats failures as transient implementation details, not first-class historical events**.
|
||||
|
||||
When an engineer arrives to investigate, they find a healthy system with a restart counter but no diagnostic context. The evidence that would explain *why* the restart occurred has already been garbage collected.
|
||||
|
||||
### Snapshot Absence
|
||||
|
||||
**Without historical state snapshots, Kubernetes can only explain what exists — never what existed**.
|
||||
|
||||
Databases preserve write-ahead logs. Kubernetes preserves intent, but not execution history.
|
||||
|
||||
What’s missing:
|
||||
|
||||
- `kubectl describe pod --at-time="2026-01-10T23:20:00Z"` doesn’t exist
|
||||
- ConfigMap and Secret contents at failure time are not queryable
|
||||
- Scheduler decision reasoning is not preserved
|
||||
- Node resource state when placement occurred is not retrievable
|
||||
|
||||
An engineer can see the current pod specification. They cannot see what the specification was when the failure occurred, or what the surrounding platform state looked like at that moment.
|
||||
|
||||
This is not about observability tooling — it’s about architectural capability. The system state needed to explain Kubernetes decisions is ephemeral by design.
|
||||
|
||||
### Correlation Gap
|
||||
|
||||
**Without a shared temporal frame, signals cannot be correlated, and ownership fragments by default**.
|
||||
|
||||
Each system answers a different diagnostic question—but incidents require answers to questions no system is responsible for.
|
||||
|
||||
Consider our OOMKill scenario:
|
||||
|
||||
- **Memory spike** : Prometheus metric (metrics team)
|
||||
- **OOMKill event** : Kubernetes events (platform team)
|
||||
- **Application error** : Container logs (app team)
|
||||
- **Network latency spike** : CNI logs (network team)
|
||||
|
||||
None of these systems references each other. No shared transaction ID. No temporal correlation mechanism. The data exists in isolation.
|
||||
|
||||
Even with perfect retention in each system, correlation is the engineer’s responsibility — performed manually, after the fact, under time pressure during an incident.
|
||||
|
||||
## But We Have Centralized Logging — Doesn’t That Fix This?
|
||||
|
||||
A common response to this experiment is: “We have centralized logging — this isn’t a problem for us.”
|
||||
|
||||
**Logs tell you what the application said — not what the platform decided.**
|
||||
|
||||
Centralized logging certainly preserves application output, and it is necessary. But it does not preservthe e Kubernetes decision context.
|
||||
|
||||
**What logs capture**:
|
||||
|
||||
- Application stdout/stderr
|
||||
- Container output
|
||||
|
||||
**What logs don’t capture**:
|
||||
|
||||
- Pod spec, ConfigMap, or Secret versions at failure time
|
||||
- Node resource state
|
||||
- Scheduler or kubelet decisions
|
||||
- Cgroup enforcement context
|
||||
|
||||
**The result**: metrics, logs, and events exist in isolation. Engineers must manually correlate them across time and systems, reconstructing what Kubernetes actually did. Evidence exists—but the explanation does not.
|
||||
|
||||
## What This Means for SRE Teams
|
||||
|
||||
Most “root cause analyses” are reconstructions, not observations.
|
||||
|
||||
**Typical incident workflow**:
|
||||
|
||||
1. Pod restarts, alert fires
|
||||
2. Engineer responds (2-5 minutes elapsed)
|
||||
3. `kubectl` shows healthy pod with restart count
|
||||
4. Engineer searches for clues:
|
||||
|
||||
- Check events (may have rotated)
|
||||
- Query Prometheus (manual historical query needed)
|
||||
- Check logs (may be unavailable for terminated container)
|
||||
- Ask “has this happened before?” (no pattern detection available)
|
||||
5. Spend time reconstructing the timeline across disconnected systems
|
||||
6. Maybe find the root cause, maybe document “transient issue”
|
||||
|
||||
The pod failed and recovered in 5 seconds. The engineer spent 30-45 minutes reconstructing what happened. This time, tax applies to every unexpected restart, every OOMKill, every eviction.
|
||||
|
||||
**The broader impacts**:
|
||||
|
||||
- Repeat incidents go undetected (no historical pattern matching)
|
||||
- New team members struggle (tribal knowledge required for manual correlation)
|
||||
- Post-mortems lack complete data (evidence gaps prevent true root cause)
|
||||
- On-call fatigue increases (every incident requires archaeological investigation)
|
||||
|
||||
## The Missing Diagnostic Primitives
|
||||
|
||||
The primitives Kubernetes needs are direct responses to the failure modes documented above.
|
||||
|
||||
### Primitive 1: Time-Bounded State Queries
|
||||
|
||||
**Addresses**: Temporal decay
|
||||
|
||||
**What it is**: The ability to query historical Kubernetes state at a specific timestamp.
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Hypothetical command
|
||||
kubectl describe pod memory-leak-test --at-time="2026-01-10T23:20:00Z"
|
||||
```
|
||||
This would return:
|
||||
|
||||
- Pod specification as it existed at that moment
|
||||
- ConfigMap and Secret contents referenced by the pod
|
||||
- Node resources available when scheduled
|
||||
- Events that existed at that timestamp
|
||||
|
||||
**Why observability tools don’t substitute**: Prometheus preserves metric history, but not Kubernetes object state. You can graph memory usage over time, but you cannot query “what was in this ConfigMap when the pod started?” Metrics show symptoms; state snapshots show conditions.
|
||||
|
||||
**The architectural gap**: Kubernetes etcd stores the current state efficiently, but the historical state requires deliberate preservation with queryable indexes. This is a design choice — optimization for operational efficiency over diagnostic capability.
|
||||
|
||||
### Primitive 2: Cross-System Temporal Correlation
|
||||
|
||||
**Addresses**: Correlation gap
|
||||
|
||||
**What it is**: A shared temporal frame with correlation identifiers across metrics, logs, events, and platform state.
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Hypothetical command
|
||||
kubectl correlate --pod=memory-leak-test \
|
||||
--time-range="23:19:30 to 23:20:30" \
|
||||
--include=events,metrics,logs
|
||||
```
|
||||
This would return a unified timeline showing:
|
||||
|
||||
- What changed in Prometheus metrics
|
||||
- Which Kubernetes events fired
|
||||
- What appeared in container logs
|
||||
- Which platform decisions were made
|
||||
|
||||
All anchored to a shared timestamp window with correlation identifiers.
|
||||
|
||||
**Why observability tools don’t substitute**: Distributed tracing solves this for requests flowing through applications. But platform-level decisions — scheduling, eviction, resource enforcement — don’t participate in trace contexts. Each system maintains its own timeline with its own timestamp precision and retention policy.
|
||||
|
||||
**The architectural gap**: Correlation requires cooperation from components that were never designed to coordinate. The kubelet doesn’t emit trace IDs. The kernel doesn’t tag OOMKills with pod UIDs. Events don’t reference metric timestamps. This coordination layer doesn’t exist.
|
||||
|
||||
### Primitive 3: Intent vs. Outcome Tracking
|
||||
|
||||
**Addresses**: Both temporal decay and snapshot absence
|
||||
|
||||
**What it is**: Preserved decision history showing what Kubernetes tried to do, what constraints it faced, and what actually happened.
|
||||
|
||||
Shell
|
||||
|
||||
|
||||
|
||||
```
|
||||
# Hypothetical command
|
||||
kubectl explain failure memory-leak-test --restart=1
|
||||
```
|
||||
This would show:
|
||||
|
||||
- What the HPA wanted (desired replica count)
|
||||
- What the scheduler attempted (placement decisions)
|
||||
- What constraints applied (resource quotas, node selectors, taints)
|
||||
- What succeeded and what failed
|
||||
- Why specific decisions were made
|
||||
|
||||
**Why observability tools don’t substitute**: Controller logs show what actions were taken, but not the reasoning or alternatives considered. You can see “scaled to 3 replicas” but not “wanted 5, only 3 nodes had capacity, quota prevented more.” The decision context is never serialized.
|
||||
|
||||
**The architectural gap**: Controllers operate on a reconciliation loop, comparing desired and actual state. The intermediate reasoning — what was attempted, what constraints blocked it, what alternatives were considered — exists only in memory during execution and is never persisted.
|
||||
|
||||
## Living With the Gap (For Now)
|
||||
|
||||
Until these primitives exist, teams compensate with partial mitigations. These are treatments for symptoms, not solutions to the underlying architectural gap.
|
||||
|
||||
**Short-term compensations**:
|
||||
|
||||
- Increase event retention to 24 hours (postpones rotation, doesn’t eliminate it)
|
||||
- Enable terminated container log retention (when platform supports it)
|
||||
- Create Prometheus recording rules for common diagnostic queries
|
||||
- Build incident runbooks that codify manual correlation steps
|
||||
|
||||
**Medium-term mitigations**:
|
||||
|
||||
- Implement centralized logging (ELK, Splunk, Loki) for application output
|
||||
- Deploy distributed tracing (Jaeger, Tempo) for request-level correlation
|
||||
- Use event exporters (kube-eventer) to forward events to durable storage
|
||||
- Create custom diagnostic capture workflows
|
||||
|
||||
**Complementary tooling**:
|
||||
|
||||
- Minimal diagnostic capture script (bundles pod specs, events, node state, logs at specific time boundaries).
|
||||
- Production cluster-wide health snapshot: see [kubectl-health-snapshot] .
|
||||
|
||||
**Takeaway**: These mitigations help manage symptoms, but **cannot eliminate the fundamental architectural gap** — Kubernetes explains what exists, not what existed or why decisions were made.
|
||||
|
||||
## Conclusion
|
||||
|
||||
Kubernetes is optimized for **self-healing**, not for explaining its decisions.
|
||||
|
||||
The 90-second evidence gap is **architectural**, not a tooling bug.
|
||||
|
||||
Without time-bounded state queries, cross-system correlation, and intent tracking:
|
||||
|
||||
- Engineers spend far more time reconstructing incidents than machines take to recover.
|
||||
- Repeat failures often go undetected.
|
||||
- Post-mortems are incomplete; on-call fatigue rises.
|
||||
|
||||
The proposed primitives address real-world failure modes, not hypothetical scenarios.
|
||||
|
||||
**Until these primitives exist, incident response remains an exercise in archaeology**.
|
||||
|
||||
## **Next Steps**
|
||||
|
||||
- Reproduce the experiment: [kubernetes-diagnostic-primitives repo](https://github.com/opscart/kubernetes-diagnostic-primitives)
|
||||
- Labs 2 & 3 in progress: deep dive into correlation fragmentation and intent opacity.
|
||||
- Stay tuned for practical workflows for cross-system incident correlation.
|
||||
|
||||
**Connect**:
|
||||
|
||||
- Blog: [https://opscart.com](https://opscart.com)
|
||||
- GitHub: [https://github.com/opscart](https://github.com/opscart)
|
||||
- LinkedIn: [linkedin.com/in/shamsherkhan](https://linkedin.com/in/shamsherkhan)
|
||||
|
||||
Kubernetes
|
||||
Observability
|
||||
|
||||
|
||||
Published at DZone with permission of Shamsher Khan.
|
||||
|
||||
[See the original article here.](https://opscart.com/when-kubernetes-forgets-the-90-second-evidence-gap/)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Opinions expressed by DZone contributors are their own.
|
||||
|
||||
Comments
|
||||
@@ -0,0 +1,13 @@
|
||||
# Safeguarding dynamic configuration changes at scale
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Cosmo W. Q — Airbnb
|
||||
- **链接**: https://medium.com/airbnb-engineering/safeguarding-dynamic-configuration-changes-at-scale-5aca5222ed68
|
||||
|
||||
## 简介
|
||||
|
||||
They built a platform for safely rolling out configuration changes. I like that it has a special mode for use in incident response.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
@@ -0,0 +1,83 @@
|
||||
# Catching a caching bug at Readyset
|
||||
|
||||
- **期号**: SRE Weekly Issue #510(2026-03-29)
|
||||
- **作者**: Michael Victor Zink — Readyset (via Antithesis)
|
||||
- **链接**: https://antithesis.com/blog/2026/readyset/
|
||||
|
||||
## 简介
|
||||
|
||||
This is a cool debugging story, and I love the emphasis on mental models. The bit about simulating different paths through the software is quite intriguing.
|
||||
|
||||
## 正文
|
||||
|
||||
[Readyset](https://readyset.io/) is a database scaling platform that sits in front of your MySQL or Postgres database, speeding up queries with zero code changes by caching only the results you need. Their new product, [QueryPilot](https://readyset.io/product/query-pilot), automatically detects high-impact queries to cache.
|
||||
|
||||
*This blog post is based on a recorded conversation with Michael Victor Zink, Software Engineer at Readyset.*
|
||||
|
||||
As the classic line goes, “There are two hard problems in computer science: cache invalidation and naming things.” [At Readyset, caching is at the core of what we do, so we think about cache invalidation a lot.](https://antithesis.com#fn-body-1)
|
||||
|
||||
Or sometimes it’s three hard problems. Cache invalidation, naming things and off-by one errors.
|
||||
|
||||
Sorry, no. Three hard problems: cache invalidation, off-by-one errors, and purple anteaters.
|
||||
|
||||
Wait, I meant three hard problems: naming things, off-by-one errors, and I forgot the other one.
|
||||
|
||||
It’s hard to find a definite attribution for the original, but it [most likely](https://martinfowler.com/bliki/TwoHardThings.html) comes from Phil Karlton.
|
||||
|
||||
So there’s some irony in the fact that Antithesis found a cache invalidation bug in our system. Not in the core product, but in our new product, QueryPilot, which we wanted to get under test in Antithesis right from the beginning. We wanted to ship something we knew would work, and we also knew that catching issues early in development would actually help us ship faster.
|
||||
|
||||
QueryPilot is simpler than our core product, but even so, it was easy to fall into a cache invalidation trap. Our existing test suite and internal manual testing didn’t find the bug. We *could* have picked it up if we’d written exactly the right tests to force that behavior — but of course, we didn’t know to write those tests until after we found the bug in Antithesis.
|
||||
|
||||
The problem was that we had an implicit mental model of how our software would be used. Previously, engineers using Readyset would search for high impact queries when they were doing performance optimization. Our tests mostly reflected this pattern of use. With QueryPilot we were moving from manual queries to automated use, which broke our assumptions. But Antithesis still found the bug naturally in the course of a test run.
|
||||
|
||||
## [What QueryPilot does](https://antithesis.com#what-querypilot-does)
|
||||
|
||||
To explain the bug, I should first say a bit about QueryPilot. It’s a proxy that sits between your application and database:
|
||||
|
||||
|
||||
|
||||
[Readyset blog](https://readyset.io/blog/readyset-querypilot-automatic-caching).
|
||||
|
||||
QueryPilot automates the process of query caching. It looks at all the queries in your upstream database, and runs our [`EXPLAIN CREATE CACHE` command](https://readyset.io/docs/reference/command-reference#create-cache) as a “dry run” to see if each query is supported for caching by Readyset. QueryPilot then picks high load, high impact queries to send to the caching sidecar, and forwards other queries directly to the database. The caching sidecar receives a replication stream from the database so that it stays up to date.
|
||||
|
||||
For an example of how this works in practice, see Readyset’s [WordPress with QueryPilot](https://readyset.io/blog/wordpress-with-querypilot-instant-database-scaling-without-code-changes) case study.
|
||||
|
||||
QueryPilot also has its own cache! [A metadata cache that records the results of the](https://antithesis.com#fn-body-3) `EXPLAIN` commands. This is where the bug comes in…
|
||||
|
||||
You can never have too many caches. We’ve lost track of how many caches Readyset has internally.
|
||||
|
||||
## [The bug](https://antithesis.com#the-bug)
|
||||
|
||||
As a starting state, let’s say that we have a table called `example` in the primary database. QueryPilot runs `EXPLAIN CREATE CACHE` on a query like `SELECT * FROM example` to check if it’s cacheable. It sends the query to the Readyset caching sidecar, which replies that yes, this query is supported for caching. So far, so good.
|
||||
|
||||
However, there’s a short period of time before the “query supported” result gets stored in QueryPilot’s metadata cache. Now imagine that the application deletes the `example` table during this time with a `DROP TABLE example` command.
|
||||
|
||||
This deletion will get replicated to the caching sidecar, which will remove the `example` table. However, QueryPilot doesn’t know about this, and happily stores “query supported” in its metadata cache.
|
||||
|
||||
If you now try and cache the `SELECT * FROM example` query for real with `CREATE CACHE`, you’ll get an error saying that the `example` table is not found. But the QueryPilot metadata cache is never invalidated, and stays permanently stale.
|
||||
|
||||
If QueryPilot thinks this is a very impactful query to cache, it will try and cache it over and over, and fail, so you’ll constantly see this error.
|
||||
|
||||
If you’d rather have your bug stories in diagram form, here’s a sequence diagram showing the order of events:
|
||||
|
||||
|
||||
|
||||
## [How Antithesis caught it](https://antithesis.com#how-antithesis-caught-it)
|
||||
|
||||
To explain how Antithesis helped us find this bug, it helps to understand why it slipped past us in the first place. The `EXPLAIN CREATE CACHE` command was originally created for humans to run, to see if a specific query they wanted to cache was supported. So it would be happening relatively rarely.
|
||||
|
||||
Deleting tables, or running other DDL [commands that could trigger the bug, is normally also pretty rare — normally the database schema is in a steady state. The chances of both running in the same tiny window are low.](https://antithesis.com#fn-body-4)
|
||||
|
||||
DDL (data definition or description language) is SQL syntax for creating and modifying database objects such as tables, indices, and users. This in contrast to SQL that creates or modifies data within tables.
|
||||
|
||||
The point of QueryPilot, on the other hand, is to automatically find queries to cache. So it was running these `EXPLAIN CREATE CACHE` statements over and over again. This meant we were much more likely to be running one while some DDL was running, like `DROP TABLE example`, triggering the race condition.
|
||||
|
||||
We didn’t think of this specific scenario when we tested QueryPilot in Antithesis. But we were looking to test what happens in general if we throw an arbitrary workload at QueryPilot that isn’t tailored for Readyset at all, with a mix of supported and unsupported queries — all kinds of random stuff. To do this we used [SQLancer](https://github.com/sqlancer/sqlancer), which generates these sorts of arbitrary queries off the shelf.
|
||||
|
||||
We ran this workload in Antithesis and it found the bug easily. Antithesis simulates a [“multiverse”](https://antithesis.com/docs/product/debugging/advanced_multiverse_debugging/moment_branch/) of different paths through your software. Each branch tries different combinations of operations in different orders. In our case, Antithesis ran lots of different SQLancer queries along with lots of QueryPilot dry run and caching attempts. This quickly found the right interleaving of events that triggered the bug — an `EXPLAIN CREATE CACHE` query running while a DDL command is in flight.
|
||||
|
||||
Once we’d hit the bad state, we used the [Multiverse Debugger](https://antithesis.com/docs/product/debugging/advanced_multiverse_debugging/overview/) to understand the sequence of events in that branch. We ran interactive debugging sessions just before and after the bug started, changed the log level, and ran SQL commands against Readyset to see what was going on. This showed us that the cached result of the `EXPLAIN` query was causing QueryPilot to retry continuously.
|
||||
|
||||
After getting into the technical details of this bug, it’s interesting to zoom out and think about it from the developer psychology side. We were trapped by our implicit models of how our software should, or would, be used. The shift from manual to automated queries changes background assumptions in ways that are hard to notice from the inside.
|
||||
|
||||
It would be nice if we could anticipate the new problems we’ll run into just by thinking harder, but in practice it works a lot better to throw everything at the database and see what happens. Antithesis doesn’t care about your mental models, which is what lets you find unknown unknowns like this one. So it isn’t just about the time you spend writing tests, or even about the time you’d need to spend thinking about the tests, it’s also about the peace of mind – do you want to launch while being pretty sure that there were gaps in your testing?
|
||||
Reference in New Issue
Block a user