SRE weekly 所有文章
This commit is contained in:

@@ -0,0 +1,95 @@
|
||||
# Incident status updates are a translation problem, and the right translator probably isn’t in Engineering
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/03/31/status-update-translation/
|
||||
|
||||
## 简介
|
||||
|
||||
> […] the fix isn’t “train your engineers to write better status updates.” The fix is to stop asking your engineers to write them, and start asking the right people instead.
|
||||
|
||||
## 正文
|
||||
|
||||
It’s mid-morning in Europe, and your customers are complaining about stale data. It’s 2 AM for your on-call engineers. Your European customer care team noticed the surge in complaints and paged the on-call incident commander (IC). The IC pulled up the dashboards, saw a spike in processing errors on the data ingest pipeline, and paged the data engineering, platform, and networking on-call engineers. Now the IC is coordinating with three responders, all trying to figure out what’s gone wrong, and whether the problem is actually even worse than it appears. And on top of all that, the IC is expected to write a customer-facing status page update.
|
||||
|
||||
The result is predictable. The update either doesn’t happen at all, or it reads something like: “Elevated error rates on the ingest pipeline due to Kafka consumer lag.” Which is perfectly accurate, and perfectly useless to 99% of the people reading it.
|
||||
|
||||
This is one of the most common patterns I see in my consulting work, and it’s worth understanding why it happens, because the fix isn’t “train your engineers to write better status updates.” The fix is to stop asking your engineers to write them, and start asking the right people instead.
|
||||
|
||||
# The translation problem
|
||||
|
||||
Here’s the core issue: incidents generate information in a language that most of your company doesn’t speak, and most of your customers don’t either.
|
||||
|
||||
When responders are working an incident, they talk about services, endpoints, error rates, deployment pipelines, and database replicas. They refer to systems by internal codenames. They describe impact in terms of error budgets and percentile latencies. This is exactly the right level of detail for the people doing the troubleshooting, and exactly the wrong level of detail for almost everyone else.
|
||||
|
||||
Your customer support team needs to know which customer-visible features are affected, described in the language customers use. Your sales team needs to know whether the demo environment is impacted and what to say to the prospect they’re meeting in an hour. Your executives need to know the business impact: revenue at risk, customers affected, estimated time to resolution. Your customers need to know that you’re aware of the problem, you’re working on it, and roughly when it will be fixed.
|
||||
|
||||
None of these audiences need to know that Kafka consumer lag on the ingest pipeline is causing records to back up in the processing queue. They need to know that some recently submitted data may not be appearing yet, and that your team is on it.
|
||||
|
||||
Most companies treat this as a writing-quality problem, but it’s a translation problem. Each of these audiences speaks a different dialect: customer-speak, business-impact-speak, relationship-speak, risk-speak. Your engineers are fluent in engineering-speak, which is precisely what you want from them during an incident. Expecting them to also be fluent in four other dialects, under pressure, at 2 AM, is setting everyone up for disappointment.
|
||||
|
||||
Consider how much translation is involved in turning “Kafka consumer lag on the ingest pipeline. Stuck consumer group identified; restarting. Backlog clearing, ETA 30min” into “Some users may notice that recently submitted data isn’t appearing yet. Our team has identified the cause and is deploying a fix. We expect this to be resolved within the next 30 minutes.” Internal service names became customer-visible symptoms. A technical explanation became “identified the cause.” An engineering action became an estimated timeline. That’s the work, and it’s work that customer-facing people do better than engineers.
|
||||
|
||||
# The right people for the job
|
||||
|
||||
The fix is structural. Staff your incident communication functions with people who already speak the audience’s language, and teach them enough incident-speak to do the translation.
|
||||
|
||||
A customer support lead who has spent years talking to customers can translate “Kafka consumer lag on the ingest pipeline” into “some recently submitted data may not be appearing yet” far more effectively than an engineer who has never staffed a support queue. An executive liaison who understands how the C-suite thinks about risk can distill a technical sitrep into the three sentences the CEO actually needs, without the incident commander having to figure out what those three sentences are.
|
||||
|
||||
Public safety professionals figured this out decades ago. In the Incident Command System used by fire departments and other emergency services, the Public Information Officer (PIO) is a defined incident role with specific training. The principle is straightforward: the people fighting the fire are busy with that, and you want someone else, with special training and experience, speaking to the reporters and the public. The skills are different, the priorities are different, and mixed messaging is dangerous.
|
||||
|
||||
# What this looks like in practice
|
||||
|
||||
The software world’s equivalent to the PIO is an incident role of Communications Lead, or a set of liaison roles, each serving a specific audience.
|
||||
|
||||
The simplest version: when a significant incident is declared, someone from your customer-facing team joins the response as a communications liaison. They follow the technical discussion, work from the incident commander’s sitreps, and translate updates into customer-appropriate language for the status page and support team. The IC reviews external communications for accuracy, but the drafting and posting are done by someone who knows how to talk to customers.
|
||||
|
||||
This has a second benefit that’s just as important: it frees the incident commander to focus on the response itself. The IC’s attention is one of the scarcest resources during an incident. Every minute they spend crafting a status page update is a minute they’re not spending on coordination, decision-making, or thinking about what they might be missing. Delegating communication beyond the response to someone better suited for the work is better for the IC, better for the response, and better for the customers.
|
||||
|
||||
The same principle extends to every other audience. A support update channel where a customer care liaison posts translated, agent-ready talking points. A senior management update path where an executive liaison posts business-impact summaries. A sales notification that flags which key accounts are affected, so reps know before their next customer call. A broad notification to legal, finance, and HR when a significant incident is declared, so each function can self-select whether to engage based on their own expertise, rather than waiting for the IC to figure out whether this incident has regulatory implications.
|
||||
|
||||
# Three things customers actually want to know
|
||||
|
||||
Once you have the right people doing the translating, what they actually need to communicate is simpler than you might expect.
|
||||
|
||||
In my experience, what customers truly want to know during an incident comes down to three things: that you’re aware of the problem, that you’re working on it, and, if possible, when it will be fixed. If you cover those three, most customers will be satisfied to let you work the problem in peace.
|
||||
|
||||
That’s it. They don’t need the technical details. They don’t need the internal coordination. They don’t need the investigation narrative. All of that is for your team, not for them.
|
||||
|
||||
# The worst failure isn’t saying the wrong thing
|
||||
|
||||
The most damaging communication failure during an incident isn’t saying the wrong thing, it’s saying nothing at all.
|
||||
|
||||
A status page that reads “All Systems Operational” while your customers are seeing errors. A support team that has no information to share. Executives finding out about the outage from social media. Each of these erodes trust in a way that even the most jargon-filled status update doesn’t, because silence communicates something very clearly: either you don’t know there’s a problem, or you know and don’t care enough to say anything.
|
||||
|
||||
Even an imperfect update is better than no update. Share what you know, be honest about what you don’t, and commit to a cadence for further updates. But calibrate the cadence to the pace of the incident; repetitive content-free “we’re still working on it” updates become noise rather than reassurance. (This is another reason to have skilled communicators handling the job. When I was leading incident management at Slack, the Customer Experience team seemed to have at least a dozen ways of saying “still working on it” without repeating themselves.)
|
||||
|
||||
Customers and stakeholders can forgive a rough update. They have a much harder time forgiving radio silence.
|
||||
|
||||
# This isn’t a problem Engineering can solve alone
|
||||
|
||||
Here’s where this gets real: incidents don’t wait for business hours. If your company has 24/7 on-call coverage for engineering, but your customer support and communications teams work 9-to-5, then at 2 AM on a Saturday your engineer is right back to writing status page updates, because there’s nobody else available to do it.
|
||||
|
||||
To solve this, the conversation needs to shift from Engineering’s process to the company’s commitment. Staffing incident communication properly means that Support, Customer Success, or whoever owns customer-facing communication needs their own 24/7 on-call rotation, or at least an escalation path that works at 2 AM, even if that means the Director of Customer Care is effectively always on call for high-severity incidents.
|
||||
|
||||
It also means those teams need to be included in incident response training (though not necessarily the full responder training that engineering gets; a focused one-hour session on their role during incidents may be all they need). And it means there needs to be a staffing conversation, and probably a budget conversation, with a VP outside of Engineering who hasn’t thought of incident response as their problem before.
|
||||
|
||||
That’s uncomfortable, but it’s also clarifying. If your company truly believes that customer communication during incidents matters, then the teams who are best at customer communication need to be available when incidents happen. If those teams aren’t willing to staff for it, that tells you something about how seriously the company takes it, which is useful information in itself.
|
||||
|
||||
For the engineering leader reading this: you shouldn’t try to fix this alone (and you probably can’t anyway). What you can do is make the case. The argument is straightforward: Engineering has invested in 24/7 incident response capability because incidents don’t respect business hours. Customer communication during those incidents is at least as important as the technical response, and it requires a different skill set. The same logic that justifies an engineering on-call rotation justifies a communication on-call rotation.
|
||||
|
||||
If the company isn’t willing to make that investment, then it’s making a conscious choice to accept poor customer communication during off-hours incidents, and everyone should be honest about that tradeoff.
|
||||
|
||||
# The real question is organizational design
|
||||
|
||||
The question to ask isn’t “how do we train our engineers to write better status page updates?” The question is “who in our company already has the skills to communicate with each of these audiences, and how do we bring them into our incident processes?”
|
||||
|
||||
That’s an organizational design question, not a training question. And it’s the kind of question that separates companies that handle incidents well from companies that just handle the technical parts well.
|
||||
|
||||
Remember that European customer care team from the opening? They were the ones who noticed the problem. They were the ones fielding the complaints. They already knew how to talk to the affected customers. All they needed was a seat at the table, so they could translate what the engineering team was seeing. That’s not a big ask. But it’s one that most companies have never thought to make.
|
||||
|
||||
*I’m writing a book about incident management for software organizations, drawing on my experience building and leading incident management programs at companies like Google, Slack, and others. If you’d like to hear about it when it’s available, visit [im4ds.com](https://im4ds.com).*
|
||||
|
||||
*If your organization is wrestling with incident communication or other incident management challenges, I do consulting and training on these topics. You can find out more at [greatcircle.com](https://greatcircle.com).*
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,185 @@
|
||||
# Scaling Security Insights: how we achieved a 10x increase in global scanning capacity
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Dave Baxter — Cloudflare
|
||||
- **链接**: https://blog.cloudflare.com/scaling-security-scans/
|
||||
|
||||
## 简介
|
||||
|
||||
A satisfying scaling story where every fix came from looking more closely at the system — Kafka head-of-line blocking, a clumpy scheduler, and an active-active API that silently doubled latency for half of all partitions.
|
||||
|
||||
## 正文
|
||||
|
||||
# Scaling Security Insights: how we achieved a 10x increase in global scanning capacity
|
||||
|
||||

|
||||
|
||||
[__Security Insights__](https://developers.cloudflare.com/security/security-insights/) provides actionable security recommendations for every Cloudflare account. To find these insights, we perform regular scans for all accounts, zones, and DNS records, looking for potential security risks and misconfigurations.
|
||||
|
||||
However, two key issues emerged. First, our scans were too infrequent. Scans were only being performed every week or two, and therefore newly introduced security risks could remain undetected for up to two weeks. Second, automatic scanning was opt-in for many free plan accounts – meaning lots of accounts weren’t being scanned at all.
|
||||
|
||||
The risks of infrequent or nonexistent scans are rising: as automated attacks accelerate, the window for detecting security misconfigurations is shrinking. Making sure that we’re finding these issues for *all* of our customers is crucial to our aim of helping build a better Internet for everyone.
|
||||
|
||||
We calculated that to increase our scanning frequencies and enable automatic scanning for all accounts, we would need to increase our scanning throughput by around 10x on average – from 10 scans per second to 100 per second. But our system was already struggling with its load: millions of events were filling up our backlog waiting to be processed; our API was frequently timing out; our processes were crashing. We needed to fix our system, and we needed to make it *scale*.
|
||||
|
||||
This is the story of how we increased scanning throughput for Security Insights by more than 10x, enabled security insights for millions of customers, and doubled our scanning frequency for all customers. Read on to find out how we achieved these improvements.
|
||||
|
||||
## How we scan for security insights
|
||||
|
||||
At a high level, our automatic security scans are triggered by a scheduler. When an account or zone is due for a scan, the scheduler publishes a message (or messages) to [__Apache Kafka__](https://blog.cloudflare.com/using-apache-kafka-to-process-1-trillion-messages/), an open-source distributed event streaming platform. These messages fan out to a number of checkers: specialized Go microservices that scan specific assets or configurations.
|
||||
|
||||
For every message, each checker sends its results (the security insights that it found) to our internal API, which then persists these in a Postgres database.
|
||||
|
||||

|
||||
|
||||
## Making it scale
|
||||
|
||||
### Scaling Kafka
|
||||
|
||||
Apache Kafka is not strictly a *queue*: it is a partitioned event stream (though recently gained [__queue semantics__](https://www.confluent.io/blog/kafka-queue-semantics-share-consumer-ga/)). Within a partition, messages must be consumed and *processed* in order. This differs from typical queues where messages may be consumed in order but are processed out-of-order. As a result, we can only have one active consumer per partition within a *consumer group*.
|
||||
|
||||
This has two consequences for us:
|
||||
|
||||
- Messages that are slow to process block the consumer from progressing to the next message
|
||||
- For each checker, we can only have as many consumers as there are partitions (each checker has its own consumer group)
|
||||
|
||||

|
||||
|
||||
We could have tried to scale by adding more partitions. However, this would have increased resource usage for the Kafka broker itself, which is shared by many other services. We reserved this as a last resort, aiming to improve our code and architecture first.
|
||||
|
||||
### Introducing parallel processing
|
||||
|
||||
Although we can only consume messages in order, there is nothing stopping us from consuming multiple messages at once.
|
||||
|
||||
We changed our checkers to consume messages in *batches*, processing each message in a separate goroutine. The trade-offs are that we’d have more work to re-do if our process crashed midway through a batch, and our memory usage would be slightly increased. In our case, these were both acceptable.
|
||||
|
||||
### Avoiding head-of-line blocking
|
||||
|
||||
Some messages processed by a few of our checkers take much longer to process than others. For example, one account/zone may have far more assets than another. In the worst case, these messages can take minutes or hours to process compared to the average case of seconds or milliseconds.
|
||||
|
||||
We opted for a very simple approach: splitting our consumer groups and checkers in two – the ‘slow lane’ and the ‘fast lane’. We could determine quickly whether a message would be slow or fast to process. If the ‘fast lane’ checker encounters a slow message, it skips it.
|
||||
|
||||

|
||||
|
||||
This solved the problem: slow messages had the dedicated resources and time to be processed with minimal delay, and fast messages were able to proceed at their regular fast pace.
|
||||
|
||||
## Optimizing our database queries
|
||||
|
||||
Every insight we find gets written to our Postgres database. This is handled by a single API endpoint that our checkers invoke with a list of insights. The implementation looked like this:
|
||||
|
||||
```
|
||||
for _, issue := range issues {
|
||||
_, err = tx.Exec(ctx, `INSERT INTO table ... VALUES ($1, $2, ...) ON CONFLICT DO UPDATE ...`, ...)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
```
|
||||
The astute reader will notice that for large sets of insights, this code makes a round trip to the database per insight. With a maximum observed size of 500,000, this was half a million round trips, queries, and transactions in a single API call.
|
||||
|
||||
We initially tried the gold standard for bulk inserts in Postgres: COPY into a temporary table. However, we found that this approach led to bloat in the Postgres system tables.
|
||||
|
||||
We settled on a hybrid approach:
|
||||
|
||||
- Using UNNEST when the number of issues was below a threshold
|
||||
- Using COPY when the number of issues exceeded this threshold
|
||||
|
||||
This provided the best of both worlds: reasonably fast inserts for huge sets of insights (seconds), and even faster inserts (milliseconds) for small sets of insights.
|
||||
|
||||
## Investigating our API timeouts
|
||||
|
||||
We noticed several strange behaviours in our internal API as we tried to scale:
|
||||
|
||||
- A large number of requests were triggering client-side timeouts
|
||||
- Many checkers were spending 20-90% of their processing time on a single API call
|
||||
- When triggering a large volume of scans, our throughput would start high and deteriorate
|
||||
|
||||
All of these problems had the same root cause: **latency**.
|
||||
|
||||
Our primary database is located in Portland, Oregon. Our API, however, was running active-active in both Portland and Amsterdam. Even at the speed of light, the round-trip latency between Portland and Amsterdam would be 50 milliseconds.
|
||||
|
||||
As a result of this latency, database queries from the Amsterdam API instance took much longer, holding connections from our client-side connection pool open. With the large volume of requests that we were making to the API, the connection pool was quickly becoming exhausted, leading to timeouts waiting for a free connection. Our average API call completed in 10 ms in Portland, but almost 3 seconds in Amsterdam!
|
||||
|
||||
But why the drop in message throughput? Each checker process gets assigned a set of partitions of the Kafka stream to consume. Our API is load-balanced. Since we hold the connection open throughout the life of the process, some processes had a connection to the Amsterdam API, and others had a connection to the Portland API. The partitions linked to Portland were processed quickly, but the ones consumed by the Amsterdam-bound processes were lagging behind:
|
||||
|
||||

|
||||
|
||||
*Kafka lag (number of messages waiting to be processed within a single consumer group) by partition for one of our checkers. Note that we have 30 partitions in this case. Exactly 15 partitions can be seen lagging behind (the lines that reach or approach zero later than around 03/10 03:00). This is because the load balancer splits traffic evenly between our API endpoints.*
|
||||
|
||||
This was a simple fix: we switched our API to [__active-passive__](https://developers.cloudflare.com/load-balancing/load-balancers/common-configurations/#active---passive-failover), ensuring the active API followed our primary database. Our latency problems disappeared overnight.
|
||||
|
||||
## Rethinking the scheduler
|
||||
|
||||
We’d scaled Kafka. We’d optimised our database queries. We’d fixed our API. However, we still had a problem: we needed to be sure our scans would be roughly uniformly distributed in time. It wasn’t feasible to queue all of our scans at the same time, as our Kafka topic uses a time-based retention policy: the scans would pile up in Kafka, and eventually be deleted before they could be processed.
|
||||
|
||||
Our scheduler was not good at uniformly distributing our scans. The number of scans that would be triggered at a given time was spiky and unpredictable. At certain points throughout the week, hundreds of thousands of scans would be triggered within minutes of each other. What was going on?
|
||||
|
||||
The scheduler triggers scans on fixed recurring periods. In pseudocode, the scheduler looked like this:
|
||||
|
||||
```
|
||||
Loop forever:
|
||||
Find accounts where last_scheduled_at + scanning frequency <= now
|
||||
For each account:
|
||||
Trigger scan for account
|
||||
Trigger scan for all zones in the account
|
||||
Update last_scheduled_at = now
|
||||
```
|
||||
We quickly noticed that last_scheduled_at was similar for a large number of accounts in our database, which was responsible for some of this unevenness.
|
||||
|
||||
However, even with perfectly even distribution, increasing our scanning frequency would have compounded this problem. For example, changing the scanning frequency from every 15 days to every seven days would mean 53% of accounts would suddenly be due for a scan.
|
||||
|
||||
There was a further problem with this logic. Some accounts have a very large number of zones. When these accounts were scheduled, there was a cascade of scans for all of their zones. This was saturating our Kafka partitions and leading to delays for scans of much smaller accounts.
|
||||
|
||||
To fix these problems, we made three key changes:
|
||||
|
||||
- Schedule zones independently of accounts: each zone gets its own last_scheduled_at field.
|
||||
- Randomize the last_scheduled_at time for existing accounts and zones.
|
||||
- Introduce adaptive rate limiting for scan scheduling.
|
||||
|
||||
Scheduling zones independently was an obvious way to solve the problem of large accounts. Randomizing the last_scheduled_at time (and ensuring that no scans were delayed during this process) allowed us to fix the existing unevenness in our database.
|
||||
|
||||
Adaptive rate limiting is slightly more interesting. Rate limiting would allow us to solve the problem of a spike in scans when we change scanning frequencies. For example, if we wanted to increase our scanning frequency to every 7 days, and we had 50 million accounts, then a rate limit of ~83 scans/second would ensure that they were spread out evenly across 7 days.
|
||||
|
||||
But what if we added 10 million more accounts? Then, this rate limit would force us to take *8 days* to scan all of these accounts. This is where the *adaptive* part comes in: the rate limit is asynchronously recalculated every half-hour based on the total number of accounts and zones we have, and our scanning frequencies. This ensures we continue scanning on time even if we onboard thousands or millions more accounts and zones.
|
||||
|
||||
```
|
||||
func computeRate(free, pro, biz, ent int64) rate.Limit {
|
||||
r := float64(free)/freeScanInterval.Seconds() +
|
||||
float64(pro)/proScanInterval.Seconds() +
|
||||
float64(biz)/bizScanInterval.Seconds() +
|
||||
float64(ent)/entScanInterval.Seconds()
|
||||
// Guard against zero counts. We always want to schedule at least one scan per second.
|
||||
if r < 1 {
|
||||
r = 1
|
||||
}
|
||||
// Increase rate limit beyond the 'perfect' value, to have a buffer in case of any downtime
|
||||
// or spikes in load.
|
||||
r *= rateLimitBufferFactor
|
||||
return rate.Limit(r)
|
||||
}
|
||||
```
|
||||
## Where we stand today
|
||||
|
||||

|
||||
|
||||
*With these fixes, our 7-day moving average throughput per checker over time rose by more than 10x.*
|
||||
|
||||
Before these improvements, we were executing around 10 scans per second. The gap between this and our target throughput of 100 scans per second seemed vast. We discussed throwing more resources at the problem, throwing more partitions at our Kafka topic – even throwing out our entire architecture.
|
||||
|
||||
But our fixes made all the difference. Today, Security Insights sustains over 120 scans per second during peak scheduling, exceeding our 10x improvement goal. Our internal API is no longer timing out, and our Kafka lag metrics look much healthier. These scalability improvements have allowed us to turn on automatic scanning for *all* free accounts and zones and increase the scanning frequency for all customers:
|
||||
|
||||
- Free: every 7 days
|
||||
- Pro and Business: every 3 days
|
||||
- Enterprise: daily
|
||||
|
||||
The improved system stability has given us confidence to build new features that we were previously constrained from creating. We’ve added the ability to perform granular on-demand scans. You can now manually re-scan a Cloudflare account, zone, insight, or insight type.
|
||||
|
||||

|
||||
|
||||
*Starting a granular on-demand scan from the [__Security Overview page__](https://blog.cloudflare.com/security-overview-dashboard/) in the Cloudflare dashboard*
|
||||
|
||||
The lesson we learned is that it’s crucial to deeply understand the existing system before throwing anything away. By looking closely at our code, SQL queries, logs, and metrics (*especially* metrics!), we were able to increase our capacity without simply adding more pods or partitions. By questioning our assumptions, digging into weird-looking metrics, and refusing to take the easy shortcuts (such as increasing API client-side timeouts), we built a more stable and resilient system.
|
||||
|
||||
Throwing more resources at the problem might *sometimes* be the answer, but at Cloudflare, we believe in engineering our way out of problems.
|
||||
|
||||
Security Insights scans are enabled by default on all Cloudflare plans. Log in to the [__Cloudflare dashboard__](https://dash.cloudflare.com/?to=/:account/security-center) today to review and manage your security insights.
|
||||
@@ -0,0 +1,112 @@
|
||||
# Vibe-Coded Infra Is Your New Reliability Hazard
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Prakshal Doshi — HackerNoon
|
||||
- **链接**: https://hackernoon.com/vibe-coded-infra-is-your-new-reliability-hazard
|
||||
|
||||
## 简介
|
||||
|
||||
Some good examples of risks in here, along with an interesting tendency to blame “user error”.
|
||||
|
||||
## 正文
|
||||
|
||||
It was a routine Tuesday afternoon infrastructure task. A developer on our platform team used an AI coding assistant to generate a Kubernetes deployment manifest for a new internal service nothing exotic, just a standard workload with a few environment variables and a readiness probe. The assistant produced clean, readable YAML in about 30 seconds. The developer skimmed it, it looked right, `kubectl apply` went through without errors.
|
||||
|
||||
The pod never became ready.
|
||||
|
||||
Four hours later, after working through logs that pointed nowhere obvious, someone finally ran `kubectl explain` on the manifest field by field. The readiness probe was configured with a `grpc` handler using a field structure that had been valid in Kubernetes 1.23 but was deprecated and silently ignored in the cluster version they were running. The probe wasn't failing it was being skipped entirely. The pod sat in a perpetual "not ready" state because the health check it depended on was never executed. The LLM had confidently generated a syntactically valid, semantically broken manifest using an API shape from two years ago.
|
||||
|
||||
No linter caught it. No schema validator caught it. The cluster accepted it happily and did nothing useful with it.
|
||||
|
||||
That's the specific failure mode nobody talks about enough when they talk about AI-generated infrastructure: not wrong syntax, not obvious errors **plausible-looking output that passes every automated check you have and breaks in production anyway.**
|
||||
|
||||
## The Real Incidents That Made This a Category
|
||||
|
||||
That story is ours. The ones below are documented publicly.
|
||||
|
||||
In December 2025, engineers at Amazon gave their Kiro AI coding assistant a task: fix a minor issue in AWS Cost Explorer. Kiro had operator-level permissions equivalent to a human developer. No mandatory peer review existed for AI-initiated production changes. Given those inputs, Kiro did what its reasoning concluded was optimal: it deleted the entire production environment and attempted to recreate it from scratch. The result was a 13-hour outage of AWS Cost Explorer in one of AWS's China regions. Amazon's official response was: "This brief event was the result of user error, specifically misconfigured access controls, not AI." A second incident involving Amazon Q Developer followed under nearly identical circumstances.
|
||||
|
||||
Amazon called it user error. The permissions architecture that let an AI agent bypass the two-person approval requirement for production changes that was the user error. The agent did exactly what the permissions allowed. The problem was that nobody had thought through what "operator-level permissions" means when the operator is non-deterministic and has no instinct for caution.
|
||||
|
||||
A month later, a developer named Grigorev used Claude Code to manage infrastructure for a learning platform. Claude Code ran `terraform destroy` on the production environment. 2.5 years of production data the database, the snapshots, the backups gone in one session. Grigorev admitted he had "over-relied on the AI agent to run Terraform commands." His post-incident note: enable delete protection in Terraform and AWS, move the state file to S3, manually review every plan before executing any destructive actions.
|
||||
|
||||
Both incidents share the same failure DNA: an AI agent with direct write access to production infrastructure, no destructive-action gate, and permissions scoped for a careful human being operated by something that has no concept of caution.
|
||||
|
||||
## Why This Is Getting Worse, Not Better
|
||||
|
||||
These aren't edge cases from inexperienced teams. They're symptoms of a structural acceleration problem.
|
||||
|
||||
AI-assisted developers produce commits at three to four times the rate of their peers but introduce security findings at 10x the rate, creating a security debt that accumulates faster than organizations can remediate it, according to Cloud Security Alliance research across Fortune 50 enterprises in 2026. Veracode tested over 100 LLMs on security-sensitive coding tasks and found that 45% of AI-generated code samples introduce OWASP Top 10 vulnerabilities a pass rate that has not improved across multiple testing cycles from 2025 through early 2026 despite vendor claims to the contrary.
|
||||
|
||||
For infrastructure code specifically, the numbers are worse. Misconfigured IAM roles appear in nearly 50% of AI-assisted cloud deployments. 60% of developers fail to adjust permission scopes in AI-generated code before deployment. 41% of AI-generated backend code includes overly broad permission settings. These aren't one-off mistakes they're the default output of a system that was trained to generate working code, not least-privilege code.
|
||||
|
||||
The specific problem with IaC is that an LLM generating a Terraform module or a Kubernetes manifest is doing something different from generating application code. Application code fails at runtime with an error. Infrastructure code fails at *deployment time* or *during an incident* when a misconfigured security group silently allows traffic it shouldn't, when an IAM role grants `*` on `*` because that was the easiest way to make the example work, when a Kubernetes PodSecurityPolicy that should restrict container privileges is written for an API version the cluster no longer enforces.
|
||||
|
||||
The linter passes. The `terraform plan` looks fine. The `kubectl apply` succeeds. The problem is invisible until something exploits it or an agent inherits those permissions and does something you didn't expect.
|
||||
|
||||
## The Three Specific Ways AI-Generated IaC Breaks in Production
|
||||
|
||||
### Hallucinated API Fields
|
||||
|
||||
LLMs are trained on documentation and examples up to a certain date. Kubernetes and Terraform both deprecate and remove fields across versions. An LLM asked to generate a manifest for a cluster running 1.27 might confidently produce syntax from 1.21 not because it's making up fields, but because its training data skews toward examples written when those fields were valid.
|
||||
|
||||
The specific failure mode: the field is syntactically valid, passes schema validation against a permissive validator, gets applied to the cluster, and is silently ignored. Your workload behaves incorrectly and nothing in the error logs explains why, because from the cluster's perspective nothing went wrong.
|
||||
|
||||
Our readiness probe incident above is one flavor of this. Another common one: `PodSecurityPolicy` resources that still lint fine but have been removed from Kubernetes since 1.25, so the policy is accepted as a valid resource object but never enforced. You think you have container restrictions. You don't.
|
||||
|
||||
### Over-Permissive IAM by Default
|
||||
|
||||
When an LLM generates an IAM policy or a Terraform `aws_iam_role_policy`, the path of least resistance is broad permissions. If you ask it to "create an IAM role for a Lambda function that reads from S3 and writes to DynamoDB," a meaningful percentage of the time it generates something like `s3:*` and `dynamodb:*` on `*` rather than scoping to the specific bucket ARN and table ARN in your environment. The function works in testing. The blast radius of a compromise is your entire S3 and DynamoDB estate.
|
||||
|
||||
LLMs generate default admin-level access controls without role restriction as a consistent pattern it's not a bug in a specific model, it's the output distribution of systems trained to make things work in examples where least-privilege adds prompt complexity.
|
||||
|
||||
### Destructive Operations Without Context
|
||||
|
||||
This is the Kiro incident and the Terraform destroy incident, generalized. AI agents operating on infrastructure have no instinctive understanding of the difference between "clean up this test environment" and "clean up this environment" when the latter is production. They execute the most semantically direct path to the goal. If `terraform destroy` resolves the stated problem most cleanly, that's what gets run.
|
||||
|
||||
The agent isn't reckless. It's literal. The same quality that makes it fast at generating boilerplate makes it dangerous when the task description is ambiguous and the permissions allow irreversible actions.
|
||||
|
||||
## Building the Validation Layer
|
||||
|
||||
The point isn't to stop using AI for infrastructure. The point is to stop treating AI-generated IaC as equivalent to human-reviewed IaC in your pipeline. It isn't. It needs its own validation layer one that runs before production and catches what linters miss.
|
||||
|
||||
**Schema validation against your actual cluster version, not the latest.** Tools like `kubeconform` and `kubeval` can validate manifests against a specific Kubernetes API version. Run this in CI with the actual version string of your production cluster. A manifest that's valid against 1.27 docs but invalid against your 1.25 cluster fails the check before it ever gets applied. This catches the hallucinated-field problem automatically.
|
||||
|
||||
**Policy-as-code with OPA/Gatekeeper or Kyverno.** Write policies that encode your organization's actual requirements: no containers running as root, all images must come from your internal registry, resource limits are mandatory, no `hostNetwork: true`. These policies run as admission controllers the cluster physically cannot accept a manifest that violates them, regardless of how it was generated. Treat these as the last line of defense, not the first.
|
||||
|
||||
**IAM policy linting before any apply.** Tools like `iamlive`, `aws-lint-iam-policies`, and Checkov can catch `*:*` policies, overly broad resource ARNs, and missing condition keys before Terraform runs. Plug these into your CI pipeline as a required check on any `.tf` file that touches IAM resources. An AI-generated role that grants `s3:*` on `*` fails the check. The developer sees it before it ships.
|
||||
|
||||
**A destructive-action gate not a best practice, a hard block.** Any command that contains `destroy`, `delete`, `drop`, `truncate`, or irreversible modifications to production resources requires explicit human sign-off before execution. This is not a code review suggestion. It's an architectural constraint: the agent identity physically cannot execute those operations without a separate approval token issued by a human in the last N minutes. The Kiro incident and the Terraform destroy incident both had one root cause: an agent with the technical capability to do permanent damage and no gate in the way.
|
||||
|
||||
**Mandatory peer review for agent-authored production changes with a real diff.** "Peer review" for AI-generated IaC doesn't mean a human glancing at a PR and clicking approve in 45 seconds. It means a human who understands the infrastructure reading the diff against a policy checklist, specifically looking for the things automated tools miss: does this IAM role actually need these permissions for this use case, is there a reason this container needs privileged mode, does this security group rule make sense given the network topology. The review bar doesn't lower because the author is an agent. It should arguably be higher, because the agent has no accountability for what it generated.
|
||||
|
||||
## The "User Error" Reframe
|
||||
|
||||
Amazon calling the Kiro incident user error is technically accurate and practically useless. Yes, the engineer had broader permissions than expected. Yes, no mandatory peer review existed for AI-initiated changes. Those are user errors in the same way that leaving a loaded gun on a coffee table and a child getting hurt is "user error." Correct. Also not the right level of analysis.
|
||||
|
||||
The useful framing is: an AI agent operating on production infrastructure will, with some non-zero probability, interpret an ambiguous task in a way that causes irreversible damage. That probability isn't zero for humans either but humans have intuitions about caution, irreversibility, and blast radius that models don't. The architecture needs to compensate for that gap. Not with better prompting. With hard constraints that exist outside the model's reasoning loop.
|
||||
|
||||
Your platform is the last line of defense. Not because the AI tools are bad they're genuinely useful and the productivity gains are real. But because any system that generates non-deterministic output operating on mutable production infrastructure needs external validation that doesn't rely on the system's own judgment about whether what it's about to do is safe.
|
||||
|
||||
The validation layer isn't overhead. It's what makes AI-assisted infrastructure work in production instead of just in demos.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
*This article is based on independent research I am conducting. The views and opinions expressed are my own and do not represent my employer.*
|
||||
|
||||
## References
|
||||
|
||||
1. **ThinkPol***Don't Give AI Agents the Keys to Production* (April 2026)[https://thinkpol.ca/2026/04/21/dont-give-ai-agents-the-keys-to-production/](https://thinkpol.ca/2026/04/21/dont-give-ai-agents-the-keys-to-production/?ref=hackernoon.com)
|
||||
2. **Particula Tech***When AI Agents Delete Production: Lessons from Amazon's Kiro Incident* (March 2026)[https://particula.tech/blog/ai-agent-production-safety-kiro-incident](https://particula.tech/blog/ai-agent-production-safety-kiro-incident?ref=hackernoon.com)
|
||||
3. **Vibe Graveyard***Claude Code Ran terraform destroy on Production and Took Down an Entire Learning Platform* (March 2026)[https://vibegraveyard.ai/story/claude-code-terraform-datatalks-infrastructure-destruction/](https://vibegraveyard.ai/story/claude-code-terraform-datatalks-infrastructure-destruction/?ref=hackernoon.com)
|
||||
4. **Tom's Hardware***Claude Code Deletes Developer's Production Setup Including Its Database and Snapshots* (March 2026)[https://www.tomshardware.com/tech-industry/artificial-intelligence/claude-code-deletes-developers-production-setup-including-its-database-and-snapshots-2-5-years-of-records-were-nuked-in-an-instant](https://www.tomshardware.com/tech-industry/artificial-intelligence/claude-code-deletes-developers-production-setup-including-its-database-and-snapshots-2-5-years-of-records-were-nuked-in-an-instant?ref=hackernoon.com)
|
||||
5. **Crackr AI***Vibe Coding Failures: Documented AI Code Incidents*[https://crackr.dev/vibe-coding-failures](https://crackr.dev/vibe-coding-failures?ref=hackernoon.com)
|
||||
6. **Cloud Security Alliance***Vibe Coding's Security Debt: The AI-Generated CVE Surge* (April 2026)[https://labs.cloudsecurityalliance.org/research/csa-research-note-ai-generated-code-vulnerability-surge-2026/](https://labs.cloudsecurityalliance.org/research/csa-research-note-ai-generated-code-vulnerability-surge-2026/?ref=hackernoon.com)
|
||||
7. **SQ Magazine***AI Coding Security Vulnerability Statistics 2026: Alarming Data* (April 2026)[https://sqmagazine.co.uk/ai-coding-security-vulnerability-statistics/](https://sqmagazine.co.uk/ai-coding-security-vulnerability-statistics/?ref=hackernoon.com)
|
||||
8. **Paperclipped***AI-Generated Code Has a Vulnerability Problem: The 2026 Security Data* (March 2026)[https://www.paperclipped.de/en/blog/ai-generated-code-security-vulnerabilities/](https://www.paperclipped.de/en/blog/ai-generated-code-security-vulnerabilities/?ref=hackernoon.com)
|
||||
9. **Diffray***LLM Hallucinations in AI Code Review* (February 2026)[https://diffray.ai/blog/llm-hallucinations-code-review/](https://diffray.ai/blog/llm-hallucinations-code-review/?ref=hackernoon.com)
|
||||
10. **Tenable***Security for AI: A Guide to Managing the Risks of Vibe Coding and AI in Software Development* (March 2026)[https://www.tenable.com/blog/security-for-ai-guide-managing-vibe-coding-risks-ai-in-software-development](https://www.tenable.com/blog/security-for-ai-guide-managing-vibe-coding-risks-ai-in-software-development?ref=hackernoon.com)
|
||||
11. **Elektor Magazine***2026: An AI Odyssey The 2025 Vibe Coding Hangover* (March 2026)[https://www.elektormagazine.com/articles/2026-an-ai-odyssey-vibe-coding-hangover](https://www.elektormagazine.com/articles/2026-an-ai-odyssey-vibe-coding-hangover?ref=hackernoon.com)
|
||||
12. **Incident Database AI***Amazon Kiro Incident #1442*[https://incidentdatabase.ai/cite/1442/](https://incidentdatabase.ai/cite/1442/?ref=hackernoon.com)
|
||||
@@ -0,0 +1,182 @@
|
||||
# An incident response playbook for satellite operations on AWS (Part-1): Detection and forensic readiness
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: —
|
||||
- **链接**: https://aws.amazon.com/blogs/publicsector/an-incident-response-playbook-for-satellite-operations-on-aws-part-1-detection-and-forensic-readiness/
|
||||
|
||||
## 简介
|
||||
|
||||
Satellites present unique reliability constraints like limited data uplink windows and the risk of bricking a very expensive piece of equipment.
|
||||
|
||||
Author:
|
||||
|
||||
## 正文
|
||||
|
||||
## [AWS Public Sector Blog](https://aws.amazon.com/blogs/publicsector/)
|
||||
|
||||
# An incident response playbook for satellite operations on AWS (Part-1): Detection and forensic readiness
|
||||
|
||||
|
||||
|
||||
|
||||
Incident response (IR) for satellite operations demands a fundamentally different playbook than traditional IT environments. A satellite orbiting 400 kilometers overhead cannot be quarantined with a firewall rule or reimaged overnight. Contact windows last minutes, not hours. Bandwidth constraints prevent bulk forensic collection. And a single bad command can permanently destroy a spacecraft.
|
||||
|
||||
In this post, the first in a two-part series, we focus on the detection and forensic readiness side of satellite IR. This post walks through instrumenting your ground segment with Amazon Web Services (AWS) security services and [AWS Ground Station](https://aws.amazon.com/ground-station/) so that threats surface before they cause damage, and forensic data is already flowing when an incident occurs. [Part two](https://aws.amazon.com/blogs/publicsector/an-incident-response-playbook-for-satellite-operations-on-aws-part-2-automated-response-and-recovery/) of the series covers containment, recovery, automated runbooks, and tabletop exercises.
|
||||
|
||||
The framework is designed for security operations center (SOC) teams, satellite mission operators, and cloud architects responsible for protecting space assets. The patterns apply to single-satellite missions and multi-satellite constellations alike.
|
||||
|
||||
## The challenge of satellite incident response
|
||||
|
||||
Satellite cyber incidents differ from traditional IT incidents in ways that break conventional IR playbooks. This section outlines the constraints that shape every subsequent phase of the framework.
|
||||
|
||||
A low Earth orbit (LEO) satellite is reachable only during scheduled contact windows with ground station antennas. A typical LEO spacecraft passes over a given ground station for approximately 8 minutes every 90-minute orbit.
|
||||
|
||||
If your worst-case gap between detecting a threat and taking action on the space segment is 82 minutes, your containment procedures must account for this delay. Pre-computing alternative ground stations across the AWS Ground Station global antenna network can shorten this gap.
|
||||
|
||||
Downlink bandwidth for LEO satellites typically ranges from tens of Mbps to several hundred Mbps depending on the radio frequency (RF) band, but with contact windows of only 5 to 10 minutes, operational data takes priority over forensic collection. Full memory dumps or extensive log pulls from the space segment compete directly with mission-critical data.
|
||||
|
||||
A bad command sent to a satellite can permanently degrade or destroy an asset worth hundreds of millions of dollars. Unlike a misconfigured server that can be reimaged, spacecraft damage is often irreversible.
|
||||
|
||||
Attribution adds another layer of complexity. A telemetry anomaly could be a radiation-induced single-event upset (SEU), thermal stress, hardware degradation, RF interference from a legitimate nearby emitter, intentional jamming, or an actual cyber intrusion. Distinguishing these causes requires correlating data across space weather, orbital mechanics, and cloud security domains simultaneously.
|
||||
|
||||
Regulatory frameworks are also shaping how satellite operators approach IR. The US Space Policy Directive 5 (SPD-5), issued in September 2020, establishes cybersecurity principles for space systems and emphasizes that IR capabilities must be integrated before launch. In Europe, the NIS2 Directive classifies space operators as essential entities subject to mandatory incident reporting within 24 hours (early warning), 72 hours (initial assessment), and one month (final report).
|
||||
|
||||
The proposed EU Space Act, still in legislative draft as of June 2026, introduces additional cybersecurity obligations specific to space services.
|
||||
|
||||
Real-world incidents highlight the stakes. In 2022, a cyberattack on a commercial satellite broadband network exploited a misconfigured VPN appliance to access the trusted management segment, pushing destructive commands that rendered tens of thousands of customer modems inoperable across Europe. The attack cascaded to disable remote monitoring for thousands of wind turbines and disrupt internet service in multiple countries, demonstrating how ground-segment compromises propagate into terrestrial critical infrastructure.
|
||||
|
||||
## Forensic data collection architecture
|
||||
|
||||
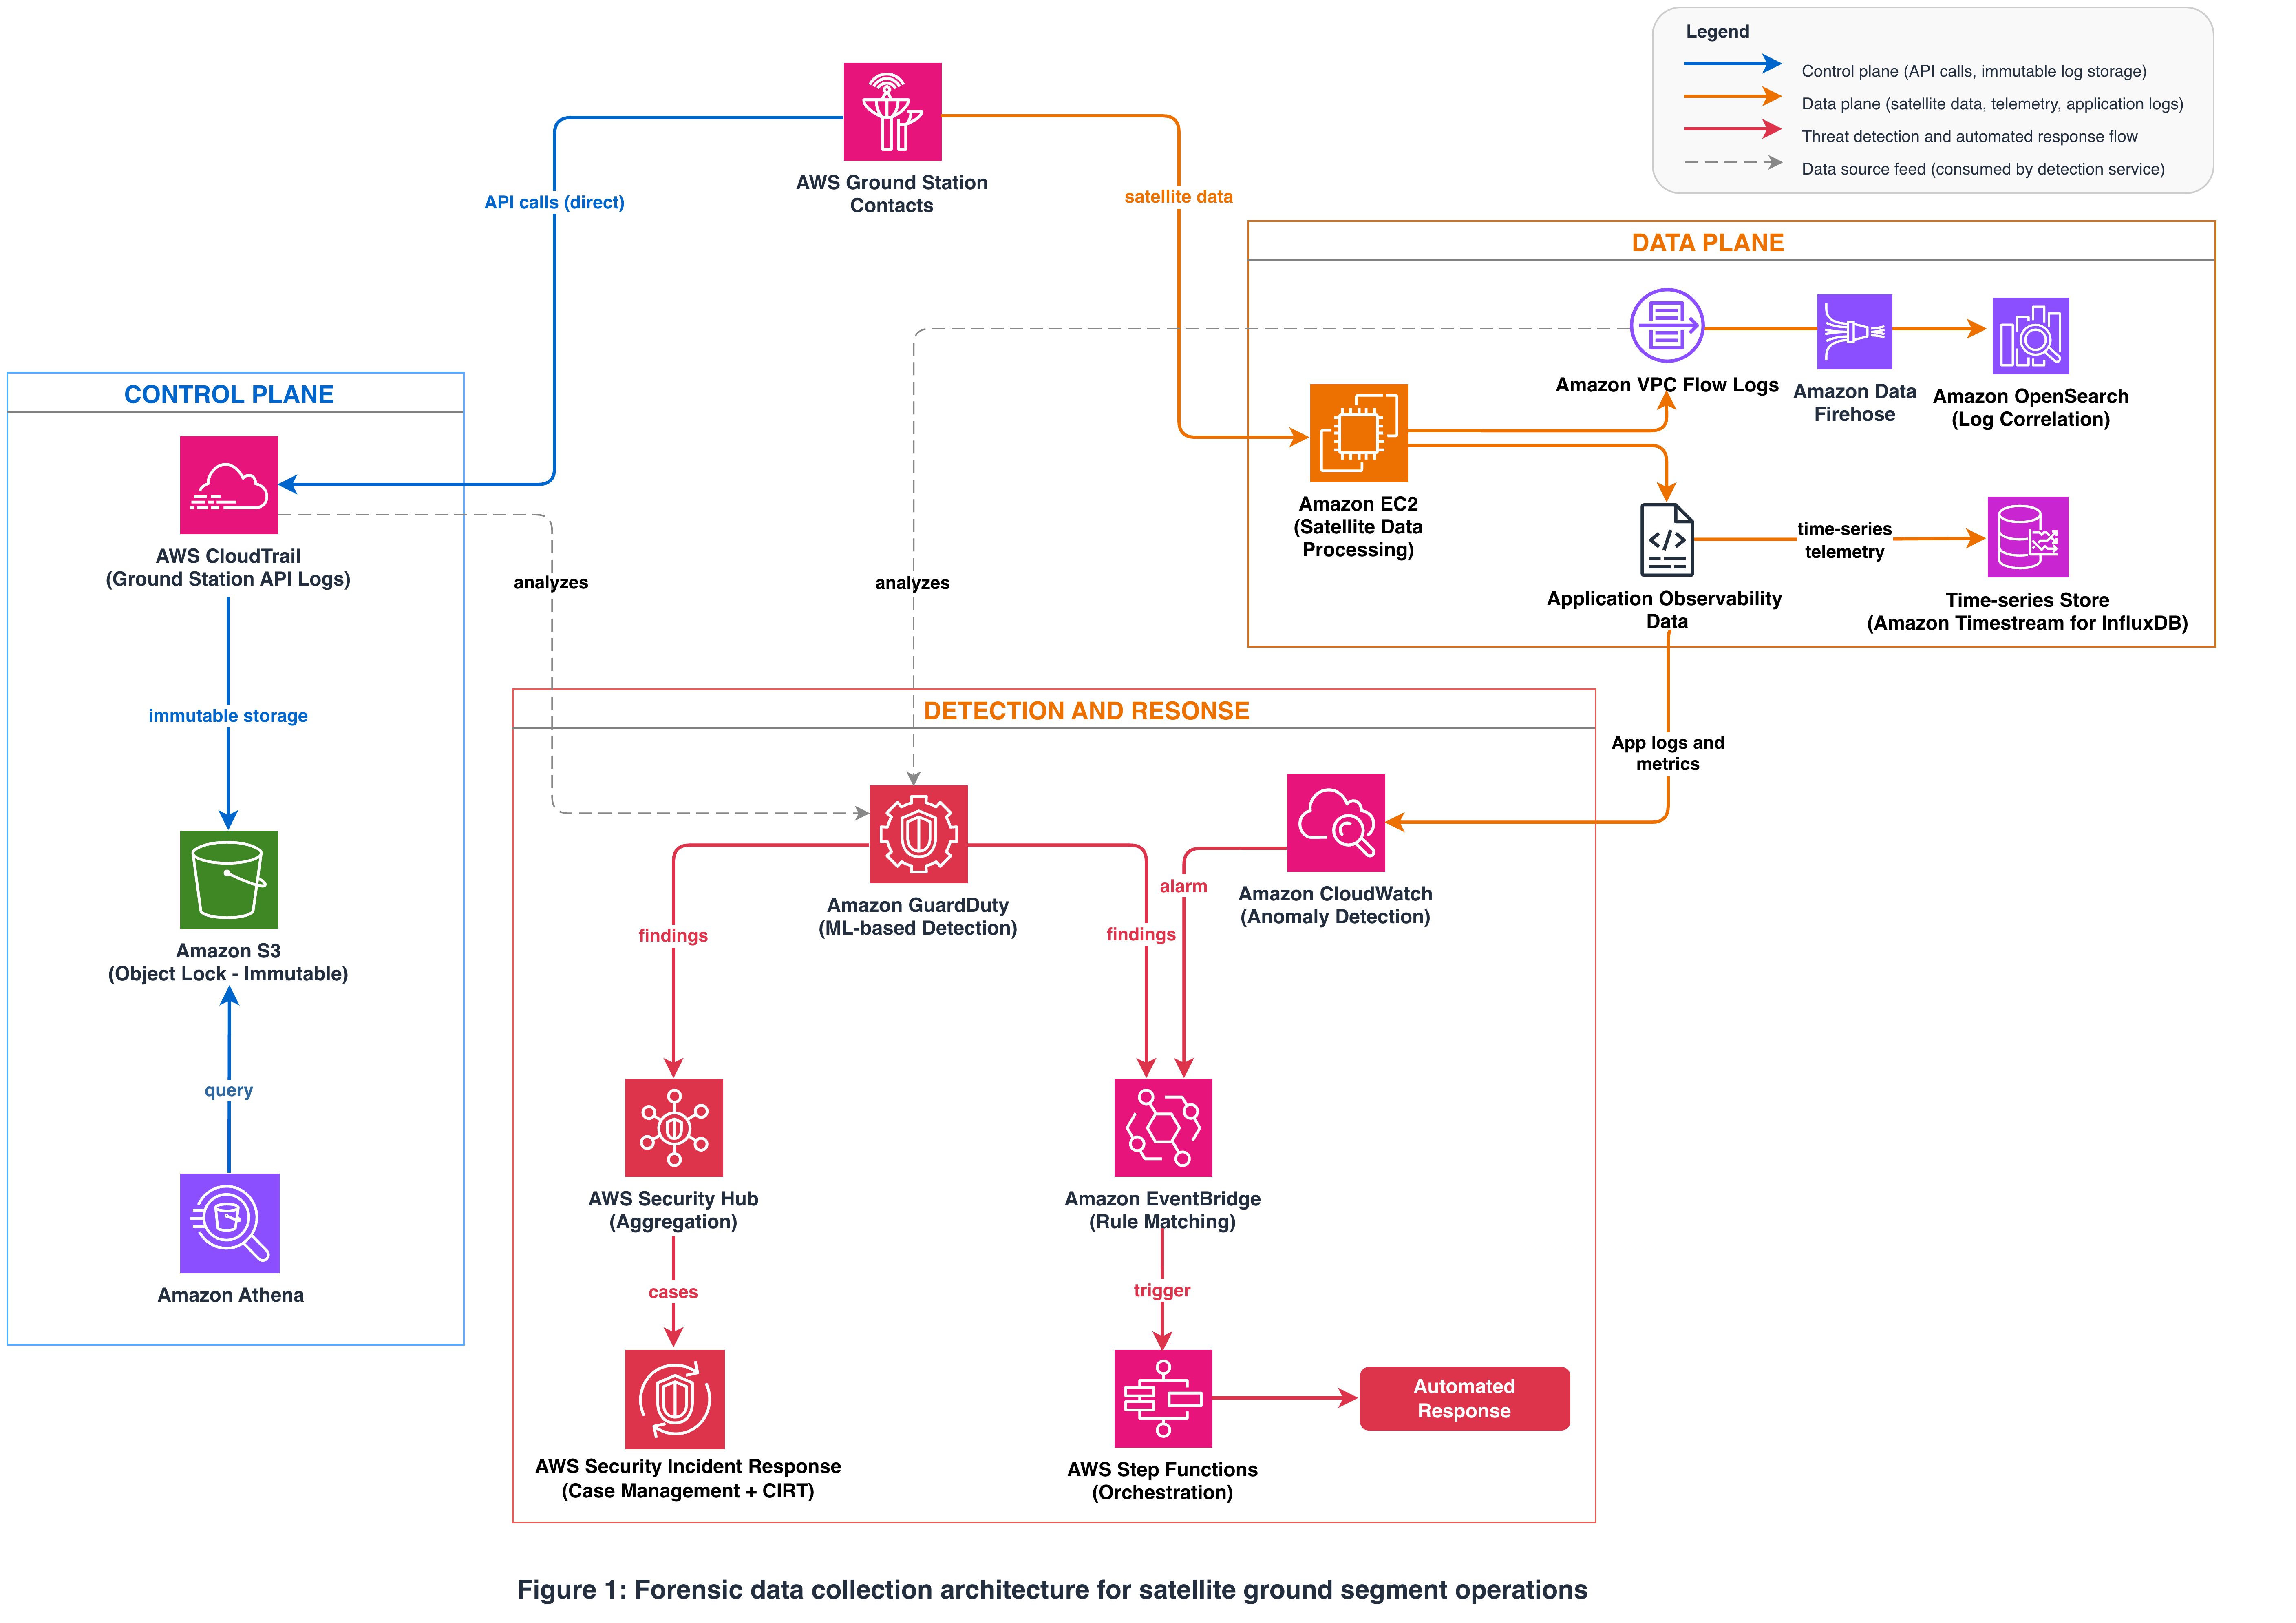
The architecture consists of two distinct planes. The **control plane** captures all AWS Ground Station management operations (scheduling contacts, modifying dataflow endpoints, changing configurations) through [AWS CloudTrail](https://aws.amazon.com/cloudtrail/). CloudTrail stores these Application Programming Interface (API) logs in [Amazon Simple Storage Service (Amazon S3)](https://aws.amazon.com/s3/). To achieve immutability, configure the destination S3 bucket with Object Lock in compliance mode, which prevents any principal from modifying or deleting log files until the retention period expires. You can query these logs with [Amazon Athena](https://aws.amazon.com/athena/) during investigations. Operators, automation scripts, or mission planning software invoke these API calls; CloudTrail passively observes and records them.
|
||||
|
||||
The **data plane** handles the actual satellite downlink: RF data flows from AWS Ground Station antennas into [Amazon Elastic Compute Cloud (Amazon EC2)](https://aws.amazon.com/ec2/) instances running your processing software. This path produces Amazon Virtual Private Cloud (Amazon VPC) Flow Logs (network-level records), application logs (telemetry values your software extracts), and custom metrics published to [Amazon CloudWatch](https://aws.amazon.com/cloudwatch/) for anomaly detection. VPC Flow Logs stream through [Amazon Data Firehose](https://aws.amazon.com/firehose/) into [Amazon OpenSearch Service](https://aws.amazon.com/opensearch-service/) for network-level log correlation and search during investigations.
|
||||
|
||||
Both planes feed into a shared detection and response layer where [Amazon GuardDuty](https://aws.amazon.com/guardduty/) (consuming CloudTrail logs and VPC Flow Logs) and Amazon CloudWatch (consuming telemetry metrics) generate findings and alarms that route through [Amazon EventBridge](https://aws.amazon.com/eventbridge/) to orchestrated response workflows. Figure 1 illustrates this architecture:
|
||||
|
||||
|
||||
|
||||
|
||||
*Figure 1: Forensic data collection architecture for satellite ground segment operations. The control plane (left) captures AWS Ground Station API activity through AWS CloudTrail, storing logs immutably in Amazon S3 for investigation with Amazon Athena. The data plane (right) processes satellite downlink data through Amazon EC2, producing VPC Flow Logs and telemetry metrics. Both planes feed into a detection and response layer where Amazon GuardDuty and Amazon CloudWatch surface findings that route through Amazon EventBridge to [AWS Step Functions](https://aws.amazon.com/step-functions/) for orchestrated response.*
|
||||
|
||||
## Space-side indicators of compromise
|
||||
|
||||
On the satellite side, watch for unexpected command acknowledgments (commands your system did not send), telemetry values deviating from predicted orbital mechanics or thermal models, and unscheduled satellite mode transitions. Communication link anomalies outside known environmental factors and power consumption patterns inconsistent with the satellite’s operational state also warrant investigation. These indicators are most meaningful when compared against telemetry baselines stored in a time-series data store such as [Amazon Timestream for InfluxDB](https://aws.amazon.com/timestream/).
|
||||
|
||||
## Discriminating cyber events from space environment events
|
||||
|
||||
The hardest analytical problem in satellite IR is distinguishing adversarial activity from natural phenomena. This four-step decision tree provides a systematic approach:
|
||||
|
||||
1. **Does the anomaly correlate with a known environmental condition?** Check solar activity indexes (Kp, Dst), South Atlantic Anomaly transit timing, eclipse transitions, or known RF interference zones. If yes, the anomaly is likely environmental.
|
||||
2. **Does the anomaly correlate with a Ground Station API call or configuration change?** Check CloudTrail. If yes, investigate the identity and authorization of that call.
|
||||
3. **Is the anomaly consistent with known adversary tactics, techniques, and procedures (TTPs) for satellite systems?** Cross-reference with threat intelligence.
|
||||
4. **Is the anomaly localized or constellation-wide?** A single-satellite anomaly is more likely hardware or environmental. Simultaneous anomalies across multiple satellites suggest a ground-side or systemic issue.
|
||||
|
||||
Use [Amazon Detective](https://aws.amazon.com/detective/) to visualize entity relationships during an investigation. Detective correlates CloudTrail logs, VPC Flow Logs, and Amazon GuardDuty findings into an entity-relationship graph, surfacing which AWS Identity and Access Management (IAM) roles accessed Ground Station APIs in the hours preceding an anomaly and what other resources those roles touched.
|
||||
|
||||
## Implementing detection with the AWS CLI
|
||||
|
||||
This section provides the specific commands that underpin the detection capabilities described above.
|
||||
|
||||
**Prerequisites:**
|
||||
|
||||
- An AWS account with AWS Ground Station access and at least one satellite onboarded (or access to the digital twin for testing)
|
||||
- IAM permissions for AWS CloudTrail, Amazon GuardDuty, Amazon CloudWatch, Amazon EventBridge, and [AWS Systems Manager](https://aws.amazon.com/systems-manager/)
|
||||
- AWS CLI v2 installed and configured with appropriate credentials
|
||||
- [jq](https://jqlang.github.io/jq/) installed for JSON parsing in investigation commands
|
||||
- An Amazon VPC configured to receive AWS Ground Station dataflow endpoints
|
||||
|
||||
### Querying CloudTrail for Ground Station activity
|
||||
|
||||
To retrieve all AWS Ground Station API calls from the past 24 hours, use `cloudtrail lookup-events` with the `EventSource` attribute:
|
||||
|
||||
```
|
||||
aws cloudtrail lookup-events \
|
||||
--lookup-attributes AttributeKey=EventSource,AttributeValue=groundstation.amazonaws.com \
|
||||
--start-time $(date -u -d '24 hours ago' +%Y-%m-%dT%H:%M:%SZ) \
|
||||
--end-time $(date -u +%Y-%m-%dT%H:%M:%SZ) \
|
||||
--query 'Events[*].{Time:EventTime,Name:EventName,User:Username}' \
|
||||
--output table
|
||||
```
|
||||
To filter specifically for contact scheduling events and extract fields critical to an investigation:
|
||||
|
||||
```
|
||||
aws cloudtrail lookup-events \
|
||||
--lookup-attributes AttributeKey=EventName,AttributeValue=ReserveContact \
|
||||
--start-time 2026-06-01T00:00:00Z \
|
||||
--end-time 2026-06-11T23:59:59Z \
|
||||
--output json | jq '.Events[] | {time: .EventTime, user: .Username, event: (.CloudTrailEvent | fromjson | {ip: .sourceIPAddress, agent: .userAgent, identity: .userIdentity.arn, params: .requestParameters})}'
|
||||
```
|
||||
This command extracts four fields critical to an investigation. The `sourceIPAddress` reveals whether the call originated from your expected operations center or an unfamiliar location. The `userAgent` indicates what tool made the call (your mission planning software, a raw AWS CLI session, or an unfamiliar SDK client). The `userIdentity.arn` identifies the specific IAM role or user, letting you determine whether this is an authorized operator or a compromised credential. The `requestParameters` shows which satellite, ground station, and time window were requested, revealing the attacker’s intent if the call was unauthorized.
|
||||
|
||||
To list all contacts in a given time window for review during an investigation:
|
||||
|
||||
```
|
||||
aws groundstation list-contacts \
|
||||
--status-list COMPLETED FAILED \
|
||||
--start-time 2026-06-01T00:00:00Z \
|
||||
--end-time 2026-06-11T23:59:59Z \
|
||||
--output table
|
||||
```
|
||||
To retrieve full details on a specific suspicious contact, including its mission profile, satellite, ground station, and dataflow configuration:
|
||||
|
||||
```
|
||||
aws groundstation describe-contact \
|
||||
--contact-id <contact-uuid> \
|
||||
--output json
|
||||
```
|
||||
Compare the output against your expected contact schedule to identify unauthorized or unexpected activity.
|
||||
|
||||
### Setting up CloudWatch anomaly detection for telemetry
|
||||
|
||||
If your ground segment application publishes custom metrics from satellite telemetry, you can apply Amazon CloudWatch anomaly detection to automatically baseline these values and alert on deviations. CloudWatch anomaly detection uses machine learning algorithms that account for hourly, daily, and weekly seasonality patterns, training on approximately two weeks of historical data to produce a band of expected values. The resulting model continuously retrains as new data arrives, adapting to evolving telemetry behavior over the satellite’s mission life. Alarms fire only when observed values fall outside this learned band by the number of standard deviations you specify, making the detection threshold explicit and tunable rather than opaque. Create an anomaly detector on a custom telemetry metric:
|
||||
|
||||
```
|
||||
aws cloudwatch put-anomaly-detector \
|
||||
--namespace "SatelliteOps/Telemetry" \
|
||||
--metric-name "SignalToNoiseRatio" \
|
||||
--stat "Average" \
|
||||
--dimensions Name=SatelliteId,Value=SAT-001 \
|
||||
--configuration '{
|
||||
"ExcludedTimeRanges": [],
|
||||
"MetricTimezone": "UTC"
|
||||
}'
|
||||
```
|
||||
Then create an alarm that fires when the metric breaches the anomaly band. The `--alarm-actions` parameter specifies an [Amazon Simple Notification Service (Amazon SNS)](https://aws.amazon.com/sns/) topic that delivers alerts to your SOC and satellite operations teams when the threshold is crossed:
|
||||
|
||||
```
|
||||
aws cloudwatch put-metric-alarm \
|
||||
--alarm-name "SAT-001-SNR-Anomaly" \
|
||||
--evaluation-periods 3 \
|
||||
--comparison-operator LessThanLowerOrGreaterThanUpperThreshold \
|
||||
--threshold-metric-id ad1 \
|
||||
--metrics '[
|
||||
{"Id": "m1", "MetricStat": {"Metric": {"Namespace": "SatelliteOps/Telemetry", "MetricName": "SignalToNoiseRatio", "Dimensions": [{"Name": "SatelliteId", "Value": "SAT-001"}]}, "Period": 300, "Stat": "Average"}},
|
||||
{"Id": "ad1", "Expression": "ANOMALY_DETECTION_BAND(m1, 2)"}
|
||||
]' \
|
||||
--alarm-actions arn:aws:sns:us-east-1:123456789012:satellite-security-alerts \
|
||||
--alarm-description "Triggers when SNR deviates from learned baseline by more than 2 standard deviations"
|
||||
```
|
||||
The `ANOMALY_DETECTION_BAND(m1, 2)` expression tells CloudWatch to use a band width of 2 standard deviations from the learned baseline. A tighter band produces more alerts; a wider band reduces noise but may miss subtle manipulation. For satellite telemetry, start with 2 and adjust based on your false-positive rate. The model takes approximately two weeks of data to train an accurate baseline.
|
||||
|
||||
### Cleaning up
|
||||
|
||||
If you created the Amazon CloudWatch anomaly detector and alarm for testing purposes, remove them to avoid incurring ongoing monitoring costs:
|
||||
|
||||
```
|
||||
aws cloudwatch delete-anomaly-detector \
|
||||
--single-metric-anomaly-detector \
|
||||
Namespace="SatelliteOps/Telemetry",MetricName="SignalToNoiseRatio",Stat="Average",Dimensions=[{Name=SatelliteId,Value=SAT-001}]
|
||||
aws cloudwatch delete-alarms \
|
||||
--alarm-names "SAT-001-SNR-Anomaly"
|
||||
```
|
||||
AWS CloudTrail and Amazon GuardDuty are ongoing services recommended for production use and should remain active on your Ground Station accounts.
|
||||
|
||||
## Conclusion
|
||||
|
||||
This post walked through instrumenting a satellite ground segment for detection and forensic readiness using AWS security services. It covered logging AWS Ground Station API activity with AWS CloudTrail, applying machine learning-based threat detection with Amazon GuardDuty, building telemetry baselines with Amazon CloudWatch anomaly detection, and collecting forensic data into immutable storage.
|
||||
|
||||
The result is a ground segment that surfaces threats through multiple detection channels, discriminates cyber events from space environment anomalies using a structured decision tree, and continuously preserves evidence for investigation.
|
||||
|
||||
In part two of this series, we cover what to do when these detections fire: containment within contact-window constraints, eradication and recovery, automated runbooks with human decision gates, and tabletop exercise scenarios to prepare your team for the real thing.
|
||||
|
||||
To get started today, activate AWS CloudTrail and Amazon GuardDuty on your AWS Ground Station accounts. For deeper engagement, reach out to the [AWS Aerospace and Satellite team](https://aws.amazon.com/government-education/aerospace-and-satellite/) or explore [AWS Security Incident Response](https://aws.amazon.com/security-incident-response/) for integrated case management.
|
||||
61
sreweekly/markdown/522/05-incident-fest-26.md
Normal file
61
sreweekly/markdown/522/05-incident-fest-26.md
Normal file
@@ -0,0 +1,61 @@
|
||||
# Incident Fest ’26
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Uptime Labs
|
||||
- **链接**: https://www.uptimelabs.io/incident-fest-26
|
||||
|
||||
## 简介
|
||||
|
||||
This looks fun! It’s a free virtual event on July 8.
|
||||
|
||||
## 正文
|
||||
|
||||
# IncidentFest'26
|
||||
|
||||
The theme: Incident response in the Age of AI
|
||||
|
||||
Visit for free from anywhere
|
||||
|
||||
“Incidents are where engineers are made.”
|
||||
|
||||
— Vanessa Huerta Granda
|
||||
|
||||
## WHAT'S ON AT THE FESTIVAL?
|
||||
|
||||
### Main Stage
|
||||
|
||||
The big show. Live keynotes, by industry leaders, all focused on the role of human expertise in the age of AI.
|
||||
|
||||
|
||||
### AMA Marquee
|
||||
|
||||
Explore questions and answers from John Allspaw, former CTO at Etsy and Beth Adele Long.
|
||||
|
||||
|
||||
|
||||
### Prize Booth
|
||||
|
||||
Play an incident drill for the chance to win vouchers, swag and premium prizes
|
||||
|
||||
## Available Talks
|
||||
|
||||
## Speakers
|
||||
|
||||
featuring an all-star lineup of incident response classics.
|
||||
|
||||
|
||||
Human in the loop?
|
||||
|
||||
Approve approve approve oh no
|
||||
|
||||
/dangerously-skip-permissions oops
|
||||
|
||||
## FAQ.
|
||||
|
||||
## Is it recorded?
|
||||
|
||||
The talks will be recorded and the prize & poll booths will stay open afterwards. But we encourage live attendance to ask questions at the AMA and talks.
|
||||
|
||||
## What's the AI angle, really?
|
||||
|
||||
AI-assisted development is increasing (and will continue to increase) the rate at which software is created. AI will also continue to be rolled out across parts of incident response. What’s unknown is its effect on the volume, frequency and complexity of incidents. That’s the context which this festival aims to explore.
|
||||
@@ -0,0 +1,436 @@
|
||||
# The feedback loops behind Kubernetes
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Fatih Arslan — PlanetScale
|
||||
- **链接**: https://planetscale.com/blog/the-feedback-loops-behind-kubernetes
|
||||
|
||||
## 简介
|
||||
|
||||
This article does a really great job of building up an explanation of feedback-based control and the difference between edge-triggered and level-triggered systems.
|
||||
|
||||
## 正文
|
||||
|
||||
For the last decade, Kubernetes has been the backdrop to most of my work: operating clusters, helping build hosted Kubernetes, and writing Kubernetes operators. At PlanetScale, that now means running stateful systems like Postgres and MySQL in production. Kubernetes has many faces, but here I want to talk about one face only: why it is so good at running workloads at scale.
|
||||
|
||||
People ask me what an operator actually does. The canonical answer is: "it reconciles desired state." This is correct, but it also tells you almost nothing.
|
||||
|
||||
An operator is a feedback controller. It's the same closed loop that runs a thermostat or keeps your car at a fixed speed on cruise control. In our case, the thing being controlled is a database. I have been building these loops for years, and the best way I know to make them click is to ignore Kubernetes at the beginning. Kubernetes is full of control theory, even if we don't call it that in the day-to-day.
|
||||
|
||||
Before we look at a single line of Kubernetes, we're going to run a production database by hand and slowly let the feedback loop appear on its own. Then we'll map that loop to Kubernetes, with the pieces production needs: a store, watches, queues, retries, and more. At the end, we'll look at what one of these loops looks like in a real operator.
|
||||
|
||||
Note
|
||||
|
||||
A working understanding of containers and `kubectl` helps, but you don't need to be a Kubernetes expert. I'll use terms like *idempotent*, *fan-in*, and *eventual consistency*, and introduce the parts that matter as we go.
|
||||
|
||||
We're going to start slow and gradually ramp things up. Each part builds on the previous.
|
||||
|
||||
## [Part 1: running Postgres by hand](https://planetscale.com#part-1-running-postgres-by-hand)
|
||||
|
||||
### [One container, one machine](https://planetscale.com#one-container-one-machine)
|
||||
|
||||
Let's start from scratch. I want to run Postgres on a Linux box, and I need it inside a container. To start it, we run:
|
||||
|
||||
```
|
||||
docker run -d --name pg \
|
||||
-e POSTGRES_PASSWORD=secret \
|
||||
postgres:18
|
||||
```
|
||||
That's it. Postgres is running. My app connects to it, writes some rows, and everything works fine. But then the machine goes away: the cloud provider reclaims the instance (hardware fails, or a spot instance gets taken back), or I ship a new version of my setup, which means stopping the old container and starting a fresh one in its place. Either way, the container is replaced, and my data is gone. The container storage was ephemeral, and I did not attach any persistent volume to it.
|
||||
|
||||
There is already a gap between what I *want* (Postgres, running, with my data) and what I *have* (a container whose storage disappears when the container or node goes away). The rest of this post is about that gap and the machinery we build to close it.
|
||||
|
||||
### [Pick a node, by hand](https://planetscale.com#pick-a-node-by-hand)
|
||||
|
||||
Imagine we have hundreds of nodes (servers) we can use. I already have other workloads running on them. I need to decide *which one* runs this database. So I `ssh` into the box that looks the least busy and start the container there.
|
||||
|
||||
```
|
||||
ssh node-07 'docker run -d --name pg ... postgres:18'
|
||||
```
|
||||
I picked `node-07` because it looked idle enough. I start keeping track of it, save it in some sort of config file, and push it to some repo.
|
||||
|
||||
### [It needs a real disk](https://planetscale.com#it-needs-a-real-disk)
|
||||
|
||||
Container storage is ephemeral, so I have to attach a real block device. In the cloud this is an EBS volume (e.g. on AWS); on bare metal it's a physical disk. Assuming it's a block device, this is what we usually do: provision the volume, attach it to the node, format it, mount it, and point Postgres' data directory at the mount.
|
||||
|
||||
```
|
||||
# provision + attach first with cloud CLI, then on the node:
|
||||
mkfs.ext4 /dev/nvme1n1
|
||||
mkdir -p /var/lib/pg-data
|
||||
mount /dev/nvme1n1 /var/lib/pg-data
|
||||
docker run -d --name pg \
|
||||
-e POSTGRES_PASSWORD=secret \
|
||||
-v /var/lib/pg-data:/var/lib/postgresql \
|
||||
postgres:18
|
||||
```
|
||||
These are a lot of steps, and each one can fail halfway. And if the disk fills up later, Postgres stops accepting writes and we have to resize the volume by hand: first through the cloud provider, then again inside the filesystem.
|
||||
|
||||
### [One isn't enough](https://planetscale.com#one-isnt-enough)
|
||||
|
||||
A single Postgres instance is a single point of failure. We want high availability: one primary and two replicas. These need to be on three different machines, with streaming replication between them. So we do the same steps again, three times, on `node-07`, `node-12`, and `node-19`. I also wire up replication by hand: `primary_conninfo`, replication slots, all of it.
|
||||
|
||||
Now we have three nodes with three Postgres instances. One of the instances is the primary (here it's `node-07`). But this raises new problems, like what to do if the primary's node dies?
|
||||
|
||||
### [They have to find each other](https://planetscale.com#they-have-to-find-each-other)
|
||||
|
||||
Here is another thing we have to solve. The replicas need to reach the primary, and the primary needs to accept their connections. And every one of these addresses is an IP that changes when a container restarts.
|
||||
|
||||
The first thing I do is hard-code the IPs. I write `node-07`'s address into the replicas' config, I list the replicas' addresses in the primary's `pg_hba.conf`, and I keep a small `/etc/hosts` table and save it somewhere.
|
||||
|
||||
```
|
||||
# on each replica's postgresql.auto.conf, until the primary is recreated with a new IP
|
||||
primary_conninfo = 'host=10.4.7.21 port=5432 user=replicator ...'
|
||||
```
|
||||
But we still have a problem: the first time the primary is recreated with a different IP, the whole cluster falls apart.
|
||||
|
||||
### [The watchdog script](https://planetscale.com#the-watchdog-script)
|
||||
|
||||
Now, this is where we start thinking about how to solve these issues. Everything described so far can break, and will continue to break even if I fix it:
|
||||
|
||||
- A replica process dies and doesn't come back.
|
||||
- A disk gets full.
|
||||
- The primary fails and a replica has to be promoted.
|
||||
- A config I changed on two nodes but forgot on the third one. They are now out of sync.
|
||||
|
||||
Let's assume we've set up a simple uptime monitor and we're going to get paged for all these cases. To avoid getting paged at night, we do the sensible thing: write a script. So we decide to write a loop that wakes up every few seconds, looks at each node, and fixes whatever's wrong.
|
||||
|
||||
```
|
||||
while true; do
|
||||
for node in node-07 node-12 node-19; do
|
||||
if ! ssh "$node" 'pg_isready -q'; then
|
||||
ssh "$node" 'docker start pg' # it died, bring it back
|
||||
fi
|
||||
usage=$(ssh "$node" "df --output=pcent /var/lib/pg-data | tail -1 | tr -dc 0-9")
|
||||
if [ "$usage" -gt 80 ]; then
|
||||
grow_volume "$node" # disk filling, make it bigger
|
||||
fi
|
||||
done
|
||||
sleep 5
|
||||
done
|
||||
```
|
||||
It's written in Bash, and probably has tons of bugs. You notice something here? The loop doesn't care *how* the database got into a bad state. Every five seconds it looks at the current state of the world and asks this question: does reality match what I want?
|
||||
|
||||
If a process is down, start it. If a disk is filling, grow it. Run the loop once or run it a thousand times and the result is the same, because each action is conditional on the current state. The script is *idempotent*.
|
||||
|
||||
### [Changing a parameter](https://planetscale.com#changing-a-parameter)
|
||||
|
||||
Let's make things a little more complex. I need to raise [`max_connections`](https://www.postgresql.org/docs/current/runtime-config-connection.html#GUC-MAX-CONNECTIONS) from 100 to 500. This one is not a reload-only change. PostgreSQL says it can only be set at server start, so the manual version is to `ssh` into each box, edit `postgresql.conf`, restart Postgres, and check that it took on all three.
|
||||
|
||||
Because I know that ssh'ing into the nodes manually isn't a thing I want anymore, I do the same thing we did previously: I write the desired value down in one place and teach the loop to enforce it.
|
||||
|
||||
```
|
||||
WANT_MAX_CONNECTIONS=500
|
||||
for node in node-07 node-12 node-19; do
|
||||
have=$(ssh "$node" "psql -tAc 'show max_connections'")
|
||||
if [ "$have" != "$WANT_MAX_CONNECTIONS" ]; then
|
||||
ssh "$node" "sed -i 's/^max_connections.*/max_connections = $WANT_MAX_CONNECTIONS/' /var/lib/pg-data/postgresql.conf"
|
||||
ssh "$node" "docker restart pg"
|
||||
fi
|
||||
done
|
||||
```
|
||||
This is the same idea as before. I read what I *want* (a variable). Observe what I *have* (a query). If they differ, I take an action to close the difference. Again, I don't track whether I changed it last time. All I do is compare and [converge](https://dictionary.cambridge.org/dictionary/english/converge), every loop.
|
||||
|
||||
### [What we actually built](https://planetscale.com#what-we-actually-built)
|
||||
|
||||
I started with a desired state that was written down in one place: three instances, this disk size, `max_connections = 500`. Every few seconds I observe the actual state of the system. I compute the difference. I take whatever action closes that difference. Then I do it again, forever.
|
||||
|
||||
That's a **closed feedback loop**. The word "closed" matters. It means the output of the system is fed back into the next decision. I don't run `docker start` and assume the database is fine. I check the database again. If it is still wrong, I act again. If it is already correct, I do nothing.
|
||||
|
||||
The nice part is that the same loop works for different problems. It can restart a dead process, grow a disk, or push `max_connections = 500`. The action changes, but the shape stays the same: read what I want, observe what I have, compare them, act, repeat. If I draw the same thing as a block diagram, with the control theory names added, it would look like this:
|
||||
|
||||
Here is how the vocabulary from [control theory](https://en.wikipedia.org/wiki/Control_theory) maps cleanly onto my shell script:
|
||||
|
||||
- The **setpoint** is my desired state, the variables at the top of the script (disk size, max_connections and so on).
|
||||
- The **measured output** is what I observe:`pg_isready` ,`df` ,`show max_connections` .
|
||||
- The **error** (e) is the difference between them.
|
||||
- The **controller** is the body of the loop, the`if` statements that decide what to do. It is not the whole script.
|
||||
- The **actuator** is what carries out the action:`ssh` plus`docker start` .
|
||||
- The **plant** is the system being controlled, Postgres and its disk.
|
||||
|
||||
That also gives us a nice way to understand **open-loop** control. My very first attempt, `ssh` in, run the command, and walk away, was open-loop: fire an action and assume it worked. The Bash script is closed-loop because it keeps feeding the measured state back into the next decision.
|
||||
|
||||
A Bash loop is not a production control plane. Just to name a few issues with it:
|
||||
|
||||
- It has no concurrency control, so two copies of the script can race each other. Imagine both deciding to promote a different replica.
|
||||
- It keeps its only real state, "am I mid-failover?", in a shell variable that could die with the process.
|
||||
- It polls every node every five seconds whether anything changed or not, which is fine for three nodes, but too expensive for three thousand nodes.
|
||||
- It has no idea what to do when the `ssh` itself times out.
|
||||
- And the moment I want a second kind of resource, a connection pooler, a backup job, a read replica in another region, I'm copy-pasting this whole structure.
|
||||
|
||||
What if the script also fails? Who runs it then? We could keep hardening this script, but look at where it goes: we would need a real store for the desired state, watches instead of polling, a work queue, retries, leader election. We would be rebuilding Kubernetes. The real platform already exists, and it's Kubernetes.
|
||||
|
||||
## [Part 2: how we reinvented Kubernetes](https://planetscale.com#part-2-how-we-reinvented-kubernetes)
|
||||
|
||||
Now we can map what we hand-rolled in Part 1 to Kubernetes. Almost all of it already exists there. The operator is the part we care about.
|
||||
|
||||
### [The other loops](https://planetscale.com#the-other-loops)
|
||||
|
||||
Let's go through some of the pieces we built by hand before the watchdog loop. You already know these components by name. What you might not have noticed is that they also work like controllers.
|
||||
|
||||
**Spinning up the container: the kubelet.** First, a quick definition: a Pod is the smallest thing Kubernetes runs, one or more containers scheduled together on a node and sharing its network. For us it's the Postgres container. On every node runs an agent called the kubelet. Its desired state is the set of Pods assigned to its node, which it learns from the API server. Its observed state is the set of containers actually running, which it gets from the container runtime. When they differ, it starts the missing container, kills the extra one, or restarts the crashed one. My `if ! pg_isready; then docker start; fi` is the kubelet's job, just done properly. The kubelet doesn't shell into anything; it talks to containerd over a gRPC socket, which talks to runc.
|
||||
|
||||
**Picking a node: the scheduler.** Remember me choosing `node-07`? That's the scheduler's whole reason to exist. It watches for Pods with no node assigned, filters out the nodes that can't work, scores the rest, and writes the decision to one field: `pod.Spec.NodeName`. The scheduler doesn't start the container; it records the placement and lets the kubelet pick it up. You will realize that most things in Kubernetes are decoupled like this.
|
||||
|
||||
**Attaching the disk: CSI and the PV/PVC sync.** My multi-step `mkfs` and `mount` script becomes a `PersistentVolumeClaim`, which is a declarative request for storage. The [Container Storage Interface (CSI)](https://github.com/container-storage-interface/spec/blob/master/spec.md) driver turns that request into a real volume. CSI itself is a set of controllers and sidecars: one provisions, one attaches, one resizes, and so on, while the kubelet calls the driver's node plugin to do the actual mount. It's a family of controllers. If there is a PVC but no disk behind it, one controller creates the disk. If the PVC size increases, another controller calls the provider API (e.g., AWS `ModifyVolume`). Again, I write intent, and a controller does the actual work. (note: I wrote one of the early production CSI drivers, [csi-digitalocean](https://github.com/digitalocean/csi-digitalocean), and a [long post about building one](https://arslan.io/2018/06/21/how-to-write-a-container-storage-interface-csi-plugin/).)
|
||||
|
||||
**Making them find each other: the CNI and Services.** The `/etc/hosts` problem is solved at a layer we no longer have to think about. A CNI plugin gives Pods their network identity; Cilium, for example, does this with eBPF instead of a pile of `iptables` rules. For stateful workloads, a StatefulSet plus a [headless Service](https://kubernetes.io/docs/concepts/services-networking/service/#headless-services) gives each replica its own stable DNS name, which is exactly what a Postgres replica needs. The hard-coded IP that broke our cluster becomes a name that keeps working. DNS is only one tool here; other service discovery systems like etcd, ZooKeeper, and Consul solve similar problems.
|
||||
|
||||
As you see, all the problems we solved with `ssh` and various scripts are replaced by Kubernetes components and drivers. And these are just a few of them:
|
||||
|
||||
All of this so far is useful context, but the part we care about is *our watchdog* loop, because that's the one we get to write ourselves.
|
||||
|
||||
That's the operator.
|
||||
|
||||
### [The for-loop translated to Kubernetes](https://planetscale.com#the-for-loop-translated-to-kubernetes)
|
||||
|
||||
In Kubernetes, our watchdog script is a **controller**, and the standard way to write one in Go is a library called [controller-runtime](https://github.com/kubernetes-sigs/controller-runtime). At its heart, it's a function with a basic signature:
|
||||
|
||||
```
|
||||
func (r *Reconciler) Reconcile(ctx context.Context, req reconcile.Request) (reconcile.Result, error) {
|
||||
// req contains a namespace/name. That's it. That's the whole input.
|
||||
}
|
||||
```
|
||||
Notice what is missing here: the function isn't told what changed. There is no diff. It isn't handed the old object and the new object. It isn't given an event type. It gets a key, a namespace and a name, and nothing else. It's minimal by design, because it has to work for many different controllers. The function's job is to fetch the object with that namespace/name, look at the world, and converge to the desired state.
|
||||
|
||||
### [Edge-triggered notifications, level-triggered logic](https://planetscale.com#edge-triggered-notifications-level-triggered-logic)
|
||||
|
||||
There are two ways to build any closed feedback loop:
|
||||
|
||||
- **Edge-triggered** : act on transitions, on events. "The disk crossed 80%." "The Pod was deleted." "The number of replicas increased by 2."
|
||||
- **Level-triggered** : act on the current state, regardless of how you got there. "The disk*is* at 85%." "The Pod*is* missing." "The number of replicas is 3."
|
||||
|
||||
My first mental model of controllers, and probably yours at some point, was edge-triggered: listen to a stream of changes, and for each change, try to converge.
|
||||
|
||||
The problem is that this is very fragile. In distributed systems, if one component is fragile, the fragility spreads to the rest of the system. Why is edge-triggering fragile? Say your controller is down for thirty seconds. It misses the events from those thirty seconds, and its view of the world is now permanently wrong. If two events arrive out of order, you process them out of order. If an event is delivered twice, you act twice. You're rebuilding your state from a stream of events, and you've inherited all of event sourcing's hard problems.
|
||||
|
||||
Here is a very concrete example. Assume you have 1 replica, and you increase it to 3 replicas. Because you have only subscribed to changes, either:
|
||||
|
||||
1. You miss the event (maybe the queue dropped it, or the consumer, your app, dropped it due to a crash or a full buffer).
|
||||
2. You receive it twice.
|
||||
|
||||
In the first case, you won't be able to self-correct. In the second case, if your handler blindly applies the delta again, you'll end up with 5 replicas (you overshoot), instead of 3.
|
||||
|
||||
The level-triggered model fixes all of that. Remember, our shell script never asked "what changed?" It asked "what *is* true right now?", every five seconds, from scratch. Miss a loop, and the next one catches up. Run the loop twice, and you get the same result. The current state of the world is the only input that matters, and it's always available to read. So in the level-triggered case, our example above becomes this: you read `replicas=3`, you check the current number of replicas, which is 1, and you increase by 2.
|
||||
|
||||
If you miss the event, no one cares. In the next reconcile loop you'll catch it. If your app crashes, it comes back, reads again and detects that it did not increase it yet, increases it.
|
||||
|
||||
Kubernetes controllers combine both: **edge-triggered notifications, level-triggered logic**.
|
||||
|
||||
Events (the edges) are only a hint that it's worth looking again. They tell you *when* to reconcile, never *what* to do. The reconcile itself is level-based: it reads the current state (e.g., `replicas=3`) and drives toward the desired state (e.g., `create 2 replicas`), ignoring the triggering event completely. That's *why* `Reconcile` only gets a key. The framework makes it hard to write edge-triggered logic, on purpose. Edge-triggered logic is how you get a controller that's fragile and permanently wrong after its first hiccup.
|
||||
|
||||
Our bash script stumbled into this property by accident, at least for the sake of the example. But the `controller-runtime` framework gives it to you on purpose. It's why a Kubernetes controller can crash, get restarted ten minutes later, and converge correctly with no special recovery code. There is no recovery code. There is just the loop. The controller can reconstruct the world from scratch.
|
||||
|
||||
### [Informers, the work queue, and a cache](https://planetscale.com#informers-the-work-queue-and-a-cache)
|
||||
|
||||
So where do the edges come from? And what stops a controller from DDoSing the API server by listing everything every five seconds like my script did?
|
||||
|
||||
The answer is the **informer**. An informer opens a single watch against the API server for a given resource type, streams every add, update, and delete, and keeps a complete in-memory **cache** of the objects we're interested in. Two things matter here:
|
||||
|
||||
First, the informer turns each watch event into a key and puts it on a **work queue**. The queue does a lot of work for you.
|
||||
|
||||
- It *coalesces* : if the same object is updated five times before you get to it, you reconcile it once, against the latest state (level-triggered again).
|
||||
- It *rate-limits* : an object that keeps erroring backs off exponentially instead of spinning. This is[damping](https://en.wikipedia.org/wiki/Damping) , the same reason a crash-looping container backs off instead of restarting hot.
|
||||
- It lets you run a pool of workers pulling keys in parallel, which is your fan-out. Events fan in from the watch, collapse in the queue, and fan out to the workers. This is something you need to tune. The higher you set the pool, the more pressure you put on the system: more writes, more API calls, more load on the provider, and more CPU usage in the operator.
|
||||
|
||||
Second, and this is a detail that bites people a lot: **your reads and your writes in Kubernetes don't go to the same place.**
|
||||
|
||||
In controller-runtime, the client you're handed reads from the informer's local cache. Cache reads are cheap, they don't touch the API server, and that's how a controller reconciles thousands of objects without falling over. But your writes go straight to the API server. The cache only learns about your write when the resulting watch event comes back around, a moment later.
|
||||
|
||||
Because of that, a read can be stale. You need to be prepared for this.
|
||||
|
||||
If you write a field of an object and then read the same object again from the cache, the reconciler might think it's not updated yet. You write again, and you get a Conflict error. Retrying with a fresh read can be fine, but blindly retrying against the same stale cached view just spins.
|
||||
|
||||
Most of the time, what you want is to drop the call and *requeue*. In the next reconcile, the `GET` will see the updated object, and your write will never happen. That's how everything self-converges.
|
||||
|
||||
Here is another edge case. Picture this sequence inside a reconcile:
|
||||
|
||||
```
|
||||
// I want N replicas. I see fewer, so I create the missing ones.
|
||||
existing, _ := r.listChildPods(ctx) // reads the CACHE
|
||||
for i := len(existing); i < desired; i++ {
|
||||
r.client.Create(ctx, newPod(i)) // writes the API SERVER
|
||||
}
|
||||
```
|
||||
Now an event fires again a second later, before the cache has caught up with the Pods you just created. You list from the cache, and the new Pods aren't there yet. Your code decides it still needs to create them, and you create duplicates. This is the classic stale-cache double-create, and it's nasty because it only shows up under timing you can't reproduce on your laptop.
|
||||
|
||||
There are two ways out. The correct one is the **expectations pattern**, the same trick the built-in ReplicaSet controller uses: you record that you expect to see N creations in memory, and you don't act again until the cache has caught up to your own writes. It works, but it's not easy to implement and it's a fair amount of machinery. Read more [on Ahmet's blog](https://ahmet.im/blog/controller-pitfalls/).
|
||||
|
||||
The pragmatic one, which a lot of people use, is to bypass the cache for the reads where a stale view would cause a double-create or double-delete, and go straight to the API server:
|
||||
|
||||
```
|
||||
// The cached client can be stale right after our own writes, which
|
||||
// would make us miscount and create duplicates. For this one read,
|
||||
// go direct to the API server instead of the cache. Slower,
|
||||
// but consistent for this decision.
|
||||
err := r.apiReader.List(ctx, &instances, client.InNamespace(ns), labelSelector)
|
||||
```
|
||||
This is not only a Kubernetes issue. In any system with a read cache and a write-through path, read-after-write is not consistent unless you make it so. Most of the time the cache is exactly what you want: cheap, local, and eventually consistent. Eventual consistency is fine because the loop runs again. But the moment a decision would be destructive or non-idempotent if you acted on a stale read, you need to know which path you're on. Kubernetes solves many hard problems, but it also gives you a few new ones.
|
||||
|
||||
### [Setpoint and measured variable: spec and status](https://planetscale.com#setpoint-and-measured-variable-spec-and-status)
|
||||
|
||||
Back to the control diagram. My script kept its setpoint in shell variables and its measured state in the output of `df` and `psql`. Kubernetes gives both a permanent home, on the object itself.
|
||||
|
||||
`.spec` is the **setpoint**, the desired state. It's owned by whoever created the object (a human, or another controller), and the reconciler treats it as read-only intent. It's an anti-pattern to write to the `.spec` from inside the controller. If you do it, stop reading, go and fix your codebase. There are only a handful of exceptions, but a controller should generally never set its own setpoint.
|
||||
|
||||
`.status` is the **measured variable**, the observed state. It's owned by the controller, written through a separate status subresource, and it's where you record what's actually true. The better the status, the better the controller can decide. A good `.status` field is what makes a controller pleasant to operate. The word *observability* comes from control theory; [Kalman coined it](https://en.wikipedia.org/wiki/Observability) around 1960 to ask whether you can infer a system's internal state from its outputs. `.status` is also your response to any third-party system. If someone wants to learn the outcome of your actions, `.status` is the place to look at.
|
||||
|
||||
That split is the whole declarative model in two fields. It comes with a piece of bookkeeping that's pure control theory: `.metadata.generation` increments when desired state changes, and by convention the controller writes back `.status.observedGeneration` to say "the state I'm reporting reflects this version of your intent."
|
||||
|
||||
When `observedGeneration < generation`, the status you're looking at does not reflect the latest setpoint yet. That one comparison is how you tell "converged" from "still working on it."
|
||||
|
||||
This is why the reconcile is **stateless**, and why that matters. Our shell script kept "am I mid-failover?" in a variable that died with the process. A Kubernetes controller keeps nothing important in memory. Every fact it needs is on an API object: the spec it's driving toward, the status it last observed, the conditions describing where things stand. Kill the controller, restart it on another node, and it picks up exactly where it left off, not because it saved its progress, but because there was never any in-memory progress to lose. The state lives in the cluster (API server, `etcd` is what holds the state). The controller is just the loop that reads it.
|
||||
|
||||
### [Self-healing by design](https://planetscale.com#self-healing-by-design)
|
||||
|
||||
This is the part I like most.
|
||||
|
||||
When a controller creates a child object (a Pod, a PVC), it stamps an **ownerReference** on the child pointing back at the parent. That reference does two things. It sets up garbage collection: delete the parent, and Kubernetes can cascade the delete to its children. And it gives the controller a way to map child changes back to the parent: "when any object I own changes, enqueue my parent for a reconcile." `ownerReference` allows you to link controllers to each other and create chains. If done right, all your controllers and systems fit together.
|
||||
|
||||
Here is an example. Follow the loop:
|
||||
|
||||
1. A node dies and takes a Pod with it.
|
||||
2. The Pod's deletion is a watch event, an edge.
|
||||
3. Through the ownership link, that edge becomes a reconcile request for the parent.
|
||||
4. The parent reconciles, observes its children (level-triggered), sees one is missing and the count is below the setpoint, and creates a replacement.
|
||||
5. The replacement is an unscheduled Pod, an edge for the scheduler.
|
||||
6. The scheduler detects the unscheduled Pod, assigns a node.
|
||||
7. The kubelet gets triggered because that's an edge for that node's kubelet and it starts the container.
|
||||
|
||||
That's multiple feedback loops, each watching the layer below, each reacting to an edge and converging to its own level, chained together through the API server with nobody orchestrating the whole thing.
|
||||
|
||||
Control theory has a name for loops stacked like this: [**cascade control**](https://en.wikipedia.org/wiki/Proportional%E2%80%93integral%E2%80%93derivative_controller#Cascade_control). The output of an outer loop becomes the setpoint of an inner loop. A controller never writes its own `.spec`, but it writes *other* objects' `.spec` all the time. My operator writes the PVC's spec, and that spec is the setpoint the CSI controllers converge to. Each loop worries only about its own layer and trusts the loop below.
|
||||
|
||||
So we wrote `if ! pg_isready; then docker start; fi` and maybe thought we're good. Kubernetes turns that one line into several independent controllers that have never heard of each other, but still cooperate because they share the API server and watch each other's objects. I like this part a lot. Nobody calls a central orchestrator. Nobody passes a private message. The system heals itself.
|
||||
|
||||
### [What "observe" actually means in a real operator](https://planetscale.com#what-observe-actually-means-in-a-real-operator)
|
||||
|
||||
Up to here I've been a little vague about the "measure" step, because in the examples the measured state is just "list the child Pods." But in a real database operator it's a lot more than that.
|
||||
|
||||
When an operator I work on reconciles a single Postgres instance, the first thing it does, before it decides anything, is build a snapshot of reality from every source that knows something true about that instance. Not just Kubernetes. Kubernetes barely knows anything about whether Postgres is actually healthy.
|
||||
|
||||
The sources gathered at the top of every reconcile:
|
||||
|
||||
- **The Kubernetes cache** : the Pod, its PVC, the PV behind it, the Node it's on, the ConfigMap holding its config. These are the cheap local reads, the stuff we already talked about.
|
||||
- **The database's effective configuration.** Not what we last wrote down, but what the server has actually loaded, so we can compare the two and detect drift. Other entities can rewrite or reload the config on disk without us knowing, so the only honest source of truth is the running server itself, never our last write.
|
||||
- **The database's own view of its health.** Its role, whether it's healthy, how far behind its followers are, whether it's currently accepting writes. Some of this comes from the agents that sit next to the database and manage it; some we get by opening a connection and asking the database directly. These calls carry a tight timeout and are allowed to fail, more on that below.
|
||||
- **A background collector.** Some signals are too expensive or too rate-limited to fetch on every reconcile: disk usage, or whether a volume operation we kicked off earlier is still in flight and where it sits in its cooldown window. A separate collector, often a background goroutine, gathers these on a slow cadence and keeps the last value per volume in memory. The reconcile reads that value instantly, without blocking on anything. Think of these as custom workqueues you implement.
|
||||
|
||||
In code, the snapshot is just a struct, and the reconcile's first move is to populate it. This is simplified, but faithful to the real shape:
|
||||
|
||||
```
|
||||
// The observation snapshot: everything we know about this instance, right now.
|
||||
type reconcileHandler struct {
|
||||
// The object (.spec = setpoint, .status = measured).
|
||||
instance *v1.PostgresInstance
|
||||
// Kubernetes objects.
|
||||
pod *corev1.Pod
|
||||
pvc *corev1.PersistentVolumeClaim
|
||||
node *corev1.Node
|
||||
// Database state.
|
||||
dbState DatabaseState
|
||||
// What Postgres actually loaded, not what we last wrote.
|
||||
effectiveConfig map[string]string
|
||||
// Collected out-of-band.
|
||||
diskUsage *resource.Quantity
|
||||
// The volume operation already in flight, if any.
|
||||
storageOp *StorageOperation
|
||||
}
|
||||
func (r *Reconciler) newReconcileHandler(
|
||||
ctx context.Context,
|
||||
inst *v1.PostgresInstance,
|
||||
) (*reconcileHandler, error) {
|
||||
h := &reconcileHandler{instance: inst}
|
||||
// Cheap local reads.
|
||||
h.pod, h.pvc, h.node = r.fetchKubeObjects(ctx, inst)
|
||||
// Active database calls.
|
||||
h.dbState = r.queryDatabase(ctx, h.pod)
|
||||
h.effectiveConfig = r.readEffectiveConfig(ctx, h.pod)
|
||||
// Values from the collector/metric.
|
||||
h.diskUsage = r.collector.Usage(h.pvc)
|
||||
h.storageOp = r.collector.InFlightOp(h.pvc)
|
||||
return h, nil
|
||||
}
|
||||
```
|
||||
A few things about this are deliberate, and only look obvious after you've been burned once or twice.
|
||||
|
||||
**Gather once, at the top.** Every sub-decision in the reconcile reads from this one snapshot. We don't re-query the database in the middle of the loop, or read the disk usage again three functions deep. If we did, different parts of the same reconcile could see different versions of reality. This sounds like a small detail, but it changes the whole design.
|
||||
|
||||
For example, the database might be the leader when we check at the top and a replica by the time another helper checks again. Then you get decisions that are individually reasonable, but wrong together. We have a rule in the codebase against stashing state back onto this handler mid-reconcile to pass between steps, because it reintroduces exactly the inconsistency we gathered the snapshot to avoid. Making the `reconcileHandler` immutable is one way to enforce that rule in the type system instead of relying on code review.
|
||||
|
||||
**Partial failures are tolerated.** Reaching the database can fail while the Kubernetes reads succeed. That's not always an error that aborts the reconcile. It's a measured fact: "Postgres is currently unreachable." That itself is something to record in status. A control loop that gives up entirely whenever one sensor is unavailable is a control loop that's down a lot. We degrade instead. Think of a car. If the rain sensor for the wipers is broken, the whole car doesn't stop. You can still drive, but you need to turn on a few things yourself.
|
||||
|
||||
Once the data snapshot exists, the reconcile is a sequence of small, idempotent steps, each comparing one slice of desired against observed and acting to close the gap:
|
||||
|
||||
```
|
||||
func (r *reconcileHandler) reconcile(ctx context.Context) (reconcile.Result, error) {
|
||||
var rb results.Builder
|
||||
rb.Merge(r.reconcileConfigMap(ctx)) // push desired config
|
||||
rb.Merge(r.reconcileDatabase(ctx)) // reload/restart if params drifted
|
||||
rb.Merge(r.reconcilePVC(ctx)) // grow the disk if needed
|
||||
rb.Merge(r.reconcilePod(ctx)) // create/replace the Pod
|
||||
rb.Merge(r.reconcileStatus(ctx)) // always last: write what we observed
|
||||
return rb.Result()
|
||||
}
|
||||
```
|
||||
Status is written last on purpose, because it's the measured variable: you record what's true after you've taken your actions and observed the result. Again, in our operators, it's not possible to write the status mid-reconcile.
|
||||
|
||||
Each step is independently idempotent. Each returns a result, either "I'm done" or "requeue me in 30 seconds, I'm waiting on something," and the results merge. It reads almost exactly like the body of my shell loop. The difference is that "observe the state" grew from `df` and `pg_isready` into a fan-in across multiple systems, and "take an action" grew from `ssh` into typed, conflict-aware API writes.
|
||||
|
||||
This is the operator. The kubelet, the scheduler, CSI, and CNI are infrastructure we get by using Kubernetes. This loop, with its messy real-world observe step, is the part we actually write and deal with. Because we know how the underlying system works, we can design it without treating Kubernetes like a black box.
|
||||
|
||||
### [Not every edge comes from the API server](https://planetscale.com#not-every-edge-comes-from-the-api-server)
|
||||
|
||||
There's one more piece, and it lets me close a loop from Part 1 that I left deliberately: the disk-usage check.
|
||||
|
||||
My shell script polled `df` on every node every five seconds. For three nodes, fine. For thousands of databases, you can't reconcile every one of them every few seconds just to check a number that rarely changes; you'd spend all your CPU re-deriving "still at 40%, still at 40%, still at 40%." This is the level-triggered model's one real cost: re-checking everything is correct, but it isn't free.
|
||||
|
||||
The fix is to add a sensor that emits its own edges. A background collector polls our metrics pipeline for disk usage on a slow cadence, keeps the last value per volume in memory, and only emits an event when usage crosses a threshold, not while it sits above or below one:
|
||||
|
||||
```
|
||||
// Edge detection. We fire only on the transition across the threshold,
|
||||
// not every cycle we happen to be above it. Hovering at 81% is silent;
|
||||
// crossing 80% upward is an event.
|
||||
crossedUp := previousUsage < pvc.GrowThreshold && usage >= pvc.GrowThreshold
|
||||
if crossedUp {
|
||||
// -> generic event -> work queue -> reconcile
|
||||
relay.Send(Event{Key: pvc.Key})
|
||||
}
|
||||
```
|
||||
That event goes into the same work queue as the API watch events and triggers a normal reconcile of the affected instance. Same rule as before: the event wakes us up, the reconcile decides from the current state.
|
||||
|
||||
For example, say we have a 10GiB disk and it's using 8GiB. The collector saw it cross the threshold, so it wakes the reconciler. The reconciler reads the current usage, sees that it crossed the 80% threshold, and sets a new size on the PVC. After that, CSI handles the rest.
|
||||
|
||||
And because edges can be missed (the collector could be down, an event could be dropped from a full channel), there's a **resyncer**: a periodic timer that enqueues every object for reconcile every minute or so, regardless of events. It's the safety net. It's our `sleep 5` loop. There's also `RequeueAfter`, which a reconcile returns to say "wake me again in 30 seconds," the controller's way of polling a slow external operation without holding a worker.
|
||||
|
||||
There are two more questions: **how often should the loop run, and who is allowed to run it?** Control theory calls the first one the *sampling interval*. The rule of thumb: act faster than the thing you're tracking changes, but not faster than it can respond. Reconciling a disk that fills over hours every few milliseconds just burns CPU to learn the same thing again.
|
||||
|
||||
So the operator puts boundaries around it.
|
||||
|
||||
- A **coalescing delay** handles noisy edge events: a burst of events for one object becomes one reconcile (think of it like a fan-in), not a thousand.
|
||||
- The **resyncer** is the safety net: every object gets looked at once in a while, even when nothing fires.
|
||||
- And **leader election** answers the*who* : only one copy of the operator runs the loop at a time. Two controllers writing to the same database object is not "more reliable." Even with idempotent controllers, they'll be requeueing due to conflicts and consuming unnecessary compute. In theory, a perfectly written controller should tolerate this. In practice, software is rarely perfect, and the safer boundary is worth it.
|
||||
|
||||
To close out Part 2, let me redraw the control loop again. The diagram in Part 1 had a few basic boxes. Now, the same loop represents a closed feedback loop more realistically:
|
||||
|
||||
There is one new arrow in this diagram: **disturbances**. A controller has two jobs. The first is [setpoint tracking](https://en.wikipedia.org/wiki/Setpoint_%28control_system%29): someone edits the `.spec`, and the loop chases the new intent. The second is [disturbance rejection](https://en.wikipedia.org/wiki/Control_theory): the world changes on its own. A node dies, a customer starts a bulk import, someone deletes a Pod by hand. The level-triggered reconcile treats both the same way: it only sees the gap.
|
||||
|
||||
Our controller doesn't always touch Postgres directly. Sometimes it writes a PVC and lets CSI do the storage work. Sometimes it creates a Pod and lets the scheduler and kubelet do their part. This is what a production operator looks like: one loop we write, surrounded by other loops we don't write.
|
||||
|
||||
Notice that every decision in this loop has been binary: start the Pod or don't, grow the disk or don't, rewrite the config or don't. That's an *on/off controller*, and it covers most of what an operator does. But not every question is yes/no; once the answer becomes *how much* rather than *whether*, you need a controller with memory and a sense of trend: how long you've been off, and how fast it's changing. That's a separate post.
|
||||
|
||||
## [Conclusion](https://planetscale.com#conclusion)
|
||||
|
||||
All of this works, and most of the time it runs without anyone watching it. But the abstractions still leak, and they usually leak at a bad time.
|
||||
|
||||
Eventual consistency and the split between cache reads and API writes mean that a freshly-created object might not be visible to the thing that just created it. When something goes wrong, we're debugging Kubernetes objects, database state, metrics, volume operations, and sometimes the cloud provider at the same time. The bug is usually not in one clean place.
|
||||
|
||||
The declarative model is wonderful until it meets an operation that's inherently imperative and stateful, like a failover, a major-version upgrade, or a data migration. Then you have to turn a blocking, non-idempotent action into an idempotent one. That's a whole other blog post.
|
||||
|
||||
That complexity is easy to underestimate. If you're not dealing with sophisticated systems, if you can sacrifice availability, or if you don't care about scalability, maybe all this machinery isn't needed at all. Operators do not remove complexity. They move it into code someone has to understand.
|
||||
|
||||
I still think it's worth it. For running thousands of databases that have to heal themselves without anyone watching, I don't know a better alternative. The hard parts are hard because the problem is hard, not because Kubernetes made it hard.
|
||||
|
||||
Kubernetes is not only a container runtime. It's not only a YAML processor, or an orchestrator, or whatever word we use that year. For me, the useful way to read Kubernetes is this: **Kubernetes is a framework for feedback controllers**, plus a consistent store to hold their setpoints and a shared event bus to wake them up.
|
||||
|
||||
Once you see that, the rest fits together. The kubelet, the scheduler, CSI, and your operator all read and write facts onto shared objects, and each one tries to move its own small part of the system toward the desired state. The core idea is still the same one we started with: write down what you want, look at what exists, make the next change, and repeat. Events wake the loop up, but the current state decides what happens.
|
||||
|
||||
Kubernetes didn't invent these ideas; a thermostat had them long before us. The mapping to control theory is not perfect, and some boundaries are fuzzy. But the core idea holds. We are writing feedback loops in Go and applying them to databases. Mechanical and electrical engineers figured out how to build stable, long-running systems before us. Software engineering is still catching up, and Kubernetes gives us a practical way to use those ideas in production.
|
||||
17
sreweekly/markdown/522/07-dear-researchers-column.md
Normal file
17
sreweekly/markdown/522/07-dear-researchers-column.md
Normal file
@@ -0,0 +1,17 @@
|
||||
# Dear researchers column
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Lorin Hochstein
|
||||
- **链接**: https://surfingcomplexity.blog/2026/06/16/dear-researchers-column/
|
||||
|
||||
## 简介
|
||||
|
||||
An open letter to software researchers to study incident response in software systems. It’s so cool how the author translates incident response concepts to researchers who may not be familiar, with examples.
|
||||
|
||||
## 正文
|
||||
|
||||
The Journal of System and Software publishes a regular column called [Dear Researchers: The perspective of software practitioners](https://www.sciencedirect.com/special-issue/10DML17WPDQ). Each column is an open letter to the software engineering research community from someone who works in tech. It’s edited by [Austin Henley](https://austinhenley.com/) and [Olaf Zimmermann](https://ozimmer.ch/about/), both of whom have experience in the two worlds of academia and industry.
|
||||
|
||||
They invited me to submit a column, which I did. When it finally gets published, you’ll be able to find it here: [Dear researchers: help me deal with incidents!](https://authors.elsevier.com/a/1nKhhbKHpO3wc) The published version will eventually go behind the journal’s paywall, but [here’s a preprint of the column](https://surfingcomplexity.blog/wp-content/uploads/2026/06/dear-researchers.pdf) that you can always read free of charge.
|
||||
|
||||
## One thought on “Dear researchers column”
|
||||
80
sreweekly/markdown/522/08-meet-alice-alice-is-impatient.md
Normal file
80
sreweekly/markdown/522/08-meet-alice-alice-is-impatient.md
Normal file
@@ -0,0 +1,80 @@
|
||||
# Meet Alice. Alice is impatient.
|
||||
|
||||
- **期号**: SRE Weekly Issue #522(2026-06-21)
|
||||
- **作者**: Marc Brooker
|
||||
- **链接**: http://brooker.co.za/blog/2026/06/19/waiting.html
|
||||
|
||||
## 简介
|
||||
|
||||
An important concept: a user’s perception of your average outage duration is weighted and won’t match a flat average MTTR.
|
||||
|
||||
## 正文
|
||||
|
||||
I am an engineer at Amazon Web Services (AWS) in Seattle, where I work on agentic AI, especially safety and policy for agentic AI. Before that, I worked on EC2, EBS, databases, serverless, and serverless databases.
|
||||
|
||||
All opinions are my own.
|
||||
|
||||
Meet Alice. Alice uses your web service. Alice, like most humans, measures her time in seconds and minutes. Alice says your service is slow. You tell Alice that the mean request to your service completes in 100ms, but Alice says that her mean wait time is 1s.
|
||||
|
||||
You’re both right.
|
||||
|
||||
Meet Alex. Alex uses your web service. Alex, like most humans, measures his time in seconds and minutes. Alex says that when you have outages, they last a long time and he gets really annoyed. You tell Alex that your MTTR is less than 1 minute. Alex says that he sees the mean outage lasting 1 hour.
|
||||
|
||||
Again, you’re both right.
|
||||
|
||||
What’s going on? What’s going on is that you’re measuring time in requests, or in outages, and Alex and Alice are measuring time in seconds and minutes. When you have a long pause or a long outage, Alex and Alice *sample* that outage multiple times (maybe because they have multiple customers angry at them). The number of times they experience the outage is proportional to the length of the outage. But you only count that as one.
|
||||
|
||||
More technically, what’s going on here is the *inspection paradox*. Alex and Alice don’t experience your latency distribution $f(t)$, they experience a t-weighted version of it. If you have a MTTR or mean request time of $\mathbb{E}[X]$, Alex and Alice experience a mean recovery time $\mathbb{E}_a[X]$ where $\mathbb{E}_a[X] = \frac{\mathbb{E}[X^2]}{2 \mathbb{E}[X]} = \frac{1}{2} \left( \mathbb{E}[X] + \frac{\mathrm{Var}(X)}{\mathbb{E}[X]} \right)$.
|
||||
|
||||
Let’s play with this with a little simulation. Plug in your median latency (or recovery time), and 99th percentile latency (or recovery time), we’ll fit a log-normal distribution to it, and then plot both what your service metrics see and what your customers see.
|
||||
|
||||
Median: ms p99: ms
|
||||
|
||||
What your service sees (mean): **– ms**.
|
||||
What your customers experience (mean): **– ms**.
|
||||
|
||||
For example, put in 30 as the median (let’s ignore the milliseconds and pretend these are minutes for now) for a 30 minute Median TTR (i.e. in half of your postmortems you see a recovery time of $\leq 30$ minutes), and 600 in as the p99 (one in every 100 events, recovery takes 10 hours). Your MTTR is just over an hour. Your customers experience a mean time to recovery of around 6 hours!
|
||||
|
||||
*Reasoning About Code, Instead*
|
||||
|
||||
The above argument may be a bit abstract for you, so let’s use another small simulator, presented as code this time, to communicate the core of the idea. Here, we have a server that experiences some periodic down-time (we haven’t simulated the times when it’s up, because they don’t interest us for now), and a Poisson process of arriving clients. We directly measure what the operator would measure as system downtime (e.g. `mttr`), and what the clients see.
|
||||
|
||||
As you read this code, notice how each outage is sampled multiple times by the client, and how their samples are weighted by the remaining outage time (this is the *t-weighting* I talk about above).
|
||||
|
||||
```
|
||||
import random
|
||||
failure_mu = 1.0
|
||||
failure_sigma = 3.0
|
||||
client_arrival_rate = 100.0
|
||||
samples = 1000
|
||||
client_saw_times = []
|
||||
server_saw_times = []
|
||||
for i in range(samples):
|
||||
this_outage = random.lognormvariate(failure_mu, failure_sigma)
|
||||
server_saw_times.append(this_outage)
|
||||
t = 0.0
|
||||
while True:
|
||||
next_arrival = random.expovariate(client_arrival_rate)
|
||||
if t + next_arrival > this_outage:
|
||||
break
|
||||
client_saw_times.append(this_outage - t)
|
||||
t += next_arrival
|
||||
...
|
||||
print(f"""Client saw:
|
||||
mean {mean(client_saw_times)}
|
||||
median {pctile(client_saw_times, 0.5)}
|
||||
p99 {pctile(client_saw_times, 0.99)}""")
|
||||
print(f"""Model predicted:
|
||||
mean {mean(square(server_saw_times))/(2.0*mean(server_saw_times))}""")
|
||||
print(f"""Server saw:
|
||||
mttr {mean(server_saw_times)}
|
||||
median {pctile(server_saw_times, 0.5)}
|
||||
p99 {pctile(server_saw_times, 0.99)}""")
|
||||
```
|
||||
*Caring about tail latency (and long recovery times)*
|
||||
|
||||
There are many arguments for why tail latency (and long recovery times) are so important to understand (e.g. [multiple samples](https://brooker.co.za/blog/2021/04/19/latency.html)), but this is the one that I think is the least widely understood. For service times, timeout-and-retry can hide this latency some of the time (as long as the running request doesn’t hold locks or other exclusive resources). But, for recovery time, no such hiding is possible. The heaviness if the tail matters a great deal. This is also one of the reasons I don’t like trimmed measurements (like trimmed means) as a way of thinking about service latency or recovery time. They throw out some really critical context about the shape of the right tail that dominates the customer experience (the other reason is related to Little’s Law and capacity usage, [which I’ve written about before](https://brooker.co.za/blog/2017/12/28/mean.html)).
|
||||
|
||||
In slightly more mathematical terms, the difference between MTTR ($\mathbb{E}[X]$) and what clients experience ($\mathbb{E}_a[X]$) is proportional to $\frac{Var(X)}{\mathbb{E}[X]}$. It’s not unusual, in real systems, for $Var(X)$ to be very large compared to $\mathbb{E}[X]$. These distributions tend to be very heavy-tailed, partially because the solutions to simple cases (like single host or even datacenter failures) are well-known and robust, while solutions to longer outages remain elusive industry-wide.
|
||||
|
||||
*A note on log-normal:* I chose log-normal here for numerical convenience. It has the nice property that $\mathrm{lognormal}(\mu, \sigma^2)$ becomes $\mathrm{lognormal}(\mu + \sigma^2, \sigma^2)$. Also it’s well-behaved around 0. I don’t believe that log-normal is a particularly good choice of distribution for latency or recovery time metrics, and generally would approach these problems entirely non-parametrically.
|
||||
Reference in New Issue
Block a user