SRE weekly 所有文章
This commit is contained in:

82
sreweekly/markdown/524/01-self-blame-isn-t-blameless.md
Normal file
82
sreweekly/markdown/524/01-self-blame-isn-t-blameless.md
Normal file
@@ -0,0 +1,82 @@
|
||||
# Self-blame isn’t blameless
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Brent Chapman
|
||||
- **链接**: https://greatcircle.com/blog/2026/04/21/self-blame-isnt-blameless/
|
||||
|
||||
## 简介
|
||||
|
||||
> Blame shuts down learning. That’s true whether the blame comes from a manager, from a peer, or from self-blame.
|
||||
|
||||
## 正文
|
||||
|
||||
Most of what’s been written about blameless post-incident reviews is about managers not blaming engineers, and engineers not blaming each other, because blame shuts down learning. What many miss is that engineers still blame themselves, and the damage is the same.
|
||||
|
||||
The most valuable output of a post-incident review isn’t the document, and it isn’t the list of action items. It’s learning: individual learning for the people involved, and organizational learning that outlasts anyone’s tenure. Everything else in the review process serves that goal.
|
||||
|
||||
# The scene
|
||||
|
||||
Somewhere in the middle of a post-incident review, one of the engineers involved in the incident speaks up:
|
||||
|
||||
“Yeah, I should have caught that. My bad. I’ll be more careful next time.”
|
||||
|
||||
|
||||
On the surface, this feels like maturity. The engineer isn’t defensive; they’re owning what happened. The team nods, accepts the explanation, and the review moves on.
|
||||
|
||||
What actually just happened is that the exploration stopped. “Sam made a mistake” became the story, and all the systemic factors that contributed to the incident went unexamined. The dashboard that was slow to load. The deployment pipeline that didn’t have a canary phase. The runbook that was last updated eighteen months ago. The schedule pressure that made skipping the check seem reasonable in the moment. None of that got talked about, because “I’ll be more careful next time” was accepted as the explanation, when it doesn’t really *explain* anything.
|
||||
|
||||
# Self-blame is still blame
|
||||
|
||||
Blame shuts down learning. That’s true whether the blame comes from a manager, from a peer, or from self-blame. A satisfying-sounding explanation arrives early in the conversation, everyone accepts it, and the exploration that would have surfaced the actual contributing factors never happens. The document captures a neat narrative. The action items address the narrow issue. The next incident reveals that the narrow issue was a symptom of something deeper that nobody investigated.
|
||||
|
||||
“I should have caught that” is a thought-terminating cliché that sounds like insight, but isn’t. It works just as well whether someone else says it or the person says it about themselves.
|
||||
|
||||
# The heroism problem after the incident
|
||||
|
||||
If your company has spent any time thinking about incident response, you’ve probably internalized a version of this principle: individual heroics are a problem during incidents. The lone-wolf engineer who goes heads-down and fixes the outage by personal brilliance and sheer force of will is not the model you want. The incident runs longer than it needed to, nobody else learns anything, and the company ends up dependent on a handful of heroes who burn out or leave. Organizational capability beats individual heroics.
|
||||
|
||||
Self-blame is the same pattern, just moved later in time.
|
||||
|
||||
The engineer who says “my bad, I’ll be more careful next time” is volunteering to carry the weight of the incident themselves. They’re taking the hit so the team can move on. It feels selfless, even noble. It also deprives the team of the conversation it actually needs to have about the contributing factors behind the incident. The hero absorbs the cost, and the company never learns what it needed to learn.
|
||||
|
||||
The response to heroism during incidents is to build structures that don’t require it: defined roles, clear handoffs, explicit delegation, training that spreads capability across the team. The response to heroism after incidents should be the same: don’t let one person carry (and bury) what needs to be shared.
|
||||
|
||||
# What to do when you see it
|
||||
|
||||
Self-blame shows up in a handful of recognizable forms. “My bad, I’ll be more careful.” “I should have known better.” “I take full responsibility for this.” “That was on me.” Whichever variant surfaces, the review needs someone else to gently redirect. Not to argue with the person, and not to wave them off. The work is to pull the conversation from the person’s character back to the situation they were in.
|
||||
|
||||
A question that works: “OK, but let’s understand the circumstances. What were you seeing at the time? What information did you have? What made the action seem like the right thing to do?”
|
||||
|
||||
This question does several things at once. It signals that the team isn’t satisfied with the self-blame as the explanation. It treats the engineer’s actions as reasonable given what they knew, which is almost always the case. And it opens up the conversation about the circumstances the engineer was working in: the missing information, the ambiguous signals, the process that everyone knew was broken but nobody had fixed. That’s where the contributing factors live. That’s where the learning lives.
|
||||
|
||||
Facilitators of post-incident reviews should anticipate self-blame, and be prepared to address it.
|
||||
|
||||
# The person in the middle
|
||||
|
||||
There’s another aspect of this that seldom gets the attention it deserves: the toll on the person absorbing the blame.
|
||||
|
||||
The engineer most involved in the incident often arrives at the review already carrying guilt and anxiety; the “my bad” moment is frequently the release of pressure they’ve been carrying for days. Treating it with care, neither accepting the self-blame as the answer nor challenging the person, is part of the job.
|
||||
|
||||
The burden doesn’t ease when the review ends. The engineer absorbing the blame carries it for a long time afterward. In healthcare, this is called “second-victim syndrome”: dealing with a patient’s trauma sometimes causes adverse emotional effects for the healthcare provider, as well, making them the “second victim.”
|
||||
|
||||
The stakes in software are different, but the experience isn’t as different as it might sound. Engineers lose sleep over incidents. They dread going to work. Some of them leave their jobs. “I should have caught that” sounds like a quick self-assessment; in practice, it’s often a thought the person has been rehearsing for days before the meeting.
|
||||
|
||||
A well-run review that explores the systemic factors behind the incident is one of the most effective interventions for this. It reframes the experience for the person involved. They’re no longer “the person who caused the outage.” They’re a participant in a systemic event the company is working to understand and prevent. That reframing matters enormously, and it can’t happen if the review stops at accepting the self-blame as the answer.
|
||||
|
||||
# Variations to watch for
|
||||
|
||||
Individual self-blame has relatives worth watching for. Group self-blame sounds like “we should have caught that”; it diffuses the ownership across the team but stops the conversation the same way. Passive voice (“the change was deployed without adequate testing”) strips the actor from the sentence without removing the judgment. “Human error” without naming the human is blame at one remove, assigned to a generic stand-in. All of these give the review a stopping point that feels satisfying but isn’t actually useful. The redirect is the same in each case: pull the conversation from implicit character judgments back to the situation people were in.
|
||||
|
||||
# The principle
|
||||
|
||||
The next stage of blameless maturity isn’t arriving at a review where nobody points fingers. It’s arriving at a review where the conversation keeps going past “my bad, I’ll be more careful next time” and into the system that made the moment possible.
|
||||
|
||||
Fred Hebert has written about a related anti-pattern he calls “[superficial blamelessness](https://resilienceinsoftware.org/news/11502437)“: reviews that successfully avoid retribution but still land on individualistic fixes (more training, pay more attention, add supervision) rather than changes to the system. Self-blame is a particularly sneaky version of that pattern. The engineer volunteers the individualistic remediation on themselves, which makes it feel like accountability instead of the shallow fix it is.
|
||||
|
||||
Accountability means understanding how your company and its systems actually operate, and making durable changes based on that understanding. One person promising to try harder doesn’t get you there.
|
||||
|
||||
*I’m writing a book, **Incident Management for DevOps and SRE**, aimed at helping companies build incident management capability that doesn’t depend on heroics. Sign up for updates at [im4ds.com](https://im4ds.com).*
|
||||
|
||||
*If your company needs help with incident management right now, my consulting practice is at [greatcircle.com/im](https://greatcircle.com/im).*
|
||||
|
||||
## Recent Comments
|
||||
@@ -0,0 +1,85 @@
|
||||
# Jet Engine on a Tractor: AI’s Big Productivity Trap
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Hamed Silatani — Uptime Labs
|
||||
- **链接**: https://www.uptimelabs.io/articles/jet-engine-on-a-tractor-ais-big-productivity-trap
|
||||
|
||||
## 简介
|
||||
|
||||
This article argues that when we use AI to move faster, we’re limited by the “weak link” in our sociotechnical system: humans.
|
||||
|
||||
## 正文
|
||||
|
||||

|
||||
|
||||
### Ready to make incident response your competitive advantage?
|
||||
|
||||
See how Uptime Labs builds provable, scalable incident response capability across your organisation.
|
||||
|
||||
Organisations are complex socio-technical systems. Two words in that phrase carry fundamental implications for AI adoption strategy: *socio-technical* and *system*.
|
||||
|
||||
The former means people are part of the system. The latter means a functioning whole: a set of parts that only produces its result together, not individually. You can have the best individual components and still end up with a dysfunctional system.
|
||||
|
||||
I'm an early adopter by nature. As an engineer, I love using new ideas to do more good, faster. But this time around, something feels off. I'm getting a lot more *done*, yet I can't see proportional productivity in terms of economic value. I'm more stressed, I work longer hours, I pay more (AI tokens) and yet the output doesn't reflect any of it.
|
||||
|
||||
Then, in what felt like a coincidence, two separate talks gave me an explanation.
|
||||
|
||||
The first was by [Adam Bender](https://youtu.be/2n41YjR5QfU?si=-o9BGS8axADNuFrn), who applies a systems thinking lens to AI adoption in software engineering. The second was by [Daron Acemoglu](https://youtu.be/xBpGn3BDcOY?si=7qQi_Kzr5qjPNc2O), an economist who uses Weak Link Theory to explain the economic impact of technological revolutions. After watching both, I realised they were saying the same thing: **your productivity is limited by the weakest link in the system.**
|
||||
|
||||
Building and operating software is a function of a socio-technical system, which is itself a subsystem of a bigger whole called an *organisation*. If you map out how software is actually created and operated in your organisation, my bet is you'll end up with a complex, interconnected system that no single person fully understands. And yet, somehow, it works. Here's my own list at Uptime Labs:
|
||||
|
||||
1. Mission of Uptime Labs: Why we do what we do
|
||||
2. Engineering principles: influencing product, architectural, and technical choices
|
||||
3. Understanding of all the technical decisions made so far
|
||||
4. Product requirements and user research
|
||||
5. Repository structure
|
||||
6. Quality gates
|
||||
7. Workflows
|
||||
8. Development environment and testing strategy
|
||||
9. Continuous deployment, post-deployment tests and rollback mechanisms
|
||||
10. Writing code and code reviews
|
||||
11. Communicating changes to customers
|
||||
12. Observability
|
||||
13. Incident response process and tooling
|
||||
|
||||
That list is already intimidating, and we're a startup. I can't even list everything, let alone map all the relationships between the parts.
|
||||
|
||||
Unless we can claim that AI eliminates the need for human input in every single one of those components, we will always end up with a socio-technical system that involves humans. Now assume AI can automate and scale all the non-human parts. Humans immediately become the weak link. At least three things are likely to happen:****
|
||||
|
||||
**1.People will feel unprecedented pressure**
|
||||
|
||||
The system accelerates around them to the point of breaking i.e. a jet engine bolted onto a tractor. You can ignite it, but the tractor wasn't built for that.
|
||||
|
||||
**2. The value of the weak link rises dramatically**
|
||||
|
||||
Engineers who address the bottleneck unlock value across the whole system. Contrary to much of the public discourse, those skills become *more* valuable, not less.
|
||||
|
||||
**3. A lot of money gets wasted**
|
||||
|
||||
We pay to generate 10x more code because we can. But if the system's output doesn't increase and may actually decrease due to pressure on the weak link. Ie. we've invested heavily in one part while starving the rest.
|
||||
|
||||
|
||||
**A few examples related to other parts of the system:**
|
||||
|
||||
Take the principle of releasing small pieces of code, noticing a problem and rolling back quickly. What happens when you're releasing far more code, far faster, without time to observe the impact in production? Some problems take hours to surface.
|
||||
|
||||
Or consider code reviews; the cognitive load scales with the volume of code.
|
||||
|
||||
Or shared system understanding, which is critical to effective incident response. If nobody fully understands what was just deployed, how does the team reason their way through an outage?
|
||||
|
||||
This is where the left-over principle becomes important. These are the skills that remain uniquely human once AI handles everything else: sense-making, coordination, communication under pressure. When an incident hits, what determines whether it takes 20 minutes or 4 hours to resolve isn't usually the tooling. It's whether the people involved can orient quickly, communicate clearly, and make decisions in uncertainty. *Those skills aren't a nice-to-have*. As AI raises the ceiling on everything else, they become the rate-limiting factor.
|
||||
|
||||
|
||||
My point isn't to slow down AI adoption. It's to think about the whole system and not waste money investing heavily in one part while the real bottleneck goes unaddressed. The examples I mentioned here all could be opportunities for innovation. Daron Acemoglu argues that at best, we're decades away from scaling all parts of the software engineering system. And even if technology is ready tomorrow, change takes time to propagate through a global ecosystem.
|
||||
|
||||
At Uptime Labs, we think carefully about what AI adoption means for operations and incident response: not just the technology itself, but the evolving relationship between humans, AI agents, software, and customers. Which skills become *more* critical as AI handles more of the rest? Operations and incident response are just one part of the picture, but they're a revealing one.
|
||||
|
||||
If you've made it this far, you deserve the biggest prize of this post: 4 golden minutes from Dr Russell Ackoff:
|
||||
|
||||
”The system is a product of the **interaction** of its parts”
|
||||
|
||||
I’d genuinely love to know what you think.
|
||||
|
||||
This is a critical moment for software engineering and IT operations. As practitioners, we have both the motivation and the duty to figure this out. Because it's quite literally affecting our lives.
|
||||
|
||||
|
||||
@@ -0,0 +1,83 @@
|
||||
# Leveraging Cognitive Diversity to Tackle System Complexity
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Nick Travaglini — Honeycomb
|
||||
- **链接**: https://www.honeycomb.io/blog/leveraging-cognitive-diversity-tackle-system-complexity
|
||||
|
||||
## 简介
|
||||
|
||||
Two cool ideas in this one that stood out to me: identity diversity versus cognitive diversity and the practice of having everyone write up what they think happened in an incident before the retrospective meeting.
|
||||
|
||||
## 正文
|
||||
|
||||
# Leveraging Cognitive Diversity to Tackle System Complexity
|
||||
|
||||
When we compose teams or staff an incident review, we almost always use identity as a proxy for perspective. We include someone from platform, someone from the application layer, someone from the team that owns the affected service. We assume that different roles and tenures will produce different mental models of the problem, and sometimes that assumption holds. But research on how people actually build mental models of complex systems suggests it fails more often than we'd expect.
|
||||
|
||||

|
||||
|
||||
By: [Nick Travaglini](https://www.honeycomb.io/author/nickt)
|
||||
|
||||

|
||||
|
||||
#### How to Resolve the Productivity Paradox in AI-Assisted Coding
|
||||
|
||||
Join Ben Good (Google) and Austin Parker (Honeycomb) as they unpack the productivity paradox in AI-assisted Coding.
|
||||
|
||||
[Watch Now](https://www.honeycomb.io/resources/webinars/resolve-productivity-paradox-ai-assisted-coding)
|
||||
|
||||
|
||||
|
||||
Most engineering leaders today understand that diversity matters. They've built teams that reflect a range of backgrounds, functions, and experience levels. They run postmortems, retrospectives, and architecture reviews that bring multiple voices to the table.
|
||||
|
||||
They believe, not unreasonably, that this variety of perspectives leads to better decisions. But there's a problem hiding inside that assumption that can undermine everything: who people are is a surprisingly poor predictor of how they think.
|
||||
|
||||
## Identity diversity isn't cognitive diversity
|
||||
|
||||
When we compose teams or staff an incident review, we almost always use identity as a proxy for perspective. We include someone from platform, someone from the application layer, someone from the team that owns the affected service. We assume that different roles and tenures will produce different mental models of the problem, and sometimes that assumption holds. But [research on how people actually build mental models of complex systems](https://journals.sagepub.com/doi/full/10.1177/26339137231203582) suggests it fails more often than we'd expect.
|
||||
|
||||
Two engineers with the same title can think about a production failure in fundamentally different ways, with different theories of what drove the failure, and different beliefs and intuitions about which signals matter. Meanwhile, two people with very different roles can turn out to be working from nearly identical mental maps, shaped by the same incidents, on-call rotations, and organizational knowledge about how the system behaves.
|
||||
|
||||
This distinction has a name: cognitive diversity. And it turns out to matter *far more* than identity diversity when your goal is to understand and navigate a [complex system](https://journals.sagepub.com/doi/full/10.1177/26339137231203582).
|
||||
|
||||
#### New to Honeycomb? Get your free account today.
|
||||
|
||||
Get access to distributed tracing, BubbleUp, triggers, and more.
|
||||
|
||||
Up to 20 million events per month included.
|
||||
|
||||
## Why cognitive diversity matters more for software systems
|
||||
|
||||
Not every problem requires cognitive diversity. A simple, narrowly scoped task with a known process doesn't demand it. In those cases, a capable engineer with the right context is enough.
|
||||
|
||||
Alas, production systems are sociotechnical systems and therefore aren’t so simple. They're characterized by interconnected components, emergent behaviors, and failures that cascade across boundaries in ways nobody fully anticipates. No single engineer, no matter how senior or experienced, holds a complete picture. The system is a tangled layered network and so it’s too large, too complex for any one mental model to capture it adequately.
|
||||
|
||||
This is where cognitive diversity stops being a nice-to-have. [Research studying how groups build models of complex social and environmental systems](https://doi.org/10.1073/pnas.2016887118) has found that groups drawing on genuinely different mental models produce more accurate representations of how those systems actually work. They surface interdependencies that isolationist approaches miss, and they capture feedback loops that homogeneous groups overlook. Their collective models do a better job of predicting how a system responds to intervention.
|
||||
|
||||
AI is making this harder, not easier. As organizations integrate models into their systems as dependencies and as components in pipelines, the surface area of unpredictable behavior grows. Model outputs are opaque in ways that a myopic focus on service dependencies aren't. Failure modes are probabilistic rather than deterministic. The mental models engineers have built up over years of working with distributed systems don't map cleanly onto systems that include components nobody fully understands, including the people who built them. The gap between what any one person can hold in their head and what the system is actually doing keeps widening.
|
||||
|
||||
|
||||
|
||||
The implication for engineering organizations is direct: the quality of your collective picture depends not just on who is in the room, but on whether the people in the room are thinking about the problem differently.
|
||||
|
||||
## What this looks like in practice
|
||||
|
||||
Shifting from identity diversity to cognitive diversity doesn't require scrapping the processes you already have. It requires adding a layer of intentionality to how you compose groups, run reviews, and synthesize what you hear. For incident reviews, start with the [Howie Guide](https://howie-guide.pagerduty.com/) and supplement it with the following:
|
||||
|
||||
**Compose incident reviews differently.** Resist the instinct to staff a postmortem according to team membership or proximity to the failure. Ask instead where each person's understanding of the system comes from. An engineer who has watched the system behave badly under load, a support engineer who has fielded the customer impact, and an on-call responder who has developed strong intuitions about which telemetry signals are unhelpful will each bring a different mental model; resist the urge to let the org chart dictate that you only invite the first. You're looking for people whose knowledge comes from different vantage points, not just different teams.
|
||||
|
||||
**Separate before you synthesize.** Rather than opening an incident review or architectural discussion with group conversation, ask participants to independently write down their own understanding of what happened first. What do they think was driving the system's behavior? Which signals do they think mattered? What do they predict a proposed fix will do? Document these models before group discussion begins. It makes cognitive differences visible and it prevents the most confident or senior voice in the room from becoming everyone's theory of the system.
|
||||
|
||||
**Treat divergence as signal, not noise.** In most postmortems, synthesis means converging on a shared account of what happened. That's useful. And in complex systems, the points of persistent disagreement are often where the most important information lives. If one engineer believes the failure was driven by a cascading timeout and another believes it was a capacity planning miss, that's not a problem to be resolved by whoever’s voice is loudest. It's a sign that your collective model of the system has real gaps. Build an explicit step into your review process: whose account is least represented in the picture we're building, and what would we need to believe for them to be right?
|
||||
|
||||
**Use cognitive diversity to stress-test changes before you ship.** Once you have a proposed fix or architectural change, take it to people who think about the system differently and ask them independently what they predict will happen. Convergent predictions are encouraging; divergent ones are a sign that your change rests on a particular theory of the system that not everyone shares. That's worth surfacing before you deploy, not after.
|
||||
|
||||
## An honest caveat
|
||||
|
||||
None of this is a formula. Centering cognitive diversity in a team requires human judgment calls. The goal is productive disagreement, not maximum difference—people who share enough common ground to collaborate but bring sufficiently distinct mental models to expand the group's collective picture of a system that is, by definition, too complex for any one of them to fully understand.
|
||||
|
||||
What the research is clear about is the cost of not trying. When engineering organizations forgo building in cognitive diversity, they risk building a collective picture of their systems that *feels* comprehensive but, in actuality, is missing critical pieces. In stable, low-complexity environments, that gap is manageable. In the kind of fast-moving, highly interconnected systems that software organizations actually run, it tends to show up in the form of incidents that surprise everyone and fixes that make things worse.
|
||||
|
||||
The question worth asking is whether your current processes are designed to find the engineer with a different model of what's happening *before* the system makes you find them.
|
||||
|
||||
P.S. I used Claude in the writing of this blog post.
|
||||
@@ -0,0 +1,412 @@
|
||||
# Automating GCP quota monitoring across multiple projects
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Aksel Allas — Coop Norge SA
|
||||
- **链接**: https://tech.coop.no/blog/platform-engineering/2026/06/25/automating-gcp-quota-monitoring-across-multiple-projects/
|
||||
|
||||
## 简介
|
||||
|
||||
> Every GCP resource and API have quotas. In a big organization, you can start having production incidents due to hitting quotas you didn’t know about in projects you have never touched before.
|
||||
|
||||
## 正文
|
||||
|
||||
# Automating GCP quota monitoring across multiple projects[¶](https://tech.coop.no#automating-gcp-quota-monitoring-across-multiple-projects)
|
||||
|
||||
Every GCP resource and API have quotas. In a big organization, you can start having production incidents due to hitting quotas you didn't know about in projects you have never touched before.
|
||||
|
||||
## The incidents[¶](https://tech.coop.no#the-incidents)
|
||||
|
||||
In May 2026, a VPC dynamic route quota was silently exceeded. GCP dropped BGP-learned (Border Gateway Protocol) routes without any alert. Traffic to on-prem destinations fell back to the default internet gateway and was black-holed (dropped without notification).
|
||||
|
||||
A couple production services were down before the issue was
|
||||
traced to `routeStatus: DROPPED` in the Cloud Router output.
|
||||
|
||||
The fix was a quota increase and a BGP re-sync, but finding the root cause took a long time because nothing indicated that a quota had been hit.
|
||||
|
||||
A separate incident involved GKE Persistent Disk storage: usage grew from 900 GB to the 1000 GB limit during a GKE version update without anyone noticing until provisioning workloads started failing.
|
||||
|
||||
Both incidents had the same root cause: **zero visibility into
|
||||
GCP quotas** across GCP projects.
|
||||
|
||||
## Why native solutions fall short[¶](https://tech.coop.no#why-native-solutions-fall-short)
|
||||
|
||||
GCP does have quota monitoring built into
|
||||
GCP Cloud Monitoring.
|
||||
[Here's the best doc on monitoring ⧉](https://cloud.google.com/monitoring/alerts/using-quota-metrics).
|
||||
You can create alert policies across projects that fire when
|
||||
a quota approaches its limit. So why wasn't it being used?
|
||||
|
||||
The problem is that GCP has **two completely separate quota
|
||||
metric systems**, and neither supports a simple "alert on
|
||||
everything" approach.
|
||||
|
||||
### Consumer quotas[¶](https://tech.coop.no#consumer-quotas)
|
||||
|
||||
The first system uses `serviceruntime.googleapis.com/quota/*`
|
||||
metrics with a generic `consumer_quota` resource type. These
|
||||
cover API-level quotas: request rates, allocation limits,
|
||||
storage quotas, and similar. A single `quota_metric` label
|
||||
identifies which specific quota the time series belongs to.
|
||||
|
||||
The good news: you can write a [PromQL ⧉](https://prometheus.io/docs/prometheus/latest/querying/basics/)
|
||||
(Prometheus Query Language) query that matches
|
||||
**all** consumer quotas without specifying individual services
|
||||
or quota names. PromQL is a language for selecting and
|
||||
aggregating time series metrics. GCP Cloud Monitoring supports
|
||||
it as an alternative to its native query language, and it's
|
||||
what powers the alert conditions described below.
|
||||
|
||||
### Resource-specific quotas[¶](https://tech.coop.no#resource-specific-quotas)
|
||||
|
||||
The second system uses service-specific metrics like
|
||||
`compute.googleapis.com/quota/dynamic_routes_per_region_per_peering_group/usage`.
|
||||
Each service defines its own monitored resource type and label
|
||||
set. These cover infrastructure-level quotas: VPC routes,
|
||||
instances per network, GKE nodes per cluster.
|
||||
|
||||
These aren't covered by consumer quota queries. Each metric
|
||||
has its own path and its own set of labels for the `on()`
|
||||
clause in PromQL. There are currently over 370 such metrics
|
||||
across 28 services.
|
||||
|
||||
The VPC routing incident? That was a resource-specific quota. The native consumer quota alerts would never have caught it.
|
||||
|
||||
## The solution[¶](https://tech.coop.no#the-solution)
|
||||
|
||||
The requirements:
|
||||
|
||||
1. Covers both quota systems
|
||||
2. Automatically picks up new quotas and services
|
||||
3. Works across all 300 monitored projects from a single place
|
||||
4. Doesn't require manual configuration per quota
|
||||
|
||||
### Architecture[¶](https://tech.coop.no#architecture)
|
||||
|
||||
```
|
||||
graph LR
|
||||
subgraph "Scoping Project"
|
||||
MS[Metrics Scope] --> AP[Alert Policies]
|
||||
AP --> NC[Slack Channel]
|
||||
end
|
||||
subgraph "Monitored Projects"
|
||||
P1[project-1] --> MS
|
||||
P2[project-2] --> MS
|
||||
P3[project-N] --> MS
|
||||
end
|
||||
subgraph "Auto-Discovery via github repo for managing Scoping Project"
|
||||
TF[Terraform] -->|data external| SH[get_quota_metrics.sh]
|
||||
SH -->|Cloud Monitoring API| PY[build_quota_promql.py]
|
||||
PY -->|per-service PromQL| TF
|
||||
end
|
||||
TF --> AP
|
||||
```
|
||||
All alerts run in a single **scoping project**. Every monitored
|
||||
project gets added to its
|
||||
[metrics scope ⧉](https://cloud.google.com/monitoring/settings/multiple-projects),
|
||||
so one set of alert policies covers every project. PromQL
|
||||
queries group by `project_id`, `quota_metric`, `location`, and
|
||||
`service`, so each unique combination fires as a separate
|
||||
incident. You know exactly which quota in which project and
|
||||
region is at risk.
|
||||
|
||||
### Consumer quota alerts[¶](https://tech.coop.no#consumer-quota-alerts)
|
||||
|
||||
For consumer quotas, there are three alert policies. No service filter, no quota name filter. They match all consumer quotas automatically.
|
||||
|
||||
**Allocation usage > 80%:** resource limits like disk, CPU,
|
||||
IP addresses:
|
||||
|
||||
```
|
||||
(
|
||||
max by (project_id, quota_metric, location, service) (
|
||||
last_over_time(
|
||||
serviceruntime_googleapis_com:quota_allocation_usage{
|
||||
monitored_resource="consumer_quota"
|
||||
}[6h]
|
||||
)
|
||||
)
|
||||
/
|
||||
min by (project_id, quota_metric, location, service) (
|
||||
last_over_time(
|
||||
serviceruntime_googleapis_com:quota_limit{
|
||||
monitored_resource="consumer_quota"
|
||||
}[6h]
|
||||
)
|
||||
)
|
||||
) > 0.8
|
||||
```
|
||||
**Rate usage > 80%:** API request rates, with read-only APIs
|
||||
excluded to reduce noise. Hitting a read rate limit causes
|
||||
retries, not outages:
|
||||
|
||||
```
|
||||
(
|
||||
sum by (project_id, quota_metric, location, service) (
|
||||
increase(
|
||||
serviceruntime_googleapis_com:quota_rate_net_usage{
|
||||
monitored_resource="consumer_quota",
|
||||
quota_metric!~".*/get_.*|.*/list_.*|.*read_requests.*|.*/read$|.*/fetch_.*|.*search_requests.*"
|
||||
}[1m]
|
||||
)
|
||||
)
|
||||
/
|
||||
max by (project_id, quota_metric, location, service) (
|
||||
last_over_time(
|
||||
serviceruntime_googleapis_com:quota_limit{
|
||||
monitored_resource="consumer_quota",
|
||||
quota_metric!~".*/get_.*|.*/list_.*|.*read_requests.*|.*/read$|.*/fetch_.*|.*search_requests.*"
|
||||
}[6h]
|
||||
)
|
||||
)
|
||||
) > 0.8
|
||||
```
|
||||
**Quota exceeded:** safety net for anything that slips past the
|
||||
80% warning, with the same read-only exclusion:
|
||||
|
||||
```
|
||||
max by (project_id, quota_metric, location, service) (
|
||||
last_over_time(
|
||||
serviceruntime_googleapis_com:quota_exceeded{
|
||||
monitored_resource="consumer_quota",
|
||||
quota_metric!~".*/get_.*|.*/list_.*|.*read_requests.*|.*/read$|.*/fetch_.*|.*search_requests.*"
|
||||
}[6h]
|
||||
)
|
||||
) > 0
|
||||
```
|
||||
When someone enables a new GCP API or Google adds a new quota, these queries pick it up with zero configuration changes.
|
||||
|
||||
### Resource-specific quota alerts[¶](https://tech.coop.no#resource-specific-quota-alerts)
|
||||
|
||||
Resource-specific quotas can't be covered by a single query.
|
||||
Each metric has different labels. A VPC network quota has
|
||||
`network_id`, a GKE quota has `cluster_name`, an AI Platform
|
||||
quota has `base_model`. The PromQL `on()` clause must match per
|
||||
metric.
|
||||
|
||||
Instead of maintaining a static list, a discovery script runs
|
||||
as a Terraform
|
||||
[`data "external"` ⧉](https://registry.terraform.io/providers/hashicorp/external/latest/docs/data-sources/external)
|
||||
source. Here's how it works in detail.
|
||||
|
||||
#### Step 1: fetch metric descriptors[¶](https://tech.coop.no#step-1-fetch-metric-descriptors)
|
||||
|
||||
A bash wrapper calls the GCP Cloud Monitoring API to get every metric descriptor in the scoping project. This includes metrics from all projects in the metrics scope:
|
||||
|
||||
```
|
||||
curl -s -H "Authorization: Bearer ${TOKEN}" \
|
||||
"${BASE_URL}/metricDescriptors" > "${METRICS_FILE}"
|
||||
curl -s -H "Authorization: Bearer ${TOKEN}" \
|
||||
"${BASE_URL}/monitoredResourceDescriptors" \
|
||||
> "${RESOURCES_FILE}"
|
||||
```
|
||||
The metric descriptors tell you what quota metrics exist (for
|
||||
example,
|
||||
`compute.googleapis.com/quota/dynamic_routes_per_region_per_peering_group/usage`)
|
||||
and what **metric labels** each one has (for example,
|
||||
`limit_name`).
|
||||
|
||||
The resource descriptors tell you what **resource labels** each
|
||||
monitored resource type has. For example,
|
||||
`compute.googleapis.com/VpcNetwork` has `resource_container`,
|
||||
`location`, and `network_id`.
|
||||
|
||||
#### Step 2: filter to resource-specific quota metrics[¶](https://tech.coop.no#step-2-filter-to-resource-specific-quota-metrics)
|
||||
|
||||
A Python script processes the JSON. It finds all metrics
|
||||
matching the pattern
|
||||
`<service>.googleapis.com/quota/<name>/usage` and `*/limit`,
|
||||
excluding `serviceruntime` (those are consumer quotas handled
|
||||
separately) and `*_internal` metrics (they have descriptors but
|
||||
get rejected by the alerting API):
|
||||
|
||||
#### Step 3: resolve the correct `on()` labels[¶](https://tech.coop.no#step-3-resolve-the-correct-on-labels)
|
||||
|
||||
This is the tricky part. For the PromQL division
|
||||
`usage / limit` to work, the `on()` clause must list every
|
||||
label shared between the two sides. These labels come from two
|
||||
sources: the resource type and the metric itself.
|
||||
|
||||
One gotcha: the resource descriptor calls the project label
|
||||
`resource_container`, but in actual PromQL queries it appears
|
||||
as `project_id`. This was discovered by querying the raw time
|
||||
series API and comparing:
|
||||
|
||||
For quotas where usage has extra labels that limit doesn't
|
||||
(mainly AI Platform metrics with a `method` label),
|
||||
`group_left()` allows the many-to-one join.
|
||||
|
||||
#### Step 4: convert metric names and generate PromQL[¶](https://tech.coop.no#step-4-convert-metric-names-and-generate-promql)
|
||||
|
||||
[GCP Cloud Monitoring PromQL ⧉](https://docs.cloud.google.com/monitoring/promql#transforming-names) uses a different
|
||||
naming convention than the API. The first `/` becomes `:`, and
|
||||
all other special characters become `_`:
|
||||
|
||||
Each quota becomes one PromQL clause:
|
||||
|
||||
```
|
||||
clause = (
|
||||
f"last_over_time({usage_name}[{lookback}])"
|
||||
f" / on({on_labels}) group_left() "
|
||||
f"last_over_time({limit_name}[{lookback}])"
|
||||
f" > {threshold}"
|
||||
)
|
||||
```
|
||||
#### Step 5: group by service[¶](https://tech.coop.no#step-5-group-by-service)
|
||||
|
||||
Clauses are grouped by service name extracted from the metric
|
||||
path and joined with `or`. The script outputs a flat JSON
|
||||
object with keys as service names, and values as complete
|
||||
PromQL queries:
|
||||
|
||||
```
|
||||
{
|
||||
"compute": "last_over_time(...) / on(...) ... > 0.8\nor\nlast_over_time(...) ...",
|
||||
"container": "...",
|
||||
"storage": "..."
|
||||
}
|
||||
```
|
||||
Terraform's `for_each` iterates over this map, creating one
|
||||
alert policy per service. Currently that's 28 services covering
|
||||
370+ quota metrics. When Google adds a new service with
|
||||
resource-specific quotas, the next `terraform apply` creates a
|
||||
new alert policy automatically.
|
||||
|
||||
A generated query for compute quotas looks like this (one
|
||||
clause per quota, joined with `or`):
|
||||
|
||||
```
|
||||
last_over_time(compute_googleapis_com:quota_dynamic_routes_per_region_per_peering_group_usage[6h])
|
||||
/ on(limit_name, location, network_id, project_id) group_left()
|
||||
last_over_time(compute_googleapis_com:quota_dynamic_routes_per_region_per_peering_group_limit[6h])
|
||||
> 0.8
|
||||
or
|
||||
last_over_time(compute_googleapis_com:quota_instances_per_vpc_network_usage[6h])
|
||||
/ on(limit_name, location, network_id, project_id) group_left()
|
||||
last_over_time(compute_googleapis_com:quota_instances_per_vpc_network_limit[6h])
|
||||
> 0.8
|
||||
```
|
||||
When a new service adds resource-specific quota metrics, the
|
||||
next `terraform apply` creates a new alert policy for that
|
||||
service automatically.
|
||||
|
||||
### The Terraform[¶](https://tech.coop.no#the-terraform)
|
||||
|
||||
The Terraform configuration ties it all together. The
|
||||
[`for_each` ⧉](https://developer.hashicorp.com/terraform/language/meta-arguments/for_each)
|
||||
over the discovery script output creates one alert policy per
|
||||
service:
|
||||
|
||||
```
|
||||
data "external" "quota_metrics" {
|
||||
program = [
|
||||
"bash",
|
||||
"${path.module}/scripts/get_quota_metrics.sh",
|
||||
local.quota_monitoring_project_id,
|
||||
tostring(local.quota_alert_threshold),
|
||||
local.quota_alert_lookback,
|
||||
]
|
||||
query = {
|
||||
exclusions = jsonencode(local.quota_alert_exclusions)
|
||||
}
|
||||
}
|
||||
resource "google_monitoring_alert_policy" "quota_resource_specific" {
|
||||
for_each = data.external.quota_metrics.result
|
||||
project = local.quota_monitoring_project_id
|
||||
display_name = "Quota > 80% - ${each.key} resource quotas"
|
||||
conditions {
|
||||
display_name = "${each.key} resource quota > 80%"
|
||||
condition_prometheus_query_language {
|
||||
query = each.value
|
||||
duration = "0s"
|
||||
evaluation_interval = "30s"
|
||||
}
|
||||
}
|
||||
notification_channels = local.quota_alert_notification_channels
|
||||
}
|
||||
```
|
||||
## Technical challenges[¶](https://tech.coop.no#technical-challenges)
|
||||
|
||||
### Sparse sampling and alert flapping[¶](https://tech.coop.no#sparse-sampling-and-alert-flapping)
|
||||
|
||||
Quota metrics are sampled infrequently. Data points arrive every 5 to 15 minutes with gaps. Alerts would fire when a data point showed usage exceeding 80%, then immediately resolve when the next evaluation found no data, then fire again when the next data point arrived.
|
||||
|
||||
PromQL alert conditions don't support
|
||||
`evaluation_missing_data = "EVALUATION_MISSING_DATA_ACTIVE"`
|
||||
(that's only available for `condition_threshold`). The fix was
|
||||
wrapping every metric selector in `last_over_time(...[6h])`,
|
||||
which returns the most recent data point within the look-back
|
||||
window. No more flapping.
|
||||
|
||||
### The `resource_container` gotcha[¶](https://tech.coop.no#the-resource_container-gotcha)
|
||||
|
||||
The GCP Cloud Monitoring API's resource descriptors list a
|
||||
label called `resource_container`, but in actual PromQL
|
||||
queries, that label appears as `project_id`. This was
|
||||
discovered by querying the raw time series API and comparing
|
||||
label names. The script maps `resource_container` to
|
||||
`project_id` automatically.
|
||||
|
||||
### Label mismatches between usage and limit[¶](https://tech.coop.no#label-mismatches-between-usage-and-limit)
|
||||
|
||||
For some quotas (mainly AI Platform), the `/usage` metric has
|
||||
an extra `method` label that the `/limit` metric doesn't have.
|
||||
A naive division fails because PromQL can't match series with
|
||||
different label sets. Using `group_left()` handles the
|
||||
many-to-one join.
|
||||
|
||||
### Read-only API quota noise[¶](https://tech.coop.no#read-only-api-quota-noise)
|
||||
|
||||
Rate quota alerts were extremely noisy. Quotas like
|
||||
`read_requests`, `list_requests`, and `search_requests` would
|
||||
fire constantly. Hitting a read rate limit causes retries, not
|
||||
outages. It's low-risk noise that drowns out real issues.
|
||||
|
||||
A regular expression filter on the `quota_metric` label
|
||||
excludes read-only patterns:
|
||||
|
||||
```
|
||||
quota_metric!~".*/get_.*|.*/list_.*|.*read_requests.*|.*/read$|.*/fetch_.*|.*search_requests.*"
|
||||
```
|
||||
## The workflow: alert to resolution[¶](https://tech.coop.no#the-workflow-alert-to-resolution)
|
||||
|
||||
When a quota alert fires, here's the investigation path:
|
||||
|
||||
**1. Alert arrives in Slack** with the project ID, quota name,
|
||||
service, and current ratio.
|
||||
|
||||
**2. Check the Quotas page** in the GCP Console for the
|
||||
affected project. The
|
||||
[Quotas & System Limits ⧉](https://console.cloud.google.com/iam-admin/quotas)
|
||||
page shows current usage alongside limits.
|
||||
|
||||
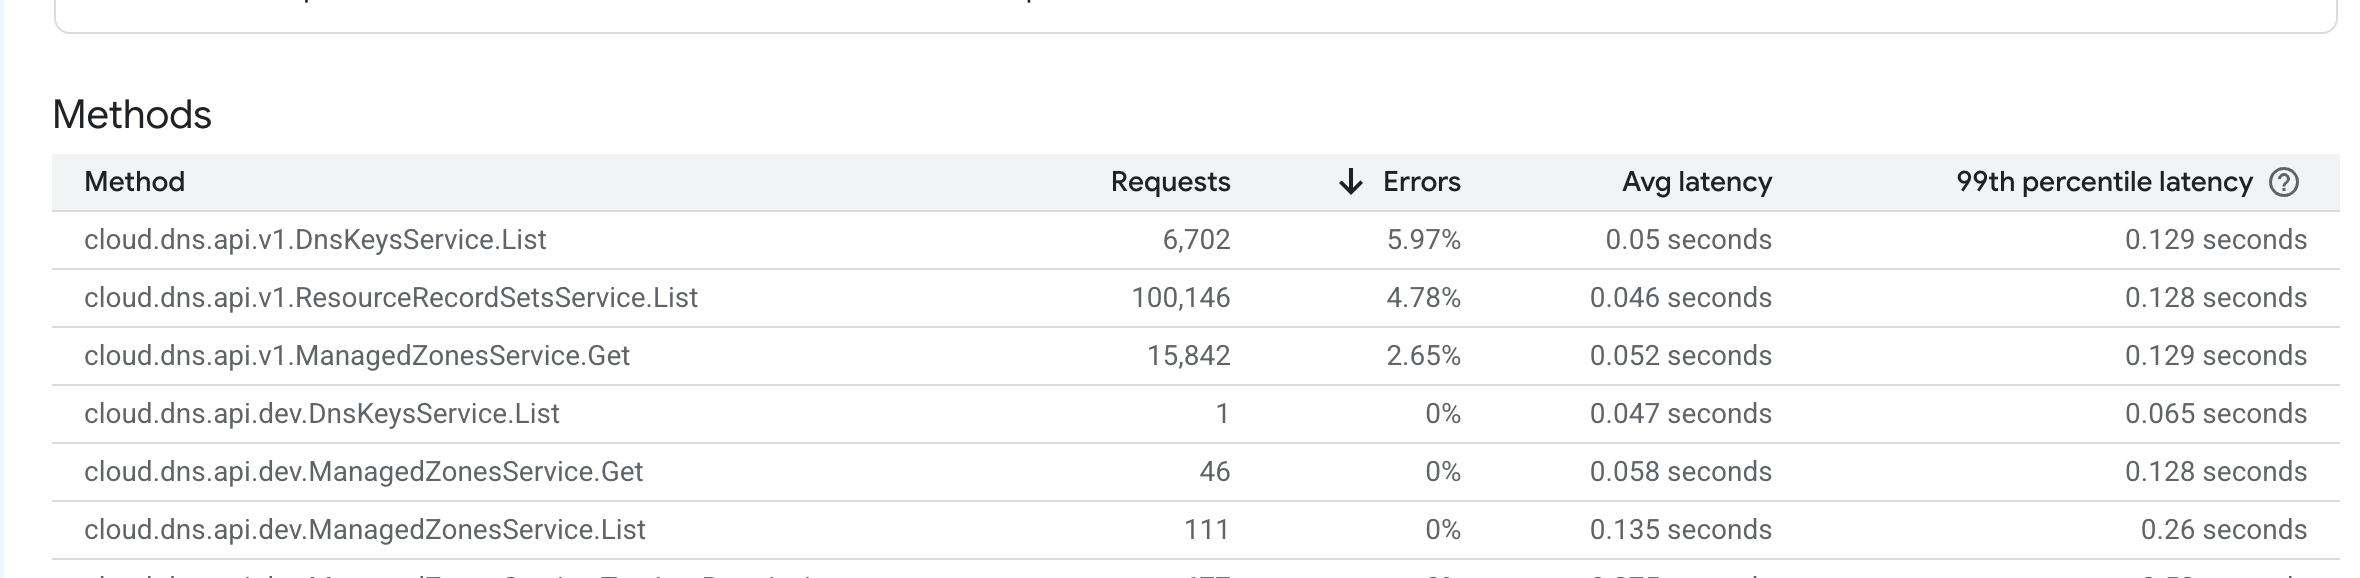
**3. Check API usage and error rates** to understand what's
|
||||
driving the consumption. The API dashboard shows request counts,
|
||||
error rates, and latency per method:
|
||||
|
||||
|
||||
|
||||
|
||||
**4. Increase the quota** if the usage is legitimate. Some
|
||||
quotas can be increased through self-service.
|
||||
|
||||
Some quotas are marked `is_fixed` and require a support ticket
|
||||
to increase. The VPC dynamic routes quota that caused the first
|
||||
incident was one of these.
|
||||
|
||||
## APIs to enable[¶](https://tech.coop.no#apis-to-enable)
|
||||
|
||||
Three APIs need to be enabled on each monitored project for quota metrics to flow correctly:
|
||||
|
||||
| API | Why |
|
||||
|---|---|
|
||||
| `cloudquotas.googleapis.com` | Accurate quota data. Not on by default. |
|
||||
| `storage-component.googleapis.com` | Google Cloud Storage quota visibility |
|
||||
| `storage.googleapis.com` | Google Cloud Storage quota visibility |
|
||||
|
||||
These get enabled through Terraform on all monitored projects once in the beginning, and were added to the new project Terraform module so future projects get them automatically.
|
||||
|
||||
## Links and resources[¶](https://tech.coop.no#links-and-resources)
|
||||
|
||||
- [Cloud Monitoring: Using quota metrics ⧉](https://cloud.google.com/monitoring/alerts/using-quota-metrics) Google's documentation on quota alerting
|
||||
- [Metrics scopes overview ⧉](https://cloud.google.com/monitoring/settings/multiple-projects) Multi-project monitoring (375 project default limit)
|
||||
- [PromQL metric name transformation ⧉](https://docs.cloud.google.com/monitoring/promql#transforming-names) How GCP metric names map to PromQL names
|
||||
63
sreweekly/markdown/524/05-know-thyself.md
Normal file
63
sreweekly/markdown/524/05-know-thyself.md
Normal file
@@ -0,0 +1,63 @@
|
||||
# Know thyself
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Jos Visser
|
||||
- **链接**: https://josvisser.substack.com/p/know-thyself
|
||||
|
||||
## 简介
|
||||
|
||||
Maybe that complex HA system is difficult enough to operate that a single-host solution would be more reliable.
|
||||
|
||||
## 正文
|
||||
|
||||
*Did you know that Wednesday Wisdom is also a podcast! Find it on [Apple Podcasts](https://podcasts.apple.com/us/podcast/wednesday-wisdom/id1781128079) or on [Spotify](https://open.spotify.com/show/3dl5l7fOGmMCNUqxHkJ7qY). Did you know that there is also a custom GPT called [Midweek Muse](https://chatgpt.com/g/g-677076fcad6c8191bd0124f7b3284a9f-midweek-muse) that has access to all of Wednesday Wisdom? Did you know that all Wednesday Wisdom videos are also available on [YouTube](https://www.youtube.com/@josvisser1805/videos)?*
|
||||
|
||||
|
||||
When I was [nineteen](https://www.youtube.com/watch?v=dDuKXlnre0o), my father gave me his [Honda CB 750 motorcycle](https://en.wikipedia.org/wiki/Honda_CB750_and_CR750) to get to college. It came with an owner’s manual, which was unfortunately quite light on [Zen and the art of motorcycle maintenance](https://en.wikipedia.org/wiki/Zen_and_the_Art_of_Motorcycle_Maintenance), so I got myself an *additional* manual that described how to do most maintenance tasks yourself. Chapter 8, on the topic of brakes, started as follows: “Now is the time to be honest with yourself about how good a mechanic you really are. Are you the kind of mechanic that usually gets everything right on the first try? Or are you the kind of mechanic that regularly makes mistakes?” I had to admit to myself that I am the latter and so I left brake maintenance to the shop, which is quite possibly why I am still alive today.
|
||||
|
||||
Fast forward twenty-odd years. I was in a project at a bank that was developing applications for large international customers. These applications had to support fine-grained authorization so that the treasurers of our customers could define the roles and responsibilities of their colleagues. The design of the user administration module was in the hands of a genial and brilliant colleague who created a data model that was so complicated that few people understood it, let alone could implement or query it correctly. I wrote an internal email called “The intergalactic data model” that explained why this design was not the right one for us. Yes, it could do *everything* any customer could *ever* ask for, but I could not see us implement, query, maintain, and troubleshoot the system correctly because of the sheer complexity of the model and the overall knowledge and skills of our software engineers.
|
||||
|
||||
I was mostly ignored, but for a few years after sending that email, I would regularly receive requests to re-send a copy of it, probably to support some internal argument. The model was implemented, but the equally genial and brilliant tech leads of the team I worked with, wrote a cron job that denormalized the information in the user administration into a data model that was much easier to understand (both for developers and for Oracle; critical for performance) and query.
|
||||
|
||||
|
||||
Years before this episode, I was teaching [MC/ServiceGuard](https://en.wikipedia.org/wiki/HP_Serviceguard) courses at Hewlett-Packard (HP). MC/ServiceGuard was a product that enabled you to run services with “high” availability on a cluster of machines. When a machine failed, the services running on that machine would move to another node in the cluster, taking its disks and IP addresses with it. This might seem trivial today, but believe me, in the 1990s this was a highly advanced use case that required specialized hard- and software support.
|
||||
|
||||
Running an MC/ServiceGuard cluster was not for the timid, as it required a lot of knowledge of, and experience with, HP-UX, the HP Logical Volume Manager, TCP/IP, and SCSI. My colleagues and I used to joke that, given the expertise of the average HP-UX system administrator, a standalone machine was probably more reliable than an MC/ServiceGuard cluster, as a single mistake could easily bring down the entire cluster or maybe erase a mirrored logical volume.
|
||||
|
||||
During one course, I was joined by a few system administrators from the [Rotterdam public transport system](https://www.ret.nl/en/), who were moving from their proprietary [HP3000](https://en.wikipedia.org/wiki/HP_3000) (with the [MPE/iX](https://en.wikipedia.org/wiki/HP_Multi-Programming_Executive) operating system) to “open” systems (meaning: HP9000s and HP-UX).
|
||||
|
||||
Fun fact: The later models of the HP3000 and HP9000 were exactly the same hardware architecture ([PA-RISC](https://en.wikipedia.org/wiki/PA-RISC) based), but HP3000s were way more expensive, because HP3000 customers had nowhere else to go and HP9000 customers could relatively easily move to other Unix systems, for instance ones offered by Sun, Digital, or IBM.
|
||||
|
||||
|
||||
The students from Rotterdam were unique, because they were attending the course *before* the decision was made to invest in an MC/ServiceGuard cluster (most students came *after* the deal had been done, to learn how to use the stuff they had already bought). At the end of the five day course, I was talking to the team lead and he said that, based on what they experienced in the course, they would *not* be moving forward with MC/ServiceGuard, as they had figured out that they did not have enough basic HP-UX knowledge to manage their cluster reliably. Great self-knowledge, leading to a great decision.
|
||||
|
||||
When doing something, anything, you have to be aware of *who* you are and what that means for what you are doing. I am not a great mechanic, so I should *not* fix the brakes of my motorcycle. The team I was in at the bank did not consist of great software engineers, so we should *not* develop an application that was based on a hyper-complicated data model. The system administrators of the Rotterdam public transport system were new to HP-UX, so they should *not* install and run an MC/ServiceGuard cluster. Technical decisions must be grounded in a correct assessment of what the people responsible for execution are capable of.
|
||||
|
||||
It’s not just about knowledge and skills, knowing your company *culture* matters just as much.
|
||||
|
||||
While at [Google Flights](https://www.google.com/travel/flights?gl=US&hl=en-US), I worked on a system for processing airline data and building the indexes that were then pushed to the flight search engine. For many reasons, all outside the scope of this article, this is a complex problem and the solution we had was starting to show its age. I set off to design a new and complicated parallel processing engine that would significantly speed up building these indexes using the latest and greatest Google technology available at that time. This project took over a year to complete its first deliverable, which given Google’s internal culture (which I once described as being the “Germany of software engineering”) was not out of the ordinary. We wrote a large and complicated piece of software, but Google’s culture was receptive to that approach, so no problem at all.
|
||||
|
||||
To be honest, there were regular questions from managers about how much time this would still take, but at the end of the day, they allowed us to continue and eventually the project was finished and went into production.
|
||||
|
||||
|
||||
Compare this with the following experience: I once worked for a startup with incredible velocity and a culture that valued shipping above anything else. Through company shenanigans outside of my control, I was asked to join a team that worked on a very fundamental and very secure solution for the problem of machine and workload identity. This is a complex problem and, much like the Google flights “fareload” building system, we set out to design and build a complicated solution that would fundamentally solve this problem. This project also took a long time; much longer in fact than our startup had an appetite for. We designed and built a great system, but it took a long time and before we could finish it and roll it out, the organization had lost focus, executives had moved on, and our project was disbanded. Great solution, beautiful design, but all things considered, we were not the kind of organization that could build and run something like this. Not for lack of technical chops, we had oodles of that, but for cultural reasons.
|
||||
|
||||
You cannot build something that takes longer than the attention span of the company.
|
||||
|
||||
I did put that experience to good use by counseling new colleagues on what to work on and how to deliver: No big-ass projects that would take months to complete, but smaller scoped targeted solutions that could be released iteratively and show value along the way.
|
||||
|
||||
|
||||
The adage “Know yourself” even applies at a *national* level. As you may or may not know, I am an active member of a Dutch political party. Within the party, we have a committee on digital affairs, which is currently mostly concerning itself with AI and digital autonomy. Within our Signal group, I regularly read far-reaching proposals on how to fix our government’s dependency on American tech companies. Most of these proposals could *only* work in a hierarchical “command and control” organization where the executives declare a new plan and the lower reaches of the organization faithfully execute it. *But that is not who we are*, and thus these proposals are meaningless.
|
||||
|
||||
The Netherlands is a negotiation-based society: Kids negotiate with their parents about bedtime and where they will go on vacation this year, students negotiate with teachers about grades, the police negotiate with the (equivalent of the) district attorneys which laws they will enforce. The Dutch form a large, complicated, and *pluralistic* society where *nobody* is in charge and *everybody* negotiates with everybody about everything all the time. Our prime minister is not even the leader of the cabinet, but a “[primus inter pares](https://en.wikipedia.org/wiki/Primus_inter_pares)” instead (the first among equals).
|
||||
|
||||
In a country like that, you cannot get the government off of Microsoft Outlook by making a decision and ruthlessly executing it from the top (hint: There is no top). You will need to create an interdepartmental platform, propose a change, seek consensus, expect resistance, do research and a pilot, expand the pilot, and generally talk until the cows come home. It is a slow process, which annoys the hell out of the nerds who think that the clock has already struck midnight on our digital dependence, and who think that *big* things need to be done *now*!
|
||||
|
||||
As a comparison: The [reform of the Dutch pension system](https://www.reuters.com/business/finance/why-dutch-pension-fund-reform-matters-markets-2025-12-29/) that went into law in 2023 and that will take effect in 2026-2027 was the result of over *fifteen* years of discussion between successive governments, unions of employees, unions of employers, pension funds, and regulators. That’s how we do things…
|
||||
|
||||
|
||||
Every plan and technical design you propose needs to match the skills of the people who are going to build it and the culture of the organization that is funding it. If you don’t understand Java very well, don’t use [Websphere](https://www.ibm.com/products/websphere-application-server) but maybe consider [Apache Tomcat](https://tomcat.apache.org/) (not a random example). If you don’t understand HP-UX very well, don’t use MC/ServiceGuard, but instead buy a [Stratus Continuum](https://www.openpa.net/systems/stratus_continuum.html) fault tolerant server. If you are a high-velocity startup, don’t propose a big-ass design that will take a year or more to build.
|
||||
|
||||
To say it with Charlie Munger: Knowing what you *cannot* do is more useful than being brilliant.
|
||||
|
||||
|
||||
@@ -0,0 +1,93 @@
|
||||
# The best code is the one you shift+delete
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Oren Eini
|
||||
- **链接**: http://ayende.com/204067-a/the-best-code-is-the-one-you-shift-delete?Key=8b5a5104-ec4c-48b9-9a86-4d2a1715e0d0
|
||||
|
||||
## 简介
|
||||
|
||||
LLMs enable interesting new use cases, like writing single-use code for use during incidents or testing.
|
||||
|
||||
## 正文
|
||||
|
||||
## The best code is the one you shift+delete
|
||||
|
||||
**7 min**|
|
||||
|
||||
**1391 words**
|
||||
|
||||
Everyone talking about coding models fixates on the same number: how fast the thing generates code. This misses the point by a lot. The story isn't about how fast the model writes code I would have written anyway.
|
||||
|
||||
It's that the model lets me do things that I *might* have done before but were expensive enough that I didn’t bother. I had three separate interactions this week that led to this blog post.
|
||||
|
||||
We had a production problem on an instance and no clear idea what was going on. What we did have was the log: something like 25-30 MB of compressed text describing everything that happened. And the actual problem wasn't spotting an error: finding errors is easy. The problem was *correlation*. We needed to line up different events across the timeline and understand how they were related.
|
||||
|
||||
In the past, I would have to trawl through the log and hope that something would pop up. These days, we can try handing the whole thing to the model and let it figure it out. If the log file wasn’t that big, it might even work. At dozens of MB, it doesn’t work (and it is quite expensive to try).
|
||||
|
||||
I went the other way. I told the model: “Write me a script that looks at the structure of this log (I gave it the first ten rows). I want the script to extract and aggregate the parts I care about, and render the result in a nice table to make it easier to understand.”
|
||||
|
||||
I had the view in under a minute, then I could explore the log and iterate:
|
||||
|
||||
- “Oh, I see that there are a lot of indexes. How many of them are for the same database?”
|
||||
- “Give me a histogram of index changes and their versions over time.”
|
||||
|
||||
The model wrote some code, produced a view, and I looked at it. Rinse & repeat until I had a pretty good idea what was going on.
|
||||
|
||||
The customer had *several* different versions of their application, each with its own set of indexes, and they kept overwriting one another, leading to a *huge* amount of indexing overhead. RavenDB actually has [a dedicated feature for that scenario](https://docs.ravendb.net/7.0/client-api/operations/maintenance/indexes/set-index-lock#lock-modes).
|
||||
|
||||
Here's the part that *matters*: I never read the code the model wrote. The moment the investigation was done, I threw all of it away. It's throwaway code whose entire purpose was to help me *see*, and once I had seen enough, I discarded it.
|
||||
|
||||
Without the model to write this code, I *could* have written it myself, but it is enough of a chore that it probably wouldn’t make sense. Doing that manually would have taken roughly the same amount of time.
|
||||
|
||||
The second interaction is the opposite kind of work. I'm doing a fairly significant refactor of how a particular query executes in Corax, and that code is going into the product and staying there for a decade or two.
|
||||
|
||||
Here, the model writes and I drive. I tell it the overall direction, it goes somewhere, and then I decide if I like the result. I find it genuinely easier to react to something than to produce it from a blank page — having a first draft to push against is faster than writing it all myself. Nevertheless, this is *my* code. I went over every single line, and I know exactly what's in there.
|
||||
|
||||
That last part takes real discipline, and it's worth being honest about why. When you're in the zone chasing a change (try something out, revert, try something else, etc.), it is very easy to surface a few hours later staring at two thousand lines of changes you never actually wrote. You went through a dozen iterations, and somewhere in there the code stopped being something you *authored* and became something that merely *happened*. Guarding against that is really important, because otherwise that isn’t your code.
|
||||
|
||||
How do I make sure it's still mine? I lean on tests, of course — regression tests to prove I didn't break the old behavior, and new tests built alongside the change to pin down the new behavior. That's the baseline for anything long-lived.
|
||||
|
||||
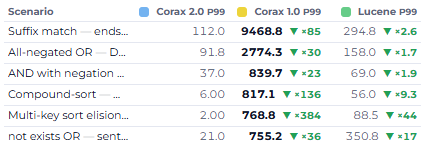
The technique I found most useful for confirming that the change is really *mine* is a little unusual. I had it build a harness that runs a set of scenarios against both the old version and the new one. It's a small app that issues queries and operations to the database and *visualizes* the results.
|
||||
|
||||
Here is what this looked like:
|
||||
|
||||
|
||||
|
||||
|
||||
You can see that I have a bunch of scenarios that I’m testing, and it is very easy for me to track progress and *know* where I need to pay attention. The actual app had a lot more capabilities: what got faster, what got slower, the ranges, the memory used, everything and the kitchen sink went into that, in a format that made sense for the sort of work I was doing.
|
||||
|
||||
Each time I had a new direction, it was either driven by this application or I asked the model to *add* it to the application, so I could keep working on it. I kept working until nothing in the new version was slower than the old, and the headline paths were dramatically faster.
|
||||
|
||||
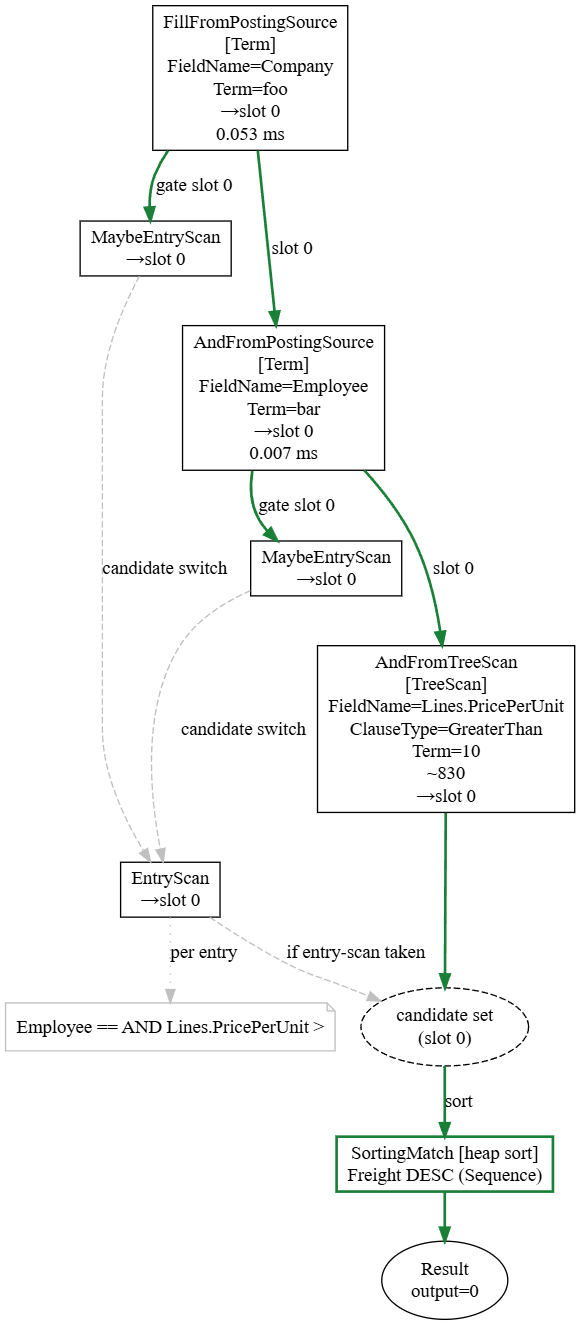
As an example of what this looked like most of the time, I ran a query, and then I inspected the structure we got back. Here is what some of that looked like:
|
||||
|
||||
|
||||
|
||||
|
||||
And as I went, I kept changing the harness itself — show me this instead, group it that way. Trivial to do, because the harness is *also* throwaway. I'm not carrying it forward. I don't care about its code quality. I never even looked at its code. It exists to make a point, and once it's made the point, it's gone.
|
||||
|
||||
I also used the model to add introspection hooks and visibility into what was going on inside the system, surfacing stuff that you would usually have to scratch your head and debug to understand. That meant that I was able to look at a problematic query, then just *look* at its query plan and the timing in it. I usually knew where I needed to pay attention from there.
|
||||
|
||||
To be honest, that part feels a lot like cheating.
|
||||
|
||||
In the cases of the log analyzer and the comparison harness, the code is literally disposable. It’s scaffolding that would be thrown away after the work is done. I didn’t pay any attention to that code (I never read it), and it was never meant to be useful for anything else.
|
||||
|
||||
In the case of the production code, I went over each line of code so many times, I dreamt of it. A lot of the code there consists of annoying building blocks (building a visualization of the query plan as a graph, for example), which were sped up enormously by asking the model to build it for us. A lot of other code there is hand-crafted to say *exactly* what I needed it to.
|
||||
|
||||
But the fact that I can get *good* scaffolding from the model for cheap changes a lot of the usual considerations. Because scaffolding is *literally* disposable code, I don’t have to worry about the usual code quality concerns. The log analyzer would probably take two or three hours to write (without the pretty graphics, which were *helpful* for easily identifying what was going on).
|
||||
|
||||
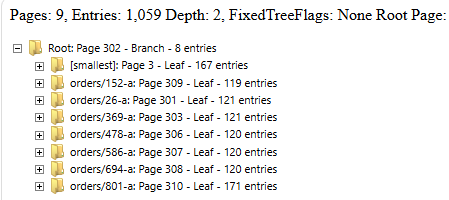
The comparison harness would be multiple weeks of effort and would probably be a non-interactive ASCII table. In fact, I don’t need to guess. Scaffolding isn’t something that is new, I do that all the time. Here is an example of one, written about a decade ago:
|
||||
|
||||
|
||||
|
||||
|
||||
In the image above, you can find the internal structure of a B+Tree inside RavenDB. Contrast that with the following scaffolding for query plans. That one, by the way, is actually staying in the product.
|
||||
|
||||
Compare that to the level of insight that you can derive from the query plan higher up in this post. The B+Tree scaffolding, by the way, is *essential* to understanding the more complex scenarios. It paid for the time it took to write it many times over.
|
||||
|
||||
The ability to now effectively do the same at very little cost means that the act of building software itself is now easier. Not because someone else is writing the core code, but because *everything else* that we need to do is also easier.
|
||||
|
||||
## Comments
|
||||
|
||||
## Comment preview
|
||||
|
||||
## Join the conversation...
|
||||
@@ -0,0 +1,13 @@
|
||||
# You Don’t Know Jack About Formal Verification
|
||||
|
||||
- **期号**: SRE Weekly Issue #524(2026-07-05)
|
||||
- **作者**: Fernanda Graciolli and Nada Amin — ACM Queue
|
||||
- **链接**: https://queue.acm.org/detail.cfm?ref=rss&id=3819084
|
||||
|
||||
## 简介
|
||||
|
||||
A good introduction to formal verification and how LLMs can help. Formal verification may be more practical now that LLMs can help us write the proofs.
|
||||
|
||||
## 正文
|
||||
|
||||
> ⚠️ 抓取失败:HTTP 403
|
||||
Reference in New Issue
Block a user