feat(sreweekly): 新增 533 期 HTML 与 532 期译文,更新 manifest;附带 youtube-transcript 转录输出
This commit is contained in:

97
sreweekly/html/533-2026-09-07.html
Normal file
97
sreweekly/html/533-2026-09-07.html
Normal file
@@ -0,0 +1,97 @@
|
|||||||
|
<p><a class="email_only" href="https://sreweekly.com/sre-weekly-issue-533/">View on sreweekly.com</a></p>
|
||||||
|
|
||||||
|
<div class="sreweekly-sponsor-message" style="border: 1px solid #b0b0b0; width: 80%;">
|
||||||
|
<h2 style="text-align: center; font-size: 80%; color: #909090;">A message from our sponsor, <a href="https://sreweekly.com/link/533">Planetscale</a>:</h2>
|
||||||
|
<p>Most database incidents start with one expensive query, not the database being down. PlanetScale gives SRE teams high-availability Postgres and MySQL with automated failover, query insights, and Database Traffic Control to stop runaway queries before they page you.</p>
|
||||||
|
<p><a href="https://sreweekly.com/link/533">→ Explore PlanetScale</a></p>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
<div class="wp-block-group"><div class="wp-block-group__inner-container is-layout-flow wp-block-group-is-layout-flow">
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://greatcircle.com/blog/2026/08/04/detection-gap/" target="_blank">Incidents start before the response does</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>What can you do to shorten the time to detect an incident? Some great ideas in here, especially monitoring your company’s main web page for a sudden uptick in traffic.</p>
|
||||||
|
<p> <small>Brent Chapman</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://surfingcomplexity.blog/2026/08/16/quick-thoughts-on-azure-regional-outage-from-july-23-26/" target="_blank">Quick thoughts on Azure Regional Outage from July 23, ’26</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>What an interesting incident! I recommend reading Azure’s write-up before reading Lorin’s excellent analysis.</p>
|
||||||
|
<p> <small>Lorin Hochstein</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://dzone.com/articles/distributed-databases-coordination" target="_blank">Why Distributed Databases Fail at Coordination Boundaries</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<blockquote>
|
||||||
|
<p>Distributed databases rarely fail in the clean, isolated ways described by component diagrams. They fail through timing gaps, stale metadata, ambiguous ownership, retry storms, incompatible health decisions, and overlapping maintenance activity.</p>
|
||||||
|
</blockquote>
|
||||||
|
<p> <small> Varsha Ganesh — DZone</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://read.zerosevzero.com/p/the-record-says" target="_blank">The Record Says</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>I love this concept of a “political incident”:</p>
|
||||||
|
<blockquote>
|
||||||
|
<p>The subject was political incidents, by which I mean the ones where the severity arrives before the impact assessment does.</p>
|
||||||
|
</blockquote>
|
||||||
|
<p>And ouch, I felt this bit:</p>
|
||||||
|
<blockquote>
|
||||||
|
<p>You have spent forty minutes of the incident on the severity field.</p>
|
||||||
|
</blockquote>
|
||||||
|
<p> <small>Tim Irving</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://hackernoon.com/what-sres-should-automate-and-never-automate-with-ai" target="_blank">What SREs Should Automate — and Never Automate — with AI</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>Where can you safely use LLM agents, versus when you should keep things in human hands? This one has some good criteria to consider.</p>
|
||||||
|
<p> <small>Sai Joshitha Kathari — HackerNoon</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://www.datadoghq.com/blog/engineering/gitretriever/" target="_blank">20× the CI traffic without getting slower: How we rebuilt Git serving at Datadog</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>I learned a lot about Git while reading this one. Speeding up Git clones in CI may not seem important, but it will when you’re trying to roll out a fix during an incident.</p>
|
||||||
|
<p> <small>Mike Thompson and Daniel Esponda — Datadog</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://netflixtechblog.com/a-tale-of-two-flink-autoscalers-e9f6a1b1492b" target="_blank">A Tale of Two Flink Autoscalers</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>Switching from their custom-written autoscaler to the new off-the-shelf option made sense, but it wasn’t a simple drop-in replacement.</p>
|
||||||
|
<p> <small>Samuel Yeboah, Francesco Di Chiara and Mingliang Liu — Netflix</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
<div class="sreweekly-entry">
|
||||||
|
<div class="sreweekly-title"><a href="https://www.adaptivecapacitylabs.com/2026/08/24/there-is-more-to-code-review-than-automatable-detection/" target="_blank">There is more to code review than (automatable) detection</a></div>
|
||||||
|
<div class="sreweekly-description">
|
||||||
|
<p>Can we replace human code review with LLM-based reviews? This article lays out what an LLM can’t replicate, and I’d argue that these are the pieces that matter most for reliability.</p>
|
||||||
|
<p> <small>John Allspaw — Adaptive Capacity Labs</small></p>
|
||||||
|
</div>
|
||||||
|
</div>
|
||||||
|
</div></div>
|
||||||
@@ -1,21 +1,7 @@
|
|||||||
{
|
{
|
||||||
"feed": "https://sreweekly.com/feed/",
|
"feed": "https://sreweekly.com/feed/",
|
||||||
"last_scanned": "2026-09-10T07:40:50",
|
"last_scanned": "2026-09-12T18:37:33",
|
||||||
"issues": {
|
"issues": {
|
||||||
"533": {
|
|
||||||
"id": "533",
|
|
||||||
"title": "SRE Weekly Issue #533",
|
|
||||||
"url": "https://sreweekly.com/sre-weekly-issue-533/",
|
|
||||||
"pub_date": "2026-09-07",
|
|
||||||
"html_file": "html/533-2026-09-07.html",
|
|
||||||
"fetched_at": "2026-09-10T07:40:50",
|
|
||||||
"extracted": true,
|
|
||||||
"article_count": 8,
|
|
||||||
"markdown_dir": "markdown/533",
|
|
||||||
"extracted_at": "2026-09-10T20:30:06",
|
|
||||||
"articles_fetched": 7,
|
|
||||||
"articles_failed": 1
|
|
||||||
},
|
|
||||||
"532": {
|
"532": {
|
||||||
"id": "532",
|
"id": "532",
|
||||||
"title": "SRE Weekly Issue #532",
|
"title": "SRE Weekly Issue #532",
|
||||||
@@ -7991,6 +7977,17 @@
|
|||||||
"extracted_at": "2026-09-12T15:40:06",
|
"extracted_at": "2026-09-12T15:40:06",
|
||||||
"articles_fetched": 6,
|
"articles_fetched": 6,
|
||||||
"articles_failed": 1
|
"articles_failed": 1
|
||||||
|
},
|
||||||
|
"533": {
|
||||||
|
"id": "533",
|
||||||
|
"title": "SRE Weekly Issue #533",
|
||||||
|
"url": "https://sreweekly.com/sre-weekly-issue-533/",
|
||||||
|
"pub_date": "2026-09-07",
|
||||||
|
"html_file": "html/533-2026-09-07.html",
|
||||||
|
"fetched_at": "2026-09-12T18:37:33",
|
||||||
|
"extracted": false,
|
||||||
|
"article_count": 0,
|
||||||
|
"markdown_dir": null
|
||||||
}
|
}
|
||||||
}
|
}
|
||||||
}
|
}
|
||||||
@@ -0,0 +1,53 @@
|
|||||||
|
# 当声明事故成为大家最爱用的变通手段
|
||||||
|
|
||||||
|
- **期号**: SRE Weekly Issue #532(2026-08-31)
|
||||||
|
- **作者**: Brent Chapman
|
||||||
|
- **链接**: https://greatcircle.com/blog/2026/08/11/declaring-incidents-for-side-effects/
|
||||||
|
|
||||||
|
## 简介
|
||||||
|
|
||||||
|
需要另一个团队立刻办事?一个神奇小技巧就能搞定:声明一次事故!这篇文章解释了为什么显而易见的解法(限制事故声明)并不是个好主意。
|
||||||
|
|
||||||
|
## 正文
|
||||||
|
|
||||||
|
你看到有人声明了一次 Sev-2 事故,于是好奇:等等,这为什么算事故?什么都没宕,客户也没受影响。但原来是一位经理需要把自己团队的问题推到另一个团队的优先级队列最前面,而事故流程恰好是达成这一目的最可靠的方式。这并非事故流程的本意,但它管用,那又有什么坏处呢?
|
||||||
|
|
||||||
|
问题在于,一旦大家发现这招好使,它就会越来越频繁地发生。产品经理声明事故,是因为事故通知是把问题送到领导面前最快的方式——这个问题已经在积压清单里躺了几个星期。客户团队声明事故,是因为他们需要工程支持来搞定一次面向重要潜在客户的大型演示,而事故流程是短期内把工程师从冲刺开发里拉出来最简单的方式。工程师声明事故,是因为这比走正式的变更冻结豁免流程容易得多。
|
||||||
|
|
||||||
|
损害是累积性的。当所声明的"事故"里越来越大的比例并非真正的紧急情况,紧急信号本身就会退化。当真正的 Sev-1 到来时,人们响应得不再那么紧张,因为他们已经被训练得预期这又是一个变通伎俩。而且激励会自我强化:钻流程空子的人能更快解决自己的问题,这教会了所有人——钻空子才是办事之道。每一次单独的声明都是一个需要办成事的人做出的可以理解的决定;是这些行为的叠加在腐蚀流程本身。
|
||||||
|
|
||||||
|
每一次非紧急声明都依然承担着一次真实事故的全部开销。响应者被从计划内的工作中拉出来。有人放下手头一切去当事故指挥。干系人切换上下文来跟进事态。当你运转足够多的这类"事故"时,团队就有可观比例的时间花在紧急模式上,而实际上并没有紧急情况——事故的所有间接成本(项目被打断、上下文切换、恢复时间)一样样照收。
|
||||||
|
|
||||||
|
这里有一个讽刺之处:人们之所以去用事故流程,恰恰是因为它管用;他们亲眼看到它能按需稳定地交付协调、优先级和紧迫感。
|
||||||
|
|
||||||
|
## 本能反应是错的
|
||||||
|
|
||||||
|
当公司注意到这个模式,本能反应往往是收紧声明标准。他们加上把关:也许声明事故需要经理批准,或者必须先完成一份事前检查清单,又或者事后有人审查这次声明是否"正当"。意图是合理的,综合效果却是腐蚀性的。
|
||||||
|
|
||||||
|
给事故声明设置门槛是适得其反的。你设置的每一个减速带,同样会拖慢真正的事故。因为不确定问题是否"够严重"而犹豫是否声明——这本来就是事故响应里最常见的失败模式。再加一道正式审批步骤,或者事后审查声明是否合理,只会让这种犹豫变得更糟,而不是更好。
|
||||||
|
|
||||||
|
你也错过了钻空子行为在告诉你的事:人们伸手去用事故流程,说明你的常规流程已经不够用了。如果只打击钻空子,你只是压制了症状,而没有从中学到任何东西,底层问题会继续存在。
|
||||||
|
|
||||||
|
## 修复逃脱路径,而不是惩罚逃跑者
|
||||||
|
|
||||||
|
换个思路:看看人们在声明可疑事故时想触发哪些副作用,然后把这些能力用其他途径提供出来。
|
||||||
|
|
||||||
|
如果绕过变更冻结最简单的办法是声明事故,那就为紧急变更建立一个非事故的豁免流程。这不必复杂;一个由指定发布管理员做的轻量审批,加上清晰的升级路径,就能覆盖大多数情况。
|
||||||
|
|
||||||
|
如果把自己问题挪到另一个团队优先级队列最前面最简单的办法是声明事故,那就创建一个不需要事故的优先级升级路径。跨团队的工单分诊会议、一个明确的加急请求机制,甚至一个相关人士真的会盯着的专属 Slack 频道,都能吸收掉大部分压力。门槛不必高到"宣布紧急状态",只要低于"等六个星期直到下一个规划周期"就行。
|
||||||
|
|
||||||
|
如果短时间内聚集跨职能团队最简单的办法是走事故流程,那就为非事故场景创建一个轻量协调机制。有些公司称之为"蜂群"(swarm)、"老虎队"或"协调请求"。叫什么名字不重要;重要的是人们有一条路能拿到所需的协作,而不必借用事故流程。
|
||||||
|
|
||||||
|
反复钻事故流程的空子来获取资源优先级或跨职能协调,不是一系列一次性的变通手段;它是一个系统性问题表现出来的症状,需要系统性的回应。Google 的 SRE 组织为此建立了正式的 [Code Yellow 和 Code Red](https://www.theengineeringmanager.com/growth/code-yellow-code-red/) 机制:当一个问题的严重程度足以要求跨职能关注、但还不构成事故时,用结构化的方式来调集资源、提升优先级。
|
||||||
|
|
||||||
|
## 诊断性问题
|
||||||
|
|
||||||
|
回顾你最近十来次事故,逐一自问:这次声明是因为发生了紧急情况,还是因为事故流程是拿到团队所需东西的更省事的路径?
|
||||||
|
|
||||||
|
你不需要正式的审计。找几位有经验的事故指挥和值班工程师聊聊;他们早就知道哪些是真的、哪些不是。然后去和那些声明了可疑事故的人谈谈(当然是本着无指责、摆事实的态度)。如果你愿意听,他们会准确地告诉你常规流程里缺了什么。
|
||||||
|
|
||||||
|
人们钻事故流程的空子只是症状。底层问题通常是常规流程太僵化、太慢、太不敏感,事故流程成了阻力最小的路径。修复底层问题,钻空子自然停止,因为再也没有什么可钻的了。你的事故紧急信号恢复如初,团队不再把紧急模式的周期烧在不紧急的事情上,当真正的 Sev-1 到来时,人们会像对待重要事件一样去响应它。
|
||||||
|
|
||||||
|
而如果你正在处理这个问题,请花点时间欣赏一下这说明了什么:人们借用事故流程,是因为它*管用*。修复之道不是让它失效,而是让其他一切也都像它一样好使。
|
||||||
|
|
||||||
|
## 最新评论
|
||||||
@@ -0,0 +1,302 @@
|
|||||||
|
# 调优 conntrack 垃圾回收,解决神秘的 Kubernetes Pod 启动超时
|
||||||
|
|
||||||
|
- **期号**: SRE Weekly Issue #532(2026-08-31)
|
||||||
|
- **作者**: Jorrick Sleijster — Adyen
|
||||||
|
- **链接**: https://www.adyen.com/knowledge-hub/inside-cilium-cni-solving-kubernetes-pod-setup-timeouts
|
||||||
|
|
||||||
|
## 简介
|
||||||
|
|
||||||
|
哇哦。距离我上次撞上一张爆满的 conntrack 表已经好几年了,这次又是个有趣的新花样。
|
||||||
|
|
||||||
|
## 正文
|
||||||
|
|
||||||
|
[Knowledge Hub](https://www.adyen.com/knowledge-hub)
|
||||||
|
|
||||||
|
文章
|
||||||
|
|
||||||
|
# Cilium CNI 内幕:破解神秘的 Kubernetes Pod 启动超时
|
||||||
|
|
||||||
|
深度剖析 Adyen 数据平台工程团队如何调查并解决 Cilium CNI 连接跟踪垃圾回收中的线性时间扩展瓶颈,修复高资源节点上神秘的 Kubernetes Pod 启动超时。
|
||||||
|
|
||||||
|
一年前我就很清楚:一行配置就能搞垮 Kubernetes 的整个网络栈。但如果有人告诉我,几小时前就已终止的 Pod 留下的残余物能阻止新 Pod 启动,我会以为他们在开玩笑。
|
||||||
|
|
||||||
|
在高性能网络里,35 秒就是一辈子。这是以每秒最多 20 万条的速度遍历我们 700 万条连接跟踪表所需的时间。在我们的 1600 万条峰值下,这种顺序查找可能长达 80 秒,导致 Cilium CNI 超时,新 Pod 无法在受影响的节点上启动。
|
||||||
|
|
||||||
|
我们在 Adyen 通过跟踪系统调用、查阅代码库和分析 eBPF 内部机制,发现了这个线性时间行为。这次调查揭示了我们的多样化负载如何把连接跟踪表的垃圾回收算法变成了关键瓶颈。
|
||||||
|
|
||||||
|
## 我们的环境:为什么我们不一样
|
||||||
|
|
||||||
|
在 Adyen,我们在全部 100 多个 Kubernetes 集群上运行 Cilium CNI。从 Calico 切换到 Cilium 时,我们就知道要让它适配生产负载会面临挑战。与 Adyen 内部的其他 Kubernetes 环境相比,我们的生产大数据集群有一个独特的使用模式:
|
||||||
|
|
||||||
|
**从 HDFS 提取数据**。我们的基础设施依赖超过 500 个数据节点。Trino 是我们对 HDFS 压力最大的工作负载之一,它对存储在 HDFS 上的数据执行分析查询。由于 HDFS 的分布式特性,每下载一个文件都需要与这 500 个节点中的任意一个建立新连接。因此,高峰时段单个 Pod 每分钟可产生约 5 万条连接。
|
||||||
|
|
||||||
|
**Pod 频繁更替**。我们在集群上启动的很多 Pod 运行的是批处理任务,比如 Spark 任务。它们存活时间从 1 秒到几个小时不等。
|
||||||
|
|
||||||
|
**工作负载种类繁多**。有些工作负载极其消耗 CPU,比如执行复杂 join 和转换的 Spark Pod,但网络连接相对较少。另一些则网络极其密集,比如 Trino Pod 查询 HDFS 上成千上万的小文件,每个文件都需要新连接。这产生了大量短命连接,给连接跟踪表造成巨大压力。
|
||||||
|
|
||||||
|
此外,我们的机器比 Adyen 内部大多数 Kubernetes 集群的机器更强大:
|
||||||
|
|
||||||
|
- 64 物理核、512GB 内存的机器
|
||||||
|
- 128 物理核、2TB 内存的机器
|
||||||
|
|
||||||
|
当时我们的环境是 Kubernetes 1.31.7 和 Cilium 1.16.5。我们给出这些具体版本,方便感兴趣的读者把我们的发现与相关代码对应起来。
|
||||||
|
|
||||||
|
为了支撑我们独特的工作负载,我们逐步调优了 Cilium:加大 DNS 代理超时、扩大连接跟踪表容量、提高 API 限流阈值、精简"安全标签"。这套配置让我们克服了一个又一个挑战,除了一件事:
|
||||||
|
|
||||||
|
**`Failed to create pod sandbox: rpc error: code = Unknown desc = failed to setup network for sandbox "0fecf4844d3f8f2df218f09d91f9698bb424e2166551952f46fd7638f4757cf2": plugin type="cilium-cni" failed (add): unable to create endpoint: Cilium API client timeout exceeded`**
|
||||||
|
|
||||||
|
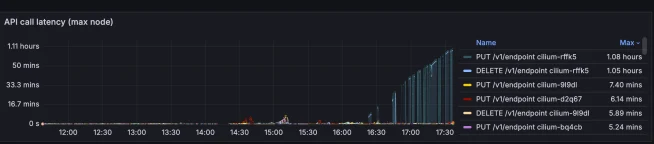
Kubernetes 会创建 Pod、启动沙箱,然后尝试用 Cilium 配置网络。这个操作会超时。从那一刻起,同一节点上任何其他 Pod 的启动都会跟着超时。此外我们注意到,在受影响的节点上,DELETE /v1/endpoint 和 PUT /v1/endpoint 这两个负责添加和删除 Cilium endpoint 的路由,其 API 耗时也增加了。从下面的图中可以清楚地看到:从下午 4:20 开始,endpoint 调用时延随时间线性增长,说明 endpoint 的创建和删除永远无法完成。
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
需要说明的是,这些集群只用于分析处理和大数据负载。这个问题在违反任何 SLO 之前就被发现、分析并彻底解决。此外,由于我们的大数据环境与核心交易链路隔离,这个问题从未影响我们的实时支付处理管道或商户交易。
|
||||||
|
|
||||||
|
## 症状:出了点问题,但出了什么问题?
|
||||||
|
|
||||||
|
首先,我们在 Cilium Agent 日志里没有找到相关超时。我们开启了 debug 日志,希望能找到隐藏的错误。什么都没有。日志给了我们宏观图景,却没有揭示瓶颈。
|
||||||
|
|
||||||
|
但我们确实从调试故障节点中学到了一些有价值的东西:
|
||||||
|
|
||||||
|
- 列出故障节点上的所有 endpoint 会超时:cilium endpoint list
|
||||||
|
- 列出某个 endpoint 的日志正常,并且显示该 endpoint 卡在 regenerating 阶段:cilium endpoint log <ENDPOINT_ID>
|
||||||
|
- 用 kubectl get ciliumendpoint 请求 endpoint 状态显示它仍在 regenerating,而 endpoint 的 Kubernetes manifest 显示为 ready 状态
|
||||||
|
- 检查 /var/run/cilium/state 下的文件系统,发现 endpoint 文件夹带有 _next 后缀,表明它们没有成功完成
|
||||||
|
|
||||||
|
这证实了我们的猜测:问题出在 Cilium agent 层,而不是 kubelet 或 CNI 插件层。但为什么,我们仍然不知道。
|
||||||
|
|
||||||
|
## 幕后:Cilium 如何为一个 Pod 配置网络
|
||||||
|
|
||||||
|
在深入调试之前,有必要了解当 Pod 启动、Cilium 为其配置网络时会发生什么。
|
||||||
|
|
||||||
|
整个过程从 Kubernetes 把 Pod 分配到某个节点开始。kubelet 发起 Pod 设置,调用配置好的 CNI 插件(在我们这里是 Cilium)。Cilium CNI 插件执行若干操作:
|
||||||
|
|
||||||
|
1. **使用 IPAM(IP 地址管理)分配一个 IP**
|
||||||
|
2. **创建链路设备**(我们的配置中是 veth 对:一端在主机的网络命名空间,一端在 Pod 里)
|
||||||
|
3. **配置 Pod 网络**:设置 IP 地址、配置路由、设置 sysctl 参数
|
||||||
|
4. **通过 Cilium agent API 创建一个 Cilium endpoint**
|
||||||
|
5. **使用 Pod 标签检索或分配安全身份**
|
||||||
|
6. **为该 endpoint 计算网络策略**
|
||||||
|
7. **生成、编译并注入 eBPF 代码**到内核
|
||||||
|
8. **向 kubelet 返回成功**
|
||||||
|
|
||||||
|
关键要理解的是:创建 Pod(也就是创建 endpoint)时,CNI 插件会调用 Cilium agent——它以 DaemonSet 的形式运行在每个节点上。agent 承担繁重的工作:管理 eBPF map、处理连接跟踪、应用网络策略,等等。
|
||||||
|
|
||||||
|
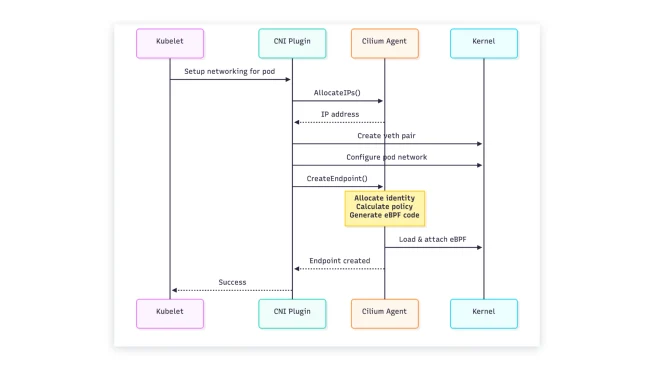
以下是流程的简化视图:
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
这个过程中至关重要的一步发生在创建 endpoint 时:Cilium 会触发连接跟踪表的垃圾回收,以验证 Pod 的 IP 没有残留上次运行留下的连接。scrubIPsInConntrackTable 函数执行这一操作:扫描整张连接跟踪表,找出并删除相关条目。
|
||||||
|
|
||||||
|
垃圾回收失败的后果很严重。过期条目会无限制累积;虽然我们的表可以容纳多达 1600 万条,但真正的瓶颈在于每个新 Pod 都必须做的那次强制扫描。这个清理步骤对缓解 IP 地址重用冲突至关重要,确保新 Pod 不会继承前一个 Pod 的任何开放连接。
|
||||||
|
|
||||||
|
我们的故事从这里才真正开始。
|
||||||
|
|
||||||
|
*注:* [Arthur Chiao 对 Cilium CNI 实现的精彩深潜](https://arthurchiao.art/blog/cilium-code-cni-create-network/) *为我们理解 CNI 流程提供了大部分基础。虽然 Arthur Chiao 是几年前写的,但核心概念仍然适用,对任何想理解 Cilium 内部机制的人来说都是无价资源。*
|
||||||
|
|
||||||
|
## 深入兔子洞:追踪根因
|
||||||
|
|
||||||
|
### agent 到底在做什么?
|
||||||
|
|
||||||
|
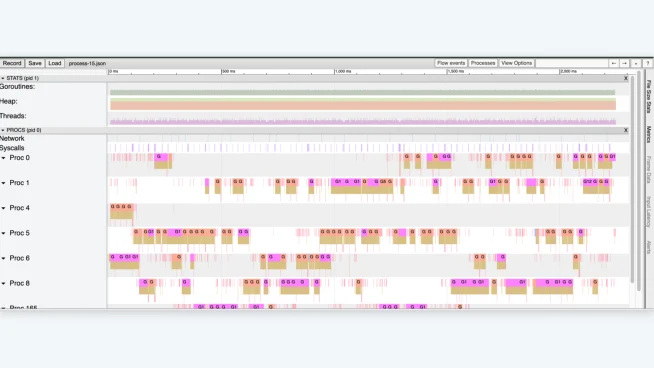
我们需要看到 Cilium agent 挂起时在做什么。于是请出 pprof——Go 自带的分析器。我们在 Cilium 配置里启用了 pprof,并在一个故障节点上 spawn 50 个 Pod 后立即抓取 trace。
|
||||||
|
|
||||||
|
CPU 和内存 profile 一开始没暴露什么。但当我们打开执行 trace,时间线视图精确显示了每个 goroutine 在做什么,一切豁然开朗。
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
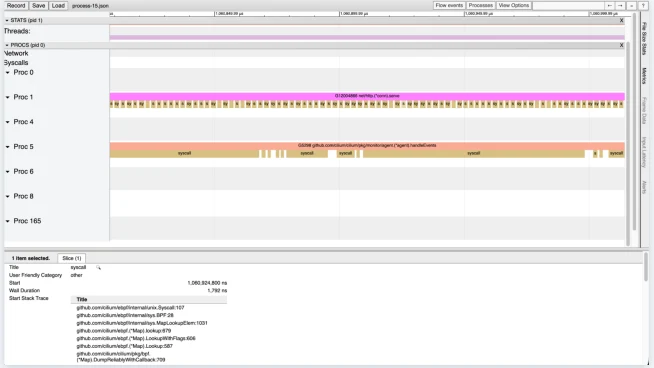
我们看到长时间运行的 goroutine 把全部时间花在系统调用上。放大之后,模式浮现了:
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
agent 在一个紧密循环里做 BPF 系统调用:nextKey()、lookup()、nextKey()、lookup(),一遍又一遍。agent 用这些系统调用遍历 eBPF map:
|
||||||
|
|
||||||
|
1. **nextKey(currentKey)** — 获取 BPF map 中 currentKey 之后的下一个 key
|
||||||
|
2. **lookup(key)** — 获取与 key 关联的值
|
||||||
|
|
||||||
|
我们来算笔账。我们选取了一段 35 毫秒的片段,数出 14,916 次系统调用。也就是每秒 426,171 次系统调用。由于从 eBPF map 取每个元素需要两次系统调用(next + get),我们每秒大约遍历 21.3 万条。
|
||||||
|
|
||||||
|
由于 Cilium 是用户态进程,每次通过系统调用访问或操作 map 都会引发一次上下文切换。上下文切换就是 CPU 暂时挂起用户态进程(Cilium)、进入内核执行代码(处理 BPF 系统调用)、再恢复用户态进程的过程。这涉及保存和恢复 CPU 寄存器与内存空间的全部状态,开销巨大,是延迟的主要来源。
|
||||||
|
|
||||||
|
这里的关键洞见是:这是一个顺序操作。你无法并行化,因为需要当前 key 才能拿到下一个 key。即使在我们的强力服务器 CPU 上,这也已经是我们能达到的最大速度。trace 里还有一个重要细节:这一切发生在 scrubIPsInConntrackTable 函数里——就是创建 endpoint 时清理连接跟踪表的那个函数。
|
||||||
|
|
||||||
|
## 为什么这么多系统调用?连接跟踪表
|
||||||
|
|
||||||
|
这时我们想起了在 cilium status --verbose 里看到的东西:
|
||||||
|
|
||||||
|
```
|
||||||
|
BPF Maps: dynamic sizing: on (ratio: 0.005000)
|
||||||
|
Name Size
|
||||||
|
TCP connection tracking 16777216
|
||||||
|
Non-TCP connection tracking 14232516
|
||||||
|
...
|
||||||
|
```
|
||||||
|
|
||||||
|
我们的 TCP 连接跟踪表最大容量 1600 万条,是 2TB 内存机器默认值 800 万条的两倍。几个月前,我们刻意在 Helm Chart 里配置了 `cilium_bpf_map_dynamic_size_ratio: 0.0050`,预期连接跟踪容量会随各节点类型的内存按比例扩展。当时这是一次有计划的扩容调整,为了防止 512GB 内存机器在高吞吐负载下连接跟踪耗尽。这个配置按预期支撑了我们独特的工作负载演进,但随着流量增长,更大的表与垃圾回收自动扩缩算法在 2TB 高资源节点上的交互,催生了一个新的扩展挑战。
|
||||||
|
|
||||||
|
但表里实际有多少条目?我们用 `cilium bpf ct list global` 列了出来,显示约 700 万条。但有意思的是:当我们把 expires 字段的时间戳和系统运行时间对照,发现绝大多数条目早已过期,有的已经过期好几个小时。这把我们的目光直接引向垃圾回收机制。
|
||||||
|
|
||||||
|
现在算账变得有意思了:
|
||||||
|
|
||||||
|
- 最大遍历速度:约每秒 20 万条
|
||||||
|
- 当前表规模:700 万条
|
||||||
|
- 遍历当前表耗时:35 秒
|
||||||
|
- 最大表规模:1600 万条(最坏情况)
|
||||||
|
- 遍历整张表耗时:80 秒
|
||||||
|
|
||||||
|
也就是说,每次创建或删除一个 endpoint,我们都要花最多 35 秒遍历连接跟踪表,最坏情况最多 80 秒。别忘了我们的 CNI 超时上限是 90 秒。
|
||||||
|
|
||||||
|
但等等,如果条目已经过期,为什么垃圾回收器不清理它们?
|
||||||
|
|
||||||
|
## 为什么过期条目没被清理?出了岔子的垃圾回收
|
||||||
|
|
||||||
|
Cilium 为连接跟踪表提供了垃圾回收。看指标,GC 触发得非常频繁:
|
||||||
|
|
||||||
|
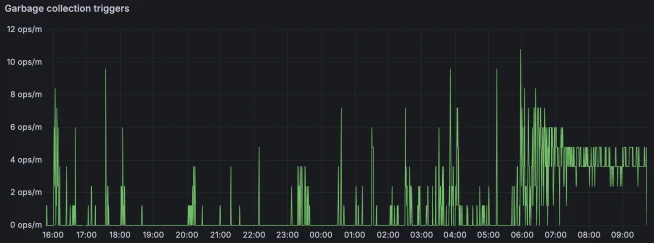
|
||||||
|
|
||||||
|
但当我们看垃圾回收器实际删了什么,问题出现了:
|
||||||
|
|
||||||
|
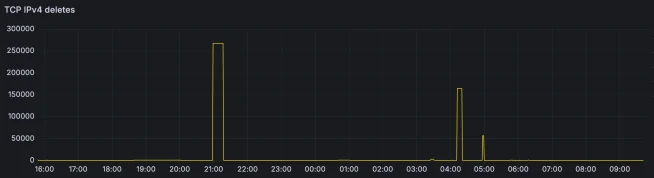
|
||||||
|
|
||||||
|
垃圾回收器频繁运行,但大部分时间几乎什么都不删。只有偶尔会删除大量条目。
|
||||||
|
|
||||||
|
深入代码后,原因浮出水面。Cilium 有两种 GC 操作:
|
||||||
|
|
||||||
|
1. **Endpoint 专属清理**:创建或删除 endpoint 时,清理匹配该 endpoint IP 的条目
|
||||||
|
2. **周期性过期条目清理**:按时间间隔运行,删除所有过期条目
|
||||||
|
|
||||||
|
指标中几乎所有的频繁 GC 都是 Pod 创建和删除触发的(第 1 类 endpoint 专属清理)。而删除过期条目的周期性清理(第 2 类)几乎没怎么跑。
|
||||||
|
|
||||||
|
为什么?因为 GC 间隔根据删除量自动扩缩:
|
||||||
|
|
||||||
|
```go
|
||||||
|
// 从 Cilium 源码简化
|
||||||
|
func GetInterval(interval time.Duration, maxDeleteRatio float64) time.Duration {
|
||||||
|
if maxDeleteRatio > 0.25 {
|
||||||
|
// 删除了超过 25% 的条目 → 更频繁地 GC
|
||||||
|
interval = time.Duration(float64(interval) * (1.0 - maxDeleteRatio))
|
||||||
|
} else if maxDeleteRatio < 0.05 {
|
||||||
|
// 删除了不到 5% 的条目 → 降低 GC 频率
|
||||||
|
interval = time.Duration(float64(interval) * 1.5)
|
||||||
|
}
|
||||||
|
if interval > ConntrackGCMaxLRUInterval {
|
||||||
|
interval = ConntrackGCMaxLRUInterval // 12 小时
|
||||||
|
}
|
||||||
|
return interval
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
一张 1600 万条的表,问题就在这里:
|
||||||
|
|
||||||
|
- 要删除超过 5%(避免变慢),你需要删除 80 万+ 条
|
||||||
|
- 要删除超过 25%(加快频率),你需要删除 400 万+ 条
|
||||||
|
- 起始间隔:5 分钟
|
||||||
|
- 最大间隔:12 小时
|
||||||
|
|
||||||
|
想象这个场景:
|
||||||
|
|
||||||
|
1. 节点刚上线或只跑轻量负载时,连接量一开始很低
|
||||||
|
2. 垃圾回收器一次运行删除的条目不到 5%,无法触发更频繁的周期
|
||||||
|
3. GC 间隔从几分钟开始逐步拉长,直到达到 12 小时上限。它从 7.5 分钟开始,涨到 11.25 分钟,再到 16.875 分钟,一路涨到 12 小时
|
||||||
|
4. 最终重型数据负载落到这个节点上,产生大量网络流量
|
||||||
|
5. 新连接持续填充跟踪表长达 12 小时,垃圾回收器才会再跑一次
|
||||||
|
|
||||||
|
等到垃圾回收最终执行时,连接跟踪表可能已经累积了多达 1600 万条过期条目。虽然这次 GC 可能删掉足够多的记录、暂时恢复速度,但周期之间过长的间隔本身就问题重重。这种滞后让表再次积满过期条目,迫使上一次 GC 之后漫长间隔内创建的每个 Pod 都承受一次全表顺序扫描的惨重性能代价。
|
||||||
|
|
||||||
|
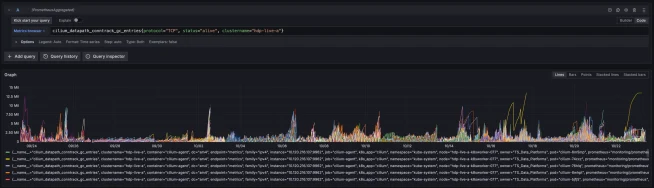
|
||||||
|
|
||||||
|
## 为什么会雪崩?互斥锁、超时与重试
|
||||||
|
|
||||||
|
单个 Pod 启动缓慢已经够烦人了,但多个 Pod 同时启动时,问题急剧升级。
|
||||||
|
|
||||||
|
我们用 gops 抓取了 Cilium agent 的 goroutine dump,用一个按相似堆栈分组的脚本分析。结果很能说明问题:
|
||||||
|
|
||||||
|
```
|
||||||
|
- 57 次出现:
|
||||||
|
createEndpoint() → WaitForFirstRegeneration() → 等待 RWMutex
|
||||||
|
- 57 次出现:
|
||||||
|
regenerateBPF() → runPreCompilationSteps() → invoked
|
||||||
|
- 56 次出现:
|
||||||
|
scrubIPsInConntrackTable() → garbageCollectConntrack() → 等待 Lock
|
||||||
|
```
|
||||||
|
|
||||||
|
连接跟踪表上有一把**全局互斥锁**。当我们同时 spawn 50 个 Pod 时:
|
||||||
|
|
||||||
|
- Pod 1 拿到锁,开始 80 秒的表遍历
|
||||||
|
- Pod 2-50 排队等锁
|
||||||
|
- Pod 1 在 80 秒后完成
|
||||||
|
- Pod 2 拿到锁,开始又一次 80 秒遍历
|
||||||
|
- 但 Pod 2 的计时器 80 秒前就开始计时了 → 90 秒时超时
|
||||||
|
- Pod 2 超时
|
||||||
|
- Pod 3-50 根本没有机会
|
||||||
|
|
||||||
|
更糟的还在后面。CNI 在 90 秒超时之后:
|
||||||
|
|
||||||
|
- 超时向调用方返回一个错误
|
||||||
|
- **但底层工作并不会停止**:agent 仍在继续遍历
|
||||||
|
- 容器运行时(containerd)立即调用 DeleteEndpoint()
|
||||||
|
- Delete 同样需要遍历 conntrack 表
|
||||||
|
- 于是系统同时排队了创建和删除操作
|
||||||
|
|
||||||
|
然后 Kubernetes 重试:
|
||||||
|
|
||||||
|
- kubelet 的 *podWorkerLoop* 在 60-90 秒后重试(带抖动)
|
||||||
|
- 每次重试又往队列里加一次 endpoint 创建和删除请求
|
||||||
|
- 队列的增长速度超过排空速度
|
||||||
|
|
||||||
|
这些在日志里都能看到。对于 cilium-node-breaker-5 这个 Pod,我们看到了:
|
||||||
|
|
||||||
|
- 15:54:30 - 创建 endpoint(第 1 次尝试)
|
||||||
|
- 15:56:00 - 删除 endpoint(超时)
|
||||||
|
- 15:57:12 - 创建 endpoint(第 2 次尝试)
|
||||||
|
- 15:59:57 - 创建 endpoint(第 3 次尝试)
|
||||||
|
- 16:02:39 - 创建 endpoint(第 4 次尝试)
|
||||||
|
|
||||||
|
节点进入争用循环:新任务到来的速度超过旧任务完成的速度,队列永远排不空。
|
||||||
|
|
||||||
|
完整图景如下:
|
||||||
|
|
||||||
|
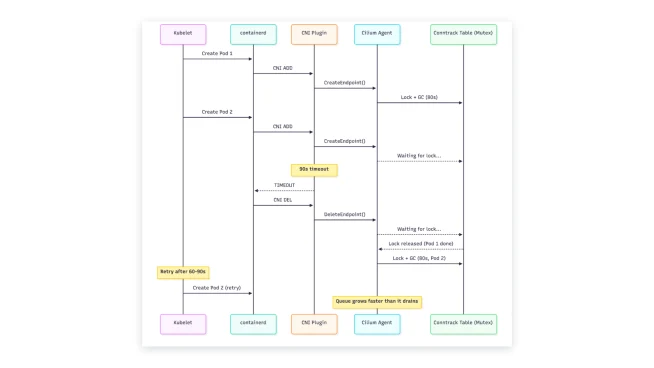
|
||||||
|
|
||||||
|
## 修复:一行搞定一切
|
||||||
|
|
||||||
|
经过所有这些调查,修复之简单令人扫兴。我们不能依赖自动扩缩的 GC 间隔,因为在安静的节点上它不可避免地会拉得太长。因此我们通过设置固定值,禁止 GC 间隔自动扩缩:
|
||||||
|
|
||||||
|
```
|
||||||
|
conntrackGCInterval: 60s
|
||||||
|
```
|
||||||
|
|
||||||
|
就这样。一行配置确保垃圾回收至少每分钟跑一次,无论它删了多少。我们上午 9:00 应用变更,10:00 完成 DaemonSet 滚动。结果不言自明:
|
||||||
|
|
||||||
|
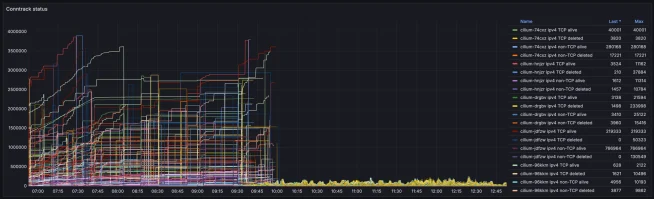
|
||||||
|
|
||||||
|
conntrack 表大小急剧下降并保持稳定。更重要的是,API 调用耗时恢复正常:
|
||||||
|
|
||||||
|
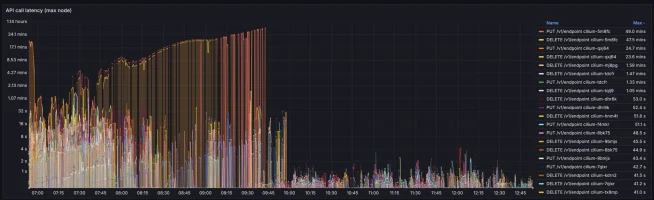
|
||||||
|
|
||||||
|
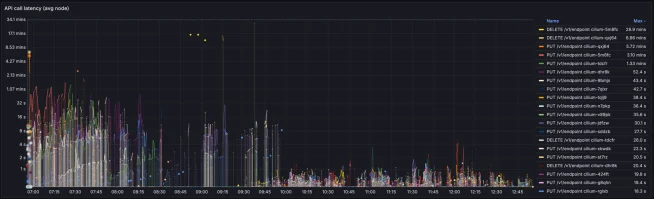
|
||||||
|
|
||||||
|
修复之后,我们再没看到一次超时错误。Pod 启动时间恢复可靠。
|
||||||
|
|
||||||
|
## 经验教训
|
||||||
|
|
||||||
|
**扩缩参数可能存在长尾交互。** 我们主动调整 bpf_map_dynamic_size_ratio 以支撑 512GB 内存机器的工作负载扩展,成功解决了最初的容量上限。但随着分析负载演进、流量增加,2TB 内存机器上动态分配出的更大表规模,暴露出它与 CNI GC 自动扩缩算法之间微妙的交互。这类扩缩参数可能要几个月、随着流量模式增长才会显现全部影响,尤其是在存在自适应后台循环的环境里。
|
||||||
|
|
||||||
|
**可观测性与全栈理解至关重要。** 日志能显示症状,但我们需要 profiling 和 tracing 才能揭示整个技术栈上的根因。容器运行时(超时、删除行为)、CNI 插件(超时值)、Cilium agent(互斥锁、GC 逻辑)和 Linux 内核(eBPF map、系统调用性能)都与理解 Pod 启动超时的成因相关。此外,用真实数字做粗略估算(napkin math)威力巨大。一旦我们拿到关键数字——每秒 20 万次系统调用、1200 万条表条目、90 秒超时——远在理解完整链条之前我们就锁定了根因。永远度量系统真实的性能特征,而不是只盯着理论极限。
|
||||||
|
|
||||||
|
**自动扩缩算法需要边界。** Cilium 的 GC 间隔自动扩缩对大多数部署是合理的:删除得多就多跑 GC,删得少就少跑以省 CPU。但算法没有考虑负载多变的情况:一台机器长期连接量很低,之后引入一个 Pod 就可能迎来极高的连接量。算法也没有考虑超大的表,在那里"5% 的条目"是个巨大的绝对数字。12 小时的最大间隔对我们的负载来说太长了。不仔细推敲边界情况的自动扩缩可能适得其反。
|
||||||
|
|
||||||
|
**超时并不会停止工作。** 当 CNI 超时时,我们以为工作会停止。并没有。agent 在后台继续处理,新的请求不断入队。这是分布式系统中的常见模式:超时保护的是调用方,但不一定会取消操作。需要时请显式地做取消。
|
||||||
|
|
||||||
|
**把 conntrack 健康当作一等运维指标。** 健康集群与争用循环的区别,清楚地体现在一些我们原本没盯的指标上:
|
||||||
|
|
||||||
|
- GC 耗时 - cilium_datapath_conntrack_gc_duration_seconds - 从 1 秒跳到 80 秒
|
||||||
|
- 表大小 - cilium_datapath_conntrack_gc_entries - 700 万条,大部分已过期
|
||||||
|
|
||||||
|
对于任何跑动态负载的 Cilium 部署,我们都建议主动对这两个指标告警,并设置 `conntrackGCInterval: 60s`。不要为了安静期的 CPU 节省,牺牲繁忙期的 Pod 启动稳定性。
|
||||||
|
|
||||||
|
## 结论
|
||||||
|
|
||||||
|
最终,一行配置解决了那个影响我们大数据平台新 Pod 启动的神秘超时:conntrackGCInterval: 60s。调查揭示,Pod 超时的根因是 Cilium 自动扩缩的垃圾回收算法——它允许清理间隔一直涨到 12 小时,导致过期条目大规模堆积,落入线性时间遍历的陷阱。
|
||||||
|
|
||||||
|
这次经历在系统弹性与全栈理解的必要性上给了我们重要启示。我们学到,扩缩参数和资源分配存在长尾交互,往往要几个月后随工作负载演进才浮出水面。我们还发现,自动扩缩算法需要严格的边界,以防止边缘情况下的意外性能退化——比如我们高资源机器上起伏不定的连接量。调查还强调,超时往往只保护调用方,不会停止底层工作,可能触发重试的争用循环——而这类问题只能靠对互斥锁、系统调用和 eBPF 内部机制的深度可观测性才能诊断。
|
||||||
|
|
||||||
|
展望未来,我们必须自问:基础设施里那些自适应行为到底是在保护我们,还是在掩盖只在峰值容量下才显现的低效?把 conntrack 健康当作一等运维指标、把可靠性置于微不足道的 CPU 节省之上,我们就能构建更健壮的系统。还有,记住:如果你在 CNI 里看到神秘超时——有时候答案就藏在每秒 42.6 万次系统调用里。
|
||||||
@@ -0,0 +1,51 @@
|
|||||||
|
# 大规模存储:我每天真正盯着的指标
|
||||||
|
|
||||||
|
- **期号**: SRE Weekly Issue #532(2026-08-31)
|
||||||
|
- **作者**: Sridhar Rajarao
|
||||||
|
- **链接**: https://sridharrajarao.com/blog/storage-at-scale/
|
||||||
|
|
||||||
|
## 简介
|
||||||
|
|
||||||
|
> 八年里,我为一套以 EB(艾字节)计量的存储系统做 SRE。我每天早晨查看的仪表盘最终缩减到七个数字。就是它们。
|
||||||
|
|
||||||
|
## 正文
|
||||||
|
|
||||||
|
八年里,我领导着支撑一套以 EB 计量的存储系统的 SRE 团队。随着时间推移,我每天早晨检查的仪表盘缩减到了一小撮数字。下面就是告诉我服务是否健康的七个指标。
|
||||||
|
|
||||||
|
可用性(Availability)告诉你系统是否在线。持久性(Durability)告诉你数据是否还在。两者不是一回事。
|
||||||
|
|
||||||
|
先看速览版。
|
||||||
|
|
||||||
|
| KPI | 衡量什么 | 我们如何跟踪 |
|
||||||
|
|---|---|---|
|
||||||
|
| 可用性 | 请求成功百分比 | 每个区域、每个服务 99.99% |
|
||||||
|
| 持久性 | 数据存活的概率 | 11 个 9(年损失率 10^-11) |
|
||||||
|
| TTFB | 返回首字节时间 | 按对象大小分桶的 p50、p95、p99 时延 |
|
||||||
|
| 金丝雀 | 合成测试流量 | 每个区域持续 PUT/GET |
|
||||||
|
| 热点 | 存储节点间的倾斜程度 | 前 N 节点负载对比集群中位数 |
|
||||||
|
| IOPS | 每秒操作数 | 每个分片、每块磁盘的读写 IOPS |
|
||||||
|
| DB 分片 | 元数据分区健康 | 分片 CPU、滞后、热键偏斜 |
|
||||||
|
|
||||||
|
## 可用性与持久性是两条不可妥协的底线
|
||||||
|
|
||||||
|
可用性就是正常运行时间。持久性关乎数据能否存活。你可以做到 100% 可用却丢了数据;你也可以做到 100% 持久却离线不可用。客户两者都在乎。我们用纠删码把每个对象写入多个可用区,达到了 11 个 9 的持久性,并且每月用一次恢复演练来证明它。
|
||||||
|
|
||||||
|
## TTFB 才是用户真正感受到的东西
|
||||||
|
|
||||||
|
整体可用性会掩盖慢尾部。一个 99.99% 可用、但 p99 TTFB 达 2 秒的服务,用起来就像坏了一样。永远按对象大小分桶跟踪时延。10 MB 的读取请求不应该和 100 字节的 HEAD 请求共享同一条 SLO。
|
||||||
|
|
||||||
|
## 金丝雀才是真相
|
||||||
|
|
||||||
|
客户不开心时不会告诉你,他们直接流失。金丝雀是从每个区域持续运行的合成 PUT/GET/LIST 流量。如果金丝雀失败 30 秒,你会在客户的寻呼机响起之前发现问题。
|
||||||
|
|
||||||
|
## 热点和 IOPS 暴露无声的故障
|
||||||
|
|
||||||
|
一个存储集群可以在 99.99% 可用的情况下,某个节点已经烧起来了。跟踪每个节点的 IOPS 和字节服务量,并对偏离集群中位数最多的前 N 个节点告警。热点是客户密钥区间压垮某个分片的前兆指标。
|
||||||
|
|
||||||
|
## DB 分片是没人谈论的部分
|
||||||
|
|
||||||
|
对象存储看起来无状态,但元数据层其实是一个分片数据库。一个过热的分片、一次出了岔子的再平衡,就能让你的控制面瘫痪。要用盯数据面同样的方式盯分片 CPU、复制滞后和热键偏斜。
|
||||||
|
|
||||||
|
数据面可以水平扩展;控制面会咬人。
|
||||||
|
|
||||||
|
这七个数字放在一起看,几乎告诉了我判断服务是否健康所需的一切。
|
||||||
@@ -0,0 +1,211 @@
|
|||||||
|
# Uber 如何征服数据库过载:从静态限流到智能负载管理
|
||||||
|
|
||||||
|
- **期号**: SRE Weekly Issue #532(2026-08-31)
|
||||||
|
- **作者**: Dhyanam Vaidya, Prathamesh Deshpande, and Mike Ma — Uber
|
||||||
|
- **链接**: https://www.uber.com/us/en/blog/from-static-rate-limiting-to-intelligent-load-management/
|
||||||
|
|
||||||
|
## 简介
|
||||||
|
|
||||||
|
这篇有大量精彩细节,讲他们的配额管理方案如何失败、又如何一步步迭代。
|
||||||
|
|
||||||
|
## 正文
|
||||||
|
|
||||||
|
# Uber 如何征服数据库过载:从静态限流到智能负载管理
|
||||||
|
|
||||||
|
# 引言
|
||||||
|
|
||||||
|
Uber 的数千个微服务为超过 1.7 亿月活用户处理流量:乘客、Uber Eats 用户、司机和骑手。这些基础设施的核心是 [Docstore](https://www.uber.com/us/en/blog/schemaless-sql-database/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) 和 [Schemaless](https://www.uber.com/us/en/blog/schemaless-part-one-mysql-datastore/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f)——Uber 基于 MySQL® 自研的分布式数据库。这些数据库横跨数千个集群,存储数十 PB 的运营数据,每秒服务数千万个请求,读写数十亿行。它们支撑着 Uber 对时延最敏感、最关键的任务负载,驱动着 Uber 的每一个业务线:从出行、配送、地图到支付,不一而足。
|
||||||
|
|
||||||
|
在这个规模上,即使轻微的过载也不是孤立事件,它们会级联。系统某一部分的短暂尖峰可以向外扩散:下游服务超时、重试堆积、性能退化放大成更大范围的故障。在多租户环境中,确保公平、防止某个租户独占全部资源同样至关重要。由于工作负载在流量形态、时延画像和对系统的影响上千差万别,构建有效的过载保护是一个极具挑战性的问题。
|
||||||
|
|
||||||
|
过载保护搞错的代价是高昂的。这篇博客分享我们如何构建了一个智能负载管理器:从多个信号检测过载,让数据库在压力下保持稳定与公平。
|
||||||
|
|
||||||
|
## Docstore 与 Schemaless
|
||||||
|
|
||||||
|
在进入保护 Uber 数据库的负载管理器之前,先快速过一遍它们的架构。
|
||||||
|
|
||||||
|
虽然 [Docstore](https://www.uber.com/us/en/blog/schemaless-sql-database/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) 支持带完整 CRUD 操作的事务,[Schemaless](https://www.uber.com/us/en/blog/schemaless-part-one-mysql-datastore/?uclick_id=0ef55d57-e714-4820-8ab3-c3f30875480f) 针对追加型(append-only)工作负载做了优化,但两者共享共同的架构基础。它由三个主要层组成:无状态查询引擎、有状态存储引擎和控制面。限于本文范围,我们聚焦查询引擎和存储引擎两层。
|
||||||
|
|
||||||
|
无状态查询引擎负责查询规划、请求路由、分片、模式管理、授权、请求解析与校验。它充当路由层:在把客户端请求交给存储层之前进行协调和校验。
|
||||||
|
|
||||||
|
有状态存储引擎处理事务管理、连接池、共识与复制。数据被分片到多个分区,每个分区由一个 leader 和两个 follower 组成,通过 [Raft](https://www.scs.stanford.edu/~zyedidia/docs/papers/raft.pdf) 协调以保证强一致性。每个分区由挂载本地 NVMe SSD 的 MySQL 节点支撑,为大规模的高吞吐、低时延工作负载而构建。
|
||||||
|
|
||||||
|
## 挑战
|
||||||
|
|
||||||
|
### 查询引擎层的基于配额限流
|
||||||
|
|
||||||
|
最初,我们探索了在无状态查询引擎层做基于配额的限流。概念很简单:根据处理的字节数给每个读和写请求分配一个容量单位成本,给用户发放固定配额,配额用尽时返回 429。由于路由节点是无状态的,我们把配额用量存在一个集中式 Redis® 缓存里。概念上合理,但在生产中撑不住。
|
||||||
|
|
||||||
|
首先,它增加了不必要的复杂性。每个请求都要一次 Redis 调用,引入了新的故障点和一次额外的网络跳数开销。
|
||||||
|
|
||||||
|
其次,无状态路由层要准确地为过载的存储分区丢弃请求,就需要维护系统中数千个分区的实时健康与负载信息。这带来了大量跟踪开销,削弱了架构的可扩展性。
|
||||||
|
|
||||||
|
成本模型也太粗糙。在 Docstore 和 Schemaless 中,由于 MySQL 处理扫描和过滤的方式,一个执行全表扫描却只返回一行的查询,与只读一行的查询被分配了相同的容量成本。这个计量上的根本缺陷意味着轻量操作和重量操作被一视同仁,使配额执行变得不可靠。
|
||||||
|
|
||||||
|
最后,配额是静态定义的,导致干系人频繁要求调整配额,在多租户环境中形同虚设。
|
||||||
|
|
||||||
|
尽管初衷美好,这个方案还是失败了。但它给了我们一个关键洞见:过载管理必须尽可能贴近存储节点。这个认识成为最终设计的基石——把过载保护放在有状态存储层。
|
||||||
|
|
||||||
|
### 识别正确的过载信号
|
||||||
|
|
||||||
|
设计一个健壮负载管理器的核心挑战,是选择可靠的过载信号。简单的基于 QPS 的限流太粗。它无法适应工作负载的波动,往往丢得太晚或太早。更有效的是并发度:当前在途的操作数。它直接反映系统负载,遵循 Little 定律:*并发度 = 吞吐量 × 时延*。在有状态系统中,它与资源使用高度吻合,是更可靠的指标。
|
||||||
|
|
||||||
|
### 平衡韧性与公平
|
||||||
|
|
||||||
|
在多租户系统中平衡韧性与公平是核心挑战。面临全局性压力时,我们希望按优先级丢弃流量,先丢低优先级请求。但当单个吵闹租户独占资源、却还没触发全局过载时,我们也需要独立于系统负载的按租户限流。这个双重要求促使我们把动态过载检测器与公平性执行机制并行组合。
|
||||||
|
|
||||||
|
## 构建统一负载管理器的基础
|
||||||
|
|
||||||
|
### 受控时延:压力下的智能排队
|
||||||
|
|
||||||
|
负载卸载之旅始于 [CoDel](https://queue.acm.org/detail.cfm?id=2209336)(受控时延,Controlled Delay),一个从网络领域借鉴来对抗"缓冲膨胀"(bufferbloat)的概念。CoDel 不按队列长度丢弃,而是看请求在队列里等了多久:以响应性为先,而不是以数量为先。
|
||||||
|
|
||||||
|
我们为每种操作类型实现了独立的 CoDel 队列:
|
||||||
|
|
||||||
|
- **读队列**:点查和轻量查询
|
||||||
|
- **写队列**:insert、update 和 upsert 操作
|
||||||
|
- **慢队列**:长时运行和后台操作,如扫描、删除或复制
|
||||||
|
|
||||||
|
每个队列独立管理,让我们在不同工作负载之间获得更好的隔离。
|
||||||
|
|
||||||
|
FIFO 排队还不够,因为纯 FIFO 按到达顺序处理请求,这在流量稳定时表现良好。但过载时,FIFO 会形成一个陷阱:旧请求不断堆积、等待过久,往往被客户端丢弃或重试,造成浪费。与此同时,仍然相关、很可能成功的新请求却在队尾闲置。
|
||||||
|
|
||||||
|
CoDel 引入自适应 LIFO 来解决这个问题。正常负载下,队列表现为 FIFO;压力之下,它切换为 LIFO,优先处理还有成功机会的新请求。这个简单的转变通过快速失败、丢弃过期工作、给新请求优先权,改善了响应性。
|
||||||
|
|
||||||
|
### Scorecard 引擎
|
||||||
|
|
||||||
|
Scorecard 引擎是一个基于规则的准入控制组件和轻量配额系统,用于在多租户环境中执行按租户的并发度限制。负载卸载在过载时保护系统,Scorecard 则确保即使在正常条件下,也没有单个租户能主导共享基础设施。
|
||||||
|
|
||||||
|
配置简单且确定。
|
||||||
|
|
||||||
|
Scorecard 的主要价值在于事故遏制。它帮助在宕机或流量尖峰期间定位干扰源头。它隔离并限制行为不当的租户而不影响其他租户,在正常负载下平衡稳定性、压力下实施严格限制,并通过快速、确定性地执行边界来缩小过载事件的爆炸半径。
|
||||||
|
|
||||||
|
Scorecard 提供了可预测的公平性和爆炸半径控制,尤其是当多个租户争夺共享资源时。
|
||||||
|
|
||||||
|
### 调节器(Regulators)
|
||||||
|
|
||||||
|
Scorecard 防范的是基于并发度的过度使用,但它没有覆盖有状态数据库系统可能过载的所有方式。有些倾斜行为很隐蔽,不会体现在并发度饱和上,但任其发展仍会拖累系统性能。
|
||||||
|
|
||||||
|
例如,一个低 QPS 的调用方可以通过发送大的写入负载搞垮系统。或者,流量倾斜到某个分区键,能让单个集群过载而其他集群闲置。
|
||||||
|
|
||||||
|
为防范这些倾斜行为,我们引入了插件式调节器:节点本地的过载检测器,执行系统不允许违反的不变量。健康运行期间它们几乎不触发,这是设计使然。与此同时,当用户意外制造热点或大规模数据摄取时,调节器介入以防止级联故障。
|
||||||
|
|
||||||
|
我们用这些调节器:
|
||||||
|
|
||||||
|
- **写字节调节器**:限制并发写入量,防止 I/O 饱和
|
||||||
|
- **分区键调节器**:节流指向热点分区键的流量
|
||||||
|
- **内存调节器**:跟踪进程空闲内存,内存不足时节流
|
||||||
|
- **Goroutine 调节器**:跟踪 goroutine 总数,超过阈值时节流
|
||||||
|
|
||||||
|
### 哪些做得好
|
||||||
|
|
||||||
|
通过丢弃多余请求,我们的 CoDel 队列阻止了失控的资源耗尽,带来了更高的稳定性和更高的被接受请求成功率。这种方法在确保过载期间核心系统功能仍然可用方面特别有效。
|
||||||
|
|
||||||
|
Scorecard 引擎通过执行按租户的并发限制,成功隔离了行为不当的租户,让我们能快速遏制吵闹邻居造成的干扰而不用惩罚其他用户,确保共享资源被公平使用。
|
||||||
|
|
||||||
|
### 局限
|
||||||
|
|
||||||
|
虽然这套初始设计为过载保护和公平性打下了基础,但它有几个局限。首先,CoDel 对所有请求一视同仁,丢弃低优先级流量和面向用户流量时没有差别,导致糟糕的客户体验和更高的值班负担。
|
||||||
|
|
||||||
|
CoDel 还依赖固定的队列超时和静态的在途并发上限,对动态系统来说是低保真方案,需要频繁手动调优,带来运维辛劳。
|
||||||
|
|
||||||
|
CoDel 中固定、静态的等待时间导致了惊群效应。请求最终被拒绝时,它们会同时重试,触发一轮又一轮过载与拒绝的循环。这些时期缺乏流量差异化,连高优先级请求也被丢弃,造成用户可见的错误,放大了爆炸半径。
|
||||||
|
|
||||||
|
归根结底,它没有让系统崩掉,但缺少高品质用户体验所需的细腻与动态。这凸显了对动态、优先级感知队列的需求。
|
||||||
|
|
||||||
|
## 架构演进
|
||||||
|
|
||||||
|
### Cinnamon 取代 CoDel
|
||||||
|
|
||||||
|
我们观察到许多过载源于低优先级的异步任务:管道、聚合器和内部垃圾回收流程。它们不应该和乘车请求或实时定价查询拥有相同的存活优先级。
|
||||||
|
|
||||||
|
为解决这个问题,我们用 [Cinnamon](https://www.uber.com/us/en/blog/cinnamon-using-century-old-tech-to-build-a-mean-load-shedder/) 取代了 CoDel——一个由 Uber Delivery 团队开发的优先级感知负载卸载器。Cinnamon 通过考虑请求等级、动态系统状态和工作负载的相对重要性,做出更聪明的卸载决策。
|
||||||
|
|
||||||
|
请求等级来自请求附带的优先级;如果没有显式优先级,Cinnamon 会根据调用方服务分配一个默认值。优先级用分层模型定义:tier 0(t0)是最关键的流量,tier 5(t5)是最不关键的。t0 预留给一小部分关键基础设施服务,t1 代表最重要的面向用户的在线流量——过载时我们核心要保护的工作负载。这套系统让 Cinnamon 在过载时优先卸载低优先级流量。
|
||||||
|
|
||||||
|
有了请求优先级感知,我们把队列结构简化为只有读和写队列。长时运行和后台操作改为标记低优先级,而不是单独一个队列。
|
||||||
|
|
||||||
|
Cinnamon 之前:CoDel 队列卸载器与优先级无关,过载时卸载不分青红皂白。
|
||||||
|
|
||||||
|
Cinnamon 之后:队列卸载器具备优先级感知,过载时按优先级顺序卸载。
|
||||||
|
|
||||||
|
### 性能与稳定性收益
|
||||||
|
|
||||||
|
基于 Cinnamon 的设计带来了性能和稳定性收益。请求被分级,Cinnamon 可以先丢低优先级流量,保护面向用户的链路。过载期间,关键用户请求得到更好保护,影响最小。
|
||||||
|
|
||||||
|
Cinnamon 还使用 P90 时延指标自适应调整队列超时阈值,免去手动调优。此外,它的 [Auto Tuner](https://www.uber.com/blog/cinnamon-auto-tuner-adaptive-concurrency-in-the-wild/) 动态调整在途上限(图 10 蓝框中显示的可用槽位),以最大化吞吐量。它持续监控并响应实时时延和错误率信号,确保稳定有效的负载卸载。
|
||||||
|
|
||||||
|
与 CoDel 的静态方法不同——固定等待时间(比如 5 毫秒)后激进地拒绝所有请求——Cinnamon 基于 [PID 的控制](https://www.uber.com/us/en/blog/pid-controller-for-cinnamon/) 让系统吸收压力而不过度反应。它根据实时时延和错误信号动态调整队列超时和在途上限,只在必要时卸载。这避免了一大类过早卸载——否则会导致不必要的拒绝、重试和惊群效应。结果是更平滑的恢复、更少的 429,以及不损害系统健康的前提下更稳定的可用性。
|
||||||
|
|
||||||
|
### 待改进之处
|
||||||
|
|
||||||
|
尽管 Cinnamon 带来了收益,仍有一些关键挑战,凸显了对统一平台的需求。
|
||||||
|
|
||||||
|
负载管理器基于服务器的本地健康采取行动,跟踪在途并发、写字节、内存使用等信号。但在分布式系统中,过载不总是局部的。leader 节点可能因为 follower 滞后而需要卸载流量,即使它自己很健康。我们称之为提交索引滞后(commit index lag)。传统上,外部组件用基于令牌桶的限流器处理这种远端卸载决策。它们容易构建,但在规模上被证明无效,会引入脑裂行为和全局次优的卸载决策。
|
||||||
|
|
||||||
|
初始设计擅长基于并发度的卸载,但它不是为了成为可复用平台而建的,无法承载一个不断增长的系统未来必然涌现的新过载信号。
|
||||||
|
|
||||||
|
这些洞见引领我们走向系统的最终演进:把 Cinnamon 从纯并发度卸载器,转变为一个真正通用的过载控制引擎。通过把所有信号整合进一个模块化的决策回路,我们实现了整体、一致的过载管理。
|
||||||
|
|
||||||
|
## 统一负载卸载引擎
|
||||||
|
|
||||||
|
### 集中过载决策
|
||||||
|
|
||||||
|
我们增强了 Cinnamon,支持可插拔的外部信号,比如 follower 提交滞后,让系统能在同一条准入控制路径内做出全局知情、优先级感知的卸载决策。这一转变把本地和远程过载逻辑统一到单一控制回路中,弥合了此前造成不稳定的缺口。
|
||||||
|
|
||||||
|
但卸载并不总是一刀切的决策,这正是负载管理器架构大放异彩之处。它建立在 BYOS(Bring Your Own Signal,自带信号)理念之上,提供了一个可插拔框架,让团队嵌入新的过载信号并把它们路由到正确的控制路径。无论压力是系统性的还是针对某个调用方的,负载管理器都根据信号按优先级广泛卸载,或按调用方精确卸载。
|
||||||
|
|
||||||
|
### 回报:统一控制,简化负载管理
|
||||||
|
|
||||||
|
转向集中、可插拔的架构让系统更稳定、更可预测,带来了实实在在的成果。
|
||||||
|
|
||||||
|
Cinnamon 用 PID 控制器立即卸载多余请求,避免了令牌桶限流器造成的内存和 goroutine 堆积。这带来了更低的尾部时延和更精简的资源用量画像,即使在重负载下也是如此。我们看到:
|
||||||
|
|
||||||
|
- 过载下吞吐量提升 80%(QPS 均值 5,400 对比 3,000)
|
||||||
|
- P99 时延降低约 70%(upsert 均值 1.0 秒对比 3.1 秒)
|
||||||
|
- 过载期间 goroutine 减少约 93%(峰值 10,000 对比 150,000)
|
||||||
|
- 堆内存占用降低约 60%(峰值 1GB 对比 5-6GB 尖峰)
|
||||||
|
|
||||||
|
我们还看到更平滑、更可预测的卸载行为。没有 PID 调节,卸载像一把锤子:反应式、突兀。有了它,更像一个调光开关:平滑、稳定。对比提交滞后在令牌桶限流器下与 Cinnamon 的 PID 控制器下的稳定方式,差别一目了然。
|
||||||
|
|
||||||
|
## 经验教训
|
||||||
|
|
||||||
|
- **优先级至上。** 有效的负载卸载始于决定什么最重要。先保护关键的、面向用户的流量。其他一切都是次要的。
|
||||||
|
- **快速失败,不要阻塞。** 尽早拒绝几乎总是好过把请求留在内存里直到过期。它减少浪费的工作,保持时延可预测,防止 OOM,让系统在压力下更有韧性。
|
||||||
|
- **用 PID 调节实现稳定卸载。** 仅基于当前错误率的简单反应式卸载往往导致不稳定,纠正得太晚、太猛。PID 调节通过纳入系统历史与趋势方向带来平衡,是平滑、持续、有韧性的过载控制的关键工具。
|
||||||
|
- **把控制放在靠近真相源的地方。** 最好的卸载决策发生在状态所在之处。保护应该放在拥有完整上下文的层——在有状态系统中通常是存储层。
|
||||||
|
- **拥抱动态性。** 尽可能避免静态配置。你的系统应该足够聪明,能根据上下文适应不同场景。
|
||||||
|
- **投资可观测性。** 良好的可观测性是一切调优与信任的基础。跟踪什么被卸载、为什么被卸载、每个组件如何促成系统压力。
|
||||||
|
- **简单胜过复杂。** 这是一条指导所有其他决策的元原则。
|
||||||
|
|
||||||
|
# 结论
|
||||||
|
|
||||||
|
我们通往健壮负载管理器的旅程,是由大规模、有状态、分布式环境的独特复杂性定义的。通过把零散组件统一进一个决策大脑、采用 Bring Your Own Signal 模型,我们获得了同时精准处理系统性过载和局部吵闹邻居问题的灵活性。结果是:一个按优先级更聪明地卸载、尾部时延更低、运维辛劳大幅减少的负载管理系统。
|
||||||
|
|
||||||
|
如果你喜欢分布式系统、数据库、存储和缓存相关的挑战,欢迎[在这里](https://www.uber.com/us/en/careers/list/?query=storage&department=Engineering)申请我们的开放职位。
|
||||||
|
|
||||||
|
## 致谢
|
||||||
|
|
||||||
|
这样规模的项目很少能靠一个人完成。我们衷心感谢 Rich Porter、Jesper Nielsen、Piyush Patel,以及 Storage 和 Delivery 两个团队的工程师们在整个旅程中的指导与协作。从设计评审到值班洞见,他们的贡献对构建这个现在守护着 Uber 最关键基础设施的系统至关重要。
|
||||||
|
|
||||||
|
*封面图片署名:"[Heavy Traffic Jam in Urban City Center](https://www.pexels.com/photo/heavy-traffic-jam-in-urban-city-center-32487428/)",作者 [Dapur Melodi](https://www.pexels.com/@dapur-melodi-192125/)*
|
||||||
|
|
||||||
|
*MySQL 是 Oracle 和/或其关联公司的注册商标。其他名称可能是其各自所有者的商标。*
|
||||||
|
|
||||||
|
*Redis 是 Redis Labs Ltd. 的商标。其所有权利归 Redis Labs Ltd. 所有。本文中的使用仅出于指代目的,不表示 Redis 与 Uber 之间存在任何赞助、背书或关联。*
|
||||||
|
|
||||||
|
Dhyanam Vaidya
|
||||||
|
|
||||||
|
Dhyanam Vaidya 是 Uber 存储平台团队的软件工程师。他参与了许多 Docstore 功能的设计与实现。他的工作聚焦于提升 Uber 分布式数据库在规模上的可靠性、韧性与运维效率。
|
||||||
|
|
||||||
|
Prathamesh Deshpande
|
||||||
|
|
||||||
|
Prathamesh Deshpande 是 Uber 存储平台团队的高级工程师(Staff Engineer),构建满足 Uber 全球可靠性与性能要求的数据库功能和分布式存储系统。他的工作聚焦于大规模数据管理、分布式数据库存储系统和平台可靠性。
|
||||||
|
|
||||||
|
Mike Ma
|
||||||
|
|
||||||
|
Mike Ma 是 Uber 存储平台团队的高级软件工程师(Staff Software Engineer),为 Schemaless 和 Docstore 的多个核心组件做出了贡献。他的工作聚焦于 Uber 大规模分布式数据库的可扩展性、可靠性、性能与卓越运维。
|
||||||
|
|
||||||
|
Chaitanya Yalamanchili
|
||||||
|
|
||||||
|
Chaitanya Yalamanchili 是 Uber 存储平台团队的高级经理兼技术负责人。他领导在线分布式存储系统的开发,致力于提供一个支撑 Uber 所有关键业务功能与业务线的一流平台。该平台每秒服务数千万 QPS,存储数十 PB 的运营数据。
|
||||||
@@ -0,0 +1,126 @@
|
|||||||
|
# 旅行者号与优雅降级之道
|
||||||
|
|
||||||
|
- **期号**: SRE Weekly Issue #532(2026-08-31)
|
||||||
|
- **作者**: Robert Barron
|
||||||
|
- **链接**: https://www.flyingbarron.com/2026/04/voyager-and-art-of-graceful-degradation.html
|
||||||
|
|
||||||
|
## 简介
|
||||||
|
|
||||||
|
这篇文章以旅行者 1 号——它的工程师刚刚又关闭了一台仪器以节省不断衰减的电力——为引申类比,讲述优雅降级。
|
||||||
|
|
||||||
|
## 正文
|
||||||
|
|
||||||
|
### 旅行者号与优雅降级之道
|
||||||
|
|
||||||
|
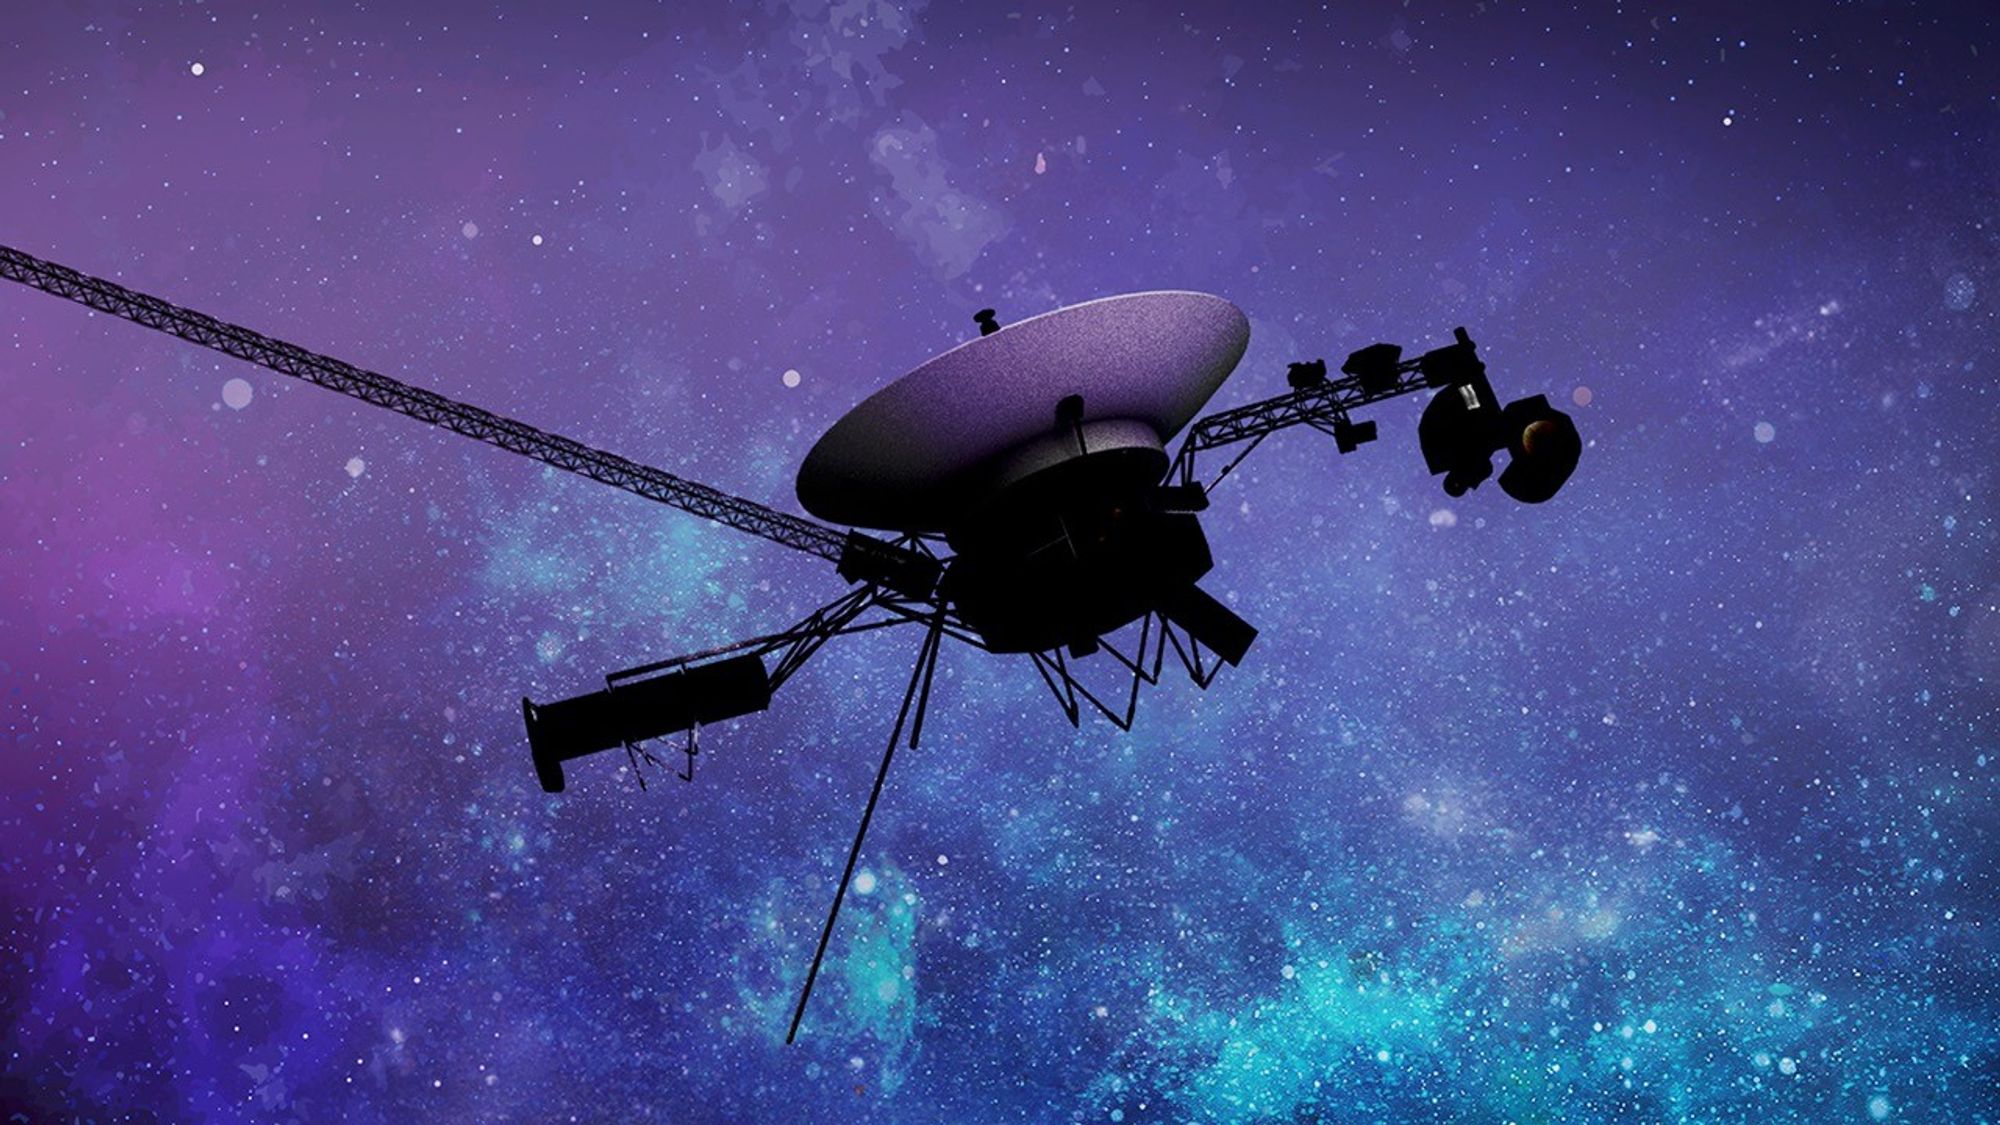
像一只优雅的天鹅,旅行者 1 号正展翅飞行——迅捷、大胆,只是某些地方有点僵硬。
|
||||||
|
|
||||||
|
|  |
|
||||||
|
| [NASA/JPL-Caltech](https://science.nasa.gov/blogs/voyager/2026/04/17/nasa-shuts-off-instrument-on-voyager-1-to-keep-spacecraft-operating/) |
|
||||||
|
|
||||||
|
它携着巨大的动量穿行在星际空间,远远越过曾经定义其使命的行星,其上的仪器仍在从人类飞行器从未到达过的区域发回数据。然而它的每一个动作都受制于一份有限且持续衰减的能量供给,每一帧信号都要仔细掂量发送它要付出多少代价。
|
||||||
|
|
||||||
|
这种平衡里有种安静的优雅。
|
||||||
|
|
||||||
|
旅行者号并不坚持做它曾经能做的一切。当条件不再允许时,它不追求峰值能力。相反,它适应——放弃一些功能好让另一些继续,把最重要的事排在仅仅可能的事之前。
|
||||||
|
|
||||||
|
在工程学里,我们对这类系统有一个名字。
|
||||||
|
|
||||||
|
#### 我们称之为**优雅降级**。
|
||||||
|
|
||||||
|
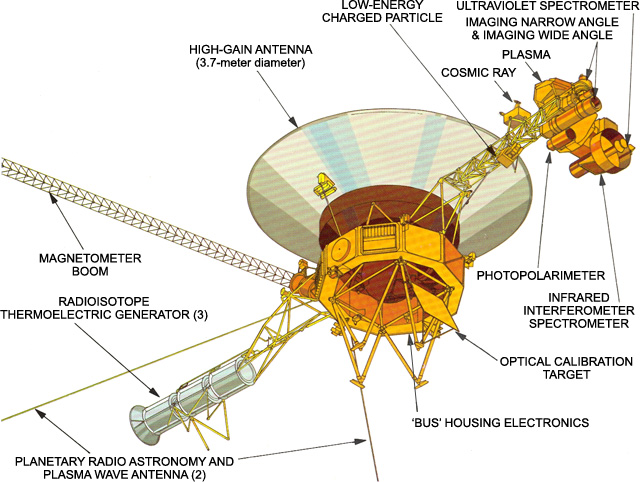
[低能带电粒子探测器(LECP)](https://pds-atmospheres.nmsu.edu/data_and_services/atmospheres_data/Voyager/lecp.html)——一台测量离子、电子和宇宙射线,用以绘制星际介质结构与压力的仪器,帮助界定太阳系与星际空间的边界——已被关闭,以节省电力、延长航天器的运行寿命。
|
||||||
|
|
||||||
|
旅行者号由放射性同位素热电发电机供电,其输出随放射性燃料衰减而下降。每年可用功率都会减少几瓦。与地球上的系统不同,这里没有扩容的可能,没有备用冗余,也没有"横向扩展"这个选项。
|
||||||
|
|
||||||
|
用 SRE 的视角看,旅行者号的功率裕量就是它的**错误预算**。它界定了在任务开始受损之前,"可以出多少错"。
|
||||||
|
|
||||||
|
任务早期,这个预算很充裕。轻微的低效、意外的行为、非最优的配置都能被容忍。几十年过去,裕量收窄了。今天,哪怕是一台不守规矩的仪器带来的一次小幅、计划外的功率下探,都可能触发旅行者号的欠压故障保护——一道自动防线,会突然关闭组件以确保生存。
|
||||||
|
|
||||||
|
二月时,一次常规滚转机动就造成了这样的下探。工程师们明白,让航天器越过那条线就意味着进入一种生存模式:优先保障系统存续,而非交付任务价值。
|
||||||
|
|
||||||
|
任何在极限边缘运维过生产系统的人都会熟悉这个时刻:
|
||||||
|
|
||||||
|
- CPU 饱和让时延变成用户可见的卡顿
|
||||||
|
- 内存压力触发进程和容器终止
|
||||||
|
- 队列堆积,直到消息过期而未能送达
|
||||||
|
- 存储耗尽,冻结了原本健康的交易
|
||||||
|
|
||||||
|
优雅降级关乎对你的目标和能力排定优先级,并在你接近无法同时满足所有目标的那个点之前、*提前*行动。
|
||||||
|
|
||||||
|
- 削减 CPU 消耗(降低帧率、移除动画、禁用可选功能)
|
||||||
|
- 推迟低优先级工作(批量报表,用聚合数据替代实时数据)
|
||||||
|
- 优先保障关键流量,丢弃非必要消息
|
||||||
|
- 存储达到阈值时拒绝新交易,保护核心路径
|
||||||
|
|
||||||
|
在可靠性工程里,就像在生活中的许多领域一样,我们宁可限电,也不愿全城停电。
|
||||||
|
|
||||||
|
虽然我们永远不想让用户失望,但我们宁愿减少功能,也不愿宕机。我们会有控制地降级体验,而不是彻底失去服务。我们用受控的方式卸载负载,而不是让级联故障来决定结局。
|
||||||
|
|
||||||
|
这正是旅行者号的工程师们做的事。
|
||||||
|
|
||||||
|
在这个时刻到来的多年之前,科学家与工程师就共同商定了一份关机顺序:随着功率下降,先牺牲哪些仪器,哪些能力最关键、必须保留。到 2026 年 4 月,旅行者 1 号最初的十台科学仪器中已有七台退役。LECP 只是名单上的下一个——不是因为它坏了,而是因为它的成本收益比已经不再有利。
|
||||||
|
|
||||||
|
这正是站点可靠性工程师(SRE)在这些时刻会做的决定:
|
||||||
|
|
||||||
|
- 高峰期禁用昂贵的推荐管道
|
||||||
|
- 提供缓存或近似结果,而不是完整计算结果
|
||||||
|
- 暂时关闭后台任务以保护面向用户的时延
|
||||||
|
|
||||||
|
*严格*来说,没有什么是坏的。系统是在有意识地选择少做一些,以便能在局部继续成功,而不是整体彻底失败。优雅降级不是弱点,而是成熟的表现。
|
||||||
|
|
||||||
|
旅行者号继续运行那些提供独一无二宝贵数据的仪器——测量星际空间的磁场和等离子体波——同时放弃另一些仪器,它们的贡献虽然还有用,却已不值得那份代价。
|
||||||
|
|
||||||
|
就连 LECP 的关闭在设计上也是可逆的。一个负责旋转传感器的小马达仍然带电,保留了未来省电措施见效后重新激活它的选项。
|
||||||
|
|
||||||
|
这就是带有可逆性考量的优雅降级:当前状态被保留,恢复路径被维护,最重要的是——选项保持开放。诚然,旅行者号突然获得新的钚燃料以补充功率的概率恰好是 0,但地面上的可靠性工程师确实在为克服导致这次降级的临时问题而做规划,并打算利用可用选项来完全恢复服务。
|
||||||
|
|
||||||
|
这就是为什么我们用特性开关(feature flag)来掩蔽功能而不是删除代码,为什么我们能临时改变用户的能力而不是把他们从系统里移除。
|
||||||
|
|
||||||
|
### 平衡性能、容量与风险
|
||||||
|
|
||||||
|
可靠性很少关乎把性能拉满。它关乎在**性能**、**容量**与**风险**之间持续平衡——尤其是当容量有限、裕量微薄的时候。
|
||||||
|
|
||||||
|
旅行者号永远运行在这样一个交汇点上。
|
||||||
|
|
||||||
|
对旅行者号而言,性能就是科学吞吐量:多少台仪器在运行、多久测量一次、返回多少数据。
|
||||||
|
|
||||||
|
容量是一份不断缩水、无法补充的功率预算。
|
||||||
|
|
||||||
|
风险随裕量收窄而增长:一次突如其来的欠压事件可能触发自主关机,而跨越 23 小时的通信延迟,恢复起来又难又慢又危险。
|
||||||
|
|
||||||
|
优雅降级就是旅行者团队管理这个三角的方式。
|
||||||
|
|
||||||
|
通过在功率到达临界值之前关闭 LECP,团队有意识地用峰值科学性能换取了更低的运行风险和保留给最重要仪器的容量。
|
||||||
|
|
||||||
|
|  |
|
||||||
|
| [旅行者号仪器状态 (NASA/JPL-Caltech)](https://science.nasa.gov/mission/voyager/where-are-voyager-1-and-voyager-2-now/#instrument-status) |
|
||||||
|
|
||||||
|
**旅行者号做得比以前少了——但它做得更安全、更可预测、更长久。**
|
||||||
|
|
||||||
|
这正对应日常的 SRE 工作:
|
||||||
|
|
||||||
|
- 降低请求并发以防止饱和
|
||||||
|
- 负载下降低图像质量或刷新率
|
||||||
|
- 在高风险窗口收缩功能范围
|
||||||
|
- 重新协商 SLO,而不是假装什么都没变
|
||||||
|
|
||||||
|
每种情况下,都是有意降低性能以把风险控制在可接受范围内。
|
||||||
|
|
||||||
|
因为旅行者号的降级路径在多年前就已定好——那时系统健康,管理层和工程方都有时间和清晰的头脑去做理性的权衡——这次意外的功率下探没有引发手忙脚乱的英雄式救火,而是触发了一个预先规划好的流程,让事前选定的仪器体面退休。没有意外,只是扎实的工程。
|
||||||
|
|
||||||
|
优雅降级不仅是一项技术能力,也是一项社会与组织能力。它需要跨团队的共识、对优先级的明确约定,以及接受"损失不可避免"这一事实。它不是要永远防止失败,而是要确保当降级发生时,是发生在你的掌控之下。
|
||||||
|
|
||||||
|
虽然我们中很少有人在一个像旅行者号一样的系统上工作,但共同点很多——
|
||||||
|
|
||||||
|
- 我们的平台通常比它们当初被设计来支撑的商业模式老得多
|
||||||
|
- 我们的架构往往比我们的架构师活得更久
|
||||||
|
- 我们用"临时"设计决策建的"临时"服务,已经变成了永久设施
|
||||||
|
|
||||||
|
我们的系统能存活下来,靠的不是永远保持完美,而是优雅地放手。至少,那些让所有者和维护者压力最小的系统都是这样。
|
||||||
|
|
||||||
|
旅行者号至今仍从星际空间发回数据,不是因为它什么都没坏过,而是因为故障一直被深思熟虑地、循序渐进地、带着谦逊地管理着。在距离地球 250 亿公里的地方,旅行者号继续演示着每位资深 SRE 最终都会学到的一课:
|
||||||
|
|
||||||
|
能活得最久的系统,不是那些死抱着每个功能不放的,而是那些提前很久就决定了愿意放弃哪些部分的。
|
||||||
|
|
||||||
|
## 评论
|
||||||
|
|
||||||
|
## 发表评论
|
||||||
3
temp/youtube-transcript/.index.json
Normal file
3
temp/youtube-transcript/.index.json
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
{
|
||||||
|
"czA9lK-MP5Q": "slight-reliability/a-beginners-guide-to-sre-episode-119"
|
||||||
|
}
|
||||||

Binary file not shown.
|
After Width: | Height: | Size: 86 KiB |
@@ -0,0 +1,18 @@
|
|||||||
|
{
|
||||||
|
"videoId": "czA9lK-MP5Q",
|
||||||
|
"title": "A Beginner's Guide to SRE (Episode 119)",
|
||||||
|
"channel": "Slight Reliability",
|
||||||
|
"channelId": "UCK-JYMQjxA144jMOPu7FJhg",
|
||||||
|
"description": "This week I repurpose a talk I just did at the JuniorDev meetup in Auckland. If you're new to SRE or observability then this is the talk for you. For the more seasoned listeners, it's a chance to see how my perspective and understanding has changed over the years.\n\nIn the episode I refer to the This Is Fine! podcast on resilience engineering: https://www.thisisfinepod.com/\n\nYou can read the Google SRE books for free online here: https://sre.google/books/\n\nYou can buy Slight Reliability merch here (Note: you cannot order the mugs outside of New Zealand):\n\nhttps://slightreliability.digitees.co.nz/\n\nYou can find Stephen on:\n\nLinkedIn: https://www.linkedin.com/in/stephentownshend/\nBluesky: https://bsky.app/profile/slightreliability.bsky.social\nYouTube: https://www.youtube.com/c/SlightReliability\nInstagram: https://www.instagram.com/slight_reliability/\nTikTok: https://www.tiktok.com/@the_kiwi_sre",
|
||||||
|
"duration": 1521,
|
||||||
|
"publishDate": "2026-03-24",
|
||||||
|
"url": "https://www.youtube.com/watch?v=czA9lK-MP5Q",
|
||||||
|
"coverImage": "imgs/cover.jpg",
|
||||||
|
"thumbnailUrl": "https://i.ytimg.com/vi/czA9lK-MP5Q/maxresdefault.jpg",
|
||||||
|
"language": {
|
||||||
|
"code": "en",
|
||||||
|
"name": "English",
|
||||||
|
"isGenerated": true
|
||||||
|
},
|
||||||
|
"chapters": []
|
||||||
|
}
|
||||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,107 @@
|
|||||||
|
---
|
||||||
|
title: "A Beginner's Guide to SRE (Episode 119)"
|
||||||
|
channel: Slight Reliability
|
||||||
|
date: 2026-03-24
|
||||||
|
url: "https://www.youtube.com/watch?v=czA9lK-MP5Q"
|
||||||
|
cover: imgs/cover.jpg
|
||||||
|
description: "This week I repurpose a talk I just did at the JuniorDev meetup in Auckland. If you're new to SRE or observability then this is the talk for you. For the more seasoned listeners, it's a chance to see how my perspective and understanding has changed over the years."
|
||||||
|
language: en
|
||||||
|
---
|
||||||
|
|
||||||
|
# A Beginner's Guide to SRE (Episode 119)
|
||||||
|
|
||||||
|
This week I repurpose a talk I just did at the JuniorDev meetup in Auckland. If you're new to SRE or observability then this is the talk for you. For the more seasoned listeners, it's a chance to see how my perspective and understanding has changed over the years.
|
||||||
|
|
||||||
|
Welcome to SRE Reliability, the show about human beings and their experiences in SRE, observability, and technology leadership. [music] I'm your host, Stephen Townsend. Welcome back to SRE Reliability. I'm Stephen Townsend, and this is the show where we learn about SRE 2 weeks at a time. A couple of weeks ago, maybe three, four weeks ago, I prepared a 20-minute introduction to SRE and observability for a meetup event called Junior Dev here in Auckland, New Zealand. [00:00:01 → 00:00:34]
|
||||||
|
|
||||||
|
Uh I spent a bit of time preparing for it, and although it's a very introductory topic, I thought it was worth putting it together into a podcast episode as well. So, I think it's interesting to reflect back over the many years that I've been producing this podcast and working in SRE to varying degrees, to reflect on how my perception and understanding of what SRE is changes over those times. >> [snorts] >> So, this is an introduction which is not particularly detailed. I deliberately made it quite high-level. I described it as if SRE is a a loaf of bread, throwing out a few crumbs to give a flavor of what it's about, rather than trying to be completely scientifically accurate in everything that I said. [00:00:32 → 00:01:24]
|
||||||
|
|
||||||
|
So, I'm going to share this presentation with you. If you were listening to the audio-only version, you're not really missing out on anything. There are some slides, but it's basically just MS Paint pictures that you've probably seen before, just a couple of new ones. There's no visual aids apart from one point which really support what I'm saying. So, you're not missing out if you just listen. [00:01:22 → 00:01:47]
|
||||||
|
|
||||||
|
But if you want to, you can go and watch this on YouTube where you can see my screen as I present this as well. So, let's see how this goes. I've got my cue cards with me here which I haven't used for a few weeks, but we'll we'll see how this goes. guys. And I'm going to start with an introduction. [00:01:47 → 00:02:04]
|
||||||
|
|
||||||
|
So, I'm assuming that if you are listening to this podcast, you probably know who I am. But if you don't, this will be an opportunity just to find out a little bit more about me. So, hi there. My name is Stephen Townsend. I live in Auckland, New Zealand with my family. [00:02:04 → 00:02:18]
|
||||||
|
|
||||||
|
You can see the picture there if you are looking at the slides. I've been working in technology for about 18 years, and my current role is the SRE and DevOps team lead at a company called Blue Card. And if you hadn't heard of Blue Card before, we provide smart metering services for electricity, for water, and for gas across New Zealand and Australia. I studied computer science at the University of Canterbury from 2002 to 2004, and then I remember thinking, I can't do this the rest of my life. I need to have some adventures. [00:02:18 → 00:02:56]
|
||||||
|
|
||||||
|
I auditioned for Toi Whakaari, the New Zealand Drama School, based in Wellington, New Zealand. Uh and I got in. I got accepted, and I went there and trained for 3 years to be a professional actor. Clearly, I'm not a professional actor. You wouldn't have seen me in anything other than maybe an extra on James Cameron's Avatar, uh the first movie. [00:02:54 → 00:03:19]
|
||||||
|
|
||||||
|
But drama school was a really formative time in my life. I learned a lot about myself. I grew a lot as a person, and I met my wife, Natasha. She was in my class, so lots was gained from that experience. However, after being a miserable unemployed actor for about 6 to 8 months, I started looking for work in tech. [00:03:17 → 00:03:40]
|
||||||
|
|
||||||
|
I wanted to take control of my life, and I wanted to get back into that world. I applied for lots of different jobs, had didn't have much luck, but I did eventually land a job as a junior performance test engineer. I'd never heard of performance testing before, or anything about it, but it turned out to be a wonderful mix of the technicals, writing code, uh analyzing huge amounts of data and finding patterns in that, understanding architecture and systems, understanding business context, even a bit of mathematics when it came to things like workload modeling or understanding data. And I did that for 13 years, and I became a deep specialist in that that space. But I got to a certain point where I was really good at what I was doing, right? [00:03:40 → 00:04:27]
|
||||||
|
|
||||||
|
I was going to different parts of the world to speak at conferences. I was producing a podcast called Performance Time, and creating articles and content online. But I felt like I'd hit this glass ceiling, where as good as I was at the thing that I was doing, I could see other things in the organization happening that I thought I could have a bigger impact in. And that's when I got first into SRE. I was part of an incubator team at IAG at the time. [00:04:25 → 00:04:53]
|
||||||
|
|
||||||
|
There were just four of us to start with, and we were tasked with the goal of finding opportunities to bring SRE principles and practices into IAG to improve how we operate software. And I was going from a thing that I was really, really good at and specialist at, into something I knew absolutely nothing about. And honestly, I found it so liberating just to let go of all the expectation, all the ego, just throw it aside, and say, ah, okay. Let's figure this out. And as you probably can tell by now, one of the ways which I learn is public learning. [00:04:53 → 00:05:30]
|
||||||
|
|
||||||
|
So, I started posting questions online, opinions online, observations, and then that's when I started this podcast, SRE Reliability. The idea was, I know nothing about SRE, come and learn with me. And that seemed to resonate with some people. Over the years, obviously, the podcast has changed. It now is predominantly about guests from around the world coming on to talk about their experiences or ideas or challenges, but it's also expanded into other areas, observability, of course, uh technology leadership, mental health, things which are important to me and important to many people working in this world. [00:05:28 → 00:06:09]
|
||||||
|
|
||||||
|
So, by the time this is released, it'll be something like 120 episodes. Around about 80 different guests from around the world have been on the podcast, so it's been reasonably successful, and it's something that I enjoy doing, and a way to keep connected to that creative part of myself. So, SRE stands for site reliability engineering. It was started by Google back in around 2003, 2004. Uh as Ben Treynor, who was and maybe still is VP of engineering at Google, said, "SRE is what you get when you treat operations as a software problem staffed by software engineers. [00:06:08 → 00:06:47]
|
||||||
|
|
||||||
|
" Now, I'm probably teaching you to suck eggs here, but since computers have existed, there's been this divide, this chasm between the people who write the code and develop the software, and the people who operate and support it in production. Dev and ops. That's the term DevOps to try and bring them together. And Google had the made this observation that in the development world, the innovation that was happening was many years ahead of what was happening in operations. So, SRE was created as a way to take all those innovative ideas around automation, simplification, abstraction, and apply them to the world of operations. [00:06:47 → 00:07:24]
|
||||||
|
|
||||||
|
And thus, SRE was born. SRE is now been adopted by organizations around the world. It means different things to different people and different organizations at different times. Up until recently, I didn't say the word SRE much anymore. I talked about reliability engineering because what I was doing and what many people do is so vastly different to what Google did and does that uh I don't know, it didn't feel right to say SRE. [00:07:24 → 00:07:52]
|
||||||
|
|
||||||
|
But I am literally titled SRE team lead now, so that's something that I I do say now. My own definition was, and I think I'm going to change it pretty soon, is that SRE is about designing, building, and operating reliable services at scale, and making the operation of those services as simple, effective, and dare I say enjoyable as possible. The other important part of SRE is it decouples the scale of an organization from the number of people required to operate its services. So, you think about the Google context as it was exploding in the early 2000s. You might have a service which has 10 times or or more, 100 times more activity on it 1 year to the next. [00:07:52 → 00:08:37]
|
||||||
|
|
||||||
|
Are you going to hire 10 or 100 times more engineers to operate it? No. That's not cost-effective, and it just doesn't work because as you add more people, you add more coordination overhead, and it just gets out of control. So, by decoupling those two things, being able to operate more complex, busier services with the same amount of people, that unlocks your ability to scale. Now, I'm going to introduce some of the principles and practices, not all of them. [00:08:35 → 00:09:03]
|
||||||
|
|
||||||
|
Selfishly, I'm picking the things which are most relevant to my role right now. So, I'm pretty new to Blue Card at the time of speaking about this. I've been brought on board to bring SRE to life and in the most amazing way. This is the first time in my career I've really got to get to just truly do the SRE thing and bring it to life in an organization who's ready for it. So, the areas I'm going to talk about today uh this idea of our culture around incidents, uh service level objectives, observability, which isn't, I guess, technically part of SRE, but it's so intertwined with it, I had to speak about it. [00:09:03 → 00:09:45]
|
||||||
|
|
||||||
|
Toil, and blameless postmortems. And there's so many more aspects to it around architecture and design and all these different principles and ideas, but I'll just start with these to give you those crumbs, to give you the flavor of what SRE is all about. So, let's start with incident culture. An incident, what is an incident? It's some kind of outage or loss of service. [00:09:42 → 00:10:08]
|
||||||
|
|
||||||
|
It generally negatively impacts your customers in some way or disrupts your business in some way. And it generally requires some human intervention to do something about it. Traditionally, when we think about incidents, we think of them as a bad thing. We must avoid the incidents. They are bad. [00:10:06 → 00:10:24]
|
||||||
|
|
||||||
|
Let's just stop them from happening, right? And we've also traditionally had this mindset that if we just engineer our systems perfectly, like just amazingly, they'll be 100% reliable and we'll never have an incident. Now, it turns out that that's just simply not true and becoming increasingly less true as the systems that we work with become more complex and more distributed over time. It turns out that incidents are a normal part of running complex systems. SRE embraces this and says incidents will occur, but when they do, what can we learn from them? [00:10:24 → 00:11:03]
|
||||||
|
|
||||||
|
What can we learn and implement so that we are more prepared for the future and we handle incidents better or our systems are more robust? The thing about incidents is they're often the time we learn the most about our organizations because we're forced to look at things we may have never thought about looking at before. Uh being exposed to different pathways through your systems or behaviors you didn't expect. We learn not just about our technology, but about how uh our different teams actually interact with each other and our processes. So, that kind of attitude around incidents, I think is an important part of SRE. [00:11:01 → 00:11:38]
|
||||||
|
|
||||||
|
Speaking about incidents is the concept of a blameless postmortem. What are they? They are a formal way of learning from incidents. Now, essentially, they are a written record of an incident which covers a timeline of different events that occurred, uh what happened, what was the impact, but most importantly, what did we learn from the incident? And what actions can we take to be better tomorrow than we were today around how we respond to incidents or how robust our systems are. [00:11:35 → 00:12:10]
|
||||||
|
|
||||||
|
Now, a blameless postmortem, you might think sounds just like a post-incident review or PIR from ITIL. Now, in a sense, they are both formal ways to learn from incidents. I would say a blameless postmortem is more collaborative. It has a a stronger focus on psychological safety, a strong important part of SRE. And it also has a stronger focus on learning in the broader sense from incidents rather than trying to find the root cause, which is another principle or idea which is dubious at best. [00:12:08 → 00:12:46]
|
||||||
|
|
||||||
|
Blameless postmortems are one of the things I've actually managed to get off the ground in the first month or two of Blue Current. It's been scary but rewarding to organize, first of all, to get a written account and to encourage people to contribute to it. Started off with just me writing about these things as I was sitting on the incident calls and chats and and pulling things together. Then other people started contributing to it. And now, for the the big important or tricky incidents where there's the stuff to talk about and learn from, pulling in business and technology stakeholders to come together and talk about it. [00:12:45 → 00:13:21]
|
||||||
|
|
||||||
|
It's been really rewarding to hear, say, for example, people from our business side who were on these calls saying, "I didn't know that that's how our technology worked before. " You know, that that is the point. That is amazing and that's the kind of thing that I'm trying to bring to life, to build a a better understanding and connection between everyone. SLOs stand for service level objectives and it is just an enormous topic and I genuinely can't do it even remote justice in this short talk that I'm doing today. But I'm going to try and give the essence of what they're about. [00:13:21 → 00:13:53]
|
||||||
|
|
||||||
|
Now, traditionally, when we set up our monitoring and alerting, we set that up around technical signals. Things like CPU usage or garbage collection, memory, network, disk, uh queue lengths, connection or thread pools, those kinds of things, right? And we set up our alerting based on thresholds. For example, if CPU exceeds 80% for more than 5 minutes, fire an alert to someone to have a look at it. That kind of thing. [00:13:52 → 00:14:22]
|
||||||
|
|
||||||
|
Now, that kind of that sounds sensible and if you've got a a simple system, it kind of works, right? But there's a couple of major challenges with this. The first one is alert noise, where you just get overwhelmed with alerts smashing you every day which aren't necessarily things you need to act on. So, you think about any non-trivial organization, how many different software systems does it have? And then how many different resources does that hardware and software resources do those technology systems have? [00:14:19 → 00:14:51]
|
||||||
|
|
||||||
|
You're talking about thousands, hundreds of thousands, millions, more than millions of different resources all with these alerts set up potentially just flooding your engineers with alerts. That's the first problem. The second problem is just because a technical signal looks bad, doesn't necessarily mean that your business is disrupted in any way or the customers are even having a problem. It is entirely possible to have a situation where, say, you've got a simple system, that CPU on a particular web or application server is running at 100% all day and yet your customers don't notice anything. They can do whatever they need to do. [00:14:51 → 00:15:29]
|
||||||
|
|
||||||
|
Um their experience is still great and your business is not suffering in any way. It is equally likely that you have, say, your beautiful dashboard where you're tracking hundreds of different technical signals and they are all green and yet your customers can't consume your services. So, technical signals are not a great way of actually understanding if there's a thing that you need to respond to, if there's a genuine incident or issue that you need to address. I think SLOs are the answer to that solution. So, we still collect technical signals all the time. [00:15:29 → 00:16:03]
|
||||||
|
|
||||||
|
We collect all the data because we may need it and it will help us diagnose and resolve issues potentially, right? But in terms of alerting, you forget about all those technical signals and instead set up your alerting based on answering one question continuously. Can my customer effectively consume my service? And if the answer is yes, then you don't need to immediately jump on and do anything. And if the answer is no, then you need to do something because you are very confident that your customer is being impacted by something that needs to be addressed. [00:16:03 → 00:16:38]
|
||||||
|
|
||||||
|
Now, that's about all I can do in this tiny little uh two or three minute talk about SLOs. I haven't even described what they are really, but just to finish off, SLOs are like an internal objective that you set around how reliable you want your services to be for your customer. You might hear of the term SLI or service level indicator. Those are the signals that we use to track whether we're meeting those service level objectives. And you might hear the term error budget. [00:16:37 → 00:17:05]
|
||||||
|
|
||||||
|
So, let's say that you want you say, "We want the service to be 99. 9% available. " That leaves you just under 9 hours a year in your error budget, which is time that you have technically said it's okay to be down that much each year. So, if you get towards the end of the year or quarter or however you you measure it and you have had no downtime or very little downtime, you've got this error budget that you can use to run riskier experiments which might have a really big payoff. So, you can use your SLOs and your error budgets to drive innovation by being able to to run these experiments which you might otherwise not have felt safe to do. [00:17:05 → 00:17:47]
|
||||||
|
|
||||||
|
All right, observability, I'm not sure if it's even technically part of SRE, but it's just so intertwined as I see it that I needed to talk about it. The technical definition is, and I'm going to say this wrong, it's something about being able to understand the inner workings of a system by observing its inputs and outputs. Something like that. That's I've got it wrong. I think the key thing to remember is that observability is a quality of a system. [00:17:45 → 00:18:08]
|
||||||
|
|
||||||
|
It's not a thing that you do. It's a thing that you can achieve. When we have observability, we have insight into what is happening within our systems so that we can understand what's going on and not only understand, but be able to more readily resolve issues or incidents or to improve our system because we understand it better. When we have observability, we have that insight. Service level objectives, SLOs, answer the first most important question, which is is there a problem that I need to respond to? [00:18:08 → 00:18:39]
|
||||||
|
|
||||||
|
Are my customers able to effectively consume my services? Observability answers the next question, which is if there is a problem, what's going on? What do I need to do? What do I need to look at? When we have that look, that view under the cover, we have a better understanding of how our increasingly complex and distributed systems actually work. [00:18:39 → 00:19:00]
|
||||||
|
|
||||||
|
And sometimes they work in ways we never would have expected before. It empowers more people to be able to, for example, handle incidents because it no longer depends on an engineer who's been in an org for 20 years and has all the context about everything going on. Because when you have observability, everyone can see quite clearly exactly what's going on and where the problem is located. It allows you to respond to incidents, investigate them, and remediate them much, much faster because you've got clear data which shows you exactly what's going on. There's no more guesswork involved. [00:19:00 → 00:19:36]
|
||||||
|
|
||||||
|
And um this is a terrible diagram if you're watching the YouTube video. It's the only sort of supporting visual here, but it's just a a diagram trying to show distributed tracing, which I think is the quintessential technique for achieving observability. The idea being that you've got a customer somewhere and they click a button to do something, you're able to trace that flow of requests throughout your system and see exactly what's triggered and when, how long it took, what errors occurred, and any other useful metadata that might help us understand exactly what's happening in a really visual way. Toil is manual, repetitive, tedious work, and operations is rife with toil. Think about you copying and pasting from one file to another or running commands and doing a bunch of forms to make a thing happen. [00:19:35 → 00:20:30]
|
||||||
|
|
||||||
|
Toil is bad because it costs a lot of money. You often got these very senior engineers who are clicking through and doing this manual tedious stuff. That's expensive, but even more so is the opportunity cost. You could be getting those senior engineers to be working on engineering work, which is going to bring you forward, make your services more reliable, help you scale your organization, or even improve your products. When you have a high amount of toil, your organization isn't able to scale because as you increase the complexity of your services or and add new services, and as you scale up the volume of activity in the business happening, if you're dependent on toil to support that, you're going to have to hire more and more and more people and then have more and more complexity to try and and coordinate all those people, and that's not effective. [00:20:28 → 00:21:18]
|
||||||
|
|
||||||
|
And toil also leads to potentially unhappy engineers. It's not necessarily satisfying work. It's not helping engineers learn and improve and grow. So, automating and simplifying our processes and ways of working in our technology, uh removing unnecessary or waste wasteful processes and things happening in our systems is a core part of SRE, and it helps not only to uh operate our systems simpler and more effectively and help us scale, it helps with staff retention as well because at least they're happier engineers and more satisfying jobs. So, that's my super fast introduction to SRE and observability. [00:21:16 → 00:21:59]
|
||||||
|
|
||||||
|
If you want to learn more, there are a ton of books by Google uh that I know the first three here are completely free online if you want to read them. There's nothing stopping you going and learning from them. I'm going to be honest, I've only read the first book cover to cover. Uh I should probably read them some more, especially now that I've got this new role. I think you need to purchase Enterprise Road Map to um to SRE, but that's something I am looking through this year. [00:21:59 → 00:22:27]
|
||||||
|
|
||||||
|
There are podcasts. There's this podcast here, uh but this I have a particular style. It's not particularly technical. It's more about the human side of SRE and the ideas, but there's other podcasts including Google's own Google SRE podcast. Nice play on words there. [00:22:24 → 00:22:43]
|
||||||
|
|
||||||
|
But one of the ways that I've learned the most about SRE is just by connecting and following with experts around the world. So, Niall Murphy was one of the co-authors of the original SRE book when he was at Google. And then you've got practitioners like Sebastian and Collette and Amin as well. I I like the way that they think about the work and and the sort of very practical way that they approach it, and I've interacted with them. They've helped me with my thinking. [00:22:42 → 00:23:09]
|
||||||
|
|
||||||
|
And uh Collette is a co-host of another podcast called This is Fine about resilience engineering, which is a ton of useful thinking that can help with SRE work. So, I recommend checking that out. So, that was my super fast introduction to SRE and observability. I do want to say in my new role, I am incredibly excited about genuinely implementing SRE practices from scratch. I'm actually getting to do it. [00:23:09 → 00:23:39]
|
||||||
|
|
||||||
|
It's very exciting and I'm facing some interesting challenges. So, I'm planning on doing quite a few more solo episodes this year to explore these different questions and how we might bring SRE and some technology leadership ideas to life as well. Another thing I wanted to mention is that for the first time in a while, I don't have a large backlog of guests for the show. I've got one interview recorded and one guest I'm thinking of approaching, but if you are working in the realm of SRE, particularly if you are implementing it on the front line, I'd love to hear from you if you'd love to come on the show. So, just reach out to me on LinkedIn or Instagram or wherever you follow me. [00:23:36 → 00:24:21]
|
||||||
|
|
||||||
|
Keeping in mind that this is a show about human beings and how they grapple with this world of SRE, rather than just technical details or particular tools or products. That's not what it's about. So, if that sounds like something you'd love to do, reach out to me. But otherwise, I hope you enjoyed this episode and I hope you have a wonderful fortnight. I'll see you again next time. [00:24:20 → 00:24:44]
|
||||||
|
|
||||||
|
>> [music] [music] [music] [music] [00:24:42 → 00:25:03]
|
||||||
Reference in New Issue
Block a user