
143 lines
7.1 KiB
Markdown
143 lines
7.1 KiB
Markdown
# 6 modes of system resilience
|
||
|
||
- **期号**: SRE Weekly Issue #288(2021-09-19)
|
||
- **作者**: Ash P — Cruform
|
||
- **链接**: https://www.srepath.com/6-system-resilience-patterns-for-increasing-software-reliability/
|
||
|
||
## 简介
|
||
|
||
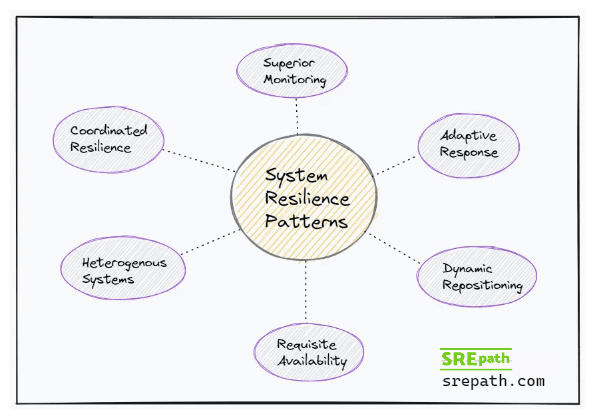
> In this post, I will cover the following modes of system resilience:Adaptive ResponseSuperior MonitoringCoordinated ResilienceHeterogenous SystemsDynamic RepositioningRequisite Availability
|
||
|
||
## 正文
|
||
|
||
## Introduction
|
||
|
||
System resilience thinking can inform better Site Reliability Engineering decisions. Specifically, it can affect how the SRE culture unfolds and handles critical situations.
|
||
|
||
The *system resilience* concept is rooted in theoretical computer science.
|
||
|
||
Don’t panic. I will explain how it can – **in a practical way – support increased software reliability** in production.
|
||
|
||
We will cover six patterns that comprise system resilience:
|
||
|
||
1. Adaptive Response
|
||
2. Superior Monitoring
|
||
3. Coordinated Resilience
|
||
4. Heterogeneous Systems
|
||
5. Dynamic Repositioning
|
||
6. Requisite Availability
|
||
|
||
|
||
|
||
The above terms likely make little sense, but we will unpack each in a moment.
|
||
|
||
First, let’s define system resilience in the software context:
|
||
|
||
*System resilience is the ability of organizational, hardware and software systems to **mitigate the severity and likelihood of failures** **or losses**, to adapt to changing conditions, and to respond appropriately after the fact.*
|
||
|
||
|
||
It’s a very academic definition but very precise in its meaning. The concept of system resilience is important for **proactively addressing software performance and reliability**.
|
||
|
||
Now, let’s unpack each of the six patterns of system resilience:
|
||
|
||
## Resilience pattern #1: Superior monitoring
|
||
|
||
### What does it mean?
|
||
|
||
Monitor for and detect adverse events in a timely manner, well before they can snowball into a critical issue.
|
||
|
||
### How to apply it to SRE practice
|
||
|
||
You can make for a superior monitoring effort by:
|
||
|
||
- seeking indicators for the likelihood and severity of system failures
|
||
- developing integrated systems of observability (logging, tracing, and monitoring) to increase confidence that adverse events are happening
|
||
- enhancing this approach by knowing the location, spread, and extent of the adverse event
|
||
|
||
## Resilience pattern #2: Adaptive response
|
||
|
||
### What does it mean?
|
||
|
||
Respond to the adverse event in a timely and effective manner
|
||
|
||
### How to apply it to SRE practice
|
||
|
||
Make these balancing considerations when you detect an adverse event and decide to respond to it:
|
||
|
||
- maintain a reasonable speed of response – not so slow that the incident scales up and not so fast that you miss critical details
|
||
- have paths of action ([like runbooks](<http://Runbooks for better incident responsehttps://www.srepath.com › runbooks-for-better-incident...>) ) ready, but don’t force a rigid path if the situation begins to move in an unusual direction
|
||
- understand that initial incidents can branch into splinter issues and have adequate resources to address the likelihood of this
|
||
- be prepared with a pre-existing tool and process set to rapidly and accurately handle incidents
|
||
|
||
## Resilience pattern #3: Coordinated resilience
|
||
|
||
### What does it mean?
|
||
|
||
Increase the *depth of resilience* by coordinating several proactive solutions that will hinder emerging incidents before they impact systems.
|
||
|
||
### How to apply it to SRE practice
|
||
|
||
Coordinated resilience begins with the architecture of the software. You can develop a coordinated resilience to incidents by doing the following:
|
||
|
||
- integrate methodologies like failover design, security integration, BDD/TDD and DevSecOps
|
||
- drive developer education in ways to apply the above methods
|
||
- adopt full-stack tracing to uncover and resolve issues at a multi-layer level
|
||
|
||
## Resilience pattern #4: Heterogenous systems
|
||
|
||
### What does it mean?
|
||
|
||
Continually find ways to spread the attack or error vector. This implies driving redundancy in all aspects of service delivery. The aim is to reduce common-mode failure risk at every juncture.
|
||
|
||
An example would be finding ways to not serve all of the traffic for a high-traffic service using one type of virtual machine service.
|
||
|
||
### How to apply to SRE practice
|
||
|
||
Consider the following ways to drive heterogeneity:
|
||
|
||
- have a variety of service delivery modalities e.g. managed K8s *and* Lambda for critical services
|
||
- create vendor-level redundancies where possible i.e. multi-vendor tooling and multi-cloud
|
||
|
||
## Resilience pattern #5: Dynamic repositioning
|
||
|
||
### What does it mean?
|
||
|
||
Increase the ability to recover from an incident by distributing and diversifying resource distribution.
|
||
|
||
### How to apply to SRE practice
|
||
|
||
This resilience pattern has never been easier thanks to cloud-based software deployment. You have options like:
|
||
|
||
-
|
||
**Geographical repositioning** – cloud services are readily available across multiple global zones
|
||
-
|
||
**Cloud repositioning** – you can run your cloud with multiple public clouds or go hybrid with a combination of public cloud and private cloud
|
||
|
||
Another repositioning possibility is altering how services are housed and coordinated. You can physically separate non-critical services from critical services or alter API rules so that the former doesn’t overload the latter.
|
||
|
||
## Resilience pattern #6: Requisite availability
|
||
|
||
### What does it mean?
|
||
|
||
It means being realistic and delineating the importance of your software services. Some systems must be available at all times, others not necessarily. Some data is more important than others.
|
||
|
||
For example, enterprise users get high availability due to negotiated service-level agreements (SLAs), but free users do not get the same promise.
|
||
|
||
### How to apply it to SRE practice
|
||
|
||
You can set tags like *service-priority* in your service catalog with a tool like Cortex to signify the critical points in the system architecture. For example, *“this service is mission-critical because it serves enterprise users while this one is a lower priority one for storing avatars.”*
|
||
|
||
Concerning data, you can sensitive data to be non-persistent to reduce the risk of corruption or compromise. If it needs to be persisted, consider moving it to a storage option that’s not directly linked to the service grid.
|
||
|
||
## Conclusion
|
||
|
||
I hope I have given you effective ideas and critical thinking opportunities for increasing reliability by unpacking these theoretical patterns of system resilience.
|
||
|
||
|
||
|
||
[see all](https://www.srepath.com/author/kashaup/))
|
||
|
||
- [#34 From Cloud to Concrete: Should You Return to On-Prem?](https://www.srepath.com/sre-2016-book-reaction-chapter-1-part-1-3/) – March 26, 2024
|
||
- [#33 Inside Google’s Data Center Design](https://www.srepath.com/sre-2016-book-reaction-chapter-1-part-1-2/) – March 19, 2024
|
||
- [#32 Clarifying Platform Engineering’s Role (with Ajay Chankramath)](https://www.srepath.com/platform-engineering-role-software-operations/) – March 14, 2024
|